# Data Engineering Companies Index — Full Knowledge Dump
> Source: https://dataengineeringcompanies.com
> Generated: 2026-09-02
> License: research excerpts may be quoted with attribution to "Data Engineering Companies Index" and a link to https://dataengineeringcompanies.com
> About: independent analyst firm benchmarking 86 data engineering services vendors. Methodology at https://dataengineeringcompanies.com/methodology/
---
# Section 1: Insights articles
## 7 Top AI Automation Companies for 2026
Source: https://dataengineeringcompanies.com/insights/ai-automation-companies/
Published: 2026-07-14T10:51:34.358886+00:00
Description: Find the best AI automation companies for your enterprise. Our 2026 guide reviews top firms, rates, use cases, and how to select the right partner.
You're likely in one of two situations. Your team ran an AI pilot that impressed stakeholders, then stalled once it hit integration, governance, or change management. Or procurement is looking at a crowded field of AI automation companies that all promise transformation and don't make the choice any easier.
The wrong partner doesn't just waste budget. It leaves you with brittle workflows, unclear ownership, and an automation stack your internal team can't run without calling the vendor back. That risk is real because automation programs increasingly live or die on the same data foundations, cloud architecture, and governance discipline as any other engineering effort - not on who has the better demo. Sixty-four of the 86 firms profiled in the Data Engineering Companies Index list ML/AI among their capabilities; see the [machine learning consulting firms](/insights/machine-learning-consulting-firms/) breakdown for how that group splits by platform and use case.
This shortlist covers seven firms that can support enterprise automation programs, plus a buyer framework built around delivery fit, operating model, and commercial reality. For engineering and architecture leaders, the real test isn't who has the flashiest agent demo. It's who can connect automation to production data systems, governance controls, and measurable operating outcomes.
## 1. Accenture
Accenture is the safest choice when the program is large, cross-functional, and politically complex. If you need one partner to cover strategy, cloud architecture, platform implementation, operating model, and managed services, Accenture belongs on the shortlist.
That fit matters because most organizations still haven't turned AI into material business performance - pilots that impress in a demo rarely show up as measurable business impact a year later. Accenture's value is its ability to move a program from pilot theater into operating discipline.
### Where Accenture wins
Accenture is strong when automation depends on enterprise data plumbing. Think Snowflake or Databricks modernization, dbt model redesign, Airflow orchestration, cloud landing zones on AWS or Azure, and governance layers that legal and security teams will approve.
It also has one advantage many AI automation companies lack. It can absorb the change management load across operations, IT, risk, and business teams without forcing the client to coordinate five specialist vendors.
- **Best for enterprise scale:** Global programs, regulated environments, and multi-cloud estates.
- **Best for platform-heavy work:** Snowflake, Databricks, hyperscaler services, and automation platforms in the same program.
- **Best for managed run:** Teams that want a partner to stay after go-live.
> **Practical rule:** Hire Accenture when internal alignment is your biggest execution risk, not when low cost is the priority.
The tradeoff is obvious. Pricing is premium, and the engagement model works best when your internal architecture, security, and process owners are ready to make decisions quickly. If you're evaluating data readiness before automation, read the [Data Engineering Companies Index AI hub](/ai-data-engineering/).
Accenture website: [Accenture AI, Data & Automation](https://www.accenture.com/us-en/edge/services/ai-data-automation)
## 2. Deloitte
Your security lead wants model controls. Legal wants traceability. Procurement wants a defensible statement of work. Business units still expect results this quarter. Deloitte is a good fit when partner selection is less about flashy demos and more about getting an AI automation program approved, governed, and funded across the enterprise.
That bias toward control is rational. In Deloitte's own [State of AI in the Enterprise report](https://www.deloitte.com/us/en/what-we-do/capabilities/applied-artificial-intelligence/content/state-of-ai-in-the-enterprise.html), governance, risk, and implementation barriers keep showing up as what slows production adoption. CIOs should read that as a buying signal. If those constraints define your environment, pick a firm built for them.
### Where Deloitte fits best
Deloitte is strongest in buyer situations where the core problem is operating model design. It does well with policy design, control mapping, model risk processes, cross-functional governance, and PMO-heavy transformation work. That makes it a better choice for enterprise AI automation programs than for isolated task automation.
It also fits organizations that need a partner to survive procurement scrutiny. Deloitte usually shows up with strong documentation, audit-ready methods, and a clearer path from pilot to run-state ownership than smaller firms. That matters if your RFP scoring model gives real weight to security, compliance, transition support, and executive reporting.
- **Best for regulated environments:** Financial services, healthcare, public sector, and other audit-heavy industries.
- **Best for multi-BU programs:** Useful when business units have different process owners, data policies, and approval chains.
- **Best for governance-led buying:** Strong option when your shortlist will be scored on controls, change management, and post-launch support, not just build speed.
> Practical rule: Hire Deloitte when governance failure is the main delivery risk. Do not hire Deloitte for a cheap, fast proof of concept.
Buyers should also price this correctly. Deloitte usually sits in the upper end of the market, and the delivery model can feel heavy for teams that just need a lean engineering squad to ship a narrow workflow. If your expected engagement is under a few hundred thousand dollars, or your success metric is speed over formal control, move them down the shortlist.
Deloitte website: [Deloitte Ready, set, scale AI](https://www.deloitte.com/us/en/services/consulting/services/ready-scale-ai-across-your-organization.html)
## 3. Cognizant
A common enterprise scenario looks like this: the workflow is broken across ERP, CRM, shared inboxes, and a few legacy systems no one wants to touch. The mandate isn't just to automate tasks. It's to redesign the process, fix the data flow, and make the operating model hold up after go-live. Cognizant is a credible option for that kind of work.
Cognizant sits in a practical middle band for large buyers. It has the scale to handle multi-region delivery, but it usually sells implementation and process change more directly than pure boardroom strategy. For CIOs and procurement leaders, that matters. You're not only buying an AI layer. You're buying integration, workflow redesign, platform fit, and run-state support.
Enterprise demand in this category tends to reward firms that combine advisory, implementation, and managed operations rather than isolated model builds. That's the buying motion where Cognizant tends to make sense.
### Best-fit buyer profile
Cognizant is strongest in programs where automation depends on adjacent modernization work. If source systems are messy, process ownership is split across functions, and the business case depends on operational rollout, keep them on the shortlist.
Use Cognizant for these scenarios:
- **Cross-functional programs:** Operations, service, supply chain, or back-office initiatives that need process redesign plus technical delivery.
- **Hybrid enterprise estates:** Good fit when legacy platforms, cloud data stacks, and multiple automation tools have to work together.
- **Mid-to-large transformation budgets:** Better aligned to buyers funding a real program, not a low-cost experiment.
Expect rate bands and contract shape to reflect that model. Cognizant usually fits buyers budgeting for a multi-workstream engagement rather than a narrow pilot. If your RFP should score implementation depth, transition planning, and managed support heavily, it deserves serious consideration.
There is a clear tradeoff. Cognizant can feel heavier than a specialist firm. Decision-making, documentation, and cross-team coordination are usually stronger than speed. That's good for enterprise control. It's bad if your main goal is to ship one narrowly scoped workflow in a few weeks.
Red flags to probe in diligence: too much reliance on offshore handoffs for process discovery, vague ownership for post-launch KPI tracking, and weak clarity on which accelerators are reusable versus custom-built. If the answers are soft, your timeline will slip and your operating costs will climb.
Practical rule: hire Cognizant when the actual problem is process complexity across systems and teams. Drop them down the list if you want the lightest possible delivery model.
Cognizant website: [Cognizant Intelligent Process Automation](https://www.cognizant.com/us/en/services/intelligent-process-automation)
## 4. Quantiphi
Quantiphi is the best option on this list for buyers who want an AI-first firm without going all the way down to a narrow boutique. It's especially compelling for customer service automation, document-heavy workflows, and cloud-native implementations on Google Cloud or AWS.
Contact center automation is one of the fastest-growing categories of enterprise AI spend, and Quantiphi is well aligned with that demand.
### Best-fit buyer profile
If your roadmap includes contact center AI, document extraction pipelines, model operations, and domain workflows in healthcare or financial services, Quantiphi is a serious contender. The firm is often strongest when data engineering and applied AI have to move together, not in separate workstreams.
That makes it attractive for engineering leaders who care about implementation detail. You'll generally get a more focused delivery posture than with the largest SIs, especially in cloud-native builds.
- **Strong fit for Google Cloud and AWS shops:** Especially for AI services tied to data platforms.
- **Strong fit for document and service workflows:** Good for unstructured data pipelines and workflow automation.
- **Strong fit for domain-led use cases:** Healthcare, public sector, and financial services stand out.
The main limitation is ecosystem breadth. If you need a fully on-prem program or a massive global rollout with dozens of business units, one of the mega-integrators is usually safer.
Quantiphi website: [Quantiphi](https://quantiphi.com)
## 5. Tredence
Tredence is the strongest choice here when the actual problem is operationalization. Many AI automation companies are good at discovery and weak at production engineering. Tredence is built for the opposite problem.
That matters because high-performing organizations don't treat AI as an isolated tool purchase. They invest in data foundations, senior talent, and governance frameworks as a package, not as separate line items. Tredence's positioning lines up with that reality.
### Why engineering leaders pick Tredence
Tredence is a fit for organizations modernizing data platforms while pushing ML and generative AI into production. For those working through LLMOps, MLOps, model governance, observability, and deployment workflows tied to real business processes, the firm particularly stands out.
It's also a sensible option when your architecture team wants tight alignment between data platform design and AI delivery. That's particularly relevant in retail, CPG, and financial services environments where data freshness, workflow orchestration, and model monitoring all matter.
> Don't separate the AI vendor from the data engineering vendor if the bottleneck is production data quality, orchestration, or governance. That split usually creates blame, not progress.
Tredence is less ideal if your roadmap leans heavily toward RPA or UI-driven automation outside a modern data platform context. In that case, pair it with a specialist or choose a broader systems integrator.
If your team is evaluating run-state controls and deployment standards, this [guide for engineering leaders on MLOps](/insights/mlops-consulting-services/) is useful.
Tredence website: [Tredence services](https://www.tredence.com/services)
## 6. West Monroe
A portfolio company misses its margin plan, leadership wants automation savings inside two quarters, and the CIO needs a partner that can tie AI spend to operating results fast. That's the buying situation where West Monroe makes sense.
West Monroe is the strongest fit on this list for mid-market firms and private-equity-backed businesses that need execution tied to EBITDA, service levels, and working-capital impact. Unlike larger firms that can bury delivery under transformation language, West Monroe usually frames the work around a business case, an operating model, and a short path to measurable gains. For procurement teams, that matters because partner selection should start with economic accountability, not slide-deck ambition.
### Where West Monroe is strongest
Choose West Monroe when you need an operator's view of automation. The firm is well suited to banking, life sciences, and PE environments where diligence, process redesign, and KPI ownership matter as much as model performance. It's also a practical option when the buyer wants senior attention and faster decision cycles than a global SI typically offers.
This is a buyer-fit decision, not just a brand decision.
- **Best for mid-market programs:** Good fit when speed, executive access, and business alignment matter more than global bench depth.
- **Best for PE-backed companies:** Strong option when the value thesis needs to show up in cost takeout, throughput, or margin improvement.
- **Best for KPI-owned automation:** Useful when finance and operations leaders expect named owners, milestone reviews, and clear success measures.
Rate expectations usually fall below top-tier global consultancies but above narrow implementation shops. Ask for pricing by phase, team mix, and outcome assumptions. If a partner cannot explain what portion of fees goes to strategy, build, change management, and run support, your RFP process is too loose.
A clear red flag is vague language around agent-based workflows, governance, and handoffs between humans and systems. Push the vendor to walk through a specific agent failure scenario and who owns the recovery - if they can't answer in concrete terms, the governance story is thinner than the pitch deck.
The main constraint is scale. West Monroe is not the best choice for multi-country rollouts that need a very large managed-services footprint across regions and time zones.
West Monroe website: [West Monroe AI services](https://www.westmonroe.com/services/ai-services-solutions)
## 7. Ashling Partners
Your team already picked the platform. The backlog is sitting there. The problem is delivery capacity, governance discipline, and whether the partner can turn automation demand into production releases without enterprise-consulting overhead.
That's where Ashling Partners fits best. Ashling is a specialist firm, and buyers should evaluate it that way. Do not hire Ashling to define a broad enterprise transformation from scratch. Hire it when the program thesis is already clear and you need a partner that can build, operationalize, and support an automation function quickly, especially in UiPath-heavy environments.
Rate discipline matters here. As noted earlier, specialist firms often price below large global consultancies because you're not paying for the same strategy layers, geographic footprint, or transformation overhead. For procurement leaders, the right move is to force a clean rate-card discussion by role, phase, and run-support scope. If Ashling cannot show where fees sit across advisory, build, testing, hypercare, and managed support, treat that as an RFP gap.
### When to choose Ashling
Ashling is a strong fit when the use case portfolio is already defined and the bottleneck is execution. That includes teams standing up an automation center of excellence, formalizing intake and prioritization, or expanding from pilot work into a managed delivery model.
It's also a good choice when the buyer wants a narrower partner with real implementation focus instead of a strategy-first account team.
- **Best for execution-heavy automation programs:** Good fit when the roadmap exists and delivery speed matters more than broad enterprise advisory.
- **Best for CoE buildout and managed run support:** Useful when you need operating model design, release discipline, and post-launch support.
- **Best for UiPath-led estates:** Validate certifications, reusable assets, and governance experience early if UiPath is central to the program.
The main risk is buying too small for the mandate. If the initiative also includes major cloud modernization, enterprise data-platform redesign, or large-scale cross-border change management, Ashling will need to work alongside a broader partner. CIOs should be explicit about that boundary before contracting.
A second red flag is platform narrowness disguised as automation strategy. Ask whether the team can map process suitability, exception handling, human review points, and model governance, not just bot deployment. If the answers stay tool-centric, buyer fit is poor.
Ashling website: [Ashling Partners](https://ashling.ai)
## Top 7 AI Automation Companies: Capabilities Comparison
| Vendor | Implementation complexity | Resource requirements | Expected outcomes | Ideal use cases | Key advantages |
|---|---:|---|---|---|---|
| Accenture (Applied Intelligence, AI, Data & Automation) | High, enterprise-scale integrations and change orchestration | Large cross-functional teams, cloud/vendor licenses, extensive change management | Scaled production deployments and organization-wide adoption | Global programs, multi-cloud enterprise transformations, large back-office automation | End-to-end delivery, pre-built accelerators, strong change management |
| Deloitte (AI & Insights, Intelligent Automation) | High, industrialized, governance-heavy rollouts | Significant consulting, governance frameworks, managed-run capabilities (IntelliForce) | Governed, repeatable, scalable automations with ROI focus | Regulated industries and enterprise-wide AI/automation scaling | Operating-model design, tool-agnostic delivery, broad industry depth |
| Cognizant (Intelligent Process Automation and AI Services) | Medium to High, process reengineering plus platform work | Advisory + delivery teams, platform integrations, partner tooling | End-to-end process orchestration and agent-based automations | Complex estates, contact centers, industrial operations | Cross-domain accelerators, strong partner ecosystem, Snowflake integrations |
| Quantiphi (Applied AI and Automation Services) | Medium, cloud-aligned, domain-focused implementations | GCP/AWS specialists, domain engineers, contact-center and doc automation tooling | Improved CX, automated document workflows, measurable contact-center gains | Contact centers, document-heavy workflows, healthcare/financials/public sector | Deep contact-center & document automation expertise, measurable outcomes |
| Tredence (Operationalizing GenAI with LLMOps/MLOps) | Medium, ML/LLM productionization and data modernization | ML/LLM engineers, data-platform modernization, observability and MLOps tooling | Production-grade GenAI/ML with disciplined LLMOps and observability | Data modernization, GenAI productionization, supply chain and retail analytics | Strong LLMOps/MLOps capability, deployment workflows, observability focus |
| West Monroe (AI Services, Agentic Transformation) | Medium, outcome-led with faster cycles than mega-SIs | Industry playbooks, operations/diligence teams, Intellio accelerators | KPI-tied automations and quantified operational savings | Mid-market banking, PE diligence, operations automation with P&L focus | Outcome-led approach, sector-specific assets, faster time-to-value for mid-market |
| Ashling Partners (Intelligent Automation Specialist) | Low to Medium, specialist RPA/agentic automation focus | UiPath-certified teams, CoE enablement, platform certifications | Rapid backlog reduction, CoE operationalization, reliable run capability | UiPath-centric RPA programs, CoE build-out, rapid automation delivery | UiPath Diamond-tier expertise, specialist focus, fast time-to-value |
## Your RFP Checklist: Proof Points, Not Promises
Before you sign anything, force every vendor through a structured scorecard. Most failed AI automation engagements don't collapse because the demo was bad. They fail because the buyer didn't validate delivery depth, data engineering capability, governance design, and post-launch ownership - the same criteria that apply to [evaluating any data engineering vendor](/insights/data-engineering-vendor-evaluation-criteria/).
Start with commercial reality. Most credible engagements break into three phases: a discovery audit, a stabilization sprint, and the platform build. Ask each vendor for a phase-by-phase quote with a duration and a deliverable attached to each one. If they can only give you a single lump-sum number for the whole program, that's a sign the scope isn't defined yet.
### What your RFP must force vendors to prove
- **Architecture depth:** Ask how they design pipelines, orchestration, and storage across Snowflake, Databricks, dbt, Airflow, AWS, Azure, and BigQuery.
- **Governance by default:** Require tests, alerts, lineage, access controls, and documented core metrics in the base scope.
- **Migration discipline:** Ask for a named approach to cutover, rollback, environment promotion, and production support.
- **Run-state ownership:** Require a formal handover plan so your team can operate day-to-day workflows confidently.
- **Cost control:** Ask how they identify cloud waste and how they'd reduce it during the engagement.
Push every vendor to show before-and-after metrics on refresh time, accuracy, and cost. Don't accept an abstract reference to "business value" - demand proof tied to system performance and operating metrics.
> If a vendor can't explain how it handles testing, lineage, orchestration failures, and ownership transfer, it isn't selling automation. It's selling future rework.
### Red flags that should eliminate a vendor
- **No named delivery team:** If the pitch is senior and the delivery plan is vague, expect substitution risk.
- **No platform point of view:** Strong partners can explain when Snowflake, Databricks, dbt, Airflow, AWS, Azure, or BigQuery fit. Weak ones say they do everything equally well.
- **No governance artifacts:** If they can't show examples of metric definitions, runbooks, or data quality controls, remove them.
- **No implementation references by problem type:** Similar industry is helpful. Similar architecture and operating complexity matter more.
- **No handover plan:** If they expect permanent dependence, that's a commercial choice, not a technical necessity.
Use a weighted scorecard across technical capability, delivery quality, governance maturity, cost transparency, industry fit, and support model, then run vendors through a live technical review, not just a procurement questionnaire. The [data engineering RFP checklist](/data-engineering-rfp-checklist/) is a reasonable starting template if you need one.
Your next step is simple. Shortlist three firms. Make them respond to the same architecture, governance, and operating-model questions. Then pick the partner that can prove it can build, transfer, and support the system you require.
---
## Airflow vs Prefect vs Dagster: A 2026 Decision Guide for Engineering Leaders
Source: https://dataengineeringcompanies.com/insights/airflow-vs-prefect-vs-dagster/
Published: 2026-03-19T08:09:37.922256+00:00
Description: A definitive guide to Airflow vs Prefect vs Dagster for enterprise data teams in 2026. Make the right choice for your data platform and avoid technical debt.
**Airflow is the safest choice for stable, high-volume batch ETL. Prefect fits dynamic, event-driven Python workflows that need to fail gracefully. Dagster fits teams that want to build and govern data assets, not just run tasks.** The right pick depends on which of those three problems you actually have. This article belongs to the **Data Pipeline Architecture** hub.
## What's the core difference between Airflow, Prefect, and Dagster?
Airflow is task-oriented and imperative: you wire tasks into a DAG and it runs them on schedule. Prefect is flow-based and Python-native, built to keep running when things go wrong. Dagster is asset-centric: you define the data you want produced, and it derives the pipeline from those dependencies.
### Quick comparison
| Criterion | Apache Airflow | Prefect | Dagster |
| :--- | :--- | :--- | :--- |
| **Core Model** | Task-oriented, imperative | Flow-based, hybrid | Asset-centric, declarative |
| **Ideal User** | Enterprise teams with mature batch ETL | Teams needing dynamic, Python-native workflows | Data platform teams focused on lineage and testing |
| **Primary Strength** | Ecosystem size and industry adoption | Developer experience and resilient execution | Integrated data lineage and local development |
Each model has real consequences for how your team builds, tests, and maintains pipelines - the table only tells you where to start looking.
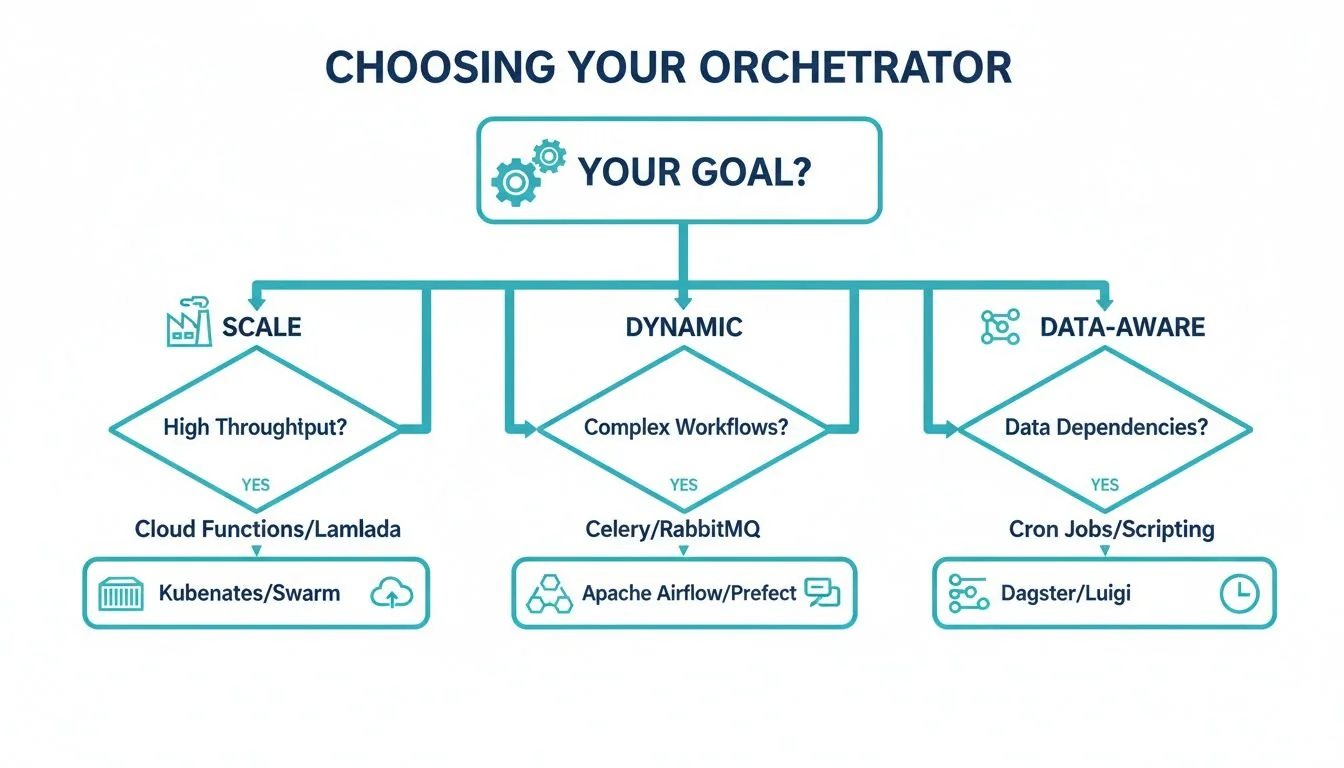
The first question is what you're optimizing for: raw throughput on predictable jobs favors Airflow, handling unpredictable logic favors Prefect, and tracking data assets end to end favors Dagster.
## How do their architectural philosophies actually differ?
[Apache Airflow](https://airflow.apache.org/) uses a traditional, imperative model: you define tasks and explicitly wire them into a Directed Acyclic Graph. It's task-centric, battle-tested for classic batch ETL where the sequence of operations doesn't change often.
> Airflow offers a proven model for stable, high-volume workloads, but that stability cuts both ways. Local testing is cumbersome, and debugging is harder than it should be because the system tracks *what to run*, not *what data got produced*.
### The move toward dynamic and data-aware orchestration
[Prefect](https://www.prefect.io/) takes a different approach with its "code as workflows" model - Python decorators turn any function into a workflow step. That gives you DAGs that can change shape at runtime, which matters for event-driven pipelines or complex application logic. Prefect's design prioritizes resilient execution over rigid structure.
[Dagster](https://dagster.io/) goes further with a declarative, data-aware philosophy. Instead of tasks, your team defines **software-defined assets** - the tables, files, or ML models you want produced - and Dagster infers the steps needed and builds the DAG from those dependencies. It's a shift from a task-centric to an asset-centric mindset.
That shift has real consequences. Dagster's asset-first approach makes data lineage a native part of the system instead of something bolted on afterward, which is why our [data orchestration platforms](/insights/data-orchestration-platforms/) comparison treats it as a separate category from task schedulers.
Airflow still holds its dominant position on the strength of its community and enterprise track record, and remains a reliable choice for large-scale, predictable jobs. Its learning curve and operational complexity are the tradeoff - teams running dynamic, fast-changing workloads on Airflow tend to spend more of their platform team's time on scheduler and DAG maintenance than teams on Prefect or Dagster do.
Picking between these tools is a bet on a development philosophy: do you want your team managing tasks, orchestrating flexible code, or declaring data assets? That answer shapes the long-term scalability and maintainability of your data platform.
## How do scalability, deployment, and cost compare?
Airflow's monolithic scheduler can become a bottleneck at scale; running it well requires real operational expertise and often a Celery or Kubernetes executor setup. Prefect and Dagster decouple orchestration from execution by design, which lowers the operational floor but shifts where complexity shows up.
Newer Airflow versions support a highly available scheduler, but configuring it properly still puts a heavy load on your platform team to keep it from becoming a single point of failure.
### Decoupled execution and cloud-native design
Prefect's agent-based model is the clearest example of decoupling: the control plane (Prefect Cloud or your own server) dispatches work to agents running inside your environment, so data and code never leave your VPC and execution resources scale independently of the control plane.
> Prefect's agent model can scale execution down to zero, so resources are only provisioned when a flow run is active. That fits serverless cost models better than an always-on Airflow deployment does.
Dagster was built for containerized environments like Kubernetes from the start. Its gRPC-based architecture creates a hard boundary between user code and core system components, so a bug in user code can't take down the scheduler - a meaningful stability advantage in cloud-native deployments.
### Managed services vs. self-hosting cost
Choosing between self-hosting and a managed service (Astronomer for Airflow, Prefect Cloud, Dagster Cloud) is a major factor in total cost of ownership. Self-hosting skips subscription fees but puts the full operational burden - security, compliance, upgrades, scaling - on your own team.
The tradeoff shows up concretely in how vendors position themselves: [Datacoves](https://datacoves.com), a 30-person firm built around the dbt/Snowflake/Airflow stack, built its own platform specifically to reduce the friction of running dbt and Airflow together - evidence that self-hosted Airflow operations are enough of a burden to build a business around solving them.
All three vendors now offer hybrid deployment models that manage the control plane for you while your data processing stays inside your own cloud - a middle ground between full self-hosting and full SaaS.
## How does developer experience compare?
Dagster and Prefect give you a real local development loop: code, test, and iterate on your laptop before deploying. Airflow's local setup is harder - you're often wrestling with Docker Compose just to test a single DAG.
### Local development and testing speed
Dagster's asset-based model and its **Dagit** UI let you materialize assets and see dependencies on your laptop, which shortens the debugging loop. Prefect's "code as workflows" approach lets engineers test flows the same way they'd test any Python function, without extra boilerplate.
> Airflow's local development friction is real: its architecture usually requires a full-stack environment, so testing one DAG often means standing up Docker Compose. That slows onboarding, and developers frequently push to a shared dev environment just to see if code works.
### Observability out of the box
Real observability means understanding data health and lineage, not just reading logs.
* **Dagster:** Every run is tied to an asset, so Dagster tracks metadata, upstream dependencies, and data freshness automatically - an integrated data catalog and lineage graph come standard.
* **Prefect:** Its event-based logging gives a real-time view of every flow run, with a clean UI covering task states and execution history.
* **Airflow:** Traditional task-level logging works but doesn't carry Dagster's data context. Getting real lineage means integrating a third-party tool like OpenLineage.
Being able to trace data dependencies and check pipeline health without adding a third-party tool is a real advantage for Dagster and Prefect teams; our guide on [data pipeline monitoring](/insights/data-pipeline-monitoring-tools/) covers what to add when your orchestrator doesn't cover it natively.
## Which orchestrator fits your use case?
There's no single "best" tool here - each was built to solve a different problem, and picking one is a real commitment to a particular way of building pipelines. The question isn't which tool has the longest feature list; it's which one matches your team's experience, pipeline complexity, and data governance needs.
### When to choose Apache Airflow
[Apache Airflow](https://airflow.apache.org/) is the industry default for large organizations running predictable, massive-scale batch jobs. Choose it if:
* **You run predictable, high-volume batch processing.** Thousands of time-based ETL jobs that need to just work, with pipelines that don't change often.
* **A mature ecosystem matters more than anything else.** Airflow's large catalog of community-maintained provider packages gives it broad connectivity to other systems.
* **A deep talent pool is critical.** Airflow's market share means experienced engineers are easier to hire than for either alternative.
Airflow's reliability has been proven at a scale its competitors are still working toward - for a CTO managing operational risk, that history is worth something on its own.
### When to choose Prefect
[Prefect](https://www.prefect.io/) is built for the messy, unpredictable workflows where Airflow's rigid structure breaks down. Consider it if:
* **Your workflows are dynamic and event-driven.** Pipelines respond to incoming files, API calls, or other events rather than a fixed clock, and Prefect's ability to generate DAGs at runtime handles that well.
* **Resilient execution matters more than raw throughput.** Your workflows fail for reasons outside your control, and Prefect's state management and retry logic are built specifically for that case.
* **Cost-efficient scaling matters.** Workloads arrive in bursts with long idle periods, and Prefect's agent model can scale to zero instead of paying for idle infrastructure.
### When to choose Dagster
[Dagster](https://dagster.io/) is a genuinely different way of thinking about orchestration - built around data assets, not tasks, for teams treating **data as a product**. Consider it if:
* **You're building a data mesh or "data as a product" culture.** Domain teams own their data products, and clear accountability across teams is a requirement, not a nice-to-have.
* **Integrated governance and lineage matter.** You want one source of truth for how data is created and where it goes, without bolting on separate lineage and observability tools.
* **Developer productivity and local testing are priorities.** You want data engineers to work like software engineers, with fast local cycles - Dagster's native `pytest` integration is a real advantage here.
## Common questions on orchestration tools
The same questions come up whenever engineering leaders compare these three tools: what migration actually costs, what a managed service means for security, and how well each fits the rest of the stack.
### How much does migrating off Airflow cost?
Migrating away from an established Airflow deployment is a real project, and the cost comes down to developer hours spent rewriting custom operators and macros - those rarely port over and usually need a full rewrite. Teams that make the move typically justify it by weighing the upfront rewrite cost against the ongoing maintenance time Prefect's or Dagster's model saves; get a firm number by prototyping your highest-maintenance DAGs in the target tool before committing to a full migration.
### Are managed orchestration services secure enough for enterprise compliance?
**Yes, when the vendor uses a hybrid deployment model.** Moving to a managed service like [Astronomer](https://www.astronomer.io/), Prefect Cloud, or [Dagster Cloud](https://dagster.io/cloud) raises fair questions about vendor lock-in and data control. All three now offer hybrid deployment: your code, data, and execution environments stay inside your own VPC, and the vendor's cloud service only manages the control plane - it sends instructions but never touches the data itself. That separation is what lets these deployments satisfy strict compliance standards like SOC 2 and HIPAA; your team's work shifts from managing infrastructure to tuning the IAM roles and network policies that govern how the control plane can reach your execution plane.
### How well does each tool integrate with dbt and the modern data stack?
All three orchestrators connect to [dbt](https://www.getdbt.com/), [Snowflake](https://www.snowflake.com/en/), and [Databricks](https://www.databricks.com/), but the depth of integration differs, and dbt is common enough in real stacks that it's worth weighing carefully - 20 of the 86 firms profiled in the Data Engineering Companies Index name dbt in their stack.
* **Dagster** has the deepest integration through its `dagster-dbt` library, which treats dbt models as first-class software assets, parses their metadata automatically, and builds a lineage graph from source to final dashboard.
* **Prefect** offers a similarly polished experience through its `prefect-dbt` collection, with orchestration that feels native and solid observability out of the box.
* **Airflow**'s integration works but feels bolted on - you're relying on community-built providers or custom Python code, with less built-in visibility than Dagster or Prefect provide.
---
Picking the right data engineering partner matters as much as picking the right orchestrator. See our [data pipeline](/data-pipeline/) hub for buying guides and firm comparisons, or read more on [data pipeline architecture patterns](/insights/data-pipeline-architecture-examples/) to see how orchestrator choice fits into the broader system design.
---
## Mastering Analytics In Finance For Enterprise Success
Source: https://dataengineeringcompanies.com/insights/analytics-in-finance/
Published: 2025-12-18T07:15:34.287375+00:00
Description: Discover practical strategies for analytics in finance that drive ROI, optimize data architecture, and streamline implementation for lasting enterprise impact.
Analytics in finance turns transaction data, market feeds, and ERP records into forecasts a finance team can act on: cash flow projections that update daily instead of monthly, fraud scoring on live transactions, and risk models that shift as conditions change instead of waiting for a quarterly review. The payoff lands in three places - lower costs from automated processes, higher revenue from better pricing and demand decisions, and losses avoided through earlier detection.
Financial analytics work is common enough among data engineering specialists that 57 of the 86 firms profiled in the [Data Engineering Companies Index](/fintech-data-engineering/) list fintech experience, and 68 list analytics and BI capabilities - the harder part is finding a partner who can get a model into a production pipeline your finance team actually trusts, not just one who can build a proof of concept.
This guide covers:
- The four types of financial analytics and how they build on each other
- How to calculate ROI and make the business case to a finance-literate board
- The five highest-impact use cases, from cash flow forecasting to treasury optimization
- The data architecture and platform choices that support real-time analytics
- A phased implementation roadmap and an RFP evaluation checklist
## What is analytics in finance, and how does it differ from static reporting?
Analytics in finance replaces static, backward-looking spreadsheets with a live view of cash flow, risk, and performance that updates as new data arrives. Instead of waiting for a monthly close to find out a number moved, finance teams see the shift as it happens and have time to act on it.
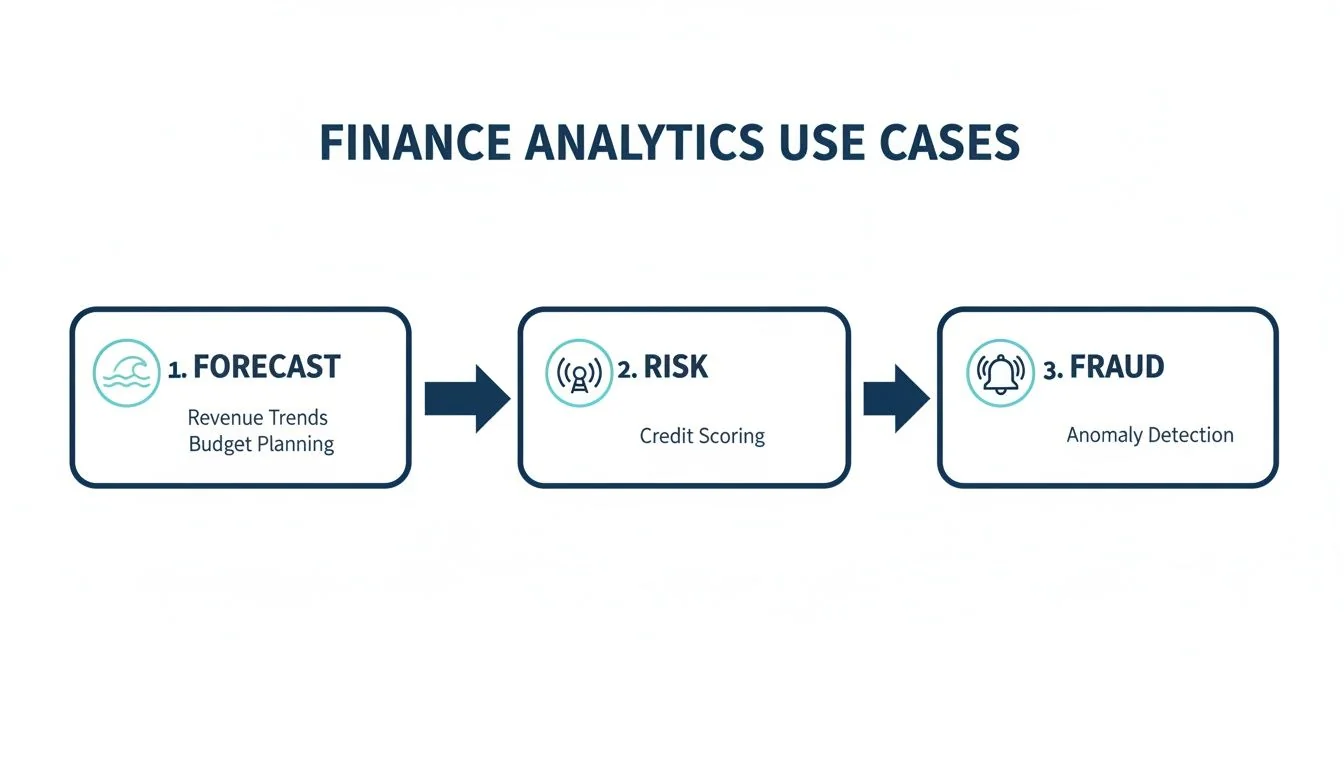
A static report tells you what happened last month. Analytics layers context, speed, and forecasting on top of that same data, turning historical numbers into a forward-looking view - a stress test that used to take days of manual spreadsheet work can run in minutes, giving teams time to reallocate budget before a demand shift actually hits.
## What are the four types of financial analytics?
Financial analytics breaks into four layers, each building on the one before it: descriptive analytics explains what already happened, diagnostic analytics explains why, predictive analytics estimates what happens next, and prescriptive analytics recommends what to do about it.
1. **Descriptive analytics** reviews past results - revenue, expenses, and variances against plan.
2. **Diagnostic analytics** digs into root causes once a descriptive report flags a problem.
3. **Predictive analytics** forecasts likely outcomes using historical patterns and current signals.
4. **Prescriptive analytics** recommends a specific action, not just a forecast.
Most finance teams already do descriptive and diagnostic work in spreadsheets. The jump that actually changes decision-making is predictive and prescriptive analytics, which requires a data pipeline stable enough to feed a model reliably - see our [modern data stack framework](https://dataengineeringcompanies.com/insights/modern-data-stack/) for how the underlying infrastructure supports each layer.
### Key takeaways
- Start with descriptive reviews to anchor a shared understanding of the numbers
- Use diagnostic checks to pinpoint the cause before proposing a fix
- Use predictive models for planning, not just historical reporting
- Apply prescriptive recommendations only once the first three layers are trustworthy
## How do you build the business case and calculate ROI?
Finance executives evaluate analytics projects in dollars, not feature lists. Tie every initiative to one of three outcomes: cost savings from automation, revenue uplift from better decisions, or risk reduction from earlier detection - then use NPV and IRR to compare projects the same way finance already compares any other capital request.
### Mapping initiatives to metrics
Document the data inputs, outputs, and resource requirements for each workflow so you can calculate a real cost per process instead of estimating one. A fraud detection pilot, for example, can be sized by comparing the dollar value of fraudulent charges it actually blocks against what it cost to build and run - use observed numbers from the pilot, not projected ones, when you present the case to the board.
### Scenario-based ROI
`ROI = (Total Benefits - Total Costs) / Total Costs`
Build three scenarios - best, expected, and worst case - so the range you present is realistic rather than a single optimistic number.
| Metric | Definition | What to track |
|---|---|---|
| Cost savings | Dollars saved through process automation | Hours removed from manual close and reporting work, converted to loaded labor cost |
| Revenue uplift | Additional income from analytics-informed pricing, cross-sell, or demand decisions | Incremental revenue attributable to a specific model, isolated from other initiatives running at the same time |
| Risk reduction | Losses avoided through earlier detection and tighter compliance | Change in confirmed fraud or credit losses measured against your own pre-analytics baseline |
There's no universal benchmark for what these numbers should be - they vary by industry, process, and how the workflow was measured before. Track leading indicators (faster reports) alongside lagging indicators (actual dollars saved) so early wins have something concrete behind them by the time you report on ROI.
Your own before-and-after numbers will carry more weight with your board than an industry-wide estimate.
## What are the highest-impact use cases?
Financial analytics delivers measurable value across five recurring use cases: cash flow forecasting, risk analytics, real-time fraud detection, performance dashboards, and treasury optimization. Each one replaces a periodic, manual process with a continuous, model-driven one.
### Cash flow forecasting
Cash flow forecasting models near-term liquidity from receivables, payables, and expected transaction volume, replacing static month-end snapshots with a rolling view that updates as new transactions post. Working-capital-intensive businesses like retailers use optimistic, base, and pessimistic scenarios to stress-test liquidity before a cash crunch happens, not after.
### Risk analytics
Risk analytics applies probabilistic models to credit, market, and operational exposure instead of relying on static credit scores or a scheduled annual review. A bank running dynamic stress-testing can reassess exposure as market conditions shift in real time, rather than discovering the impact at the next quarterly cycle.
| Use case | What it does | Primary benefit |
|---|---|---|
| Cash flow forecasting | Projects future liquidity needs from live transaction data | Reduces working capital tied up in receivables and payables |
| Risk analytics | Runs probabilistic scenarios against credit and market exposure | Surfaces risk earlier than a scheduled review would |
| Fraud detection | Scores transactions in real time using behavioral signals | Cuts fraud losses and reduces false positives sent to analysts |
| Performance dashboards | Visualizes revenue, expense, and KPI data continuously | Shortens the time between a number changing and a decision |
| Treasury optimization | Fine-tunes liquidity, funding, and hedging decisions | Improves returns on cash and reduces FX exposure |
### Real-time fraud detection
Real-time fraud detection scores transactions as they happen using behavioral and network signals, rather than static rule lists, and routes only the highest-risk transactions to a human analyst. That shift - from reviewing everything to reviewing what the model actually flags - is what lets a fraud team handle rising transaction volume without adding headcount at the same rate.
### Performance dashboards
Performance dashboards replace static monthly decks with a live view of revenue, expenses, and KPIs that updates as transactions post, so review meetings focus on deciding what to do about a number instead of debating whether it's current. For a deeper comparison of BI and dashboard tooling, see [BI software comparison](/insights/bi-software-comparison/).
### Treasury optimization
Treasury optimization uses forward-looking cash, FX, and interest rate forecasts to decide where to hold funds and when to hedge, instead of managing liquidity off a static monthly report. Manufacturers carrying debt across multiple currencies and rate structures use this approach to time refinancing and hedging decisions ahead of a rate move, not in reaction to one.
Across all five use cases, the constant is a data pipeline reliable enough that finance trusts the number without double-checking it in a spreadsheet first.
## What does the data architecture behind financial analytics look like?
Data architecture is the infrastructure that moves raw figures from source systems into a form analysts and models can actually use, without slowing down or corrupting the live reports finance already depends on.
### Pipeline components
- Raw data ingestion from ERP, CRM, and market data sources
- ETL processes that cleanse and transform data before it reaches analysts
- Data lakes for structured tables and unstructured logs alike
- Analytics sandboxes for rapid model prototyping without touching production data
### Structured vs. unstructured data
Combine schema-on-write for financial tables, where structure and accuracy matter most, with schema-on-read for logs and unstructured sources. Cloud platforms let you scale storage and compute independently, so a spike in log volume doesn't force you to over-provision the compute used for structured financial reporting.
### Platform comparison
| Feature | Snowflake | Databricks |
|---|---|---|
| Compute elasticity | Auto-scale and auto-suspend warehouses | Dynamic clusters and pools |
| Data processing | SQL-based ELT | Apache Spark for ETL and ML |
| Concurrency | Dedicated compute per warehouse | Shared compute across workloads |
| Cost model | Per-second billing | DBUs plus compute usage |
Match the platform to your peak load pattern and budget model rather than picking on brand recognition alone - see [Snowflake's warehouse documentation](https://docs.snowflake.com/en/user-guide/warehouses-overview) and [Databricks' compute documentation](https://docs.databricks.com/en/compute/index.html) for how each handles scaling in practice.
### Quality and governance
Data quality and lineage determine whether anyone actually trusts the numbers coming out of the pipeline. Trace each figure back to its source and every transformation it went through, and embed validation checks at the start of the pipeline rather than after a bad number has already reached a dashboard. For a fuller framework, see [data governance consulting](/insights/data-governance-consulting/).

- Document data flows and monitor pipeline health continuously
- Implement access controls so the environment holds up under an audit
- Revisit the architecture as reporting and compliance needs evolve
## How do you roll out financial analytics without a failed pilot?
A phased rollout breaks the project into four stages - discovery, proof of concept, pilot deployment, and enterprise rollout - so architecture and tooling decisions get tested on a small scale before they're locked in for the whole organization.
### Phase details
| Phase | Duration | Deliverables |
|---|---|---|
| Discovery | 2-4 weeks | Data inventory, use-case list, project charter |
| POC | 4-8 weeks | Prototype models, KPI dashboard, stakeholder feedback |
| Pilot | 6-12 weeks | Live integration, performance baselines |
| Rollout | 3-6 months | Training, change management, ongoing support |
Define data stewards and approval workflows during discovery, not after the pilot, and confirm early how the architecture will satisfy SOX, GDPR, or whatever compliance regime applies to your data.
### Cost and engagement models
Compare three ways to staff the work:
1. In-house team, using existing staff and institutional knowledge
2. External consultant, for a faster ramp-up on unfamiliar tooling
3. Hybrid, pairing internal staff with specialist support where the gap actually is
Key cost drivers are storage and compute, personnel, software licenses, and training - model each scenario against your actual budget rather than a generic industry estimate.
### RFP evaluation
Evaluate vendors against a consistent set of criteria:
| Criterion | What to assess |
|---|---|
| Performance | Query times and concurrency at peak volume |
| Scalability | How the platform handles growing data and user load |
| Support | SLA terms and escalation paths |
| Pricing | List rates, discounts, and any hidden fees |
| Governance | Security certifications and audit support |
Weight each criterion, request client references, and compare total cost over a 3-5 year horizon rather than the first-year quote alone. For a structured starting point, see our [data engineering RFP checklist](https://dataengineeringcompanies.com/data-engineering-rfp-checklist/).
Keep the vendor relationship active with regular updates, live demos, and feedback loops after go-live, and track adoption rates, data quality scores, and time-to-insight to know whether the rollout is actually working.
## FAQ
**Q: How does analytics in finance differ from static reporting?**
A: Analytics gives finance teams a continuously updated view of cash flow and emerging risk, so budget adjustments happen in hours instead of waiting for the next reporting cycle. See "What is analytics in finance" above.
**Q: How do I build a business case?**
A: Link each initiative to cost savings, revenue uplift, or risk reduction, model best, expected, and worst-case scenarios, apply the ROI formula, and use your own pilot numbers rather than industry benchmarks. See "How do you build the business case and calculate ROI."
**Q: What data foundation supports real-time analytics?**
A: A hybrid schema-on-write and schema-on-read approach that supports both streaming ingestion and structured financial reporting. See "What does the data architecture behind financial analytics look like."
**Q: How do I enforce governance and compliance?**
A: Assign data stewards, establish approval workflows during discovery, maintain audit trails, and use policy-as-code tools to enforce access permissions. See "How do you roll out financial analytics without a failed pilot."
Once you've scoped the use case and the architecture, the [data engineering RFP checklist](https://dataengineeringcompanies.com/data-engineering-rfp-checklist/) and [modern data stack framework](https://dataengineeringcompanies.com/insights/modern-data-stack/) are the next two stops for vetting a build partner.
---
## A Leader's Guide to Apache Spark Optimization: Moving Beyond Quick Fixes
Source: https://dataengineeringcompanies.com/insights/apache-spark-optimization/
Published: 2026-03-18T08:35:15.761045+00:00
Description: A practical framework for Apache Spark optimization: diagnosing the real bottleneck, tuning shuffle partitions and executor sizing, and choosing code fixes that cut runtime and cloud cost.
Apache Spark optimization is rarely a coding problem first. Most slow or expensive jobs trace back to one of four bottlenecks - CPU, memory, I/O, or network shuffle - and the fix is usually a configuration or architecture change, not a rewrite. This guide covers how to diagnose which bottleneck you actually have, the configuration and code changes that address each one, and when the problem has outgrown what an internal team can fix alone.
That diagnosis work matters more on managed platforms like [Databricks](https://www.databricks.com/) or AWS EMR, where a badly tuned job burns compute credits every hour it runs. Spark tuning is common enough among data engineering specialists that 64 of the 86 firms profiled in the [Data Engineering Companies Index](https://dataengineeringcompanies.com/databricks-consulting/) list Databricks capability - a rough proxy for who has actually done this kind of tuning work at scale, since Databricks is built on Spark.
## Why Are Slow Spark Jobs an Architectural Problem?
A single slow or failing Spark job is rarely just a bug - it's usually a symptom of misaligned platform configuration or accumulated architectural debt that will keep costing money until someone fixes the root cause instead of the symptom. Treating it as a one-off wastes the lesson.
For an engineering leader, the goal isn't to fix one job. It's a resilient, cost-effective Spark ecosystem, which means moving from tactical troubleshooting toward strategic platform management. Three disciplines make that shift possible:
* **Establishing performance baselines.** You can't improve what you don't measure. Benchmarking jobs defines what "good" looks like for your workloads, turning optimization from guesswork into an evidence-based process.
* **Implementing governance.** Set clear standards for code quality, mandate efficient data formats (Delta, Parquet), and establish rules for resource allocation.
* **Running architectural reviews on a cadence.** Data layouts, partitioning strategies, and cluster configurations need periodic reassessment. The architecture that worked a year ago is often wrong for today's data volume and velocity.
This shift turns Apache Spark optimization from a developer-level task into an architectural discipline, and it's the only way to keep the long-term cost of your data engineering function under control.
> For an engineering leader, every slow Spark job is a question about the platform's architecture. The answer is never just "more memory"; it's about building a system where performance is a feature, not a constant battle.
## What's the Right Way to Diagnose a Spark Performance Bottleneck?
Diagnosis starts with evidence, not guesswork. A Spark application's performance rests on four pillars - CPU, memory, I/O, and network - and a bottleneck in one destabilizes the whole system, which is how a slow job turns into architectural debt and then a higher cloud bill.
Before changing a line of code, gather evidence from the [Spark UI](https://spark.apache.org/docs/latest/web-ui.html) and a cluster monitoring dashboard like [Ganglia](http://ganglia.info/). You're looking for clues that point to the actual bottleneck, not the first thing that looks slow.
> Any optimization effort without clear metrics is just a guessing game. The Spark UI is your command center; its event timeline, stage details, and executor statistics hold the keys to nearly every performance puzzle.
### Common Spark Bottlenecks and Diagnostic Signals
This framework connects observable symptoms to their underlying root cause, so the response is targeted instead of trial and error.
| Bottleneck Area | Common Symptoms | Key Metrics to Check (Spark UI & Logs) | Initial Remediation Step |
| :--- | :--- | :--- | :--- |
| **CPU** | Cluster CPUs are pinned at **100%**; jobs run slowly despite low I/O. | High `Executor CPU Time` vs. `Task Time`. Check for Python UDFs in the DAG visualization. | Refactor code to use Spark native functions instead of UDFs; simplify complex transformations. |
| **Memory** | Frequent, long **Garbage Collection (GC)** pauses reported in executor logs; `OutOfMemoryError` (OOM) exceptions. | `GC Time` metric in the Spark UI's Executors tab. High spill to disk. | Increase executor memory, tune GC settings, or repartition data to create smaller partitions. |
| **I/O** | Tasks spend most of their time in the `Input Size / Records` phase; low CPU utilization. | High `Task Deserialization Time` or `Shuffle Read Blocked Time`. Check data source format. | Convert data from JSON/CSV to a columnar format like [Parquet](https://parquet.apache.org/) or [ORC](https://orc.apache.org/) to enable predicate pushdown. |
| **Network (Shuffle)** | Massive `Shuffle Read/Write` data shown in the Stage details; many tasks seem to hang. | Skewed `Shuffle Read Size / Records` across tasks. Check the DAG for wide transformations. | Avoid `groupByKey` in favor of `reduceByKey`; apply salting techniques to correct data skew in joins. |
### The Four Suspects
* **CPU bottlenecks.** A constantly maxed-out CPU isn't a sign of efficiency - it often means the code is doing something Spark's Catalyst optimizer can't help with, like a Python UDF running complex logic, or transformations too heavy for the available compute.
* **Memory bottlenecks.** An `OutOfMemoryError` is the obvious signal, but long **Garbage Collection (GC)** pauses are the more common one. If executor logs show frequent GC activity, workers are spending more time managing memory than processing data, usually because partitions are too large to fit in memory or caching is inefficient.
* **I/O bottlenecks.** If a job spends most of its time reading data, the storage layer is the problem. Reading large text-based files like JSON or CSV is slow by nature. Switching to a columnar format like **Parquet** lets Spark read only the columns it needs and push filters down to the data source, cutting I/O substantially.
* **Network (shuffle) bottlenecks.** Shuffle is the most expensive operation in distributed computing. A large volume of shuffle read/write data in the Spark UI points to a major culprit: redistributing data across the network, triggered by wide transformations like `groupByKey` or joins on poorly distributed keys.
## Which Spark Configuration Changes Actually Cut Costs?
Spark's default settings are built for broad compatibility, not for your workload, so running on defaults is a direct path to overspending on cloud infrastructure. Configuration is the main lever for balancing a cluster's performance against its cost.
The highest-impact configurations are tied to executors, the worker processes that run tasks. The goal is to size and count executors so parallelism is maximized without stranding resources.
### Sizing Your Executors Correctly
Two mistakes cause most of the damage: too many small executors, or too few large ones. Small executors add JVM management overhead. Large executors cause long garbage collection pauses and reduce parallelism.
A reliable starting point, instead of guessing:
1. **Assign cores per executor.** The commonly recommended range is **4-6 cores** per executor - enough parallelism per worker without I/O contention or excessive GC overhead.
2. **Calculate executor memory.** Determine the memory required per core for your workload, then add roughly **10%** for overhead (JVM, Spark internal structures). For example, with 5 cores and tasks needing 4GB per core, a starting point is `(5 * 4GB) + ~2GB overhead`.
3. **Determine the number of executors.** Divide total available cluster cores by the cores assigned per executor. That's how many workers can run concurrently.
This calculation is a far more reliable baseline than any vendor default.
### Taming the Shuffle Partition Problem
The `spark.sql.shuffle.partitions` setting controls how many partitions a shuffle operation creates, and its default of **200** is almost never right for production workloads.
Getting this value wrong is expensive in both directions. Too many partitions adds scheduling overhead that outweighs the parallelism gained. Too few partitions creates oversized tasks that spill to disk and stall the whole stage. Tuning this one parameter, even by hand, is one of the most effective changes available before touching a line of code, per [Spark's own performance tuning documentation](https://spark.apache.org/docs/latest/sql-performance-tuning.html).
> **Key takeaway:** if a shuffle stage processes 1TB of data with the default 200 partitions, each task receives a 5GB partition, which is a recipe for memory spills. Overcorrecting to 10,000 partitions creates tiny 100MB chunks, and performance dies from scheduling overhead instead. The right number is workload-dependent and requires tuning.
Modern Spark versions include Adaptive Query Execution (AQE) to dynamically merge small partitions, but AQE is not a substitute for proper configuration - it performs best when it starts from a reasonable number. Setting a sane baseline for shuffle partitions is still a fundamental part of tuning.
## Which Code-Level Changes Deliver the Biggest Performance Gains?
A perfectly tuned cluster can't compensate for poorly written code. The largest performance gains come from coding practices that guide developers toward code Spark can actually optimize.
The most important rule: use the **DataFrame** and **Dataset** APIs and avoid low-level **Resilient Distributed Datasets (RDDs)**. RDDs are opaque to Spark's Catalyst Optimizer, so Spark just executes the code as written, inefficiencies and all. With DataFrames, Catalyst understands the intent behind the code and can rearrange the execution plan for maximum efficiency.
The same principle extends to storage. File format is a code-level decision with real performance consequences.
### Optimize Data Storage and Access
Spark's performance is limited by how fast it can read data. Two practices matter most for high-performance pipelines.
* **Use columnar formats.** Standardize on **Parquet** or **Delta Lake**. Row-based formats like CSV or JSON don't scale for large processing jobs. Columnar storage enables **predicate pushdown**, letting Spark read only the columns a query needs and filter at the source.
* **Partition your data.** Organize data into subdirectories based on a frequently filtered column (`date`, `country`) to enable **partition pruning**, where Spark skips entire directories that don't match a query's `WHERE` clause. This can cut read times from hours to minutes.
> A query scanning a petabyte-scale, non-partitioned JSON dataset will always be slow and expensive. The same query against a partitioned Parquet dataset might only need to read a few gigabytes. That's not a minor tweak - it's a fundamental architectural decision.
### Master Join Strategy Optimization
Joins are a primary cause of network shuffles, and controlling the join strategy matters more than almost any other code-level decision.
* **Shuffle sort-merge join.** Spark's default for joining large tables. It shuffles and sorts both datasets across the network before merging - reliable, but heavy on network and disk I/O.
* **Broadcast hash join.** The better strategy when one table is small enough to fit in each executor's memory. Spark broadcasts a copy of the small table to every node, so the join happens locally without shuffling the large table. The threshold is configurable via `spark.sql.autoBroadcastJoinThreshold`, which [defaults to 10MB](https://spark.apache.org/docs/latest/sql-performance-tuning.html).
You have to explicitly tell Spark to use a broadcast join with a hint: `broadcast(small_df)`. For join-heavy pipelines, this is often the single most effective code-level change available.
## How Do Catalyst and Adaptive Query Execution Actually Work?
High-performance Spark code is written to work with Spark's internal optimizers, not around them. Code is a high-level suggestion that two engines - the **Catalyst Optimizer** and **Adaptive Query Execution (AQE)** - deconstruct and rebuild for efficiency.
Using the DataFrame API matters because it's the language Catalyst understands. Submit DataFrame code, and Catalyst translates the logic, applies hundreds of optimization rules, and generates the most efficient physical execution plan it can find.
> Think of Catalyst as a grandmaster chess player. Your DataFrame code is the opening move. Catalyst calculates dozens of possibilities and chooses the sequence that leads to the fastest result. Handing it raw RDDs is like blindfolding the grandmaster - it can only follow the rigid path you've dictated.
### Catalyst Plans, AQE Adapts
Catalyst plans execution before a job runs. **Adaptive Query Execution (AQE)** makes adjustments during execution, reacting to the unpredictable shape of real-world data.
AQE's key runtime optimizations:
* **Dynamically coalescing partitions.** AQE automatically merges small, inefficient shuffle partitions into larger, more optimal chunks, reducing scheduling overhead.
* **Switching join strategies.** If AQE observes at runtime that one side of a planned sort-merge join is small enough for broadcast, it switches to the faster broadcast hash join on the fly.
* **Optimizing skewed joins.** AQE detects data skew where one partition is significantly larger than others, splits the oversized partition into smaller pieces, and distributes the work evenly so a single task doesn't bottleneck the whole stage.
These optimizers work best with well-structured data and clean code, not as a substitute for either. Modern table formats like [Databricks Delta Lake](https://dataengineeringcompanies.com/insights/databricks-delta-lake/) provide the statistics and structure Catalyst and AQE need to do this work well. The job of an engineering leader is to make sure teams build systems that work with these optimizers instead of against them.
## When Should You Bring in a Data Engineering Consultancy?
Internal optimization effort hits a ceiling eventually. When your best engineers are perpetually firefighting the same jobs instead of building new capability, or cloud costs keep climbing despite tuning work, it's time to bring in specialists.
That's a strategic decision, not an admission of failure - deep system optimization is a specialized discipline that takes experience across many workloads and platforms, including [Databricks](https://www.databricks.com/) and [AWS EMR](https://aws.amazon.com/emr/).
### Vetting Potential Partners for Spark Expertise
Databricks capability is a reasonable starting filter, since Databricks is built on Spark and most firms doing serious Spark tuning work list it: 64 of the 86 firms in the Data Engineering Companies Index do. That's a filter, not a guarantee - platform familiarity and hands-on tuning experience aren't the same thing, so the vetting has to go further than a capability tag.
> A great consultant doesn't just tune your job; they diagnose the systemic platform issues that are causing the poor performance in the first place. They should leave you with not just a faster job, but a playbook to stop these problems from happening again.
Our guide on selecting a [Databricks consulting partner](https://dataengineeringcompanies.com/databricks-consulting/) covers the vetting process in more depth, and [data pipeline monitoring tools](https://dataengineeringcompanies.com/insights/data-pipeline-monitoring-tools/) is a useful companion read for what "ongoing" tuning should actually look like once a partner hands the system back to you.
### Evaluation Checklist for Spark Optimization Partners
Use this checklist during discovery calls to identify real expertise.
* **Benchmarking methodology.** "Describe your process for benchmarking our current Spark jobs. What specific metrics do you use to establish a baseline before beginning optimization?"
* **Large-scale tuning experience.** "Describe a time you optimized a terabyte-scale Spark job. What was the root bottleneck, what steps did you take, and what were the measurable improvements in runtime and cost?"
* **Cost optimization track record.** "How do you connect performance tuning directly to cloud cost savings? Share a case study where you reduced a client's Databricks or EMR bill through optimization alone."
* **Tooling and diagnostics.** "What diagnostic tools do you use beyond the Spark UI? How do you analyze executor logs and JVM garbage collection issues at scale?"
## Frequently Asked Questions About Spark Optimization
### What Is the First Thing to Check for a Slow Spark Job?
Start with the **Stages** tab in the Spark UI - it's the primary diagnostic dashboard. Look for stages with long runtimes, high volumes of **shuffle read/write** data, or significant **task skew**, where a few tasks take much longer than others. That view will quickly point to an I/O, network shuffle, or compute-bound problem.
### How Does Adaptive Query Execution Change Tuning?
**Adaptive Query Execution (AQE)** acts as an automated tuning assistant, merging small shuffle partitions and mitigating data skew in joins at runtime, which reduces the need to hand-tune parameters like `spark.sql.shuffle.partitions`. It can't fix fundamental architectural flaws, though. If source data is poorly partitioned, code is inefficient, or the cluster is wrongly sized, AQE only buys marginal improvement.
### When Should I Use a UDF in Spark?
Treat a User-Defined Function (**UDF**) as a last resort, used only when the logic isn't available as a built-in Spark function. Python UDFs are performance killers because they break Spark's ability to optimize the end-to-end query plan and add serialization overhead between the JVM and a Python process. Native Spark functions are almost always the more performant choice.
---
Apache Spark optimization is a diagnosis problem before it's a tuning problem: find the actual bottleneck, fix the configuration or code that causes it, and only then decide whether the remaining gap needs outside help. If you're evaluating vendors for that outside help, the guide on [where to find data engineering companies](https://dataengineeringcompanies.com/insights/where-to-find-data-engineering-companies/) and the [Databricks consulting](https://dataengineeringcompanies.com/databricks-consulting/) directory are good places to compare vetted partners against the checklist above.
---
## A Practical Guide to the Modern Architecture of a Data Warehouse
Source: https://dataengineeringcompanies.com/insights/architecture-of-a-data-warehouse/
Published: 2026-02-03T08:57:17.201367+00:00
Description: Explore the modern architecture of a data warehouse. This guide breaks down core layers, cloud patterns, and how to build a scalable data foundation.
A data warehouse is not a scaled-up operational database. It is an analytical system built for one job: turning raw data into reliable, fast-to-query business insight. It holds historical and current data in a structure built for analysis, creating a single source of truth that keeps analytical workloads off the transactional systems the business runs on.
## What does a modern data warehouse architecture actually do?
A modern data warehouse sits at the center of an organization's analytical capability. It ingests data from disparate sources - CRMs, ERPs, application databases, event logs - and turns it into a queryable format. Of the 86 firms profiled in the [Data Engineering Companies Index](/snowflake-consulting/), 66 list Snowflake among the platforms they build this kind of architecture on.
Raw data from operational systems (Salesforce, PostgreSQL, and similar tools) is ingested, cleansed, standardized, and organized across logical layers. The structured result then flows out through BI dashboards, reporting tools, and data science platforms, so decision-makers can query and analyze it directly instead of waiting on a report cycle.
This architecture moves past passive storage into an active analytics engine. Its goal is a unified view of the business, built to handle complex analytical queries over large datasets without slowing down the source operational systems it draws from.
### Why are companies modernizing their data warehouse architecture?
Data volume keeps growing, and the business questions being asked of it keep getting more demanding. Legacy warehouses were built for scheduled reports, not for the kind of ad hoc, cross-system analysis that modern BI and AI/ML workloads require.
A modern architecture is designed to answer questions legacy systems struggle with:
* How does a customer's website interaction journey correlate with their long-term value?
* Which marketing channels generate the highest lifetime value customers, not just initial conversions?
* What are the hidden inefficiencies in the supply chain that only integrated historical data can surface?
> The value of a data warehouse lies not in data storage but in its structure. A well-designed architecture lets an organization use historical data to build predictive models, spot trends, and get ahead of operational issues instead of reacting to them.
### What architectural principle matters most in a modern warehouse?
Legacy, on-premise data warehouses were rigid, slow, and expensive to scale. Modern, cloud-native architectures are built on elasticity, efficiency, and separation of concerns - the same principles behind the [modern data stack](https://dataengineeringcompanies.com/insights/modern-data-stack/).
The single most important principle is the **separation of storage and compute**. An organization can scale how much data it stores independently from how much processing power it pays for. A large influx of data can be ingested and stored (scaling storage) without triggering the cost of a high-performance processing cluster until a complex query actually runs (scaling compute). That's what makes the model cost-efficient at scale.
## What are the core layers of a data warehouse?
A data warehouse is a multi-layered system, not one monolithic application. Each layer does a specific job in the data lifecycle, moving raw data toward business intelligence. Data flows through a series of zones where it gets cleansed, integrated, and structured for analysis - a value chain running from raw, unprocessed data at the source layer to refined, actionable insight at the presentation layer.
This diagram shows the basic data flow: ingestion from various sources, processing and storage inside the warehouse, and consumption by end-users through analytical tools.
### What sits in the data source layer?
This is the origination layer: every system that generates business-relevant data, spanning internal and external platforms.
Common data sources include:
* **Transactional Databases:** OLTP systems like [PostgreSQL](https://www.postgresql.org/) or MySQL that power core business applications and record daily operations.
* **Cloud Applications:** SaaS platforms such as [Salesforce](https://www.salesforce.com/) for CRM, Marketo for marketing automation, or Zendesk for customer support.
* **Logs and Events:** Machine-generated data from web servers, application logs, and IoT devices that capture user interactions, system errors, and other events.
Data in this layer is raw, often inconsistent, and spread across incompatible formats. The first challenge is simply establishing connectivity and extraction from each source.
### What happens in the staging and integration layer?
After extraction, data lands in a staging and integration layer - the first processing zone, where transformation begins. In modern architectures following an ELT (Extract, Load, Transform) pattern, raw data loads directly into a dedicated staging area inside the cloud data warehouse.
This layer buffers the analytical environment from the inconsistencies of source data. Most of the core data engineering work happens here: cleansing, deduplication, and standardization.
> Practical transformations in this layer include standardizing country codes (mapping "USA," "U.S.A.," and "United States" to a single canonical value) or enriching customer records by joining data from CRM and support ticket systems.
### What does the storage and modeling layer do?
This is the core of the data warehouse, where cleansed, integrated data sits for long-term analysis. Unlike a transactional database built for write operations, this layer is optimized for high-speed read access across large datasets.
Data gets structured with specific modeling techniques to keep queries fast. The goal is a structure that's intuitive for business users and computationally efficient for analytical tools, so queries come back in seconds instead of minutes.
### How do you model data in a data warehouse?
Data modeling structures raw data into fact tables (quantitative measures) and dimension tables (descriptive context) built for analytical queries. The most common approach, dimensional modeling, organizes these into a [star schema](https://dataengineeringcompanies.com/insights/snowflake-schema-and-star-schema/) for fast BI performance, or a snowflake schema when storage efficiency and normalized dimensions matter more than raw query speed.
Beyond picking a schema shape, three decisions determine whether a model holds up under real use:
* **Star vs. Snowflake Schema:** A star schema denormalizes dimension tables - wide, with some data repetition - to minimize joins and maximize query speed, making it the default for BI-facing analytics. A snowflake schema normalizes those same dimensions into smaller, related tables, trading query speed for reduced redundancy and easier long-term maintenance.
* **Defining the Grain:** Before building a fact table, the first decision is its grain - a precise statement of what a single row represents (one line item on an order, or a daily summary of sales per store). An ambiguous grain produces inconsistent metrics and erodes trust in the data. For more on this, see our guide on [data modeling techniques](https://dataengineeringcompanies.com/insights/data-modeling-techniques/).
* **Tracking Change with SCDs:** Attributes like a customer's address or a sales territory change over time. Slowly Changing Dimensions (SCDs) govern how that gets captured: Type 1 overwrites the old value, Type 2 adds a new row with an effective date to preserve history, and Type 3 adds a "previous value" column for direct before-and-after comparisons.
### What lives in the analytics and presentation layer?
This is the user-facing layer where data becomes business value. It's the set of tools and applications that analysts, data scientists, and business leaders use to interact with the data in the warehouse - submitting queries to the storage layer and visualizing what comes back.
Common components include:
1. **Business Intelligence (BI) Tools:** Platforms like [Tableau](https://www.tableau.com/), [Power BI](https://powerbi.microsoft.com/en-us/), or Looker, which provide interactive dashboards and data visualization.
2. **Reporting Applications:** Tools for generating static, standardized reports such as monthly sales summaries or quarterly financial statements.
3. **Data Science Platforms:** Environments like Jupyter Notebooks that let data scientists work with curated datasets to build predictive models and run statistical analysis.
How well this layer works is ultimately what the whole architecture gets measured against - how easily it lets people turn data into decisions.
### Core Data Warehouse Architectural Layers and Functions
| Layer | Core Function | Example Technologies & Processes |
| :--- | :--- | :--- |
| **Data Source** | The origination point for all raw business data. | Transactional databases (PostgreSQL, MySQL), SaaS apps (Salesforce), IoT sensors, logs. |
| **Staging & Integration** | A temporary holding and processing area for data cleansing, standardization, and integration. | Data ingestion tools (Fivetran, Airbyte), raw storage zones in a cloud warehouse (Snowflake, BigQuery). |
| **Storage & Modeling** | The central repository for cleaned, structured, and historically-tracked data optimized for analytics. | Cloud data warehouses (Snowflake, Redshift), data modeling (star/snowflake schemas), data marts. |
| **Analytics & Presentation** | The user-facing layer where data is queried, visualized, and consumed to generate insights. | BI tools (Tableau, Power BI), reporting software, machine learning platforms (Jupyter). |
Each layer builds on the one before it, forming a data pipeline that turns raw operational data into a usable business asset.
## How do you choose the right data warehouse architectural blueprint?
Picking a data warehouse architecture is a strategic decision, not just a technical one. There's no universally "best" design - the right choice depends on organizational scale, data latency requirements, and long-term data strategy. Whatever blueprint you pick will shape how data gets organized, accessed, and governed for years afterward.
Base this decision on an honest read of business needs, not on industry trends. A startup's requirements for agile marketing analytics look nothing like a multinational's requirements for governed financial reporting.

### Kimball or Inmon: which modeling approach fits?
Modern cloud architectures are built on two classical methodologies that are still relevant today.
The **Kimball method**, developed by Ralph Kimball, is a "bottom-up" approach focused on getting business value out fast. It builds discrete, business-process-oriented **data marts**, typically using a **star schema** - a design with a central fact table (quantitative measures like sales revenue) surrounded by dimension tables (contextual attributes like customer, product, and date).
* **Pros:** Intuitive for business users and optimized for fast BI queries. Supports incremental development, so teams can deliver analytics for specific departments quickly.
* **Cons:** Integrating data across different data marts can get complex, and without strong governance it can lead to data silos or inconsistencies.
The **Inmon method**, developed by Bill Inmon, is a "top-down" approach. It starts with a centralized, normalized, enterprise-wide data warehouse as the single source of truth, with department-specific data marts derived from that central repository afterward.
* **Pros:** This "hub-and-spoke" model keeps data integrity and consistency high across the enterprise and reduces redundancy.
* **Cons:** Requires significant upfront planning and data modeling, which makes the initial build slower and more resource-intensive than the Kimball approach.
> In practice, many implementations are hybrids: a normalized, Inmon-style central data store for enterprise-wide governance, exposing data to business users through Kimball-style star schema data marts for performance and ease of use.
### Lakehouse or data mesh: which cloud pattern fits?
Two dominant patterns have emerged to handle data volume and variety in the cloud.
The **Lakehouse** architecture merges the low-cost, flexible storage of a data lake with the performance and transactional reliability of a data warehouse. Instead of maintaining separate systems, a Lakehouse runs BI and analytics directly on data stored in open formats (Apache Iceberg, Delta Lake) inside the data lake. It fits organizations that want to unify their data platform and support both traditional BI and AI/ML workloads on the same data, cutting duplication and architectural complexity. See our guide on [what a Lakehouse architecture is](https://dataengineeringcompanies.com/insights/what-is-lakehouse-architecture/) for more detail.
The **Data Mesh** is an organizational and technical model for decentralizing data ownership, meant to remove the bottleneck of a single central data team. It treats data as a product and applies domain-driven design to analytics.
* **Decentralized Ownership:** Business domains (marketing, finance, and so on) own their data end-to-end.
* **Data as a Product:** Each domain delivers reliable data products that other domains can consume.
* **Self-Serve Infrastructure:** A central platform team builds the tools and infrastructure that let domain teams manage their own data products.
* **Federated Governance:** A shared set of standards keeps data products interoperable, secure, and compliant.
This fits large, complex organizations where a centralized model gets in the way of speed. It puts data ownership in the hands of the teams that actually understand the domain.
## Cloud or on-premise: how do you decide?
The deployment model for a data warehouse - cloud or on-premise - is a fundamental architectural choice with real consequences for cost, scalability, and operations.
The industry trend runs strongly toward cloud, but on-premise deployments remain common in organizations with strict security or regulatory constraints, especially where data residency rules limit where data can physically sit. The shift toward cloud has also driven the rise of ELT, since cloud platforms have the compute power to run transformations in-database. For more, see these [data warehouse best practices from Estuary](https://estuary.dev/data-warehouse-best-practices/).
Weighing the two requires an honest look at the practical trade-offs.
### How do the cost models compare?
The financial models work in opposite directions.
An on-premise deployment is a **Capital Expenditure (CapEx)**. It requires a large upfront investment in servers, storage, networking hardware, and data center space. That gives a predictable, fixed cost, but it also creates a high barrier to entry and locks the organization into hardware with a limited useful life.
Cloud data warehouses run on an **Operational Expenditure (OpEx)** model. Organizations pay a recurring bill based on what they actually use (storage and compute). That removes the need for a large capital outlay, which is why advanced analytics is now accessible to companies that couldn't have justified the on-premise capital project.
### How does scalability compare between the two?
This is where the two models diverge most.
On-premise systems have fixed capacity. Scaling to meet peak demand - end-of-quarter reporting, for example - means a slow, expensive hardware procurement cycle. That forces organizations to provision for the worst case, which leaves resources sitting idle most of the time.
Cloud platforms offer **elastic scalability**. Compute can be provisioned on demand for intensive workloads and de-provisioned once the job is done, made possible by the architectural separation of storage and compute. Organizations pay only for what they actually consume, when they consume it.
> A practical benefit is workload isolation. A finance team can run resource-intensive month-end reports without slowing down real-time marketing dashboards, since each workload can get its own dedicated compute cluster.
### Who's responsible for security in each model?
The security model shifts from full control to a shared, specialized partnership.
With an on-premise warehouse, the organization owns **total responsibility** for security - physical data center access, network firewalls, user access controls, all of it. That level of control is often a requirement in regulated sectors like government, healthcare, and finance.
Cloud providers run on a **shared responsibility model**. The provider ([AWS](https://aws.amazon.com/), [Google Cloud](https://cloud.google.com/), [Microsoft Azure](https://azure.microsoft.com/)) secures the underlying infrastructure. The customer secures their data *within* the cloud through access controls, encryption, and identity management. That means ceding some control, but major cloud providers bring security expertise and tooling that most individual organizations can't match on their own.
### Who handles maintenance in each model?
This determines who owns operational uptime.
An on-premise warehouse needs a dedicated in-house team for hardware management, software patching, backups, and incident response. That builds internal expertise, but it also carries real operational overhead and depends on the availability of specialized talent.
Cloud data warehouses are **managed services**. The provider handles the underlying infrastructure maintenance - provisioning, patching, system updates. That frees data engineers to spend their time on data modeling, query optimization, and the work that actually delivers business insight.
## How do you select a data engineering partner?
Picking the right technology is only part of a successful data warehouse implementation. The expertise of the team designing and building it matters just as much. Choosing a partner takes a rigorous look at their technical competence, architectural thinking, and track record.
A good partner combines deep technical knowledge with a practical sense of how to build data platforms that actually hold up. The wrong choice produces a brittle system that's hard to maintain and doesn't deliver on the business objectives it was built for.
### Why don't certifications alone tell you enough?
Certifications on platforms like [Snowflake](https://www.snowflake.com/en/), [Databricks](https://www.databricks.com/), or [BigQuery](https://cloud.google.com/bigquery) are a baseline signal of theoretical knowledge, but they don't substitute for hands-on experience.
Instead of asking "Are your engineers certified?" ask "Walk me through a project where you migrated a legacy on-premise warehouse to a cloud-native Lakehouse architecture." That reframes the conversation around demonstrated capability instead of credentials. A partner with real experience has worked through the messy, real-world complications that come with a project like that.
> An experienced partner understands platform-specific performance tuning, cost optimization, and the common implementation pitfalls that only show up through practice. That's what prevents cost overruns and technical debt down the line.
Ask for case studies and references from projects comparable to yours in scale, complexity, and industry.
### How do you evaluate a partner's architectural philosophy?
A strong partner acts as a strategic advisor, not an order-taker. During evaluation, present your proposed architecture and ask them to critique it - their response tells you a lot about their depth and their problem-solving approach.
Do they ask probing questions about your business objectives? Do they propose alternatives and explain the trade-offs? A partner who just accepts your initial design without pushback may not have the strategic depth to build something durable.
You want a team that thinks architecturally - one that can explain the reasoning behind different data modeling techniques, justify its technology choices, and design for growth rather than just for the current spec.
### Why does industry-specific expertise matter?
Every industry has its own data challenges: regulatory compliance in finance (SOX) and healthcare (HIPAA), supply chain complexity in manufacturing. A partner with experience in your vertical is a real advantage - they already know your domain's data sources, KPIs, and the rules that apply to it.
That industry knowledge speeds up the project and lowers risk:
* **Faster Onboarding:** They already understand your terminology and KPIs.
* **Reduced Risk:** They can design proactively for GDPR, HIPAA, or CCPA compliance requirements.
* **Higher Value:** They may flag industry-specific analytics or use cases you hadn't considered.
Ask for client references and case studies from your industry to check their domain expertise is real.
### How do you compare vendors objectively?
To keep the evaluation structured, use a vendor scorecard to compare potential partners against a consistent set of criteria. It gives you a documented, systematic way to score candidates and spot risks before you commit.
The table below is a template for that scorecard: key criteria, questions to ask, and red flags to watch for.
### Vendor Evaluation Scorecard for Data Engineering Partners
This scorecard helps you systematically assess data engineering firms for a fair, thorough comparison.
| Evaluation Criterion | Key Questions to Ask | Red Flags to Watch For |
| :--- | :--- | :--- |
| **Technical Expertise** | Can you walk us through a similar Lakehouse migration project? What were the key challenges and how did you solve them? | Vague answers, heavy reliance on buzzwords, or an inability to discuss the technical trade-offs in detail. |
| **Industry Experience** | What is your experience with data compliance in our industry (HIPAA, GDPR)? Can you share specific examples? | Generic project stories that don't connect to your industry's specific data challenges or regulations. |
| **Project Methodology** | How do you manage project scope, budget, and timelines? What's your process for keeping stakeholders in the loop? | No clear, documented methodology; rigid processes that can't adapt when things change. |
| **Team Composition** | Who are the actual people who will be on our project? Can we review their experience and talk to them? | The bait-and-switch pattern: senior experts charm you in sales calls, then junior staff do the actual work. |
Working through these criteria methodically gets you a data-driven decision and a partner equipped to deliver on your architecture, not just talk about it.
## Common questions about data warehouse architecture
### What's the difference between a data warehouse and a data lake?
A **data warehouse** works like a library. It stores structured, processed, verified data (books) organized for a specific purpose: efficient querying and analysis. The data is clean, reliable, and ready to use.
A **data lake** works like a reservoir. It collects raw data in its native format from many sources, storing structured, semi-structured, and unstructured data (JSON files, images, logs) cheaply. That raw data has to be processed and refined before it's usable for most analytical purposes. Our guide on [data warehouse vs. data lake](https://dataengineeringcompanies.com/insights/data-warehouse-vs-data-lake/) covers this decision in more depth.
> The **Lakehouse** architecture aims to unify these two. It combines the low-cost, flexible storage of a data lake with the performance, reliability, and governance of a data warehouse, enabling direct analytical querying on raw data.
This hybrid model is becoming the default for modern cloud data platforms because it supports a wide range of workloads - from standard BI to machine learning - inside a single, unified architecture.
### When should you choose ELT over ETL?
The choice between ETL and ELT mostly comes down to the computational power of the target system.
**ELT (Extract, Load, Transform)** is the standard approach for modern, massively parallel processing (MPP) cloud data warehouses like [Snowflake](https://www.snowflake.com/en/), [Google BigQuery](https://cloud.google.com/bigquery), or [Amazon Redshift](https://aws.amazon.com/redshift/). These platforms have enough compute power to run complex transformations in-database more efficiently than a separate transformation engine could.
* **Key Advantage:** Flexibility. Raw data loads quickly, and transformations can be built and changed later without re-ingesting the source data - useful as business requirements shift.
**ETL (Extract, Transform, Load)** still matters in specific scenarios: when the target database doesn't have the power to transform data efficiently, or for compliance use cases where sensitive data has to be anonymized or masked *before* it lands in the central repository.
### How do you build a warehouse that still works when AI and ML workloads show up?
Preparing for future AI and machine learning workloads is less about picking specific tools and more about getting the foundations right. High-quality, accessible data is the prerequisite for any AI initiative that's going to work.
Three architectural concepts matter most:
1. **Separate Storage and Compute:** Decoupling these resources lets you provision large compute clusters for model training elastically, without disrupting concurrent BI workloads - scaling up for training and back down once it's done, to keep costs in check.
2. **Embrace a Lakehouse Pattern:** Data scientists need access to both raw, exploratory data and clean, feature-engineered data. A Lakehouse architecture gives them a single environment covering the full range of data needed for model development.
3. **Prioritize Data Governance and Cataloging:** An AI model is only as good as its training data. Solid data governance, automated data quality checks, and a real data catalog are what make an AI system trustworthy rather than a black box.
Get these three right and the same foundation supports both current analytical needs and whatever AI workload shows up next.
## Putting the architecture decision into practice
The layers, the Kimball/Inmon choice, the cloud-versus-on-premise trade-offs - these decisions compound. A staging layer built without clear ownership creates rework once the storage layer is designed; a schema chosen for query speed today can turn into a maintenance burden once five more data marts get built on top of it. Get the early layers right and the rest of the architecture gets easier to build, not harder.
If you're weighing lake versus warehouse from scratch, start with [data warehouse vs. data lake](https://dataengineeringcompanies.com/insights/data-warehouse-vs-data-lake/); if you're further along and choosing between a fresh build and an existing platform, [what is a data platform](https://dataengineeringcompanies.com/insights/what-is-a-data-platform/) covers that distinction. And whichever architecture you land on, the vendor scorecard above works just as well against the [firms in the Index](https://dataengineeringcompanies.com/data-engineering-consulting-firms/) as it does in a live vendor call - ask each one to critique your proposed design before you sign anything.
---
## AWS vs. Azure Data Partners: Choosing Your Cloud Ecosystem in 2026
Source: https://dataengineeringcompanies.com/insights/aws-vs-azure-data-partners/
Published: 2025-12-19T00:00:00.000Z
Description: Should you hire an AWS-native partner or an Azure specialist? We compare the data ecosystems, partner certifications, and multi-cloud strategies.
AWS partners fit teams building customer-facing data products who want granular engineering control. Azure partners fit organizations already centered on Microsoft tools (365, Active Directory, Power BI) who want single-vendor integration. Of the 86 firms profiled in the Data Engineering Companies Index, 76 list AWS and 70 list Azure among their platforms - most serious partners support both, but they specialize in one.
The 30-Second Verdict
Hire an Azure partner if: You are a "Microsoft shop" (Office 365, Active Directory, Power BI). Azure Data Factory + Synapse + Power BI integrate more tightly than a comparable AWS stack, which matters most in corporate IT environments. Look for the "Solutions Partner for Data & AI" badge.
Hire an AWS partner if: You are building customer-facing data products or engineering platforms that need fine-grained control. AWS offers more granular tooling (Glue, EMR, Redshift, Lambda), which startup-style engineering teams tend to prefer. Look for "AWS Data & Analytics Competency" holders.
The multi-cloud reality: Most enterprises run Azure for internal corporate data (finance, HR) and AWS for customer-facing product data. Hire a partner who understands networking and egress costs between the two, explored in our modern data stack guide.
## Which AWS or Azure migration pathway fits your current stack?
Your starting database usually decides the partner track: SQL Server shops move to Azure via Fabric or Synapse, Oracle migrations land on AWS Redshift through SCT and DMS, and customer-facing Postgres apps move through AWS Glue into Athena or Iceberg.
### Pathway A: the Microsoft loyalist (SQL Server to Azure Fabric)
If your company runs on .NET, SQL Server, and Office 365, don't fight that current.
* **The move:** Migrate on-prem SQL Server to **Azure SQL** or **Synapse** (now evolving into **Microsoft Fabric**).
* **The partner you need:** An Azure "Solutions Partner for Data & AI" who specializes in **T-SQL refactoring**.
* **Why:** Azure offers "Hybrid Benefit" licensing discounts for existing SQL Server customers, which meaningfully lowers migration cost.
### Pathway B: the Oracle refugee (Oracle to AWS Redshift/Snowflake)
If you're fleeing expensive Oracle licenses, AWS is the traditional landing zone.
* **The move:** Use **AWS SCT (Schema Conversion Tool)** and **DMS (Database Migration Service)** to move data to Redshift or S3.
* **The partner you need:** An "AWS Advanced Consulting Partner" with the **Migration Competency**.
* **Why:** AWS has the most mature tooling for migrating between heterogeneous database engines.
### Pathway C: the data product builder (Postgres to the AWS modern data stack)
If you're building a customer-facing app: RDS (Postgres) to AWS Glue to Athena/Iceberg. The partner you need is a [modern data stack](/insights/modern-data-stack/) boutique, often dbt-core focused.
## What is Microsoft Fabric, and how does it compare to the modern data stack?
Microsoft Fabric is a unified SaaS layer that wraps Synapse, Data Factory, and Power BI into one login and one governance model (OneLake), aiming to end the fragmented-stack problem. The AWS-centered alternative - Snowflake or dbt plus a tool like Fivetran - trades that convenience for looser integration but fewer lock-in points.
### Fabric vs. modern data stack: a decision matrix
| Feature | Microsoft Fabric (Azure) | Modern Data Stack (AWS + Snowflake/dbt) |
| :--- | :--- | :--- |
| **Integration** | Tight. One login for everything. | Loose. Requires managing multiple contracts (Fivetran, dbt, Snowflake). |
| **Governance** | Centralized (OneLake). | Distributed. Harder to manage lineage across tools. |
| **Lock-in** | High. You are all-in on Microsoft. | Low. You can swap components (e.g., swap Fivetran for Airbyte). |
| **Best for** | Enterprise IT departments. | Product engineering teams. |
If you choose Fabric, hire a partner who is explicitly "Fabric Certified" - OneLake shortcuts are a different working model than traditional Synapse pipelines, and general Azure experience doesn't automatically transfer.
## Which cloud has stronger partners for streaming, ML, dashboards, and governance?
AWS partners lead on streaming and IoT work, where Kinesis and MSK are the default choice. Azure partners lead on machine learning (Azure ML plus OpenAI integration), dashboarding (Power BI), and governance (Purview) - the table below scores relative partner strength by capability.
| Capability | AWS Partner Strength | Azure Partner Strength |
| :--- | :--- | :--- |
| **Streaming/IoT** | 5/5 (Kinesis/MSK is the standard) | 3/5 (Event Hubs is capable but more complex to operate) |
| **Machine learning** | 4/5 (SageMaker is powerful but a distinct workflow) | 5/5 (Azure ML + OpenAI integration leads the market) |
| **Dashboarding** | 2/5 (QuickSight lags the category) | 5/5 (Power BI leads the category) |
| **Governance** | 3/5 (DataZone is improving) | 5/5 (Purview is the enterprise standard) |
## How do enterprises split data work between AWS and Azure?
Most Fortune 500s run Azure for corporate data (finance, HR, ERP) feeding Power BI, and AWS for product data (clickstream, logs, app backends). The hardest part is hiring a partner who can build the bridge between the two without racking up egress costs.
Look for partners with **Databricks** or **Snowflake** expertise - these tools run identically on both clouds and act as a neutral layer, letting data move between environments via Iceberg or Delta Sharing without the egress fees a direct cloud-to-cloud transfer would incur.
## Which AWS and Azure partner certifications actually matter?
For AWS, the "Data & Analytics Competency" (which requires audited case studies) and the "Migration Competency" matter most, alongside Professional-level certifications rather than Associate-level ones. For Azure, the "Solutions Partner for Data & AI" designation and the "Advanced Specialization - Analytics on Azure" carry the most weight.
### AWS badges that matter
* **"Data & Analytics Competency":** The top tier. Requires audited case studies.
* **"Migration Competency":** Important if you're moving large on-prem estates.
* **Professional-level certs:** Look for "Pro" level certifications (e.g., Solutions Architect Professional), not just Associate.
### Azure badges that matter
* **"Solutions Partner for Data & AI":** Replaced the older Gold/Silver competency system.
* **"Advanced Specialization - Analytics on Azure":** The top tier for data warehousing work.
## Conclusion
Choose an **AWS partner** listed on our [AWS data engineering partner directory](/aws-data-engineering/) if you want granular control and open-source affinity. Choose an **Azure partner** from our [Azure data engineering directory](/azure-data-engineering/) if you want tight integration with an existing Microsoft estate and Power BI as the center of gravity. Choose a cross-cloud partner with Snowflake or Databricks depth if your job is bridging the two.
---
## Your Practical Guide to BI Consulting Services
Source: https://dataengineeringcompanies.com/insights/bi-consulting-services/
Published: 2026-01-15T09:04:52.397599+00:00
Description: A practical guide to BI consulting services: what they cost, how engagements are structured, how to select a vendor, and the red flags to watch for.
BI consulting services turn raw data into decisions a business can act on: a consultant maps business goals to a data strategy, builds the warehouse and pipelines underneath it, and ships dashboards that get used instead of ignored. The job is a business function that happens to use technology, not an IT project with a business veneer.
Analytics and BI work is common ground for data engineering firms - 68 of the 86 firms profiled in the [Data Engineering Companies Index](/analytics-consulting/) list it among their capabilities - but a finished dashboard and a working BI strategy are not the same deliverable, and treating them as interchangeable is where most engagements go sideways.
This guide covers what these services entail, how to structure an engagement, and how to select a partner that delivers results instead of slide decks.
## What Are BI Consulting Services?
BI consulting is a business function that uses technology to solve operational and strategic problems, not an IT project. A consultant's primary job is to translate business objectives into technical execution and make sure the right questions get asked before a single dashboard gets built.
Are you trying to increase customer lifetime value? Reduce supply chain costs? Optimize marketing spend? A competent consultant maps these goals to a concrete data strategy, which prevents the common failure mode: building something technically impressive that nobody in the business actually uses.
### The Bridge Between Data and Decisions
The most common failure mode for BI initiatives is treating them as technology rollouts. That produces expensive, underused platforms and reports that get ignored during the decisions they were supposed to inform.
> The core value of BI consulting isn't code or platform configuration. It's the strategic guidance that ensures data initiatives solve the *right* business problems. That's how data stops being a passive asset and starts driving growth and efficiency.
Without that strategic link, you get dashboards that look good and answer nothing. Consultants prevent this by focusing on adoption and tying every visualization to a KPI that drives a specific business action.
### Core Functions of a BI Consultant
Project specifics vary, but the work of a BI consultant follows a logical progression from strategy to execution, built to leave a durable data capability behind when the engagement ends. The goal is data that's accurate, relevant, and actually reachable by the people who need it.
* **Strategic Planning:** Aligning data projects with business objectives so the work has a clear return.
* **Technical Implementation:** Designing and building the infrastructure - [data warehouses](https://www.snowflake.com/guides/what-is-data-warehousing), ETL/ELT pipelines, and reporting systems.
* **Actionable Insights:** Developing analytics and dashboards that answer pressing business questions and inform daily operations.
* **Team Enablement and Training:** Equipping your team with the tools and skills for self-service analytics, so the data culture doesn't depend on the consultant staying on retainer.
Hiring a BI consultant is an investment in operational clarity - extracting specific, high-value answers from complex datasets, answers that directly influence business performance. They bring the technical expertise to build a reliable data foundation and the business judgment to make sure it gets used.
## What to Expect From a BI Consulting Partner
A BI consulting engagement moves you from reactive reporting to proactive, predictive decision-making through a defined sequence: strategy first, then architecture, pipelines, dashboards, and team enablement. Below is a breakdown of the core services you should expect.
The demand for this expertise reflects a real market trend, tracking a broader recognition that data is a core asset for competitive advantage.
A competent BI consultant acts as the direct link between raw data and business objectives.
As the diagram shows, without that strategic layer, data stays inert. The consulting expertise is what connects technical infrastructure to real-world value.
### Data Strategy and Roadmap Development
Before any technical work begins, a strong BI partner runs workshops with key stakeholders to answer two questions: what business challenges are we solving, and how will we measure success? The output is a roadmap that links every data initiative to a specific business outcome.
The output is not a theoretical document but a practical blueprint outlining priorities, timelines, and required resources - the most effective way to prevent costly investment in tools and projects that never deliver value.
### Data Warehouse and Lakehouse Architecture
With a clear strategy in place, the next step is designing the central repository for your data - a modern data warehouse or a flexible lakehouse, typically built on platforms like [Snowflake](https://www.snowflake.com/en/), [Databricks](https://www.databricks.com/), or [Microsoft Fabric](https://www.microsoft.com/en-us/microsoft-fabric).
This is the architectural plan for your entire data ecosystem. A well-designed foundation keeps your data organized, accessible, and scalable, and it's what prevents the "data swamp" problem, where information is technically stored but practically impossible to find, trust, or use.
### Modern ETL and ELT Pipeline Development
Your data is fragmented across CRMs, ERPs, marketing platforms, and spreadsheets. A major part of any BI project is building the pipelines that consolidate it.
Using ETL (Extract, Transform, Load) or ELT (Extract, Load, Transform) processes, these pipelines automate the movement, cleaning, standardization, and structuring of data - the plumbing that keeps a continuous flow of reliable data reaching decision-makers.
### Interactive Dashboard and Report Creation
This is the most visible output of a BI engagement. Using tools like [Power BI](https://powerbi.microsoft.com/en-us/), [Tableau](https://www.tableau.com/), or [Looker](https://www.looker.com/), consultants translate raw data into interactive analytical tools - the goal is intuitive, user-centric dashboards that answer real business questions at a glance, not static charts.
A sales director should be able to move from a national performance overview to a regional breakdown, down to an individual salesperson's activity, in seconds. Picking the right tool is a real decision; this [BI software comparison](https://dataengineeringcompanies.com/insights/bi-software-comparison/) is a practical starting point.
### Self-Service BI Enablement
The point of a successful BI engagement is to make the consultants unnecessary. A good firm doesn't just deliver a finished product; it leaves your team able to run analytics on its own.
> Self-service BI is more than software training; it's about building a data culture. That means clean, curated datasets, user-friendly data models, and ongoing coaching - so business users can query data independently instead of filing a ticket with IT every time.
This is where the long-term return shows up. Analytics shifts from an IT bottleneck to a distributed organizational capability.
### Data Governance and Security Frameworks
None of the above matters if your data is inconsistent, inaccurate, or insecure. Data governance sets the rules and processes that make data trustworthy and safe to act on.
A BI consultant helps implement this framework, which typically includes:
* **Data Dictionaries:** Making sure a term like "active customer" has one consistent definition across sales, marketing, and finance.
* **Access Controls:** [Permissions and role-based access](https://docs.snowflake.com/en/user-guide/security-access-control-overview) so sensitive data is only reachable by authorized people.
* **Quality Audits:** Automated checks that catch data errors before they reach a report.
This layer is what gives leadership the confidence to make high-stakes decisions based on the numbers in front of them - the final component of a complete BI ecosystem.
---
This table summarizes how these services combine to deliver business impact.
### BI Consulting Services Breakdown
| Service Offering | Primary Objective | Tangible Business Outcome |
| :--- | :--- | :--- |
| **Data Strategy & Roadmap** | Align data initiatives with business goals | A clear, actionable plan that prevents wasted effort and protects ROI. |
| **Warehouse/Lakehouse Architecture** | Build a scalable, centralized data foundation | A single source of truth that's fast, reliable, and durable. |
| **ETL/ELT Pipeline Development** | Automate the flow of clean, structured data | Consistent, high-quality data ready for analysis without manual work. |
| **Dashboard & Report Creation** | Visualize data to reveal actionable insights | Reports that answer key business questions and drive decisions. |
| **Self-Service BI Enablement** | Give business users the tools to find their own answers | Less reliance on IT and a more data-literate organization. |
| **Data Governance & Security** | Keep data accurate, consistent, and secure | More trust in the data and compliance with privacy regulations. |
Each service builds on the last, creating a system that turns raw data into a durable strategic asset.
## What Are the BI Consulting Engagement Models, and How Long Does a Project Take?
BI consulting engagements come in three structures: project-based (fixed scope, fixed price), retainer or managed services (ongoing capability), and staff augmentation (embedded expertise). Which one fits depends on whether you're buying an outcome, a capability, or a person - and getting that choice wrong is a budget problem, not a technical one.
The industry's shift to cloud-based BI has pushed engagement models toward more flexible, service-oriented structures.
### The Three Core Engagement Models
There are three primary ways to structure a BI consulting project, each suited to a different need - from outsourcing a specific outcome to embedding an expert inside your team.
1. **Project-Based Engagements**
The standard fixed-scope, fixed-timeline, fixed-price model. Appropriate when you have a well-defined objective, such as building a new executive dashboard or migrating data to [Snowflake](https://www.snowflake.com/en/). The firm is responsible for delivering a specific outcome.
This approach gives you budget predictability but limited flexibility if requirements change. It's a good fit for turnkey work with clearly defined parameters.
2. **Retainer or Managed Services**
This model is an ongoing partnership rather than a one-time project. You pay a recurring fee for a team that manages, maintains, and improves your BI environment - useful for organizations that need continuous expert support without hiring full-time staff.
A retainer works well for maturing your data capabilities, handling ad-hoc user requests, and keeping your BI platform current as the business changes. It prioritizes continuous improvement over a fixed end date.
3. **Staff Augmentation**
This model means "renting" an expert - a BI architect, data engineer, or [Power BI](https://powerbi.microsoft.com/en-us/) developer - who joins your team and works under your direction. Used to fill a specific skill gap or add capacity to a critical project.
Staff augmentation gives you the most control over day-to-day work and fits best when you have strong internal project leadership but lack specific technical expertise. You're not outsourcing the strategy; you're insourcing the talent to execute it.
> To be clear: a project-based model is about buying an outcome. A retainer is about buying ongoing capability. Staff augmentation is about buying expertise. Choose accordingly.
### How Long Should You Expect a BI Project to Take?
Project duration depends entirely on scope and complexity: a simple dashboard build runs weeks, a full platform migration can take the better part of a year. Setting realistic expectations up front matters more than the exact estimate.
Typical timelines for common BI initiatives:
* **Departmental Analytics Build:** A new dashboard suite for a single department (sales or marketing, for example) typically runs **6-10 weeks**, from requirements gathering to deployment.
* **Data Governance Framework Establishment:** A process-heavy initiative involving stakeholder workshops, metric definition, and policy work. Expect **3-6 months**.
* **Cloud Data Warehouse Migration:** Moving from an on-premise system to a cloud platform is a significant undertaking. Plan for **4-9 months** to cover assessment, architecture, migration, and testing.
These are starting points, not guarantees. Accurate scoping with your consulting partner is the single biggest factor in hitting deadlines and delivering value on schedule.
## How Much Do BI Consulting Services Cost?
BI consulting pricing depends on the required expertise, consultant location, and project complexity, not an arbitrary rate card. BI consulting is a slice of the broader global business management consulting industry, with the United States as the largest market and heavy competition among providers.
### Common Pricing Structures
Proposals typically use one of three pricing models.
* **Hourly Rates (Time & Materials):** You pay for actual hours worked. Offers maximum flexibility and suits projects with evolving requirements or a discovery phase.
* **Fixed-Price Projects:** For clearly scoped work, a fixed price gives you budget certainty. The firm commits to a specific outcome for a single, agreed-upon cost.
* **Blended Rates:** Many firms quote a single blended rate - an average across senior and junior consultants. Simplifies invoicing and can be a cost-effective way to access a mix of expertise.
> Match the pricing model to the project's nature. Use hourly rates for flexible, exploratory work. Insist on a fixed price for well-defined deliverables to control your budget.
### What Do BI Consultants Typically Charge by Region?
Geography is the primary driver of cost - a U.S.-based BI architect and an equivalent professional in Eastern Europe or Southeast Asia are not priced the same. Use the bands below as a benchmark when reviewing proposals, not a guarantee.
#### Typical BI Consultant Hourly Rate Bands
| Consultant Role | Onshore (US/CAN) | Nearshore (LATAM/Eastern Europe) | Offshore (India/SEA) |
| :--- | :--- | :--- | :--- |
| **BI Architect** | $175 - $275+ / hr | $90 - $140 / hr | $60 - $95 / hr |
| **Data Engineer** | $150 - $225 / hr | $80 - $130 / hr | $50 - $85 / hr |
| **Visualization Specialist** | $125 - $200 / hr | $70 - $110 / hr | $45 - $75 / hr |
These bands reflect local labor costs and market demand. Onshore teams offer time-zone alignment for high-collaboration work. Offshore teams offer a real cost advantage. Nearshore is often the balance between cost and logistical convenience.
### What Does a Typical BI Project Budget Look Like?
A 10-week project to build a sales analytics dashboard for a mid-sized company - integrating Salesforce and ERP data, building a unified data model, and shipping interactive reports in [Power BI](https://powerbi.microsoft.com/en-us/) - runs roughly **$75,600** at a blended onshore rate. Here's how that breaks down:
1. **Discovery & Planning (1 Week):** BI Architect and Visualization Specialist define requirements with your team. (~60 hours)
2. **Data Engineering & Modeling (4 Weeks):** Data Engineer builds data pipelines and the core data model. (~160 hours)
3. **Dashboard Development & UX (3 Weeks):** Visualization Specialist designs and builds the user-facing dashboards. (~120 hours)
4. **Testing & Deployment (2 Weeks):** The team runs user acceptance testing, makes adjustments, and rolls out the solution. (~80 hours)
**Total Estimated Hours:** 420
**Blended Onshore Rate:** ~$180/hour
**Estimated Project Cost:** ~$75,600
Scope and team composition are what actually move this number. For a more tailored estimate, a [data engineering cost calculator](https://dataengineeringcompanies.com/data-engineering-cost-calculator/) is a useful starting point for planning.
## How Do You Evaluate a BI Consulting Vendor?
Vet a BI consulting firm across four areas: technical expertise and platform certifications, verifiable industry experience, delivery methodology and communication, and cultural fit and scalability. A strong partner accelerates your path to value; a weak one creates technical debt, delays, and internal distrust of the data itself.
### Define the BI Business Case Before Comparing Firms
Set the baseline before asking a firm to propose a solution. For each proposed dashboard, model, or workflow, name the decision it supports, its current cost or delay, the owner of the outcome, and the measurement window. This stops activity metrics like dashboard count from being mistaken for business value.
Group expected value into three categories: revenue gained, operating cost reduced, and risk avoided. Require the proposal to state which category each deliverable supports and how you'll verify the result. If a benefit can't be measured directly, define a practical proxy - reporting cycle time, adoption by the intended team, or the number of reconciliations eliminated.
Once the business case is defined, move to a structured evaluation across the four areas below.
### Technical Expertise and Platform Certifications
Verify technical competence first - strategic advice means nothing without the ability to execute inside your specific stack. Ask direct, evidence-based questions and don't accept a vague claim of "expertise."
* **Platform Proficiency:** "What certifications does your team hold for our key platforms, such as [Power BI](https://powerbi.microsoft.com/en-us/), [Databricks](https://www.databricks.com/), or [Snowflake](https://www.snowflake.com/en/)?"
* **Architectural Depth:** "Describe a complex data architecture you designed for a client with a similar data ecosystem. What were the main technical challenges, and how did you resolve them?"
* **Modern Data Tooling:** "What's your approach to [data quality testing](https://docs.getdbt.com/docs/build/data-tests), automated testing, and CI/CD in BI projects? Which specific tools do you use?"
### Verifiable Industry Experience
Technical skill is necessary but not sufficient. A consultant with real experience in your industry - SaaS, manufacturing, healthcare - delivers value faster because they already understand your business context, key metrics, and regulatory constraints.
> A consultant with deep industry experience speaks your language from day one. They don't spend billable hours learning fundamental concepts like "customer churn" in SaaS or "inventory turnover" in retail. That domain knowledge is a real project accelerator.
* **Relevant Case Studies:** "Give us two or three detailed case studies from our vertical. What was the business problem, what was your solution, and what was the measurable ROI?"
* **Industry-Specific KPIs:** "For a company in our industry, what are the three most important KPIs you'd focus on first, and why?"
* **Domain Experts:** "Who on the proposed team has direct experience in our industry? Can we speak with them during evaluation?"
### Delivery Methodology and Communication
A technically sound solution can still fail from poor project management. You're not just buying a final product; you're buying a process, and your partner needs a transparent methodology for managing work and reporting progress.
For a longer list of vetting questions across the whole engagement, see this [data engineering RFP checklist](https://dataengineeringcompanies.com/data-engineering-rfp-checklist/).
* **Project Management:** "Describe your delivery methodology. How do you manage scope, timelines, and budget to prevent overruns?"
* **Communication Cadence:** "What does your standard communication plan look like? How often are check-ins, and what do your progress reports contain?"
* **Handling Scope Creep:** "Describe a project where requirements changed mid-stream. How did you manage the change and keep the project on track and on budget?"
### Cultural Fit and Scalability
Finally, assess the human element. This is a partnership requiring close collaboration for weeks or months - a strong cultural fit makes for productive work, and a mismatch creates friction.
Just as important is whether the firm can scale with you as your needs evolve, whether that means adding resources to a project or bringing in new skills like MLOps as your data maturity increases.
* **Team Dynamics:** "Describe your team's working style. Highly collaborative and hands-on, or more independent?"
* **Problem-Solving Approach:** "When an unexpected technical or logistical roadblock comes up, what's your process for escalating and resolving it?"
* **Scalability and Flexibility:** "Can your team scale up or down based on our needs? What other expertise can you provide as we mature - advanced analytics, machine learning?"
## What Red Flags Signal a Bad BI Consulting Partner?
Five warning signs cover most bad BI consulting partnerships: a one-tool vendor, a purely technical team with no business fluency, an AI pitch with no data foundation underneath it, a black-box delivery process, and a contract with no room to adapt. A failed BI initiative is more than a sunk cost - it can erode trust in data for years.

### The One-Size-Fits-All Vendor
This consultant has a preferred tool and positions it as the answer to every problem. They'll advocate for their favored platform - [Power BI](https://powerbi.microsoft.com/en-us/), [Snowflake](https://www.snowflake.com/en/), or a proprietary technology - without a real analysis of your specific needs and existing infrastructure.
A genuine partner starts by understanding your challenges, then recommends the appropriate tools. Their focus is your outcome, not the technology they'd prefer to implement.
* **A cautionary tale:** A mid-sized retail company was sold a complex [Databricks](https://www.databricks.com/) implementation for basic sales reporting. A standard Power BI setup would have covered nearly all of what they needed, at a fraction of the cost. The project ended up too expensive to finish and too complex for their internal team to run.
### The Purely Technical Team
Watch for teams that speak only in technical jargon - pipelines, data lakes, query optimization - with little mention of your business. BI projects are business initiatives, not IT exercises, and treating them as the latter is how they fail.
Your consultant needs business fluency. If they can't discuss customer lifetime value, supply chain efficiency, or sales funnel conversion, they can't build analytics that move those numbers.
> A consultant who can't clearly link their technical proposal to your P&L is a major red flag. Technology is the means, not the end. The objective is always a measurable business result.
### The AI-First Pitch Without a Foundation
With the current hype around AI, many firms lead with promises of predictive modeling and machine learning. These are real capabilities, but they're useless without a solid data foundation - you can't run advanced analytics on unreliable, poorly governed data.
A trustworthy consultant assesses your data maturity first and prioritizes building a dependable warehouse and data pipelines. A vendor who pitches AI before addressing that foundation is selling a fantasy, not a plan.
### The Black Box Approach
This vendor operates with no transparency. They take your requirements, disappear for weeks, then return with a "finished" product - little to no visibility into progress, methods, or problems along the way.
That's a high-risk approach. It blocks knowledge transfer to your team, creates long-term vendor dependency, and often produces a final product that misses the mark for lack of iterative feedback. Insist on a collaborative, agile process with frequent check-ins and shared project management tools.
### The Inflexible Contract
Finally, scrutinize the contract. A rigid Statement of Work with no provision for change is a sign of an inflexible partner - and business priorities shift, so your BI project needs room to adapt.
Look for a partner whose contracts include clear, fair processes for managing scope changes. That's a sign they understand how complex projects actually go.
## Frequently Asked Questions About BI Consulting
### How Do You Actually Measure the ROI of a BI Consulting Engagement?
ROI gets measured by defining clear, quantifiable business goals before the project begins - a competent consultant works with you to establish these baselines as the first step, not an afterthought.
This is about tangible business outcomes, not vague metrics:
* **Time Saved:** Cutting the finance team's manual reporting workload frees them up for higher-value analysis, with a direct, calculable cost benefit.
* **Revenue Gained:** A measurable increase in sales attributed to a new dashboard that surfaces high-value cross-sell opportunities.
* **Costs Cut:** A measurable reduction in inventory holding costs from improved supply chain analytics.
* **User Adoption:** Tracking how many employees actively use the BI tools to make decisions is itself a key indicator of value realized.
### Should You Hire a Small, Specialized Firm or a Big Global Consultancy?
There's no single right answer - it depends on your project's scope and your company's culture.
A niche, boutique firm often brings deep, specialized expertise. If you need a master of a specific tool like [Tableau](https://www.tableau.com/) or deep domain knowledge in e-commerce analytics, a boutique can be an agile, highly effective partner.
A large, global consultancy offers more resources, a broader talent pool, and established frameworks for large-scale, enterprise-wide transformations. For a multi-national data infrastructure overhaul, that scale can matter.
The practical advice: focus on relevant, verifiable experience that matches the problem you need to solve, not the size of the firm's logo.
### What Is the Single Biggest Factor for Success in a BI Project?
It's not the technology, and it's not the platform. The single biggest determinant of BI project success is strong executive sponsorship with a clear link to business objectives.
> A BI project is a business initiative enabled by technology, not the reverse. When a senior business leader champions the effort, they keep it focused on solving valuable problems, drive adoption, and hold the project team accountable for measurable results.
Without that champion, even a technically elegant solution fails to deliver value because it never gets integrated into how the organization actually decides things. Success isn't launching a tool - it's changing how the organization operates.
***
Finding the right BI consulting partner is one of the most consequential decisions in any data initiative. See how firms compare on [vendor selection criteria](https://dataengineeringcompanies.com/insights/vendor-management-best-practices/), then browse [independent firm profiles in the Data Engineering Companies Index](https://dataengineeringcompanies.com/data-engineering-consulting-firms/) to find a partner for your project.
---
## Best BI Software for Snowflake and BigQuery: A Practical Comparison
Source: https://dataengineeringcompanies.com/insights/bi-software-comparison/
Published: 2025-12-22T07:08:54.251769+00:00
Description: Compare Power BI, Tableau, Looker, and Qlik by semantic modeling, warehouse connectivity, self-service, governance, pricing, and migration effort.
The best BI software depends on how your team governs metrics and queries the warehouse. **Power BI fits Microsoft-centered organizations and formal reporting. Tableau fits visual exploration. Looker fits teams that want a code-defined semantic layer and warehouse pushdown. Qlik fits associative exploration across complex data.** Snowflake and BigQuery work with all four; the operating model matters more than the connector logo.
## Which BI platform fits each operating model?
| Platform | Best fit | Semantic model | Query pattern | Main tradeoff |
| :--- | :--- | :--- | :--- | :--- |
| **Power BI** | Microsoft estates, governed reporting, broad distribution | Tabular semantic models with DAX | Import, DirectQuery, composite, and Microsoft-specific modes | Broad capability, but licensing and capacity design need careful modeling |
| **Tableau** | Visual analysis and flexible dashboard authoring | Published data sources and governed content | Live connections or extracts | Strong exploration, but metric consistency needs deliberate governance |
| **Looker** | Warehouse-first analytics with code-reviewed metrics | LookML models in version-controlled projects | Generates SQL against the connected database | Strong centralized semantics, but LookML creates a specialist workflow |
| **Qlik** | Guided and associative analysis across varied sources | Associative data model | In-memory apps with source-query options | Flexible exploration, but the model and reload architecture require Qlik expertise |
Do not choose from this table alone. Test one executive dashboard, one self-service workflow, one row-level security case, and one high-concurrency workload with your own warehouse.
## What is the best BI tool for governed self-service?
**Looker is a strong fit when a central data team wants metrics defined as code and reviewed through Git. Power BI is a strong fit when governed semantic models, Microsoft identity, and familiar distribution workflows matter. Tableau works well when certified data sources and visual exploration are the priority. Qlik works well when users need to navigate associations across a curated model.**
Governed self-service is not unrestricted dashboard creation. It means users can answer new questions without redefining revenue, customer, or margin on every report. Evaluate where each platform stores metric logic, who can change it, how changes are reviewed, and how downstream content reacts.
The safest design separates three roles:
- Data engineers own reliable, documented warehouse tables.
- Analytics engineers or BI developers own reusable business definitions.
- Business users explore within approved dimensions, measures, and access rules.
If a platform makes the first dashboard easy but leaves every author to recreate core metrics, adoption can increase while trust falls.
## Which BI software works best with Snowflake or BigQuery?
All four platforms support warehouse connections, so compare execution behavior rather than connector availability.
**Looker** generates SQL from LookML and sends it to the connected database. That makes warehouse modeling, query history, and cost controls central to the BI experience. It is especially natural for teams already treating analytics code as software.
**Tableau** can use live connections or extracts. Live mode keeps the warehouse in the request path; extracts can improve interactive performance and isolate dashboards from source load, but add refresh and duplication decisions.
**Power BI** supports Import, DirectQuery, and composite semantic models. Import usually improves interactive speed but requires refresh and capacity planning. DirectQuery keeps data at the source, but dashboard performance then depends on generated queries, warehouse latency, and concurrency.
**Qlik** typically loads data into an associative application and also offers patterns that query source data on demand. Test reload windows, memory use, and how the design behaves as the model grows.
For both Snowflake and BigQuery, measure warehouse cost per dashboard session. A technically successful live-query deployment can still be a poor financial design if filters generate many expensive queries.
## How do Power BI, Tableau, Looker, and Qlik differ?
The important difference is where each product places structure.
- **Power BI** places substantial structure in semantic models, DAX measures, workspaces, and capacity configuration. It suits standardized reporting and organizations already using Microsoft administration patterns.
- **Tableau** places emphasis on visual analysis and authoring. It gives skilled analysts freedom, while governance depends on published sources, certification, permissions, and content management.
- **Looker** places business logic in LookML projects. Dimensions, measures, joins, and access rules can move through code review before users query them through Explores.
- **Qlik** places analytical behavior in its associative model. Selections expose related and unrelated values, which can support discovery that differs from a conventional report-filter workflow.
None is universally easiest. The easiest tool for report consumers may require more work from modelers, administrators, or platform engineers.
## How do you make BI easy without making it unsafe?
Start with a small certified layer. Publish the most important measures, the dimensions users actually need, clear descriptions, and a named owner. Hide implementation fields and unstable tables from default exploration.
Then add guardrails that users can see:
1. Show data freshness and the time zone on reports.
2. Define row-level and object-level access in reusable policies.
3. Separate endorsed production content from personal workspaces.
4. Track unused dashboards, duplicate metrics, slow queries, and failed refreshes.
5. Give users a route to request a metric or report change.
Avoid solving governance by locking every question behind a central ticket queue. That produces safe dashboards slowly and pushes users back to spreadsheets. The goal is a constrained, understandable surface for exploration.
## What does BI software really cost?
Model more than author licenses. BI cost can include viewer licensing, premium capacity, server or cloud hosting, embedded usage, support tiers, warehouse compute, extracts, gateways, development environments, and administration.
Use three workloads for estimates:
| Workload | What to measure |
| :--- | :--- |
| Executive reporting | Viewer count, refresh frequency, distribution, and peak concurrency |
| Analyst exploration | Author count, live-query volume, extract size, and development workflows |
| Embedded analytics | External users, query volume, tenancy, APIs, and capacity isolation |
Request a quote using these workloads, then reproduce them in a trial. A low per-user price can be misleading when the design also needs dedicated capacity or creates significant warehouse compute. A higher platform price can be rational when it replaces separate semantic, distribution, or embedded tooling.
## How should you estimate BI migration effort?
Count objects and redesign decisions, not just dashboards. Inventory data sources, semantic models, calculations, custom visuals, extracts, schedules, alerts, row-level policies, embedded applications, and downstream exports.
Classify each item:
- **Retire:** unused or duplicated content that should not move.
- **Rebuild:** valuable logic that needs a native implementation in the target.
- **Redesign:** workflows whose current architecture should not be copied.
- **Validate:** financial, regulatory, or operational reports requiring parallel results.
Pilot the hardest representative dashboard before estimating the full migration. Include user acceptance, training, dual running, and decommissioning. Syntax conversion is usually only one part of the work; metric reconciliation and adoption often dominate.
## How do you run a fair BI proof of concept?
Give each finalist the same source tables, metric definitions, security rules, and user tasks. Require a business user to answer an unprepared question, not only watch a vendor-built demo.
Measure dashboard response time at expected concurrency, warehouse queries and cost, model-development effort, permission administration, deployment between environments, accessibility, mobile behavior, and recovery from a failed refresh. Record any specialist skill needed to operate the result.
The final decision should name the platform, the semantic-layer owner, the expected query mode, the licensing assumptions, and the exit path. If you need help with selection or migration, compare [BI consulting services](/bi-consulting-services/). That services page owns implementation-provider intent; this page remains focused on software selection.
---
## BigQuery Consulting Services: 8 Firms Compared for 2026
Source: https://dataengineeringcompanies.com/insights/bigquery-consulting/
Published: 2026-07-20T09:00:00.000000+00:00
Description: Compare 8 GCP-capable data firms offering BigQuery consulting - rates, team size, and fit - plus how to verify certified BigQuery expertise.
BigQuery consulting covers schema design, query optimization, cost control, and pipeline work on Google's managed data warehouse. Below are 8 GCP and BigQuery-capable data engineering firms profiled in our directory, listed with the rate, team size, and fit data we track for each. None of these firms carry certifications or badges in our records - if certified BigQuery specialization is a requirement, verify it directly through Google's own [Partner Advantage directory](https://cloud.google.com/partners) before you shortlist.
## Compare BigQuery-capable firms
| Firm | Rate | Team size | Best for | Wrong for |
| :--- | :--- | :--- | :--- | :--- |
| [Aimpoint Digital](/aimpoint-digital/) | $175-275/hr | 200 | Data teams needing one partner credentialed across Snowflake, Databricks, and dbt | Lowest hourly cost as the driver, or a global delivery footprint beyond 200 people |
| [Analytics8](/analytics8/) | $100-200/hr | 100 | Mid-market companies needing end-to-end data solutions and modernization, with strong Looker/BI | Buyers needing elite single-platform depth from a broad-stack generalist |
| [DS Stream](/ds-stream/) | $50-99/hr | 150 | AI/data analytics and GenAI for global brands, across GCP, Azure, and AWS | Snowflake as the primary warehouse, or deep legacy warehouse migration |
| [Fractal Analytics](/fractal-analytics/) | $100-200/hr | 5000 | Enterprise AI and decision intelligence for Fortune 500 companies | Deep single-platform specialization over analytics breadth, or a firm this size adds unneeded coordination overhead |
| [Sigmoid](/sigmoid/) | $50-150/hr | 1000 | Mid-market ML engineering and data-platform work across the major clouds without top-of-market rates | Snowflake Elite/Databricks Premier depth, or niche regulated-industry compliance |
| [Slalom](/slalom/) | $150-250/hr | 13000 | Large enterprises running AWS-anchored (and GenAI) transformation; also GCP-capable | Focused multi-platform delivery where a large-enterprise rate adds unneeded cost |
| [Tiger Analytics](/tiger-analytics/) | $100-200/hr | 3000 | Large retail/CPG needing advanced analytics, AI/ML, and GenAI at enterprise scale | A deep single-platform engineering specialist, or a sub-$50K budget |
| [Tredence](/tredence/) | $100-200/hr | 3000 | Retail/CPG enterprises running large analytics or GenAI programs with migration accelerators | Sub-$50K budgets, a small senior-heavy pod, or a pure single-platform specialist need |
Firms are listed alphabetically. We do not rank firms by quality - use the best-for and wrong-for columns to narrow the list, then verify GCP specialization directly with Google before you send an RFP.
## 1. Aimpoint Digital
Rate: $175-275/hr. Team: 200. Minimum project: $25K+.
Aimpoint Digital fits data teams that need one partner covering Snowflake, Databricks, and dbt alongside GCP work, rather than splitting a modern-stack program across specialist firms. It is the wrong choice if lowest hourly cost is the deciding factor, or if a project needs a global delivery footprint beyond a 200-person bench.
## 2. Analytics8
Rate: $100-200/hr. Team: 100. Minimum project: $25K+.
Analytics8 serves mid-market companies that need end-to-end data solutions and platform modernization, with particular strength in Looker and BI delivery on top of GCP data. It is the wrong fit when the requirement is elite single-platform depth rather than a broad-stack generalist.
## 3. DS Stream
Rate: $50-99/hr. Team: 150. Minimum project: $25K+.
DS Stream works on AI and data analytics, including GenAI, for global brands across GCP, Azure, and AWS. It is the wrong choice when Snowflake must be the primary warehouse - it is not in their stack - or when a project centers on deep legacy warehouse migration.
## 4. Fractal Analytics
Rate: $100-200/hr. Team: 5000. Minimum project: $50K+.
Fractal Analytics delivers enterprise AI and decision intelligence work for Fortune 500 companies, with GCP among the platforms it supports. It is the wrong fit when a buyer needs deep single-platform specialization over analytics breadth, or cannot absorb the coordination overhead of a 5,000-person firm.
## 5. Sigmoid
Rate: $50-150/hr. Team: 1000. Minimum project: $25K+.
Sigmoid handles mid-market ML engineering and data-platform work across the major clouds, including GCP, at rates below top-of-market firms on this list. It is the wrong choice when a project needs Snowflake Elite or Databricks Premier depth, or niche regulated-industry compliance work.
## 6. Slalom
Rate: $150-250/hr. Team: 13000. Minimum project: $50K+.
Slalom is built for large enterprises running AWS-anchored transformation and GenAI programs, and is also GCP-capable for organizations running a mixed cloud estate. It is the wrong fit for focused multi-platform delivery where a $150-250/hr large-enterprise model adds cost a smaller program does not need.
## 7. Tiger Analytics
Rate: $100-200/hr. Team: 3000. Minimum project: $50K+.
Tiger Analytics supports large retail and CPG companies that need advanced analytics, AI/ML, and GenAI at enterprise scale, with GCP among the platforms covered. It is the wrong choice when the need is a deep single-platform engineering specialist, or the budget is under $50K.
## 8. Tredence
Rate: $100-200/hr. Team: 3000. Minimum project: $50K+.
Tredence runs large analytics and GenAI programs for retail and CPG enterprises, with migration accelerators and GCP capability. It is the wrong fit for sub-$50K budgets, a small senior-heavy pod, or a buyer that needs a pure single-platform specialist.
## What does a BigQuery consulting engagement involve?
A BigQuery consulting engagement typically covers schema and partitioning design, query and slot-cost optimization, pipeline development (batch or streaming ingestion), migration from another warehouse or on-prem system, and integration with tools like Looker or dbt. Scope varies by firm - confirm what's included before signing a statement of work.
## How much does BigQuery consulting cost?
Rates for the GCP-capable firms in our directory span $50-275/hr, and across our full 86-firm index rates run $45-250/hr with a median of $100/hr. Minimum project sizes for the firms above range from $25K to $50K+. Total cost depends on scope, team seniority mix, and whether the work is a net-new build or a migration.
## How do you verify a firm's BigQuery expertise?
Our directory tracks rate, team size, and stated best-fit and wrong-fit use cases for each firm, but it does not track BigQuery certifications. To confirm a firm holds Google's Data Analytics specialization or partner tier, search [Google Cloud's Partner Advantage directory](https://cloud.google.com/partners) directly - that is the authoritative source, not a vendor's own marketing page.
## When do you need a BigQuery consultant vs in-house?
Bring in a consultant when the work requires platform-specific tuning you don't have in-house - slot allocation, partition strategy, cost-anomaly diagnosis - or when a migration needs to run alongside a live production workload. Handle BigQuery in-house when your team already owns the schema and query patterns and the remaining work is routine maintenance.
## Frequently asked questions
### Do any of these 8 firms hold official Google Cloud BigQuery certifications?
Our directory does not list BigQuery or Google Cloud partner-tier certifications for any of the 8 firms above - that data isn't part of our profiles. Check [Google Cloud's Partner Advantage directory](https://cloud.google.com/partners) to see which firms currently hold a Data Analytics specialization.
### Which of these firms works with GCP as its primary cloud?
DS Stream lists GCP alongside Azure and AWS. The other seven firms are broader multi-cloud shops where GCP is one platform among several - Snowflake, Databricks, AWS, and Azure also appear in their profiles.
### What's the smallest project these firms will take on?
Aimpoint Digital, Analytics8, DS Stream, and Sigmoid list minimum project sizes of $25K+. Fractal Analytics, Slalom, Tiger Analytics, and Tredence list $50K+ minimums, reflecting their larger team sizes and enterprise focus.
### Is a smaller firm or a large one better for a BigQuery migration?
It depends on scope. A smaller team (Analytics8, DS Stream) can move faster on a contained migration with less coordination overhead. A larger firm (Slalom, Fractal Analytics, Tiger Analytics, Tredence) has more bench depth for a migration that runs alongside other workstreams, but usually comes with a higher minimum project size.
### How many firms in your directory offer GCP services overall?
56 of the 86 firms profiled in our directory list Google Cloud Platform capability. The 8 above are a subset selected for this guide; browse the full [Data Engineering Companies Index](/data-engineering-consulting-firms/) to see the rest.
---
## BigQuery vs Snowflake: An Engineering Leader's Decision Framework
Source: https://dataengineeringcompanies.com/insights/bigquery-vs-snowflake/
Published: 2026-03-02T06:53:55.531832+00:00
Description: An evidence-based BigQuery vs Snowflake comparison of architecture, pricing, and performance to guide your 2026 data platform choice.
**Snowflake and BigQuery split on one axis: dedicated, isolated compute versus serverless, shared compute.** Snowflake gives you virtual warehouses you size and isolate per team, which is why high-concurrency BI shops default to it. BigQuery has no warehouses to configure at all - it auto-scales against a shared pool, which is why ad-hoc analytics and ML teams standardized on GCP default to it.
The real question isn't which platform has more features. It's whether you need the granular control and performance isolation of dedicated compute clusters, or whether the hands-off, auto-scaling nature of a serverless model fits your team and workload better.
## Which Platform Should You Choose: Snowflake or BigQuery?
**Choose Snowflake if your priority is predictable, high-concurrency BI and you need multi-cloud flexibility. Choose BigQuery if your workloads are ad-hoc, ML-heavy, or event-driven and your organization already runs on GCP.** The decision affects total cost of ownership, operational load, and how much infrastructure your data team ends up managing day to day - it's not a feature-by-feature bake-off.
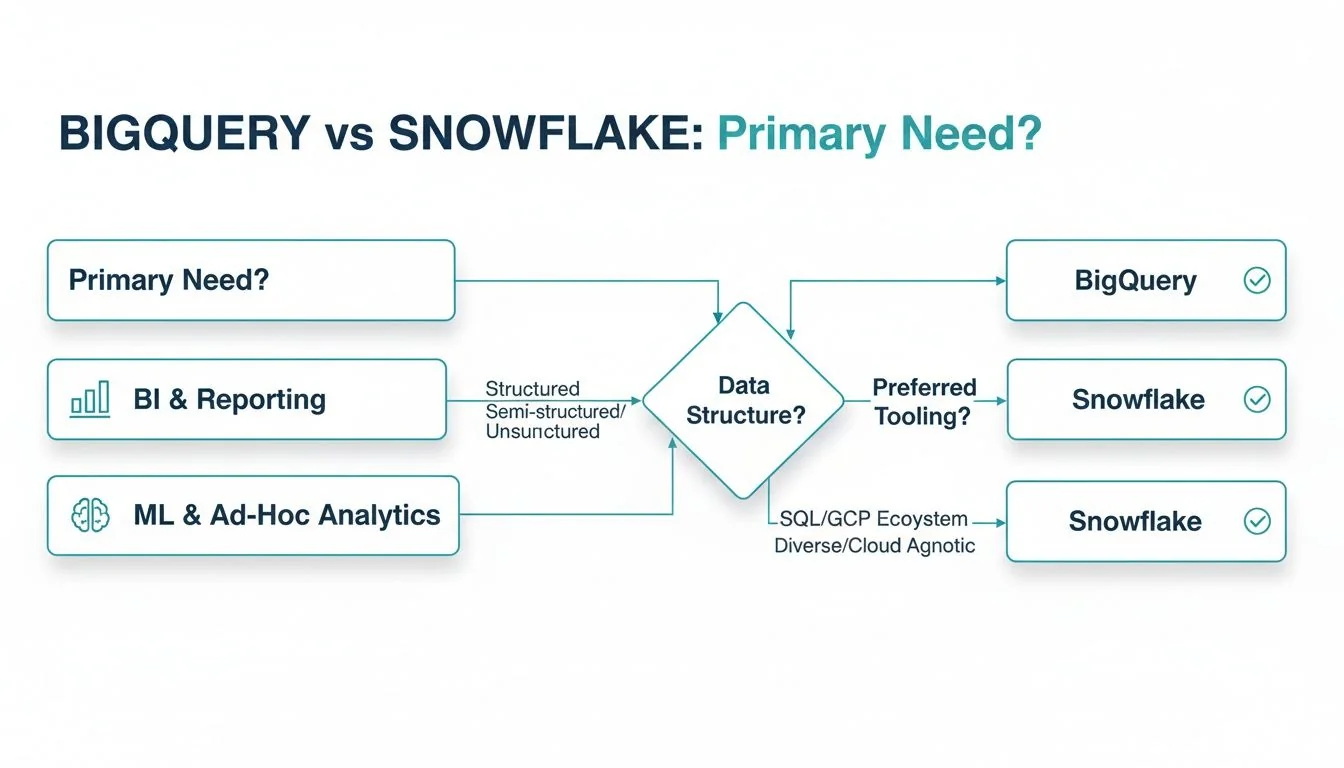
Organizations needing predictable BI performance and the flexibility of a multi-cloud or hybrid strategy will find Snowflake is the logical fit. Those standardized on GCP, with a heavy emphasis on ML and a need for simple ad-hoc querying, will gravitate toward BigQuery. The matrix below maps specific organizational priorities to the platform that best serves them.
### Executive Decision Matrix: BigQuery vs Snowflake
| Decision Factor | Choose Snowflake If... | Choose BigQuery If... |
| :--- | :--- | :--- |
| **Primary Cloud Strategy** | You operate in a multi-cloud (AWS, Azure, GCP) or hybrid environment and require a platform that avoids vendor lock-in. | Your organization is standardized on Google Cloud Platform (GCP) and you require deep, native integration with its services (e.g., Vertex AI, Looker). |
| **Key Workload** | Your focus is high-concurrency enterprise BI and reporting, requiring consistent and predictable query performance for hundreds or thousands of users. | Your workloads are ad-hoc, exploratory, or ML-centric, benefiting from serverless auto-scaling and zero infrastructure management. |
| **Cost Management Model** | You prefer predictable costs tied to performance, using dedicated virtual warehouses that can be controlled and monitored for specific budgets. | You favor a pay-per-query model for unpredictable workloads or require a fixed-cost option with flat-rate pricing for predictable high volume. |
| **Team Expertise & Ops** | Your data engineering team is skilled in infrastructure management and requires fine-grained control over compute resources for performance tuning. | Your team's priority is to eliminate infrastructure management to focus purely on analytics and data science outcomes. |
## How Do BigQuery and Snowflake Architectures Differ?
**Snowflake decouples storage from compute into virtual warehouses you provision and isolate per team. BigQuery is serverless and multi-tenant, pulling compute from a shared pool with no warehouses to manage.** That single difference drives nearly every downstream tradeoff in performance, cost, and day-to-day operations.
With Snowflake, you provision **virtual warehouses** for specific teams or workloads, and that isolation matters: a heavy data science query on one warehouse won't slow down an executive dashboard running on another. BigQuery is built on Google's internal Dremel technology - you write a query, and BigQuery allocates compute from its massive shared pool, with nothing to size or tune beforehand.
### Which Platform Handles Concurrency Better?
**Snowflake's dedicated virtual warehouses deliver more predictable performance under high concurrency, since workloads don't compete for the same resources. BigQuery handles bursty, unpredictable workloads well through auto-scaling, but shared-pool performance can fluctuate under extreme system-wide load.**
For thousands of concurrent users hitting dashboards, Snowflake's isolation is a real advantage - response times stay consistent because nobody else's query is stealing your warehouse's compute. Data science and ad-hoc teams benefit more from BigQuery's model: no provisioning, no idle-warehouse cost, and scaling that just happens.
Regardless of platform, a solid grasp of [data warehouse architecture](/insights/architecture-of-a-data-warehouse/) is worth the time before you commit to either one. For BigQuery specifically, schema design is the single biggest lever on cost and performance under on-demand pricing - partition and cluster tables before you scale usage, not after.
## Which Platform Costs Less: BigQuery or Snowflake?
**Neither platform is cheaper in the abstract - it depends entirely on workload shape.** Snowflake bills compute on a credit-based system, separate from storage. BigQuery offers on-demand pricing (pay per terabyte scanned) or flat-rate pricing where you reserve compute capacity ("slots"). The two scenarios below show how that plays out.
### How Do the Costs Play Out in Real Workloads?
**Scenario 1: Bursty Ad-Hoc Analytics**
* **Workload Profile:** A data science team runs a handful of complex, exploratory queries daily, scanning multiple terabytes in short, intense bursts.
* **Why BigQuery Wins Here:** On-demand pricing mirrors this pattern directly - you pay only for queries executed, with no cost for idle compute.
* **The Snowflake Challenge:** Covering peak demand means provisioning a warehouse that sits idle most of the day. Automating suspend/resume cuts the waste but adds operational work.
Cost modeling generally favors BigQuery's on-demand pricing for this kind of bursty, intermittent workload over a continuously running Snowflake warehouse - the exact gap depends on your query volume and how tightly you tune warehouse sizing.
**Scenario 2: Consistent Enterprise BI**
* **Workload Profile:** A large organization with thousands of users hitting BI dashboards around the clock, refreshed constantly by hundreds of concurrent queries.
* **Why Snowflake Wins Here:** A properly sized virtual warehouse gives you a fixed hourly rate for a known quantity of compute - predictable cost for a stable, high-volume workload.
* **The BigQuery Challenge:** On-demand pricing gets expensive fast at this query volume. Flat-rate slots solve it, but the entry-level commitment requires real capacity planning.
Snowflake also requires active cost management once it's running - see our breakdown of [Snowflake cost optimization](/insights/snowflake-cost-optimization/) for the specific levers. BigQuery's main hidden costs are data egress fees for moving data outside GCP and the size of the commitment required to qualify for flat-rate pricing.
## Which Platform Avoids Vendor Lock-In?
**Snowflake avoids lock-in by running natively across AWS, Azure, and GCP. BigQuery trades that flexibility for deep, native integration within the Google Cloud ecosystem.** Which one wins depends on whether your organization prioritizes cloud portability or a tightly integrated single-vendor stack.
Of the 86 firms profiled in the Data Engineering Companies Index, 66 list Snowflake and 56 list Google Cloud (GCP) among their platforms - both ecosystems have deep bench strength among implementation partners, which matters once you're past the proof-of-concept stage.
### Multi-Cloud Flexibility vs. GCP-Native Efficiency
* **Snowflake:** Its partner network is extensive and cloud-agnostic, with mature integrations into BI tools like [Tableau](https://www.tableau.com/) and [Power BI](https://powerbi.microsoft.com/en-us/) regardless of underlying cloud.
* **BigQuery:** Native integration with [Vertex AI](https://cloud.google.com/vertex-ai), [Looker](https://www.looker.com/), and Google Cloud Storage creates a low-friction environment for teams already committed to GCP - hard to replicate if you're not.
Your existing cloud strategy and tolerance for vendor dependency decide this one. An enterprise running multi-cloud will value Snowflake's flexibility; a GCP-centric organization will get more out of BigQuery's native integrations. If you're weighing a migration or a new build on either platform, our directories for [Snowflake consulting](/snowflake-consulting/) and [GCP data engineering](/gcp-data-engineering/) firms cover both paths.
## Which Platform Has Better Governance and Security?
**Snowflake ships governance features built directly into the warehouse - role-based access, column-level security, and dynamic data masking. BigQuery relies on Google Cloud's broader IAM framework plus services like VPC Service Controls and Dataplex.** Both reach enterprise-grade security; they just get there through different architectures.
Snowflake's built-in tools include:
* **Role-Based Access Control (RBAC):** A permission hierarchy built for managing large, complex teams.
* **Column-Level Security:** Restrict access to specific columns, useful for keeping PII out of analyst view.
* **Dynamic Data Masking:** Redacts sensitive data on the fly by user role, without maintaining separate masked copies.
For many teams, these self-contained features are faster to stand up than assembling equivalent controls elsewhere.
### Implementation and Ecosystem Differences
BigQuery anchors security in Google Cloud IAM - one consistent permission model across every GCP service, which is a real advantage if your organization already runs on GCP. It reaches comparable governance through:
* **VPC Service Controls:** A secure perimeter around projects that prevents data exfiltration.
* **Google Cloud Dataplex:** Centralizes data discovery, metadata management, and policy enforcement across BigQuery, Cloud Storage, and other GCP sources.
The practical difference is deployment model: Snowflake's governance toolkit is self-contained and often faster to configure. BigQuery draws on the wider GCP ecosystem, which is powerful but means configuring multiple services to match what Snowflake gives you natively.
## Frequently Asked Questions
### Is Snowflake Always More Expensive Than BigQuery?
No. Total cost of ownership depends entirely on your workloads. Snowflake tends to win on predictable, high-concurrency BI, where a well-tuned virtual warehouse serves many users at a fixed cost. BigQuery tends to win on sporadic, heavy ad-hoc queries, where you only pay for data scanned at query time.
A dashboard refreshing every five minutes for thousands of users will usually run cheaper on a correctly sized Snowflake warehouse than on thousands of individual BigQuery scans.
### How Difficult Is It to Migrate Between Platforms?
Migrating between BigQuery and Snowflake is a real engineering project, not a lift-and-shift. Both use ANSI SQL as a base, but proprietary functions and syntax mean existing queries need manual translation. Code built on platform-specific features - Snowflake Streams, BigQuery ML - needs to be re-architected, not just ported. Data egress fees for moving large volumes out of a cloud provider also need to be budgeted in.
Given that complexity, most teams bring in a specialist partner to manage the migration rather than absorb the risk in-house.
### Which Platform Is Better for Real-Time Analytics?
BigQuery has the edge for true real-time use cases. It was built for streaming ingestion from the start, with a native streaming API that makes data queryable at low latency without micro-batching. Snowflake's Snowpipe and Dynamic Tables get you near-real-time performance, but BigQuery's serverless streaming path is more direct.
## Next Steps: Platform Selection and Implementation
Use this checklist to make the call:
* **Workloads and Concurrency:**
* **Lean Snowflake if:** Your primary use case is enterprise BI with high concurrency, needing predictable performance and strict workload isolation.
* **Lean BigQuery if:** Your workloads are unpredictable, event-driven, or ML-heavy, where serverless auto-scaling is a real operational advantage.
* **Cloud Strategy and Cost Model:**
* **Lean Snowflake if:** You're running multi-cloud and need to avoid lock-in, with a financial model that favors predictable costs tied to compute.
* **Lean BigQuery if:** You're GCP-native and the pay-per-query model fits sporadic, large-scale workloads better than reserved capacity.
Picking the platform is the easy part. A qualified implementation partner earns their fee by validating your architecture up front, modeling costs against your actual query patterns, and building governance in from day one - the rework that comes from skipping these steps is what actually blows up migration budgets. Browse our [Snowflake consulting](/snowflake-consulting/) or [GCP data engineering](/gcp-data-engineering/) directories to shortlist firms with relevant platform experience, or start with the fundamentals in our [data warehouse vs. data lake](/insights/data-warehouse-vs-data-lake/) guide if the architecture decision itself is still open.
---
## A Practical Guide to Build a Data Warehouse That Delivers Value
Source: https://dataengineeringcompanies.com/insights/build-a-data-warehouse/
Published: 2026-01-29T08:54:52.636178+00:00
Description: Learn how to build a data warehouse that drives real business outcomes. This guide covers strategic planning, architecture, tech selection, and optimization.
Building a data warehouse starts with the business questions it needs to answer, not the platform you'll run it on: define outcomes first, choose an architecture (warehouse, lake, or lakehouse), pick a cloud platform such as Snowflake or Databricks, and ship it in phased sprints that prove value before you scale. Skip that order and you end up with a well-engineered system nobody actually uses.
This guide walks through the strategic planning, architecture decisions, technology selection, and optimization work behind a warehouse build that pays for itself. Platform choice narrows fast in practice: among the 86 firms profiled in the [Data Engineering Companies Index](/snowflake-consulting/), 66 list Snowflake and 76 list AWS as core platform capabilities, with 64 also building on Databricks lakehouse architecture - most warehouse projects end up choosing between this small set of stacks, not searching the whole market.
What this guide covers:
* Why a warehouse is a business investment, not an IT project, and how to frame it that way.
* Choosing between a warehouse, data lake, and lakehouse architecture.
* ETL vs. ELT, data modeling approaches, and why compute/storage separation matters.
* Selecting a cloud platform and implementation partner.
* Implementation, testing, cost management, and change management.
* When to hire a consultant and what it actually costs.
## Why Is a Modern Data Warehouse a Business Imperative?
A data warehouse earns its keep by replacing scattered SaaS silos with one source of truth that powers dashboards, compliance reporting, and machine learning models. Treating it as an archive for historical reports undersells what a well-built warehouse can do.
The legacy view of a warehouse as a place to park old reports is out of date. A modern warehouse works as the operational backbone: it powers real-time dashboards, feeds predictive AI models, and gives every department the same numbers to work from.
Most organizations run a sprawling set of SaaS tools - [Salesforce](https://www.salesforce.com/), [Marketo](https://nation.marketo.com/), [NetSuite](https://www.netsuite.com/portal/home.shtml) - each holding its own slice of the business in its own silo. A warehouse breaks down those walls by pulling the data into one place everyone can query.
### Capabilities a Warehouse Enables Beyond Reporting
A well-architected warehouse does more than consolidate information - it opens up work that would otherwise be out of reach.
* **Advanced analytics and AI:** Machine learning models are only as good as the data behind them. A warehouse supplies the clean, structured datasets needed to build accurate models for demand forecasting, churn analysis, and similar work.
* **Governance and compliance:** GDPR and CCPA require strict data handling. A modern warehouse enforces granular security policies, tracks data provenance, and simplifies audits, which cuts compliance risk.
* **Operational agility:** When marketing, sales, and finance all work from the same trusted dataset, decisions move faster and teams stop arguing over whose spreadsheet is right.
> Many data warehouse projects fail because they get treated as a technical exercise instead of a business one. If you cannot explain how the project will drive revenue, cut costs, or reduce risk, it will not hold executive support long enough to finish.
Demand for this kind of infrastructure keeps climbing, driven by the need for real-time analytics and elastic cloud infrastructure as more of the business runs on live data instead of end-of-month reports.
Putting off a warehouse build carries a real cost: insights stay locked in silos, compliance work stays manual, and competitors with clean, centralized data make faster calls. The rest of this guide covers how to build one that earns back the investment.
## What Does a Data Warehouse Blueprint Need to Include?
A data warehouse blueprint needs more than a list of data sources - it needs business questions translated into technical requirements, a phased delivery roadmap, and a governance framework defined before implementation starts, not after.
Building without this groundwork is what causes most warehouse projects to stall. Planning has to start by turning high-level business goals into specific, answerable questions, before any technology gets chosen. Teams that skip this step end up debating tools before they've agreed on what the tools need to do. The objective isn't to centralize data for its own sake - it's to let the marketing team calculate customer lifetime value or let operations forecast a supply chain disruption before it happens.
### Define Business Requirements, Not Technical Tasks
Your job as the project lead is to move stakeholders from vague requests, like "we need a sales dashboard," to the specific, high-value questions that dashboard needs to answer. What decision will it inform? What metrics does that decision actually depend on?
* **Finance:** instead of "track revenue," the requirement becomes "analyze product profitability by region, factoring in logistics and marketing spend, on a weekly basis."
* **Operations:** "monitor inventory" is too vague. A workable version is "forecast stockouts for our top 50 SKUs over the next 30 days based on historical sales and seasonality."
This shift is what separates a warehouse people use from one that quietly gets defunded a year in.
The journey is one of moving from data chaos to analytical clarity.
As the diagram shows, a modern data warehouse acts as the bridge between disconnected data silos and a structured foundation for analytics, AI, and machine learning.
### Develop a Phased Roadmap With Quick Wins
A warehouse shouldn't be built as one monolithic project. The more reliable approach is a phased roadmap that ships quick wins early to build momentum and prove value to the business.
The first phase should focus on one high-impact area, such as sales analytics. Delivering something genuinely useful to one department within the first few months creates internal advocates, which makes it much easier to secure buy-in and budget for the next phase - integrating operations or finance data, for example.
> A common mistake is trying to connect every data source from day one, which drags out planning and burns through stakeholder patience. Ship value in 90-day sprints instead.
This iterative approach means lessons from the first phase improve the next one, which makes the whole project more resilient and better aligned with the business.
### Establish Governance Early, Not as an Afterthought
Data governance has to be part of the blueprint from the start, not bolted on later. Skip it and you end up with a "data swamp" - a centralized pile of untrusted, undocumented, insecure data nobody can safely use.
Your initial governance framework should define:
* **Data ownership:** Who is accountable for the quality of data from each source system? The sales team, for example, owns the accuracy of its Salesforce data.
* **Access controls:** How will permissions work? Sensitive information should be accessible only to authorized users based on their role.
* **Data quality standards:** What are the baseline targets for completeness, accuracy, and timeliness, and how will you monitor and fix violations?
Setting these rules upfront prevents chaos later and builds trust in the data as the warehouse grows. For a deeper look, see [how to build an effective data governance strategy](/insights/data-governance-strategies/).
## What Architectural Decisions Determine a Warehouse's Long-Term Success?
The architecture you pick now - warehouse, lake, or lakehouse, plus how you model and ingest data - will shape your data capabilities for the next five to ten years, so match it to your actual data characteristics and business goals, not the latest trend.
The first decision is which paradigm to build on. It governs how you store, process, and serve data, with real downstream effects on cost, performance, and what your team can actually do with the data.

This decision determines who can use your data and how efficiently they can get value from it.
### Choosing Your Core Architecture Paradigm
The choice comes down to a traditional **data warehouse**, a **data lake**, or the hybrid **data lakehouse**. Each is built for a different job. A classic warehouse is optimized for structured, historical data, which makes it fast for standard BI reporting.
A data lake stores raw data in any format - IoT sensor streams, social feeds, server logs. It's built for data science and discovery, but takes real effort to turn into clean, report-ready output.
A data lakehouse combines the low-cost, flexible storage of a lake with the data management and transactional features of a warehouse, so BI dashboards and machine learning models can run on the same platform.
For a closer look, see our [comparison of data warehouse vs. data lake architectures](/insights/data-warehouse-vs-data-lake/).
***
### Data Warehouse vs. Lake vs. Lakehouse: How the Trade-offs Compare
| Attribute | Data Warehouse | Data Lake | Data Lakehouse |
| :--- | :--- | :--- | :--- |
| **Primary Use Case** | Business Intelligence, Reporting | AI, Machine Learning, Discovery | Both BI and AI/ML on one platform |
| **Data Types** | Structured, processed | All types (raw, unstructured) | All types (structured & unstructured) |
| **Data Schema** | Schema-on-write (pre-defined) | Schema-on-read (flexible) | Schema-on-read with enforcement |
| **Performance** | Very high for optimized queries | Slower for BI, high for big data | High for BI, optimized for AI/ML |
| **Users** | Business Analysts, Executives | Data Scientists, Data Engineers | All data users across the org |
| **Cost-Effectiveness** | Higher cost per TB | Lower storage cost, higher processing | Optimized for both storage & compute |
The right choice comes down to your primary objective. If the goal is BI reporting, a warehouse may be enough. If the goal is an AI-driven roadmap, a lakehouse is the stronger long-term investment.
***
### ETL vs. ELT: Which Should You Use?
Once you've settled the storage architecture, you need to decide how data gets ingested: ETL (extract, transform, load) or ELT (extract, load, transform).
* **ETL:** the traditional approach. Data is extracted from a source, transformed on a separate server, then loaded into the warehouse - necessary when compute and storage were tightly coupled and expensive.
* **ELT:** the cloud-native approach. Raw data is extracted and loaded directly into the platform, and all transformations happen inside it, using the platform's own scalable compute engine.
For nearly all new projects today, ELT is the better default. It's more flexible, handles large data volumes efficiently, and gives data scientists access to raw data. ETL still has a place for niche cases, like intensive data cleansing for compliance before data enters the core platform.
### Selecting a Data Modeling Approach
How you organize data inside the warehouse is another decision with real consequences - get it wrong and queries slow down and users get confused. The two dominant methodologies are Kimball and Inmon.
**The Kimball model (bottom-up):** prioritizes speed to value. You build focused data marts for individual business functions - sales, marketing - and integrate them later. It's pragmatic, faster to implement, and popular with business analysts.
**The Inmon model (top-down):** builds a single, normalized, enterprise-wide data source first, then creates departmental data marts from that central repository. It takes more upfront effort but delivers better consistency and governance, which matters in regulated industries.
> This choice has real consequences. A retailer that needs fast insight into daily sales is better served by Kimball's speed. A financial institution that needs a single, auditable view of customer transactions is better served by Inmon's rigor.
### Why Separating Compute and Storage Matters
Separating storage and compute is a defining feature of the modern data stack. Legacy on-premises systems bundled the two, so more processing power meant buying more storage too, whether you needed it or not.
Modern cloud platforms like [Snowflake](https://www.snowflake.com/en/), [Google BigQuery](https://cloud.google.com/bigquery), and [Databricks](https://www.databricks.com/) decoupled them, which changes both the economics and what's possible.
1. **Scale compute on demand:** spin up a large compute cluster for a heavy machine learning training job, then shut it down when it's done, paying only for the minutes used.
2. **Store everything affordably:** keep petabytes of data in low-cost object storage without paying for compute resources sitting idle around the clock.
This separation gives you the elasticity to handle variable workloads while keeping costs under control - an economic model that wasn't possible with the previous generation of infrastructure.
## How Do You Choose Between Snowflake, Databricks, BigQuery, and Redshift?
With the architecture set, the next step is procurement: choosing the specific platform and the team that will implement it. These choices drive total cost of ownership, time to value, and whether the project succeeds at all.
The task isn't just picking a database - it's picking an ecosystem. A handful of platforms dominate enterprise deployments, and matching a platform's actual strengths to your requirements matters more than reading its marketing.
### The Major Cloud Data Platforms Compared
Four platforms come up in nearly every enterprise shortlist. Knowing what sets each apart is the first step in narrowing the field.
* **[Snowflake](https://www.snowflake.com/en/):** built around a clean separation of storage and compute, and prioritizes simplicity. Strong for traditional BI and analytics workloads, with a large data marketplace. Often the pick for teams that want a fully managed, SQL-first experience.
* **[Databricks](https://www.databricks.com/):** grew out of Apache Spark and champions the lakehouse architecture. The platform of choice for companies with real AI and machine learning ambitions, since it unifies data engineering, analytics, and data science. Favored by engineering-led teams that want control and flexibility.
* **[Google BigQuery](https://cloud.google.com/bigquery):** a serverless warehouse that handles massive datasets and real-time analytics well. Tight integration with Google Cloud and strong ML features make it a natural fit for GCP shops and teams working with high-volume streaming data.
* **[Amazon Redshift](https://aws.amazon.com/redshift/):** the first major cloud data warehouse, and it's evolved considerably since. Deeply integrated into AWS, with strong price-performance for stable, predictable workloads. A natural fit for organizations already committed to AWS.
> No platform wins every case. The right choice for a financial institution focused on risk modeling (often Databricks) is different from the right choice for a mid-market e-commerce company focused on marketing analytics (often Snowflake or BigQuery). Let the use case drive the decision.
### Top-Tier Data Platform Feature Checklist
Once you've narrowed the field, run a structured comparison instead of relying on demos. This checklist covers the features that matter most for enterprise-grade deployments.
| Feature Category | Snowflake | Databricks | BigQuery | Redshift |
| :--- | :--- | :--- | :--- | :--- |
| **Architecture** | Decoupled Storage/Compute | Lakehouse (Unified) | Serverless, Columnar | Cluster-Based, MPP |
| **Core Use Case** | BI & Data Warehousing | AI/ML & Data Engineering | Large-Scale Analytics | Traditional DW & BI |
| **Scalability** | Instant, On-Demand | Cluster Auto-Scaling | Fully Serverless | Node-Based Scaling |
| **Data Formats** | Structured, Semi-Structured | All (Parquet, Delta Lake) | Structured, Semi-Structured | Structured |
| **Governance** | Strong RBAC, Tagging | Unity Catalog (Fine-Grained) | IAM Integration, Column-Level | Strong IAM, RBAC |
| **Ecosystem** | Strong Partner Network | Open-Source Centric | Google Cloud Integrated | AWS Integrated |
This side-by-side comparison gives you something concrete to discuss with your team, so the final decision reflects both technical and business requirements.
### Choosing the Right Implementation Partner
The platform is only half of the decision.
Unless you already have an in-house team of data engineers with recent, relevant project experience, you'll need an implementation partner - and picking the right one matters as much as picking the right platform.
Look for a partner with proven, verifiable experience on your chosen platform. Ask for detailed case studies and client references from projects similar to yours in scale and industry. Check their project management approach - an agile, iterative method is almost always better than a "big bang" waterfall rollout.
Finally, make sure there's a real plan for knowledge transfer. The goal is self-sufficiency, not an open-ended consulting contract. A good partner trains your team and works toward making themselves unnecessary.
If you're evaluating whether to bring in outside help, see [when to hire a cloud data warehouse consultant](#when-should-you-hire-a-cloud-data-warehouse-consultant) below.
## What Does Data Warehouse Implementation Actually Involve?
Implementation turns the architecture and platform decisions into a working warehouse - it requires disciplined engineering, rigorous testing, and ongoing attention to performance and cost, not just a one-time build-and-ship effort.
This is the stage where the project either becomes a trusted engine for decisions or an expensive asset nobody fully trusts.

The pipelines you build now will feed every analysis for years. A fragile pipeline undermines trust in the whole system from day one.
### Building Reliable Data Ingestion Pipelines
A warehouse is only as useful as the data feeding it. These ingestion pipelines are the arteries of the platform, and they need to hold up under real conditions. Two modes of data movement cover most enterprise needs.
* **Batch Ingestion:** the standard for large volumes of historical or less time-sensitive data, like daily ERP extracts or hourly CRM syncs. Reliability and idempotency - the ability to re-run a failed job without creating duplicate records - matter most here.
* **Streaming Ingestion:** needed for real-time use cases like fraud detection or live inventory tracking. Data flows in continuously from sources like IoT devices or application logs, and the tooling needs to handle low latency.
Every pipeline, regardless of type, needs logging, monitoring, and alerting built in, so failures get caught and diagnosed immediately.
### What Does a Testing and Validation Strategy Need to Cover?
Business decisions shouldn't run on untested data. A layered testing strategy needs to be in place before anyone gets access.
A solid plan includes:
* **Unit Tests:** Verify individual pieces of transformation logic work correctly - does a function calculate gross margin accurately?
* **Integration Tests:** Confirm data can move from source to warehouse without errors.
* **Data Quality Checks:** Automate detection of nulls, duplicates, and referential integrity violations.
* **Business Logic Validation:** The step that actually builds trust. Work with stakeholders to confirm new dashboard metrics match their existing, trusted reports.
Data is only production-ready once it's passed all four.
### Managing Performance and Cost Together
In a cloud environment, performance and cost are the same problem. An inefficient query isn't just slow - it burns budget. Optimization needs to be ongoing, not a one-time task, if the warehouse is going to stay sustainable.
> A common mistake is treating optimization as an afterthought. A cost-aware culture needs to start on day one - in a consumption-based pricing model, every engineer and analyst is effectively a budget owner.
Start with monitoring and governance: set alerts for long-running queries, set resource quotas by team, and use cost-allocation tags to track spending by department or project.
Then focus on the techniques with the biggest payoff:
* **Right-Sizing Compute:** Analyze workloads to pick appropriately sized virtual warehouses or clusters. Scaling up on demand beats over-provisioning for occasional peak loads.
* **Query Optimization:** Train users to avoid `SELECT *`, filter early, and use partitions and clustering to cut down on data scanned.
* **Materialization Strategies:** For complex queries that run often, pre-calculate results with materialized views to speed things up and cut recurring compute costs.
### Driving Adoption Through Change Management
The most technically sound warehouse is a failure if nobody uses it. Rollout is a people problem as much as a technical one, and it needs a real change management plan to prepare users for a new way of working.
Start with clear communication about why the project matters and what it means for each team specifically. Follow that with hands-on, role-based training.
* **For Business Analysts:** Train on the new data models and the BI tool.
* **For Executives:** Walk through high-level dashboards and how to pull key metrics.
* **For Data Scientists:** Go deep on raw datasets, explain data lineage, and share best practices.
Finally, set up a clear feedback channel - a dedicated Slack channel or ticketing system - to handle questions, bug reports, and new data requests. That channel is what turns a rollout into an ongoing partnership instead of a one-time handoff.
## When Should You Hire a Cloud Data Warehouse Consultant?
Hire a consultant when your team lacks recent, hands-on experience with your target platform, when the timeline doesn't allow for an internal hire-and-ramp cycle, or when the stakes of a migration are too high to learn on the job. A good consultant moves faster and transfers skills to your team along the way.
When evaluating candidates, check hands-on experience in three areas instead of counting certifications:
* **Data Modeling Methodology:** Can they defend a choice between Kimball (dimensional), Inmon (normalized), or Data Vault 2.0 for your specific problem?
* **Modern ELT Tooling:** Do they have real, practical experience with dbt for transformations, Fivetran or Airbyte for ingestion, and Airflow or Dagster for orchestration?
* **Platform-Specific Performance Tuning:** Can they speak to the optimization levers specific to your platform - virtual warehouse sizing and clustering keys on Snowflake, or Photon and Delta Lake Z-Ordering on Databricks?
On cost: hourly rates among the 86 firms in the [Data Engineering Companies Index](/data-engineering-consulting-rates-2026/) run from $45 to $250, with a median around $100 - 44 of the 86 sit in the $100-200 range and 7 charge $200 or more, typically for senior architects on complex platform work. Fixed-bid engagements scale with project scope, from small proofs-of-concept up to full enterprise migrations running well into six or seven figures - total value and delivery speed matter more than the hourly number alone.
## Frequently Asked Questions About Building a Data Warehouse
Even a detailed plan runs into practical questions. Here are direct answers to what executives and data leaders usually ask about a warehouse build.
### How Long Does It Realistically Take to Build a Data Warehouse?
Timelines vary, but a foundational warehouse for a single business area - a customer 360 view integrating CRM and marketing data, for example - typically ships in 4 to 6 months with clear objectives and a competent partner.
A full enterprise-wide warehouse is a bigger undertaking, usually a multi-phase project spanning 12 to 18 months or more. The timeline depends on how many data sources you have, their complexity, the state of your data quality, and how clear the business requirements are.
> Be skeptical of anyone promising a comprehensive enterprise solution in a few weeks. That kind of speed usually comes at the cost of governance, testing, and scalable design, which shows up later as technical debt and rework. An iterative, value-driven approach holds up better.
### What Are the Most Common Hidden Costs to Watch For?
The cloud platform subscription is just the starting line. Operational costs are what actually catch teams off guard, and a cost-aware culture is the best defense against a blown budget.
Watch for:
* **Data Egress Fees:** Moving data out of your cloud provider's ecosystem costs money, and it adds up fast in multi-cloud or third-party integration scenarios.
* **Inefficient Queries:** In a consumption-based model, one poorly written query that scans terabytes of unnecessary data can burn through credits in minutes.
* **Idle Compute Resources:** Paying for virtual warehouses or clusters that are running but not doing real work is a common, avoidable expense.
* **Third-Party Tooling:** Ingestion tools like [Fivetran](https://www.fivetran.com/), transformation frameworks like [dbt](https://www.getdbt.com/), and BI platforms all need to be in the total budget.
* **Ongoing Governance:** The work doesn't end at launch - monitoring data quality, running security audits, and routine maintenance all need dedicated resources.
### Should We Build In-House or Hire a Consultancy?
This is a real build-vs-buy decision.
Building fully in-house gives you complete control, but it requires an elite, hard-to-hire data engineering team with recent experience on modern cloud platforms. That's viable only if you already have that talent.
Hiring a specialized consultancy gets you moving faster and lowers risk by drawing on methodologies and expertise that would otherwise take years to build internally.
For most organizations, the hybrid model works best: bring in an expert partner to architect the foundation and deliver the first data products, with knowledge transfer built into the engagement from the start. They should train and upskill your internal team as they go, so you get quick wins now and self-sufficiency later.
---
These decisions build on each other: the blueprint sets scope, the architecture choice sets the ceiling on what you can do with the data, the platform and partner determine execution risk, and testing and change management determine whether anyone actually uses what gets built.
If you're moving from one platform to another rather than building fresh, [Snowflake to Databricks migration](/insights/snowflake-to-databricks-migration/) covers that path specifically. For a deeper technical breakdown of the layers inside a warehouse, see [architecture of a data warehouse](/insights/architecture-of-a-data-warehouse/). And if you're ready to bring in outside help, the [Data Engineering Companies Index](/data-engineering-consulting-firms/) has independent profiles of firms that build and migrate warehouses for a living.
---
## Build vs Buy Data Platform: An Engineering Leader's Decision Framework in 2026
Source: https://dataengineeringcompanies.com/insights/build-vs-buy-data-platform/
Published: 2026-04-01T07:06:56.454229+00:00
Description: Deciding on a build vs buy data platform? This guide provides a TCO model, performance benchmarks, and a decision framework for engineering leaders.
The build vs buy decision for a data platform comes down to one question: will owning the infrastructure make your product better, or will it just make your engineering team slower to ship? For most companies, buying a managed platform like [Snowflake](https://www.snowflake.com/) or [Databricks](https://www.databricks.com/) is the faster, cheaper, lower-risk path. Building only pays off when data infrastructure is the product you sell, not a tool that supports it.
Rates for outside help move independently of that decision. Firms in the [Data Engineering Companies Index](/data-engineering-consulting-firms/) charge $45 to $250 an hour, with a median around $100, so bringing in a partner to implement a bought platform rarely comes close to the cost of staffing a build team from scratch.
## What factors actually decide build vs. buy?
Four factors decide the call: cost, speed, talent, and control. Build it yourself and your team owns the entire stack, from provisioning Kubernetes clusters to patching open source tools to managing the underlying hardware. A [comparison of on-premises vs cloud infrastructure](https://devisia.pro/blog/on-premises-vs-cloud) is a useful primer on how much of that work buying removes. Buy a managed platform and a vendor absorbs that low-level complexity, which frees your team to work on data modeling and business logic instead.
> The fastest-moving teams don't build the most; they make smart decisions about what *not* to build. Own your data models and business logic. Let a managed platform own everything else.
### Core Trade-Offs at a Glance
This table lays out the operational reality of each path, side by side.
| Evaluation Criterion | Build (Self-Hosted Custom Platform) | Buy (Managed Vendor Platform) |
| :--- | :--- | :--- |
| **Total Cost of Ownership (TCO)** | High and unpredictable. Dominated by engineering salaries and ongoing operational overhead. | Predictable OpEx. Subscription and usage-based costs simplify budgeting. |
| **Time-to-Value** | Slow: typically **18-24 months**, spanning development, testing, and iteration cycles. | Fast: typically **6-9 months**, using pre-built connectors and proven architecture from day one. |
| **Required Talent & Focus** | Demands a dedicated team of expensive, hard-to-find platform and DevOps engineers. | Lets your team focus on high-value work: data modeling, analytics, and solving business problems. |
| **Scalability & Maintenance** | Manual and resource-intensive. Scaling requires constant engineering effort and architectural planning. | Elastic and automated. The vendor manages scaling, backed by contractual SLAs. |
## What does building a data platform actually cost?
The sticker price is misleading. Total cost of ownership is what matters, and if you build, the biggest line item is not servers or software, it is people. You are not funding a project; you are funding a permanent internal product team for as long as the platform exists.
A platform team of one senior data architect and two platform engineers is a payroll commitment that runs well into seven figures a year, before counting ongoing maintenance, security patching, and the productivity lost to delays and turnover.
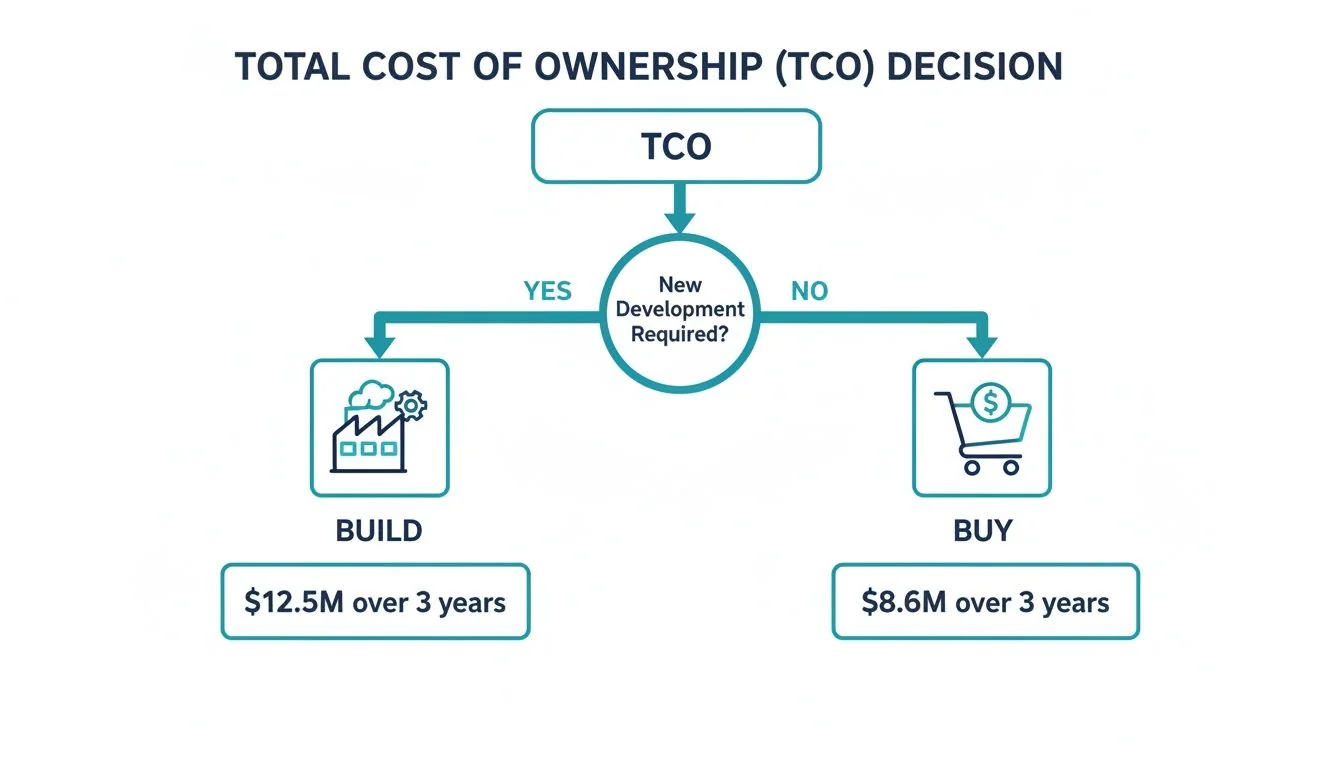
### The Financial Reality Check
Buying a platform swaps an unpredictable R&D bet for a stable operating expense: subscription fees, data processing costs, and any one-time implementation support from a consulting partner. That predictability is what a build project cannot offer, because a build budget is only an estimate until the project actually ships.
In practice, build projects tend to run over their original estimate more often than not, and the overrun usually traces back to the same handful of causes: unplanned integration work, senior engineering time, and schedule slippage that compounds over 18-plus months.
> The most expensive part of building isn't the first sprint. It's the multi-year commitment to funding a product team just to maintain, secure, and scale a platform that will always be playing catch-up with market leaders.
Buying a platform provides a clear financial model with contractual service level agreements. Building one launches a high-risk internal R&D project with an uncertain outcome and a budget that tends to grow rather than shrink. Use our [data engineering cost calculator](/data-engineering-cost-calculator/) to model your specific project expenses.
## How much faster is buying than building?
Buying typically gets a data platform into production in 6 to 9 months; building one commonly takes 18 to 24 months. That year-plus gap is not just a delay, it is time your competitors spend gaining ground while your team is still building infrastructure instead of shipping insight.
### The Real-World Performance Gap
Industry benchmarks consistently show the same pattern: teams that build their own data platform take substantially longer to get pipelines into production than teams that partner with an experienced consultancy to deploy a platform like [Databricks](https://www.databricks.com/) or [Snowflake](https://www.snowflake.com/en/).
Reliability follows the same trend. Homegrown integrations fail more often during rollout than the pre-built, already-tested connectors that ship with a mature vendor platform, and those failures show up later as rework, schedule slippage, and budget overrun. The broader [data science platform market](https://www.coherentmarketinsights.com/market-insight/data-science-platform-market-4417) reflects the same dynamics across the industry.
> When you buy a platform, you're also buying guaranteed SLAs for uptime and performance. When you build it yourself, your team is the one getting paged at 3 a.m., and every performance issue is a distraction from delivering business value.
Going with an established vendor removes most of that risk from the initiative. You get a proven ecosystem with performance guarantees, and your team spends its time generating insight now instead of building infrastructure for two more years.
## Does your team have the talent to build and maintain a platform?
The build vs buy decision is really a talent decision: who you have, and who you can realistically hire and retain. Choosing to build means committing to running what amounts to an internal software company dedicated to infrastructure.
### The True Cost of a "Build" Team
Building from scratch means recruiting a specialized team capable of handling the entire lifecycle:
* **Senior Data Architects** to design a system that scales.
* **Platform Engineers** with deep Kubernetes and DevOps experience to build and run the core infrastructure.
* **Specialized OSS Engineers** to manage, patch, and upgrade tools like Apache Airflow or dbt Core.
That talent is scarce and expensive, and sourcing senior people for these roles routinely stretches on for months even with an active search underway.
### Buying a Platform Shifts Your Team's Focus
Choosing a managed platform like [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/) doesn't eliminate the need for talent, it changes the job. Your team moves from low-level infrastructure work to work that creates business value directly.
The required skills shift toward:
* **Analytics Engineering** and data modeling *within* the platform.
* **Data Governance** and administration using the platform's built-in toolset.
* **FinOps** and vendor cost management.
This shift often lets you close remaining skill gaps with a few targeted hires or by engaging a specialized data engineering consultancy. For instance, exploring [Apache Airflow alternatives](https://digitalsoftwarereviews.com/2026/03/28/apache-airflow-alternatives/) might turn up an orchestration tool that fits your team's existing skills better than a pure open source approach. A buy decision changes your team's purpose from building infrastructure to delivering insight.
## How do build and buy compare on scalability and governance?
A data platform is only as valuable as its ability to grow with the business. Build it yourself and your team owns scalability permanently. Every spike in data volume becomes a fire drill that pulls your best engineers off revenue-generating work to provision resources and fix bottlenecks by hand.
Modern cloud-native platforms like [Snowflake](https://www.snowflake.com) or [Databricks](https://www.databricks.com) remove that problem. They scale resources up and down automatically to match demand, without manual intervention.
### Governance and long-term flexibility
Building a governance framework from scratch is a serious undertaking. Your team would have to engineer its own systems for data lineage, access control, and audit logging, work that is slow, expensive, and hard to maintain well over time. Established managed platforms ship these governance features out of the box, which matters for any organization that has to answer to an auditor or a regulator.
> Vendor lock-in is a solved problem in 2026. Modern multi-cloud strategies and open standards like [Apache Iceberg](https://iceberg.apache.org/) provide the architectural flexibility to avoid being tied to a single provider. This means your platform can evolve to support new technologies, like generative AI, without a costly overhaul.
The financial argument holds up across research from multiple analyst firms: enterprises that choose SaaS data platforms consistently report lower total cost of ownership over a multi-year horizon than those that build in-house, and the share of large enterprises attempting a from-scratch build has been shrinking for years as the managed alternatives have matured. For a closer look at where that trend is heading, see this [market analysis of the data management platform space](https://www.futuremarketinsights.com/reports/data-management-platforms-market).
## How do you actually make the build vs. buy decision?
Analysis paralysis on build vs buy has a real cost: every quarter spent debating is a quarter of technical debt and lost opportunity somewhere else. Treat this as a decision with a deadline, not an open-ended debate, and aim to have an answer within the current quarter.
### Step 1: Run the Internal TCO Assessment
Use the TCO model and decision matrix from earlier for a genuinely honest internal assessment. Weigh your team's actual capabilities, your budget constraints, and how central data infrastructure is to what you sell.
> If building a custom platform will cost over **$1.5M** in the first year and won't deliver meaningful results for over **12 months**, the "buy" path is the only practical option.
### Step 2: Start Vendor Evaluation
If your assessment points to buying, begin evaluating vendors with a structured framework, like our guide on [choosing a data engineering partner](/insights/data-engineering-partner-selection/).
Your core RFP criteria should include:
* **True multi-cloud support** and a commitment to open standards to prevent lock-in.
* **Integrated data governance** tools for security and compliance.
* **Transparent, usage-based pricing** that scales predictably.
Bring in a specialized data engineering consultancy at this stage. Their experience with vendor selection, migration planning, and implementation can turn a multi-year return on investment into a multi-month one.
## Frequently Asked Questions
### When does it make sense to build a data platform?
Almost never. Building a custom data platform is justified only in a narrow set of cases, such as:
1. **Truly unique processing needs** that no commercial tool can handle.
2. **Extreme data sovereignty rules** that forbid any third-party cloud interaction.
For the large majority of companies, the security, functionality, and predictable costs of a managed platform like [Snowflake](https://www.snowflake.com/) or [Databricks](https://databricks.com/) make buying the better decision.
### How does a data engineering consultancy help in a buy decision?
A specialized data engineering consultancy acts as a strategic accelerator. Its real value is in handling the complex decisions that follow the "buy" choice.
They typically cover three roles:
* **Unbiased Vendor Selection:** cutting through marketing claims to help you select the right platform for your specific workloads.
* **Architecture and Migration:** designing an efficient cloud data architecture and executing a low-risk migration from legacy systems.
* **Implementation and Optimization:** configuring the platform for performance and cost efficiency, and building out your initial pipelines using established practices.
### What are the biggest hidden costs of building a data platform?
The most punishing costs of a "build" decision show up in years two, three, and beyond. These long-term operational burdens are the real budget killers:
* **Talent Attrition:** retaining the specialized engineers who built the platform is expensive and difficult in a competitive market.
* **Ongoing Maintenance:** a custom platform is never "done." It requires a permanent team for bug fixes, security patching, and compatibility updates.
* **Scalability Rework:** the platform built for today's data volume will buckle under tomorrow's, forcing expensive re-architecting projects.
* **Integration Debt:** each new tool or data source requires a custom integration, creating a brittle system where maintenance costs keep rising.
---
## Choosing Causal Analysis Software: A CTO's 2026 Guide
Source: https://dataengineeringcompanies.com/insights/causal-analysis-software/
Published: 2026-07-16T10:54:52.075353+00:00
Description: CTOs: Evaluate causal analysis software beyond hype. Distinguish true causal inference from RCA & integrate with Snowflake/Databricks.
Causal analysis software answers a different question than root cause analysis tools do: not "why did this incident happen" but "what would have happened if this variable had been different." Buying the wrong one is common because both categories get marketed the same way. A CTO evaluating vendors needs to decide upfront whether the team needs a documentation and investigation workflow, or a statistical engine that infers cause-and-effect from observational data sitting in Snowflake or Databricks - those are different systems, different implementation paths, and different consulting requirements.
That distinction matters more as more of that data sits inside a governed platform. In the [Data Engineering Companies Index](/insights/machine-learning-consulting-firms/), 64 of the 86 profiled firms list ML/AI capability - but causal modeling is a narrower, harder-to-verify skill than applied ML, and it rarely comes up unprompted in a vendor demo.
## Why isn't correlation enough for causal analysis?
Most BI dashboards, observability platforms, and anomaly detectors surface association, not causation. They show that API latency rose after a deployment or that retention fell after a pricing change - they don't prove which factor produced the outcome once traffic shifts, seasonality, parallel releases, and upstream data defects enter the picture.
That gap matters more in Snowflake and Databricks environments because those platforms centralize the exact data needed to move beyond correlation. Event streams, feature flags, deployment metadata, lineage, product telemetry, and business outcomes now sit close enough to be modeled together. If your tooling still stops at "these signals changed at the same time," your team is fixing symptoms.
### This is a platform shift, not a passing trend
Buyers in regulated and high-stakes environments are increasingly picking systems that explain decisions and estimate intervention effects, not just summarize incidents after the fact. That's a procurement signal for CTOs: causal analysis software is moving into the core data stack for teams that need defensible experimentation and post-incident learning tied back to governed data assets, not a side tool bolted onto BI.
> **Practical rule:** If your team needs to decide what action to take next, correlation tools aren't enough. They describe patterns. They don't validate interventions.
### When correlation fails in practice
Three situations usually force the upgrade:
- **Deployment-heavy systems:** Your teams ship often, and multiple changes overlap in the same observation window.
- **Shared platforms:** Product, data, and infrastructure signals interact, so no single team owns the full cause chain.
- **Executive decisions:** Leaders need to know whether a change drove an outcome, not whether two metrics moved together.
In those conditions, causal analysis software stops being a research project and becomes data platform infrastructure.
## How is causal inference different from root cause analysis?
RCA is a forensic workflow you run after a known failure - gathering logs, traces, and context to trace backward to a root cause. Causal inference is a modeling system that estimates whether X caused Y after controlling for confounders, using historical data before an incident happens rather than a single ticket after one.
Search results for causal analysis routinely blur it with traditional root cause analysis methods like the 5 Whys, and that confusion is exactly why many enterprise evaluations go off track before the RFP is even written.
### RCA is a forensic workflow
RCA is what you run after a known failure. An outage happened. A bad batch shipped. A pipeline broke. The team gathers logs, traces, ticket history, and human context, then works backward through contributing conditions until it identifies a root cause and corrective action.
Think of RCA as a detective at a crime scene. The event already happened. The investigator wants the earliest triggering failure and the controls that would've prevented recurrence.
RCA tools are useful when you need:
- **Structured incident reviews**
- **Action tracking and ownership**
- **Cross-functional evidence capture**
- **Repeatable postmortem discipline**
They are not designed to recover causal structure from observational datasets at scale.
### Causal inference is a modeling system
Causal inference platforms do something else. They estimate whether X caused Y after controlling for confounding variables. In enterprise data work, that means modeling the effect of a release, policy, treatment, feature flag, routing change, or upstream data transformation on an outcome of interest.
Think of causal inference as a profiler building a model of system behavior before the next incident. It doesn't wait for a single failure ticket. It uses historical data to infer likely causal pathways and intervention effects.
> Causal inference answers "What happens if we change this variable?" RCA answers "Why did this incident happen?"
### What buyers should separate in demos
A vendor is selling RCA if the demo centers on templates, investigation boards, fishbone diagrams, and task assignment. A vendor is selling causal analysis software if the demo centers on causal graphs, treatment effects, confounding control, and validation of inferred links.
Use this quick comparison:
| Question | RCA platform | Causal inference platform |
| --- | --- | --- |
| Primary mode | Human investigation | Statistical inference |
| Timing | After incidents | Before and after incidents |
| Core data | Logs, tickets, interviews | Observational datasets, time-series, event data |
| Output | Root cause narrative, actions | Estimated effects, causal graph, intervention guidance |
| Best owner | SRE, ops, quality teams | Data science, data engineering, platform teams |
The wrong purchase creates a subtle failure mode. Leadership believes it has bought causal capability, while engineering has only bought better documentation.
## How do you integrate causal platforms with Snowflake and Databricks?
Causal analysis software doesn't drop into the stack like a dashboard plugin - it needs curated observational data, governance controls, and repeatable feature preparation before it produces output anyone should trust. The engineering lift is where most evaluations get superficial.
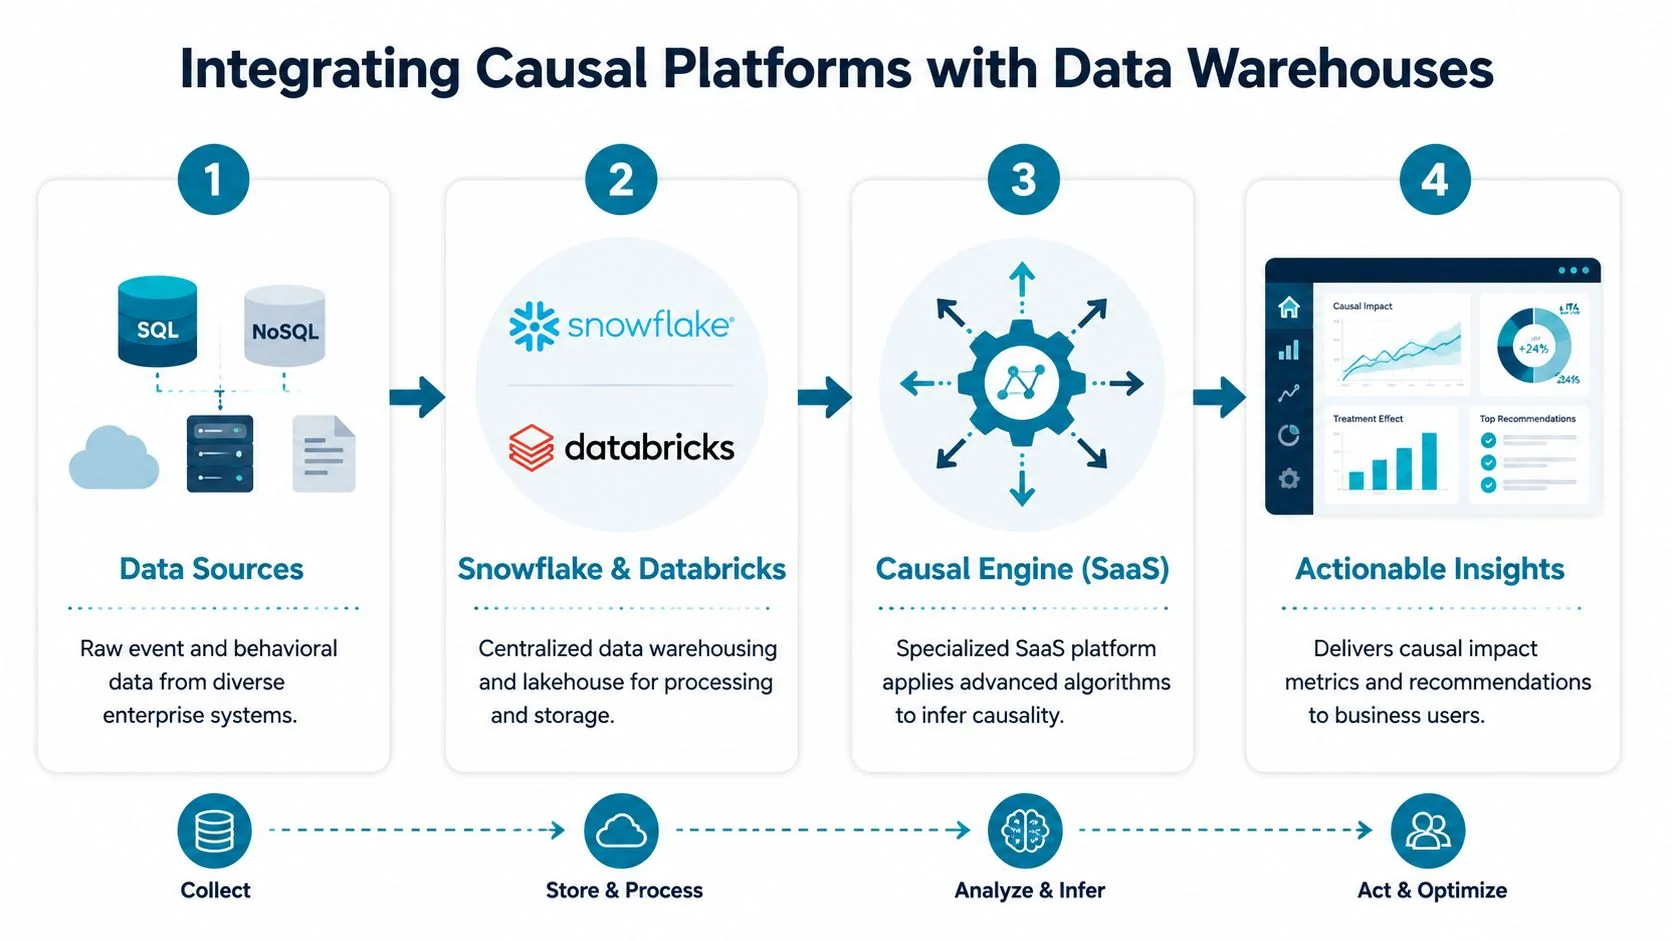
### The integration pattern
Most enterprise deployments follow a simple pattern. Raw events land in cloud storage or ingestion services. Snowflake or Databricks becomes the system of record for cleaned, joined, and governed data. The causal engine connects through controlled access, reads prepared datasets, runs inference, and writes back outputs for downstream consumption.
Salesforce's open-source [CausalAI library](https://github.com/salesforce/causalai) is a useful blueprint here because it supports causal discovery on tabular and time-series data through Structural Causal Models, with support for observational datasets and heterogeneous data types.
That matters because most real enterprise use cases are not clean experiments. They are messy observational environments with confounding variables everywhere.
### What data engineering has to build
A serious implementation usually requires these assets:
- **Conformed event models:** Product events, system events, deployment events, and business outcomes aligned on shared identifiers and time windows.
- **dbt transformation layers:** Semantic cleanup, time bucketing, treatment labeling, and exclusion logic belong in versioned models, not in a vendor UI.
- **Metadata joins:** CI/CD history, feature flag changes, incident tickets, lineage metadata, and config changes often contain the actual treatment variables.
- **Governance controls:** Service accounts, [role-based access](https://docs.snowflake.com/en/user-guide/security-access-control-overview), data masking, and query boundaries need to match existing platform policy.
For Snowflake buyers, cost discipline also matters because iterative modeling can trigger broad scans if the vendor pushes compute-heavy queries into warehouse tables. Teams planning budgets should review [Credit for Startups' Snowflake guide](https://creditforstartups.com/resources/snowflake-warehouse-cost) before approving production-scale workloads.
After the commercial model is clear, review delivery support as closely as the product. [Evaluating Snowflake consulting for modernization](/snowflake-consulting/) is useful if you need a partner to build governed data models, security boundaries, and workload patterns around the tool.
A short architectural walkthrough helps teams align on the target pattern:
### Snowflake and Databricks require different operating assumptions
Snowflake environments usually emphasize governed SQL models, secure sharing patterns, and warehouse-level workload management. Databricks estates usually bring notebook-driven exploration, feature engineering flexibility, and [lakehouse-native pipelines](https://docs.databricks.com/en/data-governance/unity-catalog/index.html). Neither is better by default.
What matters is whether the causal platform respects your operating model. If your data team has standardized on dbt plus Snowflake, don't accept a vendor that requires analysts to rebuild logic in proprietary modeling screens. If your platform team runs Databricks with strong ML workflows, don't accept a product that can't consume lakehouse-ready time-series and metadata joins without brittle extracts.
## Where does causal analysis software deliver the most value?
The clearest use cases sit at the fault line between platform operations and business outcomes: deployment impact on reliability, feature flag effect on retention, and the upstream source of pipeline degradation. Generic marketing examples rarely match what actually shows up in a data platform.
### Deployment impact on system reliability
A release goes out. Latency increases. Correlation tells you the release and the slowdown happened in the same window. It doesn't tell you whether traffic shape, cache churn, an upstream schema drift, or a concurrent infrastructure change produced the result.
Software RCA still requires a disciplined workflow of defining the problem, gathering multi-source data, isolating causes, and implementing verified corrective actions, as [Elastic outlines in its explanation of root cause analysis](https://www.elastic.co/what-is/root-cause-analysis). Causal analysis software strengthens the hardest part of that process. It helps isolate cause with statistical rigor once logs, metrics, traces, and change history are assembled.
### Feature flag effect on retention
A product team enables a feature flag and sees retention improve. Finance celebrates. Marketing had launched a campaign in the same period. A conventional dashboard can't separate the treatment effect from the campaign effect.
A causal platform can model the feature flag as the intervention, retention as the outcome, and campaign exposure as a confounder. That's the difference between allocating engineering budget based on evidence and rewarding the wrong team for the wrong reason.
> If your experimentation program relies on observational data outside controlled A/B tests, causal modeling belongs in the platform roadmap.
### Upstream source of pipeline degradation
A data quality incident shows up in the executive dashboard. The visible break appears in a reporting model, but the originating issue sits upstream in ingestion logic, a late source extract, or a schema contract violation.
Correlation-heavy monitoring floods the team with adjacent alerts. A causal workflow that incorporates lineage, job metadata, and change events can narrow the search to the originating operational change rather than the last downstream system that noticed the problem.
These are the use cases that justify the spend because they connect platform behavior to engineering decisions, not just to prettier incident reports.
## What should a causal software vendor evaluation cover?
Most RFPs ask about connectors, dashboards, and collaboration features, but those don't reveal whether a platform actually infers causality or just automates correlation with a nicer interface. Vendor rigor varies widely in this category, and the gap between marketing claims and actual methodology is where most RFPs fail to probe.
### The five-part RFP checklist
| Evaluation area | What to ask in the demo | What good looks like |
| --- | --- | --- |
| Statistical rigor | How do you distinguish causal effects from spurious correlations? | Clear explanation of causal discovery or inference methods, confounding handling, and validation steps |
| Data platform integration | How do you connect to Snowflake or Databricks without breaking governance? | Role-based access, support for governed datasets, minimal duplication, compatible deployment model |
| Scalability | What happens with high-dimensional enterprise data? | Explicit handling for many variables and repeatable performance expectations |
| Explainability | Can engineers interpret the output without a specialist translating it? | Readable causal graphs, assumptions exposed, intervention logic understandable |
| Support and services | Who helps build the data models and validate results? | Strong implementation guidance across platform engineering and causal methodology |
### The question most buyers skip
Validation should dominate the evaluation. Rigorous causal discovery methods use techniques like permutation testing and threshold-based pruning to discard spurious edges before they reach a causal graph, but that level of rigor rarely shows up in a vendor demo unless you ask for it directly.
Ask these questions directly:
- **Validation protocol:** What tests do you run to reject false edges?
- **Confounding control:** How do you detect hidden or observed confounders?
- **Intervention logic:** Can you estimate treatment effects, or only rank likely causes?
- **Auditability:** Can my team trace how the model inferred a relationship?
- **Operational fit:** Can outputs feed existing dbt, Airflow, or incident workflows?
> **Board-level filter:** If a vendor can't explain how it rejects false causal links, don't let procurement treat the product as decision-grade.
### Procurement gates for enterprise teams
For large enterprise consulting engagements, baseline delivery standards still apply. The provider needs the scale, compliance posture, contractual accountability, and multi-cloud capability expected in serious enterprise data programs - team scale, SOC 2 Type II compliance infrastructure, multi-year SLAs with indemnification, and multi-cloud architecture capability are what [enterprise data engineering procurement criteria](/enterprise-data-engineering/) typically screen for in Fortune 1000-grade engagements.
If you're formalizing selection criteria, start with this [RFP template for data engineering services](/insights/data-engineering-vendor-evaluation-criteria/) and add a causal-specific workstream for validation, observational data modeling, and platform security review.
## How should teams roll out causal analysis software?
Start with one decision problem that already has executive attention and usable historical data, not a platform-wide rollout. The sequence that works is pilot selection, data engineering, model validation, and controlled expansion, in that order.
### Phase 1 through Phase 2
**Phase 1 is pilot selection.** Choose one use case where the treatment, outcome, and major confounders are visible in existing platform data. Good candidates include deployment impact, feature flag effect, or a recurring data quality failure pattern.
**Phase 2 is data engineering.** Build the minimum governed dataset in Snowflake or Databricks. Use dbt or equivalent transformation logic to standardize identifiers, time windows, treatment labels, and exclusions. Keep this layer inside your existing SDLC.
### Phase 3 through Phase 4
**Phase 3 is model validation.** Compare early findings against historical incidents or known interventions. The point isn't to prove the model is magical. The point is to establish where it is reliable, where assumptions break, and which teams can act on its outputs.
**Phase 4 is controlled expansion.** Operationalize the output into engineering workflows, platform reviews, and business decision cycles. Train platform, analytics, and product teams differently. They won't use the same outputs in the same way.
> Start where your data platform is already strong. Don't begin with the noisiest domain in the company.
Causal capability is moving from niche tooling into standard enterprise operating practice, driven by more teams centralizing the data needed to model cause and effect instead of just observing it. The winners will be the teams that wire it into governed data platforms rather than bolt it onto incident management after the fact.
---
If you're turning this into an RFP or partner search, use DataEngineeringCompanies.com to compare enterprise data engineering providers, pressure-test consulting options, and shortlist firms that can support Snowflake or Databricks modernization alongside causal analysis software adoption.
---
## A Practical Guide to Cloud Data Integration for Modern Data Stacks
Source: https://dataengineeringcompanies.com/insights/cloud-data-integration/
Published: 2026-01-21T09:42:02.942553+00:00
Description: Discover cloud data integration essentials, compare ETL vs ELT, and learn to secure and optimize your data strategy with trusted partners.
Cloud data integration is the engineering work of moving data out of operational systems - a CRM, an ERP, application databases - into a central cloud warehouse so it can be queried, analyzed, and fed to models. Done right, it produces one consistent version of the truth instead of a dozen conflicting spreadsheet exports. The three ways to do it are ETL, ELT, and CDC, and picking the wrong one for a given workload is the most common early mistake.
AWS is the most common cloud platform among data engineering specialists: 76 of the 86 firms profiled in the [Data Engineering Companies Index](/aws-data-engineering/) list AWS integration work, ahead of Azure (70) and GCP (56). That's part of why AWS Glue shows up first in most vendor shortlists, not because it's automatically the right fit for every stack.
## Why does centralized cloud data integration matter?
Centralized cloud data integration replaces fragmented, siloed data across CRMs, ERPs, and operational databases with a unified analytical layer - typically a cloud data warehouse like Snowflake, BigQuery, or Databricks. Without it, analytics produce inconsistent results, models train on incomplete data, and reporting teams spend more time reconciling sources than generating insight.
Data originates in isolated systems: a CRM holds customer data, an ERP has financial records, legacy databases hold operational metrics. Left alone, these systems stay information silos and a holistic view of the business stays out of reach. Cloud data integration replaces manual, error-prone extraction with automated infrastructure that delivers clean, consistent, timely data to a central destination, typically a cloud data warehouse like [Snowflake](https://www.snowflake.com/en/), [Databricks](https://www.databricks.com/), or [Google BigQuery](https://cloud.google.com/bigquery). The result is a single data asset that serves as the analytical backbone of the organization.
### Why data integration became a core business function
What was once a back-office IT task is now a strategic priority. Without a coherent integration strategy, initiatives from predictive analytics to AI-driven personalization stall on incomplete or inconsistent data.
The global data integration market is projected to grow from USD 17.58 billion in 2026 to USD 33.24 billion by 2030, driven largely by the complexity of managing data across multi-cloud and hybrid environments. For a detailed breakdown of these drivers, see this [industry analysis](https://www.fortunebusinessinsights.com/data-integration-market-103130).
That growth reflects a simple principle: competitive advantage is tied to the ability to decide based on complete, accurate data. Cloud data integration is the mechanism that delivers it.
> An organization running on siloed data is operating without a shared source of truth. Cloud data integration imposes order, creating the synchronized foundation that meaningful analysis depends on.
A successful implementation delivers concrete outcomes:
* **Unified decision-making:** Executive dashboards reflect the entire business, not fragmented departmental views.
* **AI and ML enablement:** Models need large volumes of consolidated, high-quality data. Integration is the supply chain that keeps them trained and running.
* **Operational efficiency:** Automated data flows remove manual reconciliation work, freeing engineers for higher-value work than data wrangling.
## How do you choose between ETL, ELT, and CDC?
The three primary integration patterns - ETL (transform before load), ELT (load raw, then transform using warehouse compute), and CDC (capture only row-level changes) - suit different requirements. ELT with a modern cloud warehouse is the default for new analytics projects; CDC is essential for low-latency replication; ETL stays relevant mainly where compliance mandates pre-transformation.
Selecting an architecture is a foundational decision with long-term consequences for scalability, cost, and speed to insight. The choice depends on your data sources, cloud infrastructure, and the latency the business actually needs. Getting it wrong leads to inefficient pipelines, technical debt, and budget overruns.
The decision usually starts with a simple assessment: is data fragmented across systems, or already centralized?
For nearly every enterprise, the answer is fragmented. Cloud data integration is the prerequisite for a unified analytical view, and ETL, ELT, and CDC are the three patterns for getting there.
### ETL: the traditional staging-first approach
**ETL (Extract, Transform, Load)** is the older pattern. It performs transformations on a separate, dedicated staging server before loading data into the destination.
1. **Extract:** Raw data is pulled from source systems (CRMs, ERPs, databases).
2. **Transform:** On a processing engine outside the warehouse, the data is cleaned, standardized, aggregated, and structured.
3. **Load:** The processed, analysis-ready data is loaded into the cloud data warehouse.
ETL originated when warehouse processing power was limited and storage was expensive. Transforming data before loading minimized the burden on the destination. The pattern still makes sense for highly structured data or compliance requirements that mandate masking *before* data enters the central repository.
### ELT: the modern in-warehouse approach
**ELT (Extract, Load, Transform)** is the dominant modern pattern, made possible by the elastic compute and storage of cloud warehouses. It defers transformation until after data has been loaded.
* **Extract:** Raw data is pulled from sources.
* **Load:** The raw, unprocessed data is loaded into the cloud data warehouse immediately.
* **Transform:** All cleaning, joining, and modeling happens *inside* the warehouse, using its parallel processing capacity.
This pattern takes advantage of the scalable engines in platforms like [Snowflake](https://www.snowflake.com/en/) or [Google BigQuery](https://cloud.google.com/bigquery). It gives teams the flexibility to store raw data first and transform it for multiple, different use cases later. ELT is the standard for most cloud data integration projects today, especially ones involving large volumes of semi-structured data from modern applications.
> ELT inverts the traditional order. Instead of "prepare then deliver," the model becomes "deliver raw, prepare on demand" - using the destination system's own power for speed and flexibility.
### CDC: the real-time replication engine
**Change Data Capture (CDC)** focuses on replication efficiency. Instead of copying entire datasets on a schedule, CDC identifies and captures only the incremental changes (updates, insertions, deletions) in source databases as they occur, typically by reading database transaction logs.
Consider a large ERP system with 10 million customer records. A full daily reload is wasteful and puts unnecessary load on the source system. With CDC, after the initial load, the pipeline only transmits the roughly 10,000 records that actually changed that day, not the entire 10 million.
CDC matters most for use cases that need low-latency data, such as:
* Real-time operational dashboards
* Fraud detection systems
* Keeping operational and analytical databases in sync
This approach dramatically reduces load on source systems and network traffic, making it an efficient way to keep a cloud data warehouse current.
### ETL vs ELT vs CDC at a glance
| Attribute | ETL (Extract, Transform, Load) | ELT (Extract, Load, Transform) | CDC (Change Data Capture) |
| :--- | :--- | :--- | :--- |
| **Data Transformation** | Occurs on a separate staging server before loading. | Happens directly within the cloud data warehouse after loading. | Captures only changed data; transformation can follow ETL or ELT logic. |
| **Data State in Warehouse**| Only clean, structured, and transformed data is stored. | Raw, unprocessed data is stored alongside transformed data. | Warehouse data is kept in near real-time sync with the source system. |
| **Ideal Use Case** | Structured data, compliance-heavy industries, on-premise warehouses. | Big data, semi-structured data, fast-paced analytics, data exploration. | Real-time analytics, database replication, minimizing source system load. |
| **Flexibility** | Lower. Transformation logic is fixed before loading. | Higher. Raw data is available for multiple, future transformations. | Highest for data freshness. It's about *what* you move, not *how* you transform it. |
| **Speed to Insight** | Slower, as transformation is a bottleneck upfront. | Faster, as raw data is available for querying almost immediately. | Near-instantaneous for use cases dependent on the latest data. |
Picking the right pattern, or more often a hybrid, is a foundational decision. See [data integration best practices](/insights/data-integration-best-practices/) for a deeper look at these tradeoffs.
## Which cloud integration tool should you use: AWS Glue, Azure Data Factory, GCP Dataflow, Fivetran, or Airbyte?
Choosing the right tool matters as much as choosing the right architecture. The five dominant tools split into two categories: cloud-native managed services (AWS Glue, Azure Data Factory, GCP Dataflow) and cloud-agnostic SaaS connectors (Fivetran, Airbyte). Teams already committed to one cloud generally lean on its native service to minimize egress costs and stay inside the ecosystem; multi-cloud teams tend to prefer Fivetran or Airbyte for their broader connector coverage.
| Tool | Type | Best For | Connector Coverage | Pricing Model | Managed/Serverless |
|---|---|---|---|---|---|
| **AWS Glue** | Cloud-native (AWS) | AWS-native ETL/ELT, Spark-based transforms | AWS services + JDBC | Pay per DPU-hour | Yes |
| **Azure Data Factory** | Cloud-native (Azure) | Azure pipelines, Synapse integration, hybrid on-prem | 90+ connectors | Pay per activity run | Yes |
| **GCP Cloud Dataflow** | Cloud-native (GCP) | Stream + batch on Apache Beam, BigQuery pipelines | GCP services + Beam I/O | Pay per vCPU-hour | Yes |
| **Fivetran** | SaaS connector | Managed ELT with 500+ pre-built connectors | 500+ sources | Consumption-based (MAR) | Yes (fully managed) |
| **Airbyte** | Open-source / SaaS | Self-hosted or cloud, 300+ connectors, customizable | 300+ sources | Open-source free / Airbyte Cloud | Hybrid |
### Cost comparison by tool
Choosing the wrong integration tool can produce cost spikes as data volumes grow. Here's a practical cost range for each option at mid-market scale:
| Tool | Typical Monthly Cost (mid-market) | Key Cost Driver | Hidden Cost Risk |
|---|---|---|---|
| **AWS Glue** | $500-$5,000 | DPU-hours per job run | Inefficient Spark jobs can multiply costs 5-10x |
| **Azure Data Factory** | $400-$3,000 | Activity runs + data movement | Cross-region data movement egress fees |
| **GCP Cloud Dataflow** | $600-$6,000 | vCPU-hours for streaming jobs | Streaming pipelines often cost 3-5x batch equivalents |
| **Fivetran** | $500-$10,000+ | Monthly Active Rows (MAR) | High-volume tables scale pricing fast |
| **Airbyte (cloud)** | $200-$3,000 | Credits per connector sync | Self-hosted option cuts most cost at the expense of engineering time |
*Costs reflect blended mid-market usage. Enterprise data volumes and complex transformation logic can push these figures well beyond the ranges shown.*
## What are the benefits and risks of cloud data integration?
A well-run cloud data integration project creates a real competitive advantage by turning data into an accessible, trustworthy asset. Ignoring the risks, though, can turn the same project into a cost overrun or a compliance problem. A pragmatic approach weighs both sides deliberately.
### The business case for integration
* **Fueling AI and ML work:** Machine learning models depend on a continuous supply of clean, consolidated data. A solid integration strategy is what feeds projects ranging from predictive analytics to generative AI.
* **Sharpening analytics:** A single source of truth removes the silos and conflicting reports that slow down decisions, and teams typically see faster time-to-insight once redundant reconciliation work disappears.
* **Boosting operational efficiency:** Automation replaces brittle manual processes with resilient pipelines, freeing engineers to focus on higher-value work instead of maintenance.
> The core value of cloud data integration is compressing the time between a business event and an informed decision based on it - turning data from a historical record into something closer to a real-time asset.
### What can go wrong
Enterprise data environments are inherently complex, and integration work doesn't remove that complexity so much as manage it. The average enterprise reportedly runs over 300 SaaS applications, each one a potential data silo - see this [overview of enterprise data integration adoption](https://www.integrate.io/blog/data-integration-adoption-rates-enterprises/) for more on the scale involved. The most common risks that follow are cost overruns, compliance failures, and vendor lock-in.
#### Runaway cloud costs
The pay-as-you-go cloud model is flexible, but it can lead to uncontrolled spending if pipelines run inefficiently. A poorly configured job that processes excessive data or runs too frequently can burn through a cloud budget fast.
**Primary drivers of cost overruns:**
* **Inefficient data movement:** High egress fees from moving large volumes between cloud regions or from on-premise systems.
* **Redundant processing:** Rerunning transformations on entire datasets instead of just incremental changes wastes compute.
* **Idle resources:** Over-provisioned compute clusters sitting idle for long stretches.
#### Compliance and governance failures
Moving data across multiple systems and cloud environments introduces real compliance risk. Without strong governance, sensitive data like Personally Identifiable Information (PII) can be exposed, leading to violations of regulations like GDPR or CCPA - and the fines and reputational damage that follow.
#### The strategic cost of vendor lock-in
Choosing a cloud data integration platform is a long-term commitment. Many proprietary tools use unique connectors, transformation languages, and closed architectures that make switching vendors difficult and expensive. That lock-in can slow adoption of better technology and leave you dependent on one vendor's pricing and roadmap. Choosing platforms built on open standards keeps that door open.
## What does cloud data integration security and governance actually require?
Cloud data integration security requires three layers: role-based access control at the pipeline tool level (not just the warehouse), data masking for PII fields during transit through staging environments, and automated lineage tracking for audit trails. Retrofitting security after a production breach is far more expensive, in both direct remediation and reputational cost, than building it in from day one.
Security and governance are too often treated as afterthoughts in data projects, which doesn't hold up in cloud environments. Effective cloud data integration means designing security into the architecture from the start rather than bolting it on later - moving past basic encryption and embedding controls directly into the pipelines themselves. Done right, governance becomes an automated function instead of a manual bottleneck.

### Go beyond basic access controls
Effective governance extends past controlling access to the final warehouse. It requires granular control inside the integration platform itself. **Role-Based Access Control (RBAC)** should apply at the integration layer to manage who can create, modify, and run data pipelines.
> A mature security model asks not "who can access the warehouse" but "who has permission to build, modify, or view the pipelines that feed it." That shift stops unauthorized data movement at its source.
Implementing RBAC within the integration tool allows for specific, granular rules:
* **Data engineers** can get full permissions for specific data domains (marketing pipelines, say) while being denied access to sensitive financial data pipelines.
* **BI analysts** can get read-only access to pipeline logs and metadata for troubleshooting, without the ability to alter pipeline logic.
* **Auditors** can get temporary, view-only access to compliance reports and data lineage maps, meeting regulatory requirements without exposing configuration settings.
This is the principle of least privilege in practice: minimizing the risk of accidental exposure or malicious activity.
### Protect data during transit, not just at rest
Data needs protection not only at rest and in transit but during processing. Pipelines often use temporary staging areas where PII can be exposed if it isn't handled deliberately.
**Data masking** is one of the more effective controls here. Masking techniques should apply during the transformation stage to de-sensitize data before it moves further through the pipeline.
* **Redaction:** Replaces sensitive values with fixed characters (a Social Security Number becomes `XXX-XX-XXXX`).
* **Substitution:** Replaces real values with consistent but fictitious identifiers, allowing behavioral analysis without exposing identity.
* **Shuffling:** Randomizes values within a column, preserving statistical properties while breaking the link to individual records.
Masking data mid-flight makes it useless to anyone who gains unauthorized access to staging environments - which matters for complying with privacy regulations like [GDPR](https://gdpr.eu/tag/gdpr/) and CCPA.
### Maintain clear data lineage for compliance
For auditing and compliance, organizations need to demonstrate the complete lifecycle of their data. **Data lineage** provides that audit trail, tracking data from its source through every transformation to its final destination.
Modern cloud integration platforms can generate and visualize lineage automatically, mapping every data flow. That's useful for debugging pipeline failures and assessing the impact of proposed changes, and it gives compliance teams verifiable proof of how data is handled when regulators ask. See [data pipeline monitoring tools](/insights/data-pipeline-monitoring-tools/) for how lineage tracking fits into a broader monitoring setup.
## How do you evaluate and select the right integration partner?
Evaluating cloud data integration partners means probing three dimensions beyond standard certifications: documented experience with your specific source systems and target warehouse, evidence of cost optimization (efficient connector configurations, incremental loading strategies), and a clear approach to governance and lineage. Certifications are a floor, not a ceiling - the best partners can show real production experience.
Choosing an implementation partner is a critical decision. The right one provides strategic guidance and technical expertise and helps you avoid costly mistakes; the wrong one leads to budget overruns, technical debt, and project failure. This isn't just about procuring a tool - it's about securing proven expertise.
The market for these services is growing quickly. In the U.S. alone, the data integration services market generated USD 7,143.6 million in 2024 and is projected to reach USD 12,113.8 million by 2030, according to this [market outlook](https://www.grandviewresearch.com/horizon/outlook/data-integration-market/united-states). That growth reflects wider recognition that a specialized consultancy is often a more effective path than attempting complex integrations solely in-house.

### Go beyond surface-level certifications
Certifications from platforms like [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/) are a baseline, not a guarantee of expertise. Any consultancy can acquire certifications - the goal is telling apart theoretical knowledge from real, practical experience.
Move past standard questions about successful projects and probe for how a firm handles adversity.
> A partner's competence shows less in their successes than in how they analyze their failures. Ask for an anonymized account of a project that ran into serious trouble, and what specifically was learned from it.
That question cuts through sales rhetoric. A mature firm will give a thoughtful answer that shows some humility and a real process for improvement. An inexperienced firm tends to get defensive or claim it has never had a project fail - a significant red flag.
### The essential RFP checklist
A well-structured Request for Proposal (RFP) is essential for a standardized, objective comparison of potential partners. Your RFP should compel vendors to give specific, evidence-based answers instead of generic marketing material.
Ensure your RFP demands concrete detail on:
* **Industry-specific experience:** Require case studies relevant to your industry. A firm experienced in healthcare compliance is a better fit for a hospital system than one focused exclusively on retail.
* **Team composition and experience:** Request anonymized profiles of the proposed project team. Look for a balanced mix of senior architects and experienced engineers, not a team dominated by junior staff.
* **Technology stack agnosticism:** Assess whether the partner is objective. A consultancy that recommends the same tool for every client may be led by sales incentives rather than your actual needs.
* **Proposed project governance:** Demand a documented methodology for managing communication, timelines, and scope changes. A well-defined process signals discipline.
A rigorous RFP process is what systematically weeds out unsuitable partners. For more on this, review criteria for selecting a [data engineering consulting firm](/data-engineering-consulting-firms/).
### Vendor and consultancy RFP red flags
| Red Flag Category | Specific Warning Sign | Why It Matters |
| :--- | :--- | :--- |
| **Pricing and Contracts** | Vague, bundled pricing models without clear line items. | Obscures the true cost of services and can hide low-value offerings. A detailed cost breakdown is non-negotiable. |
| **Technical Depth** | Over-reliance on a single technology stack or vendor. | A true partner recommends the optimal tool for the problem, not just the tool they know best. |
| **Team and Expertise** | A "bait-and-switch" with the project team. | The senior experts from the sales process get replaced by a junior team post-contract. Insist on meeting the core delivery team. |
| **Communication** | Evasive answers to tough questions, especially about failures. | A lack of transparency during the sales cycle predicts behavior when project challenges show up. |
Identifying these red flags matters as much as analyzing the technical substance of a proposal.
## Cloud Data Integration FAQs
### What is a realistic timeline for a first integration project?
A simple point-to-point connection can be built in days, but a foundational project - integrating a core ERP system with a cloud data warehouse, say - realistically takes three to six months. That timeline covers several non-negotiable phases.
A typical project timeline includes:
* **Discovery and scoping (2-4 weeks):** In-depth analysis of source data quality, business logic, and stakeholder requirements to define a clear scope.
* **Architecture design (2-3 weeks):** Selecting integration patterns (ETL, ELT, CDC) and designing scalable, resilient pipelines.
* **Development and testing (6-12 weeks):** Building pipelines and transformation logic, plus rigorous data validation and performance testing.
* **Deployment and UAT (2-4 weeks):** Go-live followed by User Acceptance Testing, where business stakeholders validate the data and outputs.
Trying to compress these phases usually creates technical debt that costs more to fix later than it would have cost to do right the first time.
### Can a team handle cloud data integration in-house?
Building an in-house team is doable but hard, given how tight the market is for engineers with expertise across multiple cloud platforms and integration tools. Many organizations report an ongoing shortage of qualified data talent, which is part of why an in-house approach tends to work best for large enterprises with substantial budgets and mature IT organizations. For most other companies, a hybrid model or an expert consultancy is the more practical route.
> Outsourcing is a decision to move faster, not a sign of internal weakness. An experienced partner brings frameworks and cross-industry pattern recognition that can save an internal team months of trial and error.
A common and effective approach is to bring in a partner for the initial architectural design and implementation while upskilling the internal team to handle long-term maintenance.
### How do you choose between a platform and custom code?
This is the classic build-versus-buy question. Custom scripts (in Python, say) can work for simple, isolated tasks, but a dedicated integration platform is almost always the better long-term choice for enterprise needs, based on total cost of ownership rather than upfront price.
* **Custom code:** Needs specialized developers for both initial build and ongoing maintenance. It typically lacks built-in governance, monitoring, and error handling, and scaling gets harder as each new source needs custom development.
* **Integration platform:** Provides pre-built connectors, automated security and governance, visual development, and out-of-the-box monitoring and alerting. The license cost is higher upfront, but operational overhead drops significantly over time.
Organizations that lean on custom scripts often find maintenance eats the majority of their data engineering time, leaving little room for new work.
### What are the most common hidden costs?
Standard budgets usually account for software licensing and cloud compute, but several other costs tend to show up unexpectedly. Planning for them ahead of time avoids budget overruns.
* **Data egress fees:** Cloud providers charge for moving data out of their networks or between geographic regions. An inefficiently designed pipeline that transfers large datasets frequently can rack up substantial fees.
* **Rework from poor data quality:** Skipping data profiling and cleaning at the source shows up downstream as broken pipelines, inaccurate analytics, and wasted engineering time.
* **Ongoing maintenance and optimization:** Source system APIs change, business requirements evolve, and data volumes grow. A common budgeting rule of thumb is to set aside an additional 15-20% of the initial project cost each year for ongoing maintenance and enhancements.
Anticipating these second-order costs is what keeps a project on budget and delivering the return it was supposed to.
---
Picking the right architecture and tool only gets you halfway - the rest comes down to execution. If you're deciding between ETL and ELT for a specific project, [ETL tools comparison](/insights/etl-tools-comparison/) breaks down the leading platforms in more detail, and [Fivetran vs. Airbyte](/insights/fivetran-vs-airbyte/) covers the two most common SaaS connectors head to head. Once you're ready to bring in outside help, the RFP checklist above doubles as a scorecard for vetting a [data engineering consulting firm](/data-engineering-consulting-firms/) - ask how they handle each item, not just whether they've done integration work before.
---
## Your Cloud Migration Assessment Checklist: A Practical 10-Point Framework
Source: https://dataengineeringcompanies.com/insights/cloud-migration-assessment-checklist/
Published: 2025-12-20T07:25:10.587925+00:00
Description: Discover the cloud migration assessment checklist to plan cost, security, data, and vendor decisions for a successful 2026 migration.
A cloud migration assessment means running formal checks across ten areas before you move anything: the business case, current infrastructure, security and compliance, organizational readiness, data strategy, application architecture, network performance, disaster recovery, vendor fit, and testing. Treat any of these as optional and you inherit a problem in production that a week of assessment work would have caught on paper.
This guide walks through all ten checkpoints, framed as questions a technical lead or PM should be able to answer before signing off on a migration budget, plus a comparison table for weighing complexity against resourcing. Migration shows up in 78 of the 86 firm profiles in the [Data Engineering Companies Index](/data-migration-companies/) - which makes the assessment the real differentiator, since most vendors claim the capability but few show up with a structured plan for your specific environment.
## 1. Why does a cloud migration start with a business case and cost analysis?
A migration without a documented business case has no way to justify budget, measure success, or survive the first cost overrun. Build a total cost of ownership (TCO) comparison, an ROI projection, and a list of intangible benefits like agility and scalability before you start evaluating vendors or architectures.
Budgets run over most often when the business case skips hidden costs and treats the move as a technical exercise instead of a financial one. A retailer weighing a shift to a managed data platform needs the business case to spell out whether the win is cost savings, faster reporting, or both - those two goals lead to different architectures, and conflating them is how scope creeps.
### Actionable Implementation Tips
* **Run a TCO comparison.** Use the AWS TCO Calculator or Azure Cost Management to weigh current on-premises costs (hardware, software, maintenance, real estate, power) against projected cloud spend.
* **Find the hidden costs.** Data egress fees, cloud-native licensing, and the cost of hiring or training staff with cloud skills rarely make it into the first draft of a budget. This [data engineering cost calculator](/data-engineering-cost-calculator/) is a useful starting point for modeling them.
* **Model more than one scenario.** Build best-case, worst-case, and most-likely projections, and budget a contingency buffer for the complexity you can't estimate yet.
* **Revisit pricing quarterly.** Provider pricing models and your own usage patterns both change - review them regularly to catch new discount options like Reserved Instances or Savings Plans.
## 2. Why does migration planning start with a full infrastructure and application inventory?
You can't plan a route without knowing your starting point. A precise inventory of every server, application, database, and their dependencies sets the baseline that determines cost estimates, timeline feasibility, and which applications are migration candidates versus retirement candidates.
Skipping this step is how migrations get lost midway through - a dependency nobody mapped turns into a production outage weeks after the plan was signed off. An organization consolidating a large legacy application portfolio typically finds a meaningful share are better candidates for retirement than migration, and that's much cheaper to learn during the inventory than during cutover.
### Actionable Implementation Tips
* **Automate discovery.** Tools like AWS Application Discovery Service, Azure Migrate, or third-party platforms such as Flexera collect server configurations, performance metrics, and network connections without a manual audit.
* **Document business criticality, not just assets.** Interview application owners to assign a criticality rating (high, medium, low) to each system - that rating is what drives migration sequencing.
* **Build dependency maps.** Turn discovery-tool data into diagrams showing how applications, databases, and servers interact, so you can group interdependent assets into "move groups" that need to migrate together.
* **Track utilization before you size anything.** Collect CPU, RAM, and storage I/O data over 30-90 days so cloud instances get sized to actual usage instead of guesswork - a common source of wasted spend.
## 3. How do you assess security and compliance requirements before migrating?
List every regulatory, industry, and internal security standard that applies to your data, then map each one to how it will be enforced under the cloud's shared-responsibility model - the provider secures the cloud itself, you stay responsible for what runs on it.
Skipping this mapping is how migrations end up non-compliant after the fact, which is a far more expensive fix than building it in from day one. A healthcare organization moving protected health information needs a signed Business Associate Agreement with its cloud provider, plus encryption and access controls that satisfy [HIPAA](https://www.hhs.gov/hipaa/for-professionals/index.html), before any patient data moves - not after.
### Actionable Implementation Tips
* **Run a compliance gap analysis.** List every applicable regulation (GDPR, CCPA, PCI DSS, HIPAA) and map it against your target provider's certifications, using resources like the AWS Compliance Center or Microsoft Trust Center.
* **Map every control, not just the big ones.** For each on-premises security control, document its cloud-native replacement - an on-premises firewall typically becomes a combination of network security groups, a web application firewall, and cloud-native threat detection.
* **Bring in compliance and legal early.** Their read on how regulations apply under the shared-responsibility model should shape architecture decisions, not review them after the fact.
* **Set data governance policy before migration starts.** Define data classification, encryption at rest and in transit, and access management up front - see [data governance consulting](/insights/data-governance-consulting/) for a fuller framework.
## 4. Why does cloud migration need organizational readiness and change management?
Technology can be provisioned in minutes; reskilling people and shifting how a team works takes months. Map every group affected by the migration, from executive sponsors to the analysts running daily reports, and build training and communication for each before cutover, not after adoption stalls.
Without a change plan, teams tend to revert to familiar workflows even after a technically clean migration, which quietly reintroduces the inefficiencies the project was meant to fix. A cross-functional Cloud Center of Excellence - a standing group of cloud advocates and architects - gives the organization a place to own best practices and field questions, instead of leaving each business unit to work it out alone.
### Actionable Implementation Tips
* **Run a skills gap analysis.** Compare your team's current cloud competencies against what the target environment needs - Terraform for infrastructure as code, Kubernetes for orchestration - and build a training plan around the gaps.
* **Stand up a Cloud Center of Excellence.** A cross-functional group of architects and operations specialists that standardizes practices and supports the migration across business units, rather than leaving each team to reinvent it.
* **Build a communication plan.** The [ADKAR model](https://www.prosci.com/methodology/adkar) (Awareness, Desire, Knowledge, Ability, Reinforcement) is a useful structure for explaining why the migration is happening and addressing concerns directly.
* **Recruit champions in each department.** Peer advocates who can answer questions and model the new workflow tend to drive adoption faster than a top-down announcement.
## 5. What does a data migration strategy need to cover?
Data migration is usually the highest-risk phase of any cloud move, so the plan needs to cover data volume, transfer method, validation, and acceptable downtime before a single table moves. The goal is turning the highest-stakes part of the project into a scheduled, testable process instead of a leap of faith.

Without a validation plan, a migration can quietly move corrupted or incomplete data into the new environment, and nobody notices until a report doesn't tie out weeks later. A migration that can't tolerate downtime typically runs a phased, trickle approach - active data replicates continuously while historical archives move in bulk on a separate track, shrinking the cutover window to almost nothing. For a broader walkthrough of this discipline, see [data migration best practices](/insights/data-migration-best-practices/).
### Actionable Implementation Tips
* **Classify data before choosing a method.** Criticality, volume, and how often it changes determine whether a dataset fits a big-bang cutover or needs a phased, trickle migration.
* **Match the tool to the transfer.** Physical appliances like AWS Snowball or Azure Data Box for large offline transfers; a service like AWS Database Migration Service or Azure Database Migration Service for continuous online migration.
* **Plan for transformation, not just transfer.** Schema changes, data type conversions, and enrichment rarely happen in a like-for-like move - use a cloud staging area to perform and validate transformations before loading into the target system.
* **Automate validation.** Checksums, row counts, and sample queries catch integrity issues far more reliably than manual spot-checking, especially at petabyte scale.
## 6. How do you decide which migration strategy fits each application?
The "6 Rs" framework gives technical teams a shared vocabulary for deciding how to move each application, because a monolithic legacy system and a containerized microservice don't belong on the same migration path.
| Path | What it means |
| --- | --- |
| Rehost | Lift-and-shift; fits apps with no code access or where speed matters more than optimization. |
| Replatform | Minor cloud optimization, like moving a database to a managed service (e.g., RDS). |
| Refactor | Re-architect for cloud-native features; highest effort, highest potential payoff. |
| Repurchase | Replace with a SaaS product instead of migrating the existing app. |
| Retire | Decommission - the application is no longer needed. |
| Retain | Keep on-premises, usually due to compliance or tight interdependency. |
Default to rehosting everything and you get a quick migration that fails to use any cloud-native capability, which shows up later as high costs and flat performance. A legacy CRM is often a better fit for repurchasing a SaaS alternative than for a costly refactor, while a core, differentiating application might justify rebuilding as serverless to get real scalability out of the move.
### Actionable Implementation Tips
* **Classify every application against the 6 Rs.** Systematic categorization up front prevents defaulting to rehost by inertia.
* **Sequence migration waves by risk.** Start with low-risk Rehost or simple Replatform candidates to build internal expertise before tackling a Refactor.
* **Evaluate SaaS-first before committing to a rebuild.** A market-leading SaaS product can often meet the business need faster than a Replatform or Refactor.
* **Map dependencies before grouping waves.** Application dependency mapping tools show which systems have to move together - see [data orchestration platforms](/insights/data-orchestration-platforms/) for how these dependencies carry through into pipeline design downstream.
## 7. What does a network and performance assessment need to check?
Map the bridge between your current infrastructure and the cloud - connectivity, bandwidth, latency, and how each application performs once it moves - before cutover, not after users start complaining. An application that runs fine on a local network can turn sluggish over a wide-area connection to the cloud.
This gets missed most often with latency-sensitive workloads: a system that performed well on-premises may need dedicated network connections to hold the same performance in the cloud, and finding that out after go-live is expensive. A financial services workload with strict latency requirements typically needs dedicated connectivity rather than a standard VPN to keep response times where the business needs them.
### Actionable Implementation Tips
* **Baseline current performance first.** Document response times, throughput, and latency between application tiers before migrating, so you have a real benchmark for post-migration success.
* **Evaluate dedicated connectivity for critical workloads.** Services like AWS Direct Connect or Azure ExpressRoute bypass the public internet for more consistent bandwidth and lower latency than a standard VPN.
* **Load-test before the final cutover.** Simulate real traffic and transfer volumes against a proof-of-concept environment to expose bottlenecks while they're still cheap to fix.
* **Plan for content delivery.** A CDN like Amazon CloudFront or Azure CDN caches content closer to users if your application serves a geographically distributed audience.
## 8. How do you plan for disaster recovery and business continuity during migration?
Disaster recovery planning covers more than backups - it means designing systems that survive an outage and defining how the business keeps running with minimal disruption during and after the cutover itself, when the risk of something going wrong is highest.
Without a documented DR strategy, an outage or a failed cutover can turn into extended downtime and real revenue loss - the cost of skipping this step tends to show up exactly when you can least afford it. A financial services firm running a multi-region architecture can fail traffic over to a secondary region automatically if the primary region goes down, keeping critical services online through the kind of event that would otherwise be a full outage.
### Actionable Implementation Tips
* **Set RTO and RPO targets per application.** Recovery Time Objective (how fast you need to be back online) and Recovery Point Objective (how much data loss is tolerable) determine whether you need simple backups or active-active multi-region failover.
* **Use cloud-native DR tooling.** [Azure Site Recovery](https://azure.microsoft.com/en-us/products/site-recovery) or AWS Elastic Disaster Recovery automate replication and failover for on-premises or cloud virtual machines, cutting manual intervention during an actual incident.
* **Run DR drills on a schedule, not just once.** Quarterly drills that simulate everything from a single application failure to a full regional outage are what validate the plan actually works.
* **Write runbooks and automate what you can.** Step-by-step recovery procedures, backed by infrastructure as code where possible, reduce the chance of human error during a high-stress failover.
## 9. How do you evaluate and select a cloud vendor?
Compare AWS, Azure, and Google Cloud (or a subset) against a weighted scorecard covering technical capability, pricing, SLA terms, and roadmap fit, not just the platform your team already knows. The choice functions as a long-term partnership, not a one-time procurement decision.
Defaulting to the most familiar platform is how teams miss a competitor that would have been the better fit for a specific workload - stronger analytics tooling, better pricing for a particular usage pattern, or data center presence in a region that actually matters to the business. A proof-of-concept deployed on the top two or three candidates surfaces more real information about API quality and support responsiveness than any vendor pitch does.
### Actionable Implementation Tips
* **Build a weighted scoring matrix.** Compare compute and storage performance, analytics and ML capabilities, compliance certifications, and data center presence across candidates objectively.
* **Issue a formal RFP.** Include workload specifications and performance requirements so shortlisted vendors return comparable, tailored pricing and architecture recommendations - see the [data engineering RFP checklist](/data-engineering-rfp-checklist/) for what to include.
* **Read the SLA fine print.** Uptime guarantees, performance commitments, and the actual remedies offered for a service failure vary more between providers than the marketing suggests.
* **Run a proof-of-concept before committing.** Deploying a small, non-critical workload on your top candidates gives you real experience with each provider's console, APIs, and support team.
## 10. What does a migration testing and QA plan need to include?
Test functionality, performance, and security across the migrated environment as a continuous workstream through the whole migration, not a final check before go-live. The plan needs to confirm the new environment meets or beats the benchmarks the on-premises system was already hitting.
Skip a structured test plan and issues like broken integrations or performance regressions surface after cutover instead of before it, which turns a fixable bug into an outage with users already depending on the new system. A pre-production environment that mirrors the target architecture is what makes load testing and user acceptance testing meaningful instead of theoretical.
### Actionable Implementation Tips
* **Mirror production before testing anything else.** A pre-production environment matching the target cloud architecture is a prerequisite for accurate performance, load, and user acceptance testing.
* **Automate regression testing.** Tools like Selenium for functional tests and a CI pipeline for automated execution make repeatable validation possible instead of a one-time manual pass.
* **Load-test against realistic traffic.** A load generator like JMeter simulates peak demand and exposes bottlenecks before real users do.
* **Fold security testing into QA, not around it.** Penetration testing, vulnerability scanning, and configuration review belong in the same workstream as functional testing, run before go-live.
## How do the ten migration checkpoints compare on effort and risk?
Complexity and resourcing needs scale together for most of these checkpoints, which is why sequencing matters as much as coverage - the highest-effort items (security, data migration, application architecture) also carry the highest cost if you skip them.
| Checkpoint | Implementation complexity | Resource requirements | Expected outcomes | Ideal use cases | Key advantages |
| --- | --- | --- | --- | --- | --- |
| Business Case and Cost Analysis | Low-Medium - financial modeling and analysis | Finance leads, cost tools, stakeholder time | TCO, ROI, budget plan, cost risks identified | Executive approval, budgeting, large migrations | Justifies investment, reveals savings, prevents overruns |
| Current Infrastructure and Application Inventory | Medium-High - discovery and mapping effort | Discovery tools, app owners, inventory scanners | Complete asset inventory, dependency maps, baselines | Large or legacy estates, initial planning phases | Prevents omissions, aids capacity and license planning |
| Security and Compliance Requirements | High - regulatory mapping and controls design | Compliance experts, security tooling, audits | Compliance mappings, controls, data governance plan | Regulated industries (healthcare, finance, government) | Ensures compliance, strengthens security posture |
| Organizational Readiness and Change Management | Medium - training and cultural programs | Change leads, trainers, time for adoption | Skills gap closure, communication plan, adoption metrics | Large orgs, reskilling initiatives, cultural shifts | Increases adoption, reduces resistance and delays |
| Data Migration Strategy and Planning | High - complex data movement and validation | Data transfer tools, validation scripts, storage | Validated transfers, migration schedule, rollback plans | Petabyte-scale moves, critical data migrations | Minimizes data loss, reduces downtime, ensures quality |
| Application Architecture and Rehosting Strategy | High - per-app technical analysis | Solution architects, modernization tools, dev effort | 6R-based migration plan, modernization roadmap | Mixed app portfolios, modernization programs | Optimizes approach per app, identifies modernization wins |
| Network and Performance Assessment | Medium-High - network testing and tuning | Network engineers, load test tools, bandwidth upgrades | Connectivity plan, latency baselines, optimization needs | Latency-sensitive apps, global services | Prevents performance degradation, supports SLAs |
| Disaster Recovery and Business Continuity Planning | Medium - DR design and testing | DR tools, automation, multi-region resources | RTO/RPO targets, failover and failback procedures, drills | Mission-critical systems, high-availability needs | Improves recovery time, reduces business disruption |
| Vendor Selection and Comparison | Medium - evaluation and negotiation | Procurement, RFPs, technical evaluation teams | Selected provider(s), contract terms, cost models | Choosing cloud provider(s), multi-cloud strategies | Ensures provider fit, reduces vendor risk, enables negotiation |
| Testing and Quality Assurance Plan | Medium-High - comprehensive testing cycles | QA teams, test environments, automation tools | Functional, performance, security validation, rollback plans | Production cutovers, high-reliability systems | Catches issues pre-cutover, reduces post-migration incidents |
## Turning the checklist into an execution plan
These ten checkpoints work as a system, not a sequence to rubber-stamp in order. The business case sets the budget; the inventory sets the scope; security and data strategy set the technical constraints; and testing is what confirms the other nine held up under real conditions. Skip one and the risk doesn't disappear - it resurfaces later, in production, at a worse time to fix it.
Most teams underinvest in the same two checkpoints: organizational readiness and network performance. Both are easy to defer because nothing breaks during planning - the gap only shows up after go-live, once users are stuck with a slow application or reverting to the old workflow because nobody prepared them for the new one.
Once the assessment is done, it becomes the scorecard for evaluating a migration partner - not just whether a vendor has done migrations before, but whether they can walk through how they'd handle each of these ten areas for your specific environment. If you're still deciding between platforms, [Snowflake vs. Databricks](/snowflake-vs-databricks/) covers that architecture decision, and [cloud migration consulting services](/insights/cloud-migration-consulting-services/) covers what a structured engagement with an outside partner should look like.
---
## A Pragmatic Guide to Cloud Migration Consulting Services for Data Leaders
Source: https://dataengineeringcompanies.com/insights/cloud-migration-consulting-services/
Published: 2026-02-10T09:29:55.592694+00:00
Description: A practical guide to cloud migration consulting services. Learn to choose partners, manage costs, and execute a successful data platform modernization.
Cloud migration consulting services provide the strategy, security engineering, and platform expertise needed to move enterprise data infrastructure to Snowflake, Databricks, or a hyperscaler cloud without breaking the systems that depend on it. It is not a server swap - it is a re-engineering of how the business runs, and it calls for skills most internal IT teams have not had the chance to build on their own systems.
Migration is the most common capability firms in this space list: 78 of the 86 firms profiled in the [Data Engineering Companies Index](/data-migration-companies/) name data migration among their services, though far fewer have actually run one end to end without a budget overrun. This guide covers when to hire a consultant, how to pick a migration strategy, what a project really costs, and what to demand in the contract before you sign it.
## Why hire cloud migration consultants instead of building the team in-house?
Migrating complex systems to platforms like [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/) calls for niche expertise most internal teams have not built yet. A consulting partner that has run hundreds of these projects has already solved the problems your team is about to hit for the first time, which compresses timelines and cuts the risk of costly rework.
When constructing a high-tech manufacturing facility, you engage architects and structural engineers with a portfolio of similar projects. They understand the material demands, the likely points of failure, and how to execute correctly on the first attempt. Migrating complex data systems to the cloud is an analogous engineering challenge, requiring deep, niche expertise that goes far beyond general cloud proficiency.
### Risk mitigation and project acceleration
Engaging cloud migration consulting services is an exercise in risk management and timeline compression. A seasoned consulting partner has executed hundreds of these projects and has already encountered and solved the precise problems your team is about to face for the first time.
This experience matters for avoiding common, high-impact errors. The focus is on delivering measurable business outcomes:
* **Risk mitigation.** Consultants apply proven frameworks to manage security, compliance, and data governance, protecting data when it is most vulnerable.
* **Accelerated timelines.** They use established methodologies and automation tools that can significantly shorten the project lifecycle from planning to a fully operational system.
* **Cost predictability.** An effective partner helps avoid "bill shock" by accurately forecasting cloud expenditure and implementing cost management practices from day one.
For a deeper look at what these engagements typically include, see this overview of [cloud migration services](https://www.cloudorbis.com/blog/cloud-migration-services).
### Accessing expertise you would otherwise spend years building
Building an in-house team with real depth in cloud architecture, data engineering, and security takes years, and a few failed hires along the way. Consulting services exist because they offer a faster, more practical path to that same expertise.
For data leaders, partnering with an experienced firm de-risks the modernization project itself. A team that has already tuned dozens of Snowflake or Databricks environments tends to catch the licensing waste and misconfigured clusters that an internal team, learning the platform for the first time, typically misses.
> Hiring a consultant is not an admission of internal weakness. It is a strategic decision to use external, battle-tested expertise to ensure a complex, mission-critical project succeeds and delivers a measurable business outcome.
What, specifically, should you expect from a consulting partner? Here are the core components of a typical engagement.
### Core components of a cloud migration engagement
A well-structured migration is not a monolithic task but a series of distinct phases, each with its own objectives and deliverables. This roadmap approach ensures a comprehensive transition from the current state to the target cloud environment.
Here is a breakdown of the typical service components a competent cloud migration partner should provide.
| Service Component | Objective and Key Activities | Primary Deliverable |
| :--- | :--- | :--- |
| **Discovery & Assessment** | Analyze the current state, identify technical and business dependencies, and define success criteria. Involves stakeholder interviews, infrastructure audits, and application portfolio analysis. | **Migration Readiness Report & Business Case** |
| **Strategy & Planning** | Design the target cloud architecture, select the optimal migration strategy (e.g., rehost, replatform), and develop a detailed project roadmap with timelines and resource allocation. | **Migration Plan & Target State Architecture** |
| **Execution & Migration** | Build the foundational cloud environment, migrate applications and data in planned waves, and conduct rigorous functional and performance testing. | **Deployed Cloud Environment & Migrated Workloads** |
| **Optimization & Governance** | Fine-tune performance, implement cost controls (**FinOps**), and establish long-term governance policies for security, compliance, and operational management. | **Optimized & Secure Cloud Operations Framework** |
Each stage is logically dependent on the previous one, ensuring the technical solution aligns directly with business objectives from inception.
## Which cloud migration strategy fits: rehost, replatform, or rearchitect?
The right strategy depends on what you are optimizing for. Rehosting ("lift-and-shift") moves fastest but carries existing technical debt into the cloud unchanged. Replatforming makes targeted upgrades along the way. Rearchitecting rebuilds applications to be cloud-native and delivers the largest long-term gains, for the largest upfront cost. Cloud migration consulting services provide the analytical rigor to pick between them.
Think of it as moving a business physically. How you choose to transport people and equipment from one location to another involves trade-offs in time, cost, and effort. The same trade-offs apply to migrating data and applications.
### Rehosting: the "lift-and-shift" approach
Rehosting, or **lift-and-shift**, is the most direct migration path. It is analogous to moving the entire contents of a facility to a new location without modification. The process is fast and minimally disruptive.
This approach is best suited for organizations facing a hard deadline, such as an expiring data center lease. The primary benefit is speed. The significant drawback is that existing architectural inefficiencies and technical debt are carried over to the cloud, often resulting in suboptimal performance and higher-than-expected operational costs.
The flowchart below provides a simple framework for evaluating these options based on key business drivers: risk, speed, and required expertise.
The choice of strategy represents a direct trade-off between speed-to-cloud and realizing the full potential of cloud-native capabilities.
### Replatforming: the "lift-and-reshape" approach
Replatforming, or **lift-and-reshape**, balances speed with optimization. In our analogy, this is like moving all your equipment but upgrading key machinery to take advantage of the new facility's improved power and cooling systems. You are not redesigning the entire production line, but making targeted upgrades for immediate efficiency gains.
A common example is migrating an on-premises SQL database to a managed cloud service like [Amazon RDS](https://aws.amazon.com/rds/) or [Azure SQL](https://azure.microsoft.com/en-us/products/azure-sql). With minor code modifications, you can use cloud-native features such as automated backups and dynamic scaling without a full application rewrite. It is a pragmatic middle ground that delivers tangible value without the complexity of a complete overhaul.
### Rearchitecting: the full modernization
Rearchitecting, also known as **refactoring**, is the most resource-intensive strategy but offers the greatest long-term benefits. This is equivalent to a full facility gut and renovation, rebuilding systems to maximize efficiency and output for the next decade.
> This path involves fundamentally rebuilding applications to be cloud-native, often using modern architectural patterns like serverless functions, containers, and microservices. It is how you achieve maximum performance, scalability, and cost efficiency.
Rearchitecting is the necessary path when legacy systems cannot support future business requirements, such as real-time analytics or large-scale AI/ML model training. It requires the largest upfront investment but positions the organization for maximum agility and innovation. If you are considering this strategy, our [cloud migration assessment checklist](https://dataengineeringcompanies.com/insights/cloud-migration-assessment-checklist) provides a structured starting point for the discovery phase.
Ultimately, selecting a strategy is a business decision, not purely a technical one. A competent consulting partner will help you weigh the trade-offs of each approach, ensuring your migration plan directly supports your company's strategic goals.
## What does a cloud migration actually cost, and how long does it take?
Total cost of ownership includes consulting fees, new cloud consumption, software licensing, and the opportunity cost of your internal team's time, not just the consultant's invoice. Underestimating that full picture is one of the primary causes of migration budget overruns and stakeholder frustration.
### Deconstructing your total migration investment
Think of it like building a house. The architect's fee is just the beginning. You still have to buy the lumber, wire, and drywall, pay for permits, and hire the crew to put it all together. A cloud migration budget works the same way, with a few key components you have to plan for.
Your budget should include line items for:
* **Consulting fees.** The direct cost for external expertise in strategy, architecture, and execution.
* **Cloud consumption.** The recurring operational expense from [AWS](https://aws.amazon.com/), [Azure](https://azure.microsoft.com/), or [GCP](https://cloud.google.com/). This represents a shift from capital expenditure (CapEx) to operational expenditure (OpEx).
* **Duplicate environments.** For a period, you will pay for both the legacy on-premises infrastructure and the new cloud environment. This "migration bubble" is a temporary but significant cost.
* **Internal team time.** The salaried time of your key personnel who will be involved in the project. This is a real and substantial cost, and the one budgets most often leave out.
Quantifying these expenses early matters. Implementing disciplined [cloud cost optimization best practices](https://www.cloudxray.ai/blog/cloud-cost-optimization-best-practices) from the project's inception prevents significant financial waste later.
### Benchmarking project timelines and costs
The primary driver of your timeline and budget is scope. Migrating a single departmental data mart is an entirely different undertaking than modernizing an enterprise-wide data platform. Data volume, application complexity, and the chosen migration strategy all have a direct and significant impact.
> A frequent error is misjudging the complexity of a legacy system as a simple "lift-and-shift." Deeper analysis often reveals tangled dependencies and undocumented business logic that force a more complex replatforming effort, invalidating the original schedule and budget.
While large enterprises still dominate market share, small and medium-sized businesses are increasingly migrating to the cloud too, a sign that migration budgets are no longer just an enterprise line item.
### Example cloud migration costs by project scope
To provide a pragmatic baseline, this table offers high-level estimates. Use these as a starting point for internal budget discussions, not as firm quotes. Their purpose is to help set realistic expectations.
| Project Scope | Estimated Timeline | Typical Consulting Cost Band (USD) | Key Influencing Factors |
| :----------------------------- | :----------------- | :--------------------------------- | :------------------------------------------------------------------------ |
| **Departmental Data Mart** | 3-6 Months | $75,000 - $250,000 | Limited data sources, simple business logic, clear stakeholder alignment. |
| **Multi-Source Data Warehouse** | 6-12 Months | $250,000 - $750,000 | Multiple data sources, moderate data transformation complexity, some legacy dependencies. |
| **Enterprise Data Platform** | 12-24+ Months | $750,000 - $2M+ | High data volume, complex integrations, significant re-architecting, stringent security needs. |
The range is wide. Project complexity, driven by data volume, integrations, and security requirements, is the primary determinant of where an initiative lands on this spectrum.
## How do you evaluate and choose a cloud migration consulting partner?
Filter first on relevant technical depth, not hourly rate. A partner who lacks experience in your regulated industry will be learning on your project and your budget. Verify certifications, request industry-specific case studies, and confirm the senior architects who pitch you are the same people who will do the work.
This is not about finding the lowest hourly rate. A low-cost proposal often indicates a less experienced team or a standardized approach that ignores your specific business context. Real value comes from a partner with demonstrable technical expertise, a transparent methodology, and a vested interest in your success.

The market for these services is expanding rapidly, which makes rigorous due diligence more important, not less. Because North America remains the largest market for these services, a partner's familiarity with regional compliance frameworks like HIPAA or GDPR is not optional.
### Verifying technical and industry expertise
Your initial filter should be direct: is their expertise deep and relevant to your specific needs? A consultancy might claim hundreds of cloud engineers, but if they lack experience migrating platforms in your regulated industry (finance, healthcare, or similar), they will be learning on your project and your budget.
Demand concrete evidence of their capabilities:
* **Platform-specific certifications.** Don't ask if they work with [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/). Ask for the number of certified professionals and their certification levels (for example, SnowPro Advanced Architect). This is an objective measure of their investment in the technology.
* **Industry-relevant case studies.** Request case studies from companies of a similar scale and in your industry. A successful migration for a retail data warehouse presents different challenges than one for a healthcare analytics platform governed by HIPAA.
* **Methodology and accelerators.** An experienced firm will have a refined migration methodology. Ask them to present it and detail any proprietary tools or "accelerators" they use for tasks like data validation or code conversion, which can reduce manual effort.
### Critical questions for your RFP
Your Request for Proposal is your primary tool for differentiating true experts from generalists. Move beyond marketing claims and investigate their operational processes, problem-solving capabilities, and approach to knowledge transfer.
> A strong consulting partner's goal is to make themselves obsolete. Their objective should be to successfully migrate the platform and execute a comprehensive knowledge transfer, enabling your team to operate it independently.
Here are five essential questions to include in your evaluation:
1. **"Describe your risk mitigation framework and how you would apply it to our specific project."** This tests their foresight. A strong answer will detail how they identify, quantify, and plan for technical, operational, and financial risks before they materialize.
2. **"How do you ensure comprehensive knowledge transfer to our internal team?"** Look for a structured plan that includes paired programming, rigorous documentation standards, and dedicated training sessions. A vague promise of "collaboration" is insufficient.
3. **"Walk us through a past project that faced significant, unexpected challenges. How did you resolve it?"** This question reveals their real-world problem-solving skills and integrity. All large projects encounter obstacles; you need a partner who takes ownership and resolves issues, not one who assigns blame.
4. **"What is your governance model for project communication, reporting, and change management?"** A professional firm will describe a clear cadence of status meetings, executive dashboards, and a formal change control process to prevent scope creep.
5. **"How do you measure success, and what specific KPIs will you report on throughout the engagement?"** This ensures your definition of "done" aligns with theirs. Look for metrics beyond "on time and on budget," such as improvements in query performance, cost reduction targets, or data quality scores.
### Red flags to watch out for
Spotting negative indicators matters as much as recognizing positive ones. These signs can signal inexperience, a lack of transparency, or a poor cultural fit.
* **Vague proposals.** A proposal lacking detail on deliverables, timelines, and scope is a warning. A detailed Statement of Work (SOW) will be explicit about what is in scope and, equally important, what is out of scope.
* **A "bait and switch" team.** The senior architects involved in the sales process must be the same individuals leading the project. Secure written commitments on key personnel who will be dedicated to your engagement.
* **Lack of client references.** A firm with a strong track record will be eager for you to speak with past clients. Hesitation or excuses are significant red flags.
Selecting the right cloud migration consulting services is a strategic decision, not a simple procurement. By focusing on verifiable expertise, asking incisive questions, and staying alert for red flags, you can find a partner that guides you to a successful outcome.
## What are the most common cloud migration pitfalls?
The three recurring failure points are surprise cloud bills ("bill shock") from workloads moved without re-architecting for consumption-based pricing, performance regressions when legacy applications run unmodified in the cloud, and security gaps from treating cloud infrastructure like an extension of the old data center instead of a new shared-responsibility model.
These issues are rarely unforeseeable and are often not purely technical. They frequently stem from misaligned expectations regarding cost, performance, and security. Without a clear-eyed assessment of these risks, a project can be perceived as a failure by the business, even if the technical cutover is successful.
### Preventing post-migration bill shock
A common negative outcome for newly migrated companies is the arrival of the first cloud invoice. A bill that is an order of magnitude higher than anticipated is known as "bill shock." It occurs when workloads are moved without re-architecting for cloud consumption models. This is analogous to moving into a larger facility and leaving all equipment running 24/7, then being surprised by the utility bill.
The solution is a proactive cost management discipline, commonly referred to as [**FinOps**](https://www.finops.org/introduction/what-is-finops/). This has to be built into the migration plan from the outset, not added as an afterthought.
* **Establish a cost allocation model.** Before migration, define a strategy for tracking expenditures. A combination of account-based and tag-based costing lets you attribute every dollar of cloud spend to the correct team, project, or environment, eliminating untracked costs.
* **Implement budget alerts.** Configure automated notifications that trigger when spending approaches predefined thresholds. This turns cost management from a reactive reporting function into a proactive, real-time activity.
* **Practice migration hygiene.** After each migration wave, consultants must be rigorous about decommissioning temporary resources. This includes shutting down migration servers and deleting obsolete storage snapshots, which can silently accrue significant costs.
### Managing unexpected performance issues
Another pitfall is the assumption that an application performing adequately on-premises will perform identically in the cloud. This is often not the case. Legacy applications, in particular, were not designed for the latency and distributed nature of cloud environments, which can lead to significant performance degradation post-migration.
> A critical error is treating the cloud as merely a remote data center. True performance gains are achieved by adapting applications to use cloud-native services, not by running legacy software on virtual machines.
This is where a thorough, candid assessment during the discovery phase is invaluable. Consultants should identify applications sensitive to latency or with complex interdependencies. For these high-risk systems, a simple "lift-and-shift" is typically the wrong strategy. Replatforming or refactoring is often necessary to ensure they meet or exceed their previous performance benchmarks. You can find a deeper analysis of these strategies in our guide on [data migration best practices](https://dataengineeringcompanies.com/insights/data-migration-best-practices).
### Securing your new cloud environment

Cloud security operates on a [**shared responsibility model**](https://aws.amazon.com/compliance/shared-responsibility-model/). The cloud provider (AWS, Azure, or GCP) secures the underlying infrastructure, but the customer is fully responsible for securing their data, applications, and access controls. A common mistake is migrating to the cloud without a clear security plan adapted to this operational model.
It requires a different security paradigm, one centered on identity and data access.
* **Identity and Access Management (IAM).** From project inception, enforce the principle of least privilege. Each user and application should be granted only the minimum permissions required for its function.
* **Data encryption.** Ensure data is encrypted everywhere: both in transit over the network and at rest on storage volumes.
* **Compliance mapping.** For regulated industries like finance or healthcare, consultants must map existing compliance controls (HIPAA, PCI DSS, and similar) to the new cloud services to ensure no compliance gaps are created during the migration.
By addressing these three challenges, cost, performance, and security, before they surface, you can turn a high-risk technical project into a predictable business initiative.
## What should a cloud migration Statement of Work include?
The SOW is the single most important document in a migration engagement. It turns high-level goals into specific commitments on what will be done, by when, and how success will be measured. Ambiguous SOWs are the leading cause of scope creep, budget overruns, and partnership friction.
After selecting a migration partner, the final critical step is structuring a contract that defines a clear plan of execution. The SOW moves beyond high-level goals to specific, detailed commitments, and it is the formal agreement between you and your partner on what will be done, by when, and how success will be measured.
### The anatomy of an effective SOW
A well-drafted SOW leaves no room for interpretation. It should serve as a detailed guide that any stakeholder, from a project manager to a finance executive, can understand. It is the single source of truth for the engagement.
A complete SOW must include:
* **Clear objectives.** Define the specific business outcomes the project is intended to achieve, linking technical tasks to business value.
* **Scope boundaries.** Explicitly list all items that are **in-scope** (for example, migrating the finance data mart to Snowflake) and, just as important, what is **out-of-scope** (for example, decommissioning legacy servers).
* **Specific deliverables.** Name the tangible outputs, such as a "Target State Architecture Document" or a "Completed Production Environment Cutover." Avoid vague descriptions.
* **Acceptance criteria.** Define the objective conditions under which a deliverable will be considered complete. For example, "The migration will be accepted only after 99% of data validation tests pass successfully."
* **Governance structure.** Outline the communication cadence, including weekly status meetings, key contacts for both teams, and a clear escalation path for resolving issues.
> Your contract is a strategic tool, not just a legal formality. The level of detail in a consultant's proposed SOW is a direct reflection of their experience. A seasoned partner provides a granular plan; an inexperienced one relies on ambiguous language.
### Choosing the right pricing model
The pricing structure directly influences the incentives and risk allocation for both parties. Selecting the right model is about aligning everyone's interests from the start.
In cloud migration consulting, three primary pricing models are common:
1. **Fixed-price.** Best suited for projects with a clearly defined and stable scope. It offers budget predictability but provides little flexibility for changes.
2. **Time and materials (T&M).** The standard for projects with an evolving or uncertain scope. It offers maximum flexibility but requires strong project management from the client to control costs.
3. **Outcome-based.** A more advanced model where a portion of the payment is tied to achieving specific business results, such as an agreed percentage reduction in infrastructure costs post-migration.
Each model is appropriate for different situations. For a detailed comparison, see our guide on [fixed-price vs. time and materials](https://dataengineeringcompanies.com/insights/fixed-price-vs-time-and-materials). Establishing the right contractual foundation is the first step toward a successful partnership.
## Common questions about cloud migration consulting services
Having questions at this stage is a sign of diligence. Here are the most common inquiries from leaders evaluating cloud migration consultants.
### What's the real ROI on a cloud migration project?
Focusing solely on immediate hardware and licensing savings is shortsighted. The strategic ROI comes from the new capabilities the cloud enables.
Consider the second-order effects: engineering teams can ship products faster, data analysts gain access to scalable compute for AI initiatives, and the entire operation becomes more resilient. A competent consultant will not offer a generic percentage but will work with you to build a detailed business case that maps the investment directly to your specific strategic goals.
### How long are consultants on the hook after we go live?
The goal is to build your team's independence, not create a long-term dependency. A well-structured engagement includes a clear transition plan.
> A typical handover involves 1-3 months of intensive, hands-on support immediately post-launch to resolve issues and optimize performance. This may be followed by 3-6 months of advisory support on retainer as your internal team assumes full operational control. Make knowledge transfer a mandatory, defined deliverable in your contract.
### Can a consultant help us pick the right cloud (AWS, Azure, or GCP)?
Yes. This should be a primary function during the strategy phase. A top-tier, platform-agnostic consultant provides an objective, data-driven recommendation.
They will analyze your specific workloads, security requirements, and budget to present a clear, quantitative comparison of the major providers. See our [AWS](https://dataengineeringcompanies.com/aws-data-engineering/), [Azure](https://dataengineeringcompanies.com/azure-data-engineering/), and [GCP](https://dataengineeringcompanies.com/gcp-data-engineering/) data engineering hubs for platform-specific context. Be wary of any firm that heavily favors one provider without a compelling, business-specific justification. Their allegiance should be to your objectives, not to a sales channel partner.
### What's the difference between a huge global firm and a niche consultancy?
Choosing the right type of firm depends on the project's nature.
* **Global System Integrators (GSIs)** are large-scale organizations offering a broad range of IT services. They are typically engaged for enterprise-wide digital transformations that impact multiple business units.
* **Boutique data consultancies** are specialists with deep, focused expertise in platforms like [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/). Their agility and specialized skill sets make them well suited for targeted data platform modernization projects requiring significant technical depth.
---
Choosing between a global systems integrator and a boutique data consultancy, or between rehosting and rearchitecting, comes down to the same question every time: what does your specific data estate actually need, not what a vendor wants to sell you. Cross-reference candidates against our [directory of data engineering consulting firms](https://dataengineeringcompanies.com/data-engineering-consulting-firms/), and use the [guide to choosing a data engineering company](https://dataengineeringcompanies.com/how-to-choose-data-engineering-company/) to structure your evaluation before you send an RFP.
---
## A Practical Data Analysis Strategy for 2026 and Beyond
Source: https://dataengineeringcompanies.com/insights/data-analysis-strategy/
Published: 2025-12-16T07:11:26.560845+00:00
Description: Build a data analysis strategy that drives real growth: align business goals with technology, establish governance guardrails, and integrate AI for actionable insights.
TL;DR: Key Takeaways
A business plan, not a tech document: A data analysis strategy connects data initiatives to measurable outcomes like revenue growth and churn reduction.
Six pillars, in order: Business Objectives, Architecture, Technology, People/Skills, Governance, and KPIs/ROI - sequenced so business questions drive data needs, not the other way around.
Question-first: Avoid the "tech-first" trap. Start with critical business questions (e.g., "Why are high-value customers churning?"), then select the tools needed to answer them.
Phased execution: Don't try to do everything at once. Start with a 60-90 day high-impact pilot project to prove value, then scale.
Governance decides adoption: Without trusted data, adoption fails. Establish clear ownership and a business glossary early to prevent "data swamps."
A data analysis strategy is a business plan for how your organization collects, manages, analyzes, and deploys data to hit specific commercial goals. It's the operational blueprint that connects technical data work to measurable business outcomes. Without it, data projects turn into costly experiments that never pay for themselves.
## Why Do You Need a Data Analysis Strategy?
Collecting data stopped being a competitive advantage on its own once every company started doing it. Without a documented strategy, organizations sit on data lakes and warehouses with no coherent process for converting that raw material into better decisions, lower costs, or more revenue - so the strategy is what turns storage into a business asset.
### Shifting from Reactive Reporting to Proactive Decision-Making
A functional strategy moves an organization from reactive analysis (reporting on past events) toward proactive, predictive work. The focus shifts from "What happened last quarter?" to forward-looking, high-value questions:
* Which customers are likely to churn in the next 90 days, and what intervention is most likely to retain them?
* What is the optimal price point for a new product to maximize market penetration and profitability?
* Where are the critical bottlenecks in our supply chain that are eroding margins?
Answering these questions creates a real competitive edge. The market for data analytics tools and services has grown for a decade straight, and the companies pulling ahead are the ones using real-time insight to tighten forecasting and cut waste - not the ones with the most data sitting in a warehouse.
> A data analysis strategy is not a technical document for the IT department. It is a business plan that aligns technology, people, and processes with critical commercial objectives.
This strategy matters for any organization focused on sustainable growth. It provides the framework needed to manage complexity, anticipate market shifts, and outperform competitors who still rely on intuition alone. The rest of this guide lays out a repeatable framework for building that capability.
## What Are the Six Pillars of a Data Analysis Strategy?
The six pillars are business objectives, data architecture, tools and technology, people and skills, governance, and KPIs/ROI - sequenced so business questions drive data needs, which in turn drive technology choices, and not the reverse.
This process works like an architectural blueprint drawn up before construction begins. Nobody builds a skyscraper by stacking expensive materials speculatively; a detailed plan comes first. The same logic applies to building a data capability, and getting the sequence backward - buying platforms before defining the problems they need to solve - is the single most common and costly mistake teams make.
This logical flow is what converts raw data into profit.
As illustrated, a sound strategy is the bridge between inert data and a real competitive advantage. Here's each of the six pillars that forms that bridge.
### The Six Pillar Data Strategy Framework at a Glance
This table gives a high-level view of the framework's core components, purpose, and key considerations for each pillar.
| Pillar | Core Focus | Critical Question to Answer |
| --- | --- | --- |
| **1. Business Objectives** | Aligning data initiatives with C-level goals and outcomes. | What specific business problems are we trying to solve? |
| **2. Data & Architecture** | Identifying and structuring the raw data needed for analysis. | Where does the data reside, and how will we unify it for analysis? |
| **3. Tools & Technology** | Selecting the right software and platforms for the job. | What stack will enable our team to answer our questions efficiently? |
| **4. People & Skills** | Building a team with the right talent to execute the strategy. | Do we have the required skills, and are the roles clearly defined? |
| **5. Governance & Integrity** | Ensuring data is accurate, secure, and trustworthy. | How do we guarantee our insights are built on reliable data? |
| **6. KPIs & ROI** | Measuring the tangible business impact of your data efforts. | Did our data initiatives measurably impact the target business goals? |
Addressing these six areas systematically creates a strategy where each element reinforces the others and materially improves your odds of success.
### Pillar 1: What Business Questions Should Drive Your Strategy?
All data work starts here. Before any data is collected or analyzed, you need to define what the business actually needs to achieve. This pillar translates broad corporate objectives into specific, answerable questions.
Vague goals like "increase revenue" aren't actionable. A useful strategy needs precise questions such as:
* Which customer segments exhibit the highest lifetime value, and what were the acquisition channels for these segments?
* What are the top three drivers of customer churn within the first 90 days of service?
* At which specific stage of our sales funnel do we lose the most high-value leads?
Answering these questions produces intelligence you can act on immediately. This step keeps the entire data strategy focused on solving real-world problems instead of building dashboards for their own sake.
### Pillar 2: Where Should Your Data Come From?
Once the questions are defined, you can identify the data required to answer them. This pillar means locating, acquiring, and structuring disparate data sources into a unified, reliable foundation for analysis.
To answer the customer churn question, for example, you'd need to integrate data from multiple systems:
1. **CRM Data:** Customer records, sign-up dates, and all sales and support interactions.
2. **Product Usage Data:** Application logs detailing user activity, feature adoption, and session frequency.
3. **Billing System Data:** Subscription levels, payment histories, and cancellation reasons.
Your data architecture - the system designed to collect, store, and integrate these sources within a data warehouse or lakehouse - forms the technical backbone of your strategy. A flawed architecture produces data silos and insights nobody trusts.
### Pillar 3: Which Tools and Technology Should You Choose?
With business questions and data requirements defined, you can pick the appropriate tools. This pillar has to come third. Buying technology first and then bending business problems to fit the tool's capabilities produces expensive, underused software - "shelfware."
Your technology stack needs to support the entire data lifecycle, from ingestion to visualization. Key components include data integration tools like [Fivetran](https://www.fivetran.com/), a cloud data platform such as [Snowflake](https://www.snowflake.com/) or [Databricks](https://www.databricks.com/), data transformation software like [dbt](https://www.getdbt.com/), and business intelligence platforms like [Tableau](https://www.tableau.com/) or [Power BI](https://powerbi.microsoft.com/en-us/).
> The objective is not to acquire the most advanced tools, but the *most appropriate* tools. A simple, well-integrated stack that solves core business problems is worth more than a complex, underused one.
### Pillar 4: Who Do You Need on Your Team?
Tools are enablers; people generate insight. This pillar addresses the human side of a data analysis strategy: an honest assessment of your team's current capabilities against the skills the strategy actually requires.
That means defining clear roles and responsibilities for data analysts, data engineers, and data scientists, plus a real commitment to training where skill gaps show up. The goal is a data-literate culture where employees across the organization can confidently use data to make decisions.
### Pillar 5: How Do You Govern Data Integrity?
If stakeholders don't trust the data, the strategy fails, full stop. This pillar establishes the rules and processes that keep data accurate, consistent, secure, and compliant.
Data governance defines data ownership, access controls, and usage policies. It covers data quality standards, metadata management, and security protocols for sensitive information. Our **[data governance framework template](/insights/data-governance-framework-template/)** is a starting point for building this system without starting from a blank page. Strong governance is the foundation everything else in this list depends on.
### Pillar 6: How Do You Measure Performance and ROI?
The final pillar closes the loop by measuring the impact of your data initiatives against the objectives defined in Pillar 1. This step is what demonstrates the value of the strategy and secures continued investment.
Key performance indicators need to tie directly to business outcomes. Focus on tangible results:
* **Operational Efficiency:** Did we reduce supply chain costs by 15%?
* **Revenue Growth:** Did we increase cross-sell revenue by $2 million?
* **Customer Experience:** Did we reduce the customer churn rate by 10%?
Tracking these metrics is how you demonstrate ROI and keep refining the strategy based on what actually happened, not what the plan assumed would happen.
## How Do You Build an Analytics Technology Stack?
### How Should Analytics Maturity Shape Your Roadmap?
An analytics roadmap should start from the organization's current operating capability, not from the most advanced tool on the shortlist.
| Maturity stage | Typical constraint | Next practical move |
|---|---|---|
| **Foundational** | Definitions conflict, ownership is unclear, and reporting depends on manual extracts. | Standardize critical metrics, assign owners, and automate one high-value reporting flow. |
| **Operational** | Core reporting works, but teams duplicate logic and struggle to trust or reuse data products. | Introduce governed models, quality checks, documentation, and a shared semantic layer. |
| **Advanced** | Trusted data products exist, but predictive or real-time use cases are hard to operate reliably. | Add workload-specific serving, monitoring, experimentation, and model governance only where the business case supports them. |
Use this maturity assessment to sequence work. Jumping straight from foundational reporting to real-time predictive analytics usually creates more systems to operate than the organization can support before it has reliable definitions, ownership, and feedback loops in place.
After defining business objectives and outlining the data architecture, the next step is choosing tools. This isn't about acquiring the latest technology; it's a calculated decision to equip your team with the specific software needed to execute the strategy.
Think of it as equipping a workshop. You don't buy every tool available; you select the specific instruments the projects in front of you require. Your analytics stack should follow the same purpose-driven logic - each component needs to serve a clear function in turning raw data into insight people act on.

The goal is an integrated system where data flows without manual handoffs, from raw sources to clean, analysis-ready datasets.
### What Are the Core Components of a Modern Analytics Stack?
A functional analytics stack is typically composed of several layers, each addressing a specific stage of the data lifecycle. Vendors vary, but the core functions are universal.
* **Data Storage and Warehousing:** The central repository for structured and semi-structured data. Cloud platforms like [**Snowflake**](https://www.snowflake.com/en/) or [**Google BigQuery**](https://cloud.google.com/bigquery) handle massive data volumes and execute complex queries efficiently.
* **Data Transformation:** Raw data is rarely ready for analysis. A tool like [**dbt (data build tool)**](https://www.getdbt.com/) cleans, models, and structures data directly within the warehouse, so analysis rests on consistent, documented business logic instead of one-off spreadsheet formulas.
* **Business Intelligence (BI) and Visualization:** The interface for end-users. BI platforms such as [**Tableau**](https://www.tableau.com/) or [**Microsoft Power BI**](https://powerbi.microsoft.com/en-us/) connect to the data warehouse so teams can explore data, build dashboards, and communicate findings.
These three layers form the core of the [**modern data stack**](/insights/modern-data-stack/), a modular approach that lets organizations pick the strongest tool for each function instead of locking into one vendor's full suite.
### What Should You Evaluate Before Choosing Analytics Technology?
Selecting technology vendors takes more than a feature comparison. The right choice has to fit your team's skills, budget, and long-term business objectives.
Weigh these practical factors before committing:
1. **Total Cost of Ownership (TCO):** Look past the license fee. Factor in implementation costs, subscription fees, training, and the engineering time required for ongoing maintenance. A "cheaper" tool that demands constant manual oversight isn't actually cheaper.
2. **Scalability and Performance:** Will this solution hold up in 12-24 months? A platform that performs well with 10 terabytes of data may degrade badly at 100 terabytes. Pick tools that scale with your data volume and user base without runaway costs.
3. **Integration and Interoperability:** Your tools must integrate without manual workarounds. Poor interoperability creates data silos and forces people to stitch things together by hand, defeating the point of a modern stack. Look for well-documented APIs and pre-built connectors.
4. **Team Skillset and Usability:** A tool only helps if your team can actually use it. Does it require specialized skills like SQL or Python, or does it offer a usable interface? Choose tools that fit your existing team's skills or your hiring plan, not tools that introduce a steep, frustrating learning curve.
> Your technology stack should be a business enabler, not an engineering bottleneck. Prioritize simplicity and reliability. A stack that delivers reliable insights today beats a complex system built for hypothetical future needs that never gets fully adopted.
Focus on these principles and you'll build an analytics capability that's purpose-built for your strategy - giving your team what they need to deliver results today while keeping room to adapt later.
## How Do You Turn a Data Strategy Into Action?
A data analysis strategy document has no value until it's executed. The return on investment only shows up once the plan gets translated into daily operations - which is exactly where many initiatives stall, caught between the strategic vision and the practical mess of implementation.
The key is to treat implementation as a phased rollout, not a single, large-scale event. Think of it like building a new highway system: you start with one high-impact route to prove value, then expand the network. This builds momentum, limits disruption, and validates the investment at each stage.

### Why Start With a Pilot Project?
The most effective way to begin implementation is with a pilot: not a technical test, but a focused initiative aimed at a specific, high-value business problem within a defined timeframe, typically **60 to 90 days**.
The objective is a quick, measurable win that secures executive buy-in and proves the strategy's potential. The project should tie to a key business objective and have a clearly defined success metric.
**Examples of effective pilot projects:**
* **Marketing:** Identify the top 5% of customers at risk of churning and launch a targeted retention campaign, measuring the change in churn rate for that cohort.
* **Sales:** Develop a lead-scoring model to prioritize sales efforts on high-probability opportunities and measure the impact on conversion rates.
* **Operations:** Pinpoint the primary cause of a recurring supply chain delay and implement a change to reduce it, measuring the impact on logistics costs.
A successful pilot generates the political capital and organizational momentum a broader rollout needs.
### How Do You Break Down Data Silos?
Data initiatives usually fail because of organizational friction, not technical limitations. Departmental silos are the main obstacle to a cohesive data strategy, and overcoming them requires building cross-functional collaboration and a real sense of shared ownership.
> A data strategy's success is ultimately measured by its adoption. If people don't use the insights to make different, better decisions, the entire investment is wasted.
One effective mechanism for building that collaboration is an **Analytics Council** or Center of Excellence: a cross-functional group with representatives from key business units (marketing, finance, operations) alongside IT and the data team.
This council acts as the steering committee for the data strategy. Its responsibilities include:
1. **Prioritizing Projects:** Evaluating and ranking analytics initiatives based on business value.
2. **Standardizing Metrics:** Making sure key business metrics are defined and calculated consistently across the organization.
3. **Championing Data Literacy:** Promoting training and best practices to build data skills throughout the company.
This structure breaks down silos by giving each department a voice in the process, turning potential resistors into active stakeholders. For a deeper look at the foundational role of governance, see our guide to [data governance consulting](/insights/data-governance-consulting/).
### How Do You Scale From Pilot to Full Rollout?
After a successful pilot and a working collaborative governance structure, you can move to a phased rollout. Avoid a "big bang" implementation. Instead, address business units or problem areas sequentially, applying lessons from the pilot to refine the approach each time.
This iterative process matters because the questions worth asking keep changing as the business changes. An effective data analysis strategy isn't static - it's a living system that gets revisited every time a new data source, product line, or market shift changes what "good" looks like.
The strategy needs continuous refinement through a feedback loop: measure results, learn from them, adapt the plan. Building this agile mindset into implementation is what keeps your data capabilities evolving in step with the business, instead of falling a year behind it.
## How Does a Data Strategy Support AI, Cloud, and Modernization?
A well-defined data analysis strategy is the foundation for major technology initiatives: cloud migration, analytics modernization, and adopting artificial intelligence. Without it, these projects tend to become disjointed, expensive efforts that never deliver their promised business value.
### How Does a Data Strategy De-Risk Cloud Migration?
Migrating data infrastructure to the cloud is complex, and a "lift and shift" approach is rarely optimal. A data analysis strategy gives you the framework to manage that complexity by forcing you to answer critical questions *before* the migration starts.
The strategy identifies your most critical data assets, so you can prioritize the migration and make sure high-value data gets moved, secured, and governed correctly from the outset. It also shapes your cloud architecture, helping you pick the most cost-effective and performant cloud services for your specific needs.
> A cloud migration without a data strategy is like moving to a new city without a map. You might get there eventually, but you'll likely get lost, take expensive detours, and leave your most valuable possessions behind.
### How Does a Data Strategy Guide Analytics Modernization?
Many organizations are stuck with legacy reporting systems that are slow, hard to use, and produce stale insights. Analytics modernization means replacing those systems with an agile, self-service environment where business users can answer their own questions.
Your data analysis strategy is the roadmap for that transition. It defines who needs access to what data and the specific business questions they need to answer. That clarity shapes the choice of modern BI tools like [Tableau](https://www.tableau.com/) or [Power BI](https://powerbi.microsoft.com/en-us/) and guides the development of clean, reliable data models - shifting the culture from reactive reporting to proactive, data-literate decision-making.
### How Does a Data Strategy Prepare You for AI?
AI and machine learning can create a real competitive advantage, but every successful AI model rests on one non-negotiable prerequisite: clean, well-governed, accessible data.
Your data analysis strategy is what creates that foundation. It establishes the governance and data quality standards needed to produce reliable training data - because an AI model trained on inconsistent or inaccurate data produces unreliable, sometimes harmful, results. The strategy ensures the data pipelines feeding your AI initiatives are documented, tested, and something engineers actually trust.
This foundation is also what makes predictive and prescriptive analytics possible later. Neither works on data nobody trusts - a churn model trained on inconsistent CRM records will make confidently wrong predictions, which is worse than making no prediction at all.
These initiatives aren't isolated projects. They're interconnected outcomes of one coherent data analysis strategy that turns data from a passive asset into an active driver of growth.
## What Are the Most Common Data Strategy Pitfalls?
Most data strategy documents fail when they run into real-world business pressure. These failures are rarely technical - they're predictable, process-oriented mistakes, and an effective data analysis strategy anticipates them before they happen.
### Pitfall 1: Buying Technology Before Defining the Problem
This is the most frequent and costly mistake. A vendor demo for a powerful, AI-driven analytics platform can be compelling. But buying a tool before clearly defining the business problems it needs to solve is like buying a Formula 1 car for a daily commute - expensive, overly complex, and ill-suited for the actual need.
This technology-first approach produces costly shelfware and frustrated teams trying to force their business requirements into the features of the wrong tool.
**How to sidestep it:**
* **Start with the business questions.** Interview department heads and ask, "What are the top three questions you cannot answer today that would fundamentally change how you manage your team?"
* **Define the "why" first.** Solidify the business case *before* evaluating vendors. Objectives like "reduce customer churn by 15%" or "identify our most profitable marketing channels" should dictate the technical requirements, not the other way around.
> The right question is never "What can this cool new tool do?" It should always be, "What business problem must we solve, and what's the simplest, most effective way to solve it?"
### Pitfall 2: Ignoring Data Governance Until It's a Crisis
Treating data governance as a bureaucratic task for later is a recipe for failure. If users don't trust the data, they won't use the analytics tools. Inconsistent metrics, conflicting reports, and unclear data ownership create a culture where every insight gets questioned, and the whole investment becomes worthless.
The problem compounds over time. One bad decision based on flawed data can erode trust for years, and it's hard to regain that momentum once it's gone.
**How to sidestep it:**
* **Assign ownership early.** Appoint clear data stewards for critical data domains (customer, product, sales). Accountability directly improves data quality.
* **Build a shared dictionary.** Create a business glossary with standard definitions for key metrics like "Active User" or "Gross Margin." A common data language ends the confusion and unproductive debates.
A successful data analysis strategy ultimately depends less on having the newest technology and more on avoiding these fundamental, non-technical errors. Focus on business problems first, build a foundation of trusted data, and you create an environment where insight can actually drive performance.
## Your Data Analysis Strategy Questions, Answered
This section covers common questions that come up when implementing a data analysis strategy.
### How Do You Actually Measure the ROI of a Data Strategy?
Measuring ROI means tracking both quantitative financial gains and qualitative operational improvements against a pre-defined baseline.
* **Hard Metrics:** Direct, bottom-line impacts - cost savings from automating manual reporting, incremental revenue from an optimized pricing model, or a measurable increase in customer lifetime value from effective retention campaigns.
* **Soft Metrics:** Operational improvements that matter just as much - a shorter time-to-decision, business teams self-serving analytics without IT intervention, and more confidence in financial forecasts.
### What's the Difference Between a Data Strategy and a Data Analysis Strategy?
These terms are related but distinct.
A **data strategy** is the comprehensive, enterprise-wide plan for managing all of an organization's data assets: acquisition, storage, security, governance, and infrastructure. It's the foundational blueprint for the entire information ecosystem.
A **data analysis strategy** is a more focused subset of the overall data strategy. It's specifically concerned with turning raw data into actionable business insight - the activation layer that sits on top of the broader data infrastructure, built to answer specific business questions and drive decisions. If you'd rather bring in outside help drafting either document, see our guide to [data strategy consultation](/insights/data-strategy-consultation/).
> A data analysis strategy is where raw data gets purposefully transformed into a competitive advantage. It's the bridge between having data and actually using it to win.
### How Often Should We Update Our Data Analysis Strategy?
A data analysis strategy is not a static document. It has to evolve with the business.
Run a comprehensive review **annually** to keep the strategy aligned with the company's long-term goals, market conditions, and available technology.
On top of that, run **quarterly check-ins** to track progress against KPIs and make tactical adjustments. If a major business event happens - a merger, a new product launch, a significant competitive move - re-evaluate the strategy immediately so it stays relevant.
---
Finding the right partner matters as much as the framework itself. Analytics or BI capability is now common among data consultancies - 68 of the 86 firms profiled in the Data Engineering Companies Index name analytics or BI among their capabilities - so the harder task is matching a firm's strengths to your pillars, not finding one that offers analytics at all. Compare vendors in our [analytics consulting](/analytics-consulting/) directory, or [explore the full directory](/) to find a data engineering partner suited to your stack.
---
## The Actionable Guide to Data Analytics in the Insurance Industry (2026)
Source: https://dataengineeringcompanies.com/insights/data-analytics-in-insurance-industry/
Published: 2025-12-05T06:43:47.997502+00:00
Description: How data analytics transforms the insurance industry: AI-driven risk scoring, IoT-based underwriting, fraud detection, and claims automation with real-world ROI benchmarks.
TL;DR: Key Takeaways
Real-Time Personalization: The industry is moving from static demographic models to real-time behavioral scoring via IoT and telematics, allowing for hyper-personalized policies.
Automated Operations: Insurers are using data pipelines to automate claims processing (handling simple cases in under 24h) and deploying AI to detect fraud before payouts occur.
Modern Infrastructure: Success requires a modern data stack - specifically data lakehouses and data mesh architectures - to govern AI/ML pipelines and ensure compliance.
Proactive Protection: Analytics is enabling a shift from reactive claim payments to proactive risk mitigation, using climate modeling and sentiment analysis to prevent losses and churn.
Data analytics in the insurance industry means using real-time data - telematics, IoT sensors, claims history, and behavioral signals - to price risk, automate claims, and catch fraud before payouts go out. It replaces static actuarial tables and demographic risk pools with continuous, individual-level scoring across underwriting, claims, and retention.
For decades this was a back-office function that ran quarterly reports. It's now the operating system for how insurers price, sell, and pay out - and the carriers that treat it that way are pulling ahead on loss ratios and retention.
## How Is Data Analytics Changing the Insurance Industry?
**Data analytics is shifting the industry from reactive, demographic-based risk pooling to proactive, individual-level risk management.** Instead of relying on dusty actuarial tables and broad zip-code buckets, insurers now stream data from IoT devices, telematics sensors, and digital interactions to price, sell, and pay claims in near real time.
This isn't a side project. Insurance leaders are increasing technology spending going into 2026, with AI and big data analytics named as top priorities, and early movers are already reporting gains in both sales conversion and claims accuracy.
### How Does Analytics Shift Insurers from Reactive to Predictive?
Wait for a claim, then pay it - that's the old model. Data analytics flips it: insurers use behavioral and environmental signals to anticipate and reduce risk before it turns into a claim.
* **For insurers:** sharper pricing, fewer fraudulent payouts, and better management of capital reserves.
* **For customers:** premiums that reflect actual behavior, claims that settle faster, and services that help prevent the loss in the first place.
## How Do Insurers Use Real-Time Data to Personalize Policies?
**Insurers combine telematics, wearable, and smart-home data with machine learning to price policies on individual behavior instead of broad demographic categories.** A driver's actual braking patterns, a policyholder's activity data, or a home's real-time leak sensors all feed models that adjust premiums and coverage continuously rather than once a year.
The volume of connected devices - cars, wearables, home sensors - keeps growing, and insurers are using that stream to move from static risk models to real-time behavioral scoring. Vehicle telematics, wearable health metrics, and smart home signals give a continuous view of actual risk, which insurers report improves premium accuracy and reduces churn compared with demographic-only pricing.
### Fuse IoT and Telematics for Hyper-Personalized Underwriting
A car insurance policy that rewards safe driving habits instantly, not just at renewal, starts with data from OBD-II trackers: driving speed, braking patterns, and mileage feed a behavioral score for each driver.
This goes beyond basic usage-based insurance. Insurers build automated data pipelines to ingest this telemetry, apply machine learning models like XGBoost to score risk, and adjust policies on a set cadence - quarterly, for example - without a person reviewing every file.
> **Actionable Insight:** Integrate APIs from OBD-II trackers directly into [Snowflake](https://www.snowflake.com/) pipelines. Layer ML models (XGBoost) on top to auto-adjust policies quarterly. This creates a scalable system that adapts to new vehicle technologies without manual intervention.
This model extends beyond auto insurance. Health insurers can use wearable data to incentivize healthy habits, while property insurers can use smart home sensors to detect water leaks or fire risks, offering discounts for proactive prevention.
### Embed Generative AI for Dynamic Pricing Engines
While IoT data refines individual risk, generative AI changes how insurers price that risk in a volatile market. Static, annual pricing can't keep pace with economic shifts or climate events, so real-time pricing engines are becoming standard rather than optional.
These engines blend market trends, behavioral data, and simulation to adjust premiums far more often than once a year. Some insurers run scenario simulations across hundreds of variables to catch profitable risk segments that static models miss.
> **Actionable Insight:** Use [LangChain](https://www.langchain.com/) with Snowflake Cortex to simulate pricing scenarios across hundreds of variables. A/B test the resulting strategies via [Optimizely](https://www.optimizely.com/) and tie every pricing decision to a measurable ROI dashboard.
### The New Underwriting Paradigm
This evolution from generalized risk pools to individualized scoring is a fundamental change in the relationship between insurer and customer. It's no longer just a transaction; it's becoming a partnership focused on actively managing risk.
The table below breaks down the difference.
### Modern vs Traditional Underwriting Models
| Attribute | Traditional Model | Modern Analytics-Driven Model |
| :--- | :--- | :--- |
| **Data Sources** | Demographic data, credit scores, claim history | Real-time telematics, IoT sensors, behavioral data |
| **Risk Assessment** | Static, based on historical group averages | Dynamic, based on individual real-time behavior |
| **Pricing** | Fixed, annual adjustments | Dynamic, sub-hourly adjustments |
| **Customer Interaction** | Reactive, primarily during claims or renewal | Proactive, with continuous feedback and incentives |
| **Business Outcome** | Broad risk pooling, potential for premium leakage | Hyper-personalized policies, improved accuracy and retention |
This shift benefits both sides of the transaction: insurers improve loss ratios, and customers get pricing that reflects their own behavior instead of a zip-code average.
## How Does Data Analytics Automate Claims and Catch Fraud?
**Data analytics automates claims by routing straightforward cases through predictive models for instant approval, and catches fraud by mapping relationships between claimants, adjusters, and vendors to flag suspicious patterns before payout.** Both save money: fewer manual claims reviews, and fewer fraudulent payouts that never should have gone out.
Claims processing and fraud are the two costliest operational headaches for most insurers, and both cost more than dollars - slow claims and missed fraud strain customer trust. The goal is a "touchless" claims process where straightforward claims get filed, processed, and paid automatically, often within a day, while analytical models are aimed at an insurance fraud problem that industry estimates put in the hundreds of billions of dollars annually.
### Orchestrate Predictive Claims with Micro-Batch Streaming
Manual claims handling is slow by design - each file waits in a queue for a human to review it. Data pipelines change that by triggering the moment a claim is filed, so straightforward cases can resolve in hours instead of weeks.
The process streams change data capture (CDC) from policy databases into platforms that trigger predictive models. These models check for completeness, compliance, and fraud red flags, approving straightforward claims automatically and routing complex cases to a human adjuster. The result isn't just faster resolution - it's a complete, audit-ready record of every decision. Firms offering [Databricks consulting](/databricks-consulting/) can help set this pipeline up.
> **Actionable Insight:** Stream CDC from policy databases to Databricks Delta tables, triggering dbt models for auto-approval thresholds. This approach reduces manual handling costs, backfills historical data for compliance, and keeps the pipeline ready for new model types as they're added.
### Deploy AI-Driven Fraud Networks to Catch Claims Before Payout
Manual reviews catch only a fraction of fraud. Modern fraud detection instead uses AI-powered link analysis and graph models to map relationships between claimants, adjusters, and vendors, surfacing coordinated fraud rings that a single-claim review would miss.
Anomaly detection on these claims graphs lets insurers flag likely fraud before a payout goes out rather than clawing it back afterward. That's a meaningful part of why the market for AI in insurance is projected to reach [$79.86 billion by 2032, with 44% of insurers already using AI for fraud detection](https://datagrid.com/blog/ai-agent-for-insurance-statistics).
> **Actionable Insight:** Build graph models (Neo4j is a common choice) from claims data and external feeds like social media and weather data, then feed them into a scoring engine such as H2O.ai for real-time fraud scoring on every new claim.
Combining automated claims processing with graph-based fraud detection is where data analytics delivers the clearest ROI in insurance today.
## What Data Stack Do Insurers Need for Analytics at Scale?
**Insurers need three infrastructure layers to run analytics at scale: a data lakehouse for unified storage, a data mesh (or similar ownership model) so domain teams can move fast without breaking governance, and MLOps to keep models accurate as risk patterns shift.** Good models without this infrastructure stall at the pilot stage.
The core of a modern stack is the data lakehouse - a hybrid architecture that combines a data lake's low-cost storage with a data warehouse's query performance, giving you one source of truth for everything from raw telematics to structured policy data. [Snowflake](https://www.snowflake.com/en/) and [Databricks](https://www.databricks.com/) are the two platforms most insurers evaluate first for this layer.
### Govern AI/ML Pipelines with Lineage-First Data Meshes
As insurers scale, a centralized data team becomes a bottleneck. A data mesh architecture solves this by treating data as a product: individual business domains - claims, underwriting - take ownership of their own [data pipelines](/insights/how-to-build-data-pipelines/) and analytics. That decentralized model only works with strong governance underneath it; see our [data governance best practices](/insights/data-governance-best-practices/) guide for the underlying framework.
Key components of a governed data mesh include:
* **Centralized metadata catalog:** Tools like [Collibra](https://www.collibra.com/) give every domain team a shared, searchable record of what data exists, who owns it, and how it's been transformed - which matters for both model explainability and audit readiness in multi-cloud environments.
* **Automated data quality:** Integrating tools like Great Expectations into pipelines ensures data is trustworthy from the start.
* **Automated compliance checks:** Running prescriptive analytics on policy histories lets ML models flag likely HIPAA or GDPR gaps before renewal instead of during an audit.
> **Actionable Insight:** Catalog assets in Collibra and wire Soda tests to GitHub Actions for drift alerts. Use Great Expectations in ELT flows to enforce data quality SLAs, and feed anomalies into Monte Carlo for incident playbooks. This gives domain teams self-serve access without losing centralized oversight.
### Automating the Model Lifecycle with MLOps
Machine learning models aren't "set it and forget it." A fraud model trained on last year's data quickly goes stale. MLOps - automating training, testing, deployment, and monitoring as one pipeline - is what keeps models accurate as patterns shift.
That means models predicting catastrophic climate losses get retrained on fresh data on a schedule, not only when someone notices they're wrong. A common workflow uses CI/CD pipelines to automatically retrain a Random Forest model on the latest NOAA datasets in a platform like [SageMaker](https://aws.amazon.com/sagemaker/), keeping risk models current.

The lakehouse, the mesh, and MLOps aren't separate projects - they're the infrastructure stack that lets claims automation, fraud detection, and dynamic pricing actually run in production instead of staying stuck in a proof of concept.
## How Does Analytics Shift Insurers from Reactive to Proactive?

**Proactive protection means insurers use predictive models to flag and mitigate risk before a loss happens, instead of only paying out after it does.** The two clearest applications are climate risk modeling and customer retention - both areas where historical averages alone miss what's coming next.
This works because insurers now have access to real-time datasets - satellite imagery, weather feeds, behavioral signals - that historical loss tables never captured. That shifts the business model from a financial safety net to something closer to active risk management.
### Build Climate-Resilient Risk Models with Ensemble Forecasts
Extreme weather events keep making old loss data less reliable as a guide to future risk. Insurers are responding by building climate-resilient risk models that combine satellite imagery, weather APIs, and geospatial data instead of relying on historical averages alone.
These models lean on ensemble forecasts - blending multiple data sources and algorithms - to produce a more reliable picture than any single model alone. Insurers use them to size reserves more accurately and to design new parametric products around specific weather triggers.
> **Actionable Insight:** Train a Random Forest model on NOAA datasets in [AWS SageMaker](https://aws.amazon.com/sagemaker/). Partition the data by geo-hash for federated queries with [Trino](https://trino.io/), and retrain quarterly via CI/CD to keep the model current as new weather data comes in.
### How Can Sentiment Analytics Reduce Policyholder Churn?
**Sentiment analysis flags unhappy policyholders before they start shopping for a new policy, using behavioral signals from CRM data and social platforms as an early warning system for churn.** That gives retention teams a window to intervene before a customer has already decided to leave.
By using NLP to mine unstructured text and voice data from support calls and platforms like X and Reddit, insurers can identify at-risk customers and deploy targeted retention offers instead of generic renewal reminders. For more on applying predictive analytics to retention, see this [Oliver Wyman analysis](https://www.oliverwyman.com/our-expertise/insights/2025/nov/predictive-analytics-new-frontier.html).
> **Actionable Insight:** Pipe X/Reddit feeds via Kafka to BigQuery ML for NLP scoring, then segment customers using dbt. Deploy the system via Airflow to trigger personalized Slack alerts for account managers, creating a voice-of-customer loop that runs continuously.
## How Can Insurers Turn Analytics from a Cost Center into Revenue?
**Insurers turn analytics from a cost center into revenue in two stages: first by putting predictive insights directly into frontline workflows, then by monetizing anonymized data through external partnerships.** Both stages depend on the governance and infrastructure work covered above - you can't monetize data you can't trust or explain.
Internally, that means agents and adjusters see risk scores in the tools they already use. Externally, it means packaging anonymized, aggregated insights as a product other companies will pay for.
### Democratize Insights via Low-Code BI for Frontline Teams
Insights that stay locked in a data team's dashboard don't change anything. The goal is embedding predictive intelligence directly into the daily workflows of agents, underwriters, and claims adjusters, using low-code BI tools that turn complex data into visualizations a non-analyst can act on.
Tools like [Domo](https://www.domo.com/) get embedded directly into agent dashboards so decisions don't wait on a request to the data team. When an agent sees a client's real-time churn risk score during a call, they can act on it immediately instead of finding out after the customer has already left.
> **Actionable Insight:** Expose dbt models as certified assets in [Tableau](https://www.tableau.com/) or [Domo](https://www.domo.com/). Use row-level security for role-based views to create a secure, self-service environment for "citizen data scientists" while tracking adoption KPIs.
### Monetize Ecosystems Through API-Driven Data Sharing
Turning anonymized data assets into a revenue stream is the next frontier, and embedded insurance runs on exactly this kind of secure, API-driven data sharing. As more premium volume flows through partner ecosystems - retailers, automakers, and fintechs bundling coverage into their own products - the analytics layer behind that sharing becomes a real business opportunity, not just a compliance requirement.
This isn't about selling raw customer data. It's about creating privacy-compliant analytical products: exposing anonymized, aggregated insights through a secure API to support new partnerships and business lines. For more on connecting these systems, see our guide on [data integration best practices](/insights/data-integration-best-practices/).
* **For automotive partners:** Share aggregated driving-behavior data to help improve vehicle safety.
* **For InsurTech startups:** Offer sandboxed data environments to test new products without exposing production systems.
> **Actionable Insight:** Expose anonymized aggregates via a GraphQL API on AWS API Gateway, with usage metering managed through Stripe. Start with a small pilot partnership to validate demand and pricing before opening the API more broadly.
Together, internal embedding and external monetization are what separate an analytics function that reports on the business from one that actively changes its trajectory.
## Frequently Asked Questions
As you map out an analytics strategy for your insurance business, a few questions come up consistently. Here are straightforward answers.
### What's the Toughest Nut to Crack When Getting Started?
Hands down, the biggest challenge is **data quality and integration**. Most insurers are wrestling with a tangled web of legacy systems and siloed data. Policy data lives in one place, claims in another, and customer interactions somewhere else entirely.
This fragmentation makes it nearly impossible to get a single, trustworthy view of a customer or a policy. So before you can build machine learning models, you have to do the foundational work: cleaning up the data, standardizing it, and pulling it together. This isn't glamorous, but a unified data platform with strong governance is the essential first step.
### How Can Smaller Insurers Possibly Keep Up with the Industry Giants?
It's tempting to think the big carriers have an insurmountable advantage, but smaller insurers can use their size to their benefit. The key is to be **agile and hyper-focused**.
Instead of trying to build a massive in-house data science team, they can use cloud platforms that let them pay for only what they use, keeping costs manageable.
Here's how they can punch above their weight:
* **Team up with InsurTechs:** Why build a complex fraud detection or telematics system from scratch? Partnering with a specialist gives instant access to top-tier capabilities.
* **Own a niche:** Find a specific customer segment and serve them better than anyone else. Using unique data to build highly personalized products can create a loyal customer base the big guys can't touch.
* **Move faster:** With less bureaucracy, smaller companies can adopt and implement new technology more quickly than their larger competitors.
### How Do You Stop AI Models from Being Unfair or Discriminatory?
This matters both ethically and legally. You can't bolt on "fairness" at the end; it has to be built into the process from the start, as part of a responsible AI framework.
> The core idea is to constantly check for and correct bias. This means auditing your training data for historical prejudices, using explainable AI (XAI) tools to understand *why* a model made a certain decision, and keeping detailed records of your data and model versions for full transparency.
You also need to regularly test models to confirm they aren't negatively affecting certain groups of people. For sensitive decisions - like denying a claim or applying a large premium increase - a human should always have the final say. That mix of automation and human judgment is what builds trust and keeps you on the right side of regulations.
---
Most insurance IT teams don't have this stack built in-house, and assembling it from scratch is slower than partnering with specialists who've done it before. If you're evaluating outside help, our directory includes firms with [fintech-specific data engineering experience](/fintech-data-engineering/) as well as dedicated [analytics consulting](/analytics-consulting/) providers who work directly with underwriting and claims data. Notably, 57 of the 86 firms profiled in the Data Engineering Companies Index name financial services among their industries.
---
## Data Catalog Tools Comparison for Engineering Leaders
Source: https://dataengineeringcompanies.com/insights/data-catalog-tools-comparison/
Published: 2026-03-25T10:31:26.898054+00:00
Description: Data catalog tools comparison - For engineering leaders: This data catalog tools comparison provides a deep dive into Alation, Collibra, Atlan, & Informatica. S
Choosing a data catalog isn't about finding the "best" tool - it's about picking the one that fits your data platform, governance model, and team. The decision affects developer productivity, compliance, and how fast your organization can actually use its data, so the real question is which business driver matters most: engineering velocity, strict compliance, or broad self-service analytics. Governance shows up as a named capability for 11 of the 86 firms in the [Data Engineering Companies Index](/data-governance/) - a smaller slice than migration or analytics work, which tells you catalog and governance expertise is a more specialized skill to screen for than a default one.
## A decision framework for data catalog selection
The data catalog market splits into three distinct philosophies, each built around a different business objective. Knowing which one you need is the first step toward a useful vendor evaluation, before you look at a single feature matrix.
* **Modern self-service catalogs:** Tools like [Atlan](https://atlan.com/) are built for the modern data stack: [Snowflake](https://www.snowflake.com/en/), [Databricks](https://www.databricks.com/), and [dbt](https://www.getdbt.com/). They prioritize developer experience, API-first integration, and agile collaboration.
* **Traditional governance platforms:** Solutions such as [Collibra](https://www.collibra.com/) are designed for highly regulated environments. Their architecture is built for top-down control, with formal stewardship workflows and strict policy enforcement for auditability.
* **Active metadata platforms:** Platforms like [Alation](https://www.alation.com/) use AI to analyze data usage patterns and automate curation. Their objective is to close the gap between technical data producers and business data consumers.
> The most common failure pattern is picking a tool off a feature matrix. That's how teams end up with a governance-first platform that slows down an agile data team, or a developer-centric tool that fails a basic compliance audit.
### Core decision drivers: an evaluation checklist
Frame your evaluation around a primary objective. Are you optimizing for engineering velocity, securing sensitive data, or giving business analysts self-service access? Each goal points to a different type of catalog.
| **Primary Driver** | **Description** | **Best-Fit Catalog Type** | **Key Functionality** |
| :--- | :--- | :--- | :--- |
| **Developer Productivity** | Accelerate data discovery and reduce time-to-insight for engineers and analysts on a modern data stack. | Modern Self-Service | Deep dbt/Airflow integration, column-level lineage, API-first architecture. |
| **Strict Compliance** | Enforce auditable data policies and manage risk in regulated industries like finance or healthcare. | Traditional Governance | Formal stewardship workflows, role-based access controls (RBAC), automated policy enforcement. |
| **Broad User Adoption** | Provide non-technical users with trusted, self-service access to data for analytics and reporting. | Active Metadata | AI-driven search, automated documentation, embedded collaboration tools. |
This framework sets the criteria for a direct, head-to-head comparison of leading vendors based on the specific business problems each one actually solves.
## Why are cloud-native, active metadata catalogs replacing legacy tools?
Cloud-native, AI-driven catalogs are displacing legacy, on-premise tools because they integrate directly with the modern data stack instead of requiring custom-built connectors bolted onto an older architecture. Picking the wrong catalog today ties your data strategy to a depreciating asset, wasting budget as the rest of the market moves on.
One driver behind this shift is the sheer growth of enterprise data volume. As the number of tables, pipelines, and sources multiplies, manual, spreadsheet-driven inventories stop scaling, and teams turn to a dedicated catalog to keep track of what data exists, where it lives, and whether it can be trusted.
### The cloud-native imperative
Legacy, on-premise catalog solutions are falling behind. The market has shifted decisively to the cloud, and any vendor whose roadmap isn't deeply integrated with [Snowflake](https://www.snowflake.com/en/), [Databricks](https://www.databricks.com/), [dbt](https://www.getdbt.com/), and the major cloud providers is a risky long-term bet.
Cloud-native platforms are built to integrate directly with the modern data stack, which is why rollouts on them tend to move faster than on tools that need custom integration work bolted onto an on-premise architecture.
> The biggest risk in vendor selection is picking a "cloud-agnostic" tool that's actually a monolithic on-premise application ported to a cloud server. A genuinely cloud-native catalog uses the elasticity and native services of its host platform to deliver scale that legacy architectures can't match.
### The rise of active metadata and AI
The market has split into passive, static catalogs and active, intelligent platforms. Passive catalogs function as a simple inventory system for data assets: they document what exists and where, and nothing more.
Active catalogs work differently. They use AI and machine learning to automate metadata discovery, recommend data quality improvements, and orchestrate governance workflows. The competitive edge now comes from AI-driven features like automated column-level lineage, PII detection, and semantic search, which directly address the real barrier to catalog adoption: the cost and manual effort of curation. A catalog without that intelligence is a bet against where the category is headed.
## What criteria actually matter when evaluating a data catalog?
A useful evaluation goes past feature lists and tests each tool against the operational challenges your data engineering team actually faces day to day. Five technical pillars cover most of what separates a catalog that gets adopted from one that doesn't.
### Metadata management and automation
A catalog's core function is metadata management, but the real differentiator is automation. The platform needs bi-directional metadata sync: it should ingest metadata from your data stack, but also push curated context, like business definitions and quality scores, back into the tools your team already uses.
### Data lineage and impact analysis
Visual lineage graphs are table stakes now. The capability that matters is column-level lineage tracking across complex transformations and disparate systems, from a source database, through dbt models, to a BI dashboard. For a closer look at how vendors handle this specifically, see our [data lineage tools comparison](/insights/data-lineage-tools-comparison/).
> A useful test for any data catalog is its impact analysis. If a pipeline fails or a column is deprecated, the tool should immediately surface every downstream dashboard, report, and data product affected. If it can't, that's a fundamental gap for enterprise use.
### Collaboration and stewardship
A data catalog that functions as a read-only library is a wasted investment. It needs to be an active part of your data culture, letting stewards curate assets, certify datasets, and resolve issues directly inside the tool. Look for persona-based workflows, integrated ticketing, and discussion threads tied to specific data assets.
### Integration and extensibility
Deep, native connectors matter more than a long integrations list. Your catalog needs to work with your core data stack, including [Snowflake](https://www.snowflake.com/en/), [Databricks](https://www.databricks.com/), [dbt](https://www.getdbt.com/), and [Airflow](https://airflow.apache.org/), without custom glue code for each one. A well-documented, open API is what makes custom integrations and governance automation possible once the standard connectors run out.
### Security and governance enforcement
A modern data catalog needs to actively enforce governance policies, not just document them. It has to function as part of your security posture, not sit next to it.
Key capabilities include:
* **Automated PII/sensitive data classification** that can trigger specific access policies.
* **Role-based access controls (RBAC)** that propagate permissions from the catalog to the underlying data sources.
* **Detailed audit logs** that provide a reliable record of data access.
## How do Alation, Collibra, Atlan, and Informatica actually compare?
[Alation](https://www.alation.com/), [Collibra](https://www.collibra.com/), [Atlan](https://atlan.com/), and [Informatica](https://www.informatica.com/) split along architectural philosophy more than feature count: Collibra and Informatica are built for top-down governance, Alation for AI-assisted self-service, and Atlan for developer-first, API-driven workflows. An effective catalog still needs to deliver on all three fronts: automated metadata management, clear lineage, and collaboration features that don't get in the way.
The right tool balances the technical side (metadata sync, lineage tracking) with the human side (getting analysts and stewards to actually use it).
### Architectural philosophies and core strengths
The fundamental difference between these platforms is their architectural DNA, which shapes their ideal use case and target user.
* **Collibra & Informatica:** Governance platforms built for regulated industries like finance and healthcare, where top-down control and auditability matter most. Their strength is managing complex stewardship workflows and enforcing data policies.
* **Alation:** This tool pioneered "active" metadata, using AI to understand data usage patterns and automate curation. It's built to bridge technical and business users, making it a strong pick for organizations focused on self-service analytics.
* **Atlan:** Built for the modern data stack, Atlan is a developer-first, API-driven platform with a bottom-up, collaborative model that fits how modern data teams actually work. Deep integrations with tools like dbt, Snowflake, and Slack make it a strong fit for agile organizations prioritizing engineering velocity.
Informatica and Collibra remain the larger, more established players in this market, particularly in regulated industries, while Alation has a strong footprint in the self-service intelligence segment. Newer platforms like Atlan are gaining ground with deployments measured in weeks rather than quarters, and increasingly show up in analyst evaluations like Gartner's Magic Quadrant and the Forrester Wave for data catalogs.
### Data catalog tool comparison matrix
This matrix compares Alation, Collibra, Atlan, and Informatica across the criteria that matter most for enterprise adoption.
| Evaluation Criterion | Alation | Collibra | Atlan | Informatica |
| :--- | :--- | :--- | :--- | :--- |
| **Metadata Management** | AI-driven automation, strong behavioral intelligence | Governance-centric, manual curation focus | Active metadata, API-first, automated bots | Strong but part of a larger, monolithic platform |
| **Data Lineage** | Good cross-system lineage | Strong on governance lineage, less on BI tools | Excellent column-level lineage, deep BI/ETL integration | Excellent end-to-end, part of broader MDM suite |
| **Collaboration & Search** | Strong natural language search and wiki-like articles | Formalized stewardship workflows | Embedded in Slack/Jira, contextual discussions | Search is functional but less intuitive |
| **Modern Stack Integration** | Good, improving connectors | Fair, often requires custom development for new tools | Excellent, deep integrations with dbt, Fivetran, etc. | Lagging on modern tools, strong on traditional ETL |
| **Deployment & Scalability** | SaaS or self-hosted, scales well with usage | Primarily self-hosted/VPC, complex to deploy | SaaS-native, fast deployment, scales horizontally | Can be complex, often requires professional services |
| **User Experience (UX)** | Business-user friendly, intuitive | Governance-focused, can be complex for analysts | Developer-centric, designed for modern workflows | Traditional enterprise UI, functional but dated |
| **Primary Use Case** | Self-Service Analytics & Data Democratization | Enterprise Data Governance & Compliance | Agile Data Teams & Modern Data Stack | Master Data Management & Large-Scale Governance |
This matrix shows the "best" tool is contingent on your organization's primary objective: strict governance, agile development, or broad business adoption. No single tool wins every category.
> Atlan's deep integration with tools like Slack, Jira, and dbt is a deliberate strategy to embed the catalog into the daily workflow of a modern data team, in contrast to the more siloed, governance-centric interfaces of traditional platforms.
## Which catalog tool fits which use case?
A feature-by-feature comparison only gets you so far. The tool that wins on paper isn't necessarily the one that fits your actual operational reality, so match the tool's core architecture to your primary use case first.
The three scenarios below cover common situations for engineering leaders. For each, here's the tool we'd recommend based on architecture, integrations, and governance model.
### The modern data stack scale-up
This scenario is an agile team on the modern data stack: [Snowflake](https://www.snowflake.com/en/), [dbt](https://www.getdbt.com/), and modern BI tools. The objective is developer velocity, and anything requiring heavy manual curation or rigid, top-down workflows is a non-starter.
* **Top recommendation:** [Atlan](https://atlan.com/)
* **Rationale:** Atlan is built for this environment. Its API-first design and deep dbt integration (capturing both metadata and lineage) fit the modern stack natively, and it embeds collaboration inside Slack and Jira instead of adding another tool to check. Its active metadata capabilities automate discovery and documentation, cutting the manual effort that slows fast-moving teams down.
### The enterprise governance overhaul
This scenario is a large enterprise in a regulated industry like finance or healthcare. The mission is auditable, top-down governance, with the focus on compliance, data quality assurance, and strict access controls.
* **Top recommendation:** [Collibra](https://www.collibra.com/)
* **Rationale:** Enterprise governance is Collibra's core competency. The platform is built around formal stewardship workflows, complex policy enforcement, and an authoritative business glossary. It's less agile, but it delivers the centralized control and audit trails regulators expect, and it's strongest at modeling the complex governance structures of a large, mature organization.
For teams on Databricks specifically, the evaluation is more nuanced: Unity Catalog's native governance and lineage capabilities can change the business case for a third-party tool entirely, so weigh what you'd actually gain from a Collibra or Alation deployment beyond what's already built into the platform.
### The federated data mesh implementation
In this scenario, a large enterprise is decentralizing data ownership to individual business domains. The challenges are enabling discovery across domains, ensuring interoperability, and keeping quality standards consistent for "data products" without a central bottleneck.
* **Top recommendation:** [Alation](https://www.alation.com/)
* **Rationale:** Alation is well suited to federated environments. It uses AI to analyze data usage, connect disparate data sources, and close knowledge gaps between domains. Its search and discovery capabilities, paired with an accessible interface, create something close to a central marketplace for data products, letting domain teams own their data while giving the whole organization one place to find it.
## What red flags should disqualify a vendor during evaluation?
Vague answers on data lineage for your specific stack, deliberately confusing pricing, or a closed ecosystem with thin API documentation are all serious warning signs during a vendor evaluation. Selecting a data catalog is a long-term commitment, and a wrong choice costs months or years of wasted effort to unwind.
If a vendor can't demonstrate a live connection to your primary data sources, that's a deal-breaker. The same goes for pricing: if calculating total cost of ownership takes multiple sales calls and a spreadsheet, the vendor is probably obscuring costs. Be wary of any vendor that resists giving your team a sandbox environment for hands-on evaluation.
### Your procurement checklist
Give your procurement team direct questions that move past the sales pitch and assess the vendor as a potential long-term partner.
**Key questions for vendors:**
1. **Lineage specificity:** "Demonstrate column-level lineage from our source system X, through our transformation tool Y, and into our BI tool Z. We need to see this working with our actual stack."
2. **Pricing transparency:** "Provide the three-year total cost of ownership for our projected usage, including all connector fees, support tiers, and user licenses. What's excluded from this quote?"
3. **Implementation reality:** "We need a reference call with a customer of similar size and tech stack. How long was their implementation timeline from contract signing to first value delivered?"
4. **API and extensibility:** "Show us the documentation for your public APIs, and examples of how other customers have extended the platform for custom metadata or governance workflows."
> A common sales tactic is vague promises about "future roadmap support" for your core tools. If the vendor can't demo a connector today, assume it doesn't exist for the purposes of your evaluation.
### Structuring your next steps
The next step is a focused proof of concept with your top two vendors. Pick a single, high-value business problem, like tracing a critical KPI from its source to a C-level dashboard, and use it as an apples-to-apples benchmark for your final decision.
## Frequently asked questions
Here are direct answers to common questions from engineering leaders evaluating data catalogs.
### How long does it take to implement a data catalog?
Implementation timelines depend on the tool and the scope of the initial project. Modern, SaaS-first catalogs like [Atlan](https://atlan.com/) can be operational in weeks, especially when the initial focus is a high-impact source like [Snowflake](https://www.snowflake.com/en/) or [dbt](https://www.getdbt.com/).
Traditional, governance-first platforms like [Collibra](https://www.collibra.com/) typically need many months of implementation work, often stretching toward a year once you account for workflow configuration and organizational change management. Scope is the real driver: a pilot targeting one business-critical source can deliver value fast, while cataloging an entire enterprise data lake from day one is a multi-quarter effort.
### What's the difference between an active and passive data catalog?
A passive data catalog is a read-only inventory of data assets. It collects metadata to provide a static reference but doesn't act on that information.
An active data catalog uses open APIs to create bi-directional metadata flow: it collects context and also pushes it back into the tools your team uses, like BI dashboards and SQL editors, surfacing business definitions or data quality warnings directly in someone's workflow. An active catalog also automates governance by using metadata to trigger actions, making it an operational hub rather than a reference document.
### How should we measure the ROI of a data catalog?
ROI measurement needs both quantitative and qualitative metrics. On the quantitative side, the most direct metric is time saved in data discovery; a successful implementation should also reduce data-related support tickets and speed up onboarding for new data team members.
On the qualitative side, watch for increased data trust (measured through internal surveys) and higher usage of certified, governed data assets. Both should show up eventually as faster delivery of new data products and analytics projects. If discovery time and support tickets aren't moving after the first year, that's a signal to revisit your adoption strategy rather than the tool itself.
Choosing between these platforms comes down to which failure mode you can least afford: a governance-first tool that slows down your engineering team, or a developer-first tool that fails a compliance audit. Once you've picked a catalog, the harder work is pairing it with the rest of your governance program - [data governance best practices](/insights/data-governance-best-practices/) covers the broader framework, and [data governance vs. data management](/insights/data-governance-vs-data-management/) is worth a read if you're still separating the two disciplines. For firms that can help implement whichever platform you land on, browse the [data governance directory](/data-governance/).
---
## Data Contracts in Data Engineering: A Guide for Engineering Leaders
Source: https://dataengineeringcompanies.com/insights/data-contracts-in-data-engineering/
Published: 2026-03-15T07:23:26.662269+00:00
Description: Explore data contracts in data engineering to enforce agreements, prevent pipeline failures, and boost data reliability across Snowflake and Databricks.
A data contract is a machine-readable, enforceable agreement between a data producer and a data consumer that defines schema, quality thresholds, and semantics before a breaking change can ship. It works like an API contract in software engineering: it catches a renamed field or a changed data type in CI, instead of letting it break a dashboard or model downstream.
20 of the 86 firms profiled in the [Data Engineering Companies Index](/data-governance/) list dbt among their capabilities, and dbt tests are one of the most common ways teams enforce data contracts in practice - see [dbt implementation partners](/insights/dbt-implementation-partners/) for vendors that build these checks directly into dbt pipelines. The contract doesn't need a new platform to get started, just a place to put the rules and a pipeline that fails when they're broken.
## Why do data pipelines break in the first place?
Pipelines break because the team producing data and the team consuming it operate with no formal agreement between them. An application owner renames a field, changes an enum value, or alters a data type with zero visibility into who depends on it downstream - and a critical dashboard or model breaks without warning.
The problem originates in how modern engineering organizations are structured. Autonomous teams are incentivized to ship code and optimize their own services, often with no visibility into who uses the data their applications generate. This forces the data team into a reactive, defensive posture: they spend their cycles diagnosing upstream changes instead of delivering new analytics and AI/ML capabilities. A data platform meant to be a strategic asset becomes a source of recurring, high-cost maintenance.
> If your data pipelines consistently break, your data ecosystem is not producing trusted data. It is enabling teams to ship code without accountability, with data failures as an acceptable externality.
Without a formal agreement, every application dependent on that data - from a dashboard in [Tableau](https://www.tableau.com/) to a model in [Databricks](https://www.databricks.com/) - is vulnerable to unannounced, breaking changes.
### The cost of unreliable data
This instability carries direct financial consequences beyond wasted engineering effort.
* **Eroded business trust:** When executives cannot rely on the data presented, they lose faith in the data team and the platform investments made on its behalf.
* **Wasted engineering time:** Data teams without contracts routinely lose a meaningful share of their week resolving data quality fires instead of building new capabilities - a real cost even without an exact percentage attached to it.
* **Delayed project ROI:** High-value analytics and AI initiatives stall because the underlying data is untrustworthy, directly delaying time-to-market for revenue-generating projects.
* **Compliance and financial risk:** Inaccurate data in financial reporting or regulated domains exposes the business to fines and legal jeopardy under frameworks like [GDPR](https://eur-lex.europa.eu/eli/reg/2016/679/oj).
Data contracts break this cycle by shifting accountability for data quality upstream to the source. That turns data from a fragile byproduct into a documented product with a named owner.
## What does an enforceable data contract actually include?
An enforceable data contract is a formal specification - not a Word document - that defines the structure, semantics, and quality expectations for a data asset, following a standard like the [Open Data Contract Standard](https://bitol-io.github.io/open-data-contract-standard/latest/). It works because both producer and consumer treat it as the source of truth, not a suggestion.
To be effective, a data contract needs several components that establish agreement between producers and consumers.
### Core structural and semantic components
These elements form the foundation of the agreement and prevent the most common breaking changes.
* **Schema definition:** The blueprint of the data. It defines field names, data types (`string`, `integer`, `timestamp`), and structure. This is what stops `customer_id` from silently changing from an integer to a string and breaking every downstream query.
* **Semantic guarantees:** Defines the business meaning of the data. A `status` field is not just a string; it must be one of `['active', 'inactive', 'pending']`. These rules catch logical errors that a schema check alone would miss.
### Operational and quality guarantees
Beyond structure, a complete contract specifies operational behavior and turns reliability into measurable targets.
> An enforceable data contract turns vague promises into measurable commitments. It is the difference between "the data should be fresh" and "this dataset is guaranteed to be updated by 6 AM UTC with less than a **1%** null rate on critical fields."
Key operational components include:
* **Data quality metrics:** Explicit thresholds written into the contract - freshness (data is no more than 60 minutes old), completeness (the `email` field is non-null in at least **99%** of records), or validity (a `country_code` must be a valid ISO 3166-1 alpha-2 code).
* **Service level agreements (SLAs):** Performance expectations for data delivery, such as latency guarantees or uptime commitments for the data asset.
* **Evolution protocol:** A clear process for managing change, including versioning strategies, deprecation policies for old fields, and rules for backward compatibility, so the contract doesn't evolve out from under its consumers.
Demand for experienced data engineers tends to outpace supply, which makes automated defenses like data contracts more valuable, not less, since there aren't enough people to catch every breaking change by hand.
## Where should data contracts be enforced: producer side or consumer side?
Data contracts get enforced in one of two places: at the producer, before data leaves the source system, or at the consumer, when data arrives downstream. Producer-side enforcement blocks bad data at the origin; consumer-side enforcement protects systems that have no control over the source.
Enforcing a contract is not optional if the contract is meant to mean anything - without automated checks, it's just documentation that goes stale. The right strategy depends on your technology stack (Snowflake, Databricks), team topology, and how much control you have over the data sources.
### Producer-side enforcement
This is the most proactive approach. It validates data *before* it leaves the source system, catching issues at the point of origin. Enforcement happens within the producer's CI/CD pipeline: when a developer commits a change that would violate a data contract, such as altering a column's data type, the build fails and the deployment is blocked.
* **Pros:** Prevents bad data from ever entering the ecosystem. Gives developers immediate feedback. Reduces the monitoring burden on downstream teams.
* **Cons:** Requires buy-in from application engineering teams. Can add friction to their workflow if it isn't a low-effort, automated check.
### Consumer-side assertions
Here, the data consumer runs validation checks on arrival. This is a defensive posture used to protect downstream processes. If incoming data fails validation, the consumer can reject the batch, quarantine it, or trigger an alert.
This pattern is necessary when consumers have no control over producers, such as when ingesting data from a third-party API. Tools like [dbt](https://www.getdbt.com/) and [Great Expectations](https://greatexpectations.io/) are built for implementing these checks inside a data warehouse or transformation layer.
> This approach lets consumers protect themselves, but it is fundamentally reactive. The bad data has already been produced and transported, forcing the consumer to spend resources identifying and handling it.
Regardless of the pattern, effective enforcement depends on ongoing [data observability](https://www.datateams.ai/blog/what-is-data-observability). Monitoring contract adherence over time is what helps a team track compliance and quickly diagnose the root cause of a failure.
## How do you actually implement data contracts?
Most teams choose between two implementation models: **contracts-as-code**, where validation rules live directly in the pipeline and CI/CD process, and a **registry-driven model**, where a centralized service stores, versions, and enforces the contract. The right choice depends on where your risk concentrates - batch pipelines or streaming systems.
The contracts-as-code approach integrates validation rules directly into existing data pipelines and CI/CD processes. This is a natural fit for teams that treat their infrastructure as code, using [dbt tests](https://docs.getdbt.com/docs/build/data-tests) or [Great Expectations](https://greatexpectations.io/) checkpoints inside a Git-based workflow.
A registry-driven model uses a centralized service, like [Confluent Schema Registry](https://docs.confluent.io/platform/current/schema-registry/index.html) for Kafka or a dedicated data contract platform, to store, version, and enforce contracts. This decouples producers from consumers and acts as a single source of truth, which suits complex microservices or data mesh architectures.
### Data contract implementation tooling comparison
The right choice depends on your existing stack, team structure, and primary use case. This table compares common approaches for implementing data contracts.
| Approach / Tool | Primary Enforcement Point | Best For | Integration Complexity | Cost Model |
| :--- | :--- | :--- | :--- | :--- |
| **dbt Tests** | In-warehouse, post-load | Teams using dbt for transformations in Snowflake or Databricks | Low (within dbt ecosystem) | Open-source (compute costs apply) |
| **Great Expectations** | CI/CD pipeline or orchestration | Validating data at multiple stages (pre-ingest, post-transform) | Medium (requires Python/CLI integration) | Open-source |
| **Schema Registries** | Producer-side (e.g., Kafka) | Real-time event streams and microservices | Medium to High (requires client library integration) | Varies (open-source or managed service) |
| **Commercial Platforms** | Centralized gateway & producers | Enterprises needing a unified governance layer across multiple systems | High (platform integration) | Subscription (SaaS) |
No single tool covers every case. The most successful implementations blend approaches: a schema registry for event streams and dbt tests for analytical models, with compliance built to be the path of least resistance for developers rather than an extra step they have to remember.
Producer-side schema validation and in-warehouse assertions catch different classes of errors, so combining them closes gaps that either one alone would miss. A layered strategy provides defense at the source and again just before consumption. [Data integration best practices](https://dataengineeringcompanies.com/insights/data-integration-best-practices/) covers the broader pipeline architecture this fits into.
## How do you build the executive business case for data contracts?
Frame data contracts as a strategic investment with measurable ROI, not a technical exercise: less time spent firefighting bad data, faster time-to-value on analytics and AI initiatives, and lower compliance risk from an auditable governance framework. That framing lands with executives in a way that "we need better data quality tooling" does not.
Start with engineering efficiency. Teams without contracts routinely spend meaningful time debugging bad data instead of shipping new work - a hidden cost that data contracts claw back by preventing the errors before they happen, freeing your most expensive technical talent to focus on building instead of repairing.
### Quantifying the financial impact
Data contracts generate ROI through several mechanisms:
* **Accelerated time-to-value:** Trustworthy data eliminates the "data cleanup" phase that stalls most analytics and AI projects, directly shortening time-to-market for revenue-generating initiatives.
* **Reduced compliance risk:** An auditable, contract-based framework for data gives you a clear system for governance, lowering the risk of fines tied to regulations like [GDPR](https://eur-lex.europa.eu/eli/reg/2016/679/oj), as detailed in our guide to [data governance best practices](https://dataengineeringcompanies.com/insights/data-governance-best-practices/).
* **Improved talent retention:** Chronic data quality fire drills and inter-team finger-pointing lead to burnout. Data contracts create clear ownership and reduce friction, which shows up in job satisfaction and lower turnover.
Market data supports the underlying trend. The Big Data Engineering Services market keeps growing, with a significant portion tied to data integration - the domain that depends on stable contracts. With most data deployments now in the cloud, a formal, contract-driven framework matters more for managing complexity and risk, not less.
> The business case is straightforward: invest proactively in data contracts, or keep paying the compounding cost of unreliable data through project delays, wasted salaries, and missed opportunities. Data contracts shift spend from reactive repairs to planned prevention.
Framed this way, data contracts read as a direct investment in operational efficiency and reliability, not a cost center.
## Frequently Asked Questions About Data Contracts
Here are direct answers to the most common questions engineering leaders ask about implementing data contracts.
### What Is the Difference Between a Data Contract and a Schema Registry?
A schema registry is a tool; a data contract is the complete agreement.
A schema registry, such as [Confluent's](https://docs.confluent.io/platform/current/schema-registry/index.html), defines and enforces the *structure* of data - field names and data types. It is the blueprint.
A data contract is the full service-level agreement. It includes the schema but also adds guarantees for data quality (null rates), semantics (allowed enum values), and operational SLAs (freshness). A contract is the complete set of expectations; a schema registry enforces only one part of it.
### How Do Data Contracts Fit into a Data Mesh Architecture?
Data contracts are the enabling technology for a data mesh.
A data mesh architecture treats **data as a product**, with decentralized teams owning their respective data domains. For that distributed model to work, there has to be a standard for how data products are defined, versioned, and guaranteed.
Data contracts provide that standard. They are the formal, enforceable interface for a data product, defining its quality, reliability, and meaning - the mechanism that lets dozens of teams build and consume data products independently without creating chaos.
### What Is the Best First Step in a Legacy Environment?
Don't attempt a "big bang" implementation across every legacy system. Start with a single, high-value, high-pain use case.
Identify a critical business process that frequently fails due to data issues - a key executive dashboard, a customer-facing ML model, or a regulatory report. That's your pilot project.
Work with the *consumers* of that data to define a consumer-driven contract. Enforce it on the consumer side using tools they already have, such as [dbt tests](https://docs.getdbt.com/docs/build/data-tests) or [Great Expectations](https://greatexpectations.io/) checkpoints. This delivers an immediate win by stabilizing one critical asset and gives you a concrete success story to use when you make the case for broader adoption.
---
Data contracts work best as part of a wider governance program, not a standalone fix. [Data governance best practices](https://dataengineeringcompanies.com/insights/data-governance-best-practices/) covers that broader framework, and [data pipeline testing best practices](/insights/data-pipeline-testing-best-practices/) covers how to validate what the contract promises. If you're vetting firms for the work, the [data engineering consulting firms directory](/data-engineering-consulting-firms/) is a place to start.
---
## Your Guide to Data Engineering Consulting Rates 2026
Source: https://dataengineeringcompanies.com/insights/data-engineering-consulting-rates-2026/
Published: 2026-02-23T06:53:40.39179+00:00
Description: Get an inside look at data engineering consulting rates 2026. This guide breaks down costs by firm size, project scope, and how to maximize your ROI.
Across the 86 firms profiled in the Data Engineering Companies Index, published hourly rates run **$45-$250** with a median of **$100**: 35 firms bill under $100/hr, 44 bill $100-$200, and 7 bill $200 or more. Large offshore-heavy IT services shops cluster at the low end, boutique cloud-platform specialists dominate the middle, and Big Four and elite strategy firms sit at the top.
## Why Do Data Engineering Consulting Rates Vary So Much?
Rates vary mainly by firm size and structure, not by the work itself. A Snowflake migration costs the same amount of engineering effort whether a $50/hr offshore team or a $250/hr strategy firm does it - the price difference buys project management depth, risk transfer, and brand assurance, not necessarily better code.
### What Do the Three Consultant Tiers Cost?
The Index's 86 firms split into three rough bands. Large IT services and Big Four/strategy firms span **$75 to $250+/hr**; boutique and mid-sized specialists - the largest bracket at 44 firms - bill **$100-$200/hr**; independent freelancers, who aren't part of the firm-level Index, average **$83.42/hr** industry-wide.
* **Large IT Services, Big Four & Global Strategy Firms:** This bracket spans the widest range in the Index. Deloitte and Accenture price data engineering work at $75-200/hr with $50K-$100K minimum projects, while McKinsey, Bain, and BCG X publish rates of $250+/hr with $400K-$500K+ minimums for enterprise-wide strategic engagements. These firms fit large-scale, multi-year transformations where risk management and executive-level oversight matter as much as the technical build.
* **Boutique & Mid-Sized Specialists:** The largest single bracket - 44 of 86 firms bill $100-$200/hr. Hakkoda, for example, lists $140-220/hr with a $50,000+ minimum project. These firms suit targeted, well-scoped work like a Databricks migration or a Snowflake environment optimization.
* **Independent Freelance Consultants:** Freelancers sit outside the firm-level Index, but industry data from [ContractRates.fyi](https://www.contractrates.fyi/Data-Engineer/hourly-rates) puts the global average at **$83.42/hr**, close to the Index's own sub-$100/hr bracket. Rates run higher for freelancers with rare, in-demand skills.
> Consultants who build data pipelines for generative AI models sit in a distinct category. Their AI/ML infrastructure expertise commands rates roughly 20-30% higher than engineers focused on traditional business intelligence work.
### 2026 Data Engineering Consulting Rates at a Glance
This table pulls real hourly-rate and minimum-project figures from firm profiles in the Index, organized by bracket.
| Consultant Type | Hourly Rate (Index examples) | Minimum Project (Index examples) | Best For |
| :--- | :--- | :--- | :--- |
| **Large IT Services / Big Four** | Deloitte $75-175; Accenture $120-200 | $50K-$100K+ | Large-scale, staff-heavy transformations |
| **Elite Strategy Firms** | McKinsey, Bain, BCG X: $250+ | $400K-$500K+ | Enterprise-wide strategic transformation |
| **Boutique Specialist** | Hakkoda $140-220 | $50K+ | Platform modernizations, specific outcomes |
| **Independent Freelancer** | ~$83-150 (ContractRates.fyi) | $10K-$25K typical | Team augmentation, targeted task completion |
Use this table as a starting point for a budget discussion, not a quote. Confirm the specific firm's published rate and minimum before you build a business case around it.
### How Do You Set a Realistic Budget Anchor?
Start from the Index's published range - $45-$250/hr, median $100 - then narrow it using firm type and project scope. That gives you a ballpark estimate before issuing an RFP, so neither a $350/hr quote nor a $40/hr quote catches you off guard.
For instance, if you're planning a six-month project requiring two senior consultants from a boutique firm, that $100-$200/hr bracket gives you a defensible starting figure for internal discussions. The rest of this guide breaks down how to refine that number based on your project's specifics.
## How Do Enterprise, Mid-Size, and Freelance Consultants Compare?
The rate on a proposal reflects more than raw hourly cost - it reflects the resources, process, and risk transfer a partner brings to your project. Matching your project's requirements to the right partner type is the first step toward a workable budget.
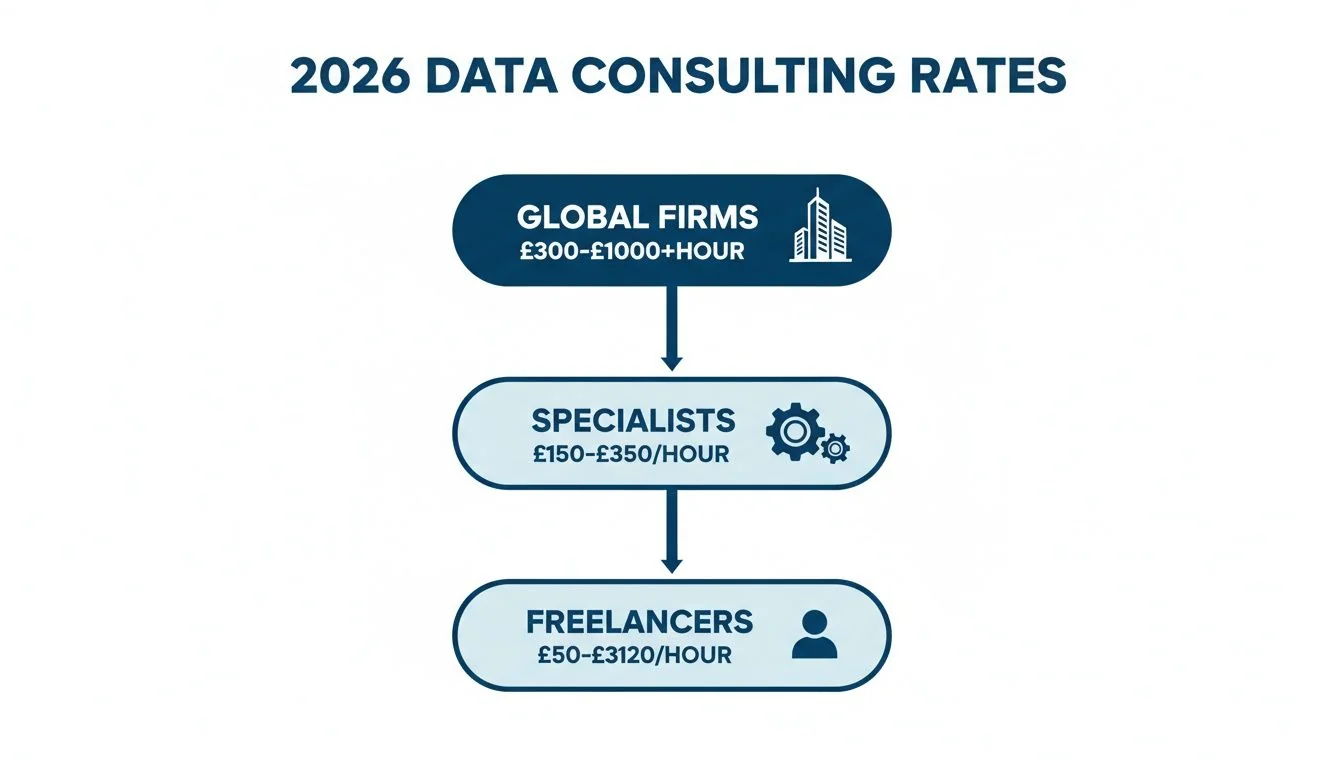
### Enterprise Firms: The Strategic Architects
At the top of the market sit the Big Four and major global system integrators, publishing rates from $75/hr (Deloitte) up to $250+/hr (McKinsey, Bain, BCG X). You engage these firms when a project extends beyond technology into organizational change. They excel in scenarios such as:
* **Petabyte-scale transformations:** overhauling an entire data ecosystem for a Fortune 500 company.
* **Complex regulatory environments:** navigating compliance in finance or healthcare, where errors carry real consequences.
* **Global program management:** coordinating work across continents, business units, and technology stacks.
The hourly rate here buys a proven methodology, formal risk management, and senior engineers, project managers, and subject-matter experts working alongside each other.
### Mid-Sized Specialists: The Value Sweet Spot
For most businesses, mid-sized and boutique consultancies deliver the best balance of expertise and cost. At $100-$200/hr - the bracket that covers 44 of the 86 firms in the Index - they bring specialized talent without enterprise-level overhead.
> Mid-sized firms operate like special forces units. They deploy targeted, high-impact teams to solve specific, complex problems without the logistical footprint of a full army.
These specialists are strong partners for well-defined projects with clear outcomes, including:
* Migrating a legacy data warehouse to [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/).
* Building a new data governance framework.
* Optimizing data pipelines for new analytics or AI/ML models.
Their singular focus is data engineering, which often means faster delivery and more pragmatic solutions for the platform-modernization projects most companies actually face.
### Freelance Experts: The Tactical Reinforcement
Independent freelance consultants offer flexible, targeted access to senior talent. The global average sits around $83.42/hr per ContractRates.fyi, while freelancers with in-demand niche skills can charge $150/hr or more.
Hiring a freelancer works well for:
* **Targeted expertise:** a specialist to solve a problem with a tool like [Fivetran](https://www.fivetran.com/) or [dbt](https://www.getdbt.com/).
* **Staff augmentation:** an extra senior-level engineer to help your team hit a deadline.
* **Short-term support:** a temporary expert to design a pipeline or run a platform audit.
The trade-off is more hands-on management from you, since you're not paying for the project-management layer a firm provides. For companies with strong internal leadership, it's an effective way to get direct access to senior talent at a lower cost.
## What Actually Drives Your Total Consulting Costs?
The hourly rate on a proposal is just the starting point. Several other variables shape the total cost of a data engineering project.
### Project Scope and Complexity
The single largest cost driver is scope. A small, tightly defined task costs less than a complete overhaul of your data infrastructure.
* **A targeted fix:** optimizing a single slow data pipeline might take one consultant a few weeks. The scope is small, the goal is clear, and the cost stays contained.
* **A full platform migration:** migrating an entire analytics stack from a legacy on-premise system to a modern cloud platform is months of work, multiple engineers, and real project management overhead. The total cost lands orders of magnitude higher.
Scope creep - project goals expanding beyond the original agreement - is a silent budget killer. A clear statement of work is your best defense against it.
### Required Expertise and Team Composition
The specific skills on your project directly affect the blended hourly rate. Not all data engineers are interchangeable, and specialization is a real cost factor.
> A project requiring a certified Databricks architect with generative AI pipeline experience will command a premium over one a generalist data developer could handle.
This is especially true as demand for AI/ML pipeline skills intensifies. Among the Index's top bracket - the 7 firms billing $200/hr or more, including McKinsey, Bain, BCG X, EY, KPMG, and PwC - certified Snowflake and Databricks architects with generative-AI experience command the premium end of that range. CIOs weigh that cost against delivery track record, especially in regulated industries like finance and healthcare where a bad migration is expensive to unwind.
### Geography and Delivery Model
The physical location of your consulting team also affects the final cost. Choosing between onshore, nearshore, and offshore resources can lead to significant price differences.
* **Onshore:** consultants in your own country offer the smoothest communication but the highest rates.
* **Nearshore:** teams in nearby countries (Latin America for a US client, for example) balance cost savings with convenient time-zone alignment.
* **Offshore:** consultants in distant regions like India or Eastern Europe offer the largest cost reductions but can introduce communication and time-zone friction.
Many firms now use a hybrid or "blended-shore" model, pairing senior onshore architects with offshore development teams to balance cost and quality.
As you engage consultants, it's also worth understanding what the best [cloud cost management software for 2026](https://www.cloudtoggle.com/blog-en/cloud-cost-management-softwares/) can do, since infrastructure spend often outlasts the consulting engagement itself.
To turn these cost drivers into a real number for your project, run it through the [Data Engineering Cost Calculator](/data-engineering-cost-calculator/) for a scope-specific estimate.
## Choosing the Right Engagement Model for Your Project
Hiring the right consultant is only half the decision - how you structure the engagement shapes incentives, risk, and budget predictability just as much. The three main models are Time & Materials, Fixed-Price, and Retainer, and picking the right one upfront helps avoid mismatched expectations and budget overruns.
### Time & Materials (T&M): The Flexible Build
A Time & Materials model is like paying a mechanic by the hour to restore a classic car: you pay for the actual time and parts used, which gives you room to adapt as unforeseen issues arise.
This model fits projects where requirements aren't fully defined, such as:
* **AI/ML experimentation:** testing different models where the project's direction depends on early findings.
* **Complex system troubleshooting:** investigating a data integrity issue where the root cause is unknown.
* **Agile development sprints:** working against a dynamic backlog where priorities may shift.
The benefit of T&M is adaptability - you can pivot without renegotiating the contract. The trade-off is less budget certainty, which means strong project management and regular check-ins to keep costs in line.
For a deeper look, see our guide on [fixed-price versus time and materials models](/insights/fixed-price-vs-time-and-materials/).
### Fixed-Price: The Predefined Blueprint
A Fixed-Price project is like buying a pre-built shed from a catalog: you know the exact specifications and price beforehand, and the consultant commits to delivering a specific outcome for one all-in price.
This works best when you have clear, well-documented requirements and a fixed scope, for tasks like:
* **A specific database migration:** moving a defined set of tables from SQL Server to Snowflake.
* **Building a single, well-defined dashboard:** a sales performance dashboard with pre-agreed KPIs.
* **A platform security audit:** evaluating your data platform against a known compliance framework like SOC 2 or HIPAA.
> The power of a Fixed-Price project is its predictability. It transfers the risk of time and cost overruns to the consultant, giving you budget certainty. The catch is that any change, no matter how small, will likely require a formal - and often costly - change order.
### Retainer: The Specialist on Call
The Retainer model is like having a specialist doctor on call: you pay a consistent fee to secure their time and expertise for ongoing needs, from emergencies to routine advice. This is a long-term partnership, not a single project.
Retainers suit ongoing maintenance, optimization, and expert guidance, and they're especially common with mid-sized firms - the same $100-$200/hr bracket covering 44 of the Index's 86 firms. Rate variations across industries like logistics and retail run roughly 20-30% depending on how specialized the work is. You can find more consulting trends and statistics in the [Runn.io blog](https://www.runn.io/blog/consulting-statistics).
## How to Evaluate Proposals and Negotiate Value
Once proposals arrive, it's tempting to focus on price, but the lowest hourly rate rarely indicates the best value. True negotiation isn't about haggling over hours - it's about dissecting the proposal to understand what you're actually buying. A low bid from an unqualified team is a fast track to project failure and expensive recovery work.
### Moving Beyond the Blended Rate
A "blended rate" can hide inefficiencies. It averages the cost of senior architects and junior developers into a single number, which can mask an unbalanced team structure.
Ask for a detailed breakdown of roles and responsibilities. What percentage of the project will a $300/hr senior architect handle versus a $125/hr junior engineer? An over-reliance on junior talent might lower the blended rate but lead to slower progress, rework, and a project that ultimately costs more and delivers less.
> The most effective proposals clearly define roles and responsibilities. They map senior resources to critical, high-risk tasks and assign junior talent to well-defined, lower-complexity work under proper supervision.
### Scrutinizing Experience and Defining Success
Every consulting firm claims "relevant experience." Your job is to verify it. Don't accept vague statements like "we've worked in your industry" - ask for specific, verifiable proof:
* **Who was the client?**
* **What was the specific business problem you solved?**
* **What technologies did you use, and what was the tangible outcome?**
This level of detail separates firms with genuine expertise from those with a polished sales deck. The [data engineering consulting firms directory](/data-engineering-consulting-firms/) lets you filter by industry and platform expertise, so you can pre-vet a shortlist of qualified partners before proposals start arriving.
Equally important is defining what success looks like for *your* project. Clear acceptance criteria - the specific, measurable conditions that must be met before you sign off on a deliverable - are non-negotiable. Without them, you risk disagreements over subjective opinions at the project's conclusion.
### Common Red Flags in Proposals
Watch for these warning signs as you review proposals:
* **Vague deliverables:** be wary of statements like "optimize data pipelines" or "improve data quality." Without specific metrics, they're meaningless. A strong proposal states "reduce pipeline processing time by 30%" or "decrease the data error rate to under 1%."
* **Over-reliance on subcontractors:** you need to know who's actually doing the work. Heavy, undisclosed use of subcontractors can create quality-control and communication problems.
* **No risk mitigation plan:** every project hits obstacles. A professional firm names likely roadblocks and how it plans to handle them.
Freelance talent is part of the mix, too. Freelance data engineering consultants command a global average of $83.42/hr per [ContractRates.fyi](https://www.contractrates.fyi/Data-Engineer/hourly-rates), close to the Index's own sub-$100/hr bracket. Blending freelance specialists with a boutique firm's project management is one way to keep a minimum project size closer to $25,000-$50,000 (Simform's and Hakkoda's published minimums) than the $400,000+ minimums the elite strategy tier requires.
## Connecting Consulting Rates to Business ROI
The real test of any data engineering project isn't its cost - it's the value it creates. Thinking in terms of ROI forces you to define success in financial terms before the project begins, which gives you a lens for evaluating proposals and holding your partner accountable for results.
### Building a Practical Business Case
Justifying the investment starts with a simple question: "If this project succeeds, what is it worth to our business?" The key is translating technical outcomes into financial language that resonates with stakeholders from the CFO to the sales team.
A few common scenarios and how to quantify their impact:
* **Faster insights:** if a consultant helps cut your analytics cycle time by 30%, that could mean launching a product three months sooner or spotting a market trend before competitors do.
* **Lower processing costs:** a project that cuts data processing overhead by 40% is a direct saving that drops to the bottom line or gets reinvested.
* **Better data quality:** reducing data errors by 90% means fewer failed marketing campaigns, more reliable financial reports, and less customer churn caused by bad data.
> The most successful data projects are built on specific, measurable goals. Instead of a vague goal like "improve our data," a stronger objective is "cut operational costs by $500,000 annually by automating manual data entry."
### From Technical Metrics to Financial Outcomes
To build a solid ROI model, connect technical improvements to their financial consequences - this is how you justify what might look like a high hourly rate.
Start by identifying your company's key business drivers - what generates revenue or incurs costs - then work backward to see how better data engineering influences them. This requires close collaboration between your technical and business leaders. A [data strategy consultation](/insights/data-strategy-consultation/) is often the right starting point, since it aligns what's technically possible with what's strategically important.
### An ROI Calculation Example
Here's a simplified, illustrative scenario for a retail company.
**The problem:** their inventory system uses stale, batch-processed data, leading to stockouts of popular items and overstock of unwanted products.
**The solution:** they hire a data engineering consultant to build real-time data pipelines connecting point-of-sale systems to the inventory platform.
**The calculation:**
1. **Consulting cost:** a six-week project at $150/hr costs $36,000.
2. **Value from reduced stockouts:** the company estimates it loses $20,000 a month in sales from empty shelves. The new system is projected to cut that loss by 75% ($20,000 x 0.75 = $15,000/month gain).
3. **Value from reduced overstock:** carrying costs for unsold inventory total $10,000 a month. Real-time data is expected to cut this by 50% ($10,000 x 0.50 = $5,000/month saving).
Total monthly value created: $20,000 ($15,000 + $5,000). The project pays for itself in under two months and delivers an annual ROI of over 500% after that - reframing the $36,000 fee from a sunk cost into a high-yield investment.
## Common Questions Answered
### How Much Should a Data Engineering Project Cost in 2026?
There's no single price, but you can build a solid estimate from the Index's real range: $45-$250/hr across 86 firms, median $100. A small, focused project like optimizing a single data pipeline might cost $15,000-$40,000; a full cloud platform migration could run $150,000 to over $1 million depending on scope, team composition, and duration.
### Are Offshore Data Engineering Rates Always Cheaper?
On an hourly basis, almost always - a developer in a market like India or Eastern Europe often charges 40-60% less than a comparable developer in the US. That doesn't guarantee a lower total project cost, since managing communication overhead and time-zone differences poorly can make an offshore project more expensive than an onshore one through rework and delays. Many firms use a blended-shore model - senior onshore architects for strategy paired with offshore teams for development - to balance cost and quality.
### What Is a "Blended Rate" and Should I Trust It?
A blended rate averages the hourly cost of an entire project team, mixing senior and junior developer time into one number. It simplifies a proposal but can be misleading - a low blended rate may signal a team with too many junior, less experienced members. Ask for a full breakdown of team members, individual rates, and allocated hours before you trust it.
### How Can I Ensure I Get a Good Return on My Investment?
Shift your focus from technical tasks to business outcomes before signing a contract. Don't aim to "build a new data warehouse" - aim to "reduce operational reporting time by 50%, saving $200,000 annually in labor costs." Tying the hourly rate to a calculated ROI turns the project into a strategic investment instead of a cost center, and gives you a clear yardstick for holding your consulting partner accountable.
---
Ready to compare consultants side by side? Browse hourly rates and minimum project sizes across the [86 firms in the Data Engineering Companies Index](/data-engineering-consulting-firms/), or run your own numbers through the [Data Engineering Cost Calculator](/data-engineering-cost-calculator/).
---
## Your Guide to Data Engineering Consulting Services
Source: https://dataengineeringcompanies.com/insights/data-engineering-consulting-services/
Published: 2026-01-17T08:34:52.385526+00:00
Description: A practical guide to data engineering consulting services: costs, engagement models, vendor selection, red flags, and platform-specific guidance.
Data engineering consultants design and build the pipelines, warehouses, and infrastructure that turn raw, disparate data into a reliable, structured asset - the layer analytics, machine learning, and AI initiatives sit on top of. They replace manual data wrangling with automated ETL/ELT workflows so analysts and data scientists spend their time on analysis instead of data prep.
The 86 firms profiled in the [Data Engineering Companies Index](/data-engineering-consulting-firms/) range from 3 boutique shops under 50 people to 49 firms with 500 or more employees. That spread matters as much as platform expertise when you're deciding whether you need a specialist team or a firm that can staff a multi-year build.
## What Are Data Engineering Consulting Services?
Data engineering consulting services design and build the pipelines, warehouses, and infrastructure that transform raw operational data into analytics-ready assets. Consultants replace manual data wrangling, automate ETL/ELT workflows, and make sure analysts and data scientists work with reliable, governed data instead of losing most of their week to cleanup and prep.
## How much do data engineering consulting services cost?
Most data engineering consulting services fall between $75 and $250 per hour, with mid-market specialists commonly landing near $100 to $150 per hour. Project-based builds vary more widely: a focused warehouse or pipeline implementation may start around $50,000, while enterprise modernization can run into the high six figures. For a deeper breakdown by role and project type, see [data engineering consulting rates for 2026](/insights/data-engineering-consulting-rates-2026/).
## When should a company hire a data engineering consultant?
Hire a consultant when internal teams are blocked by platform expertise, data quality problems, migration risk, or delivery capacity. The strongest use cases are Snowflake or Databricks migrations, production pipeline rebuilds, governance implementation, and AI readiness work that requires reliable data foundations. If you're still weighing whether to build the capability in-house instead, [consulting vs. an in-house team](/insights/data-engineering-consulting-vs-in-house-team/) walks through that trade-off directly.
Data engineering is the technical infrastructure - the digital equivalent of a building's foundation, plumbing, and electrical grid - that has to exist before analytics or AI can function. Consultants solve the unglamorous problems that make raw data unusable: they build and automate the pipelines that move information from source systems to analytical environments, turning a chaotic flood of data into something structured and dependable.
This work is not about building dashboards. It's about building the factory that produces the trustworthy data those dashboards depend on. Effective data engineering makes sure that when analysts or data scientists query the data, the results are fast, accurate, and reflect operational reality.
### The Core Business Problems They Solve
Organizations engage data engineering consultants to solve specific, costly operational problems that slow down growth and decision-making. This isn't theoretical work - it's about removing friction and opening up capabilities the business couldn't reach on its own.
Key problems they are hired to resolve include:
* **Fragmented and Siloed Data:** Sales data in [Salesforce](https://www.salesforce.com/), marketing data in [HubSpot](https://www.hubspot.com/), and product usage data in a legacy SQL database can't be analyzed together. Consultants design and implement systems to unify this data into a single source of truth.
* **Poor Data Quality and Inconsistency:** Inaccurate data leads to flawed business decisions. If data is riddled with duplicates, errors, or missing values, any analysis built on it is unreliable. Consultants build automated validation, cleansing, and monitoring processes to keep data integrity intact.
* **Manual and Inefficient Processes:** When analytics teams spend the bulk of their week on data preparation and cleaning instead of analysis, the bottleneck is an engineering problem, not an analytics one. Consultants automate these manual workflows so experts can focus on higher-value work.
> **Directory Insight:** Across the 86 firms in the [Data Engineering Companies Index](/data-engineering-consulting-firms/), hourly rates range from $45 to $250, with a median of $100. 35 firms bill under $100/hr, 44 sit between $100 and $200/hr, and 7 charge $200/hr or more. On team size, 3 firms run under 50 people, 34 sit between 50 and 500, and 49 employ 500 or more - so both boutique and enterprise-scale partners are well represented.
> The objective of data engineering consulting is to build a scalable, compliant, trustworthy data architecture that powers confident, data-driven decisions.
### Why is demand for data engineering consultants rising?
Ambitious AI and analytics goals go nowhere without a solid data foundation underneath them, and that's fueling a steady rise in demand for specialized data engineering skills. The drivers are straightforward: data volume keeps growing, cloud platform adoption keeps expanding, and the competitive cost of not putting data to work keeps rising. Market-sizing estimates for the sector vary by analyst firm, but the direction is consistent across all of them - up.
## Which engagement model and deliverables should you choose?
Data engineering engagements fall into three models: staff augmentation (embedding expert engineers in your team for 3-12 months), managed services (outsourcing ongoing data operations under SLAs), and project-based work (building a defined platform with a fixed SOW). Choosing the wrong model is a leading cause of cost overruns and missed business objectives.
The structure of the engagement determines the scope, cost, and outcome, so aligning the model to the business problem is critical for success. Are you hiring a specialist to fill a temporary skill gap, a managed service provider for long-term operational stability, or a project team to build a new system from the ground up? Each model addresses a different need, and understanding the differences is essential for scoping the work, setting expectations, and defining what "done" means.
### What does staff augmentation involve?
This model embeds one or more expert data engineers directly into an existing team for a defined period. The goal isn't to outsource a project but to inject senior-level expertise that accelerates progress and closes a specific skill gap. It's most effective when a company already has a well-defined project and in-house project management but lacks a specific technical capability - for example, a team that needs to build pipelines in [Databricks](https://www.databricks.com/) but has no deep experience with the platform can bring in a consultant for six months to execute the work and upskill internal staff at the same time. See [data engineering staff augmentation](/insights/data-engineering-staff-augmentation/) for a fuller breakdown of how the model works, and [fractional data engineering services](/insights/fractional-data-engineering-services/) for a lighter-weight variant aimed at smaller teams.
**Typical deliverables for staff augmentation:**
* **Code Contributions:** The consultant commits production-ready code to the client's repositories, following existing development workflows and standards.
* **Knowledge Transfer:** The consultant mentors junior engineers, participates in code reviews, and produces documentation so the internal team can own and maintain the work long-term.
* **Accelerated Timelines:** The primary outcome is hitting a critical project milestone faster than the existing team could reach on its own.
### What does a managed services engagement cover?
Managed services is a long-term partnership where a third party takes responsibility for managing, maintaining, and optimizing a company's data infrastructure. This model shifts the focus from augmenting a team to outsourcing the entire operational function - it's a fit for organizations that would rather concentrate on their core business than on running a data platform. The consulting firm effectively becomes the data operations team, handling everything from monitoring pipeline failures and optimizing cloud costs to protecting data quality and system uptime. [Data engineering managed services](/insights/data-engineering-managed-services/) covers pricing structures and what to put in the SLA.
> With a managed service, you're purchasing a guaranteed outcome - system uptime, performance, and reliability - defined by a formal Service Level Agreement (SLA).
### What does a project-based engagement look like?
This is the traditional consulting model, used to build new systems or execute major platform migrations. The client has a specific business objective, such as migrating to [Snowflake](https://www.snowflake.com/en/) (see [data migration best practices](/insights/data-migration-best-practices/) for how that typically runs) or implementing a data governance framework, and hires a firm to deliver a complete, turnkey solution.
The engagement is governed by a detailed Statement of Work (SOW) that specifies scope, timeline, milestones, and deliverables. The consulting firm supplies its own project managers, architects, and engineers to manage the full lifecycle, from design to deployment.
**Typical deliverables for project-based work:**
* **A Deployed Data Platform:** A fully functional data warehouse or lakehouse, tested and ready for analytics teams to use.
* **Automated ETL/ELT Pipelines:** A set of production-grade pipelines that ingest, transform, and load data without manual intervention.
* **Comprehensive Documentation:** Architectural diagrams, data dictionaries, and operational runbooks that let the client's team understand and manage the system going forward.
* **A Data Governance Framework:** Policies, access controls, and quality checks that keep data secure, compliant, and trustworthy.
## How do consulting services line up with modern data platforms?
Choosing a data engineering consultant means checking that their technical expertise lines up with your technology stack. A competent consultant doesn't push a technology for its own sake - they recommend the platform best suited to the business problem in front of them.
That alignment matters because a platform optimized for structured data warehousing performs poorly on large-scale machine learning workloads, and vice versa. Understanding how consultants map their services to today's dominant platforms - [Snowflake](https://www.snowflake.com/en/), [Databricks](https://www.databricks.com/), and the native toolsets of [AWS](https://aws.amazon.com/), [GCP](https://cloud.google.com/), and [Azure](https://azure.microsoft.com/) - is key to making an informed investment.
### How do consultants match workloads to platform strengths?
An experienced consultant treats platforms as specialized tools for different jobs. The first step is analyzing the client's primary workload - business intelligence reporting, real-time stream processing, or AI model training - and matching it to the platform built for that job.
* **Snowflake for Unified Analytics:** Consultants typically recommend **Snowflake** when the primary objective is consolidating data from multiple sources into a cloud data warehouse for business intelligence and analytics. Its architecture, which separates storage and compute, handles variable analytic query loads with minimal administrative overhead.
* **Databricks for Complex Data Science and AI:** **Databricks** is the preferred platform when data engineering needs to support advanced data science, large-scale ETL/ELT, and machine learning. Built on Apache Spark, it processes massive datasets and unifies data engineering and data science workflows inside its "lakehouse" architecture.
* **Native Cloud Services for Integrated Ecosystems:** For companies deeply invested in a single cloud provider, consultants often reach for native services instead - **AWS Glue** for serverless data integration, **Azure Data Factory** for orchestrating complex workflows, or **Google Cloud Dataflow** for stream and batch processing. The advantage is tight integration with everything else already running in that cloud ecosystem.
The diagram below shows how these consulting models apply across those platforms.

As the visual shows, the engagement model depends on the client's internal capabilities and the project's objectives - whether that's filling a temporary skills gap or executing a full platform build.
### Platform Strengths for Data Engineering Workloads
This table maps common data engineering tasks to platform strengths, reflecting typical implementation patterns based on each platform's core design.
| Data Engineering Task | Snowflake | Databricks | Native Cloud (AWS/GCP/Azure) |
| :--- | :--- | :--- | :--- |
| **Cloud Data Warehousing** | **Excellent.** Core strength. Optimized for SQL-based analytics and BI. | **Good.** Supported via Databricks SQL, but primary focus is broader. | **Good.** Services like BigQuery, Redshift, and Synapse are strong contenders. |
| **Large-Scale Data Processing (ETL/ELT)** | **Good.** Snowpark extends capabilities beyond SQL for complex transformations. | **Excellent.** Built on Spark, making it well suited to massive data pipelines. | **Excellent.** Tools like Glue, Data Factory, and Dataflow are built for this. |
| **Streaming & Real-Time Analytics** | **Good.** Capabilities are improving with features like Snowpipe Streaming. | **Excellent.** Structured Streaming is a core, powerful feature for real-time data. | **Excellent.** Kinesis, Event Hubs, and Pub/Sub are purpose-built for streaming. |
| **AI/ML Model Preparation & Training** | **Fair.** Can store and serve feature data, but not a primary training platform. | **Excellent.** Core strength. Unifies data prep, model training, and MLOps. | **Good.** Strong integration with dedicated AI/ML services (e.g., SageMaker, Vertex AI). |
| **Data Governance & Management** | **Excellent.** Strong, built-in features for security, access control, and compliance. | **Good.** [Unity Catalog](https://docs.databricks.com/en/data-governance/unity-catalog/index.html) provides a centralized governance solution for the lakehouse. | **Good.** Relies on a combination of platform-wide and service-specific tools. |
The final decision depends on the primary business objective: accelerating BI reporting or building next-generation AI products. A qualified consultant helps answer that question and then aligns the technology to it.
### What is the modern data stack, and why does it matter here?
The decision is rarely about a single platform. Leading data engineering consultants now focus on combining best-in-class tools into a cohesive data ecosystem - Fivetran for ingestion, dbt for transformation, and Airflow for orchestration are common building blocks.
> A consultant's value lies in acting as a system architect. They don't just install software - they orchestrate a suite of tools that work together to deliver reliable, high-quality data.
This approach avoids vendor lock-in and produces a custom-built solution where each component is chosen for being the best at its specific job. Matched with the right combination of platforms, a consultant turns technology from a cost center into a strategic asset.
## What do data engineering consultants actually cost?
Data engineering consulting rates run roughly $45 to $400+/hr depending on seniority, specialization, and firm size. Across the 86 firms in the [Data Engineering Companies Index](/data-engineering-consulting-firms/), 44 firms charge $100-$200/hr, 35 charge under $100/hr, and 7 charge $200/hr or more - see [data engineering consulting rates for 2026](/insights/data-engineering-consulting-rates-2026/) for the full rate breakdown by role.
Understanding the required investment is a prerequisite for any data engineering initiative. Engaging consultants is a strategic investment in specialized, high-demand skills essential for building a company's data backbone. The cost reflects the consultant's experience, the complexity of the problem, and the business value delivered. A realistic budget is critical for managing expectations and setting the project up to succeed.
### What roles cost what?
Rates are shaped by location, experience level, and expertise in specific technology stacks - a top-tier firm in a major tech hub commands different rates than a boutique consultancy in a smaller market. Even so, it's possible to set reliable ballpark figures for budgeting purposes in 2026.
* **Data Architect:** Responsible for the high-level design of the entire data ecosystem. Seasoned architects with deep expertise in cloud platforms and data governance typically bill between **$250 to $400+ per hour**.
* **Senior Data Engineer:** The expert builders who construct and optimize data pipelines. Rates for engineers with advanced skills in platforms like [Snowflake](https://www.snowflake.com/) or [Databricks](https://www.databricks.com/) generally fall within the **$175 to $275 per hour** range.
* **Mid-Level Data Engineer:** Executes the designs senior staff lay out and handles day-to-day development. Typically bills between **$125 and $195 per hour**.
> Don't fixate on securing the lowest hourly rate. A senior engineer at **$225/hour** who solves a complex problem in 10 hours delivers better return on investment than a junior consultant at **$130/hour** who takes 40 hours and delivers a brittle solution. You're paying for expertise and efficiency, not just time.
### Why do firms have minimum project sizes?
Most established consulting firms enforce a minimum project budget - not to exclude smaller clients, but to make sure every engagement is funded enough to succeed. Delivering meaningful business impact, like a cloud migration or a new analytics platform, requires a certain level of investment to be done correctly; insufficient budgets lead to compromises, shortcuts, and technical debt that costs more to fix later. Setting a minimum protects both the client's investment and the firm's own reputation for delivering solid work.
Most minimum project thresholds start in the **$50,000 to $75,000** range, typically covering discovery, architectural design, initial development, and testing. For larger projects, such as modernizing an enterprise data platform, minimums often start at **$150,000** or more.
Financial clarity upfront is critical for building a budget that aligns with business goals and sets the initiative up for success.
## How do you evaluate and select a data engineering vendor?

Selecting a data engineering consultant is a strategic partnership decision. A bad choice can mean a stalled project, significant technical debt, and a wasted budget. A structured evaluation process, driven by a detailed Request for Proposal (RFP), is the most effective way to reduce that risk - it shifts the conversation from marketing claims to measurable competence. [Data engineering partner selection](/insights/data-engineering-partner-selection/) covers the full evaluation framework in more depth.
Sourcing this expertise is genuinely hard right now. Data engineering is a fast-growing field, and experienced engineers stay in short supply relative to demand, which constrains the talent pool. That scarcity is a big part of why companies turn to consulting firms for critical projects rather than trying to hire every skill in-house.
### What separates real technical mastery from a good sales pitch?
The primary evaluation criterion has to be technical competence. A firm's claimed expertise means nothing without a track record of successful implementations in complex, real-world environments.
Probe for practical skills:
* **Platform Certifications:** Are their engineers certified on relevant platforms? Look for advanced credentials such as the [Snowflake](https://www.snowflake.com/) SnowPro Advanced series or [Databricks](https://www.databricks.com/) Certified Data Engineer Professional.
* **Project History:** Request anonymized case studies for projects of similar scale and complexity to your own. What specific business problems did they solve, and what was the architectural solution?
* **Code Quality Standards:** How do they keep code maintainable, testable, and well-documented? Ask for a sample of their coding standards or documentation practices.
> The most useful question isn't "What tools do you use?" but "Show me an example of a complex problem you solved using these tools and describe the business outcome." That question separates practitioners from theorists.
### What does strong delivery methodology and project governance look like?
Technical expertise doesn't count for much without strong project management and a reliable delivery process. How a firm manages the work matters as much as their technical skill set - a good partner brings structure and transparency to the engagement.
Look for evidence of a mature delivery process:
* **Agile vs. Waterfall:** Do they employ a clear methodology? More importantly, how do they adapt it to a client's specific culture and requirements?
* **Communication Cadence:** What's their standard protocol for status updates, stakeholder meetings, and issue escalation?
* **Resource Planning:** How do they guarantee that the senior experts presented during the sales process are the same people assigned to the project?
### What evaluation criteria get overlooked?
Look beyond the standard checklist - the factors that separate a great partner from an adequate vendor are often in the details.
1. **Data Governance and Security:** Scrutinize their experience with role-based access controls, data masking for PII, and compliance frameworks such as [GDPR](https://gdpr-info.eu/) or [HIPAA](https://www.hhs.gov/hipaa/index.html).
2. **Post-Engagement Support:** What's the transition plan once the project wraps? A strong partner provides a structured hand-off, comprehensive documentation, and flexible options for ongoing support.
3. **Knowledge Transfer:** The best consultants leave your team more capable than they found it. Ask specifically how they plan to upskill your staff - pair programming, workshops, or detailed operational runbooks.
A thorough evaluation takes effort, but it's the single most effective way to reduce the risk in your investment.
## What red flags signal a bad data engineering consulting hire?
Three warning signs predict a failed data engineering engagement: proposing a specific technology stack before understanding your business problem, vague deliverables without defined milestones or acceptance criteria, and presenting senior architects in sales while staffing projects with junior engineers. Each of these patterns is detectable during the RFP process if you know what to ask.
Knowing what to avoid in a data engineering consultant matters as much as knowing what to look for. A compelling sales presentation can obscure fundamental gaps that lead to budget overruns, project delays, and significant technical debt. Catching these warning signs early is a critical part of due diligence.
### Red Flag 1: The One-Size-Fits-All Tech Stack
Be cautious of any consultant who jumps straight to a specific technology. If their first recommendation is [Snowflake](https://www.snowflake.com/en/), [Databricks](https://www.databricks.com/), or a particular cloud provider before they've thoroughly understood your business problem, that's a major red flag.
This usually means they're either a reseller working a sales quota or their team has a narrow skill set. Either way, they're fitting your problem to their solution instead of designing the right solution for your problem. A true expert starts by asking about business goals, current pain points, and long-term objectives - the technology stack is the *how*, and it should only get decided after a clear read on the *why*.
**How to Mitigate:**
Frame initial discussions around business outcomes. Instead of asking what tools they use, ask how they'd solve your problem. For example: "Our objective is to reduce report generation time by 50%. What are two or three architectural approaches you'd consider, and what are the trade-offs of each?" That forces a problem-first answer.
### Red Flag 2: Vague Scopes and Fuzzy Deliverables
A proposal that says "We'll modernize your data platform" is a promise, not a plan. If a proposal is full of buzzwords but lacks a concrete roadmap with clear milestones and defined deliverables, that's a significant risk. Vagueness in a scope of work benefits the consultant, not the client - it opens the door to continuous billing and disputes over what "done" means.
Every professional engagement needs to be built on clarity: what gets delivered at each stage, how success gets measured, and the acceptance criteria for each deliverable.
> A detailed Statement of Work (SOW) is your best defense against project risk. If a firm resists defining phased milestones, specific deliverables, and clear acceptance criteria, that signals a reluctance to be held accountable for results.
### Red Flag 3: The Bait-and-Switch with Junior Talent
This is a common tactic, particularly with larger firms. Senior architects get featured prominently in the sales process, but once the contract is signed, the project gets staffed with junior resources - you end up paying premium rates for a team that's learning on your project.
Junior engineers have a role, but a team lacking strong senior leadership is a recipe for slow progress, brittle code, and short-sighted solutions that need future remediation.
**How to Mitigate:**
Be specific about project staffing.
* **Ask for Names:** Request the names and roles of the individuals assigned to your project.
* **Check Their Experience:** Ask for anonymized resumes or biographies for key team members.
* **Set Ratios:** You can contractually mandate a specific ratio of senior-to-junior engineers.
* **Interview the Team:** Insist on interviewing the project lead and senior engineers who'll actually perform the work, not just the sales lead.
Spotting these red flags early keeps you from consultants who over-promise and under-deliver, and puts you in control of getting a real return on your investment in data engineering consulting services.
## Frequently Asked Questions
Here are direct answers to common questions leaders ask before engaging a data engineering consultant.
### What Is the Real Difference Between a Data Engineer and a Data Scientist?
Using a professional kitchen analogy:
The **data engineer** designs and builds the kitchen. They install industrial-grade plumbing, set up high-powered gas lines, and organize the storage systems, so the chefs have reliable access to high-quality ingredients precisely when needed.
The **data scientist** is the executive chef. They use those prepared ingredients to create and innovate - work that's impossible without a functioning kitchen. A chef can't cook if the infrastructure isn't in place.
### How Long Does a Typical Data Engineering Project Take?
Project timelines vary based on scope and complexity. No credible consultant will give you a fixed duration without a thorough discovery phase first.
Here's a realistic breakdown:
* **Discovery & Audit:** This initial phase typically takes **2-4 weeks**. The consultants map your existing systems and deliver a detailed roadmap.
* **Initial Implementation:** A focused project, such as building the first set of critical data pipelines or migrating a single major data source, usually takes **2-3 months**.
* **Platform Modernization:** A complete overhaul of your data infrastructure is a bigger undertaking - these projects typically run **3-9 months**.
The best partners work in agile sprints, delivering incremental value every few weeks rather than one deliverable at the end.
### How Do I Measure the Success of the Engagement?
Success has to tie to measurable business outcomes, not just project completion.
> The real measure of success isn't a deployed platform - it's a quantifiable improvement in business agility. Track KPIs such as a meaningful reduction in time-to-insight for the analytics team or a measurable decrease in cloud compute costs from optimized pipelines.
Look for concrete metrics:
* **Improved Data Quality:** A drop in business user complaints and support tickets related to data errors.
* **Faster Report Generation:** Critical reports that used to take hours now run in minutes.
* **Increased Team Efficiency:** A measurable drop in the hours your analysts spend on manual data preparation.
---
Ready to stop evaluating and start building? **DataEngineeringCompanies.com** provides firm profiles and practical tools to help you select the right partner with confidence. [Find your ideal data engineering firm today](https://dataengineeringcompanies.com).
**Related guides from DataEngineeringCompanies.com:**
- [How to Choose a Data Engineering Company](/how-to-choose-data-engineering-company/) - step-by-step vendor selection framework with scoring rubric
- [Data Engineering Partner Selection](/insights/data-engineering-partner-selection/) - the full RFP and evaluation framework referenced above
- [Enterprise Data Engineering Consulting](/enterprise-data-engineering/) - selection guide for SOC 2-compliant, enterprise-scale engagements
---
## Data Engineering Consulting vs. In-House Team: A Decision Framework for Engineering Leaders
Source: https://dataengineeringcompanies.com/insights/data-engineering-consulting-vs-in-house-team/
Published: 2026-03-20T09:20:03.366651+00:00
Description: Data engineering consulting vs in-house team: compare cost, speed, and skills to choose the best fit for your 2026 data strategy.
Data engineering consulting and an in-house team solve different problems. Use a consulting firm when you need a production data platform built fast by people who already have the certifications and the playbooks. Build in-house when you're investing in a capability you plan to run and grow for years.
Rates in this market run $45 to $250 an hour, with a median around $100, based on DataEngineeringCompanies.com's analysis of the 86 firms in the [Data Engineering Companies Index](/data-engineering-consulting-firms/) - a useful anchor when you're weighing a consultant's invoice against the fully loaded cost of a new hire. Get that comparison wrong and you either burn a project's timeline waiting for hires who don't exist yet, or hand your core data infrastructure to a vendor who won't be there in eighteen months.
## How do you decide between consulting and building in-house?
The choice depends on the type of work: use a consulting firm for a time-boxed project like a platform migration, and build in-house when the capability needs to exist as a core, ongoing function of the business. The decision pits short-term execution against the long-term accumulation of institutional knowledge, and pretending it's a single universal answer is how teams end up with the wrong model for the job in front of them.
There's also a distinction inside "consulting" itself. Hiring a firm to deliver a finished data platform is a different engagement than hiring contractors to fill open seats on your team. The first is outcome-based consulting; the second is staff augmentation, and the two carry different cost structures, oversight needs, and risk. See our breakdown of [data engineering staff augmentation](/insights/data-engineering-staff-augmentation/) if you're not sure which one you actually need.
### Key decision criteria for engineering leaders
Engineering leaders evaluating this choice are weighing three factors:
* **Speed-to-value:** How quickly can you deliver a production-ready data pipeline or platform that generates tangible business value?
* **Total cost of ownership (TCO):** What is the fully loaded cost beyond contractor rates or salaries, once you count recruitment, benefits, management overhead, and the cost of leaving a role unfilled?
* **Access to specialized skills:** Can you acquire and retain talent with real expertise in platforms like [Snowflake](https://www.snowflake.com/en/), [Databricks](https://www.databricks.com/), or tools like [dbt](https://www.getdbt.com/)?
### Consulting vs. in-house, side by side
| Criteria | Data Engineering Consulting | In-House Data Engineering Team |
| :--- | :--- | :--- |
| **Speed-to-Value** | **High:** A consulting team delivers production-ready systems in weeks or a few months, using pre-built frameworks and skipping the internal learning curve. | **Low:** Ramp-up is slow. Hiring, onboarding, and internal knowledge-building can take 6-9 months before significant value is delivered. |
| **Cost Structure** | **High Variable Cost (OpEx):** Project-based fees with a defined end. No long-term overhead or liabilities. | **High Fixed Cost (OpEx/CapEx):** Salaries, benefits, and training are recurring, long-term financial commitments. |
| **Skill Access** | **On-Demand:** Access to a roster of experienced specialists across the modern data stack, from platform implementation to data governance. | **Limited & Competitive:** Access is constrained by the hiring market. Finding niche specialists (Databricks performance tuning, for instance) is slow and expensive. |
| **Business Context** | **Low:** Consultants start with zero institutional knowledge and need active management to understand business nuance. | **High:** Over time, an in-house team builds institutional knowledge and aligns closely with specific business unit needs. |
| **Scalability** | **Flexible:** Scale a team up for a major project and down at completion, without an HR process attached. | **Rigid:** Scaling up or down is a slow, resource-intensive HR and management exercise. |
| **Best For** | Urgent platform migrations ([AWS](https://aws.amazon.com/), [Azure](https://azure.microsoft.com/en-us), [GCP/BigQuery](https://cloud.google.com/bigquery)), designing pipeline architecture, or standing up a data governance framework from scratch. | Long-term operational stability, ongoing platform maintenance, and a data capability that functions as a core strategic asset. |
Consultants are an accelerant for specialized, high-stakes projects. An in-house team is a long-term investment in a core competency. Most organizations eventually need both.
## What does an in-house data engineer actually cost beyond salary?
Comparing a consultant's rate to a full-time salary compares the wrong numbers. The real comparison is Total Cost of Ownership: base salary plus recruiting, benefits, payroll taxes, training, and the management time spent hiring, onboarding, and retaining that person.
Budget for all of it:
* **Recruitment costs.** Agency or contingency recruiter fees add a real percentage on top of the first-year salary, before the role is even filled.
* **Benefits and payroll taxes.** Health insurance, retirement matching, and employer payroll taxes add a substantial amount on top of base pay - this is not a rounding error.
* **Training and development.** Continuous education for platforms like Snowflake, Databricks, and dbt is a recurring cost of keeping the skill current, not a one-time expense.
* **Management and onboarding overhead.** The time engineering managers and senior engineers spend recruiting, interviewing, and mentoring is a real, if hidden, productivity cost.
### The hidden costs of hiring in-house
The talent pool for specialized data engineering skills is thin, and that scarcity alone is enough to make hiring the single biggest schedule risk in an in-house build-out. It drives up salaries, recruiting costs, and time-to-hire all at once.
> A senior data engineer's base salary is only part of the bill. Add recruiting fees, benefits, payroll taxes, and the management time spent hiring and onboarding, and the fully loaded annual cost typically runs well above the number on the offer letter - before you count the opportunity cost of a hiring cycle that can stretch past six months.
### Modeling the cost of consulting
Data engineering consulting operates on a different financial model, typically project-based or retainer fees. The initial proposal can look high, but it's a predictable, all-inclusive cost that skips the long-term liabilities of benefits, severance, and training budgets. Our [data engineering consulting rates](/insights/data-engineering-consulting-rates-2026/) guide has current benchmarks for that OpEx investment.
For a framework on making the comparison formally, see [build vs. buy for a data platform](/insights/build-vs-buy-data-platform/), which walks through similar math from the platform-decision side. For a 12-month data platform implementation, a consulting engagement is frequently more cost-effective than hiring, training, and managing a new team from scratch, especially once you factor in the risk of a project stalling on a skill gap.
The decision isn't really about the hourly rate. It's a choice about financial risk, predictability, and speed-to-value.
## How much faster is a consulting engagement than an in-house build?
For urgent work like a cloud data migration, consultants typically deliver a production-ready platform in months while an in-house team is still hiring. That timeline gap is the single biggest argument for bringing in outside help on time-sensitive projects, and it's where the two models diverge the most.
Consultants arrive with playbooks, code accelerators, and hands-on implementation experience on platforms like [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/). They've already worked through the common failure points, which lets them skip the learning curve an internal team has to go through firsthand. They're paid to execute, not to learn on your budget.
### Contrasting project timelines
Building an in-house team follows a slow, sequential path. The project clock starts when the job description is approved, not when work begins. In the current market, finding and hiring one senior data engineer commonly takes 3-6 months, and onboarding to full productivity adds another 1-3 months on top.
During that 4-9 month stretch, no project work gets done. A consulting partner would already have infrastructure provisioned and initial pipelines delivered.
> For a typical data warehouse modernization project, an experienced consulting firm often delivers a production-ready solution in 4-6 months. An internal team starting from scratch commonly needs 9-12 months to reach the same milestone, once hiring and onboarding delays are factored in.
### The opportunity cost of delay
That gap isn't just a schedule slip - it's lost business opportunity and compounding technical debt. The effects ripple across the organization:
* **Delayed analytics.** BI and data science teams work with stale, unreliable data, forcing decisions to get made on incomplete information.
* **Stalled AI/ML initiatives.** Planned predictive models and revenue-generating AI applications stay on hold.
* **Competitive disadvantage.** A competitor working with a consultant can launch a data-driven feature and take market share while you're still interviewing candidates.
Engaging a data engineering consulting firm is a strategic investment in compressing time. For urgent, high-impact projects, the acceleration it provides delivers business value months faster than an in-house team can manage alone.
### Bridging specialized skill gaps on demand
The modern data stack is a wide ecosystem of specialized tools. Most organizations can't staff full-time experts in every niche - from Snowflake cost optimization and Databricks performance tuning to data governance with [Collibra](https://www.collibra.com/) or CI/CD for data pipelines with [dbt](https://www.getdbt.com/).
Using a data engineering consulting firm gives you on-demand access to a bench of specialists, which beats the long, often futile search for a single "unicorn" engineer.
### Accessing a roster of experts
Partnering with a consultancy also gives you access to the firm's collective knowledge, which matters when an Enterprise Architect or VP of Engineering is planning a multi-year roadmap.
* **Cloud infrastructure.** Get access to someone experienced in [AWS](https://aws.amazon.com/), [Azure](https://azure.microsoft.com/en-us), or [GCP/BigQuery](https://cloud.google.com/bigquery) to design and provision your data platform correctly from day one.
* **Data modeling and transformation.** Bring in a specialist to architect a scalable dbt project or work through a complex data modeling problem without a six-month hiring cycle.
* **MLOps and advanced analytics.** As your platform matures, bring in MLOps engineers to productionize machine learning models when you need them, not before.
This model gets you the right expert at the right time, without the recruiting delay and cost of hiring for a niche, hard-to-fill role.
> A consulting firm can deploy a specialist for a focused, three-month engagement to solve a specific problem, such as tuning a runaway Databricks cluster. You get the fix without the long-term cost of a full-time hire. That kind of surgical, short-term engagement is hard to replicate with an in-house team.
The market trend backs this up: more engineering leaders are treating specialized consulting as a standing part of their data strategy, not a stopgap for when hiring stalls.
## What happens to governance and institutional knowledge after the consultants leave?
Consultants can stand up a governance framework fast, using proven templates for data quality, access controls, and compliance monitoring - but they build it, they don't run it long term. Without a deliberate handoff, the platform they built starts to decay the day the engagement ends.
Your team model shapes how your data practice scales and stays secure over time. Consultants can implement data governance frameworks quickly on platforms like [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/), but their role is to build the framework, not to operate it indefinitely.
### The handoff: the most critical phase of a consulting engagement
The most common failure point in a consulting project is a weak handoff. Without a structured knowledge transfer process, the delivered platform degrades and the project's return on investment goes with it.
> The success of a data consulting project is measured six months after the engagement ends: can your internal team confidently operate, maintain, and improve the system on its own? A poor handoff creates technical debt and a dangerous dependency on the vendor.
Knowledge transfer should be a contractual deliverable, not an afterthought. Your statement of work should require:
* **Paired programming.** Your engineers actively code and review alongside the consultants, not just watch.
* **Living documentation.** Comprehensive, version-controlled documentation for every pipeline, model, and piece of infrastructure.
* **Recorded training sessions.** Technical walkthroughs and business logic explanations get recorded and archived as a permanent onboarding asset.
### Surge capacity vs. sustainable operations
The two models offer different scalability profiles. Consultants provide immediate surge capacity: the ability to assemble a large, experienced team for a major undertaking like a cloud migration. That lets you make a big technological leap without a permanent increase in headcount.
An in-house team provides steady, incremental capacity. They handle ongoing maintenance, bug fixes, and feature work that keeps the data platform aligned with changing business needs - the kind of operational ownership consultants aren't built for.
A hybrid strategy is often the most effective approach: use consultants for high-impact, transformative projects that need specialized skills and speed, and give your in-house team ownership of the long-term vision, day-to-day operations, and the knowledge transfer that keeps the platform delivering value after the consultants leave.
## How do you turn this into an actual decision?
Score both models against the factors that matter most to your organization right now, using a weighted matrix rather than gut feel. The exercise below is a template - the weights are yours to set, but the scoring discipline is what produces a defensible answer.
Start by classifying the nature of the work. Is it a net-new, high-impact project, or the buildout of a long-term operational capability? This flowchart is an initial directional guide.
This is a first-pass filter. The type of work - transformative project vs. ongoing function - is the single most important factor.
### A quantitative evaluation framework
This weighted decision matrix asks you to score each factor by its current importance to your organization. Assign a weight from 1 to 5 to each criterion, then score each model from 1 to 10 on how well it delivers on that factor. The weighted score gives you a quantitative, defensible result.
| Decision Factor | Weight (1-5) | Consulting Score (1-10) | In-House Score (1-10) | Weighted Score |
| :--- | :--- | :--- | :--- | :--- |
| **Speed to Value** | 5 | 9 | 3 | **C:** 45, **IH:** 15 |
| **Long-Term TCO** | 4 | 6 | 8 | **C:** 24, **IH:** 32 |
| **Access to Niche Skills** | 5 | 10 | 4 | **C:** 50, **IH:** 20 |
| **Knowledge Retention**| 3 | 4 | 9 | **C:** 12, **IH:** 27 |
| **Scalability (Up/Down)**| 4 | 9 | 5 | **C:** 36, **IH:** 20 |
| **Total Score** | | | | **C: 167**, **IH: 114** |
In this example, heavy weighting on speed and access to niche skills makes consulting the clear choice. Your own weights will differ, but the exercise gives you a data-backed rationale instead of a guess.
### What to do with your score
* **If consulting scored higher:** Your immediate priority is a precise scope of work (SOW). A vague request gets a vague proposal. Use our guide on [how to evaluate a data engineering partner](/insights/data-engineering-partner-selection/) to structure a rigorous RFP and start vendor selection.
* **If in-house scored higher:** Your priority is a realistic hiring plan. Acknowledge the competitive market and map an achievable timeline and budget for recruiting, interviewing, onboarding, and ongoing training.
## Common questions engineering leaders ask
### When does a hybrid model make the most sense?
A hybrid model is the right strategy when you need to execute a major project quickly while also building long-term internal capability. This is common for large-scale platform migrations or a full data architecture overhaul.
In this setup, consultants handle the initial heavy lifting: architectural design and intensive implementation. Your in-house team works directly alongside them, absorbing knowledge, contributing business context, and preparing to take on full operational ownership after launch. It's the approach that gives you the most acceleration without giving up long-term self-sufficiency.
***
Whichever way the matrix points, the decision doesn't have to be permanent. Teams revisit this call as scope changes - a [managed services](/insights/data-engineering-managed-services/) arrangement can bridge the gap if you want ongoing support without a full consulting engagement or a new hire. Once you know which model fits, [how to choose a data engineering company](/how-to-choose-data-engineering-company/) covers what to look for in a partner.
---
## The 10-Point Data Engineering Due Diligence Checklist for 2026
Source: https://dataengineeringcompanies.com/insights/data-engineering-due-diligence-checklist/
Published: 2026-04-02T07:14:08.329571+00:00
Description: Don't hire a consultant without this data engineering due diligence checklist. Vet firms on architecture, cost, governance, and team skills before you sign.
Choosing a data engineering consulting firm is one of the most consequential decisions a technology leader makes: a strong partner accelerates platform modernization, and a weak one leaves you with budget overruns and technical debt that outlasts the contract. The stakes are high and vetting is harder than it should be, because marketing claims dominate most sales conversations.
This checklist covers ten points, from pipeline architecture and team certifications to FinOps discipline and delivery methodology, along with the specific evidence and questions to use when scoring a vendor. Rates alone show how wide the range is: firms in the [Data Engineering Companies Index](/data-engineering-consulting-firms/) charge anywhere from $45 to $250 an hour, with a median around $100 - a gap that reflects real differences in capability, not just overhead. Use these ten points to cut through the pitch and get to what a firm can actually deliver.
## 1. What does strong data pipeline architecture look like in a vendor?
A vendor's pipeline architecture should be resilient, scalable, and cost-efficient for your specific data volumes, not just built from whatever tools the firm knows best. The distinction that matters is whether their design choices are driven by your operational needs or by what's easiest for them to staff.
That means evaluating their command of modern ETL/ELT patterns, their judgment on streaming versus batch processing, and whether they implement data lineage tracking people actually use. A firm that defaults to expensive, high-frequency streaming for every use case without a clear business justification is optimizing for their own convenience, not your budget.
### Evidence to Request and Questions to Ask
Move beyond sales presentations and demand concrete proof of technical depth.
* **Architectural Diagrams:** Request anonymized architecture diagrams from past projects with similar data volumes and complexity. Ask them to walk you through the design, explaining their choice of components (e.g., Fivetran for ingestion, dbt for transformation, Airflow for orchestration) and the trade-offs involved.
* **Source System Experience:** Probe their experience with your specific source systems. Ask: "Describe a project where you migrated data from SAP S/4HANA to a Snowflake data warehouse. What were the main technical challenges, and how did you solve them?"
* **Cost Governance:** Assess their approach to financial management. Ask: "How do you implement cost controls and monitoring for a Databricks environment? Provide an example where you reduced a client's query or compute costs."
* **SLAs and Recovery:** Test their understanding of operational reality. Present a scenario: "If our primary sales pipeline fails and our SLA is two hours, what is your standard recovery procedure and communication protocol?"
> **Key Takeaway:** The goal is to verify hands-on technical expertise, not sales engineering polish. A competent partner understands how architectural choices connect to operational performance and total cost of ownership, and can speak specifically about warehouse credits, cluster compute, and designing for failure.
## 2. How do you verify a vendor's team actually has the expertise they claim?
Ask for named individuals, not brand reputation. A firm's proposal should list who is staffed on your account, their certifications, and how long they've worked together - not just adjectives like "senior" and "expert."
Team size varies enormously across the market: of the 86 firms profiled in the [Data Engineering Companies Index](/insights/enterprise-vs-boutique-firms/), only 3 run under 50 people while 49 run 500 or more. Size alone doesn't predict whether a team has the specialists you need, which is exactly why you confirm certifications and tenure directly rather than assume them from a firm's headcount. Look for certified cloud architects (AWS, GCP, Azure), platform specialists (Snowflake, Databricks), and engineers with credentials from programs like Snowflake University or Databricks Academy.
### Evidence to Request and Questions to Ask
Move past vague assurances of "a great team" and demand specific, verifiable proof.
* **Team Roster & Certifications:** Request a detailed team roster for your engagement, including roles, tenure with the firm, and a list of active technical certifications. Ask: "Can you provide links to the official certification profiles for the lead architect and senior engineers assigned to our account on platforms like Databricks Academy or Credly?"
* **Specialization Breadth:** Evaluate the team's skill distribution. A team of only cloud architects is insufficient. Ask: "Beyond cloud infrastructure, who on the team holds certifications in data transformation tools like dbt or orchestration platforms like Airflow? Describe the roles they will play."
* **Team Cohesion and Stability:** Probe the stability and experience of the proposed team. High turnover is a significant project risk. Ask: "What is the average tenure of the proposed team members, both at your firm and working together? Can you provide project success rates or client satisfaction scores for this specific team?"
* **Investment in Training:** Understand their commitment to skill development. Ask: "What is your annual budget and policy for employee training and certifications? How do you ensure your engineers stay current on new platform features and best practices?"
> **Key Takeaway:** You are hiring a team, not a brand name. Verify that the individuals assigned to your project hold current, relevant certifications and have a track record working together. A partner's investment in its team's education is a direct investment in your project's outcome, which is why it's worth checking against broader [vendor evaluation criteria](/insights/data-engineering-vendor-evaluation-criteria/) before you sign.
## 3. What should a data governance and compliance framework actually cover?
A governance framework should make data discoverable, trustworthy, secure, and compliant with regulations like GDPR, CCPA, and HIPAA, without freezing analytics teams out of the data they need. The practical test is whether a vendor can point to cataloging, lineage tracking, role-based access controls, and audit logging they've actually implemented, not policies they've written but never operationalized.
Governance is worth scrutinizing precisely because it's often treated as an afterthought: just 11 of the 86 firms in the Index list it among their core capabilities, against 78 that list migration work. If governance matters for your industry, don't assume a firm that's strong on pipelines is equally strong here - ask about it directly, and check how they balance risk controls against the agility your data science and analytics teams need.
### Evidence to Request and Questions to Ask
Push for tangible proof of past work, and probe their methodology for industry-specific compliance challenges.
* **Industry-Specific Case Studies:** Request examples of governance implementations within your regulated industry. Ask: "Walk us through a project where you implemented a HIPAA-compliant governance framework for a healthcare provider. How did you manage PHI, and what access control models did you use?"
* **Tooling Experience:** Assess their familiarity with your existing or planned governance stack. Ask: "We use Collibra for our data catalog. Describe your process for integrating it with a new Snowflake data warehouse to automate metadata ingestion and lineage mapping."
* **Policy and Documentation Samples:** Ask for anonymized examples of governance charters, data classification policies, or compliance reports they have produced. This shows the clarity and practicality of their work.
* **Balancing Governance and Agility:** Test their understanding of modern, federated governance models. Ask: "How do you implement a data mesh governance model that gives domain teams control while keeping central policy enforcement and data quality standards in place?"
> **Key Takeaway:** Real data governance expertise shows up as controls that are both effective and practical. Listen for specific regulations, named tools like Alation or Atlan, and measurable outcomes such as faster data discovery, reduced compliance risk, and business users making decisions with confidence in the data.
## 4. How do you evaluate a vendor's FinOps and cost management maturity?
Look for a partner who treats your cloud budget like their own - building cost governance and optimization into delivery as standard practice, not something they address only after the bill arrives. This isn't about picking the cheapest bid; it's about finding a partner who can keep a high-performing platform inside your budget.
Many firms can build pipelines. Fewer can actively manage and optimize the recurring cloud spend those pipelines generate, which is where a partner's real financial discipline shows. Ask them to walk through their [FinOps](https://www.finops.org/introduction/what-is-finops/) practice with specifics, not generalities.
### Evidence to Request and Questions to Ask
Demand evidence of past performance and a clear methodology for cost governance.
* **Cost Optimization Case Studies:** Ask for specific case studies with real, quantified before-and-after numbers on cloud data platform costs, like Databricks or Snowflake spend. For instance, ask: "Show us a case where you reduced a client's monthly Databricks DBU consumption. What specific techniques did you use, and what was the percentage reduction?"
* **Platform-Specific Pricing Knowledge:** Test their expertise on the platforms you use. Ask: "What are the three most common drivers of unexpected cost overruns in a Snowflake environment, and what monitoring and alerting mechanisms do you implement to prevent them?"
* **FinOps Governance Framework:** Inquire about their formal process for managing costs. Ask: "Can you walk us through your FinOps framework? How do you establish budgets, create showback or chargeback models for business units, and conduct regular cost reviews?"
* **Balancing Cost and Performance:** Present a trade-off scenario. Say: "Our analytics team needs query results in under five seconds, but their workload is driving up warehouse costs. How would you approach optimizing this without degrading their experience?"
> **Key Takeaway:** A competent partner proves their value in ongoing operational efficiency, not just the initial build. Listen for specifics on reserved capacity, storage tiering, query optimization, and cost-attribution models. Their goal should be maximizing your return on the data platform, not their own billable hours on a system nobody has bothered to tune.
## 5. What does a real data quality and observability practice look like?
Data quality work should be continuous and automated - testing, anomaly detection, and incident response built into the pipeline itself - not a final check before data ships to a dashboard. A firm whose quality strategy stops at dbt tests alone hasn't built for a complex, multi-source environment.
A firm that pairs an observability platform like Monte Carlo with a clear incident response protocol catches data problems before they reach a business report. A partner whose quality strategy ends at [dbt tests](https://docs.getdbt.com/docs/build/data-tests) alone lacks the operational depth a complex enterprise environment needs - dbt tests validate what you thought to check for; observability platforms catch what you didn't.
### Evidence to Request and Questions to Ask
Move past vague promises of "high-quality data" and demand specific evidence of their frameworks and tool proficiency.
* **Platform Experience:** Evaluate their hands-on experience with modern data quality tools. Ask: "Describe a project where you implemented a data observability platform like Monte Carlo or Soda. What specific types of anomalies did it help you detect, and what was the business impact?"
* **Testing Strategy:** Probe the depth and breadth of their quality testing methodology. Ask: "Walk us through your standard testing strategy for a new data pipeline. Where do you implement unit tests, integration tests, and freshness checks? Provide an example of a data quality rule framework you built using [Great Expectations](https://docs.greatexpectations.io/docs/home)."
* **Incident Response Process:** Test their operational readiness for when data issues inevitably arise. Present a scenario: "Our revenue dashboard is showing a sudden 50% drop. What are the first three steps in your incident response playbook, and what is your communication protocol with business stakeholders?"
* **Metrics and KPIs:** Assess their ability to measure and report on data quality. Ask: "What key metrics do you use to track data reliability? Provide an example of a dashboard you've built to monitor data uptime and mean time to resolution."
> **Key Takeaway:** A capable partner treats data quality as a continuous, automated process built into the data lifecycle, not a final-step check. Listen for data contracts, schema change detection, and how they balance quality rigor against development speed - proof they can deliver data that's present and trustworthy.
## 6. Why does organizational adoption belong in a technical due diligence checklist?
A technically flawless data platform that nobody uses has still failed. Assess a firm's ability to drive organizational adoption: how they train different user groups, communicate progress, manage resistance, and set up governance that gives users real ownership, not just documentation dropped at project close.
You're evaluating their ability to turn a platform investment into measurable business value through actual use. A partner that focuses only on the technology stack, with no plan for people and process, will deliver a platform that struggles to earn back its cost.
### Evidence to Request and Questions to Ask
Look for proof of methodology and its impact on past projects.
* **Change Management Methodology:** Ask them to detail their approach. "Do you follow a standard model like ADKAR or Kotter, or do you have a proprietary framework? Walk us through the phases and key activities for a project like ours."
* **Training and Enablement Materials:** Request anonymized samples of training programs they have developed. Ask: "Can you provide examples of training materials you created for different user groups, such as business analysts versus executive leadership, on a new Databricks platform?"
* **Adoption Measurement:** Probe how they quantify success. Ask: "How do you define and measure user adoption? Share specific KPIs you track, like time to proficiency or query success rates, and the results you achieved for a recent client."
* **Executive Sponsorship & Governance:** Assess their strategy for embedding the change. Present a scenario: "We have multiple business divisions with competing priorities. How would you recommend structuring a data council and engaging our executive sponsors to ensure alignment and sustained adoption?"
> **Key Takeaway:** A top-tier data engineering partner knows the job isn't finished when the last pipeline runs successfully. They act as change agents bridging IT and the business, so the tools they build actually get used in day-to-day decisions. Look for specific adoption rates, training completion metrics, and a repeatable change process.
## 7. Can the vendor actually connect to your legacy systems, not just modern SaaS tools?
A platform's value depends on how well it connects to what you already run, from decades-old ERPs to current SaaS applications. Firms with experience limited to API-friendly SaaS tools often struggle when they hit an aging AS/400 or a heavily customized SAP instance.
You're evaluating their practical ability to extract data from a diverse set of sources: CRMs, HR systems, and proprietary on-premise databases. That requires API-first architecture skills, real judgment on connector ecosystems like Fivetran or Stitch, and the ability to build custom integrations when off-the-shelf tools fall short.
### Evidence to Request and Questions to Ask
Push for evidence of their experience with systems that mirror your own technology stack.
* **Source System Inventory:** Provide a list of your most critical source systems (e.g., Salesforce, NetSuite, an Oracle E-Business Suite database). Ask: "Detail your experience integrating with these specific platforms. For Salesforce, describe a project where you managed complex object relationships and custom fields."
* **Connector Strategy:** Investigate their approach to tool selection. Ask: "When do you recommend a managed connector service like Fivetran versus building a custom API integration? Describe a scenario where a custom build was the necessary choice and explain the rationale."
* **Legacy System Case Study:** Probe their experience with difficult, non-standard sources. Request: "Provide an anonymized case study or architecture diagram where you connected a legacy, on-premise system to a cloud data warehouse like Snowflake. What were the main security and data extraction challenges?"
* **Data Mapping and Quality:** Assess their methodology for handling data at the point of ingestion. Ask: "How do you approach data mapping and schema validation when integrating data from over 20 different sources? What is your process for managing data quality issues that originate in the source system?"
> **Key Takeaway:** The goal is confirming their ability to handle the messy reality of enterprise integration. A capable partner knows when to use pre-built connectors for speed and when custom development is worth the investment, and can speak specifically about managing API rate limits and source schema drift.
## 8. Is the vendor's data foundation actually ready for AI/ML work?
A data foundation built only for BI dashboards becomes a bottleneck for data science teams. Ask whether a vendor's pipelines support feature engineering, model training, and MLOps, not just SQL reporting - that's the real test of AI/ML readiness.
You're looking for a firm that thinks beyond tables and dashboards, preparing your organization for predictive modeling, recommendation engines, and other AI-driven applications. Part of that foundation is knowing how to handle different data types well, including the unstructured formats that most ML use cases depend on alongside structured tables. A partner focused only on BI reporting will build a platform your data science team outgrows quickly.
### Evidence to Request and Questions to Ask
Go beyond surface-level claims of "AI expertise" and demand proof of their data engineering capabilities in an ML context.
* **Feature Store Experience:** Ask about their practical experience with feature stores, which accelerate ML development. Ask: "Describe a project where you implemented a feature store like Tecton or a Databricks native solution. What was the impact on the data science team's time-to-model?"
* **MLOps Infrastructure:** Probe their knowledge of the end-to-end machine learning lifecycle. Ask: "How do you design data pipelines to support model retraining, monitoring for drift, and governance using tools like MLflow? Provide an example from a financial services or healthcare client."
* **Self-Service Analytics Enablement:** Evaluate how their architecture gives analysts and data scientists secure access. Ask: "Walk us through how you would configure a Databricks SQL or Snowflake environment to provide secure, self-service access for our analytics team while controlling costs."
* **Industry-Specific Use Cases:** Test their domain knowledge. Present a scenario: "For an e-commerce company, what data foundation is required to build a real-time recommendation engine? What architectural choices would you make and why?"
> **Key Takeaway:** A partner truly ready for AI/ML shows a clear line from data engineering to data science: feature engineering pipelines, model registries, and data preparation for specific algorithms, not generic data warehousing repackaged as "AI-ready." Their success shows up in the speed and reliability of your ML models in production.
## 9. How deep is the vendor's expertise in your specific cloud platform?
General cloud knowledge isn't enough. Your evaluation needs to confirm platform-specific depth in Snowflake, Databricks, or BigQuery - the difference between a firm that capitalizes on native features and cost controls, and one that delivers a generic build that fails to earn back your platform investment.
True proficiency means understanding a platform's architecture, pricing model, and feature roadmap. A firm with deep Snowflake experience designs workloads to control warehouse credit consumption; a Databricks specialist structures Unity Catalog correctly for your governance needs. Without that specific expertise, you risk paying for a solution that never delivers the platform's full value.
### Evidence to Request and Questions to Ask
Go beyond marketing claims of "partnership" and demand tangible proof of platform-specific implementation and optimization skills.
* **Partnership Verification & Certifications:** Ask for their official partner tier (e.g., Snowflake Elite Partner, Databricks Preferred Partner, Google Cloud Premier Partner) and request a list of certified individuals. Verify this status directly on the vendor's partner portal. Ask: "How many of the engineers staffed on our project will hold active, advanced certifications for [Your Platform]?"
* **Platform-Specific Optimizations:** Probe their ability to fine-tune performance and cost. Ask: "Provide an example where you migrated a client to Databricks and reduced their processing costs by modifying their job cluster configurations and implementing Photon. What was the outcome?"
* **Migration Strategy:** Assess their experience with complex migrations. Present a scenario: "We are migrating from an on-premise Netezza system to Snowflake. Outline your phased approach, key risk mitigation steps, and the tools you would use for data validation."
* **Roadmap Awareness:** Check their knowledge of the platform's future. Ask: "What upcoming features on the [Your Platform] roadmap are most relevant to our industry, and how would you incorporate them into our architecture over the next 12 months?"
> **Key Takeaway:** The best partners don't just use a cloud platform, they master it. Look for a clear history of platform-native solutions, fluent discussion of cost drivers like warehouse credits or DBUs, and advice grounded in where the platform is actually headed, not a generic pitch that would apply to any vendor.
## 10. Does the vendor have a real project delivery methodology, or just a promise to "be agile"?
A brilliant technical solution delivered late, over budget, or off-target from the business problem is still a failure. Evaluating delivery methodology and governance tests whether a firm executes predictably and stays accountable from kickoff to handoff - a defined framework, not a slogan.
The evaluation here focuses on their practical approach to managing work, communication, and risk. A mature partner has a well-defined process, whether Scrum, a hybrid model, or phased delivery, backed by governance structures like steering committees and regular stakeholder reviews. A firm that can't articulate its change control process is a red flag for scope creep and budget overruns down the line.
### Evidence to Request and Questions to Ask
Inspect their process documentation and question its real-world application.
* **Methodology Documentation:** Request a formal document outlining their project delivery methodology. Ask them to explain how they adapt it for projects of different sizes and complexities, such as a large-scale data platform migration versus a smaller proof-of-concept.
* **Scope & Change Management:** Probe their process for handling evolving requirements. Ask: "Walk us through your change control process. If we request a new data source be added mid-sprint that impacts the timeline by 10%, how is that documented, approved, and communicated?"
* **Risk Management:** Evaluate their foresight and planning for common data project pitfalls. Ask: "Provide a risk register from a past project. What were the top three technical risks you identified for a Snowflake migration, and what were your mitigation plans?"
* **Progress Reporting & Cadence:** Understand how you will be kept informed. Inquire: "What does your standard project reporting look like? Provide a sample weekly status report and describe the cadence of your steering committee and technical workstream meetings."
> **Key Takeaway:** A strong delivery methodology provides the guardrails for a successful project. A competent partner shows a repeatable process for managing scope, risk, and communication - proof they run projects deliberately rather than letting them happen.
## Actionable Framework: A 10-Point Comparison Table
Use this table to score potential data engineering partners against the core criteria. A vendor's strength in one area, like AI/ML readiness, can be offset by a weakness in FinOps, so weigh all ten before you decide.
| Criterion | Key Evaluation Area | Top-Tier Vendor Evidence | Red Flag |
|---|---|---|---|
| **1. Pipeline Architecture** | Resilience, scalability, and cost-efficiency of designs. | Provides anonymized architectural diagrams with clear rationale for component choices. | Proposes a one-size-fits-all architecture without probing your specific needs. |
| **2. Team Expertise** | Verifiable certifications and team cohesion. | Shares public certification profiles for the proposed team (e.g., on Credly). | Vague promises of "senior talent" without specific names or credentials. |
| **3. Data Governance** | Practical implementation in regulated environments. | Shows a HIPAA-compliant RBAC model for a healthcare client. | Defines governance only in theoretical terms without implementation examples. |
| **4. FinOps & Cost Mgmt** | Proven ability to reduce cloud data platform spend. | Case study with a real, quantified before-and-after reduction in Snowflake credit or Databricks DBU spend. | Cannot articulate platform-specific cost drivers (e.g., warehouse size vs. clusters). |
| **5. Data Quality** | Proactive observability and incident response. | Details an incident response playbook and data observability tool implementation. | Data quality strategy is limited to basic dbt tests with no monitoring. |
| **6. Org. Adoption** | Structured change management and user training. | Provides sample training materials tailored to different user personas (e.g., analyst vs. exec). | Believes the project ends when the technology is deployed. |
| **7. Integration** | Experience with legacy and complex source systems. | Describes connecting a legacy on-premise Oracle DB to a cloud data warehouse. | Only has experience with modern, API-first SaaS tools. |
| **8. AI/ML Readiness** | Foundation building for data science (e.g., feature stores). | Explains how their pipelines populate a feature store to accelerate model training. | Equates AI/ML readiness with building standard BI dashboards. |
| **9. Platform Proficiency** | Deep, platform-native optimization skills. | Outlines a phased migration strategy from Netezza to Snowflake with validation steps. | Holds only basic-level vendor partnerships or certifications. |
| **10. Project Delivery** | Disciplined execution and risk management. | Provides an example risk register and change control process document. | Cannot show a sample project status report or define governance cadence. |
## From Checklist to Shortlist: Your Next Steps
You've now worked through a ten-point data engineering due diligence checklist built to get past a vendor's sales pitch and into what they can actually deliver: a resilient, scalable, cost-effective data platform. A checklist is only a tool, though - the real work is applying it inside your own evaluation process.
### Operationalizing Your Due Diligence
1. **Build a weighted scorecard.** Not all ten criteria carry equal weight for your organization. A fintech company under heavy regulation should weight **Data Governance & Compliance** higher than a startup focused on rapid growth; a retail enterprise personalizing customer experiences should weight **AI/ML Readiness** higher.
* **Action:** Assign a percentage weight to each of the ten criteria. For example, "Data Governance" might be 30% for a healthcare organization, while "Cost Management & FinOps" might be 25% for a PE-backed company under margin pressure.
* **Example allocation:** Data Pipeline Architecture 15%, Team Expertise & Certifications 10%, Data Governance & Compliance 20%, Cost Management & FinOps 15%, and the remaining six criteria splitting the rest until you reach 100%.
2. **Run structured vendor interviews.** Use the questions from each section as a script during vendor presentations and technical deep-dives. Don't let a potential partner control the narrative - drive the conversation toward your specific criteria.
* **Action:** When a vendor discusses their **Project Delivery Methodology**, press them on the exact governance model. Ask for anonymized status reports, risk logs, and escalation paths from previous projects.
* **Evidence to Request:** For **Cloud Platform Proficiency**, ask for a real-world (anonymized) migration plan they developed for a client with a starting point similar to yours.
3. **Validate with reference calls.** Vendor-provided references will always be positive; your job is extracting specifics. Use your weighted scorecard to guide the conversation toward what matters most to you.
* **Action:** Instead of asking "Were you happy with the project?" ask something tied to the checklist: "Can you describe how the vendor helped you establish a data quality monitoring framework, and what was the before-and-after impact on data reliability?"
### The End Goal: Confidence, Not Just a Contract
The point of a rigorous due diligence process isn't to make procurement more complicated - it's to de-risk one of the most consequential technology investments your company will make. Getting your data foundation right, or wrong, has cascading effects on operational efficiency, product innovation, and your ability to deploy AI while staying compliant.
A thorough, evidence-based evaluation turns vendor selection from a subjective pitch contest into an objective decision grounded in what a firm can actually show you. Take the time to vet properly, and you're not just hiring coders - you're choosing a [partner](/insights/data-engineering-partner-selection/) who understands the business implications of every architectural decision they make on your behalf.
---
## Data Engineering for SaaS Companies: Leaders' 2026 Guide
Source: https://dataengineeringcompanies.com/insights/data-engineering-for-saa-s-companies/
Published: 2026-05-28T10:24:50.00602+00:00
Description: Elevate your data engineering for SaaS companies. This guide covers multi-tenancy, cost, vendor selection, & platform modernization for leaders.
**Data engineering for SaaS companies is a cost-discipline problem before it's a tooling problem.** The winning move isn't collecting more data - it's turning product, billing, CRM, and support data into trustworthy metrics and customer-facing features without letting warehouse spend, pipeline sprawl, and governance debt outgrow product value. If those three rise faster than the business, you didn't build an asset. You built overhead.
The right question is simple: which data platform design gives the business trustworthy metrics, AI-ready data, and customer-facing analytics at a cost structure you can defend? That's the standard I use when advising software companies on data platform modernization, vendor selection, and consulting engagements.
## Why is cost the real challenge in SaaS data engineering, not capability?
**The market already offers more ways to move data into Snowflake, Databricks, BigQuery, Redshift, or Azure than any team needs.** You can wire up Fivetran, Airbyte, dbt, Airflow, Dagster, Kafka, Spark, and half a dozen observability tools in a quarter. That doesn't mean you should - the constraint isn't what you can build, it's what you can afford to keep running.
A better framing comes from [Centric Consulting's discussion of data engineering unit economics and ROI discipline](https://centricconsulting.com/blog/data-engineers-the-hidden-drivers-of-the-great-data-disruption/). Their point is the one most SaaS leaders miss: coverage usually focuses on pipeline capability and speed, while the harder business question is how to keep data costs proportional to product growth.
### Treat data spend like data COGS
If your product depends on usage reporting, customer health scoring, embedded analytics, revenue reporting, or AI features, your data platform is part of delivery. Track it like **data COGS**, not a vague shared services budget, across four lenses:
- **Ingestion cost per source**. Know which connectors, CDC jobs, and event streams justify their spend.
- **Transformation cost per domain**. If finance, product, and support each run duplicative models, fix the model design before you blame the warehouse.
- **Serving cost per workload**. Internal BI, reverse ETL, customer dashboards, and ML features should not all share the same latency and compute assumptions.
- **Governance overhead per team**. Every manual permission review, schema fix, and broken metric definition is operating cost.
That discipline starts with cloud basics. If your finance and engineering teams need a good operating baseline, Buttercloud's guide to [cloud cost optimization strategies for startups](https://www.buttercloud.com/blog/cloud-cost-optimization-strategies) is a useful companion for setting expectations before your data stack expands.
> **Practical rule:** If a platform decision doesn't improve margin, retention reporting, or product capability in a measurable way, defer it.
### The expensive mistake
The most common mistake is building for hypothetical scale. Teams buy a streaming architecture before they've identified one workload that requires it. They stand up Databricks because it feels like the safer long-term bet, then run mostly SQL transformations that a warehouse and dbt would handle more easily. They let every department add tools, then act surprised when governance and cloud bills drift.
For data engineering for SaaS companies, the standard should be harsh: **prove the use case, prove the ownership model, then build the minimum architecture that survives growth**.
## How should you architect multi-tenant data for isolation?
**For SaaS companies, the hardest architecture decision usually isn't Snowflake versus Databricks - it's how tenant data is isolated.** Get this wrong and you inherit one of two bad outcomes: cost per tenant becomes absurd, or your governance model collapses the first time an enterprise customer asks detailed questions about access boundaries, data residency, or customer-facing analytics.
### The three patterns that actually matter
| Attribute | Silo Model (Database per Tenant) | Pool Model (Shared Database) | Hybrid Model (Pooled with Premium Silos) |
|---|---|---|---|
| **Isolation boundary** | Strongest logical separation | Shared storage with tenant filters | Mixed, based on tenant tier or risk |
| **Cost per tenant** | Highest | Lowest | Controlled, if used selectively |
| **Operational burden** | High | Lower at baseline | Medium to high |
| **Performance isolation** | Strong | Variable unless carefully engineered | Strong for premium workloads |
| **Governance complexity** | Lower inside each tenant, higher across fleet | High because policy errors affect everyone | Highest because two models coexist |
| **Customer-facing analytics fit** | Good for strict isolation requirements | Good for broad scale if row-level controls are mature | Best when large tenants need custom treatment |
| **Migration flexibility** | Weak if you over-customize | Strong if schemas stay disciplined | Strongest if tenant promotion paths are planned |
### When does the silo model work?
The **silo model** gives each tenant its own database, schema, or full environment. It's expensive, but the trade-off is obvious and sometimes necessary. Use it when you have:
- **Strict enterprise boundaries** where customers expect hard separation
- **Custom compute or retention policies** for a subset of tenants
- **Contractual obligations** that require dedicated treatment
- **Heavy customer-facing analytics** that would otherwise create noisy-neighbor problems
The downside is operational drag. Every migration, schema update, and quality check multiplies across tenants. Consulting teams often underestimate this because the early implementation looks clean. The pain shows up later in fleet management.
### When does the pool model work?
The **pool model** is the default choice for most SaaS platforms because it gives the best cost profile: one shared platform, one set of models, one warehouse, one observability layer. But pooled architecture only works if you treat tenant controls as first-class engineering, not an afterthought:
- **Tenant keys are mandatory** in raw, staged, and modeled layers
- **Row-level access rules** are versioned and tested
- **Metric definitions** are tenant-aware from the start
- **Schema changes** are reviewed for downstream tenant impact
- **Customer-facing workloads** don't query ad hoc shared tables
> Shared infrastructure is cheap right up until one bad join leaks cross-tenant data.
### When should you use a hybrid model?
The **hybrid model** is where mature SaaS platforms end up: pool the majority of tenants, then promote selected tenants or workloads into silos when economics, compliance, or performance justify the move. That keeps baseline costs under control while preserving a premium path for larger accounts.
#### My recommendation for choosing
Don't pick a tenancy pattern as a philosophical preference. Pick it based on these decision criteria:
1. **Revenue model.** If premium accounts pay for dedicated analytics, hybrid is usually the commercial fit.
2. **Customer-facing data requirements.** If your product exposes usage dashboards, benchmarking, or exports, pooled models need stricter semantic controls.
3. **Support model.** If your support team frequently inspects customer-level data, access boundaries must be explicit and auditable.
4. **Migration path.** If a pooled tenant can't move into a dedicated setup without a rewrite, your architecture is brittle.
5. **Consulting team capability.** Many firms can build pipelines. Fewer can design tenant isolation, promotion paths, and policy automation cleanly.
The mistake to avoid is trying to solve multi-tenancy inside BI alone. Isolation belongs in platform design, transformation logic, and permissioning. If you leave it to dashboards, you've already lost control.
## What does a modern SaaS data stack look like?
**The best SaaS data stack is modular, not maximal:** managed ingestion where speed matters, SQL-first transformation where repeatability matters, and warehouse or lakehouse choices based on workload shape rather than what's trending.
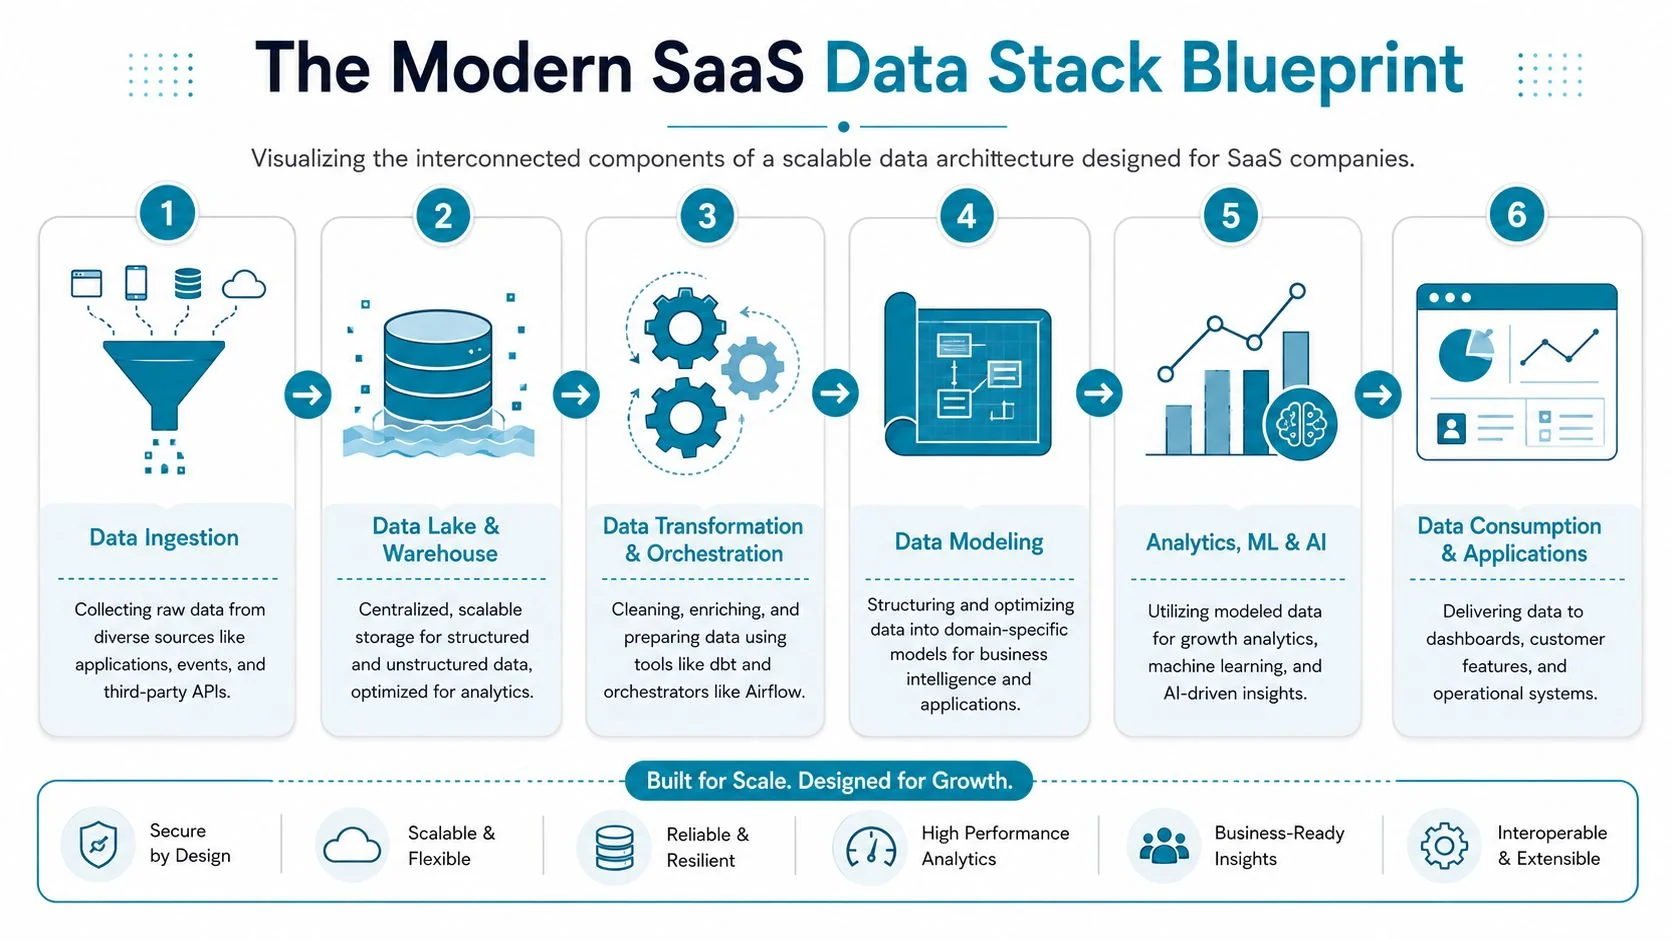
### A blueprint that survives growth
A practical stack for data engineering for SaaS companies usually looks like this:
- **Product event ingestion** with Segment or Snowplow when event governance matters
- **Operational source ingestion** with Fivetran or Airbyte for Salesforce, HubSpot, Zendesk, NetSuite, and similar systems
- **Core platform** on Snowflake, Databricks, BigQuery, or an AWS/Azure-native architecture depending on team skill and workload shape
- **Transformation layer** in dbt for standardized, testable business logic
- **Orchestration** with Airflow or Dagster when workflow control and dependencies matter
- **Consumption layer** for BI, reverse ETL, embedded analytics, ML features, and application services
### Snowflake or Databricks for SaaS?
**Choose Snowflake first** if your immediate goals are finance-grade metrics, modeled analytics, internal reporting, and predictable SQL-heavy delivery. It's usually the cleaner fit for teams that need fast time to value with strong separation between storage, compute, and governed sharing - see [Snowflake's own documentation on secure data sharing](https://docs.snowflake.com/en/user-guide/data-sharing-intro) for how that separation works in practice.
**Choose Databricks first** if your platform already has heavy data science, large-scale event processing, unstructured or semi-structured workloads, or engineering teams comfortable with Spark-oriented patterns. It's a better fit when analytics and ML engineering are tightly coupled.
BigQuery is strong when the team is already committed to GCP. AWS and Azure-native patterns make sense when procurement, security, and platform operations already center there. But don't let cloud loyalty override workload reality.
### Why dbt and orchestration matter more than tool fashion
dbt became the standard for a reason: it forces business logic into version-controlled, testable transformations, per [dbt's own documentation](https://docs.getdbt.com/docs/introduction). That matters more than connector count.
Your orchestrator matters too, but less than people assume. Airflow remains a solid choice when you need broad ecosystem support and explicit dependency management. Dagster is attractive when you want stronger software-defined assets and developer ergonomics. Either works if the team owns it.
If you're planning AI-heavy workloads, this piece on [AI integration in data stacks](/insights/modern-data-stack/) is a useful reference for separating core analytical architecture from experimentation layers.
> Don't buy six tools to avoid writing standards. Standards are the real platform.
### What to avoid
- **Connector sprawl** where each team buys its own sync tool
- **Transformation split-brain** where logic is scattered across SQL, Python notebooks, BI dashboards, and app code
- **Single-cluster thinking** where every workload shares one compute posture
- **Premature streaming** without a real product or operational need
- **Opaque vendor lock-in** where nobody can explain how critical models are built
The stack should reflect business priorities. If the current priority is board metrics and embedded reporting, optimize for governed SQL and clear tenancy patterns. If the current priority is ML feature velocity, optimize for data contracts, feature consistency, and notebook-to-production discipline.
## How do you model data for analytics, ML, and customer features?
**A platform becomes valuable when the data model serves real consumers, and for SaaS those consumers fall into three groups: operators, models, and customers.** Each needs a different modeling discipline, not one shared layer stretched three ways.
One SaaS-focused KPI guide makes the point directly: CAC, LTV, churn, MRR, and NRR all depend on engineered data pipelines, and the discipline connects straight to financial execution, not just reporting ([Phoenix Strategy Group on SaaS KPI data engineering](https://www.phoenixstrategy.group/blog/data-engineering-guide-kpis-for-saas-companies)).
### Internal analytics needs one metric layer
If finance, sales, and product all calculate MRR differently, the problem isn't dashboard design - it's model design. Build an explicit semantic layer for:
- **Customer grain** with account, tenant, contract, and lifecycle status
- **Subscription grain** with plan, effective dates, expansion, contraction, and cancellation events
- **Usage grain** with normalized product events tied to account identity
- **Support and CRM grain** for health, funnel, and retention analysis
Keep the metric logic centralized in dbt. Test it. Version it. Don't let Looker, Power BI, Sigma, and ad hoc SQL each invent their own revenue definitions.
### ML workloads need stable features, not hero notebooks
Most SaaS ML efforts fail because feature logic differs between experimentation and production. For churn models, lead scoring, anomaly detection, or product recommendations, define feature pipelines that reuse the same trusted entities and event models from the analytics layer, then expose them through a feature-serving pattern your platform team can support consistently.
That doesn't require a heavyweight feature store on day one. It does require discipline around:
- **Point-in-time correctness**
- **Entity keys and tenant scope**
- **Refresh cadence**
- **Training-serving consistency**
Here's a useful engineering overview before you push models into production:
### Customer-facing features need product-grade data contracts
Many internal data teams stumble on this point: embedded analytics, usage dashboards, benchmarks, customer exports, and admin reporting are not BI side projects. They are product features, and they need to be modeled separately from internal analytics.
1. **Create product-serving models.** They should be tenant-scoped, latency-aware, and backward-compatible.
2. **Version customer-facing metrics.** If a definition changes, support migration intentionally. Don't surprise customers.
3. **Precompute what's expensive.** Your app should not fire complex warehouse queries for every dashboard load.
4. **Define freshness by feature.** Some customer metrics can be delayed. Others can't. Don't overbuild real-time where near-real-time is enough.
> If a customer sees the number, your product team owns the definition with data engineering. Not BI.
## What does a SaaS data governance and security framework look like?
**Most governance programs fail because they start as policy-writing exercises. SaaS companies need operational governance that survives continuous schema change, fast product releases, and cross-functional data access.**
A recent overview of data engineering trends highlighted the gap directly: governance for customer-facing and AI-ready SaaS data is under-addressed, especially around schema change, data quality, and safe sharing, and the field is shifting from infrastructure plumbing to reliability engineering for decisioning and AI ([Refonte Learning on data engineering trends and governance](https://www.refontelearning.com/blog/data-engineering-in-2026-trends-tools-and-how-to-thrive)).
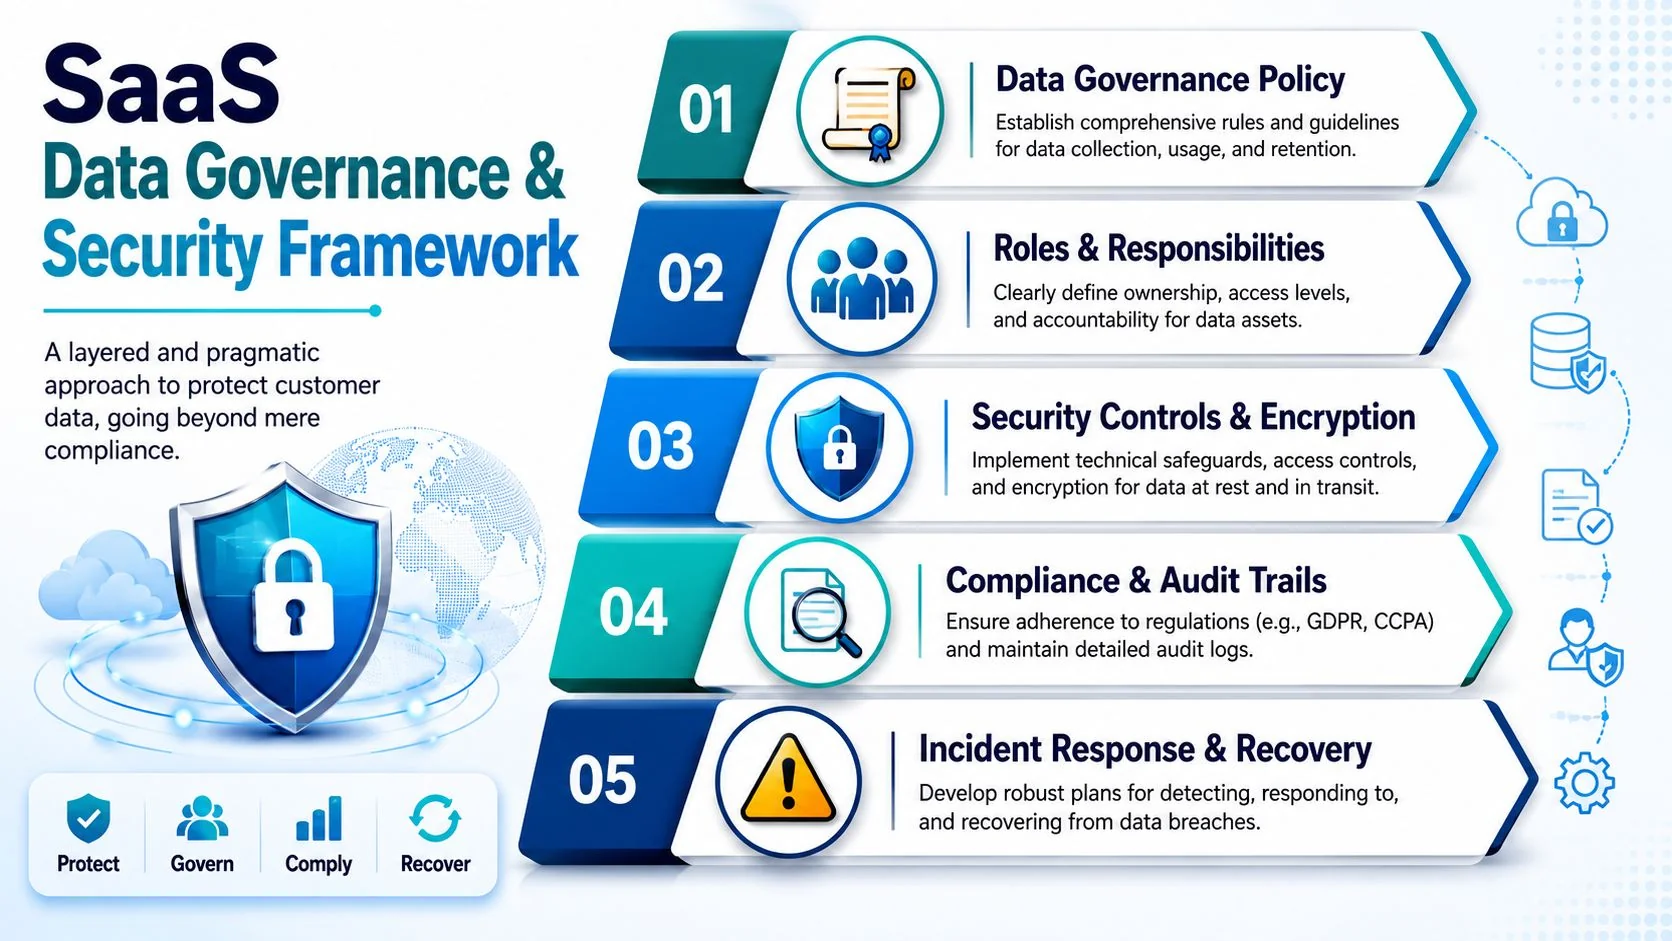
### Five controls that matter
#### Policy tied to data products
Every critical domain needs an owner. Product events, billing data, customer identity, support data, and financial metrics should each have accountable ownership. Use a shared standard for classification, retention, and acceptable use. If you need a starting point, the [DataEngineeringCompanies governance template](/insights/data-governance-framework-template/) is a practical way to structure ownership and policy decisions.
#### Access control at the right granularity
Role-based access is the floor, not the ceiling. Use:
- **Column-level restriction** for sensitive attributes
- **Masked development datasets** for lower environments
- **Tenant-aware policies** for shared environments
- **Auditable privileged access** for support and operations teams
Application security still matters around the edges of the platform too. If your engineering org is tightening controls end to end, this guide on how to [secure your SaaS application](https://www.affordablepentesting.com/post/saas-pentesting) is a useful complement to data-layer governance.
#### Data quality contracts
Data quality should be attached to models and interfaces, not reviewed in a meeting after something breaks. Require tests for:
- **Schema stability**
- **Null and uniqueness expectations**
- **Accepted value ranges**
- **Freshness windows**
- **Tenant key integrity**
### How do you build observability instead of assigning blame?
**Instrument pipelines so teams can catch schema drift, missed loads, and metric divergence before they reach a dashboard - not after a customer notices.** When sources change, dashboards break, ML features drift, and support teams lose trust, so observability has to answer three questions automatically.
| Governance concern | What to monitor | What action to automate |
|---|---|---|
| **Schema change** | Upstream field additions, deletions, type changes | Block unsafe promotion and alert owners |
| **Data freshness** | Missed loads and delayed event arrival | Trigger retries and escalate on breach |
| **Metric consistency** | Divergence between canonical and downstream models | Fail tests before dashboards refresh |
| **Access misuse** | Unexpected queries against sensitive domains | Audit and revoke when policy is breached |
> Governance that slows delivery gets bypassed. Governance embedded in CI, orchestration, and access policies gets adopted.
### Discovery closes the loop
You also need discoverability. Every metric and high-value model should have a documented definition, owner, upstream lineage, and intended audience. Without that, analysts fork logic, product managers export raw tables, and ML teams train on unvetted inputs.
For data engineering for SaaS companies, governance is not a compliance annex. It's what lets the company ship customer-facing analytics and AI features without losing trust.
## How do you select a data engineering vendor for a SaaS platform?
**Ask vendors to answer these questions clearly - if they dodge, remove them from the shortlist.** A generalist consultancy can migrate data; it takes a specialist to design tenant isolation, board metrics, product analytics, and governance without spawning years of cleanup work. As SaaS adoption accelerated, data engineering grew from a small specialty into critical infrastructure, tracking the shift toward standardized, automated, cloud-based pipelines ([DataEngi on the rise of data engineering in SaaS](https://www.dataengi.com/post/how-data-engineering-enables-customer-analytics-in-saas)).
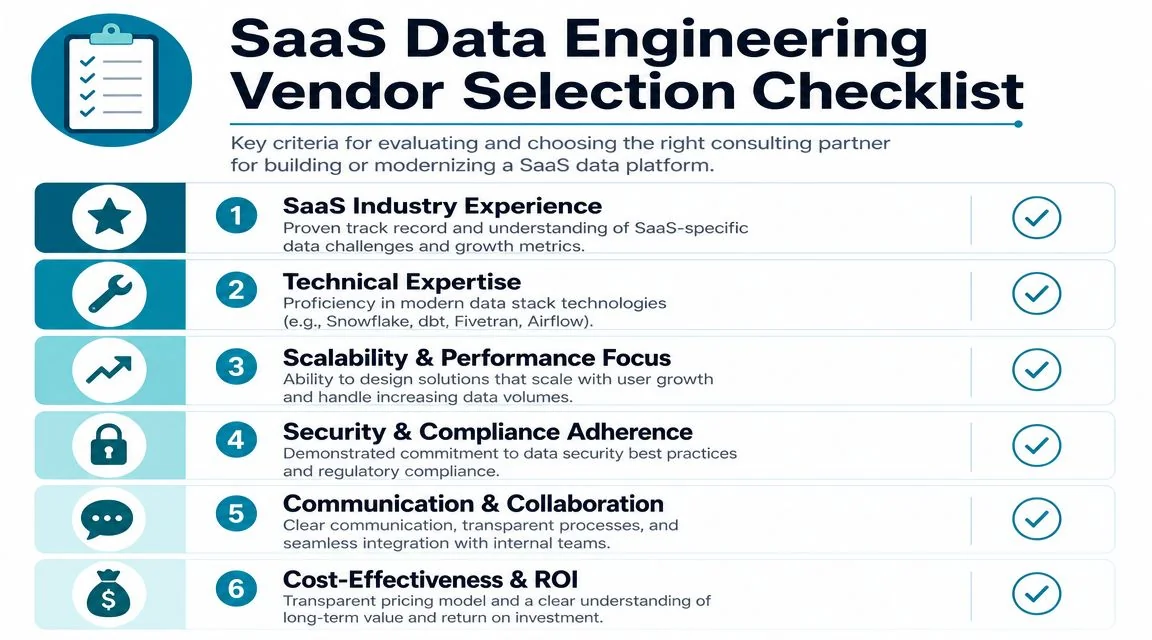
### What I'd put in the RFP
1. Which SaaS data platforms have you built that include tenant isolation?
2. What tenancy pattern do you recommend for our product and why?
3. How do you model MRR, churn, expansion, contraction, and NRR canonically?
4. Which cloud are you strongest on: AWS, Azure, or GCP?
5. What is your default warehouse recommendation and what would change it?
6. How do you decide between Snowflake and Databricks?
7. What ingestion tools do you prefer for CRM, billing, support, and product events?
8. When do you recommend dbt, and when don't you?
9. How do you enforce schema change management?
10. How do you implement row-level and column-level access control?
11. How do you design customer-facing analytics models differently from internal BI?
12. What observability stack do you deploy by default?
13. How do you document metric definitions and lineage?
14. What do you automate in CI/CD for data assets?
15. How do you estimate ROI before implementation?
16. How do you control data platform unit costs as volume grows?
17. What team roles are included, and which are fractional?
18. What work is done offshore, onshore, or hybrid?
19. How do you transfer ownership to our internal team?
20. What does success look like in the first ninety days?
21. Show an example of a failed engagement and what you changed afterward.
22. What assumptions in our draft architecture do you disagree with?
### How to score proposals
Don't score heavily on slide quality or brand recognition. Score on evidence of judgment:
- **Architecture fit** for your tenancy and workload model
- **Platform depth** in your chosen cloud and core tools
- **Governance maturity** beyond access-control boilerplate
- **Commercial clarity** on scope ownership and change control
- **Enablement quality** so your team can run the platform afterward
> The best consulting partner is the one willing to narrow scope early, challenge your assumptions, and say no to unnecessary platform complexity.
If your team is earlier stage and still deciding whether to build this function in-house at all, [our guide to data engineering for startups](/insights/data-engineering-for-startups/) covers the same tradeoffs at a smaller scale, before tenancy and governance complexity set in.
## What does a 90-day data platform modernization roadmap look like?
**The first ninety days should produce one thing above all else: confidence that your platform direction is financially sane and operationally trustworthy.** That means an audited baseline, one production path shipped end to end, and named owners for the metrics that matter - not a finished platform.
### Days 1 to 30
Audit the current stack. Map every source, pipeline, model, dashboard, and downstream dependency. Identify where metric definitions diverge, where tenant isolation is weak, and where spend is rising without clear value. Then make three decisions: your target tenancy model, your core platform choice, and the first business metric domain to standardize.
### Days 31 to 60
Build the foundation, not the whole future state. Stand up the core environment. Implement one high-value path end to end, typically product events plus billing or CRM into the warehouse, dbt models, tests, and a governed dashboard. Add access policies and schema-change alerts now, not later.
### Days 61 to 90
Expand to a second source domain and force governance into the operating model. Define owners for key datasets. Publish metric definitions. Add observability. Separate internal models from product-serving models if embedded analytics is on the roadmap.
By day ninety, you should have:
- **One canonical metric domain**
- **One validated tenant isolation pattern**
- **One production governance workflow**
- **One clear cost model for further rollout**
That's enough to scale intelligently. It's also worth checking your ingestion architecture against a general reference model - our breakdown of [what a data pipeline actually is](/data-pipeline/) is a useful sanity check before you lock in day-31 decisions.
---
If you're evaluating consulting partners for data engineering for SaaS companies, use DataEngineeringCompanies.com to compare firms by platform expertise, industry fit, delivery model, and budget. 64 of the 86 firms profiled in the Data Engineering Companies Index name machine learning or AI among their capabilities, so if AI-ready data is part of your roadmap, that's a filter worth applying during shortlisting. Pressure-test candidates with the RFP criteria above, and choose the team that can defend both the architecture and the economics.
---
## Data Engineering for Startups: A 2026 Strategy Guide
Source: https://dataengineeringcompanies.com/insights/data-engineering-for-startups/
Published: 2026-05-12T10:10:10.685115+00:00
Description: Master data engineering for startups in 2026. Learn to assess maturity, choose cost-effective architectures, and build scalable foundations for AI and ML.
**Data engineering for startups means matching pipeline, warehouse, and governance investment to your current stage - not borrowing the architecture of a company ten times your size.** A seed-stage company needs one warehouse, a handful of core sources, and a shared metrics layer. It does not need a sprawling lakehouse roadmap, six governance councils, or a full-time platform team.
I'll be blunt. The expensive mistakes are predictable. Teams scale pipelines before they validate the business questions. They hire the wrong first data engineer. They sign a consultancy that sells a platform migration when the actual need is two reliable pipelines, dbt models, and basic access control. Then they wonder why the stack feels heavy and nobody trusts the dashboards.
The right approach is narrower. Build only the data capability your current stage can use. Choose tools that your team can operate without heroics. Treat vendor selection like capital allocation, because that's what it is.
## How much data infrastructure does a startup need at each stage?
**Data infrastructure needs track funding stage: seed-stage startups need one warehouse and a handful of core sources, Series A needs dbt models and scheduled orchestration, and Series B earns governance, lineage, and access controls that hold up under scrutiny.** Funding stage isn't a perfect proxy, but it maps to what actually changes - team size, reporting pressure, customer complexity, and tolerance for rework.
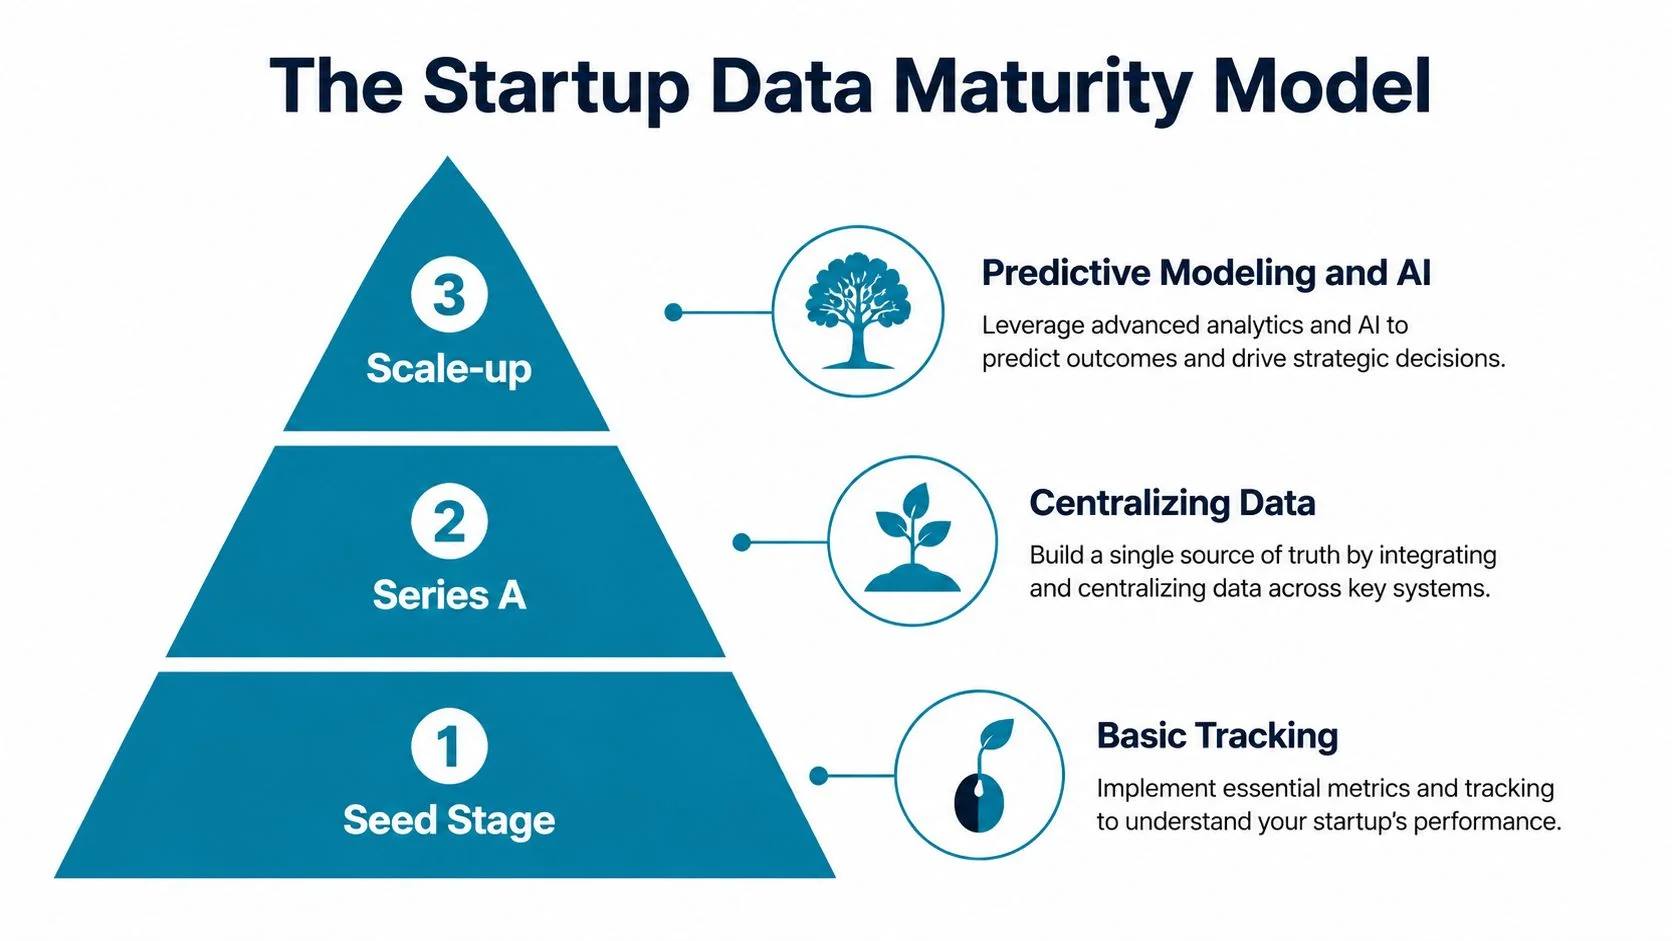
### Seed stage
At seed, your job is simple. Prove demand, understand behavior, and stop debating metrics in Slack.
A structured validation process matters here because startups still die from building the wrong thing. A phased approach helps address the **34% failure rate from lack of product-market fit**, while **22% fail during validation because they scale too early**. When teams skip data quality gates at this stage, they create **40-60% downstream analytics errors**, according to [DesignRush coverage of startup failure benchmarks](https://www.designrush.com/agency/business-consulting/trends/startup-failure-rate-statistics).
Good enough at seed looks like this:
- **One warehouse or queryable core store:** BigQuery, Snowflake, or a lightweight managed pattern on AWS.
- **A few critical sources only:** Billing, product analytics, CRM.
- **One shared metrics layer:** Even if it's just dbt models and documented SQL.
- **A narrow dashboard set:** Revenue, activation, retention, pipeline.
If you're ingesting every event under the sun before you know which product questions matter, you're wasting cash.
> **Practical rule:** If a source doesn't change a product, growth, or revenue decision this quarter, don't prioritize it.
### Series A stage
Series A changes the mandate. You're not proving the market anymore. You're trying to centralize reporting, remove manual joins, and make teams self-sufficient.
Many startups overcorrect at this stage. They jump from spreadsheet chaos to platform maximalism. Don't. What you need is a stable transformation layer, scheduled pipelines, and clear ownership.
Use these questions to gauge maturity:
| Focus area | What leadership needs answered |
|---|---|
| **Growth** | Which channels produce retained users, not just signups |
| **Sales** | Which segments convert fastest and expand cleanly |
| **Product** | Which behaviors predict activation and churn |
| **Finance** | Which metrics match board reporting without manual reconciliation |
At this stage, “good enough” means Airflow or managed orchestration, dbt for transformations, warehouse-level role-based access, and basic data tests on core models.
### Series B and beyond
Now the company earns the right to invest in harder infrastructure. The questions shift from “what happened?” to “what's driving efficiency, risk, and forecast quality?”
You should expect pressure for cleaner lineage, stronger governance, and ML-ready datasets. That still doesn't justify random complexity. It just means the stack must hold up under more users, more domains, and more scrutiny.
A useful self-check:
1. **Do teams share metric definitions?**
2. **Can you trace a board metric back to source data?**
3. **Can a new data source land without breaking downstream models?**
4. **Can engineering explain platform cost drivers in plain English?**
If the answer is no to most of these, you don't need more tools. You need tighter operating discipline.
## What's the minimum viable data stack for a startup?
**The minimum viable data stack is the one your team can operate next month without a specialist babysitting it - not the one that looks impressive in an architecture diagram.** Match the pattern to your team's actual operating capacity, then upgrade only when the workload, not ambition, demands it.
For small teams, hiring mistakes are brutal. Teams with **fewer than 10 engineers face a 3x higher failure risk from bad first data engineering hires**, and **60% of startups hire generalist software engineers internally over specialists**. The same benchmark set also notes that many of Y Combinator's data engineering startups bootstrap in-house before scaling, and some early teams use **$10K pilots** to validate outside help first, as summarized by [Seedtable's data engineering startup analysis](https://www.seedtable.com/best-data-engineering-startups).
### Pattern one for pre-PMF speed
This is the stitched-SaaS stack. It's ugly, fast, and often correct for very early companies.
Typical shape:
- **Ingestion:** Managed connectors
- **Storage:** BigQuery or Snowflake
- **Transformation:** SQL in warehouse, maybe a little dbt later
- **Orchestration:** Native schedules or lightweight managed jobs
- **BI:** One tool, one semantic owner
This pattern works when the business needs visibility fast and the engineering team can't babysit infrastructure.
### Pattern two for a scalable foundation
This is the default recommendation for most Series A startups.
A practical setup looks like this:
| Layer | Recommended approach |
|---|---|
| **Warehouse** | Snowflake for strong managed experience, BigQuery for GCP-native teams |
| **Pipelines** | Airflow or managed orchestration for repeatability |
| **Transformations** | dbt for versioned models and testable logic |
| **Cloud** | AWS, Azure, or GCP based on existing engineering footprint |
| **Documentation** | Inline model docs plus a shared data dictionary |
Pick the cloud that matches your product and team. Don't create cross-cloud complexity because a consultant likes one vendor more than another.
If you want a grounded view of how the modern stack fits together, this guide to the [modern data stack](https://dataengineeringcompanies.com/insights/modern-data-stack/) is worth reviewing before you lock in platform choices.
### Pattern three for the modern core
Databricks starts to make sense in this context. It is not necessary at the seed stage simply because it is fashionable, but rather when you need broader data engineering and ML workflows within a single operating model.
Choose this pattern when:
- **You need mixed workloads:** Analytics, feature pipelines, heavier transformation.
- **You have real platform ownership:** Someone can manage standards, jobs, and spend.
- **Your data mix is widening:** Structured product data plus logs, event streams, or ML artifacts.
> Don't buy Databricks because you expect to need AI later. Buy it when your current workload already justifies the operational model.
### My blunt build-buy-outsource view
Build in-house when data logic is part of product advantage. Buy managed components whenever they remove commodity work. Outsource narrowly, for design, migration, and acceleration, not as a permanent substitute for ownership.
The wrong move is hiring a senior “unicorn” before you know the shape of the problem. The second wrong move is outsourcing the entire stack and learning nothing. A part-time specialist is often the better bridge between those two mistakes - see [fractional data engineering services](/insights/fractional-data-engineering-services/) if your team needs senior judgment without a full-time hire or an open-ended consulting engagement.
## How do you select a data engineering vendor or consultant?
**Screen on delivery shape and handoff quality, not rate cards or reference architectures - ask who owns the dbt models and Airflow DAGs after launch, and what your internal engineer can run independently by project end.** Most startup procurement fails because founders buy reassurance instead of outcomes.
They sit through polished demos, nod at reference architectures, and skip the hard questions about scope control, handoff quality, and operating cost.
That's how startups end up with **30-50% budget overruns** from scope creep and cloud misconfigurations. It's also why **40% of projects are delayed by poor vendor alignment**, and why practical checklists matter if you want to avoid the **25% abandonment rate in early-stage engagements**, based on [Dataforest's summary of Clutch and G2 startup outsourcing benchmarks](https://dataforest.ai/blog/top-data-engineering-companies-for-startups).
### Should you build, buy, or outsource your data engineering?
**Build in-house only for core data models tied to product advantage; buy managed SaaS for commodity ingestion and hosting; outsource to a consultancy for migrations, stack design, and platform bootstrap.** Use a three-way decision instead of pretending every project belongs in-house.
| Criteria | Build In-House | Buy (SaaS/Managed Service) | Outsource (Consultancy) |
|---|---|---|---|
| **Best use case** | Core data models tied to product advantage | Commodity ingestion, hosting, and routine ops | Migrations, stack design, platform bootstrap |
| **Leadership burden** | Highest | Lowest | Medium |
| **Speed to initial value** | Slower | Fastest | Fast if scope is tight |
| **Knowledge retention** | Highest | Low for internals, high for usage | Varies by handoff quality |
| **Cost control** | Strong long term, weak early | Predictable if usage is simple | Risky without milestone discipline |
| **Best for** | Teams with clear ownership and roadmap | Teams optimizing for simplicity | Teams needing expertise they don't yet have |
### What should you ask before you shortlist a vendor?
Of the 86 firms profiled in the Data Engineering Companies Index, 3 are under 50 people and 34 are 50-500 - and hourly rates run $45-$250 (median $100). That spread means rate alone tells you nothing about fit; see [data engineering consulting rates for 2026](/insights/data-engineering-consulting-rates-2026/) for how that range breaks down by firm size and project scope. The best buyers start with delivery shape, minimum project thresholds, and proof the consultancy has implemented the exact stack they're recommending.
Use this checklist in first-round conversations:
- **Architecture fit:** Ask which parts of the proposed stack the vendor would avoid for your current stage.
- **Implementation ownership:** Ask who writes dbt models, who owns Airflow DAGs, and who documents lineage.
- **Cost exposure:** Ask what specifically increases warehouse and orchestration spend after launch.
- **Handoff quality:** Ask what your internal engineer should be able to run independently by project end.
- **Milestone discipline:** Ask for fixed deliverables tied to business outcomes, not just sprint burn.
- **Platform bias:** Ask how many active Snowflake, Databricks, BigQuery, and AWS implementations they maintain.
If you need a stronger screening process, this checklist for [how to evaluate data engineering vendors](https://dataengineeringcompanies.com/insights/data-engineering-vendor-evaluation-criteria/) is a useful companion.
> A consultant who refuses to narrow scope in the first meeting is already telling you how the engagement will go.
### My vendor selection rule
Never hire a firm to “build your data platform.” Hire a firm to deliver a defined operating capability. For example: centralize revenue and product data in Snowflake, implement dbt models for board reporting, train one internal owner, and leave documented runbooks.
That language protects you from architecture theater.
## What should the first 90 days of a startup data project look like?
**Run three 30-day sprints: land the core warehouse and one dashboard in days 1-30, introduce dbt and train your first self-service users in days 31-60, then add quality tests, access controls, and runbooks in days 61-90.** A startup data project should show business value inside the first month, or leadership loses confidence and the work drifts into backlog purgatory.
Keep scope tight. Avoid the big-bang rollout that creates technical debt before anyone gets value.
### Days 1 to 30
Stand up the core warehouse and land the fewest sources that answer the most important questions. For most startups, that means billing, CRM, and product analytics.
Deliver one dashboard that leadership already argues about. Usually revenue, activation, or funnel conversion. Not five dashboards. One.
### Days 31 to 60
Introduce dbt. Move business logic out of ad hoc SQL and into versioned models with tests on critical fields.
Then train your first non-engineering users. Don't wait for perfection. A good self-service motion starts when someone in finance or growth can answer a common question without filing a ticket.
Here's the hiring angle most teams ignore: once the first sprint proves value, you can define the permanent owner role far better. If you're drafting that role after the stack starts taking shape, this guide on [crafting data engineer job roles](https://www.remotely.works/blog/how-do-i-write-an-effective-job-description-for-a-data-engineer-role) helps tighten expectations around ownership, platform work, and collaboration.
### Days 61 to 90
Add the controls that keep the whole thing from collapsing under growth.
Use a lightweight hardening checklist:
1. **Data quality tests** on core dbt models.
2. **Access controls** at warehouse level for finance, product, and exec views.
3. **Documentation** for source freshness, model definitions, and dashboard owners.
4. **Runbooks** for failed pipelines and common support issues.
> The first 90 days are for proving reliability and usefulness, not for collecting every possible data source.
This phased approach is what keeps a startup from scaling noise.
## Does data governance have to slow a startup down?
**No - startups need four lightweight controls, not enterprise process: shared metric definitions, role-based access, dbt tests on critical fields, and a named owner per dashboard.** That's enough to answer the questions that actually cause chaos: why finance counts customers one way and product another, who can see compensation data, and which table anyone should trust.
Most startup teams hate governance because they've only seen the enterprise version - endless approvals, vague ownership, policies nobody reads. That isn't governance. That's theater.
### What do the four controls look like day to day?
Here's each one:
- **Shared definitions:** One documented definition for customer, active user, churn, revenue.
- **Role-based access:** Finance sees payroll. Product doesn't.
- **Data quality checks:** dbt tests on keys, freshness, and accepted values for business-critical models.
- **Owner tags:** Every dashboard and model has a named person responsible for it.
That's enough to eliminate a surprising amount of chaos.
### The anti-bureaucracy operating model
Use governance where mistrust is expensive. Don't wrap every table in process. Your highest-value datasets deserve standards. Your experimental sandbox does not.
A simple split works well:
| Data type | Governance level |
|---|---|
| **Board and finance metrics** | Strict definitions, access control, testing |
| **Operational dashboards** | Shared definitions, moderate testing |
| **Exploration and prototypes** | Minimal controls, expiration expectations |
This keeps speed where speed matters and discipline where mistakes are costly.
For a broader operating checklist, this summary of [8 data governance best practice essentials](https://ziloservices.com/blogs/data-governance-best-practice/) is a useful reference to adapt, not copy wholesale.
### The rule I push with founders
If a metric appears in a board deck, funding memo, or customer-facing SLA, govern it. If it's a scratchpad analysis, don't turn it into a policy artifact.
> Governance should remove recurring arguments. If it adds new ones, you designed it badly.
## When should a startup upgrade its stack for AI?
**Upgrade when the workload outgrows the stack, not when a board member asks about AI - watch for batch loads that are too slow, a warehouse carrying too much transformation logic, or an ML use case with a committed business owner.** AI plans fail for the same reason startup analytics stacks fail: teams chase outcomes before they build the operating substrate.
That's not a philosophical point. **90% of AI and machine learning projects directly depend on resilient data engineering pipelines**, and AI project failure can **exceed 80% without a reliable data foundation**. The same benchmark set notes that **over 80% of startups use cloud-managed data engineering tools** for faster deployment and predictable costs, according to [Folio3's data engineering market and startup benchmark roundup](https://data.folio3.com/blog/data-engineering-stats/).
### What are the concrete triggers to watch for?
Four triggers matter more than the calendar:
- **Batch is too slow:** Product or operations need fresher decisions than scheduled warehouse loads can support.
- **The warehouse is carrying too much logic:** Transformations, feature prep, and analytics all compete for the same operational envelope.
- **Data domains are multiplying:** New product lines, regions, or business units require lineage and ownership standards.
- **ML use cases are real:** Forecasting, personalization, risk scoring, or support automation now have a committed business owner.
That's when more advanced architecture earns its keep.
### What does AI-ready actually mean?
**An AI-ready startup stack isn't defined by a vector database or a flashy orchestration layer - it means you can produce trusted datasets consistently, document where they came from, and reproduce them when models drift or auditors ask hard questions.**
That usually means:
| Capability | Why it matters |
|---|---|
| **Reliable ingestion** | Models fail when source data shifts silently |
| **Versioned transformations** | Training and inference need reproducible logic |
| **Lineage** | Teams must trace predictions back to source data |
| **Access control** | Sensitive data can't leak into model pipelines |
If you're planning the next layer of AI capability, this primer on [building an effective AI stack](https://www.flaex.ai/blog/leverage-artificial-intelligence) is a useful external read because it frames AI as a systems decision, not just a model decision.
### My opinionated recommendation
For most startups, the shortest path to AI value is boring work done well: clean warehouse tables, tested dbt models, disciplined metadata, and cloud-managed services your team can operate.
That is what enables experimentation without wrecking reliability.
## Your Next Three Actions to Build a Data-Driven Startup
Stop researching and make three decisions this week.
### 1. Place your company in the right maturity stage
Use the model above and write down your current stage, your next stage, and the one business question that matters most before the next fundraise or planning cycle.
If you can't name that question, your data roadmap is already too abstract.
### 2. Pick the stack you can run with current ownership
Choose one of the three patterns. Then list the exact owner for warehouse administration, pipeline monitoring, dbt review, and dashboard definitions.
If those owners don't exist, don't pretend you have an in-house strategy. You have a procurement decision.
### 3. Run a disciplined vendor screen before you buy help
If you need outside support, use a shortlist process with milestone-based scope, handoff requirements, and explicit questions about platform bias, documentation, and operating cost. Then compare firms with actual data instead of polished pitch decks.
If you'd rather skip the manual shortlist, the [get matched](/get-matched/) tool takes your stack, budget, and stage and returns a short list of firms from the 86-firm index that actually fit, instead of another round of cold demos.
---
The startups that win with data engineering aren't the ones with the fanciest architecture. They're the ones that build only what the business can absorb, insist on operational ownership, and refuse to let vendors define the roadmap for them.
---
## Top Data Engineering Managed Services for 2026
Source: https://dataengineeringcompanies.com/insights/data-engineering-managed-services/
Published: 2026-05-07T08:44:05.547676+00:00
Description: Compare leading data engineering managed services. Find models, pricing, & vendors. Use our RFP checklist to select your ideal Snowflake or Databricks partner.
Most CTOs buy data engineering managed services for speed. They should buy them for **control over cost, execution, and operational risk**.
Most new data engineering work lands in the cloud now, and vendors of every size are chasing that demand. Team size varies widely across the 86 firms profiled in the [Data Engineering Companies Index](/data-engineering-consulting-firms/) - 3 run under 50 people, 34 sit in the 50-500 range, and 49 run 500 or more - which is exactly why the engagement model matters more than the logo on the proposal. Vendor interest tells you demand exists. It doesn't tell you which model protects your platform, your budget, or your internal advantage.
That's the actual procurement problem. Most firms can pitch Snowflake, Databricks, dbt, Airflow, AWS, Azure, and BigQuery. Fewer can explain how they'll prevent runaway change requests, preserve institutional knowledge, and hand you a platform your team can still govern a year later.
If you're selecting a partner for an enterprise data platform initiative, don't start with brand logos. Start with operating model, contractual guardrails, and technical proof.
## What are the different data engineering managed service models?
Data engineering managed services come in three models: **fully managed**, where the vendor owns operations end to end; **co-managed**, where you keep architectural authority and the vendor executes agreed layers; and **staff augmentation**, where you rent specialist labor you direct yourself. Pick the wrong one and you either overpay for work your team could handle, or under-buy and end up with a vendor who can't own outcomes.
### Fully managed
A **fully managed** model means the provider owns platform operations, pipeline orchestration, monitoring, upgrades, incident response, and usually a chunk of roadmap delivery. This is the right model when your internal team is thin, your estate is fragmented, or you need fast stabilization after a failed migration.
It also gives you the cleanest budget story if the contract is written properly. One provider owns delivery. One provider owns support. One provider can't blame your staff for every miss.
The downside is obvious. If the vendor owns architecture, orchestration, and runbooks without disciplined documentation and transition obligations, your data platform becomes a rented asset.
> **Practical rule:** Use fully managed only if the contract includes mandatory documentation, named service boundaries, knowledge transfer, and exit support.
### Co-managed
A **co-managed** structure is usually the best fit for enterprise data engineering. Your team keeps architectural authority, platform standards, access policy, and business logic ownership. The vendor handles agreed layers such as Airflow operations, dbt development capacity, Snowflake performance tuning, Databricks jobs, or cloud infrastructure automation.
This model preserves internal judgment. It also keeps your staff close enough to the platform to retain context on lineage, data contracts, and domain logic.
It's harder to govern than fully managed because split ownership creates gray zones. If a pipeline fails, the vendor can point at source quality, while your team points at orchestration. Fix that in the SOW. Define ownership by layer, tool, and incident type.
### Staff augmentation
**Staff augmentation** is not a managed service. It's rented labor. That distinction matters.
Use augmentation when you know the architecture, already have engineering management in place, and need targeted skills such as Spark optimization, dbt refactoring, or BigQuery migration support. Don't use it when you need a partner to own service levels or platform outcomes. Augmented engineers follow your lead. If your internal operating model is weak, augmentation amplifies the weakness.
### Which model fits your situation
| Model | Best when | Main strength | Main risk |
|---|---|---|---|
| Fully managed | Team lacks bandwidth or operational maturity | Clear accountability | Vendor dependency |
| Co-managed | You want outside execution but keep strategic control | Balance of control and speed | Blurred ownership |
| Staff augmentation | You need specialist capacity inside an existing program | Flexibility | No outcome ownership |
Use this decision lens:
- **Choose fully managed** if your priority is service continuity, migration recovery, or getting a cloud data platform under control fast.
- **Choose co-managed** if you want the vendor to accelerate delivery while your architects keep standards, platform direction, and governance.
- **Choose staff augmentation** if your roadmap is clear and you're filling specific gaps in Snowflake, Databricks, dbt, Airflow, or cloud-native infrastructure.
The vendors that matter will tell you where their model doesn't fit. The weak ones call everything "flexible."
## What core capabilities should a data engineering managed services partner deliver?
A capable partner has to execute five things well: ingestion design that matches business reality, ETL/ELT your own team can maintain, data modeling that serves the business, governance built into delivery from day one, and observability that catches more than failed jobs. A polished proposal means nothing if the partner can't handle the mechanics underneath it.
AWS's own prescriptive guidance on data engineering frames managed orchestration services like Amazon MWAA as a way to shift routine pipeline operations off your team, so engineers spend less time managing infrastructure and more time on the pipelines themselves. See [AWS's data engineering perspective](https://docs.aws.amazon.com/prescriptive-guidance/latest/aws-caf-platform-perspective/data-eng.html) for the underlying pattern. That benefit only shows up when the provider is actually strong in the basics below.
### Ingestion that matches business reality
A serious partner doesn't just say "batch and streaming." They map ingestion patterns to business criticality, source volatility, and failure handling.
For example, SAP extracts, SaaS APIs, CDC pipelines, event streams, and file drops should not all be governed the same way. Ask how they handle schema drift, replay, late-arriving data, and source-side throttling. If they can't explain the difference between operational ingestion design and analytics ingestion design, move on.
What to verify:
- **Source coverage:** They should name the systems they've integrated, not just say "many connectors."
- **Recovery design:** Ask for their retry, backfill, and replay approach.
- **Platform fit:** On AWS, they should speak comfortably about S3, Glue, MWAA, and orchestration boundaries.
### ETL and ELT that your team can maintain
Good ETL and ELT work is boring in the right way. It's modular, version-controlled, testable, and easy to hand over. In Snowflake and BigQuery estates, that usually means clean ELT patterns and disciplined SQL transformations. In Databricks estates, it often means Spark jobs where they're justified, not because the vendor likes PySpark.
If the provider wants to bury core business logic inside proprietary accelerators or opaque notebooks, push back. Your future operating cost lives inside those choices.
> Ask every vendor to walk through one representative pipeline from ingestion to consumption, including code ownership, testing, rollback, and handoff.
### Data modeling that serves the business
A vendor should be able to defend when to use dimensional models, when to use wide tables, and when to expose curated domain layers for self-service. If they answer every question with "lakehouse," you're listening to product marketing, not architecture.
Look for clarity on semantic consistency. Revenue, customer, order, claim, policy, account - these aren't just columns. They're business definitions with downstream political consequences.
### Governance built into delivery
Governance isn't a later workstream. It belongs in access design, lineage, PII handling, data contracts, and release controls from the start.
You also want operational observability, not just platform uptime dashboards. For governance work specifically, this guide to [data observability](https://www.trackingplan.com/blog/what-is-data-observability) treats freshness, schema drift, and trust as engineering concerns worth catching upstream, not reporting concerns you notice after the fact.
What to verify in governance reviews:
- **Access model:** Role design across engineers, analysts, and service accounts
- **Lineage discipline:** How they track dependencies across ingestion, transformation, and reporting
- **Policy enforcement:** How masking, retention, and audit expectations are implemented in pipelines
### Observability that goes beyond failed jobs
Average vendors alert on failed runs. Strong vendors detect silent data failures, freshness issues, quality regressions, and cost anomalies.
That means they should instrument checks for null spikes, duplicate loads, schema changes, unexpected volume shifts, and warehouse or cluster consumption jumps. If they don't monitor spend behavior on Snowflake virtual warehouses, Databricks compute, or BigQuery query patterns, they're not managing the platform. They're babysitting it.
Here's the short test. Ask the vendor what happens when a pipeline technically succeeds but loads bad data. Their answer will tell you whether they operate a data service or just maintain jobs.
## What are the real benefits and risks of data engineering managed services?
Managed services pay off when they remove bottlenecks your internal team can't clear quickly: compressed delivery time, specialist coverage without a bigger bench, and room for your staff to focus on domain logic instead of firefighting. The risks are contractual and organizational - vendor lock-in, cost sprawl, and a team that quietly becomes an approval layer instead of a technical owner.
Data engineering is already central to enterprise operations. 77 percent of organizations now consider it critical or very important, rising to 92 percent in large enterprises, while 56 percent use data engineering capabilities constantly or frequently, according to [Matillion's data engineering trends analysis](https://www.matillion.com/blog/data-engineering-trends). The strategic argument is settled. The procurement argument, on cost and risk, is not.
Recruiting takes time. Platform mistakes are expensive. Cloud migrations stall when nobody owns the ugly middle between architecture diagrams and operating pipelines - that's the gap managed services are meant to close.
### The upside worth paying for
The best managed service engagements do three things well.
- **They compress delivery time.** A capable partner brings reference architecture, implementation muscle, and people who've already handled Snowflake migrations, Databricks workspace design, dbt project structure, or Airflow orchestration patterns.
- **They give you specialist coverage without building a full bench.** That matters when you need one strong platform architect, one pipeline lead, and one governance-heavy engineer, not a permanent team in every niche.
- **They let your internal team focus on product and domain logic.** Your staff should define business rules, domain ownership, and platform standards. They shouldn't spend their week firefighting brittle infrastructure.
### The risks vendors downplay
The genuine hazards are contractual and organizational.
**Vendor lock-in** starts when the provider bakes critical transformation logic into proprietary frameworks, controls your deployment pipelines, and withholds the runbooks your team needs to operate independently.
**Cost sprawl** starts when the MSA looks simple but the SOW leaves room for overages, after-hours fees, premium support charges, and endless "out of scope" change requests.
**Capability erosion** happens when your internal team becomes an approval layer instead of a technical owner. Six months later, nobody on your side understands the DAGs, job dependencies, or warehouse tuning choices.
> If the vendor owns every hard decision, your team won't be stronger at the end of the engagement. It will be weaker.
### Guardrails that change the outcome
Insist on these from day one:
- **Architecture ownership stays with you.** Even in a managed model, your team approves standards, core platform choices, and major design changes.
- **Documentation is a deliverable, not a courtesy.** Runbooks, lineage artifacts, data model decisions, and environment diagrams belong in the contract.
- **Exit support is priced and defined up front.** If transition terms are vague, dependency is the business model.
- **Knowledge transfer is scheduled, not optional.** Monthly walkthroughs beat last-minute handovers.
Managed services work. Blind dependency doesn't.
## How are data engineering managed services priced, and where do the hidden costs hide?
Most vendor quotes are designed to look simple. The actual cost sits in exclusions, assumptions, and cloud consumption nobody wants to discuss in the first meeting. Across the 86 firms in the [Data Engineering Companies Index](/insights/data-engineering-consulting-rates-2026/), hourly rates run $45 to $250, with a median around $100 - a wide enough band that the rate on a card tells you almost nothing about scope, seniority, or who actually owns the outcome.
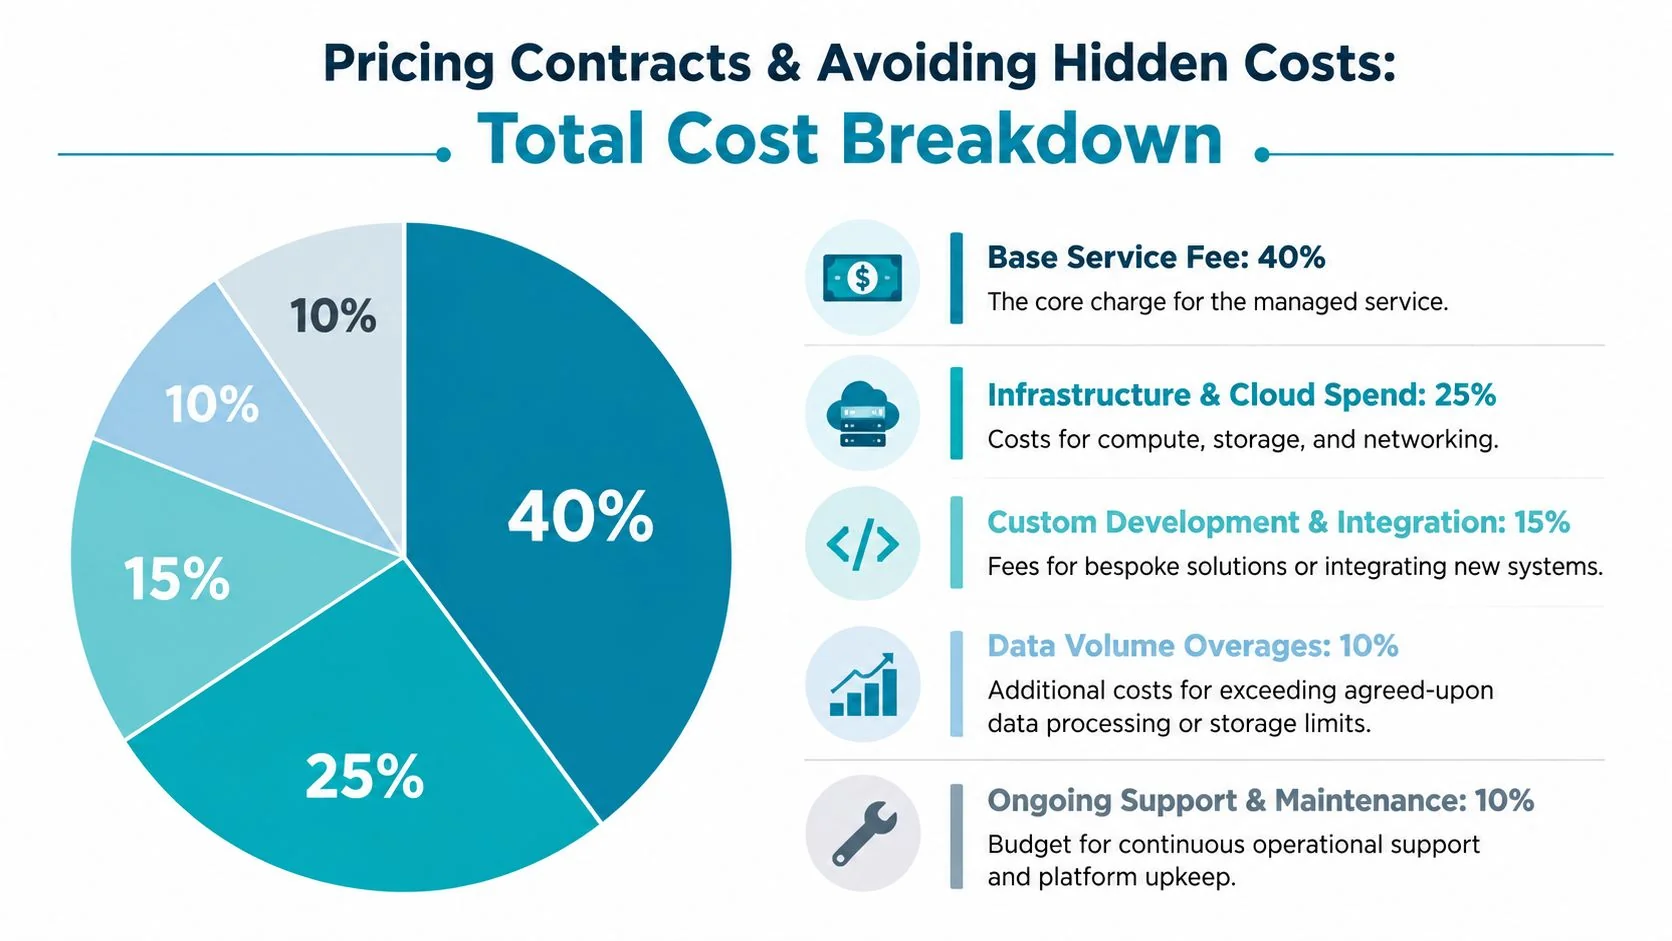
### Price the engagement, not the line item
You're not buying "managed data engineering." You're buying some combination of platform operations, development capacity, support response, governance work, and cloud cost management.
A vendor with a lower hourly rate can still be more expensive if they require larger team minimums, bundle senior review inefficiently, or trigger constant change requests. That's why rate cards alone are weak procurement tools.
### The three pricing models you'll see
| Pricing model | Good for | Procurement risk |
|---|---|---|
| Fixed retainer | Stable support, recurring operations | Hidden exclusions and low flexibility |
| Time and materials | Ambiguous discovery or changing scope | Weak budget predictability |
| Consumption-linked | Elastic workloads and cloud-heavy estates | Harder attribution of overruns |
The right choice depends on maturity.
A stable Snowflake or BigQuery platform with known support boundaries fits a retainer. A messy modernization effort involving Airflow, dbt, cloud infrastructure, and migration unknowns usually needs time and materials during discovery, then a controlled retainer or milestone model later. Consumption-linked contracts need especially hard governance because the vendor has little natural incentive to reduce billable usage unless the contract forces it.
### Hidden cost traps to surface in the RFP
Use direct questions. Don't ask whether pricing is transparent. Ask where invoices increase.
- **Change request fees:** What triggers them, who approves them, and how fast can they stack up?
- **Minimum commitments:** Is there a monthly floor regardless of actual ticket or sprint volume?
- **After-hours support:** What counts as standard coverage versus premium coverage?
- **Environment charges:** Are non-production support, testing, and release management included?
- **Cloud accountability:** Who owns warehouse tuning, cluster right-sizing, and storage lifecycle discipline?
> **Commercial test:** If a vendor cannot model your total monthly cost under low, expected, and high workload scenarios, they are not ready for enterprise procurement.
### Contract clauses worth insisting on
Your MSA and SOW should include:
- **Named roles and blended rates**
- **A cap or approval gate for overages**
- **Defined inclusions for support, monitoring, and incident response**
- **Clear ownership of code, documentation, and configuration artifacts**
- **Exit assistance terms with timelines and deliverables**
- **A cloud cost governance obligation, not just a usage disclaimer**
The biggest mistake is treating data engineering managed services like generic IT support. They aren't. The architecture evolves while the meter is running.
## How do you build a vendor evaluation scorecard for data engineering managed services?
If your selection process depends on demos and chemistry, expect expensive surprises later. Use a weighted scorecard, force evidence into the room, and set the passing bar before the first vendor presents.
### Use weighted scoring, not gut feel
Below is a practical scorecard you can use in an RFP or final-round vendor review.
| Category (Weight) | Evaluation Criterion | What to Look For | Score (1-5) |
|---|---|---|---|
| Technical expertise (30) | Platform depth | Proven delivery in Snowflake, Databricks, dbt, Airflow, AWS, Azure, or BigQuery relevant to your stack | |
| Technical expertise (30) | Architecture quality | Clear reference architecture, environment separation, orchestration design, and recovery patterns | |
| Delivery methodology (20) | Execution discipline | Sprint cadence, release process, testing standards, incident handling, and documentation routines | |
| Governance and security (20) | Control maturity | Access model, lineage, masking, retention controls, and auditability | |
| Commercial viability (15) | Pricing transparency | Clear rates, service boundaries, overage rules, and support terms | |
| Commercial viability (15) | Partnership durability | Named team continuity, escalation path, transition support, and knowledge transfer plan | |
If you want a ready-made procurement artifact, this [data engineering vendor scorecard](/insights/data-engineering-vendor-evaluation-criteria/) gives a structured version you can adapt.
### How to score without fooling yourself
Don't accept self-reported maturity at face value. Require proof.
- **For technical depth:** Ask for one architecture review with the delivery lead, not just sales.
- **For delivery quality:** Request sample runbooks, backlog examples, and testing conventions with sensitive details removed.
- **For governance:** Ask how they track lineage, role design, and policy enforcement inside actual projects.
- **For commercial fit:** Make them walk through a mock invoice against your expected scope.
### Questions that expose weak vendors
Use pointed questions in final-stage diligence.
1. Who owns business logic when source systems change unexpectedly?
2. How do you separate urgent incident work from roadmap delivery so both don't collapse?
3. What artifacts do you deliver monthly besides tickets closed?
4. How do you transition the service to an internal team or replacement partner?
5. Which parts of the stack depend on your proprietary assets?
> Score low if the vendor answers with process language but no artifacts, no examples, and no named owners.
### Minimum passing standard
Set a floor before review starts. For enterprise work, I'd reject any vendor that scores poorly in governance or commercial transparency, even if they're technically strong. You can coach a good engineering team into your workflow. You can't fix a contract that rewards opacity.
## What are the red flags in Snowflake, Databricks, and AI vendor pitches?
The fastest way to waste budget is to hire a vendor that speaks fluently in platform marketing and vaguely in implementation detail. Vendors increasingly reach for "mesh," "AI-ready," and "lakehouse" language to cover for thin delivery discipline - the terms sound current, but they don't substitute for evidence of who owns which domain, how governance actually works, and what breaks once a team scales past its first pilot.
### Snowflake red flags
A weak Snowflake partner usually reveals itself in one of three ways:
- **They ignore cost governance.** If they don't talk about warehouse sizing, query discipline, and workload isolation, they'll spend your budget casually.
- **They overuse proprietary features without portability logic.** That increases lock-in and complicates future platform choices.
- **They treat dbt as optional structure.** For many teams, maintainable transformation logic depends on disciplined model organization and testing.
### Databricks red flags
Databricks projects fail when vendors oversell "unified analytics" and underspecify operations.
Watch for these signals:
- **No clear workspace and environment strategy**
- **Weak story on job orchestration and dependency management**
- **No serious MLOps plan for feature pipelines, model inputs, or handoff between data engineering and ML teams**
If they can demo notebooks but not explain production controls, they're not ready.
### AI project red flags
The most dangerous phrase in vendor meetings is "AI readiness." It usually means nothing specific.
Reject vendors that promise AI outcomes without a concrete plan for data quality, feature engineering, lineage, access control, and curated training datasets. Also reject any partner pushing data mesh or federated ownership models without evidence they can support domain accountability and governance in your operating environment.
> AI programs don't fail because the model was too small. They fail because the underlying data platform was unmanaged, undocumented, and politically ownerless.
## What should the first 90 days of a managed services engagement look like?
The first 90 days break into four phases: lock internal alignment in weeks one and two, run a disciplined vendor shortlist through week six, do technical and commercial diligence through week ten, and onboard deliberately in the final two weeks. Skipping straight to onboarding is how avoidable disputes end up in month four.
Weeks one and two, lock internal alignment. Name an executive owner, a technical owner, and a procurement owner. Define target platforms, essential controls, migration scope, support boundaries, and what stays in-house.
Weeks three through six, run a disciplined shortlist. Use the scorecard. Force every vendor to respond to the same architecture, governance, pricing, and transition questions. Reject any proposal that hides assumptions or turns documentation into optional work.
Weeks seven through ten, do technical and commercial diligence in parallel. Meet the actual delivery lead. Review a sample runbook. Review invoice logic. Negotiate service boundaries, overage approvals, exit support, and code ownership before legal redlines stall progress.
Weeks eleven and twelve, onboard deliberately. Set architecture approval cadence, ticket severity definitions, monthly operating reviews, and knowledge transfer sessions from the start. Don't wait until the platform is live to discover who owns lineage, cloud spend, or failed releases.
---
Start with the operating model. Then force proof on technical delivery. Then close the commercial traps. That sequence gives you a partner you can manage, not just a vendor you can hire.
---
## Data Engineering Partner Selection: The 2026 Five-Stage Framework
Source: https://dataengineeringcompanies.com/insights/data-engineering-partner-selection/
Published: 2026-05-15T08:00:00.000Z
Description: A 2026 framework for data engineering partner selection: pre-RFP signal scan, sourcing, evaluation, paid pilot, contract, and 90-day handover.
Most selection processes fail because they treat vendor selection as a procurement exercise. It isn't. It's an intelligence-gathering exercise that begins weeks before a single vendor knows your name, and it ends 90 days after signature - not at contract close.
The five-stage framework in this article organises the entire journey: from the moment a buying committee starts forming opinions about the vendor market, through shortlisting, evidence-based evaluation, negotiation, and into the first quarter of delivery. Each stage has a distinct deliverable, a clear owner, and a hard exit gate.
The market has more variance than most committees expect. Of the [86 firms profiled in the Data Engineering Companies Index](/data-engineering-consulting-firms/), only 3 run under 50 people and 49 have 500 or more - team size alone is a legitimate first-pass filter, which is exactly why Stage 0 below treats it as a signal worth checking before a single call is scheduled.
The other articles in this cluster cover individual pieces in depth: the [8-factor scorecard mechanics](/insights/data-engineering-vendor-evaluation-criteria/), the [internal RFP process](/data-engineering-rfp-checklist/), [pilot and proof-of-concept scoping](/insights/data-engineering-due-diligence-checklist/), and [post-signature governance](/insights/data-engineering-managed-services/). This article is the map that shows where each piece fits.
---
## Why partner selection breaks before the RFP is written
In 2025, a buying committee at a mid-market fintech spent three weeks crafting a detailed RFP. They sent it to six vendors. Two of the better-qualified firms had already been filtered out of consideration - not by the committee, but by the committee's AI research workflow. A procurement analyst had asked Perplexity to surface "top Databricks partners with financial services experience under 200 people." Neither firm appeared in the results because their methodology pages were thin, their dbt reference library was empty, and their only public case study named a client that no longer existed.
This is the 2026 reality. Buying-side AI copilots - ChatGPT Research, Perplexity, Gemini, Claude - now assemble candidate sets from public signals before any formal sourcing step begins. The shortlist, functionally, is decided during the committee's orientation phase, not during RFP response review. Vendors with weak external signal environments get filtered out without ever seeing the deal.
What counts as a "signal" in this context? Peer reviews on G2 and Gartner Peer Insights, analyst mentions, partner tier pages on [Snowflake](https://www.snowflake.com/en/partners/) and [Databricks](https://www.databricks.com/partners), GitHub repos with documented usage patterns, methodology pages describing *how* the firm approaches ingestion and transformation, and third-party references like Reddit threads on r/dataengineering. An AI copilot doing vendor research synthesises all of this in seconds.
Stage 0 of the five-stage framework addresses this directly. The other four stages address what most procurement guides already describe - they just describe it with less precision and no connection to how the 2026 buyer actually behaves.
---
## What is the 2026 five-stage data engineering partner selection framework?
The framework covers six discrete stages (Stage 0 through Stage 5). Stage 0 is the pre-RFP signal scan - the phase most selection guides skip entirely. Stages 1-4 are the structured selection process. Stage 5 is the first 90 days, which determines whether the engagement actually delivers.
Here is the full framework at a glance:
| Stage | Label | Core Deliverable | Primary Owner | Typical Duration |
|---|---|---|---|---|
| Stage 0 | Pre-RFP Signal Scan | Candidate set + signal gap analysis | Head of Data / Procurement | 1-2 weeks |
| Stage 1 | Internal Alignment | Non-negotiables doc + success metrics | Head of Data + Finance + Legal | 2 weeks |
| Stage 2 | Sourcing & Shortlist | 4-6 vendor shortlist with rationale | Head of Data + Procurement | 1-2 weeks |
| Stage 3 | Evidence-Based Evaluation | Scored proposals + pilot results | Evaluation committee | 4-6 weeks |
| Stage 4 | Negotiation | Signed MSA + SOW with six key clauses | Procurement + Legal | 1-2 weeks |
| Stage 5 | First 90 Days | Onboarded team + first milestone delivered | Project sponsor + vendor PM | 12 weeks |
---
## Stage 0: What is the pre-RFP signal scan?
The pre-RFP signal scan is a structured audit of public signals - reviews, partner-tier pages, GitHub activity, and AI-copilot query results - run before any vendor is contacted, so the committee understands the vendor market before vendor decks start landing in inboxes.
Every buying committee already does an informal version of this: an analyst asks their AI assistant, checks a Slack community, reads a few Reddit threads. What they find in those first few hours shapes the candidate set for everything that follows, whether or not anyone treats it as a formal step. Running it deliberately also reveals which vendors have invested in public credibility and which are relying entirely on direct sales.
Eight sources matter most:
| Signal Source | What It Tells You | Cost to Verify |
|---|---|---|
| G2 / Gartner Peer Insights reviews | Client sentiment, delivery track record, support quality | Free; 30 min |
| Snowflake / Databricks partner tier pages | Verified certifications, deal count, specialisation tags | Free; 15 min per vendor |
| GitHub public repos | Real methodology, tool preferences, documentation discipline | Free; 1 hr |
| dbt Hub / dbt Slack | Package contributions, community reputation | Free; 30 min |
| LinkedIn team profiles | Actual seniority of named staff; turnover signals | Free; 1 hr |
| Reddit r/dataengineering | Unprompted vendor mentions (positive and negative) | Free; 1 hr |
| Published methodology pages (vendor site) | Depth of technical thinking vs. marketing language | Free; 30 min per vendor |
| AI copilot query results | What shortlist an LLM assembles for your use case | Free; 15 min |
The last row deserves emphasis. Run the query yourself: ask Claude, Perplexity, or ChatGPT something like "Which data engineering consultancies have deep Databricks experience in regulated financial services, under 300 staff?" If a vendor you're considering doesn't appear in those results, ask yourself why. Buyers who use AI copilots will reach the same conclusion about that vendor.
This scan takes 8-12 hours total. Output: a candidate pool of 10-15 firms, annotated with public-signal quality ratings. That pool feeds Stage 2 shortlisting.
---
## Stage 1: What has to be locked internally before vendor 1 is contacted?
Fifteen non-negotiables need to be written down and signed off before any vendor interaction begins - constraints firm enough that a vendor failing any one of them is automatically disqualified, regardless of price or reputation.
The [RFP process best-practices guide](/data-engineering-rfp-checklist/) covers how to assemble a cross-functional evaluation team and run structured stakeholder interviews; this article won't repeat that. What follows is the specific list:
15 Items to Lock Before Contacting Any Vendor
1. Data residency requirements - which countries or cloud regions data can and cannot touch
2. Compliance obligations - HIPAA, SOC 2 Type II, PCI-DSS, FCA, GDPR, or sector-specific frameworks
3. EU AI Act readiness requirement - if the engagement involves AI/ML pipelines, is an Article 13 transparency obligation or high-risk system classification in scope?
4. Target platform decision - Snowflake, Databricks, BigQuery, Redshift, or undecided (and if undecided, who owns that decision)
5. Integration constraints - which source systems must be supported on day one vs. deferred
6. Staffing model preference - onshore, nearshore, offshore, or hybrid; any geographies excluded
7. Engagement model preference - T&M, fixed-price, outcome-based, or hybrid
8. Budget envelope - total approved spend including contingency; any phased release conditions
9. Internal team involvement - will the vendor work alongside internal engineers or own delivery end-to-end?
10. IP ownership requirements - who owns bespoke code, models, and documentation produced during the engagement
11. Success metrics - specific, measurable outcomes the engagement must deliver (pipeline SLA, query latency target, data quality score)
12. Timeline hard constraints - regulatory deadlines, board commitments, product launches that define the outer boundary
13. Key-personnel requirements - whether the buying committee requires named individuals to be contractually committed to the engagement
14. Off-ramp conditions - what triggers would cause the organisation to terminate early, and what transition assistance is expected
15. Internal decision authority - who has final sign-off, and whether procurement or legal has veto power over commercial terms
On the EU AI Act: obligations for high-risk AI systems under [Regulation (EU) 2024/1689](https://artificialintelligenceact.eu/) start applying in August 2026, and penalties scale by severity, up to €35 million or 7% of global annual turnover for the most serious violations. Any data engineering engagement that feeds an ML model used in credit scoring, HR decisions, critical infrastructure, or medical triage is potentially in scope. A vendor that doesn't raise this proactively in a regulated-industry deal is a red flag.
Link this non-negotiables document to the [evaluation criteria](/insights/data-engineering-vendor-evaluation-criteria/) scorecard before Stage 2 begins, so shortlisting and scoring both run against the same constraints.
---
## Stage 2: Sourcing & shortlist - who actually matters?
The candidate pool from Stage 0 typically contains 10-15 firms. The shortlist for Stage 3 evaluation should contain exactly 4-6.
Fewer than four vendors and the committee has no genuine comparison. More than six and the evaluation process becomes unmanageable - proposal review alone consumes 40+ hours, discovery calls fill two calendar weeks, and scoring becomes inconsistent because reviewers burn out. The 4-6 number is not arbitrary. It's where evidence quality and time investment balance.
The first cut is vendor type. This decision is consequential enough that it deserves its own section (see below: "Pure data engineering vendor or MLOps partner?"), but the shortlisting logic looks like this:
```
Does your 18-month roadmap include production ML workloads?
├── Yes → Does it include model retraining, drift monitoring, or
│ feature stores?
│ ├── Yes → MLOps-aware partner required. Filter out
│ │ pure-DE vendors that cannot articulate
│ │ model lifecycle management.
│ └── No → Data engineering vendor with basic ML
│ exposure is sufficient.
└── No → Pure data engineering vendor is fine. Platform
specialism matters more than ML breadth.
├── Committed to Snowflake → Snowflake Elite/Premier
│ partner with SnowPro-certified lead
├── Committed to Databricks → Databricks SI partner
│ with Solution Architect certification
└── Platform undecided → Multi-cloud generalist with
documented comparative experience
```
After filtering by type, apply a short evidence screen to each remaining candidate:
1. Does the firm have at least three case studies in your industry vertical, with verifiable client names?
2. Does the partner tier page confirm active certification (not lapsed) for your target platform?
3. Do the LinkedIn profiles of named senior staff match what the firm claims about seniority?
4. Has the firm responded to an [RFP mistakes](/data-engineering-rfp-checklist/) situation before - i.e., do they have references from engagements that started late or were rescued?
5. Is their rate range publicly known or confirmed by peers to fall within the budget envelope set in Stage 1?
Firms that fail two or more of these checks drop off the list. The remainder form the shortlist for Stage 3.
---
## Stage 3: What does evidence-based evaluation actually involve?
Stage 3 stacks four mechanisms in sequence - the RFP, the scorecard, discovery calls, and the paid pilot - and each one filters candidates further before a contract is drafted.
The [8-factor scorecard methodology](/insights/data-engineering-vendor-evaluation-criteria/) is documented in full elsewhere. Apply it as-is. What this article covers is what's new for 2026: four probes that should be added to every technical evaluation, regardless of vendor type.
**The Cortex AI vs. Mosaic AI literacy probe.** Ask any data engineering vendor to explain the difference between [Snowflake Cortex AI](https://www.snowflake.com/en/product/features/cortex/) and [Databricks Mosaic AI](https://www.databricks.com/product/machine-learning). A generalist vendor with genuine platform depth can give a specific answer in under three minutes: Cortex sits inside Snowflake's serverless layer and is optimised for SQL-first teams using pre-built LLM functions without leaving the Snowflake governance perimeter; Mosaic is integrated into the Databricks Lakehouse and targets teams that need end-to-end ML lifecycle management with MLflow. A vendor that can't make this distinction clearly has not worked at depth with either platform in the past 12 months.
**The EU AI Act preparedness probe.** Ask: "If this engagement includes ML pipelines that feed a credit-decisioning or HR-screening model, what does your standard delivery approach include to address EU AI Act Article 13 transparency requirements?" A prepared vendor will reference documentation standards, logging requirements, and human oversight checkpoints. An unprepared vendor will give a vague answer about "governance frameworks." That's a meaningful signal.
**The AI copilot integration probe.** Ask how the vendor's delivery team uses AI coding tools (GitHub Copilot, Cursor, Claude) on client engagements. Specifically: what's their policy on AI-generated code review, and how do they handle proprietary data exposure in copilot prompts? Vendors with no policy on this are operating without guardrails on your IP.
**The 4-week paid pilot rubric.** Every final-round vendor should run a paid, time-boxed pilot before contract signature. The full scoping approach is in the [due diligence checklist](/insights/data-engineering-due-diligence-checklist/). The brief version: scope it to one real problem (not a toy dataset), set four weekly milestone checkpoints, and evaluate the vendor on delivery quality, communication clarity, and their response to a deliberate mid-pilot scope question. How a vendor handles ambiguity in week two tells you more than their proposal did.
---
## Stage 4: Which contract clauses move project economics more than headline rate?
Most procurement teams focus negotiation energy on the day rate. That's where the smallest lever is. The six clauses below move project economics - total cost, project continuity, and risk allocation - far more than a 5% rate reduction.
**Change-order rate cap.** Data engineering projects generate change orders. Every undocumented assumption in the SOW becomes a change-order opportunity. Negotiate a cap: change orders cannot exceed 15-20% of the original SOW value in aggregate without triggering a formal re-scoping review requiring the project sponsor's sign-off. Without this clause, scope creep is unbounded.
**Key-personnel guarantee.** The people who sold the engagement are rarely the people who deliver it. Name the specific senior engineers and architect(s) committed to the project, and require written notice plus a 30-day transition period if any named individual is removed. This clause has real teeth. Include a rate credit mechanism if the firm substitutes a named person without the required notice.
**IP ownership.** Bespoke code, data models, pipeline configurations, and documentation produced during the engagement should be owned by the client, not licensed. Most vendor MSAs default to a broad license grant rather than full assignment. Push for outright assignment of all custom work product. Reusable components (internal frameworks, accelerators) can remain vendor-owned - but they should be listed explicitly in the agreement.
**Milestone payments with 10% holdback.** Break the total engagement value into milestone payments tied to agreed deliverables - not calendar dates. Hold back 10% of each milestone until the client's internal team signs off on the deliverable's quality. This single clause shifts quality accountability from the vendor's definition to the client's. It doesn't guarantee good work, but it makes disputes about "done" much rarer.
**Off-ramp and transition assistance.** Define exit explicitly. If the engagement terminates early - for any reason, including convenience - the vendor must provide a handover pack: current-state architecture diagrams, runbooks, access credential transfer, and a two-week knowledge transfer session. Without this clause, early termination leaves the client holding a half-finished project with no documentation.
**SLA penalties with teeth.** SLAs without financial consequences are aspirational. Negotiate a penalty structure: for a production pipeline, a per-hour cost for SLA breaches beyond a defined threshold. Cap vendor liability at a meaningful number (typically 12 months of engagement fees for gross negligence; lower for standard breaches), but make the penalty schedule real enough that the vendor has skin in the game.
Every one of these clauses is a rate conversation as much as a legal one; the [current consulting rate ranges](/insights/data-engineering-consulting-rates-2026/) are the reference point for judging whether a proposed cap, holdback, or penalty schedule is reasonable for the engagement size.
---
## Stage 5: Why do most engagements quietly fail in the first 90 days?
Contract signed. Kick-off scheduled. Now the real work starts - and a significant share of data engineering engagements quietly begin to fail in weeks 2-6, long before any status report reflects it.
Three patterns cause most early failures.
**Dual backlog.** The vendor team starts their own sprint board. The internal team has their own Jira. Nobody agrees on what "done" looks like for the first sprint. Fix this before kick-off: one backlog, one definition of done, one sprint review. The vendor works in the client's tooling or the tooling is formally agreed before day one. This is the same governance discipline covered in [managed data engineering services](/insights/data-engineering-managed-services/), applied from day one of a new engagement rather than after a failure forces the issue.
**Senior absence after week two.** The architect who ran the discovery calls attends the kick-off, then disappears into a different account. The team doing the actual work is junior. Address this with the key-personnel clause from Stage 4 and by scheduling a monthly senior-architect review checkpoint in the engagement governance calendar - not as an option, but as a contractual cadence.
**No kill-switch criteria.** Without agreed escalation triggers, underperformance goes undocumented until the project is months off-track. Define measurable criteria that trigger a formal review: two consecutive sprint velocity misses, a pipeline SLA breach of more than four hours, or a code-review rejection rate above 30% in any given week. These aren't termination triggers - they're early-warning mechanisms that force a structured conversation.
The 90-day handover cadence should look like this: weekly sprint reviews for the first eight weeks, bi-weekly after that, with a formal 30/60/90-day checkpoint against the success metrics defined in Stage 1.
The engagement that fails quietly usually had a clean kick-off. The warning signs appear in week three: sprint reviews that end without clear next steps, questions from the vendor team that should have been answered in discovery, and a "we're on track" status report that nobody has tested against the actual deliverable.
---
## How long should data engineering partner selection take?
Realistically, 10-16 weeks from the start of Stage 0 to contract signature, plus 12 weeks for the initial delivery phase. The table below shows a 14-week baseline:
| Week | Activity | Owner |
|---|---|---|
| 1-2 | Stage 0: Signal scan, candidate pool assembly | Analyst / Head of Data |
| 3-4 | Stage 1: Internal alignment, non-negotiables document | Head of Data + Finance + Legal |
| 5-6 | Stage 2: Shortlisting (4-6 vendors), outreach | Head of Data + Procurement |
| 7 | Stage 3: RFP issued, briefing calls | Procurement |
| 8-9 | Stage 3: Proposals received, initial scorecard scoring | Evaluation committee |
| 10 | Stage 3: Discovery calls with 3-4 finalists | Evaluation committee |
| 11-12 | Stage 3: Paid pilots with 2-3 finalists | Evaluation committee + technical leads |
| 13 | Stage 3: Pilot debrief, vendor selection decision | Head of Data + Project sponsor |
| 14 | Stage 4: Negotiation, MSA + SOW finalised | Procurement + Legal |
| 15 onward | Stage 5: 90-day onboarding and delivery | Project sponsor + vendor PM |
Timelines compress when the buying committee is decisive and internal alignment is fast. They expand when legal review takes longer than expected, when a finalist vendor drops out of the pilot, or when procurement has a mandatory 30-day review period for contracts above a certain value. Budget 16 weeks if any of those conditions apply.
---
## Pure data engineering vendor or MLOps partner?
This is the decision that most selection guides gloss over, and it's where buying committees make the most expensive mistakes.
A pure data engineering vendor builds pipelines, data models, ingestion layers, and transformation logic. That's the core. A small number also handle orchestration tooling and data quality frameworks. Most stop there.
An MLOps-aware partner adds model training infrastructure, feature stores, model monitoring, retraining pipelines, and experiment tracking. Firms in this category typically work with [MLflow](https://mlflow.org/) or Weights & Biases, understand drift detection, and can architect a system where a data pipeline feeds a model registry that feeds a serving layer with appropriate observability.
If production ML is on the 18-month roadmap, hiring a pure data engineering vendor creates a handover problem. The pipelines are built to one standard; the ML infrastructure, hired separately later, expects a different one. Integration work gets expensive fast.
The wrong answer here is usually discovered six months in, when the data engineering vendor finishes their statement of work and the ML team arrives to find pipelines built without feature engineering hooks, no model registry connection, and a data model that makes retraining windows nearly impossible to compute. The rewrite costs more than a correct initial selection would have.
---
## How does this framework compare to other selection approaches?
The five-stage framework is not the only structured approach to data engineering partner selection. Here's how it compares:
| Framework | Strength | Weakness | Best For |
|---|---|---|---|
| Five-Stage (this framework) | Covers the full journey including pre-RFP and post-signature; 2026 AI-copilot aware | Requires 10-16 weeks; demanding for small teams | Mid-market to enterprise; strategic engagements over $150K |
| Gartner-style category model | Strong analyst rigour; good for platform decisions | Lags real market by 12-18 months; limited to covered vendors | Large enterprise with Gartner access |
| ISG Provider Lens | Broad market coverage; free tiers available | Country-level granularity can obscure team-level quality | Regional sourcing decisions |
| Forrester Wave | Strong buyer-value framing; useful for C-suite alignment | Paid access; infrequent updates for niche categories | Vendor positioning in board-level discussions |
| Scorecard-only approach | Fast to implement; easy to defend internally | Skips signal scan and pilot; misses pre-RFP vendor filtering | Small engagements; tight timelines; low-risk projects |
---
## What does this look like for a 250-person fintech vs a 2,000-person healthcare org?
**250-person fintech (Series C, building a credit risk data platform on Databricks)**
Non-negotiables from Stage 1: FCA compliance, UK data residency, EU AI Act Article 5 compliance for the credit-scoring model, Databricks-only stack, T&M engagement. Budget: £400-600K over 12 months.
Signal scan surfaces 11 firms. Eight are filtered in Stage 2: three have no UK financial services case studies, two are Snowflake specialists, two are too large, one has a lapsed certification. Shortlist: three firms.
Paid pilot scopes a single ingestion pipeline from a core banking API into a Delta Lake bronze layer. The winning firm delivers in week two and spends the remaining time on observability and medallion-layer refactoring. The runner-up delivers in week three with no documentation.
Total selection timeline: 11 weeks. The sticking point in negotiation: IP assignment on reusable connector code - resolved by agreeing a source-access license back to the client.
**2,000-person healthcare org (NHS-affiliated, migrating from on-premises EDW to Snowflake, GDPR and NHS DSP Toolkit obligations)**
Non-negotiables: UK data residency with NHS CIG approval, DSP Toolkit compliance, Snowflake Elite partner status, fixed-price migration phase, named senior architect for the full engagement. Budget: £1.2-2M over 18 months. Procurement must run a public tender under PCR 2015.
The procurement requirement adds 4-6 weeks (OJEU-equivalent notice, mandatory standstill). Seven firms respond; five are technically compliant. Stage 3 discovery includes a mandatory DSP Toolkit evidence session. Two firms cannot answer the IG controls question adequately. Paid pilot with two finalists scopes a single patient-pathway dataset migration with anonymisation and audit logging.
Total selection timeline: 16 weeks. Stage 5 onboarding extends by three weeks due to a mandatory data processing agreement review with NHS legal.
---
## Frequently asked questions
### How is partner selection different from vendor selection?
The terms are used interchangeably in most procurement contexts, but they describe meaningfully different relationships. A vendor provides a product or service at defined specifications - you buy it, receive it, and manage the handover. A partner is involved in defining the problem, designing the solution, and taking some accountability for the outcome. Data engineering engagements are almost always partnerships in practice: the consulting firm's decisions about architecture, tooling, and team structure directly determine the quality of what the client inherits. "Vendor selection" undersells the stakes. "Partner selection" is the more accurate framing, and it changes which evaluation criteria matter most - delivery discipline and knowledge transfer move up; price moves down.
### Should we send the RFP to 10 vendors to be safe?
No. Sending an RFP to 10 vendors signals to the market that the buying committee hasn't done its homework. Quality firms read a 10-vendor RFP as a procurement checkbox exercise and either decline to respond or submit a templated proposal without investing senior time. The result is a stack of mediocre responses that takes weeks to score and reveals little. Four to six vendors, pre-qualified through the Stage 0 signal scan and Stage 2 evidence screen, produce richer proposals and more competitive commercial terms than ten cold invitations.
### What if our top-scoring vendor is also the most expensive?
Price it out explicitly. Get a total cost of ownership estimate over the full engagement duration - not just the day rate. Then ask: what is the cost of the project failing? For a $500K Snowflake migration that slips by four months, the real cost is pipeline downtime, internal engineering hours spent managing the mess, and the replatforming cost if the architecture has to be redone. If the highest-scoring vendor costs 20% more than the next-best option, the premium is almost always worth it for strategic engagements. If it's 50%+ more, run the due diligence on why - sometimes a large rate premium reflects genuine depth, but sometimes it reflects an overpriced sales team. Use the negotiation levers in Stage 4 before concluding the price is fixed.
### How early should we involve procurement?
Day one of Stage 1, at the absolute latest. Procurement involvement late in the process - after the technical team has already formed preferences and shortlisted vendors - creates the worst outcomes. The technical team has anchored on a favourite; procurement then tries to apply criteria that weren't agreed at the start; the preferred vendor doesn't score well on procurement's generic rubric; conflict follows. Bringing procurement in at Stage 1 means they co-own the non-negotiables document, understand the technical requirements well enough to score proposals fairly, and have already flagged any contract value thresholds that trigger mandatory tender rules. This is especially important in public sector and regulated industry contexts where PCR or equivalent frameworks apply.
### Is a free pilot ever acceptable?
Occasionally, but rarely for the right reasons. Some vendors offer free pilots as a sales tactic - they assign junior staff, scope the pilot to something that showcases a pre-built accelerator, and use the "free" framing to reduce the buying committee's scrutiny. A paid pilot, even a small one (£5-15K for four weeks), changes the dynamic. The vendor assigns real staff. The buying committee treats the milestone checkpoints seriously. The output is evaluated against a formal rubric, not gratitude. If a vendor insists on a free pilot only, ask specifically what team they'll assign and what the milestone structure looks like. If the answer is vague, the pilot is a demo dressed as a proof of concept.
---
## Next step
If the selection process is just starting, the [RFP checklist](/data-engineering-rfp-checklist/) walks through the RFP document itself item by item, and [how to choose a data engineering company](/how-to-choose-data-engineering-company/) covers the decision from a broader angle. If the shortlist is already formed and the evaluation is the problem, the [scorecard template](/insights/data-engineering-vendor-evaluation-criteria/) has the scoring mechanism ready to use.
For committees that want to check the market before running a full signal scan themselves, the [Data Engineering Companies Index](/data-engineering-consulting-firms/) surfaces firms by platform, industry, team size, and rate range.
For budget benchmarking before finalising the envelope in Stage 1, [current data engineering consulting rates](/insights/data-engineering-consulting-rates-2026/) gives a rate range by platform and engagement model.
---
## A Pragmatic Guide to Data Engineering Project Management
Source: https://dataengineeringcompanies.com/insights/data-engineering-project-management/
Published: 2026-03-22T09:15:34.577523+00:00
Description: Master data engineering project management with this playbook. Learn proven strategies for on-time delivery of complex data pipelines and cloud platforms.
Managing a data engineering project well comes down to five disciplines: define success in business terms before writing code, gate delivery through phases with real sign-offs, govern any outside consultancy as tightly as your own team, track velocity and cost together instead of separately, and treat risk as day-one work rather than a post-launch cleanup. Most data engineering projects that miss their deadline or blow through budget fail for one of these reasons, not because the engineering talent was weak.
This guide walks through the five-phase lifecycle for building a data platform, how to run an RFP and govern a consulting partner, the KPIs that actually predict whether a project is healthy, and a risk register you can adapt directly.
## Why do data engineering projects fail?
Elite teams using platforms like [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/) still get derailed, and it is rarely a technical problem. The root cause is almost always a disconnect between engineering execution and a specific, agreed business outcome - a gap that shows up as scope creep, stakeholder disengagement, and budget overruns.
### Anatomy of Failure: The Three Core Breakdowns
Data project failure follows a consistent pattern. These are the most common breakdowns engineering leaders must prevent.
* **Unrealistic or Vague Scope:** Projects that start with ambiguous goals ("modernize our analytics") are the ones most likely to fail. Without a quantifiable, bounded scope, requirements shift continuously, and shifting requirements are what turn a project into rework and budget overruns. A tightly scoped [Statement of Work](/insights/data-engineering-statement-of-work/) is the first line of defense.
* **Mismanaged Consulting Engagements:** Engaging an external firm without disciplined oversight introduces significant risk. Ambiguous Statements of Work, inconsistent communication, and weak governance lead directly to misaligned priorities and uncontrolled budget expansion.
* **Focus on Technology Over Business Value:** Technical teams can become fixated on building a "perfect" or maximally scalable architecture. Stakeholders, however, measure success by tangible business results. A project that runs for months without delivering measurable value will lose executive support.
Projects that start without agreed success criteria are the ones most likely to blow through budget. Without a shared definition of "done," scope keeps expanding, and cost follows it.
### Common Failure Points in Data Engineering Projects and Their Solutions
These issues consistently derail data initiatives. This framework helps leaders identify and mitigate them proactively.
| Failure Point | Leading Indicator | Actionable Mitigation Strategy |
| :--- | :--- | :--- |
| **Vague Business Requirements** | Stakeholders use fuzzy terms like "better insights" or "modernize our data." | Insist on quantifiable KPIs before any work begins. Translate business goals into specific data outcomes (e.g., "reduce report generation time from 4 hours to 15 minutes"). |
| **Lack of Stakeholder Buy-In** | Key business users repeatedly miss planning meetings or are slow to provide feedback. | Establish a formal project steering committee with defined roles and responsibilities. Schedule mandatory bi-weekly demos to maintain engagement and gather feedback. |
| **Poor Source Data Quality** | Engineers discover source data is incomplete, inconsistent, or undocumented mid-project. | Mandate a dedicated data audit and profiling phase during project discovery. Allocate 15-20% of the initial engineering timeline specifically for data cleansing and preparation. |
| **"Big Bang" Delivery Model** | The project plan outlines a single, monolithic deployment after 6-9 months of development. | Re-architect the project plan for agile, milestone-based delivery. Mandate the delivery of a usable, high-value data product every 4-6 weeks to build momentum and demonstrate value. |
| **Technology-Driven Development** | The team spends the first month debating tools (e.g., Airflow vs. Dagster) instead of user needs. | Freeze all technology decisions until the business requirements and core use cases are documented and signed off. The problem must define the tool, not the other way around. |
Recognizing these patterns is the first step. A structured project management framework that prioritizes quantifiable goals, incremental delivery, and continuous communication turns high-risk data initiatives into predictable, value-driven successes.
## What does the five-phase lifecycle for a data platform build look like?
Monolithic, "big bang" data platform projects are a direct path to failure. Building a modern data platform requires an iterative methodology that delivers business value quickly and adapts to new information. The most successful data engineering initiatives follow a structured, five-phase lifecycle built specifically for cloud-native tools like [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/).
The purpose of this framework is to prevent the common failure sequence of data projects.
This outcome is avoidable by structuring work into gated phases. Each gate forces a critical alignment decision, so the project can't proceed with a fundamental flaw baked in.
### Phase 1: Discovery & Scoping (Weeks 1-4)
This phase translates vague business requests into a concrete, prioritized backlog. No code is written.
* **Key Activities:** Conduct stakeholder interviews to define specific business questions. Sketch a high-level entity-relationship diagram (ERD). Draft a Success Criteria Document defining quantifiable outcomes (e.g., "reduce customer churn analysis time from 3 days to 2 hours").
* **The Gate:** **This phase is not complete until business sponsors formally sign off on the prioritized use cases and their associated KPIs.** This is the primary defense against building a platform no one uses.
### Phase 2: Architectural Design (Weeks 5-6)
With a clear "what," the team defines the "how." This is where defensible technology choices are made based on the defined use cases, not trends.
* **Key Deliverables:** Produce a detailed technical design document specifying data flows, modeling layers, and CI/CD strategy. A mandatory component is a total cost of ownership (TCO) analysis comparing at least two viable platform options (e.g., Snowflake vs. Databricks) based on projected workloads and data volume.
* **The Gate:** **The project does not proceed until the TCO is approved and the architectural design is signed off by the lead architect or VP of Engineering.**
### Phase 3: Iterative Build (Sprints, Weeks 7-20)
The project shifts into an agile execution rhythm. The team works in short sprints (typically two weeks) to build, test, and deliver functional components of the platform.
* **Typical Cycle:** Ingest a new data source, apply business logic with a tool like [dbt](https://www.getdbt.com/), and expose the curated data mart for analyst use. Each cycle must produce a testable, usable output.
* **The Gate:** **Each sprint concludes with a demo to stakeholders. The sprint is not "done" until the acceptance criteria for its user stories are met.**
### Phase 4: User Acceptance & Deployment (Weeks 21-22)
Moving from development to a stable production environment requires a dedicated process. This is about building a reliable, automated pipeline for code promotion.
* **Core Activities:** Configure CI/CD pipelines to automate testing and deployment. Conduct formal User Acceptance Testing (UAT) with business users. Finalize operational runbooks and on-call schedules.
* **The Gate:** **The platform is not "live" until UAT is passed and the operations team formally accepts the handover documentation.**
### Phase 5: Optimization & Governance (Ongoing)
The project is not "done" at launch. It transitions into a continuous loop of monitoring, cost management, and enhancement based on real-world usage.
* **Ongoing Tasks:** Implement automated alerts for query performance degradation and budget anomalies. Fine-tune cloud spend based on usage patterns. Evolve data models to support new business requirements. This ongoing iteration is the core of effective data engineering project management.
## How do you select and manage a data engineering consultancy?
Selecting a consulting partner is the highest-leverage decision an engineering leader makes on a data project. The right firm accelerates your roadmap by years; the wrong one consumes budget and delivers technical debt. The goal of an RFP is to cut through sales pitches and identify partners with proven, relevant expertise.
The evaluation process starts with a technically rigorous Request for Proposal. A well-structured RFP functions as a technical screen - it should force every firm, including any of the 86 profiled in the [Data Engineering Companies Index](/data-engineering-consulting-firms/), to demonstrate expertise instead of just claiming it. Our [RFP checklist](/data-engineering-rfp-checklist/) turns the scenario-based questions below into a document you can send out this week.
### Structuring a Technically Rigorous RFP
Your RFP is a technical interview for an entire company. It must force prospective partners to demonstrate expertise, not just claim it.
* **Technology-Specific Scenarios:** Do not ask, "Do you have experience with Airflow?" Instead, provide a scenario: "Describe how you would design an idempotent and backfill-capable data pipeline using Airflow to process 1TB of daily event data from S3. What specific operators would you use and how would you manage state?"
* **Architectural Trade-offs:** Force a defensible position. For example: "Given our requirement for sub-second query latency on 10TB of nested JSON data, argue for either [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/) with Delta Lake. Your justification must include a TCO comparison for a 12-month period, factoring in compute, storage, and egress costs."
* **dbt Best Practices:** Test their modeling discipline. Ask: "Provide a sample `dbt_project.yml` and directory structure for a multi-layered data model (staging, intermediate, marts). How do you enforce [data quality tests](https://docs.getdbt.com/docs/build/data-tests) and documentation standards within this framework?"
### From Contract to Kickoff: Establishing Governance
Once a partner is selected, the focus must shift immediately to governance. An ambiguous Statement of Work is an invitation for scope creep. The SOW must be airtight, with explicit deliverables, timelines, and quantitative acceptance criteria for each project phase.
From day one, establish a firm communication rhythm:
* **Weekly Technical Syncs:** For the core project team to resolve technical blockers and review progress at a granular level.
* **Bi-Weekly Steering Committee:** For executive sponsors and consultancy leadership to review budget vs. actuals, track major milestones, and ensure continued alignment with business goals.
This dual-track governance model maintains both tactical momentum and strategic alignment, so the partner you selected actually delivers what they promised.
## Which KPIs actually measure data engineering project success?
Vanity metrics like "tasks completed" are insufficient for managing data engineering projects. Leaders need clear signals on project velocity, financial health, and business impact - a multi-faceted measurement framework, not a single number.
### Engineering Velocity and Predictability
These metrics measure the engineering team's throughput and process efficiency.
* **Sprint Velocity (Predictability over Volume):** The goal is not the highest number of story points, but a stable, predictable velocity. Consistency indicates the team has hit a sustainable pace, allowing for reliable forecasting of delivery dates.
* **Cycle Time:** This measures the wall-clock time from when a task begins to when it is deployed to production. A decreasing cycle time is a strong indicator of improving process efficiency and bottleneck removal.
### Financial Discipline and Cloud Cost Control
Financial oversight is non-negotiable.
* **Budget vs. Actual:** This must be tracked monthly, comparing planned spend for both consulting services and cloud platforms ([AWS](https://aws.amazon.com/), [GCP](https://cloud.google.com/), [Azure](https://azure.microsoft.com/)) against actual consumption.
* **Cloud Cost per Environment:** Total cloud spend is an incomplete metric. Break down costs by environment (dev, test, prod) to identify waste, such as oversized or idle development resources.
### Business Value and ROI
This is the ultimate measure of project success and justifies future investment. For a fuller framework on tying platform work to dollar figures, see our guide to [measuring data engineering ROI](/insights/data-engineering-roi-measurement/).
* **Data Uptime & SLA Adherence:** Track the percentage of time critical datasets are available and meet quality standards. If you promise the finance team 99.95% uptime for their end-of-quarter reporting data, this metric proves you are delivering.
* **Query Performance Improvement:** This provides a tangible metric of success. Example: "The new data model reduced the P95 query time for the executive sales dashboard from 90 seconds to 5 seconds." This is a clear win to report to stakeholders.
### A Framework for Cloud Cost Control
Runaway cloud spend can derail a project. An effective cost control strategy is multi-layered, and it starts before the platform goes live: cost controls built in during the design phase are far cheaper to enforce than a post-launch cleanup, which usually means untangling months of untagged, oversized resources.
First, implement a **mandatory resource tagging policy**. Every resource must be tagged with `project`, `environment`, and `owner`. This is non-negotiable and provides immediate visibility for cost allocation. Couple this with automated budget alerts that notify stakeholders when spending crosses **75%** of the monthly forecast.
Second, integrate cost control into the architecture. When using a platform like [Snowflake](https://www.snowflake.com/en/), this means selecting the correct [virtual warehouse size](https://docs.snowflake.com/en/user-guide/warehouses-overview) for each workload (do not default to `Large`) and setting aggressive auto-suspend policies (e.g., 60 seconds). These are not suggestions; they are fundamental budget controls. Proactive management prevents budget-breaking invoices.
## How do you integrate risk management and governance into a data project?
Data pipelines handle a company's most critical assets. Treating risk management as a post-launch activity is a significant liability. Effective data engineering project management involves identifying threats before they materialize and establishing clear ownership from day one.
Begin with a living risk register - a practical document tracking real-world threats, not a compliance checkbox. The most common risks for data platform projects are predictable:
* **Data Quality Degradation:** The "garbage in, garbage out" problem, amplified at scale.
* **Security Vulnerabilities:** Misconfigured IAM roles, unencrypted data in transit, or insecure API endpoints.
* **Vendor Lock-In:** Over-reliance on a single proprietary tool, limiting future architectural flexibility.
* **Scope Creep:** The accumulation of "small" stakeholder requests that derail timelines and inflate budgets.
### From Risk Identification to Mitigation
For each identified risk, a specific mitigation strategy is required. This involves implementing technical and procedural guardrails.
| Risk | Mitigation Strategy |
| :--- | :--- |
| **Data Quality Degradation** | Implement data contracts at ingestion points. Use [dbt tests](https://docs.getdbt.com/docs/build/data-tests) to run automated data quality checks (freshness, uniqueness, referential integrity) on every pipeline run. |
| **Security Vulnerabilities** | Mandate peer review for all Infrastructure-as-Code (IaC) changes. Run automated security scans (e.g., Trivy, tfsec) within the CI/CD pipeline. Enforce principle of least privilege for all database roles. |
| **Vendor Lock-In** | Prioritize tools with open standards and APIs (e.g., SQL, Parquet). Isolate vendor-specific logic behind an abstraction layer to simplify future migration. |
| **Scope Creep** | Institute a formal change control process. All new requests must be evaluated for business value, cost, and timeline impact before being approved by the steering committee. |
A documented risk register with pre-defined mitigation plans turns a scramble after a production incident into a known, rehearsed response. The risks above are manageable precisely because they're predictable - the register just has to exist before they show up.
### A Lightweight, Effective Governance Model
Governance should provide clarity, not bureaucracy. An effective framework defines accountability.
* **Data Owner:** A business leader (e.g., VP of Marketing) who is accountable for a specific data domain (e.g., customer data). They have final authority on access and usage policies.
* **Data Steward:** A domain expert, often from the business unit, responsible for the day-to-day management of data quality, definitions, and metadata for their domain.
* **Data Custodian:** The technical team (data engineers) responsible for the secure transport, storage, and processing of the data, implementing the policies defined by owners and stewards. On platforms like Databricks, this often maps directly to [Unity Catalog](https://docs.databricks.com/en/data-governance/unity-catalog/index.html) access roles.
This structure clarifies decision-making. Enforcing it takes a documented change-control process, so platform modifications are introduced in a controlled, predictable manner that protects the integrity of the data.
## What do engineering leaders ask most about data platform projects?
These are the most common questions from leaders managing data platform projects, with direct answers.
### What is a realistic timeline for a data platform MVP?
For a mid-sized enterprise building a core data platform MVP on [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/), a realistic timeline is **four to six months**. Any proposal promising a fully governed platform in under three months is either drastically under-scoped or being presented by an inexperienced team.
This **four-to-six-month** timeline allows for the delivery of tangible value, typically scoped to:
* Ingestion of **3-5** critical data sources.
* Development of a foundational data model.
* Delivery of **1-2** high-impact business intelligence dashboards or data marts.
A typical project plan is structured as follows:
* **Months 1-1.5 (Discovery & Design):** Lock down requirements, finalize architecture, and develop a detailed, milestone-based project plan.
* **Months 1.5-6 (Iterative Build & Deploy):** Execute in an agile rhythm, building data pipelines and models, and delivering functionality to stakeholders for continuous feedback.
### How much should we budget for a data engineering consulting engagement?
Hourly rates across the 86 firms profiled in the [Data Engineering Companies Index](/data-engineering-consulting-firms/) run from $45 to $250, with a median of $100. Most firms (44 of 86) sit in the $100-$200 range; 35 charge under $100, and only 7 charge above $200/hr.
To size an engagement, multiply your team's expected hours by the blended rate of the firms you're evaluating, then budget cloud consumption costs as a separate line item - consulting spend and cloud spend get confused often enough to cause real problems if they aren't tracked apart.
Insist on a detailed [Statement of Work](/insights/data-engineering-statement-of-work/) that ties payments to the delivery of specific milestones. This provides better budget control than an open-ended time-and-materials contract.
> **Key Takeaway:** Be skeptical of a rate far below $45/hr. In data engineering, rock-bottom rates are a direct indicator of junior talent. That creates short-term savings but incurs substantial long-term costs from architectural errors, technical debt, and extensive rework.
## Turning the Framework Into Practice
None of this works as a checklist you complete once. Scoping controls risk, phased delivery proves value early, KPIs catch drift before it becomes a crisis, and a risk register turns unpredictable failures into known, manageable ones. Skip a step and the risk does not disappear - it shows up later, more expensive.
If you're still drafting the engagement itself, our guides to [writing a data engineering Statement of Work](/insights/data-engineering-statement-of-work/) and [choosing the right partner](/insights/data-engineering-partner-selection/) cover the two decisions that do the most to prevent the failure modes above.
---
## Strategic Data Engineering ROI Measurement for CTOs
Source: https://dataengineeringcompanies.com/insights/data-engineering-roi-measurement/
Published: 2026-04-28T08:57:07.185926+00:00
Description: Master data engineering ROI measurement with our 2026 guide. Get frameworks, KPIs, and templates to justify investments and evaluate partners.
Data engineering ROI measurement has one real test: can you tell your CFO what you're buying, when payback happens, and how you'll know the consultancy caused the result rather than just showed up while it happened. If the honest answer is "better data foundations," that's a technical preference, not a business case.
For a multi-million dollar Snowflake, Databricks, dbt, or Airflow modernization, a credible ROI model has to do three jobs at once: justify the spend, govern delivery, and protect you during vendor selection. Skip the first and the project never gets funded. Skip the second and it drifts once it does. Skip the third and you'll over-credit the consultancy for wins your own team drove, or under-manage the parts that were always yours to own.
## What does your CFO actually want when they ask for ROI on data engineering?
Most CTOs answer this question backwards, leading with architecture when the CFO is asking about economics, risk, and timing. A real answer names what gets cheaper or faster, quantifies it, and states when the investment pays back.
A working answer sounds like: we're investing to cut manual engineering effort, reduce downtime and data-trust failures, and speed up business decisions that are currently blocked by stale or unreliable pipelines. Then you quantify each one.
That's the difference between a funded platform program and a "phase zero" that never scales.
### Why standard IT ROI logic fails
Traditional infrastructure ROI models focus on hard cost takeout. That's too narrow for data engineering. A migration from legacy ETL to modern cloud data pipelines on Snowflake, Databricks, BigQuery, or Azure isn't just a hosting change. It changes transformation speed, reliability, governance, developer workflow, and how fast business teams can act on data.
Vendor-sponsored benchmarks are directionally useful even though they aren't neutral. Nucleus Research's analysis of ETL platform customers, published by Integrate.io, found three-year ROI well above 100% with payback inside a year, driven mainly by faster transformations and fewer manual error fixes ([Integrate.io ETL ROI benchmarks](https://www.integrate.io/blog/etl-roi-calculation-examples-and-stats/)). Treat that as a vendor-sponsored best case, not a baseline for your own project.
**Practical rule:** if your business case doesn't show baseline pain, target metrics, owners, and a payback path, finance will treat it as discretionary spend.
### Build the business case before the architecture deck
Before you debate Databricks versus Snowflake, or dbt versus in-platform SQL, put the economics into a structure your executive peers can review. A clean format like [WeekBlast's business case template](https://weekblast.com/blog/business-case-template) helps because it forces explicit assumptions, options, costs, risks, and ownership.
Use it to answer five questions:
- **What is broken now:** Manual rework, slow transformations, unreliable pipelines, weak lineage, duplicated metrics.
- **What changes in the target state:** Automated orchestration, testable transformations, clearer ownership, lower latency, stronger governance.
- **Who benefits:** Data engineering, analytics, finance, operations, and executive decision-makers.
- **How value shows up:** Labor savings, fewer incidents, faster decisions, reduced bad-data exposure, better AI/ML readiness.
- **How you'll prove it:** A baseline and review cadence tied to named KPIs.
If you can't explain ROI in those terms, don't issue the RFP yet.
## What are the three layers of data engineering ROI?
A credible ROI model has three layers: operational efficiency, strategic impact, and innovation and growth. Present only one, and the business case looks incomplete no matter how strong the underlying numbers are.
### Operational efficiency
This is the floor. It covers the obvious gains from better pipeline architecture, orchestration, and transformation practices.
Think about what changes when a consultancy replaces brittle legacy ETL with well-structured dbt models, Airflow orchestration, and cloud-native storage and compute. Engineers spend less time patching jobs. Analysts wait less. Teams stop rebuilding the same logic in multiple places.
The clearest benchmark here comes from modern analytics engineering. A Forrester Consulting Total Economic Impact study commissioned by dbt Labs found 194% ROI with breakeven inside six months, tied to gains in developer productivity, data quality, and collaboration efficiency ([dbt Labs analytics ROI research](https://www.getdbt.com/blog/analytics-roi-best-practices)). It's a commissioned study, so read the multiple as an upper bound, but the underlying mechanism, less time lost to rework and coordination, holds up on its own logic.
Operational efficiency is the easiest layer to model because it maps directly to labor and support effort. It's also the weakest layer to lead with if you're asking for a large modernization budget. Cost savings alone rarely justify a platform shift.
### Strategic impact
At this point, the business case becomes credible.
Strategic impact sits between engineering output and executive value. It includes lower data latency, more reliable reporting, faster issue resolution, and greater confidence in planning, pricing, supply chain, or growth decisions. The point isn't "our pipelines are better." The point is that leaders stop making decisions on stale or suspect data.
A data platform earns executive support when it changes decision velocity, not when it merely improves architecture hygiene.
This layer is what connects platform work to planning cycles, operating cadence, and cross-functional trust. It's also where governance belongs. Governance isn't compliance theater. It's what lets finance, operations, and product teams use the same numbers without relitigating definitions every week.
### Innovation and growth
This is the top layer. Organizations frequently mention it too early and too vaguely.
Innovation and growth value appears when your platform supports new data products, AI/ML workloads, experimentation, and reusable data assets across teams. That's the upside a CEO cares about, but it only becomes believable once the bottom two layers are already quantified.
A consultancy pitching "AI readiness" without a measurable plan for pipeline reliability, lineage, and transformation quality is selling aspiration. Don't buy aspiration.
### How to use the three-layer model in executive conversations
Use the layers to separate benefits by audience:
| Executive audience | ROI layer they care about most | What to show |
|---|---|---|
| **CFO** | **Operational efficiency** | Labor savings, reduced manual processing, payback timing |
| **COO** | **Strategic impact** | Better reliability, lower latency, fewer reporting disruptions |
| **CEO or BU leader** | **Innovation and growth** | Faster launch of analytics and AI-enabled use cases |
A consultancy should map its proposal to all three. If it only talks about engineering velocity, it's underselling the work. If it only talks about transformation and AI, it's hiding execution risk.
## Which KPIs connect engineering work to business value?
The fastest way to ruin data engineering ROI measurement is to track only financial outputs. You need operating KPIs that move before the money shows up, or you'll discover failure only after the budget is spent.
### Efficiency KPIs that finance can understand
For platform modernization, start with a small set of operational KPIs and refuse to let the vendor bury them under vanity dashboards.
Track these before the engagement starts:
- **Transformation cycle time:** How long it takes to build, test, and release a production-ready transformation.
- **Manual intervention load:** How often engineers step in to rerun jobs, fix schemas, backfill data, or reconcile outputs.
- **Support burden:** The volume and type of data-related support work created by pipeline failures or broken definitions.
- **Delivery throughput:** The speed at which the team ships trusted data assets to downstream analytics users.
If you want a useful parallel for measuring the human side of engineering output, this piece on [modern approaches to developer productivity](https://www.monito.dev/blog/how-to-measure-developer-productivity) is worth reading. The core lesson applies directly here: measure flow and friction, not just raw activity.
### Latency is a business KPI, not a plumbing KPI
Most engineering teams understate the value of latency. They treat it as a technical improvement. It isn't. It directly affects decision speed.
Cutting latency in half, from a daily batch to same-day availability, measurably speeds up the decisions that depend on it: campaign changes, fraud flags, inventory calls. The exact dollar value depends on what's riding on the data, but the direction holds across most use cases we've reviewed: faster data means faster, cheaper decisions.
That gives you a practical way to position latency KPIs:
| KPI | Definition | Business translation |
|---|---|---|
| **Data latency** | Time from source event to analytical availability | Decision speed |
| **SLA adherence** | Whether critical datasets arrive on time | Planning reliability |
| **Time-to-insight** | Time from business question to trusted answer | Commercial responsiveness |
For a retail or fintech stack, that may mean campaign optimization or fraud analysis. For enterprise finance, it may mean faster variance analysis or more credible forecasting. The metric is technical. The value is operational.
Don't report latency as "pipeline freshness." Report it as the delay between an event and an executive action.
### Reliability KPIs separate serious vendors from slideware
Operational execution determines whether Snowflake, Databricks, Airflow, Kafka, and dbt implementations succeed or fail. If pipelines break constantly, the rest of the ROI model is fiction.
Monitor:
- **Pipeline success rate:** Percentage of scheduled jobs completing without failure.
- **Incident frequency:** How often critical pipelines break in a reporting period.
- **Time-to-recovery:** How long it takes the team to restore service after a failure.
- **Rework load:** Engineering and analyst time spent fixing downstream consequences of upstream issues.
These KPIs matter because they expose whether the consultancy is building an operable platform or just delivering initial migration scope.
### Governance and adoption KPIs prove the platform is being used
A technically elegant platform with poor adoption has weak returns.
Use governance and adoption measures such as:
- **Certified data asset usage:** Whether business teams consume governed models and dashboards.
- **Metric consistency:** Whether teams rely on standardized definitions instead of local spreadsheet logic.
- **Lineage coverage:** Whether critical datasets can be traced back to source and transformation logic.
- **New use-case activation:** How quickly a new reporting, analytics, or AI need can move onto the platform.
### A sane KPI rule set
Keep the scorecard tight.
- **Use a baseline:** Measure before consultants touch the stack.
- **Tie each KPI to an owner:** Finance owns cost assumptions. Engineering owns reliability. Business teams validate adoption.
- **Track leading and lagging indicators:** Time-to-recovery and latency move before revenue or cost outcomes do.
- **Review monthly, not only at the steering committee:** ROI drift starts in operating metrics.
## How do you build an ROI model finance will actually trust?
A workable model is simple enough for finance to audit and detailed enough for engineering to defend. Start with the standard ROI formula already used in ETL modernization analysis, (Net Benefits / Total Costs) x 100, then make the inputs rigorous.
### Step one: baseline the current state
Capture the current operating reality before vendor selection, not after kickoff.
You need baseline values for effort, incidents, latency, support burden, and trust issues. Reliability matters here because poor reliability compounds quietly: frequent pipeline breakages force engineers into reactive firefighting instead of planned work, and every hour spent restoring a failed job is an hour not spent on the roadmap you funded the project for. Baseline your current break rate and mean time to recovery before the engagement starts, because those two numbers, more than any single dollar estimate, tell you whether reliability is actually improving.
### Step two: convert engineering improvements into monetary value
Weak business cases usually fail here. They stop at "faster pipelines" instead of converting outcomes into money.
Use three buckets:
1. **Efficiency benefits**
Translate lower manual effort and fewer support tickets into labor savings or capacity released for higher-value work.
2. **Risk reduction benefits**
Quantify avoided downtime, avoided rework, and lower exposure to bad-data decisions.
3. **Enablement benefits**
Value faster delivery of dashboards, models, and analytics use cases by tying them to documented business dependencies.
**Operator advice:** if a benefit can't be tied to a baseline metric and an owner, exclude it from the core ROI case and keep it as upside.
### Step three: price the full investment
Count all costs, not just consultancy fees.
Include platform licenses, cloud consumption, migration effort, internal engineering time, training, observability tooling, governance work, and post-go-live stabilization. If you ignore internal time, your model will look good and be wrong.
Consultancy fees vary widely: hourly rates across the [86 firms profiled in the Index](/data-engineering-consulting-firms/) run from $45 to $250, with a median around $100. A rate quote alone tells you little about total project cost without knowing the scope and hours behind it. For teams building reusable tracking into client programs, the discipline used to [track client AI automation ROI](https://administrate.dev/ai-automation-roi-tracking) is a useful reference point: define value events, assign ownership, and review actuals against the model from the start.
### Step four: model year by year
Use a worksheet that finance and procurement can inspect.
| Metric | Formula / Source | Year 1 Value | Year 2 Value | Year 3 Value |
|---|---|---:|---:|---:|
| **Efficiency benefits** | Baseline engineering and analyst effort reduced after modernization | | | |
| **Reliability benefits** | Downtime and rework avoided based on incident reduction and faster recovery | | | |
| **Latency benefits** | Value from faster decisions on critical workflows | | | |
| **Governance and trust benefits** | Avoided reconciliation effort and reduced bad-data exposure | | | |
| **Total benefits** | Sum of all benefit categories | | | |
| **Consultancy cost** | SOW fees and retained support | | | |
| **Technology cost** | Platform, tooling, and cloud spend | | | |
| **Internal cost** | Staff time, change management, training | | | |
| **Total costs** | Sum of all investment categories | | | |
| **Net benefits** | Total benefits less total costs | | | |
| **ROI** | (Net Benefits / Total Costs) x 100 | | | |
### Step five: force a payback discussion
Your CFO will ask two things after ROI: when do we break even, and what would cause us to miss?
Answer both in writing. Then tie the risk factors to delivery controls such as stage gates, KPI reviews, and acceptance criteria in the SOW.
## How do you isolate what the consultancy actually delivered?
Clients over-credit the consultancy when a modernization works and over-blame it when one stalls. Both are lazy. Attribution has to be designed into the engagement, in the contract, before work starts.
### Why attribution breaks down
In real programs, outcomes come from mixed inputs. The consultancy redesigns pipelines. Your internal team cleans up governance. A platform vendor changes pricing or features. Business teams improve adoption. Then everyone argues about who delivered the return.
Elder Research, a data science consultancy that has written about this pattern, points out that attribution problems are common wherever internal and external teams both touch the same pipeline: buyers tend to over-credit the vendor when a project succeeds and over-blame it when one stalls, and without a contract that separates the two, budgets get reallocated on weak evidence ([Elder Research on data engineering pitfalls](https://www.elderresearch.com/blog/four-common-data-engineering-pitfalls-and-how-to-avoid-them/)).
That should change how you write every SOW.
### What to put in the contract
The stronger proposals define attribution up front, before the SOW is signed, rather than leaving it to be argued about at the steering committee.
Require these elements:
- **Named KPI ownership:** State which KPI the consultancy influences directly, which KPI your internal team owns, and which KPI is shared.
- **Pilot-based attribution:** Use a scoped migration, pipeline domain, or business unit as a controlled proof point before wider rollout.
- **Pre and post baselines:** Freeze the baseline period before implementation starts.
- **Exclusion logic:** Identify benefits that shouldn't be credited to the vendor, such as parallel internal governance changes or business process redesign.
If attribution isn't written into the contract, the vendor will still talk about ROI. You just won't be able to verify whose ROI it is.
### The simplest attribution model that works
Use a three-part split:
| Contribution area | Primary owner | How to evaluate |
|---|---|---|
| **Platform implementation** | **Consultancy** | Delivery against scope, reliability, latency, migration quality |
| **Operating model and governance adoption** | **Internal team** | Stewardship, process discipline, metric consistency |
| **Business uptake** | **Shared** | Adoption of outputs, use-case activation, stakeholder usage |
That model won't make attribution perfect. It makes it governable. That's enough.
## What does negative ROI from data downtime actually look like?
Most ROI models are too optimistic because they count delivered features and ignore whether anyone trusts the data after go-live. A migration can hit scope, go live on time, and still destroy value if schema drift, broken lineage, or weak quality controls force teams back into manual validation.
That's negative ROI in practice, even if the deck says the platform is "live." Sound governance and access control, of the kind Databricks Unity Catalog or Snowflake's role-based access model are built around, is part of what keeps that trust intact ([Databricks Unity Catalog documentation](https://docs.databricks.com/en/data-governance/unity-catalog/index.html), [Snowflake access control overview](https://docs.snowflake.com/en/user-guide/security-access-control-overview)).
### Trust-adjusted ROI is the model most teams skip
A meaningful share of cloud platform modernizations show negative ROI in year one once you account for the cost of untrusted data, not because the migration failed technically, but because nobody trusted the output enough to retire the old manual checks. One way to model that is trust-adjusted ROI: (Value - (Investment + Downtime Cost)) / Investment ([Domo's overview of data analytics ROI](https://www.domo.com/glossary/data-analytics-roi)).
That formula matters because it forces you to subtract the cost of instability and distrust, not just implementation spend.
Three trust killers show up constantly in consulting proposals:
- **Weak observability:** No serious plan for freshness, schema, volume, and lineage monitoring.
- **Thin governance design:** Ownership and certification get deferred until after migration.
- **Success defined as cutover:** The vendor treats data moved as value delivered.
For a deeper operating view, review this guide to [data reliability engineering](https://dataengineeringcompanies.com/insights/data-reliability-engineering/). Reliability isn't an add-on. It's the control layer that protects ROI after launch.
### How to price downtime and trust gaps
Use a simple challenge test during procurement.
Ask every consultancy to show:
1. how it will detect broken pipelines,
2. how it will surface data quality regressions,
3. who responds to incidents,
4. how business users will know a dataset is trusted,
5. what happens to KPI reporting when a critical dependency fails.
If the answer is vague, your ROI model is inflated.
A platform with low trust has two costs. The first is direct rework. The second is that business teams stop using it and rebuild workarounds outside your controls.
A short explainer is worth watching if your executive team still treats downtime as an IT uptime issue rather than a decision-quality issue.
### Red flags that belong in every vendor review
Don't approve a consultancy proposal if it lacks:
- **A production observability plan**
- **Lineage and ownership definitions for critical data products**
- **Runbooks for incident response and recovery**
- **Post-go-live trust metrics**
- **A method for tracking negative ROI drivers alongside positive gains**
If those items are missing, the model is incomplete and the spend is harder to defend.
## How do you turn the ROI model into an RFP?
A good ROI model doesn't sit in a finance deck. It becomes the backbone of the RFP, the SOW, and the steering committee.
Use this action plan before you engage a consultancy:
- **Define the business case in three layers:** Separate efficiency, strategic impact, and innovation benefits so each executive stakeholder sees the value relevant to them.
- **Baseline the operating KPIs now:** Capture latency, reliability, support burden, trust issues, and delivery speed before procurement begins.
- **Embed attribution into the SOW:** Require named KPI ownership, pilot-based proof points, and exclusion logic for benefits driven by internal work.
- **Use trust-adjusted ROI, not headline ROI:** Subtract downtime and trust failures from the value model.
- **Make reliability part of vendor evaluation:** Treat observability, lineage, incident response, and governance design as commercial requirements, not technical extras.
Pair the model with a structured [RFP checklist](/data-engineering-rfp-checklist/) so procurement isn't reinventing the requirements list from scratch, and use this benchmark on [data engineering consulting rates for 2026](https://dataengineeringcompanies.com/insights/data-engineering-consulting-rates-2026/) to pressure-test whether a proposal's economics line up with the expected return.
Your next move is straightforward: build the ROI model before you shortlist vendors, then make every consultancy respond to that model instead of to a generic migration brief. Use the [Data Engineering Companies Index](/data-engineering-consulting-firms/) to compare firms, pressure-test capabilities, and tighten your shortlist before the RFP goes out.
---
## Data Engineering Staff Augmentation: A 2026 Playbook
Source: https://dataengineeringcompanies.com/insights/data-engineering-staff-augmentation/
Published: 2026-04-23T07:33:33.698298+00:00
Description: Your authoritative guide to data engineering staff augmentation. Learn when to use it, how to vet vendors, benchmark rates, and manage engagements for max ROI.
The worst advice in data engineering staff augmentation is "just add engineers fast." Speed matters, but it isn't the hard part.
The hard part is buying the right control model, locking down the contract before the first sprint, and forcing real integration into your architecture, governance, and delivery rituals. Miss those three and you don't get the expected benefit. You get extra people, extra meetings, and extra failure modes.
That matters because the labor gap is real. Experienced data engineers are in short supply, which is exactly why many teams use augmentation to fill specialized gaps without waiting through full hiring cycles. Rates vary widely with seniority and platform: across the 86 firms tracked in the [Data Engineering Companies Index](/data-engineering-consulting-firms/), hourly rates for data engineering work run $45-250, with a median around $100. That spread alone should tell you rate cards won't do your vetting for you.
But scarcity alone doesn't justify the model. Plenty of teams use augmentation when they should buy managed delivery, hire full-time, or pause until scope is stable.
If you're evaluating a first major deal for Snowflake, Databricks, dbt, Airflow, AWS, Azure, or BigQuery work, treat this as a procurement and operating manual, not a talent article.
## When should you choose augmentation over other delivery models?
Staff augmentation fits when you want to keep control of architecture and backlog but need outside specialists inside your team. Skip it when you need a vendor to own outcomes end to end - that's a [managed services](/insights/data-engineering-managed-services/) engagement, not augmentation.
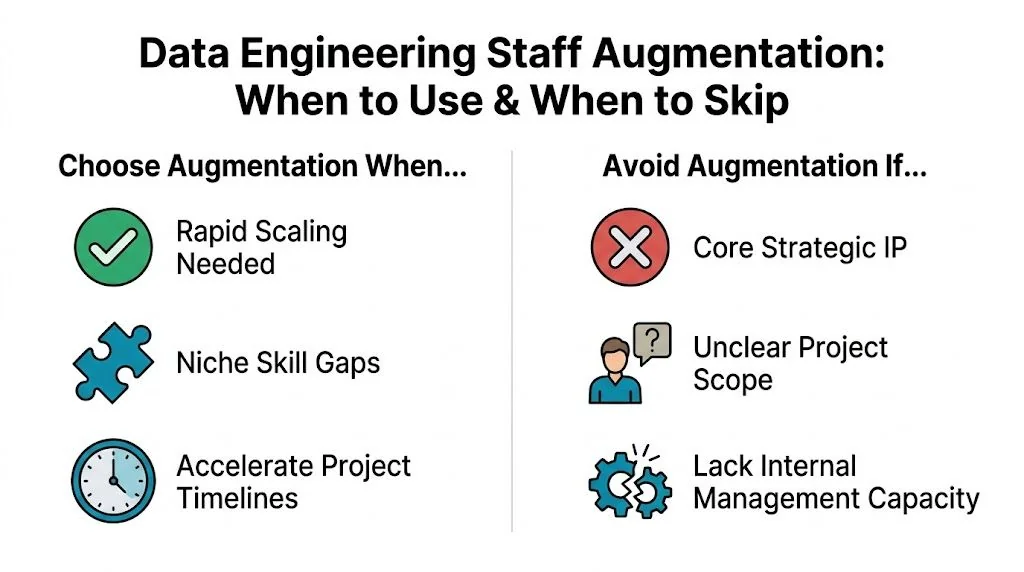
### Choose augmentation for deadline-bound specialist work
Data engineering staff augmentation fits well when the work is clear, the deadline is real, and your internal leaders still want design authority.
Good examples:
- **Snowflake or Databricks migration with a fixed target date**. You already know the platform, have an internal owner, and need engineers who've done warehouse migration, ELT refactoring, dbt modeling, and orchestration in Airflow.
- **Cloud modernization on AWS, Azure, or GCP**. Your platform team knows the security model and cost controls, but lacks enough hands with Terraform, data lake patterns, or warehouse-specific tuning.
- **Governance-heavy programs**. You need temporary expertise for cataloging, lineage, access policy implementation, or audit preparation, but not a permanent bench of governance specialists.
- **Backlog compression after architecture is set**. Your staff architect already chose the stack. Now you need execution capacity.
If you already have a competent head of data, platform lead, or principal architect, augmentation gives you speed without surrendering the steering wheel.
> **Practical rule:** If your team can write the first 20 tickets with clear acceptance criteria, augmentation is usually viable.
### Avoid augmentation when ownership is the real problem
A lot of leaders claim they need more capacity. What they actually lack is product direction, architectural ownership, or stakeholder alignment.
Don't use augmentation when:
- **The target state is undefined**. If you still haven't decided between Snowflake and Databricks, or whether dbt belongs in the stack, external engineers will amplify indecision.
- **The work includes core strategic IP that you won't expose**. If critical transformation logic, pricing models, or regulated decisioning systems can't be shared cleanly, the engagement will stall.
- **No internal manager can run the team**. Augmented engineers need a real counterpart. If nobody owns backlog, review standards, and business tradeoffs, buy a managed service instead.
- **You want a vendor to absorb delivery risk**. Augmentation gives you labor and expertise. It does not transfer accountability the way a managed delivery contract does.
Teams often confuse augmentation with outsourcing, or with the fractional-hire alternative. If your actual need is ongoing part-time senior coverage rather than a full embedded team, [fractional data engineering services](/insights/fractional-data-engineering-services/) is worth comparing before you write the RFP - and the broader [in-house vs. consulting](/insights/data-engineering-consulting-vs-in-house-team/) tradeoff is worth revisiting if you're not sure augmentation is the right model at all.
### Use this decision lens
Here's the simplest way to decide.
| Model | Best fit | Bad fit | Who owns delivery |
|---|---|---|---|
| **Staff augmentation** | Clear backlog, internal architecture control, short-to-midterm specialist need | Undefined scope, weak internal management | **You** |
| **Managed service** | Need outcome ownership, cross-functional execution, lower management burden | Team wants deep day-to-day control of individuals | **Vendor** |
| **Full-time hire** | Long-term platform ownership, stable recurring need, culture-sensitive roles | Urgent deadline or rare niche skill needed briefly | **You** |
### The test most buyers skip
Ask one uncomfortable question: **What happens after month six?**
If the answer is "they'll keep owning the platform," you probably don't want augmentation. That's a sign you need permanent hires or a managed model with explicit accountability. Augmentation works best as a force multiplier, not as a disguised replacement for internal leadership.
> Buy augmentation for execution under your system. Don't buy it to compensate for the absence of a system.
## What should your RFP force vendors to prove?
Most RFPs for data engineering staff augmentation ask for resumes, rate cards, and generic platform logos - which is how buyers end up choosing on price and regretting it later. The criterion that actually predicts success is embedded delivery fit: can this team work inside your standards, your reviews, and your incident process from week one.
### What your RFP must force vendors to prove
Based on the Data Engineering Companies Index's analysis of the 86 firms it profiles, the strongest evaluation process tests six things: platform depth, cloud implementation history, governance maturity, delivery integration, staffing realism, and commercial discipline.
If the vendor can't answer these cleanly, they're not ready for serious Snowflake, Databricks, dbt, Airflow, AWS, Azure, or BigQuery work.
| Evaluation Category | Criteria | What to Ask/Verify |
|---|---|---|
| **Platform expertise** | Hands-on delivery in Snowflake, Databricks, dbt, Airflow | Ask for named certifications, recent implementation examples, and who on the proposed team holds them |
| **Cloud infrastructure** | Depth in AWS, Azure, or GCP | Ask which cloud they've used for ingestion, orchestration, storage, IAM alignment, and observability |
| **Data architecture** | Pipeline design, medallion or warehouse patterns, transformation standards | Ask for a sample architecture decision log and how they choose between platform-native features and external tools |
| **Governance and security** | Access controls, lineage, audit readiness, data handling discipline | Ask how they work within your policies, who approves access, and what documentation they produce |
| **Industry context** | Experience in healthcare, fintech, retail, or enterprise environments | Ask for comparable environments, especially where data sensitivity or compliance shaped design choices |
| **Embedded delivery fit** | Ability to work as part of your team | Ask how they run standups, code reviews, incident response, and stakeholder communication |
| **Staffing model** | Seniority mix and replacement process | Ask who is actually assigned, who shadows them, and how quickly they replace a weak performer |
| **Commercial terms** | Rate transparency, ramp clauses, exit rights | Ask for notice periods, substitution terms, non-solicit language, and how unused capacity is handled |
### Don't ask for more case studies. Ask for operating evidence
Case studies are marketing. Delivery mechanics are real.
Your RFP should require responses to questions like these:
1. **Who will review pull requests in week one?**
If the answer is vague, they don't know how to embed.
2. **What artifacts do you produce during architecture work?**
You want decision logs, environment diagrams, lineage notes, test standards, and runbooks.
3. **How do you handle a mismatch between your preferred stack and ours?**
Good partners adapt. Bad ones try to smuggle in their house style.
4. **What's your replacement policy for an underperforming engineer?**
This needs a contractual answer, not a relationship answer.
5. **How do you work inside our governance model?**
This matters more than generic "security first" language.
For a structured starting point, [Data Engineering Vendor Evaluation Criteria](/insights/data-engineering-vendor-evaluation-criteria/) breaks these categories down further, and [Data Engineering Partner Selection](/insights/data-engineering-partner-selection/) covers how to weight them against each other.
### The shortlisting process I'd use
Use a three-stage filter.
#### Stage one screens for capability truth
Cut vendors that can't show direct work in your actual stack. If you're migrating to Snowflake with dbt and Airflow on AWS, don't entertain a generic "cloud and data" pitch. Ask for the exact mix.
#### Stage two screens for team realism
Interview the proposed architect and at least one proposed engineer. Not sales. Not an account lead. The actual people.
Probe for specifics:
- **dbt standards** such as model layering, testing habits, and CI expectations
- **Airflow discipline** around retries, idempotency, and ownership of failed jobs
- **Warehouse design** choices in Snowflake, Databricks, or BigQuery
- **Cloud controls** for IAM, secrets handling, and environment separation
#### Stage three screens for operating fit
Run a working session. Give them a sanitized problem from your environment. Ask how they would structure discovery, identify risk, sequence delivery, and communicate tradeoffs.
That will tell you more than ten reference calls.
> The vendor you want is the one that asks hard questions about your environment before talking about headcount.
For leaders building the process from scratch, the [RFP checklist](/data-engineering-rfp-checklist/) is a solid operational reference.
## How do you benchmark rates and size an augmented team?
Rates alone predict little about outcome quality - across the 86 firms in the index, hourly rates span $45-250 with a median near $100, and a cheap team with the wrong mix will burn more time in architecture churn and rework than it saves in hourly rate. Use rates as a screening tool, not as your decision model.
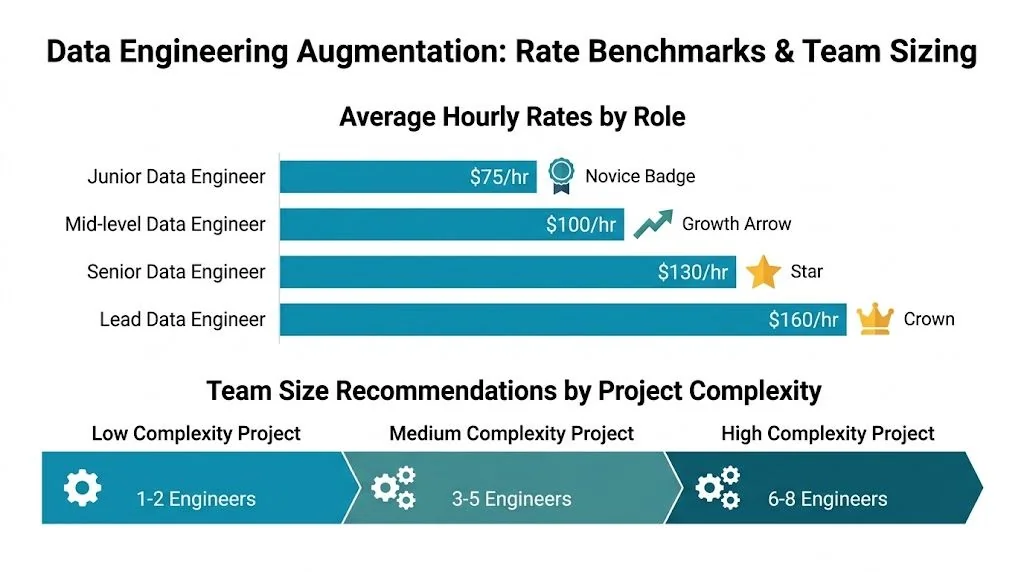
### What should drive budget
Start with these cost drivers:
- **Platform complexity**. Snowflake migration and optimization work prices differently from generic SQL pipeline maintenance. Databricks plus lakehouse design shifts the profile again.
- **Seniority concentration**. One strong architect and a few execution-focused engineers beats a team full of expensive generalists.
- **Governance load**. If the work involves access design, audit requirements, lineage, or regulated data handling, expect heavier senior oversight.
- **Time-zone overlap**. If your team insists on deep overlap for standups, reviews, and incident handling, you'll narrow the talent pool.
For a current market reference point, [data engineering consulting rates](/insights/data-engineering-consulting-rates-2026/) breaks rates down by seniority and platform in more detail.
### Team shapes that usually work
Don't start with a giant pod. Start with the minimum team that can own architecture, delivery, and handoff.
For a **warehouse modernization or migration**, aim for:
- **One lead architect or principal engineer** for target-state design, security alignment, and review standards
- **Two to four data engineers** for ingestion, transformation, testing, and orchestration
- **Optional analytics engineer** if dbt model quality and semantic consistency matter early
For a **governance-heavy platform hardening effort**:
- **One senior platform or data architect**
- **One or two engineers** focused on access patterns, lineage, policy implementation, and operational cleanup
- **Strong internal security or governance counterpart**, which cannot be outsourced in practice
For an **initial ML data foundation effort**:
- **One senior data engineer** who understands feature pipelines and production data quality
- **One engineer** for integration and orchestration
- **Internal ML owner** to define requirements and acceptance, because external engineers should not invent your model priorities
### What to challenge in vendor proposals
Push back when you see:
- **Too many leads**. You're funding meetings.
- **No architect at all**. Then your team is doing hidden architecture work anyway.
- **A giant first-month ramp**. That usually signals weak discovery discipline.
- **A fully offshore team for high-collaboration migration work** when your internal team is new to the platform.
## What does good onboarding for augmented engineers look like?
Most staff augmentation failures happen after signature, not before. The vendor sold capability; your operating model failed to absorb it. Onboarding is where that gap either closes or calcifies.
### Week one is about access and norms
In the first week, don't chase output. Chase friction removal.
Your augmented engineers need working access to Git, Jira, cloud consoles, warehouse environments, dbt repos, orchestration tooling, monitoring, and communication channels. They also need your standards in writing: branching model, PR expectations, naming conventions, incident rules, and what "done" means. This is also the point to apply least-privilege access design rather than granting broad permissions and tightening later - see AWS's own [IAM best practices](https://docs.aws.amazon.com/IAM/latest/UserGuide/best-practices.html) for the baseline pattern.
Use a checklist.
- **Tooling access**. Grant only the minimum necessary permissions, but grant them fast.
- **Architecture briefing**. Walk through sources, pipelines, warehouses, transformation layers, and known pain points.
- **Team rituals**. Explain standups, escalation paths, review etiquette, and response-time expectations.
- **Delivery scope**. Define what they own now, what they influence, and what stays internal.
> If an engineer spends the first five business days waiting for permissions, that's your failure, not theirs.
### Week two is about productive integration
By week two, they should be inside the actual work, not in a sandbox forever.
Good onboarding means they take on contained tasks that expose the core system: one ingestion path, one dbt model family, one Airflow DAG group, one warehouse optimization issue. You want them learning your environment while shipping useful work. A good manager also pairs them with internal peers for code review and design discussion, which cuts the "external team" dynamic before it starts.
This walkthrough is worth sharing with internal managers before kickoff:
### The first 30 days need visible operating rhythm
By day 30, you should see four things:
1. **The team works in the same backlog and sprint rhythm**
2. **PRs follow internal standards without constant correction**
3. **Architecture decisions are documented, not trapped in calls**
4. **Leads can name delivery risks without asking the vendor to summarize reality**
Use a simple cadence:
- **Daily** for engineering sync
- **Weekly** for stakeholder review and risk log
- **Biweekly** for architecture and governance review
- **Monthly** for commercial and performance review
Don't let the vendor run a parallel reporting system. One team, one board, one definition of status.
## What KPIs and contract clauses actually protect you?
Data engineering staff augmentation touches architecture, access, infrastructure, and business-critical data flows, so weak oversight becomes operational risk fast. If you can't govern the engagement, don't start it.
Integration delays and compliance gaps are a common failure mode on augmented teams, particularly when access controls and review standards aren't defined before the engineer's first commit. Platform-native governance tooling - Snowflake's [access control model](https://docs.snowflake.com/en/user-guide/security-access-control-overview) and Databricks' [Unity Catalog](https://docs.databricks.com/en/data-governance/unity-catalog/index.html) - exists specifically to make that risk visible instead of implicit, and both should be part of week-one onboarding, not a month-three retrofit.
### Track operational value, not just activity
Story points are not governance. Hours billed are not governance. Track indicators that tell you whether the team is improving the platform you run.
Monitor:
- **Pipeline reliability**. Are scheduled runs stable, recoverable, and understood?
- **Change failure pattern**. Which releases break pipelines, models, or permissions?
- **Review quality**. How many PRs need rework for standards, test coverage, or architectural mismatch? [dbt's built-in test framework](https://docs.getdbt.com/docs/build/data-tests) is a reasonable baseline for what "tested" should mean before a PR merges.
- **Documentation completeness**. Are runbooks, lineage notes, and decision records being produced as work happens?
- **Knowledge transfer evidence**. Can your internal team operate what the vendor built?
Use a monthly scorecard, but keep it operational. If a metric doesn't drive a management action, drop it.
### Contract clauses that separate good deals from bad ones
A proper SOW for data engineering work needs more than rate cards and names. [Data Engineering Statement of Work](/insights/data-engineering-statement-of-work/) covers the full clause set; the ones that matter most here are non-negotiable:
- **IP assignment**. All code, models, documentation, workflows, and architecture artifacts produced under the engagement belong to you.
- **Data handling rules**. Spell out access boundaries, storage restrictions, logging expectations, and approved tools.
- **Named resources and substitution limits**. Don't let the vendor swap people casually.
- **Right to replace**. You need a clean path to remove a weak engineer quickly.
- **Documentation obligations**. Tie payment or milestone acceptance to artifacts, not just labor.
- **Exit support**. Require structured handoff, repo hygiene, and transition assistance.
> **Contract rule:** If knowledge transfer is not written into the SOW, it will be postponed until the last week, then done badly.
### The red flags to treat seriously
Walk away if you hear any of these:
- "We'll adapt governance as we go."
- "Our senior architect can float across multiple clients."
- "We usually use our own internal tooling for visibility."
- "Let's finalize replacement terms later."
- "Access can be broad at first and tightened later."
That language tells you the vendor wants convenience. You need control. [Vendor Management Best Practices](/insights/vendor-management-best-practices/) covers how to enforce that control once the contract is signed.
## Turning augmentation into a permanent capability gain
The right outcome isn't a long vendor dependency. It's a stronger internal data engineering function.
Use external specialists to accelerate a migration, harden governance, stand up dbt standards, or modernize orchestration. Then convert what they built into internal capability: named internal owners, shadowing during delivery, architecture records that survive turnover, and explicit handoff checkpoints before the contract ends.
If you're starting this process this week, take three actions:
1. **Decide the model objectively**. If you need ownership, buy managed delivery. If you need execution under your direction, buy augmentation.
2. **Rewrite the RFP around embedded delivery fit**. Force vendors to prove they can work inside your stack, cloud, and governance model.
3. **Lock in onboarding and exit terms before signature**. Most pain comes from weak integration and weak handoff, not weak resumes.
Compare firms by platform, industry, capabilities, and commercial fit in the [Data Engineering Companies Index](/data-engineering-consulting-firms/), then use the [RFP checklist](/data-engineering-rfp-checklist/) to pressure-test your shortlist before you sign.
---
## Mastering the Data Engineering Statement of Work
Source: https://dataengineeringcompanies.com/insights/data-engineering-statement-of-work/
Published: 2026-02-26T06:54:54.629357+00:00
Description: Craft a bulletproof data engineering statement of work. Our guide offers actionable clauses, pricing models, and a template to keep your data projects on track.
A data engineering Statement of Work (SOW) is the contract that defines deliverables, timelines, technical specifications, and acceptance criteria for a project - the single document both sides point to when something goes wrong. A vague SOW is the most common cause of scope creep and budget overruns in data engineering work; a specific one is what keeps a migration or pipeline build on schedule and on budget.
This guide breaks down the four clauses that make an SOW enforceable - objectives, deliverables, technical specs, and acceptance criteria - plus the commercial terms that come with them. Rates are one of the most contested parts of that negotiation: across the 86 firms profiled in the [Data Engineering Companies Index](/insights/data-engineering-consulting-rates-2026/), hourly rates for data engineering work range from $45 to $250, with a median around $100 - a spread worth knowing before you negotiate a rate card into your SOW.
## Why does a vague SOW guarantee project failure?
A vague SOW is the primary point of failure in data engineering initiatives, because it lets the client and vendor walk into the engagement with two different definitions of "done." That gap surfaces mid-project, when it's most expensive to fix.
It's not a bureaucratic formality - it's the foundation of the client-vendor relationship. If that foundation is weak, the project is compromised from the start, particularly for complex efforts like a cloud migration to platforms such as [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/).
The consequences of ambiguity are concrete, not theoretical. Consider an SOW that specifies "data transformation logic" without defining the rules: the client expects complex business aggregations, the vendor delivers basic data cleansing. That single point of ambiguity can trigger weeks of rework, blow deadlines, and stall the AI initiatives waiting on that data.
### What does ambiguity actually cost you?
Budget overruns tied to poorly scoped work are common enough in data engineering contracts to be a known risk category, not an edge case - and the exposure is worse in cloud migration projects, where unforeseen costs compound quickly once a team is mid-build.
Operationally, the lack of defined benchmarks creates chaos, a challenge that [BI consulting services](/insights/bi-consulting-services/) help organizations work through. A deliverable like a "real-time analytics dashboard" is meaningless without a specific Service Level Agreement (SLA) for data latency: to the client, "real-time" might mean sub-five-second latency; to the vendor, it could mean five minutes. Without a quantifiable metric, the project stalls on subjective arguments.
> A well-crafted SOW forces critical conversations upfront. It moves key decisions from the reactive, high-pressure environment of an active project to the strategic, low-pressure planning phase where they belong.
### How do you turn the SOW into a strategic blueprint?
For a CIO or Head of Data focused on ROI in [Enterprise Data Engineering](/enterprise-data-engineering/), the SOW is a primary risk mitigation tool - not a contract addendum to skim before signing.
To get there, the SOW must specify:
* **Data Sources:** Exactly which tables, APIs, or event streams are in scope? Name them.
* **Transformation Logic:** What are the specific business rules, joins, and aggregations required? Document them.
* **Performance Benchmarks:** What are the quantifiable metrics for pipeline speed and data freshness? Define them.
* **Deliverables:** What are the tangible outcomes? Define them clearly, beyond high-level activities.
Before we get into each section, this table summarizes the core components of a data engineering SOW.
### Essential SOW Components at a Glance
| SOW Section | Primary Goal | Key Information to Include |
| :--- | :--- | :--- |
| **Project Overview** | Align on the "why" | Business problem, project goals, high-level objectives. |
| **Scope of Work** | Define the "what" | In-scope/out-of-scope activities, specific deliverables. |
| **Technical Specs** | Detail the "how" | Data sources, transformation rules, target architecture. |
| **Acceptance Criteria** | Clarify "done" | Measurable criteria for sign-off on each deliverable. |
| **Pricing & Payment** | Agree on the "cost" | Pricing model (T&M, Fixed), payment schedule, rates. |
| **SLAs & Support** | Guarantee "performance" | Uptime guarantees, data latency targets, support hours. |
Getting these core elements right isn't optional.
A data engineering project's technical specifications should build in [data integration best practices](/insights/data-integration-best-practices/) from the start, not add them after the SOW is signed. Treat the SOW as the primary tool for ensuring project success, and the rest of this guide gets specific about how.
## Which SOW clauses actually prevent project failure?
Four clauses turn a Statement of Work from a wish list into an enforceable contract: project objectives, deliverables mapped to milestones, technical specifications, and a RACI matrix for roles. Each one closes a specific gap where miscommunication tends to happen.
This is where business requirements become technical and operational specifications that prevent misunderstandings and scope creep.
The path from a vague SOW to execution is predictably costly. Ambiguity in the initial document sets the stage for project failure.
As illustrated, ambiguity isn't a minor issue - it's the root cause of project dysfunction that destroys return on investment.
### What makes a project objective enforceable?
The Project Objectives section establishes the "why." It has to state the business problem and the quantifiable future state - not vague goals like "improve data access" or "modernize the data platform."
For instance, a weak objective states: "Migrate the on-premise data warehouse to the cloud."
A strong, actionable objective is specific: "**The primary objective is to migrate the legacy SQL Server data warehouse to a new Snowflake environment on AWS. This migration aims to reduce query latency for the 'Executive Sales Dashboard' from an average of 90 seconds to under 5 seconds and decrease monthly data infrastructure costs by at least 15% within the first quarter post-launch.**"
This version provides a clear target. It defines success by linking technical work directly to measurable performance and financial outcomes.
### How do you map deliverables to milestones and payments?
This clause breaks the project into tangible outputs (deliverables) linked to specific checkpoints (milestones) that trigger payments - so you pay for verified progress, not just effort.
Every deliverable should be a noun - a report, a configured pipeline, a deployed data model. Verbs like "analyzing" or "developing" describe activities, not deliverables, and shouldn't be used as one.
Here's a practical breakdown for a new ETL pipeline project:
* **Milestone 1: Discovery & Architecture Sign-off**
* **Deliverable:** A detailed Technical Design Document outlining data sources, transformation logic for the top 5 critical entities, target schema in [Databricks](https://www.databricks.com/) Delta Lake, and a data validation strategy.
* **Payment:** 15% of total project cost upon client approval.
* **Milestone 2: Core Pipeline Development & Unit Testing**
* **Deliverable:** Deployed ingestion pipelines for [Salesforce](https://www.salesforce.com/) and [Marketo](https://nation.marketo.com/) data into the bronze layer. Deployed dbt models for transforming this data into the silver layer. A report showing unit test coverage of **at least 85%** for all transformation logic.
* **Payment:** 40% of total project cost upon successful test report review.
* **Milestone 3: UAT & Production Deployment**
* **Deliverable:** Successful completion of User Acceptance Testing (UAT) with no more than 2 high-priority bugs outstanding. The full pipeline is deployed to the production environment and has run successfully for **5 consecutive business days**.
* **Payment:** 45% of total project cost upon successful production run confirmation.
This approach creates a logical, defensible flow where payments are tied directly to working, tested components.
> The single most effective way to de-risk a data engineering project is to link every payment to a physically demonstrable and pre-approved deliverable. If it can't be tested or verified, it shouldn't be paid for yet.
### How detailed do the technical specifications need to be?
Ambiguous technical specifications are a primary source of conflict. This section has to be detailed enough that no one has to guess about the technology stack, versions, or environments.
Assume no prior knowledge of your environment. Be explicit.
**Essential Technical Specifications to Include:**
* **Cloud Platform and Region:** Specify the provider and the exact region (e.g., [Google Cloud Platform](https://cloud.google.com/), `us-central1`). This impacts latency, data sovereignty, and cost.
* **Core Technologies:** List the primary tools and their required versions. For example: "The solution will be built using Databricks Runtime 14.3 LTS, with all transformation logic managed in [dbt Core](https://www.getdbt.com/) v1.8. All orchestration will be handled by [Airflow](https://airflow.apache.org/) 2.9."
* **Source Systems:** Explicitly list every data source in scope. Include API endpoints, database names, and required authentication methods. For example: "[Salesforce](https://www.salesforce.com/) source data will be extracted via the Bulk API 2.0. The Oracle ERP connection will use a dedicated read-only replica database."
* **Coding and Style Guides:** If you have internal standards, reference them directly. "All Python code must adhere to PEP 8 standards and include type hinting. All SQL transformations within dbt models must follow the established company style guide."
This level of detail preempts debates about tooling and makes sure the final product integrates with your existing ecosystem.
### How do you assign roles and responsibilities with a RACI matrix?
A project can fail despite clear objectives and a solid technical plan if roles are undefined. A RACI matrix is the most effective tool for fixing that - it maps ownership for every major task.
RACI stands for **R**esponsible, **A**ccountable, **C**onsulted, and **I**nformed.
Here's a sample RACI for a data warehouse modernization project:
| Task / Deliverable | Data Engineering Vendor | Client Project Manager | Client Data Architect | Client Business Analyst |
| :--- | :--- | :--- | :--- | :--- |
| **Define Business Requirements** | C | A | C | R |
| **Draft Technical Design Doc** | R | I | A | C |
| **Approve Technical Design** | I | C | A | I |
| **Develop ETL Pipelines** | R | I | C | I |
| **Perform User Acceptance Testing** | C | A | I | R |
| **Final Production Sign-off** | I | A | R | I |
This chart eliminates ambiguity. It's immediately clear that while the vendor is Responsible for development, the client's Data Architect is ultimately Accountable for the design - a distinction that matters when something goes wrong and someone has to own the fix.
## What makes acceptance criteria actually work?
Acceptance criteria work when every one is SMART - specific, measurable, achievable, relevant, and time-bound - so "done" is something both sides can verify with a number, not argue about after the fact.
This section is where project success gets formally verified. Vague acceptance criteria are a leading cause of project disputes; this part of the SOW is the final quality gate, converting subjective sign-offs into objective, provable benchmarks.
Without it, "done" stays subjective, and disputes follow.
### How do you turn vague hopes into SMART criteria?
Criteria like "the pipeline should be fast" or "the dashboard needs to be accurate" are unenforceable wishes. Every criterion needs to be SMART: Specific, Measurable, Achievable, Relevant, and Time-bound.
Let's use our data platform migration example.
**A vague (and useless) criterion:** The daily sales ingestion pipeline should be fast and reliable.
**A SMART (and enforceable) criterion:** The daily sales ingestion pipeline from [Salesforce](https://www.salesforce.com/) to [Snowflake](https://www.snowflake.com/) must complete its full run in under **60 minutes**, starting between 2 AM and 3 AM UTC. It must successfully process a minimum of **1 million records** with a data quality error rate below **0.1%**, as verified by the project's data validation framework.
The second version is contractual. It defines "fast" (under 60 minutes) and "reliable" (error rate below 0.1%) within a specific operational context - there's no room for interpretation.
### What testing types belong in a data engineering SOW?
A strong SOW specifies *how* deliverables will be verified, by mandating specific test types that must pass before milestone sign-off. For data engineering, that means three core validation layers.
* **Unit Tests for Transformation Logic:** These tests isolate and verify the smallest code components, typically individual [dbt](https://www.getdbt.com/) models or Python functions. The SOW should mandate minimum code coverage. For example: "All SQL and Python transformation models must achieve **at least 85% unit test coverage**, validating critical business logic for calculations like Gross Margin and Customer LTV."
* **Integration Tests for Pipelines:** These tests verify that components work together. The entire pipeline runs, from source to target, with a representative dataset to check data flow, schema integrity, and system handoffs. A valid criterion is: "The end-to-end pipeline must execute successfully using the provided staging dataset, with source record counts matching target record counts within a **0.05% tolerance**."
* **User Acceptance Testing (UAT) for Dashboards:** This is the final validation by business users. They use the output, typically a BI dashboard, to confirm it meets their requirements. Criteria must be tied to business scenarios. For instance: "The 'Executive Sales Dashboard' in [Tableau](https://www.tableau.com/) must correctly display Q4 sales figures that reconcile with the legacy financial report, with a variance of no more than **$100**."
This layered approach acts as a safety net, catching issues early - from bugs in individual functions to inaccuracies in executive-level reporting. For a deeper walkthrough of building this into your pipeline, see [data pipeline testing best practices](/insights/data-pipeline-testing-best-practices/).
> A data engineering statement of work without measurable acceptance criteria is just a wish list. It lacks the teeth needed to hold your vendor accountable for delivering a solution that performs under real-world conditions.
### How do you quantify performance and scalability requirements?
Performance isn't just about speed - it's about stability under increasing load. The SOW needs to define how the system should behave as data volumes grow, because scalability is a requirement teams skip more often than they expect: an SOW that specifies a throughput target but never defines the load-testing scenario tends to need rework once real production volumes hit. Build future-state load scenarios into your acceptance criteria to catch this before launch, not after.
Here's how to define scalability in your SOW:
**Performance Under Load Test:**
"The system must demonstrate the ability to process a peak load of **5 million records** (simulating end-of-quarter volume) within a **90-minute** processing window. During this test, CPU utilization on the primary [Snowflake](https://www.snowflake.com/) warehouse must not exceed **80%** for more than 10 consecutive minutes."
This criterion works because it sets a clear performance benchmark under stress while also specifying resource constraints. That stops a vendor from hitting the target by throwing excessive, costly compute at the problem, so the solution stays functional and economically viable at scale.
## How do you nail down pricing, rates, and SLAs?
Pricing model, rate transparency, and enforceable SLAs are the three commercial terms that determine whether an SOW protects your budget or exposes it - get any one wrong and the technical scope stops mattering.
Selecting the right pricing model and defining service levels matters as much as the technical scope. These commercial terms set the financial rules of the engagement and are foundational to the client-vendor relationship.
Structuring the commercials incorrectly leads to budget overruns and misaligned incentives. The goal is to protect your investment and incentivize the outcomes you actually want.
### Which pricing model fits your project?
The optimal pricing model depends on how clearly the project scope is defined. The commercial structure has to match the level of uncertainty.
The goal is to balance risk fairly between you and the vendor. The three common models are:
#### Pricing Model Comparison for Data Projects
| Pricing Model | Best For | Pros | Cons |
| :--- | :--- | :--- | :--- |
| **Fixed Price** | Well-defined projects with zero ambiguity, like a lift-and-shift migration of **10** specific pipelines. | Predictable budget; vendor assumes risk for time overruns. | Inflexible. Any change requires a formal and often expensive change order. Can incentivize vendors to cut corners to protect margins. |
| **Time & Materials (T&M)** | Exploratory or agile projects with evolving requirements, like building a new ML feature platform. | Maximum flexibility to adapt. You pay only for actual effort. | Budget risk is entirely on the client. Requires tight project management to control scope creep. |
| **Retainer** | Ongoing operational support, maintenance, and continuous improvement for an existing data platform. | Guaranteed access to a dedicated team; predictable monthly cost for operations. | Can be inefficient if workload is inconsistent. You pay for team availability, not just output, which can be costly during lulls. |
For most complex data modernizations, a hybrid approach works best: a Fixed Price engagement for an initial discovery and architectural design phase, then a shift to a T&M model once the scope is clearly defined for core development sprints.
For a more detailed breakdown, see [Fixed Price vs. Time and Materials contracts](/insights/fixed-price-vs-time-and-materials/).
### What do data engineering rates actually look like?
Effective negotiation starts with a real baseline, not a vendor's asking price. Across the 86 firms profiled in the [Data Engineering Companies Index](/insights/data-engineering-consulting-rates-2026/), hourly rates for data engineering work run $45 to $250, with a median around $100/hour: 35 of those firms bill under $100/hour, 44 sit in the $100-200 band, and 7 charge $200 or more, generally the specialized boutiques and platform-certified architects staffing complex Snowflake or Databricks builds.
For major platform builds on [Snowflake](https://www.snowflake.com/) or [Databricks](https://www.databricks.com/), that baseline is a starting point, not the whole picture. Ask for an explicit rate card broken down by role, a verified team composition, and proof of platform certifications before you sign - a vendor quoting a single blended rate for the whole engagement is a sign the SOW needs more detail, not less.
> A vendor's refusal to provide a transparent rate card is a real red flag. It hides true costs and makes it hard to verify you're getting the senior-level talent you were promised.
### What makes an SLA actually enforceable?
A Service Level Agreement (SLA) is your project's insurance policy: a business contract, not a technical wish list, that makes sure the platform performs to an agreed-upon standard. Generic SLAs don't work; they have to be specific, measurable, and tied to financial penalties.
Focus on metrics that directly impact business operations:
* **Data Pipeline Uptime:** Define this precisely. A target of **99.9% uptime** monthly is standard, but you must define "downtime." Is it a single failed run or a delay beyond a specific time window?
* **Data Latency/Freshness:** This is critical for analytics teams. Specify the maximum acceptable delay from source to target. Example: "Data from Salesforce opportunities must be queryable in Snowflake **within 15 minutes** of creation or update."
* **Issue Resolution Time:** Define tiers based on severity with firm deadlines.
* **Severity 1 (Critical Outage):** Acknowledgment < 30 minutes; Resolution < 4 hours.
* **Severity 2 (Degraded Performance):** Acknowledgment < 2 hours; Resolution < 8 business hours.
Finally, attach consequences to SLAs. A "service credit" clause is the most effective enforcement mechanism: if an SLA is missed, the vendor issues a credit (for example, **5%** of the monthly fee) on the next invoice. That's what gives the vendor an actual financial incentive to hit the standard, not just a reason to apologize for missing it.
## What are the most common SOW pitfalls and vendor red flags?
Four patterns account for most SOW-related disputes: scope creep disguised as "agile," vague staffing promises, no formal change control process, and security and compliance treated as an afterthought. Each has a specific fix.
A data engineering Statement of Work can look solid on paper and still conceal real risk. Catching these issues before signing is what keeps them from becoming costly disputes later.
These aren't minor oversights - they're foundational cracks. Mismatched vendor capabilities are one of the more common reasons a data engineering engagement runs over budget, once the gap between the sales pitch and the delivery team becomes obvious. For more on what's driving demand and vendor selection pressure in this market, see [the big data engineering service market](https://www.marketresearchfuture.com/reports/big-data-engineering-service-market-28677).
### How does "agile" language hide scope creep?
A common tactic is using "agile collaboration" to justify an undefined scope. Agile development itself works fine; in an SOW, it can become a vehicle for uncontrolled scope creep.
* **The Red Flag:** The scope section contains vague verbs like "discover," "explore," or "iterate" without being linked to specific, time-boxed deliverables. Language about "flexible backlogs" appears without a clear process for pricing and prioritizing new items.
* **What to Do Instead:** Mandate a hybrid model. The SOW must define a core set of non-negotiable deliverables for a fixed price. Exploratory work outside that scope should be managed in distinct sprints with separate budgets and a formal approval process.
### What's wrong with vague resource commitments?
Another major red flag is ambiguous language about project staffing. A promise of senior talent means nothing without a contractual guarantee.
> A vendor's "A-team" often appears during the sales process, only to be replaced by a more junior team post-contract. The SOW is the only tool to prevent this bait-and-switch.
Here is a common example:
* **The Red Flag:** The SOW states you will have "access to senior architects" or be supported by a "team of experienced engineers." These subjective phrases are legally unenforceable.
* **What to Do Instead:** Insist on a "Key Personnel" clause. This section must name the specific individuals (e.g., Lead Architect, Senior Engineer) assigned to the project. Critically, it must also state that the vendor cannot reassign these individuals without your explicit written consent. This is non-negotiable.
### Why does an SOW need a formal change control process?
No project proceeds exactly as planned. New data sources emerge, priorities shift, and requirements evolve. An SOW lacking a formal change control process is a recipe for conflict, turning every minor adjustment into a major dispute.
Without this process, you are vulnerable to informal agreements that reappear as surprise invoices.
**A Strong Change Control Clause Includes:**
1. **A Formal Change Request Form:** Specifies required information (description, business justification, impact analysis).
2. **A Clear Approval Workflow:** Defines who from each team must sign off *before* work begins.
3. **Impact Assessment:** Mandates a written assessment from the vendor on how the change affects the project's timeline, budget, and other deliverables.
This structured process removes emotion and ambiguity from change management, turning potential arguments into standard business decisions. For a broader framework, see [vendor management best practices](/insights/vendor-management-best-practices/), and for evaluating vendors before you sign, our guide on [how to evaluate data engineering vendors](/insights/data-engineering-vendor-evaluation-criteria/).
### What happens when security and compliance become an afterthought?
In 2025, data security is a core requirement, not an afterthought. Many SOWs gloss over this with a generic sentence like, "Vendor will adhere to industry best practices."
That's insufficient, especially when dealing with data subject to regulations like [GDPR](https://gdpr-info.eu/), CCPA, or [HIPAA](https://www.hhs.gov/hipaa/index.html).
* **The Red Flag:** The SOW lacks a dedicated section for security and compliance. There is no mention of specific regulations, data handling protocols, encryption standards, or access control policies.
* **What to Do Instead:** The SOW must be explicit. It should reference applicable regulations (e.g., "All data processing must be GDPR-compliant"). It must also detail technical requirements, such as "All data at rest must be encrypted using AES-256" and "Access to production data will be restricted to named individuals via role-based access control." Platforms like Snowflake and [Databricks Unity Catalog](https://docs.databricks.com/en/data-governance/unity-catalog/index.html) ship native controls for this - name them in the SOW rather than leaving the implementation up to the vendor.
## What belongs in your SOW template and pre-signature checklist?
A complete SOW template bundles these clauses - SMART objectives, noun-based deliverables, quantified acceptance criteria, named key personnel, change control, and SLAs with teeth - into one document, plus a final checklist to run before anyone signs.
To make this practical, we've bundled these principles into a downloadable, editable data engineering Statement of Work template. It includes annotations explaining the purpose of each clause and prompts to guide you, with specific notes for projects on platforms like Snowflake, Databricks, AWS, or GCP.
### Your Pre-Signature SOW Checklist
Before signing, perform a final review using this checklist. It can catch ambiguous language before it becomes a contractual issue.
* **Are the Objectives SMART?** Ensure every goal is Specific, Measurable, Achievable, Relevant, and Time-bound.
* **Are Deliverables Nouns, Not Verbs?** Every deliverable must be a tangible output ("Technical Design Document," "Deployed Data Pipeline"), not an activity ("Analyzing," "Developing").
* **Is Acceptance Criteria Quantified?** Every deliverable needs hard numbers defining success: performance benchmarks, data quality thresholds, and specific functional tests.
* **Are Key People Named?** The SOW must list the lead architect and senior engineers by name and require your written approval for any changes.
* **Is Change Control Spelled Out?** There must be a formal process for requesting, estimating, and approving changes.
* **Do SLAs Have Teeth?** SLAs for uptime or support must be tied to financial credits or penalties for non-compliance.
> The strength of your SOW directly correlates to the predictability of your project's outcome. A few hours spent clarifying these details upfront will save you weeks of disputes and rework down the line.
For those in the vendor selection phase, our guide on [creating a data engineering RFP](/data-engineering-rfp-checklist/) is also a valuable resource.
## Frequently Asked Questions
A well-constructed Statement of Work ensures alignment from day one. Here are answers to common questions that arise during its creation.
### What's the Real Difference Between an SOW and a Contract?
The Statement of Work (SOW) is the project's technical blueprint - the "what." It details the specific tasks, deliverables, timelines, and specifications.
The contract is the legal framework - the "how." It's the legally binding agreement that incorporates the SOW by reference and includes broader terms like payment conditions, liability, confidentiality, and intellectual property ownership. The SOW defines what to build; the contract ensures it gets paid for and outlines legal recourse.
### Just How Detailed Does a Data Engineering SOW Need to Be?
It must be specific enough to eliminate misinterpretation. Any ambiguity will be interpreted differently by each party.
This means providing granular detail. A data engineer with no prior context should be able to understand precisely what to build from the SOW alone. This requires naming specific data sources, defining transformation logic, detailing target data schemas, and listing the full tech stack, including [Python](https://www.python.org/) versions or the structure of [dbt](https://www.getdbt.com/) models. Performance KPIs are also essential.
### Who Actually Writes the SOW?
Drafting an SOW is a collaborative process.
Typically, the client initiates by defining the business objectives and success criteria. The vendor then drafts the document, translating those needs into a technical approach, resource plan, and timeline. The client's technical leads, project managers, and legal team must then review it in detail. It is an iterative process of negotiation and refinement until both parties are in full agreement.
Precision matters at this scale: the global market for these services is large and growing quickly, so ambiguity is a cost, not a formality.
---
Finding the right partner is the first step to a successful project. At **DataEngineeringCompanies.com**, we profile 86 data engineering firms with verified rates and capabilities, so you can build your shortlist from real data instead of a sales pitch.
[Find your ideal data engineering partner today.](https://dataengineeringcompanies.com)
---
## Data Engineering Vendor Evaluation Criteria: 35 Criteria for 2026
Source: https://dataengineeringcompanies.com/insights/data-engineering-vendor-evaluation-criteria/
Published: 2026-05-29T08:00:00.000Z
Description: The complete 35-criterion evaluation framework for choosing a data engineering vendor in 2026 - definitions, verification, red flags, and weighting.
Most vendor evaluation guides give you a framework. This one gives you the criteria - 35 of them, with definitions, verification sources, red flags, and suggested weights, organized into seven groups.
The difference matters. This article is the reference you pull up when you need to know exactly _what_ criterion 3.3 means, how to test it, and what a failing response looks like - and it now folds in the scoring mechanics and the discovery-call question set, so the full evaluation lives in one place.
The spread this framework has to sort through is real: rates across the [86 firms in the Data Engineering Companies Index](/data-engineering-consulting-firms/) run from $45 to $250 an hour, with a median around $100. A vendor at the top of that range and one at the bottom can both look qualified on a website. The 35 criteria below are how you tell them apart before signing anything.
It is a procurement reference. Use it that way.
## What can be the criteria for vendor evaluation in 2026?
That question has a 2024 answer and a 2026 answer, and they are not the same.
In 2024, a reasonable data engineering vendor evaluation covered platform credentials, delivery process, team quality, contract terms, and basic security posture. AI/ML readiness was a soft plus - nice if present, not a disqualifier if absent.
In 2026, that changed. Three forces converged:
**EU AI Act enforcement** (full compliance required by August 2026 under [Regulation EU 2024/1689](https://artificialintelligenceact.eu/)) moved vendor AI risk management from a contractual afterthought to a legal requirement for any engagement touching EU data subjects.
**Warehouse-native AI** matured. Snowflake Cortex and Databricks Mosaic AI are now primary feature vectors - not experimental add-ons. A vendor who cannot articulate the trade-offs between the two cannot credibly architect a forward-looking platform.
**Agentic pipelines** entered production. LangGraph, CrewAI, and similar orchestration layers are running in live data platforms. Vendors without hands-on experience are not missing a nice-to-have; they are missing the direction the work is going.
The result: AI/ML Readiness is now a top-level evaluation group, not a sub-criterion buried under Innovation. That is the defining shift from 2024 to 2026 frameworks.
The 35 criteria below are organized into seven groups:
Each criterion below has four fields: what it measures, how to verify it (not trust it), the red flag that tells you the vendor is weak on it, and a suggested percentage weight within its group. The group weights and how to apply them across project archetypes are covered in the weighting section.
## How is data engineering vendor evaluation different from generic IT vendor evaluation?
Generic IT evaluation criteria - responsiveness, SLA adherence, security posture, commercial flexibility - are not wrong. They are just incomplete for data work.
Three gaps matter most:
**Platform fidelity is binary in data engineering.** A consultancy either knows Snowflake's workload isolation and Cortex well enough to make production-grade decisions or it doesn't. There is no "good enough" equivalent to being a Snowflake Elite partner with named certified architects. Generic IT evaluations collapse this distinction into a single "technical expertise" score.
**Data quality is operationally fragile in a way most IT deliverables are not.** A misconfigured API or a slow application can be patched at runtime. A broken data pipeline silently delivers wrong numbers to executives, finance models, and machine learning features - often for weeks before anyone notices. This makes observability maturity a first-class criterion that generic IT evaluations ignore entirely.
**Handoff quality determines whether the engagement has a business outcome.** Code delivered without documented lineage, without runbooks, without reproducible environment definitions, is a liability handed to the client. Generic IT evaluations lightly score "documentation." Data engineering evaluations should treat it as a proxy for everything the vendor understands about operational maintenance.
The 35 criteria below reflect these differences. They do not replace generic IT vendor evaluation - they extend it.
## What are the 7 groups of vendor evaluation criteria for data engineering?
Before the detailed tables, a one-line description of each group:
| Group | Focus | Criteria |
|---|---|---|
| G1: Platform Fidelity | Depth of partnership and hands-on mastery of specific tools | 1.1-1.5 |
| G2: Delivery Maturity | How they build, test, promote, and observe data products | 2.1-2.5 |
| G3: AI/ML Readiness 2026 | Warehouse-native AI, agents, EU AI Act compliance | 3.1-3.5 |
| G4: Industry Fit | Vertical knowledge, regulatory fluency, domain-specific SLAs | 4.1-4.5 |
| G5: Commercial Hygiene | Contract structure, IP ownership, off-ramp protections | 5.1-5.5 |
| G6: Team & Talent | Named team policy, retention, subcontractor transparency | 6.1-6.5 |
| G7: Continuity & Risk | Financial stability, BCDR, cyber posture, exit readiness | 7.1-7.5 |
Below are the full tables for each group. Then a measurement-source map, a weighting section for three project archetypes, and the 35-item checklist.
---
## Group 1: Platform Fidelity (5 criteria)
Platform fidelity is the most verifiable cluster in the evaluation. Partner tiers, certified engineer counts, and published reference architectures are public or auditable. There is no excuse for taking vendor claims at face value here.
| Criterion | Definition | How to verify | Red flag | Suggested weight in group |
|---|---|---|---|---|
| **1.1 Partner tier** (Snowflake / Databricks / dbt) | Official partnership classification: Snowflake Elite, Premier, or Registered; Databricks SI Premier or Registered; dbt Labs partner status | Check directly against [Snowflake partner directory](https://www.snowflake.com/partners/), [Databricks partner listings](https://www.databricks.com/company/partners), and [dbt Labs partner directory](https://www.getdbt.com/partners). Do not accept screenshots. | Claims "Snowflake partner" but cannot confirm tier; or tier is Registered not Elite/Premier for a complex project | 30% |
| **1.2 Named certified engineers** | Actual count of Snowflake SnowPro Advanced, Databricks Certified, or dbt-certified engineers assigned to your engagement - not total headcount across the firm | Request names and certification IDs. Validate via Snowflake/Databricks certification lookup portals. | "We have 40 Snowflake-certified engineers" with no ability to name any assigned to your project | 25% |
| **1.3 Cortex AI / Mosaic AI hands-on (2026)** | Demonstrated production use of warehouse-native LLM features: Snowflake Cortex Analyst, Cortex Search, or Databricks Mosaic AI in a live client environment - not a sandbox demo | Request case study with client name, approximate data volume, and the specific Cortex or Mosaic AI feature used. Verify via reference call. | Describes Cortex/Mosaic AI using only marketing-page language; or conflates it with general OpenAI API integration | 20% |
| **1.4 SDK and open-source contributions** | Active use of or contributions to Snowpark, delta-rs, PySpark, or published dbt packages on dbt Hub - signals engineers who read source code, not just documentation | Search GitHub for the firm's org handle; check dbt Hub for published packages. Look for commit recency, not just existence. | Open-source "contributions" are a stale fork from 2022 with no commits; or no GitHub org presence at all | 15% |
| **1.5 Published reference architectures** | Publicly available architecture guides, blog posts, or technical documentation demonstrating how the firm designs systems on their claimed platforms - not white-label vendor content | Request URLs. Look for author attribution, technical specificity, and publication date within the last 18 months. | "We have internal IP" with nothing public; or all published content is co-authored with the platform vendor's marketing team | 10% |
---
## Group 2: Delivery Maturity (5 criteria)
Delivery maturity is where most projects either succeed or accumulate invisible debt. A vendor who cannot separate development from production environments, or who treats observability as an afterthought, will hand you a platform that works in demos and fails in quarter-end runs.
| Criterion | Definition | How to verify | Red flag | Suggested weight in group |
|---|---|---|---|---|
| **2.1 CI/CD for data** | Separate dev/staging/prod environments with automated tests (dbt tests, Great Expectations, or equivalent) gating promotion to production | Request a sample CI/CD pipeline diagram and ask how a failing test is handled before a merge. Ask for an example of a deployment they rolled back. | "We use version control" without a gate between environments; or environments exist but promotion is manual with no automated test pass requirement | 30% |
| **2.2 Infrastructure-as-code coverage** | Terraform or Pulumi for cloud infrastructure; dbt for transformation logic - with both committed to a repository and subject to review | Request a sample Terraform module or dbt project structure. Ask what percentage of their last three projects used IaC from day one. | "We can do Terraform if you need it"; or IaC was retrofitted after initial build because it was "faster to click through the console" | 25% |
| **2.3 Orchestration sophistication** | Demonstrated competence with a specific orchestrator (Airflow, Dagster, or Prefect) - including cross-DAG dependencies, SLA monitoring, alerting, and environment promotion - not just "we support multiple orchestrators" | Ask them to walk through a specific DAG design decision: why they chose a sensor over a trigger in a given scenario, or how they handle partial pipeline failures. | Generic "we use Airflow" without specific knowledge of its scheduler, executor configuration, or failure handling; or "we use whatever the client has" | 25% |
| **2.4 Observability tooling** | Hands-on production experience with at least one dedicated data observability tool (Monte Carlo, Bigeye, Anomalo, Datafold) - not just logging and alerting | Ask for a specific anomaly they caught in production via observability tooling that would not have been caught by standard monitoring. | No hands-on observability tool experience; or conflates database monitoring (CloudWatch, Datadog) with data observability | 10% |
| **2.5 Change-management process** | Documented PR review standards, deployment cadence, and release notes discipline - evidence that changes are reviewed and traceable | Request a sample PR template or deployment checklist. Ask how they manage a breaking schema change across dependent pipelines. | No PR template; deploys happen whenever an engineer finishes work; schema changes are communicated informally via Slack | 10% |
---
## Group 3: AI/ML Readiness 2026 - the new fork in the road
This group did not exist in 2024 evaluation frameworks. It exists now because the delta between vendors who have production AI/ML experience and those who do not is widening fast. A 2026 data platform built by a vendor with no Cortex or Mosaic AI literacy will need redesign before it can support agentic use cases. That redesign is your problem, not theirs.
EU AI Act note: August 2026 marks full compliance enforcement for high-risk AI system providers. Any vendor operating in or serving EU markets must have a documented risk management process for AI systems. If they cannot describe it, they are operating without compliance infrastructure - a legal and operational liability you inherit.
| Criterion | Definition | How to verify | Red flag | Suggested weight in group |
|---|---|---|---|---|
| **3.1 LLM-on-warehouse experience** | Production delivery of features using Snowflake Cortex (Analyst, Search, Complete) or Databricks Mosaic AI - with the ability to articulate specific trade-offs between the two (latency, cost, governance model, feature completeness) | Ask: "For a client on Snowflake, when would you recommend Cortex Analyst over a standalone RAG pipeline, and when would you not?" If they cannot answer without hedging, they have not built it in production. | Lumps Cortex and Mosaic AI together as "AI features"; cannot articulate any performance or governance difference; references only ChatGPT or Azure OpenAI for all LLM use cases | 25% |
| **3.2 Agent orchestration in production** | Demonstrated delivery of agentic data workflows using LangGraph, CrewAI, or custom orchestration - in a live client environment handling real data | Request an architecture overview of an agentic pipeline they built: what triggered the agent, what tools it called, how it handled failure, and how human oversight was maintained | "We've done agentic proofs of concept" or "we're planning to launch an AI practice" - PoC work does not count as production experience | 25% |
| **3.3 EU AI Act preparedness** | Vendor has a documented AI risk management process: risk classification methodology for AI systems, bias-testing pipeline, and a named compliance lead or external counsel responsible for AI Act adherence | Ask: "Walk me through your AI risk classification process for an EU engagement. Who owns it?" Verify by requesting a sample risk register or compliance framework document. | "We're keeping an eye on it"; or compliance is described as "the client's responsibility"; or they have not heard of [Regulation EU 2024/1689](https://artificialintelligenceact.eu/) | 20% |
| **3.4 Model governance** | Documented approach to ML model lineage, drift detection, and retraining triggers - including use of Population Stability Index (PSI) thresholds or equivalent metrics - and integration with the data platform's existing lineage tooling | Ask how they connect model performance degradation detection to the upstream data pipeline that feeds the model. Look for specificity about PSI thresholds, monitoring cadence, and alerting. | Model governance described as "we document in Confluence"; no connection between data pipeline monitoring and model retraining decisions; no mention of drift metrics | 15% |
| **3.5 AI coding agent integration** | Articulated policy on AI coding assistant use (Cursor, Cody, GitHub Copilot, Aider) in their delivery workflow - including guardrails: what code is reviewed by humans, what is auto-merged, and how they handle hallucinated dependencies | Ask: "Do your engineers use AI coding assistants on client engagements? What guardrails govern that?" Either "yes with policy" or "no, by design" are acceptable. "Yes, freely" without policy is not. | Unrestricted use of AI coding assistants with no review policy; cannot describe what their engineers do with AI-generated code before it reaches client infrastructure | 15% |
---
## Group 4: Industry Fit (5 criteria)
Industry fit is not about logos. A vendor can list healthcare clients and still not know what a claims adjudication cycle looks like in a data model. Depth matters more than breadth here.
| Criterion | Definition | How to verify | Red flag | Suggested weight in group |
|---|---|---|---|---|
| **4.1 Vertical case studies at your scale** | Documented delivery in your industry at a comparable data volume, team size, and platform complexity - not just "we've worked in financial services" | Request two case studies with approximate data volumes, number of pipelines, and what happened when something went wrong. Call the reference client. | Case studies are from five years ago, a different sub-vertical, or a project significantly smaller than yours | 30% |
| **4.2 Regulatory familiarity** | Working knowledge of the specific compliance regime governing your data: HIPAA (healthcare), PCI-DSS (payments), GDPR (EU data subjects), FINRA (broker-dealer), or sector-specific audit requirements | Present a scenario: "We have PII from EU users flowing into our Snowflake warehouse. Walk me through how you'd design access controls and data retention." Score the specificity of the answer. | Regulatory knowledge described at the framework level only - "we're familiar with GDPR" - without specific design decisions; or relies entirely on "the legal team handles compliance" | 25% |
| **4.3 Domain glossary fluency** | Engineers on the proposed team can speak the domain language without a translator: insurance loss ratios, fintech reconciliation cycles, healthcare NDC codes, retail sell-through rates - whatever applies to your business | Test this in the discovery call. Introduce two or three domain-specific terms and watch whether the proposed team engages with them or asks the business stakeholder to explain | Cannot define basic domain terms; engineers redirect domain questions to the account manager or subject matter expert rather than engaging directly | 20% |
| **4.4 Client logos in your vertical** | Named current or recent clients in your industry - not a list of industry categories - available for reference | Ask for the names of two current or recent clients in your vertical and request permission to contact them. A vendor who cannot provide a single named client in your industry has not earned the claim. | A list of industry categories ("we serve healthcare, financial services, retail") with no named accounts willing to speak as references | 15% |
| **4.5 Industry-specific SLAs** | Demonstrated understanding that your industry imposes non-standard timing requirements: month-end close in finance, claims turnaround in insurance, data freshness for algorithmic trading, HIPAA breach notification windows | Ask: "Given our industry, what SLAs would you recommend for pipeline freshness and incident response?" A strong answer cites industry norms without prompting. | SLA discussion defaults entirely to generic uptime metrics; no mention of domain-specific timing requirements | 10% |
---
## Group 5: Commercial Hygiene (5 criteria)
A vendor's commercial terms reveal their risk posture and partnership philosophy faster than any technical discussion. Resistance to change-order caps or IP clarity is not negotiable friction - it is a signal.
| Criterion | Definition | How to verify | Red flag | Suggested weight in group |
|---|---|---|---|---|
| **5.1 Change-order rate cap** | Contract clause limiting the cumulative value of change orders without re-scoping - typically 10-15% of the original SOW value before a formal scope review is required | Review the MSA/SOW draft. Ask: "What triggers a formal scope review?" If the answer is "when we decide it's necessary," the clause is absent. | No cap on change orders; "we manage scope collaboratively" without a contractual floor; or change-order language that effectively allows open-ended billing | 25% |
| **5.2 IP ownership clause** | Unambiguous statement that the client owns 100% of all work product: custom code, data models, pipeline logic, documentation, and any derivative works | Read the IP clause directly - do not accept a verbal confirmation. The contract should use language like "all work product is work made for hire and is the exclusive property of Client." | Joint IP language; "vendor retains rights to methodologies and frameworks" without clear delineation from client deliverables; "subject to prior art" carve-outs that could encumber custom work | 25% |
| **5.3 Milestone payments + holdback** | Payment structure tied to delivery milestones with a 10% holdback released only upon successful acceptance testing and documentation handover | Review the SOW payment schedule. Confirm that the final payment tranche is contingent on documented acceptance criteria. | Front-loaded payment schedule; no holdback; acceptance criteria defined by the vendor rather than the client; "net-30 on invoice" without milestone contingency | 20% |
| **5.4 Off-ramp and transition clause** | Contractual right to exit for convenience plus an obligation on the vendor to provide transition assistance - knowledge transfer, handover documentation, and a minimum notice-period cooperation window | Confirm the termination-for-convenience clause exists and that it includes a cooperation period (typically 30-60 days) with specific transition deliverables. | No termination-for-convenience clause; or exit clause exists but vendor has no transition cooperation obligation; or transition assistance is billable at standard rates with no cap | 20% |
| **5.5 SLA penalty structure** | Contractual penalties (service credits, payment deductions) tied to measurable SLA failures - pipeline availability, data freshness, incident response time | Ask for the SLA schedule and penalty table. Look for specific thresholds: "If P95 pipeline latency exceeds X minutes for more than Y hours in a calendar month, Vendor credits Z% of monthly fees." | SLA commitments without financial consequences; "we take SLAs seriously" without a penalty structure; or penalty caps so low they remove any incentive for vendor compliance | 10% |
---
## Group 6: Team & Talent (5 criteria)
Staffing risk is the most common source of project failure that evaluations fail to catch in time. The team you meet in the pitch is not always the team that shows up to build.
| Criterion | Definition | How to verify | Red flag | Suggested weight in group |
|---|---|---|---|---|
| **6.1 Named-team policy** | Specific named individuals assigned to your project - lead architect, lead engineer, and engagement manager - included in the SOW before signature, not "TBD based on availability" | Require names in the SOW as a condition of contract. Ask each proposed person to participate in at least one technical session before signing. | "We will confirm the team upon contract execution"; named architects in the proposal are partners who will not be doing delivery work; or the team changes between proposal and SOW | 30% |
| **6.2 Key personnel substitution clause** | Contract clause requiring client approval for substitution of named key personnel - with a defined process (notice period, proposed replacement CV, client acceptance window) | Review the key personnel clause in the MSA. Confirm it requires advance notice (30 days minimum) and client approval before substitution takes effect. | No key personnel clause; or vendor retains unilateral right to substitute staff with only "equivalent experience" as the standard; or clause exists but approval is deemed granted if client doesn't respond within 48 hours | 25% |
| **6.3 Geographic mix and time-zone overlap** | Documented delivery team geography with enough overlap with your operating hours to support daily collaboration - typically a minimum of 4 hours of working-hour overlap | Ask for a team roster with locations and confirm which time zones have decision-making authority (not just execution capacity). | All senior architects are onshore; all execution is offshore with a 1-hour overlap window; or time zone overlap is described in terms of "asynchronous collaboration works fine for us" | 20% |
| **6.4 Retention rate of senior engineers** | Annual retention rate for engineers at senior/staff level - a proxy for team stability and the likelihood that the people you evaluated will still be there at month six | Ask directly: "What is your annual retention rate for senior engineers over the past two years?" Acceptable answers include a specific percentage with context. | Cannot provide a number; deflects to general "we have a great culture" language; or Glassdoor reviews show a pattern of project-level churn | 15% |
| **6.5 Subcontractor disclosure** | Full disclosure of which project work will be subcontracted, to what entity, in what geography, and why - with client approval rights over subcontractor use | Ask: "What percentage of this engagement do you expect to deliver via subcontractors, and will we have approval rights?" Require subcontractor disclosure in the SOW. | Subcontractor use is described as standard practice without disclosure; or the vendor treats this as confidential; or subcontractors are described as "extended team members" to obscure the arrangement | 10% |
---
## Group 7: Continuity & Risk (5 criteria)
Continuity criteria are the ones organizations skip because they feel like low-probability events. They are also the ones that determine whether a vendor failure becomes a recoverable problem or a 12-month rebuild.
| Criterion | Definition | How to verify | Red flag | Suggested weight in group |
|---|---|---|---|---|
| **7.1 Financial stability** | Confidence that the vendor will exist and remain solvent through the project lifecycle - assessed through ownership structure (private/PE-backed/public), revenue run-rate transparency, and customer concentration risk | Ask: "Who owns the business, and have there been any ownership changes in the last 24 months?" For PE-backed firms, ask about fund vintage and remaining hold period. | Recent acquisition by a PE fund with a short expected hold; high dependence on one or two anchor clients who could leave; or vendor declines to discuss ownership or financial health | 30% |
| **7.2 BCDR plan** | Documented Business Continuity and Disaster Recovery plan covering key personnel loss, office disruption, and cloud infrastructure failure - specific to how the vendor delivers data engineering work | Request the BCDR plan summary or ask for a walkthrough: "If your lead architect is unavailable for two weeks at a critical project phase, what is your response?" | No documented BCDR plan; or BCDR documentation is generic ("we use cloud infrastructure") without specifics on personnel succession and project continuity | 25% |
| **7.3 Cybersecurity posture** | SOC 2 Type II certification, ISO 27001 certification, or equivalent - with a recent penetration test (within 12 months) and a disclosed vulnerability disclosure policy | Request the SOC 2 Type II report summary (not the full report - the summary is sufficient for procurement purposes). Confirm pen-test recency. | SOC 2 Type I only (point-in-time audit, not continuous controls); certification pending but not yet achieved; pen test more than 24 months old; no vulnerability disclosure policy | 20% |
| **7.4 Insurance coverage** | Active cyber liability insurance and professional E&O (Errors & Omissions) coverage with limits commensurate with the project value - typically at least $5M each for enterprise engagements | Request certificates of insurance. Confirm coverage limits, policy expiry, and that your organization is named as an additional insured on the cyber policy. | Coverage limits of $1M or less for a multi-million-dollar engagement; policy expires before project completion; vendor cannot produce a certificate of insurance promptly | 15% |
| **7.5 Exit readiness** | Evidence that the vendor has successfully transferred knowledge and platform ownership to a client at the end of a prior engagement - demonstrated through documented runbooks, pipeline catalogs, and reference client confirmation | Ask for a reference call specifically focused on the handover experience: what was delivered, was it sufficient, and what did the client need to build themselves. | No reference available for a completed handover; or transition materials described as "standard documentation" without specifics; or vendor has no history of disengagements - only ongoing managed service relationships | 10% |
---
## How to measure each criterion: the source map
Every criterion has a measurement source. Knowing which source answers which question prevents evaluation theater - where vendors prepare polished responses to soft questions while the hard evidence never gets checked.
The practical rule: if a criterion can only be answered by the vendor themselves (RFP response or working session), it needs a second source - either a public signal or a reference call - before it can be scored at full confidence.
---
## What is the 3 vendor rule? (And why data engineering needs 4-6, not 3)
The "3 vendor rule" is procurement folk wisdom: ask for proposals from 7 vendors, bring 3 to final evaluation. The logic is clean - 3 gives you genuine competition without overwhelming the evaluation team.
For standard IT procurement, the rule is defensible. For data engineering vendor selection, it is too narrow.
Here is the problem: data engineering vendors differ on dimensions that only become visible when you have enough comparison points. Platform fidelity is not evenly distributed. A vendor who is a Snowflake Elite partner may have weak Databricks depth. A vendor with excellent delivery maturity may have no AI/ML readiness. A vendor with strong AI credentials may have thin commercial hygiene. Three vendors rarely give you enough triangulation to see these trade-offs clearly.
The sweet spot, based on the [86-vendor scored dataset](/) behind this framework, is **4-6 vendors** in serious evaluation:
- **4 vendors**: minimum for meaningful technical triangulation on platform fidelity
- **5-6 vendors**: appropriate for complex multi-platform or regulated-industry projects where risk criteria need broader comparison
The practical implication: your longlist should be 8-12. Your shortlist should be 4-6, not 3. The extra 1-3 vendors cost more evaluation time, but they buy disproportionately more signal on the criteria where vendors otherwise cluster tightly.
The one exception: if you have an incumbent with a strong track record and the project is a natural extension of existing work, a 3-vendor final evaluation (incumbent + 2 challengers) is defensible. But for new platform builds or significant capability gaps, go to 4-6.
---
## What are the 4 pillars of data engineering?
The four pillars of data engineering are:
1. **Collection** - acquiring data from source systems (APIs, databases, event streams, files) with appropriate reliability, latency, and schema management
2. **Cleaning** - transforming, validating, deduplicating, and enriching raw data to a state fit for downstream use
3. **Analysis-readiness** - modeling data in structures (star schemas, OBT, lakehouses) that support the query patterns of the business and its tools
4. **Operationalisation** - running pipelines in production with monitoring, alerting, SLA management, and the governance controls required by the business and its regulators
Each pillar maps directly to specific criteria in the 35-criterion framework:
| Pillar | Primary criteria | Key verification questions |
|---|---|---|
| Collection | 1.2 (named certified engineers), 2.3 (orchestration sophistication), 2.1 (CI/CD for data) | Can they ingest from your specific sources reliably? What is their retry and dead-letter handling approach? |
| Cleaning | 2.5 (change-management process), 4.3 (domain glossary fluency), 3.4 (model governance) | How do they manage schema evolution? What constitutes an acceptable data quality SLA? |
| Analysis-readiness | 1.3 (Cortex/Mosaic AI), 4.1 (vertical case studies), 1.5 (published reference architectures) | Can they model for your business questions, not just generic star schemas? Have they built for your query volumes? |
| Operationalisation | 2.4 (observability tooling), 7.2 (BCDR), 7.5 (exit readiness), 5.5 (SLA penalty structure) | What does "production-ready" mean to them? How do they handle incidents? What does handover look like? |
The pillar framework is useful for scoping. Before you assign weights to the 35 criteria, confirm which pillars carry the most risk for your project. A greenfield platform build has roughly equal weight across all four. A migration project typically has disproportionate risk in Collection and Cleaning. An AI enablement project puts the heaviest weight on Analysis-readiness and - increasingly - Operationalisation of model pipelines.
For more on the evaluation process that surrounds these pillars, the [data engineering partner selection hub](/insights/data-engineering-partner-selection/) covers the full CIO decision workflow.
---
## How should the 35 criteria be weighted for different project types?
The 35 criteria do not carry equal weight across all project types. The tables below show suggested group-level weights for three common archetypes. Criteria weights within each group stay constant (as shown in the group tables above) - only the group-level allocation shifts.
**Archetype A: Net-new platform build** - Greenfield Snowflake or Databricks platform, no existing modern infrastructure, organisation building from scratch.
**Archetype B: Modernisation / migration** - Moving from legacy warehouse, on-prem Hadoop, or first-generation cloud to a modern platform. Data exists; the goal is reliability, scalability, and reduced operational cost.
**Archetype C: AI/ML enablement** - Existing modern platform; the project's goal is to add AI/ML capabilities: feature stores, model pipelines, Cortex/Mosaic AI integration, or agentic data workflows.
| Group | Archetype A: New Build | Archetype B: Migration | Archetype C: AI/ML |
|---|---:|---:|---:|
| G1: Platform Fidelity | 20% | 20% | 15% |
| G2: Delivery Maturity | 20% | 25% | 15% |
| G3: AI/ML Readiness | 15% | 5% | 30% |
| G4: Industry Fit | 10% | 15% | 10% |
| G5: Commercial Hygiene | 10% | 10% | 10% |
| G6: Team & Talent | 15% | 15% | 10% |
| G7: Continuity & Risk | 10% | 10% | 10% |
| **Total** | **100%** | **100%** | **100%** |
Notes on the weightings:
- For Archetype B (migration), Delivery Maturity carries the highest weight because migration risk is predominantly an execution problem - cutover readiness, rollback discipline, and reconciliation rigor.
- For Archetype C (AI/ML), Group 3 jumps to 30% - nearly double the next closest group. Vendors without hands-on warehouse-native AI experience should not be shortlisted for this work.
- Group 5 (Commercial Hygiene) and Group 7 (Continuity & Risk) stay flat across all archetypes at 10% each. These are not project-type-dependent; they are baseline requirements regardless of what is being built.
For the mechanics of applying these group weights and running the scoring sessions, see the scoring-framework section of this guide.
---
## How do you convert the 35 criteria into a single vendor score?
Score each vendor 1-5 on every criterion, using a fixed scale so evaluators can't drift toward "gut feel":
| Score | Definition |
|---|---|
| 5 | Exceeds the criterion with verified evidence |
| 4 | Meets the criterion; minor, low-risk gaps |
| 3 | Acceptable, but carries visible risk |
| 2 | Weak evidence or a real concern |
| 1 | Unacceptable - can disqualify the vendor on its own |
Then apply two layers of weight, both already defined above: the criterion's weight within its group (the group tables) multiplied by that group's weight for your project archetype (the archetype table). A criterion's effective weight in the final score is criterion weight × group weight - not the criterion weight alone. Sum every weighted score across all 35 criteria to get the vendor's total. In a spreadsheet, `SUMPRODUCT` across (score × criterion weight × group weight) computes this directly.
Score independently before comparing notes with other evaluators. If two scores on the same criterion land more than a point apart, resolve the gap with evidence - a reference call, a certification lookup, a contract clause - not a discussion. A vendor with no evidence for a criterion gets scored on the gap, not the promise: mark it a 1 or 2, don't average toward the middle.
---
## What are the highest-value questions to ask on a vendor discovery call?
The 35 criteria define what to score. A discovery call is where you get a vendor to reveal it out loud, without the prep time an RFP response allows.
If a full hour isn't available, these ten questions cover the five dimensions that most often decide whether an engagement succeeds: brief comprehension, architecture judgment, staffing reality, commercial transparency, and exit terms.
1. What in our brief feels under-specified or contradictory? *(brief comprehension)*
2. Walk us through the architecture you'd propose, end to end. *(technical depth)*
3. What's the single most expensive line item over 24 months? *(cost realism)*
4. Who specifically will work on this - names and LinkedIn URLs? *(staffing reality)*
5. What percentage of the team will be substituted between proposal and project start? *(bait-and-switch risk)*
6. How do you handle a silent data-quality regression? *(delivery maturity)*
7. Who owns the IP - and is there any co-IP language in your standard MSA? *(commercial risk)*
8. What's the total cost of a 4-week paid pilot, and is it credit-forward? *(de-risking)*
9. What was your last security incident, and what changed because of it? *(security culture)*
10. What's the one clause we should push back on in your contract? *(negotiation honesty)*
A vendor who answers all ten without hesitation, and without deflecting to "it depends," has been through this before.
---
## Frequently asked questions
### How many vendor evaluation criteria should an RFP contain?
More criteria create noise, not signal. An RFP issued to vendors should not ask about all 35 criteria - it should ask about the ten to twelve most differentiated ones for your project type.
The full 35-criterion framework is for your internal evaluation, not the vendor document. Use the RFP to elicit evidence. Use the scorecard to assess it. Sending a 35-question RFP to vendors produces 35 narrative answers that are difficult to compare and incentivize length over clarity.
A well-structured RFP for data engineering typically contains 8-12 open-ended scenario questions targeting your highest-weight criteria, plus structured fields for certifications, team composition, and commercial assumptions. For process guidance, see [RFP process best practices](/data-engineering-rfp-checklist/).
### Should we share our weighted scorecard with the vendors?
No. Sharing the scorecard - including your weightings - before evaluation is complete allows vendors to optimize responses toward your scoring model rather than showing you their actual capabilities and approach. That defeats the purpose.
After selection, sharing the scorecard results with the winning vendor is useful: it establishes shared expectations and creates an accountability framework for the engagement. Sharing with unsuccessful vendors as part of a debrief is reasonable and professionally courteous.
### What evaluation criteria changed most between 2024 and 2026?
Three changes are material:
**Group 3 (AI/ML Readiness) did not exist as a discrete evaluation group in 2024.** Criteria like LLM-on-warehouse experience, agent orchestration in production, and EU AI Act preparedness were either absent from frameworks entirely or buried as sub-criteria under "Innovation." In 2026, they are a standalone group worth 15-30% of total weight depending on project type.
**Observability maturity (criterion 2.4) moved from a tie-breaker to a baseline requirement.** In 2024, hands-on experience with dedicated observability tools (Monte Carlo, Bigeye, Datafold) was a differentiator. In 2026, it is an expected competency. Vendors without it are missing a production-readiness standard that has become industry norm.
**EU AI Act compliance (criterion 3.3) became a procurement criterion.** Prior to the Act's enforcement, AI governance was a soft discussion topic. With full compliance required by August 2026, any vendor operating in EU markets who cannot produce a documented AI risk management process is operating outside legal requirements. That is a disqualifying condition, not a scoring deduction.
For a broader view of what changed, the [data engineering due diligence checklist](/insights/data-engineering-due-diligence-checklist/) covers the validation layer that sits alongside this evaluation framework.
### Can a smaller boutique meet all 35 criteria?
Not all 35, but that is not the right test.
A boutique with 15-25 engineers will typically score lower on financial stability (7.1), BCDR plan depth (7.2), and subcontractor disclosure scope (6.5) - simply because those criteria assume a certain organizational scale. That is expected and should be weighted accordingly.
What smaller boutiques can and should score well on: named-team policy (6.1), platform fidelity at the individual-engineer level (1.2), orchestration sophistication (2.3), and domain glossary fluency (4.3). A 20-person Snowflake specialist with three SnowPro Advanced certified engineers and five reference clients in your vertical will outperform a 500-person generalist IT firm on the criteria that most predict project success.
The practical adjustment: for boutiques, raise the weight of Criteria 6.4 (retention rate) and 7.1 (financial stability) in your internal discussion, and add explicit questions about bench depth for key-personnel coverage. Then evaluate against the adjusted model - not a standard designed for large systems integrators.
---
## Next step
The 35 criteria above define what to measure. Applying them without letting a proposal-writing exercise turn into vendor management theater is a separate discipline, covered in [vendor management best practices](/insights/vendor-management-best-practices/).
If you are actively issuing an RFP, the discovery-call question set in this guide gives you the verbal-format versions of the verification questions above. The [POC scoping guide](/insights/data-engineering-statement-of-work/) covers how to structure a paid proof of concept that tests criteria 2.1-2.5 and 3.1-3.2 in a controlled setting. For common RFP errors that cause evaluations to reach the wrong conclusion, see [RFP mistakes to avoid](/data-engineering-rfp-checklist/).
If you want to see how these criteria play out across a live vendor pool, the [data engineering consulting firms directory](/data-engineering-consulting-firms/) profiles the 86 firms this framework was built against.
---
## The 35-criterion checklist (print or copy as a 1-pager)
**Group 1: Platform Fidelity**
1. [ ] 1.1 Partner tier confirmed in official vendor directory (Elite/Premier, not self-reported)
2. [ ] 1.2 Named certified engineers verified by certification ID, not headcount claim
3. [ ] 1.3 Cortex AI / Mosaic AI production case study with client reference
4. [ ] 1.4 Open-source or SDK contributions verified on GitHub/dbt Hub with recent commits
5. [ ] 1.5 Published reference architecture with author attribution, dated within 18 months
**Group 2: Delivery Maturity**
6. [ ] 2.1 CI/CD pipeline with automated test gates between dev and production environments
7. [ ] 2.2 IaC coverage via Terraform/Pulumi and dbt, committed to repository from project start
8. [ ] 2.3 Orchestration depth: specific Airflow/Dagster/Prefect design decisions explained, not just claimed
9. [ ] 2.4 Production experience with Monte Carlo, Bigeye, Anomalo, or Datafold
10. [ ] 2.5 PR template and deployment checklist confirmed; breaking-change process documented
**Group 3: AI/ML Readiness 2026**
11. [ ] 3.1 Articulated trade-off between Snowflake Cortex and Databricks Mosaic AI for your use case
12. [ ] 3.2 Agentic workflow in production (LangGraph, CrewAI, or equivalent) - not PoC only
13. [ ] 3.3 Documented EU AI Act compliance process with named responsible owner
14. [ ] 3.4 Model governance with PSI-based drift detection tied to upstream pipeline monitoring
15. [ ] 3.5 AI coding assistant policy documented: scope, guardrails, human review requirements
**Group 4: Industry Fit**
16. [ ] 4.1 Vertical case study with comparable scale - reference client available to speak
17. [ ] 4.2 Regulatory scenario answered with specific design decisions (HIPAA/GDPR/PCI-DSS/FINRA)
18. [ ] 4.3 Domain terminology engaged directly by proposed delivery team, not routed to SME
19. [ ] 4.4 Named client in your vertical willing to take a reference call
20. [ ] 4.5 Industry-specific SLA recommendations given unprompted during discussion
**Group 5: Commercial Hygiene**
21. [ ] 5.1 Change-order rate cap (≤15% of SOW value) in the contract
22. [ ] 5.2 IP ownership clause: 100% work-for-hire language, no joint-IP or methodology carve-outs
23. [ ] 5.3 Milestone payment schedule with 10% holdback on final acceptance
24. [ ] 5.4 Termination-for-convenience clause with 30-60 day vendor cooperation obligation
25. [ ] 5.5 SLA penalty table with specific credit percentages tied to measurable failure thresholds
**Group 6: Team & Talent**
26. [ ] 6.1 Named team (lead architect, lead engineer, engagement manager) in SOW before signing
27. [ ] 6.2 Key personnel substitution clause: 30-day notice + client approval required
28. [ ] 6.3 Geographic mix confirmed: minimum 4-hour working-hour overlap with your team
29. [ ] 6.4 Senior engineer retention rate: specific percentage provided for last 2 years
30. [ ] 6.5 Subcontractor use disclosed: percentage, entity, geography, client approval right confirmed
**Group 7: Continuity & Risk**
31. [ ] 7.1 Ownership structure confirmed: PE/private/public, no undisclosed change-of-control in last 24 months
32. [ ] 7.2 BCDR plan reviewed: personnel succession and project continuity are explicit, not implied
33. [ ] 7.3 SOC 2 Type II or ISO 27001 confirmed; pen test within 12 months
34. [ ] 7.4 Certificate of insurance: cyber liability + E&O at ≥$5M, client named as additional insured
35. [ ] 7.5 Handover reference: prior client confirms runbooks, pipeline catalog, and knowledge transfer quality
---
## 10 Actionable Data governance Best Practices for 2026
Source: https://dataengineeringcompanies.com/insights/data-governance-best-practices/
Published: 2025-12-31T09:16:48.990871+00:00
Description: Discover 10 actionable data governance best practices for 2026. This no-fluff guide provides practical insights for establishing a modern governance program.
Data governance best practices come down to five things working together: a framework with real executive backing, a catalog people actually use, clear ownership instead of finger-pointing, quality checks built into pipelines rather than bolted on after, and access controls that scale with self-service analytics. Skip any one of them and the rest becomes theater - policies nobody follows, a catalog nobody trusts, or an access model nobody can audit.
This guide covers ten practices for building a governance program on platforms like Snowflake and Databricks, plus a comparison table for weighing implementation complexity against expected outcomes. Governance turns out to be a harder capability to find than most data engineering work: only 11 of the 86 firms profiled in the [Data Engineering Companies Index](/data-governance/) name it explicitly among their capabilities, which says more about how specialized the work is than how common the need is.
What this guide covers:
* **Framework and ownership models** that hold up against actual org charts, not just policy documents.
* **Data quality and lineage practices** that catch problems before they reach a dashboard.
* **Access control design** that protects sensitive data without locking out the people who need it.
* **Continuous review practices** that keep a governance program from going stale a year after launch.
## 1. Why does data governance start with an executive-sponsored framework?
A governance framework without executive sponsorship is a list of suggestions nobody is required to follow. Appoint a Chief Data Officer or a governance steering committee with the authority to enforce policy, then codify rules for data classification, retention, security, and regulatory compliance that map to actual business risk. Our [data governance framework template](/insights/data-governance-framework-template/) walks through the four pillars, policies, roles, processes, and metrics, that most programs need to operationalize.
A global financial institution subject to SOX and GDPR would use its framework to map specific data elements to compliance controls, so financial reporting data carries clear access controls and audit trails while customer data handling aligns with consent requirements. Modern platforms like Snowflake and Databricks now build governance capabilities directly into their architectures, which lowers the technical lift but does not replace the need for a chartered owner of the policy itself.
### Actionable Implementation Tips
* **Secure executive sponsorship.** Appoint a CDO or form a steering committee with C-level representation that meets quarterly at minimum to review progress and resolve escalations.
* **Define and document policies.** Start with classification, access control, and retention, mapped directly to regulatory requirements like HIPAA or CCPA rather than generic best-practice language.
* **Launch a pilot, not a big-bang rollout.** Select one business domain, such as customer data, to pilot the framework and refine the process before scaling it.
* **Establish a central knowledge base.** Use Confluence, SharePoint, or a similar tool to keep policies, standards, and procedures in one version-controlled place.
## 2. What makes a data catalog worth maintaining?
A data catalog only earns its keep if people actually use it to find, understand, and trust data instead of relying on tribal knowledge. Effective metadata management documents who owns each dataset, where it came from, how it's defined, and how reliable it is, turning data discovery from a Slack-message hunt into a search query. That distinction matters for scoping the work: our explainer on [data governance vs. data management](/insights/data-governance-vs-data-management/) draws the line between the policy layer and the platform-engineering layer that supports it.
A retail company can use a catalog like Alation or Collibra to trace a "customer lifetime value" metric from its executive dashboard back to the raw transactional data, so everyone understands the calculation and trusts the number. Databricks' Unity Catalog now captures lineage natively, and companies like Uber and Lyft built their own catalogs (Databook and Amundsen) years ago because discovery at scale doesn't work without one. This is a cornerstone of any [data governance strategy](/insights/data-governance-strategies/) that intends to survive contact with real usage.
### Actionable Implementation Tips
* **Start with high-value datasets.** Catalog the domains, customer, product, sales, that drive most of the business value instead of trying to document everything at once.
* **Integrate with your data stack.** Connect the catalog to your cloud platform (Snowflake, Databricks) and to dbt, which can populate column descriptions and lineage from its own metadata.
* **Appoint data stewards.** Assign business and technical stewards to specific domains and task them with curating definitions and certifying key assets.
* **Build a business glossary.** Define terms like "Active User" or "Gross Margin" with business leaders, then link those terms to the physical data assets so interpretation stays consistent.
## 3. Who should own data, and who should steward it?
Data Owners, usually business leaders, are accountable for a data domain's strategic value and compliance; Data Stewards, usually subject matter experts, handle the day-to-day work of quality, metadata, and access. Without that split, "who is responsible for this data" has no answer when a report breaks, and accountability evaporates. Firms that specialize in this kind of program design show up under [master data management consulting](/insights/master-data-management-consulting/) if you need outside help standing up the model.
A large retailer might designate the VP of Marketing as Data Owner for customer-level data, accountable for its compliant use in campaigns, while a Senior Marketing Analyst acts as Data Steward, defining what counts as a valid customer address and working with IT to enforce it. That split prevents the common failure mode where a data issue surfaces and every team points at another team.
### Actionable Implementation Tips
* **Document roles with a RACI matrix.** Build one for key domains like Customer, Product, and Finance so owner versus steward responsibilities are explicit, not assumed.
* **Start with critical domains.** Prioritize high-value, high-risk data first rather than assigning owners to every dataset at once.
* **Establish a steward community of practice.** Give stewards a forum to standardize definitions, like a shared definition of "Active Customer," and solve cross-functional problems together.
* **Tie stewardship to performance reviews.** Link stewardship activities to job descriptions so the role is a real professional responsibility, not a side project.
## 4. What does a data quality standard need to cover?
A data quality standard needs measurable thresholds, accuracy, completeness, consistency, and timeliness, enforced as automated tests inside the pipeline rather than caught manually after the fact. Rules should be version-controlled and documented like code, so issues get flagged at the source instead of surfacing three dashboards downstream.
A marketing team relying on customer contact data for segmentation might enforce a completeness threshold on the `email_address` field and validate its format with a regex check before records enter the marketing automation platform. dbt supports this kind of in-workflow testing, and dedicated tools like Soda and Great Expectations handle broader pipeline monitoring.
### Actionable Implementation Tips
* **Define quality dimensions and thresholds.** Set explicit SLAs, for example a timeliness target for sales data ingestion or an accuracy threshold for product SKUs against a source system.
* **Integrate checks into pipelines.** Use dbt tests or similar tools to run validations on every model build and stop the pipeline when a critical threshold is breached.
* **Automate monitoring and alerting.** Deploy Great Expectations or Soda to profile data continuously and route warnings versus critical failures to the right escalation path.
* **Build a feedback loop.** Give data consumers a clear way, a Slack channel or a Jira queue, to report quality issues back to the data owner.
## 5. How should access control be designed for self-service analytics?
Role-Based Access Control (RBAC), and its more granular counterpart Attribute-Based Access Control (ABAC), should enforce the principle of least privilege: users get access to exactly the data their job requires, no more. Snowflake and Databricks both build this in natively now, with row-level security and dynamic column masking available as platform features rather than custom builds.

A healthcare system can use RBAC to grant doctors access to patient records within their department while a billing specialist sees only financial information. ABAC adds conditions on top, restricting access to a clinician's active shift, for instance. This level of control is what regulations like HIPAA actually require in practice, not just in policy language.
### Actionable Implementation Tips
* **Design a clear role hierarchy.** Map roles like Financial Analyst, Data Scientist, and Marketing Manager to specific data permissions, aligned with your identity provider groups in Okta or Azure AD.
* **Start from zero access.** Grant only the permissions a role actually needs rather than provisioning broadly and trimming later.
* **Automate provisioning and deprovisioning.** Tie your data platform to your identity provider so access updates automatically when someone joins, changes roles, or leaves.
* **Run quarterly access reviews.** Audit who has access to what on a schedule, and revoke permissions that no longer match the role.
## 6. Why does lineage matter beyond compliance audits?
Data lineage maps how data flows from source to destination, which means a change to a source-system column doesn't silently break a dozen downstream dashboards. Impact analysis, powered by lineage, tells you the blast radius of a proposed change before you make it, which is a maintenance requirement, not just an audit checkbox.

dbt now captures lineage automatically by parsing SQL to build dependency graphs, and platforms like Collibra and Alation extend that to cross-system, column-level lineage that connects technical metadata to business context. That level of detail is what lets a team trace a KPI on a C-level dashboard back to the raw source tables when something looks wrong. Our [comparison of data lineage tools](/insights/data-lineage-tools-comparison/) breaks down which platforms handle which depth of tracking.
### Actionable Implementation Tips
* **Automate lineage capture.** Use native features in dbt (`dbt docs generate`) or Databricks Delta Live Tables, and integrate open standards like OpenLineage to pull metadata from orchestrators like Airflow and Prefect.
* **Establish naming conventions.** Consistent naming for tables, columns, and schemas makes automated tracing far more reliable.
* **Track column-level lineage for sensitive data.** For PII specifically, column-level tracking supports precise impact analysis for privacy audits.
* **Wire impact analysis into CI/CD.** Run an automated impact report before deploying pipeline changes, and require sign-off from downstream owners when the impact score crosses a threshold.
## 7. How do data contracts keep a data mesh from turning into chaos?
Data contracts are machine-readable agreements between data producers and consumers that define a data product's schema, quality, and service levels, and they're what makes a decentralized data mesh architecture workable instead of a source of constant breakage. Contracts get validated automatically in CI/CD, which turns governance from a manual after-the-fact cleanup into an automated, proactive check. Our piece on [data contracts in data engineering](/insights/data-contracts-in-data-engineering/) covers the mechanics in more depth.
A marketing team consuming customer data from a sales domain can rely on a contract guaranteeing the `customer_id` field is always present and correctly formatted. If the sales team tries to deploy a change that breaks that guarantee, the CI/CD pipeline fails the build before it reaches production. dbt now ships contract features, and Confluent Schema Registry enforces schema evolution for streaming data.
### Actionable Implementation Tips
* **Start with critical data products.** Define contracts first for high-value datasets that have multiple downstream consumers.
* **Automate contract validation in CI/CD.** Use dbt contracts or a schema registry to check schema, data types, and quality rules before code merges.
* **Establish a contract review process.** New contracts, and changes to existing ones, should get sign-off from both producer and consumer teams before deployment.
* **Define a deprecation policy.** Versioning, a notification period, and migration support for consumers should be standard, not improvised.
* **Monitor for violations.** Alert data product owners immediately when a contract is breached in production.
## 8. Why do governance programs need a community, not just a policy doc?
Policies that nobody understands or champions don't get followed, no matter how well they're written. A data steward council creates a feedback loop between the central governance team and the business units doing the actual work, and it's where stewards trade solutions instead of each team reinventing the same fix.
A large retailer might run a Product Data Steward Council that meets monthly, with stewards from merchandising, marketing, and supply chain standardizing product attributes and resolving the discrepancies that cause downstream reporting errors. That peer-to-peer problem-solving tends to work better than a central team dictating standards from a distance. Snowflake and Microsoft both offer training and certifications now, on the reasonable assumption that trained users adopt governance faster than untrained ones.
### Actionable Implementation Tips
* **Establish a data steward council.** A cross-functional group that meets at least monthly, focused first on sharing challenges and standardizing definitions.
* **Build role-specific training.** Tailor modules for owners, stewards, and consumers, using platforms like Coursera or LinkedIn Learning for the basics and internal training for your specific tools and policies.
* **Launch a governance knowledge hub.** A wiki or intranet page holding glossaries, policy documents, process maps, and steward contacts in one place.
* **Host quarterly governance forums.** Include executive participation to share wins, give roadmap updates, and recognize steward contributions publicly.
## 9. Which tools actually belong in a governance stack?
A governance stack needs a catalog, a quality tool, a lineage layer, and an access control system that integrate with each other and with your core data platform, not a pile of disconnected point solutions. Integration is the differentiator: a catalog like Atlan or Alation connected to dbt and to an identity layer like Okta produces automated governance instead of manual, error-prone enforcement.
A retail company could use this kind of integrated stack to automatically tag PII as it enters Snowflake, have the catalog classify it, have Great Expectations validate its format, and have access policies apply automatically based on roles defined in the identity system. That's what "automated" governance actually looks like in practice, not a marketing claim.
### Actionable Implementation Tips
* **Evaluate tools on integration, not features.** Prioritize native connectors and API support for your existing platforms (Snowflake, Databricks) and identity systems.
* **Start with a core set.** Three to five essential tools covering cataloging, quality, and access management beats a dozen specialized point solutions rolled out at once.
* **Prioritize automation.** Pick tools that automate classification, lineage mapping, and policy enforcement, for example using Databricks Unity Catalog for fine-grained access control natively.
* **Assign tool ownership.** Someone specific should own each tool's configuration, maintenance, and training, or the investment erodes over time.
## 10. Does governance work end once the framework ships?
No. Governance is a continuous program, not a one-time project, and it needs regular effectiveness reviews to stay relevant as data sources, regulations, and business priorities change. Treating the initial framework as the finish line is how programs quietly go stale.
A healthcare organization can track a governance dashboard showing the percentage of patient records compliant with HIPAA standards or the average time to resolve a data quality issue, and watch those metrics move as evidence the program is working. Maturity models from firms like Gartner give organizations a structured way to benchmark where they stand and plan the next stage.
### Actionable Implementation Tips
* **Define 5-10 core KPIs.** Data quality scores, policy compliance rates, issue resolution times, and the number of certified assets are a reasonable starting set.
* **Build a governance dashboard.** Visualize KPIs in a BI tool and make it visible to executives and stewards, not just the governance team.
* **Hold quarterly reviews.** Bring the steering committee together to review trends, address roadblocks, and adjust priorities.
* **Run annual maturity assessments.** Use a framework like Gartner's or CMMI to benchmark the program and update the roadmap.
* **Collect user feedback systematically.** Annual surveys and focus groups with data consumers surface what isn't working before it becomes a bigger problem.
## Top 10 Data Governance Best Practices Comparison
| Item | Implementation Complexity | Resource Requirements | Expected Outcomes | Ideal Use Cases | Key Advantages |
|---|---:|---|---|---|---|
| Establish a Data Governance Framework, Executive Sponsorship, and Policies | High - organization-wide change, policy design | Executive sponsorship, CDO/lead, legal/compliance, long-term budget | Clear accountability, consistent policies, regulatory compliance | Regulated industries, large platform migrations | Central authority, reduced legal/reputational risk, audit readiness |
| Implement Data Cataloging and Metadata Management | Medium - integrations and ongoing curation | Catalog tool, metadata automation, data stewards | Improved discovery, documented lineage and definitions | Mid/enterprise analytics teams, migrations with inherited assets | Faster data discovery, impact analysis, better trust |
| Define Data Ownership and Stewardship Models | Medium - role definition and cultural change | Role assignments, training, RACI matrices | Clear ownership, improved data quality and SLAs | Data mesh adoption, scaling governance across domains | Domain alignment, faster decisions, accountability |
| Establish Data Quality Standards and Monitoring | Medium-High - rule definition and pipeline integration | Quality tools, tests in pipelines, monitoring and remediation workflows | Reliable analytics, fewer downstream errors, SLAs met | AI/ML production, critical reporting and regulatory data | Prevents bad data, early detection, reduces remediation cost |
| Implement Role-Based Access Control (RBAC) and Data Security | High - fine-grained controls and IAM integration | IAM, access controls, audit logging, security ops | Reduced unauthorized access, compliance, audit trails | Regulated enterprises, multi-tenant or sensitive data environments | Strong access enforcement, auditability, least-privilege control |
| Create Data Lineage and Impact Analysis Capabilities | Medium - automated capture and visualization | Lineage tools, instrumented pipelines, visualization dashboards | Faster root-cause analysis, clear change impact | Large/complex pipelines, migrations, compliance audits | Traceability of data flows, reduced change risk |
| Implement Data Contracts and Data Mesh Architecture | High - CI/CD, schema governance, cultural shift | Schema registries, CI pipelines, developer discipline | Stable producer-consumer interfaces, decentralized delivery | Organizations scaling domains, streaming platforms | Prevents breaking changes, enables autonomous domains |
| Build Data Governance Communities and Training Programs | Low-Medium - coordination and curriculum development | Training materials, facilitators, time from participants | Increased data literacy, adoption, sustained governance | Cultural transformation, post-migration enablement | Peer learning, faster adoption, broader ownership |
| Establish Data Governance Technology Stack and Tool Integration | High - tool selection and cross-platform integration | Tool licenses, engineers for integration, ongoing maintenance | Automated enforcement, centralized visibility, fewer manual tasks | Enterprise governance, heterogeneous tool environments | Automation, consolidated governance view, simplified audits |
| Implement Continuous Governance and Regular Effectiveness Reviews | Medium - programmatic monitoring and iteration | Metrics, dashboards, periodic reviews, executive oversight | Measured governance ROI, continuous improvement, relevance maintained | Mature governance programs, regulated organizations | Sustained governance value, data-driven prioritization and improvements |
## Putting the Framework Into Practice
These ten practices work as a system, not a checklist to complete in order. The framework sets accountability; the catalog and lineage make data findable and traceable; quality standards and access control keep it trustworthy and secure; contracts and tooling automate the enforcement; and community and continuous review keep the whole thing from decaying once the initial project team moves on.
Avoid a big-bang rollout. In the first 90 days, secure an executive sponsor, draft a minimum viable policy set covering classification, access, and quality, and appoint stewards for one pilot domain. Over the next two quarters, stand up a data catalog for that domain and establish quality baselines you can actually measure. After that, expand domain by domain, formalize training, and integrate the catalog, quality, and security tools so enforcement stops depending on manual effort.
If you're still deciding how governance fits alongside a platform move, [data migration best practices](/insights/data-migration-best-practices/) covers the sequencing question directly. For finding a partner who can help build the program itself, our directories for [enterprise data engineering](/enterprise-data-engineering/), [healthcare data engineering](/healthcare-data-engineering/), and [fintech data engineering](/fintech-data-engineering/) firms narrow the search by the regulatory context you're working under.
---
## Data Governance Consulting: A Practical Guide to Implementation
Source: https://dataengineeringcompanies.com/insights/data-governance-consulting/
Published: 2026-01-30T09:33:57.482504+00:00
Description: Explore data governance consulting to learn how experts deliver results, pricing, and how to hire the right firm.
Most guides to data governance consulting try to sell you on why you need it. This one assumes you're already convinced and need to know how to run the engagement itself: what a consultant should actually deliver, what it costs, how the timeline breaks down, and the RFP questions that separate real practitioners from a slide deck. If you're still comparing firms by name, our [data governance consulting directory](https://dataengineeringcompanies.com/data-governance/) ranks the ones in our index. This page picks up from there - what to expect once you've hired one.
## What Does a Data Governance Consulting Engagement Actually Involve?
**A data governance consulting engagement pairs a strategist who defines the business case with a governance lead who builds the operating model and a technical architect who implements controls inside your data platform. Together they turn scattered data ownership into defined roles, documented policies, and a working data catalog your teams actually use.**
A useful analogy is urban planning. An unplanned city ends up with gridlock, failing utilities, and chaos; a planned one works because someone designed the rules before the buildings went up. Data governance consulting does the same job for enterprise data - consultants design the rules, define the roles, and implement the systems that turn data chaos into a resource people trust.
This work matters because the initiatives riding on top of it - trustworthy AI, compliance with regulations like GDPR, self-service analytics - don't function without a solid data foundation underneath them. Attempting them without governance is building a skyscraper on sand.
### Why Organizations Bring in Outside Help
Most organizations that try to launch a governance program internally stall out, usually from a lack of niche experience, dedicated resources, or the objective standing needed to referee internal disputes over data. A consulting firm supplies both the blueprint and the hands to build it, moving faster while sidestepping the politics that derail internal-only attempts.
> The value of a consultant is converting abstract governance concepts into concrete actions that support specific business objectives - better decision-making, reduced compliance risk, or lower operational cost.
> **Directory Insight:** Governance work concentrates where regulation is heaviest. In our directory of 86 data engineering firms, 60 (70%) serve financial services and 37 (43%) serve healthcare - the two sectors where a governance failure carries direct regulatory and legal consequences. Pricing follows the same logic: 44 firms (51%) list rates in the $100-200/hr band for this kind of work.
Engaging a consultant is ultimately about moving data from liability to asset - the difference between managing a data swamp and a well-curated resource people actually pull decisions from.
### The Three Pillars of an Effective Governance Program
A data governance program that works is not a technology project - it is a business discipline built on three interdependent pillars. A consultant's job is to integrate these into a framework that fits your organization, not a generic template.
* **People:** Defining clear ownership and accountability. Who is responsible for the integrity of customer data? Who signs off on financial data accuracy? Consultants help establish **Data Owners** (senior leaders accountable for a data domain) and **Data Stewards** (subject matter experts responsible for day-to-day management), so data quality becomes a shared responsibility instead of nobody's job.
* **Process:** Codifying rules for data handling - policies for access and security, workflows for data quality remediation, standards for metadata management. These processes create the consistency that makes data reliable across the enterprise.
* **Technology:** Not a solution on its own, but a critical enabler. Consultants give objective guidance on selecting and implementing the right tools - data catalogs, metadata management platforms, data quality dashboards - to automate and support the people and processes already in place.
### Core Components of a Modern Data Governance Program
This table outlines the components most engagements build and the consultant's role in delivering them.
| Governance Pillar | Consultant's Role & Key Deliverable |
| :--- | :--- |
| **Data Policy & Standards** | Draft clear, enforceable rules for data quality, access, security, and usage. **Deliverable:** A formal Data Governance Policy document. |
| **Data Stewardship** | Identify and train business users as "Data Stewards" accountable for specific data domains. **Deliverable:** A Data Stewardship Model and RACI matrix. |
| **Data Catalog & Lineage** | Implement a central inventory of data assets to make data discoverable, understandable, and trusted. **Deliverable:** A fully populated and searchable [Data Catalog](https://atlan.com/what-is-a-data-catalog/). |
| **Metadata Management** | Define and manage "data about data" (definitions, sources, formats) to provide essential business context. **Deliverable:** A Metadata Management Strategy. |
| **Roles & Organization Design** | Structure the human elements of governance, including a Data Governance Council and defined roles/responsibilities. **Deliverable:** An organizational chart and RACI matrix. |
These components are interdependent - a failure in one pillar undermines the others. An effective consultant makes sure all of them get built and stay connected to your actual business requirements.
## What Do Data Governance Consultants Actually Deliver?
**Expect five concrete artifacts: a RACI matrix assigning data ownership, a ratified data governance policy, a configured data catalog with a populated business glossary, documented data quality rules, and a stewardship model your team can run without the consultant in the room. A credible engagement produces these, not just a strategy deck.**
Consultants act as the architects and general contractors for your data infrastructure - they provide the blueprints, building codes, and operating manuals required to build the system correctly and keep it running.
### The Core Consulting Team Structure
An effective engagement mixes strategic planning, project management, and hands-on technical implementation. Titles vary by firm, but the functions fall into three roles.
* **The Principal/Strategist:** Translates business objectives into a governance strategy, engages executive leadership, and defines success in terms of risk reduction, efficiency, or revenue. Owns the "why."
* **The Governance Lead/Manager:** Converts the strategy into an execution plan with a timeline and resource allocation, and makes sure policies are adoptable by your organization. Owns the "how."
* **The Technical Architect:** Builds the technical scaffolding - implementing [data quality rules](https://docs.snowflake.com/en/user-guide/security-access-control-overview) and access controls in Snowflake, configuring [Unity Catalog](https://www.databricks.com/product/unity-catalog) permissions in Databricks, and setting up data masking policies. Owns the "what."
> A common failure point in governance work is the gap between written policy and technical implementation. A well-structured team is designed to bridge that gap so the technical solution actually enforces the documented rules.
A team heavy on strategy without technical depth produces an elegant but unbuildable roadmap. A team of pure technologists builds a technically sound system that misses the business problem.
### Establishing Clear Data Ownership and Stewardship
One of the first problems a consultant addresses is ambiguity over ownership. Without clear accountability, data becomes everyone's problem and no one's responsibility. The fix is a **Data Stewardship Model**, delivered as:
* **A Defined RACI Matrix:** Clarifies who is **R**esponsible, **A**ccountable, **C**onsulted, and **I**nformed for critical data domains like customer or product data, eliminating circular debates over authority.
* **Data Steward Role Descriptions:** Concise job descriptions that define the day-to-day duties of a Data Steward, so they can be folded into existing roles.
* **A Data Governance Council Charter:** The founding document for the senior leadership committee overseeing the program - its mission, authority, and decision process.
### Developing the Official Data Rulebook
Once ownership is established, the rules get defined. Consultants build the rulebook for how the organization manages, protects, and uses its data.
> These documents earn their value from clarity and practicality, not length. A consultant's job is to write rules that fit how the business actually operates, not academic ideals nobody follows.
The key documents:
* **A Formal Data Governance Policy:** A short, executive-sponsored document that officially authorizes the program and grants it authority.
* **Data Standards Documents:** The detailed specifications - for example, a Customer Data Standard spelling out the required phone number format or which fields are mandatory on a new customer record.
### Building a Data Catalog Your Team Will Actually Use
You cannot govern what you cannot find. A central part of most engagements is implementing a **Data Catalog** - a search engine for enterprise data that surfaces what exists, where it came from, and what it means.
* **Tool Selection & Configuration:** Evaluating vendors like [Collibra](https://www.collibra.com/), [Alation](https://www.alation.com/), or [Atlan](https://atlan.com/) and managing the initial setup.
* **Populated Business Glossary:** A definitive dictionary of business terms, so "Active Customer" means the same thing to everyone. See our guide to [data governance strategies](https://dataengineeringcompanies.com/insights/data-governance-strategies/) for more on getting this adopted.
* **Initial Data Asset Curation:** Connecting the catalog to critical sources (CRM, ERP) and documenting key datasets with owners, lineage, and quality scores.
### Building a Framework for Trustworthy Data
Finally, consultants deliver a **Data Quality Framework** - the mechanism that keeps data accurate, complete, and reliable, shifting quality management from firefighting to a managed discipline.
* **Data Quality Scorecards:** Dashboards that monitor the health of critical data, flagging issues like missing email addresses or malformed zip codes.
* **Issue Resolution Workflows:** A documented process for logging, assigning, and verifying the fix for a data error.
* **Data Quality Rule Library:** Automated business rules that check data accuracy - for example, flagging any new sales order missing a shipping address.
## When Does Data Governance Consulting Deliver the Most Value?
**Governance consulting pays off fastest in three situations: before a cloud migration, where bad data would otherwise just move to a more expensive platform; before an AI or ML rollout, where model quality depends on documented, unbiased training data; and during a merger, where two companies need one shared definition of "customer."**
### Scenario 1: De-Risking a Major Cloud Migration
Migrating to a platform like [Snowflake](https://www.snowflake.com/) or [Databricks](https://www.databricks.com/) carries a real risk: garbage in, garbage out. Moving decades of poorly documented, low-quality data to a new platform doesn't fix anything - it relocates the problem to a more expensive environment.
A consultant intervenes before the migration. A retail company planning to move sales, inventory, and customer data to Snowflake discovers its legacy systems are full of duplicate records and conflicting product hierarchies with no clear owner. The consultant audits the most critical datasets, stands up a temporary stewardship council to resolve conflicting definitions, and catalogs lineage before the migration starts - so the team knows what it's moving and why.
### Scenario 2: Enabling Trustworthy AI and Machine Learning
AI and ML models are only as good as their training data. Models built on biased, incomplete, or inaccurate data underperform and introduce reputational and legal risk.
A financial institution building a churn-prediction model finds its historical data fragmented across systems with no documented lineage and undocumented bias. The consultant implements a governance framework tailored to the AI data lifecycle - strict data quality rules, lineage documented from source to model, and a "model card" detailing the training data's characteristics and known biases - so the model can clear a regulatory audit.
### Scenario 3: Harmonizing Data During a Merger or Acquisition
When two companies merge, their data ecosystems collide - conflicting systems, processes, and definitions for basic business terms. This can stall post-merger integration for months and erode the deal's value.
A manufacturing firm acquiring a smaller competitor discovers it can't produce a unified customer list because the two companies run different CRMs, product taxonomies, and sales territories. The consultant runs workshops with both sides to agree on a single "golden record" definition for customers and products, then oversees the technical mapping from legacy data to the unified standard.
### Use Case Impact Summary
| Scenario | Core Business Problem | Key Governance Solution |
| :--- | :--- | :--- |
| **Cloud Migration** | Migrating low-quality data to a new platform, producing untrusted analytics. | Pre-migration data quality assessment, cataloging, and clear ownership. |
| **AI & ML Initiatives** | Biased or inaccurate training data leading to ineffective or harmful models. | AI-specific lifecycle management, lineage tracking, and bias documentation. |
| **Mergers & Acquisitions** | Conflicting data systems and definitions blocking post-merger integration. | Harmonization workshops, "golden records," and mapping to a unified standard. |
## How Long Does a Data Governance Implementation Take?
**Most implementations run three phases: a 4-6 week assessment that produces a roadmap, a 3-4 month foundation phase that builds and pilots the core program, and a 6-12+ month enterprise rollout that scales what the pilot proved. Expect the first phase to set the pace and budget for everything after it.**
Engagements generally fall into two categories. A **strategic advisory retainer** gives you ongoing access to senior consultants for guidance and roadmap adjustments - it fits organizations that already have an implementation team and need experienced oversight. The more common model is **project-based implementation**: a structured engagement with defined phases, concrete deliverables, and a predictable timeline.
### The Typical Phased Approach
Consultants almost always recommend a phased lifecycle, so the foundation gets built correctly before the program expands. Each phase reduces risk and builds on the one before it, starting with a short, intensive assessment and moving into a longer build-test-scale cycle with checkpoints along the way.
### Phase 1: Assessment and Roadmap (4-6 Weeks)
Consultants interview key stakeholders, review existing documentation, and analyze the technical stack to produce an objective read on the current state - strengths, weaknesses, and organizational readiness.
The primary deliverable is a **Data Governance Roadmap**:
* **A Maturity Assessment:** An objective score of the current state, benchmarked against industry peers.
* **Prioritized Use Cases:** A short list of high-impact problems governance can solve first - cleansing customer data for marketing, or validating data for regulatory reporting.
* **A Phased Implementation Plan:** A timeline, resource plan, and budget estimate for the phases that follow.
This roadmap is the business case for securing funding and support for the full initiative.
### Phase 2: Foundation and Pilot (3-4 Months)
The focus shifts to building the core program and testing it on a small, high-impact pilot - where theory gets validated through practical application.
> The pilot needs to succeed. It's the internal proof of concept that wins over skeptics and builds the momentum needed to keep going.
During this stage, consultants work with the internal team to:
1. **Establish the Governance Body:** Formally launch a Data Governance Council and train the first group of Data Stewards.
2. **Develop Core Policies:** Draft and ratify the first essential policies, scoped tightly to the pilot's data domain.
3. **Implement a Tool:** Deploy a data catalog or quality tool, but limit its scope to the pilot to avoid over-engineering.
4. **Execute the Pilot:** Run the project start to finish, measuring impact on a key metric like data quality improvement or time saved.
By the end of this phase, the organization has a working, small-scale version of the program and the metrics to prove its value.
### Phase 3: Enterprise Rollout (6-12+ Months)
The final phase scales the program using the lessons from the pilot, expanding across other departments and data domains. Timeline varies widely - a mid-sized company might finish in 6 months, while a large global corporation could take multiple years.
This stage is less about invention and more about repetition and refinement. The consultant's role shifts from direct implementation to coaching, gradually shifting ownership to your internal team as the program scales, until governance becomes a routine part of how the business operates.
## What Does Data Governance Consulting Cost?
**Cost depends on engagement model and team seniority more than headline hourly rate. Project-based work fits a defined outcome, retainers fit ongoing strategic guidance, and staff augmentation fits a specific technical gap. Most credible firms set a minimum project size, because governance work below a certain scope can't produce a durable result.**
### Choosing the Right Engagement Model
* **Project-Based (Fixed Scope):** A specific outcome, timeline, and fixed price agreed upfront. Predictable cost and clearly defined scope.
* **Best for:** Initiating a new governance program, implementing a data catalog, or a targeted data quality remediation.
* **Trade-off:** Unforeseen issues - common in data projects - usually require a formal change order.
* **Retainer (Advisory):** An ongoing agreement for a set number of expert hours per month, for continuous strategic guidance rather than project execution.
* **Best for:** Organizations with an established program that need ongoing oversight to mature it, run steering committee meetings, or work through internal politics.
* **Trade-off:** Value depends on active, purposeful use. Unused retainer hours are a sunk cost.
* **Staff Augmentation (Embedded Experts):** Consultants embedded directly in your team to fill a specific skill gap for a defined period - for example, an embedded Snowflake or Databricks architect implementing data quality rules or fine-grained access controls.
* **Best for:** Projects that need deep, hands-on technical expertise you don't have internally.
* **Trade-off:** Usually the most expensive model per hour, and risks dependency without a knowledge-transfer plan built into the contract.
> A retainer gives you a governance brain trust on demand - useful when you need consistent high-level strategy more than hands-on build work. A project-based engagement fits better when the deliverable and deadline are clear.
### Breaking Down Consultant Rate Bands
Rates vary by geography and firm prestige but generally fall into predictable tiers. An effective firm blends the team to optimize value.
* **Analyst/Consultant:** Junior professionals handling data analysis, process documentation, and workshop support under senior guidance.
* **Senior Consultant:** Experienced practitioners leading specific workstreams, like the stewardship model or a catalog pilot.
* **Manager/Principal:** The project lead responsible for delivery, client relationship, and budget.
* **Partner/Director:** Senior executive providing strategic guidance and holding ultimate accountability for the project.
> Focusing only on hourly rate is a mistake. A highly experienced consultant might solve in 10 hours what would take a junior resource 40 - making the senior person the cheaper option.
### Why You'll See Minimum Project Thresholds
Most credible firms set a minimum project size, often starting in the $50,000 to $75,000 range. This isn't arbitrary - it's roughly the minimum investment needed for stakeholder interviews, a thorough current-state assessment, a customized roadmap, and a pilot that actually proves value. A firm with a minimum is signaling it wants outcomes, not billable hours.
### The Key Factors That Drive Your Total Project Cost
**Data Governance Consulting Cost Factors and Rate Bands (2025 Estimates)**
| Factor / Role | Description | Typical Rate Band (USD/hr) |
| :--- | :--- | :--- |
| **Project Scope** | Number of business units, data domains, and systems included. | **High Impact:** A larger scope means more interviews, analysis, and coordination hours. |
| **Organizational Complexity** | Company size, geographic spread, and internal team alignment. | **High Impact:** A decentralized, global organization needs significantly more change management. |
| **Tool Implementation** | Whether the project includes selecting and configuring a new platform, such as a [data catalog](https://www.alation.com/) or [data quality tool](https://www.talend.com/products/data-quality/). | **Medium to High Impact:** Adds technical tasks, vendor management, and configuration work. |
| **Deliverable Depth** | Level of detail required, from a strategic roadmap to granular operational policies. | **Medium Impact:** Operational-level deliverables take longer to build than high-level frameworks. |
| **Analyst / Junior Consultant** | Entry-level work: data gathering, documentation, workshop support. | **$150 - $250** |
| **Senior Consultant** | Leads specific workstreams, like policy development or stewardship design. | **$250 - $400** |
| **Manager / Principal** | Day-to-day project lead: delivery, client relationship, budget. | **$375 - $550** |
| **Partner / Director** | Senior oversight and ultimate accountability for project success. | **$500 - $800+** |
A wide-scope project inside a complex organization naturally needs more senior oversight and a longer timeline, which raises the total cost. Understanding these drivers up front helps you scope an engagement that fits your budget without stripping out the work that actually matters.
## How Do You Choose the Right Data Governance Consulting Partner?
**Screen out firms selling a generic framework or their own software as the only fix. Ask for anonymized deliverables from past projects, request case studies from companies your size and industry, and confirm platform-specific hands-on experience with your stack. A weighted scorecard keeps the decision anchored to what actually predicts success.**
Selecting the wrong partner leads to wasted budget, a stalled project, and diminished internal credibility. Evaluate the way you'd evaluate a specialist surgeon: specific expertise, a proven track record, and success with cases like yours.
### Look Beyond Generic Frameworks
Eliminate any firm promoting a one-size-fits-all methodology. A framework built for a global financial institution doesn't fit a regional healthcare provider or a direct-to-consumer retailer. Find a team with hands-on experience in your specific industry - it dictates regulatory constraints (HIPAA in healthcare, for example), how basic terms get defined ("product" in manufacturing versus "policy" in insurance), and the business processes governance has to work around.
### The Technical and Practical Evaluation Checklist
Your RFP and interview process should rigorously evaluate practical skill:
1. **Platform-Specific Technical Chops:** Certified, hands-on experience with your stack ([Snowflake](https://www.snowflake.com/), [Databricks](https://www.databricks.com/), [Google BigQuery](https://cloud.google.com/bigquery))? Ask for examples of governance controls they've built inside these platforms, not bolted on top.
2. **Proof of Implementation, Not Just Theory:** Ask to see anonymized deliverables from past projects - a stewardship RACI matrix, a data quality scorecard, a business glossary. This separates practitioners from theorists fast.
3. **Relevant Industry Case Studies:** No generic success stories. Request two or three detailed case studies from companies of similar size, industry, and complexity, and dig into the specific problems solved and results delivered.
4. **A Flexible, Collaborative Approach:** The best partners co-create the solution with your team, with knowledge transfer written into the contract from day one. Their methodology should adapt to you, not the other way around.
> A top-tier partner leaves your organization self-sufficient. The goal of a good engagement is building internal capability, not creating a dependency on consultants.
### Using a Weighted Scorecard for Objective Evaluation
A polished presentation or a charismatic salesperson can distort the decision. A scorecard anchors it to predefined priorities. Adapt the weights to what matters most to your organization.
| Category | Criteria | Weight (%) |
| :--- | :--- | :--- |
| **Strategic Vision (30%)** | Understanding of your business objectives and a realistic roadmap. | 15% |
| | Connection of governance to strategic initiatives (e.g., AI/ML, analytics). | 15% |
| **Technical Expertise (25%)** | Proven experience with your data stack (e.g., Collibra, Alation, Purview). | 15% |
| | Expertise in your cloud environment (Snowflake, Databricks, AWS, Azure). | 10% |
| **Methodology & Delivery (25%)** | A clear, structured, and adaptable implementation plan. | 15% |
| | A concrete plan for knowledge transfer and team enablement. | 10% |
| **Cultural Fit & Soft Skills (10%)** | Demonstrated ability to manage change and communicate effectively. | 5% |
| | Reference feedback on their collaborative approach. | 5% |
| **Commercials (10%)** | Transparent pricing and clear value proposition in the scope of work. | 10% |
### RFP Questions That Separate Experts from Generalists
A generic RFP gets generic responses. Anchor your request in specific business context (for example: "We're migrating our CRM to a new platform in Q3 and need a data stewardship model for customer data before the cutover") and use scenario-based questions that reveal how a firm actually thinks:
1. Describe a governance project that hit significant resistance from business stakeholders. What were the objections, and how did you get to buy-in?
2. Detail your methodology for measuring ROI on a governance initiative. What metrics do you use to show both financial and operational impact?
3. Assume our budget is cut 30% mid-engagement. Present a revised plan for reprioritizing the roadmap to deliver maximum value with fewer resources.
4. Walk through a governance project that failed or stalled. What were the root causes, and what do you apply differently now?
5. Our data team is resource-constrained. Design a lightweight, sustainable framework that delivers value without excessive administrative overhead.
6. Outline your knowledge-transfer process so our internal team can manage and evolve the program after the engagement ends.
> The best consultants ask clarifying questions before they submit a proposal - a sign they're trying to understand your actual problem, not just win the contract.
### Critical Red Flags to Watch For
* **Pushing Proprietary Tools:** Be wary of firms that insist their own software is the only solution - that's a sign they're selling a product, not a tailored strategy.
* **The "Bait and Switch":** The senior partner who led the sales process shouldn't disappear after signing, leaving junior analysts to run the work. Meet the actual project manager and senior consultant before you sign.
* **Vague Success Metrics:** If a firm can't define success with concrete KPIs, walk away. Their work needs to connect directly to business outcomes - data quality, compliance risk, decision speed.
Using a structured evaluation process cuts the risk of a bad pick. Finding the right **[data governance consultant](https://dataengineeringcompanies.com/data-governance/)** means finding a partner who understands your business, has the technical skills, and is committed to a program that outlasts the engagement.
## Where Is Data Governance Headed?
**Governance is shifting from manual, centralized control toward automated and federated models. AI-assisted tools now handle routine classification and quality monitoring, freeing stewards for judgment calls, while Data Mesh pushes ownership out to the business domains that generate the data instead of a single central team.**
* **Automated Governance:** AI-powered tools increasingly automate data classification, quality monitoring, and policy enforcement, freeing human experts for higher-value work.
* **Data Ethics as a Core Component:** Governance is expanding beyond legal compliance into data ethics - fairness, transparency, and accountability built into the framework itself.
* **Federated Models:** Centralized, command-and-control governance is being replaced by federated models like **Data Mesh**, which lets individual business domains own and manage their data as a "product" instead of routing everything through one central team.
> Data governance is the foundation of trust in a company's data. It's what lets leaders and teams make decisions, move fast, and operate with confidence in a business environment that keeps getting more complex.
## What Should You Do Before You Contact a Consultant?

**Pick one high-value pilot instead of a company-wide overhaul, sketch its scope (data domain, systems, affected teams), and secure an executive sponsor before the first call. Frame the project as solving a specific business problem, not as "a data governance initiative" - that framing gets budget approved faster.**
A large-scale, company-wide overhaul from a standing start tends to run over budget and burn out the organization. The better path: translate "our data is a mess" into one specific, high-impact problem a pilot project can solve.
### Your Pre-Flight Checklist
* **Identify a High-Value Pilot:** Don't try to fix everything at once. Pinpoint one persistent problem - is marketing stuck on bad customer data? Is e-commerce constrained by unreliable product data? These are good starting points.
* **Sketch Out a Preliminary Scope:** Document the target data domain (e.g., Customer Data), the primary systems involved (e.g., Salesforce, ERP), and the teams most affected.
* **Secure an Executive Sponsor:** Non-negotiable. Find a leader directly impacted by the problem who's willing to advocate for the initiative - their political capital matters.
* **Socialize the Business Case:** Frame the project as solving stakeholders' specific business problem, not as "a data governance project." You're helping them hit their targets, not building a framework for its own sake.
With these in place, you have what a good consulting partner needs to build a formal roadmap and secure funding.
### A Word of Caution About Tools
The conversation will turn to technology. The market is full of governance platforms from vendors like [Collibra](https://www.collibra.com/), [Alation](https://www.alation.com/), and [Atlan](https://atlan.com/). These tools scale a governance program - they aren't the program itself.
> A common mistake: buying an expensive data catalog expecting it to be a silver bullet, then finding it unused six months later because no one defined data ownership or set the rules. Tools enable a process; they don't create one.
This is where an experienced consultant earns their fee - defining your process and operating model first, then helping you select and implement the technology that supports it. A consultant's role here typically includes:
* **Deep-Dive Requirements Gathering:** Translating business goals into a detailed list of technical requirements.
* **Objective Vendor Evaluation:** Managing the selection process, from a vendor shortlist through proof-of-concept bake-offs.
* **Phased, Value-Driven Implementation:** Rolling out the tool in a way that supports the pilot project directly, delivering value from day one.
To get a head start on the framework itself, see our [data governance framework template](https://dataengineeringcompanies.com/insights/data-governance-framework-template/) and eight working [data governance framework examples](https://dataengineeringcompanies.com/insights/data-governance-framework-examples/) - [DAMA-DMBOK](https://www.dama.org/cpages/body-of-knowledge), COBIT, EDM Council DCAM, and others - so you can pressure-test which model your consultant is actually applying.
## What Do Teams Usually Ask Before Hiring a Data Governance Consultant?
The same practical questions come up in most first conversations with a prospective firm.
### What's the Real ROI on a Data Governance Project?
Quantifying direct ROI is hard but achievable, typically measured across three areas. First, **cost avoidance** - preventing regulatory fines and the costs of a data breach. Second, **operational efficiency** - time saved when teams stop searching for data, questioning its accuracy, or fixing errors by hand. Third, and usually the biggest, **revenue enablement**: good governance is the foundation for faster decisions, effective AI models, and business growth a good consulting team can trace back to specific metrics.
### Can't We Just Do This Ourselves Without Consultants?
It's possible, but hard. Most companies lack the specialized expertise, dedicated time, or neutral standing a consultant brings. Consultants carry experience from many prior implementations and know the common pitfalls to avoid.
They speed up the process and manage the change management that usually derails internal-only initiatives.
> An internal-only program often gets bogged down in politics, stalls from a lack of visible progress, and fails to demonstrate value. The cost of that failure is usually higher than the cost of hiring help.
### How Do We Make Sure Our Team Actually Learns This Stuff?
Knowledge transfer needs to be a contractual part of the engagement, spelled out in the Statement of Work. Look for:
* **A "co-delivery" model:** Your team works alongside the consultants, not as passive observers.
* **Thorough documentation:** Every process, policy, and technical configuration documented for your team to own.
* **Formal training sessions:** Structured workshops for data stewards and governance council members.
Insist on these from the outset. The goal is for the consultants to make themselves unnecessary by leaving your team able to run the program alone.
### Should We Go with an Independent Consultant or a Large Firm?
Depends on scope, complexity, and internal capacity.
An independent consultant typically brings deep, specialized expertise in a niche area - regulatory compliance for financial services, for example - and is often more agile and cost-effective for strategic guidance or team mentorship.
A large firm provides a full team, established methodologies, and the scale needed for enterprise-wide transformation. If you're implementing across multiple business units and need significant staff augmentation, a firm is usually the better fit.
* **For strategic guidance and team mentoring:** An independent consultant is often more effective.
* **For large-scale implementation and staff augmentation:** A larger firm brings the resources and breadth you need.
### What Does Success Actually Look Like? Defining KPIs Before You Sign
Before signing, define success in clear, quantifiable business terms - a completed checklist of deliverables isn't the goal, measurable improvement in business operations is.
* **Reduction in data errors:** Fewer customer support tickets tied to bad data, or less manual rework in monthly finance reporting.
* **Reduced time-to-insight:** How long the analytics team takes to find, trust, and use data for a new report - weeks down to days.
* **Quantifiable risk reduction:** Passing an internal or external audit, or producing lineage reports for regulators on demand.
* **Increased user adoption of data assets:** Rising usage rates in self-service BI tools are a reliable signal governance is working.
### What's a Realistic Timeline for Seeing Early Wins?
Data governance is a long-term discipline, but you should see tangible results within the first 90 to 180 days. An effective consultant structures the project to deliver quick wins that build momentum:
* Resolving critical data quality issues in a high-visibility executive dashboard.
* Defining and assigning data ownership for a single key domain, like "Customer" or "Product."
* Implementing a business glossary for one department to standardize terminology.
These early wins secure stakeholder buy-in and justify continued investment. If a prospective consultant can't articulate what success looks like in the first six months, they lack the results-oriented approach you need.
---
Ready to find the right expert partner for your data initiative? **DataEngineeringCompanies.com** offers independent firm profiles and practical tools to help you select a consultancy with confidence. Explore the directory to find your shortlist faster. Start your search at [https://dataengineeringcompanies.com](https://dataengineeringcompanies.com).
---
## 8 Practical Data Governance Framework Examples for 2026 and Beyond
Source: https://dataengineeringcompanies.com/insights/data-governance-framework-examples/
Published: 2025-12-29T08:54:16.824253+00:00
Description: Explore 8 practical data governance framework examples, from DAMA to COBIT. Get deep analysis, pros/cons, and actionable tips for your 2026 strategy.
Eight frameworks cover most real-world data governance programs: DAMA-DMBOK, COBIT, FAIR, NIST, ISO/IEC 38505, Gartner's Data Management and Analytics model, Collibra's platform model, and Everest Group's maturity model. Each solves a different problem - enterprise scope, IT control, data sharing, security alignment, board accountability, benchmarking, execution tooling, or vendor evaluation - so most teams combine two or three rather than adopting one wholesale.
Of the 86 firms profiled in the Data Engineering Companies Index, 11 name data governance among their service capabilities - a signal that governance has moved from a compliance checkbox to a standard line item in data engineering scopes of work.
## 1. DAMA-DMBOK (Data Management Body of Knowledge)
### What is DAMA-DMBOK and who is it for?
DAMA-DMBOK is a reference encyclopedia for data management, not a step-by-step framework. Developed by DAMA International, it defines 11 Knowledge Areas that give large, regulated organizations a shared vocabulary for treating data as an enterprise asset.
Financial institutions use DAMA principles to structure data controls for GDPR and CCPA, keeping lineage and quality auditable. Healthcare systems apply its lifecycle and security guidance to protect Patient Health Information across Snowflake and Databricks environments.
### Strategic Breakdown & Analysis
DAMA-DMBOK's strength is exhaustive scope. It pushes organizations to address metadata management, data quality, architecture, and security together rather than in isolation. Its "Knowledge Area Wheel" is the standard visual for how these disciplines connect.
* **When to use it:** Large, mature enterprises with sprawling, multi-platform data environments that need a standardized, enterprise-wide data management function - especially in finance, insurance, and healthcare.
* **Why it works:** It gives IT, legal, and business units a common language and a recognized set of principles, which helps break down data silos and build a culture of stewardship.
> **Key Insight:** DAMA-DMBOK is a mental model, not a project plan. Its value comes from adapting it to your context, not from implementing all 11 knowledge areas on day one.
### How do you start implementing DAMA-DMBOK?
Start with two or three knowledge areas tied to your worst pain points, form a Data Governance Council with executive sponsorship, map policies to your actual platforms (Snowflake tags, Databricks Unity Catalog), and budget for cataloging tools like Collibra or Informatica - manual enforcement does not scale past a handful of teams.
For organizations needing specialized guidance, [data governance consulting services](/insights/data-governance-consulting/) can accelerate DAMA-aligned adoption.
## 2. COBIT (Control Objectives for Information and Related Technology)
### What is COBIT and when should you use it?
COBIT, developed by ISACA, is an IT governance framework built around risk, compliance, and control - useful wherever data governance has to plug into a wider IT governance structure rather than stand alone.
Banks use COBIT to build auditable data controls for SOX and Basel III. Healthcare providers use its control objectives to trace HIPAA compliance from policy down to specific AWS or Azure configurations, which matters for [cloud data security](/data-governance/).
### Strategic Breakdown & Analysis
COBIT's strength is control and auditability. It converts governance principles into specific, measurable control objectives, which is why audit, risk, and compliance teams reach for it first.
* **When to use it:** Public companies, government agencies, and regulated industries that must demonstrate compliance to external auditors, or any enterprise unifying data governance within a broader IT governance structure.
* **Why it works:** It links business goals directly to IT processes and data controls, so governance work reads as risk mitigation, not just a technical exercise.
> **Key Insight:** COBIT is a framework for value creation and risk optimization, not only a rulebook. Use it to build a governance program that auditors recognize and business leaders trust.
### How do you pair COBIT with an operational framework?
Use COBIT for governance, risk, and control structure, and layer DAMA-DMBOK on top for day-to-day data management practice. Benchmark maturity on COBIT's 0-5 Process Capability Model, map control objectives directly into vendor RFPs, and automate evidence collection instead of gathering it by hand for every audit cycle.
## 3. FAIR (Findable, Accessible, Interoperable, and Reusable)
### What are the FAIR data principles?
FAIR is a set of guiding principles, not a formal framework: data should be Findable, Accessible, Interoperable, and Reusable. It originated in the research community to improve data sharing and has since become the default vocabulary for data product management in the enterprise.
Analytics-heavy organizations and AI/ML teams adopt FAIR to power data democratization - making datasets discoverable enough that data scientists can find and reuse them without asking around. Teams migrating to Snowflake or Databricks apply FAIR so the new lakehouse does not turn into a data swamp.

### Strategic Breakdown & Analysis
FAIR's strength is that it targets outcomes, not process. It reframes governance from "control and restriction" to "enablement and reuse," which lands better with the analysts and scientists who actually consume the data.
* **When to use it:** Organizations building a self-service analytics culture, accelerating AI/ML development, or managing large, federated data ecosystems where data-driven innovation is the competitive edge.
* **Why it works:** It targets the most common friction point in data work - finding and understanding relevant data - by prioritizing machine-readable, rich metadata.
> **Key Insight:** FAIR treats data as a reusable product, not a byproduct of some other process. That mindset shift drives adoption and return on a modern data stack.
### How do you operationalize FAIR principles?
Automate metadata extraction with platform-native tools (Snowflake tag propagation, Databricks Unity Catalog) to make data Findable. Define documented, role-based access controls to make it Accessible without being wide open. Standardize business logic with a semantic layer like dbt or Looker for Interoperability and Reusability. Then track time-to-insight and self-service adoption instead of policy adherence alone.
## 4. NIST Data Governance Framework
### What is the NIST Data Governance Framework?
The NIST framework, from the U.S. National Institute of Standards and Technology, is a flexible, principles-based model built around security and continuous improvement. It is lighter than the commercial frameworks and prioritizes risk management aligned with cybersecurity practice over strict prescription.
U.S. federal agencies, defense contractors, and critical infrastructure operators use it as the default because it gives them a government-endorsed, auditable path to demonstrate data stewardship.
### Strategic Breakdown & Analysis
NIST's strength is its tight integration with the [NIST Cybersecurity Framework](https://www.nist.gov/cyberframework). It treats data governance as one component of overall security posture rather than a separate discipline.
* **When to use it:** Federal agencies, government contractors, and critical infrastructure sectors - and any organization already running the NIST Cybersecurity Framework that wants a unified approach.
* **Why it works:** Instead of dictating rigid rules, it sets outcomes and controls that organizations tailor to their own risk profile, stack, and regulatory obligations.
> **Key Insight:** NIST links data governance directly to security controls and risk mitigation, which makes it a measurable part of a security program rather than a standalone data exercise.
### How do you apply NIST alongside other frameworks?
Integrate data governance roles into your existing NIST Cybersecurity Framework program to avoid duplicated effort. Use NIST SP 800-53 control mappings when evaluating data platform vendors, run quarterly assessment cycles instead of a one-time rollout, and layer DAMA-DMBOK on top for data quality and metadata management - NIST covers security well but stays thin on those areas. A [NIST-aligned data governance framework template](https://dataengineeringcompanies.com/insights/data-governance-framework-template/) is a reasonable starting point for documentation.
## 5. ISO/IEC 38505 (Corporate Governance of IT)
### What is ISO/IEC 38505 and why is it board-level?
ISO/IEC 38505 extends corporate governance principles to data, placing accountability with the board and executive leadership rather than the IT department. It gives directors a structure to evaluate, direct, and monitor how the organization uses data as a strategic asset.
Multinational organizations use it to align subsidiaries across legal jurisdictions - a listed company can apply ISO 38505 so that board-level risk appetite carries through consistently to every subsidiary. Technology vendors pursue alignment with it to reassure enterprise clients their products support real governance.
### Strategic Breakdown & Analysis
ISO/IEC 38505's strength is its board-level focus, built on six principles: Responsibility, Strategy, Acquisition, Performance, Conformance, and Human Behavior. It moves the conversation from technical data management to strategic asset oversight.
* **When to use it:** Large, publicly traded, or multinational corporations where board-level oversight is required, or any organization aligning with broader ISO certification efforts.
* **Why it works:** It creates clear accountability at the C-suite and board level, which secures the resources and long-term commitment a governance program needs to survive past its first year.
> **Key Insight:** ISO/IEC 38505 is a strategic overlay, not a substitute for an operational framework like DAMA-DMBOK. It supplies the "why" and "who" from the boardroom; other frameworks supply the "how" and "what" for operational teams.
### How do you get board-level data governance adopted?
Draft a Data Governance Charter around the six ISO 38505 principles and get it board-approved. Form a Data Governance Steering Committee that reports to a C-suite executive or board subcommittee. Combine ISO 38505 for direction with DAMA-DMBOK for execution, and add ISO 38505 alignment questions to vendor RFPs for any partner handling critical data on Snowflake or Azure.
## 6. Gartner's Data Management and Analytics Framework
### What is Gartner's Data Management and Analytics framework?
Gartner's Data Management and Analytics (DMA) model is a diagnostic and benchmarking tool, not a standalone methodology. Built from Gartner's analysis of thousands of organizations, it scores governance, quality, architecture, and analytics capability on a 0-5 scale.
CIOs and CDOs use it to build data strategy roadmaps and justify budget. A retailer might benchmark its data literacy program against industry peers to win executive buy-in for training; a fast-growing tech firm might use it to check AI/ML readiness before committing to a platform build.
### Strategic Breakdown & Analysis
The model's strength is external validation. It moves the conversation from internal opinion to industry-vetted benchmarks, which matters when you need C-suite support and budget.
* **When to use it:** Organizations building a business case for governance, benchmarking against competitors, or evaluating vendors - particularly useful for procurement teams writing RFPs.
* **Why it works:** It supplies an independent, authoritative view that resonates with executives and turns a complex domain into a clear, phased maturity journey.
> **Key Insight:** Gartner's model tells you where you are and where to go next; pair it with a prescriptive framework like DAMA-DMBOK or DCAM for the implementation detail it doesn't cover.
### How do you use a Gartner maturity assessment?
Run a baseline self-assessment across governance, quality, and analytics, and be honest about the score. Cite Gartner's peer benchmarking data in executive presentations to justify funding. Use its Magic Quadrant reports to shortlist governance tooling, and set explicit maturity-level requirements (Level 2 to Level 3, for example) in RFPs for data engineering partners.
## 7. Collibra's Intelligent Data Governance Platform Framework
### What does Collibra's governance framework do differently?
Collibra operationalizes governance through software rather than a paper framework. It embeds stewardship, policy enforcement, and metadata management directly into the workflows where data gets created and consumed, so governance becomes an active process instead of a static document.
Large enterprises running modern stacks use it at scale - tech companies apply it for data democratization on Snowflake and Databricks, and financial services firms use its automated lineage and workflow features to prove regulatory compliance for specific data elements.

### Strategic Breakdown & Analysis
Collibra's strength is turning abstract policy into automated action inside one platform, bridging the business side (defining rules and meaning) and IT (implementing them).
* **When to use it:** Organizations that already have governance principles defined - often DAMA-based - and need to operationalize them at scale on a modern cloud stack.
* **Why it works:** It replaces manual, email-driven governance with automated workflows for access requests and glossary updates, and pulls technical metadata straight from source systems.
> **Key Insight:** Collibra is an operating model, not just a tool. Treating rollout as a business transformation - not a software deployment - is what determines whether it sticks.
### How much does a Collibra rollout cost and take?
Target one or two high-value domains first - customer data or financial reporting - and prove ROI before expanding. Turn on native Snowflake and Databricks connectors from day one for automated lineage. Map governance workflows (report certification, data quality resolution) before configuring the platform. Budget 6-12 months for initial deployment; first-year cost for platform, services, and training typically runs $500K-$1.5M for enterprise projects.
## 8. Everest Group's Data Governance Maturity Model
### What is Everest Group's Data Governance Maturity Model?
Everest Group's model assesses organizational capability across five maturity levels rather than dictating implementation steps. Built from research across hundreds of organizations, it links maturity directly to outcomes like risk mitigation, operational efficiency, and business value.
Procurement teams and executives use it to evaluate data engineering consultancies or benchmark internal programs - a financial services firm might build a multi-year governance roadmap from it, while service providers align their offerings to its criteria to prove governance expertise to prospective clients.
### Strategic Breakdown & Analysis
The model's strength is its external, objective perspective. It shifts the conversation from technical implementation detail to measurable business impact, which resonates with executive audiences.
* **When to use it:** Procurement and vendor management teams running RFPs for data engineering services, or CIOs and CDOs benchmarking initiatives against peers.
* **Why it works:** It gives everyone a common, third-party language for capability, which makes vendor and internal-team comparisons closer to apples-to-apples.
> **Key Insight:** Everest Group's model is an assessment and benchmarking tool, not a how-to guide like DAMA-DMBOK. Its value is in asking the right questions and measuring what matters when evaluating external partners.
### How do you use the Everest model with vendors?
Write RFP questions around Everest's maturity levels and ask vendors to show how past projects hit Level 3 (Managed) or Level 4 (Optimized) outcomes. Use its benchmarking data in board presentations to justify the ROI of moving up a level. Pair it with DAMA-DMBOK - Everest supplies the "what" and "why," DAMA supplies the "how" - and run the assessment annually alongside your strategic planning cycle.
## 8 Data Governance Frameworks Compared
| Framework | Implementation complexity | Resource requirements | Expected outcomes | Ideal use cases | Key advantages | Typical cost/time |
|---|---:|---|---|---|---|---|
| DAMA-DMBOK (Data Management Body of Knowledge) | High - comprehensive, steep learning curve | Large cross-functional teams, metadata tools, training, governance council | Holistic data governance, improved data quality, clear roles and processes | Large enterprises, multi-platform modernization (Snowflake, Databricks) | Industry standard coverage across full data lifecycle; clear role definitions | $500K-$2M+; 12-24 months typical |
| COBIT (Control Objectives for IT) | High - control-focused and detailed | Audit/compliance teams, monitoring tools, governance processes, training | Strong controls, reduced audit findings, regulatory alignment | Regulated industries (banking, healthcare), vendor/procurement assessments | Strong risk/compliance emphasis and alignment with internal audit | Implementation services $300K-$1.5M; training $3K-$8K/person |
| FAIR (Findable, Accessible, Interoperable, Reusable) | Low-Medium - lightweight, principle-based | Metadata/catalog tools, automation, technical stewards, semantic layers | Improved discoverability, interoperability, faster analytics and reuse | Cloud-native analytics, AI/ML teams, Snowflake/Databricks migrations | Modern stack alignment enabling self-service and faster time-to-insight | Tooling $30K-$200K/yr; initial consulting $50K-$150K; months to realize benefits |
| NIST Data Governance Framework | Medium - principles-based and flexible | Internal resources, alignment with NIST cybersecurity, continuous monitoring | Improved security/compliance posture, continuous improvement cycles | Federal agencies, government contractors, critical infrastructure | Government-endorsed, aligns with NIST Cybersecurity Framework | $50K-$200K; iterative implementation with lower upfront cost |
| ISO/IEC 38505 (Corporate Governance of IT) | High - executive/board level engagement required | Executive sponsorship, auditing, consulting, policy documentation | Board-level accountability, cross-border governance alignment, stakeholder confidence | Multinationals, organizations seeking ISO certification and investor assurance | International standard facilitating multi-jurisdictional credibility | Certification $150K-$400K; implementation 18-36 months |
| Gartner Data Management & Analytics (DMA) | Low-Medium - assessment focused, proprietary | Gartner subscription/advisory, assessment services for validation | Maturity benchmarking, peer comparisons, prioritized investment roadmap | CIOs/CDOs, procurement, vendor evaluation and benchmarking | Empirical benchmarking and clear capability statements for decision-making | Subscription $15K-$100K; assessments $50K-$200K |
| Collibra Intelligent Data Governance Platform | Medium-High - platform deployment and change mgmt | Platform licenses, implementation services, integrations, training | Operationalized governance: lineage, metadata, automated workflows | Enterprises needing tool-driven governance on Snowflake/Databricks | Workflow automation, native cloud integrations, automated lineage | Licensing $150K-$500K+/yr; 6-12 month rollout; first-year $500K-$1.5M |
| Everest Group Data Governance Maturity Model | Low-Medium - outcomes-focused maturity assessment | Research subscription, assessment services, benchmarking data | Business-aligned governance roadmap, vendor capability benchmarking | Procurement teams, vendor assessments, ROI-driven governance programs | Outcomes and vendor benchmarking tailored to procurement needs | Subscriptions $10K-$50K; assessments $25K-$100K |
## How do you combine these frameworks into one program?
Pick a structural anchor and layer in controls and roles, rather than adopting a single framework wholesale. A financial services firm might anchor in COBIT's control objectives for auditability while borrowing DAMA's knowledge areas for stewardship and quality. A research-driven biotech might prioritize FAIR for interoperability and layer in a lightweight NIST implementation for security.
Avoid the "big bang" rollout - it overwhelms stakeholders and stalls momentum. Pick one high-impact, low-complexity data domain as a pilot before expanding.
> **Strategic Insight:** Make your first governance project a quick win tied to a live business initiative. If the company is launching an AI-powered recommendation engine, focus initial governance work on the customer data domain that feeds it - a measurable improvement in model accuracy or data prep time builds the case for the next phase.
### What is a practical first-90-days roadmap?
1. **Run a maturity assessment.** Before picking a framework, benchmark your current state - data quality, stewardship, policy enforcement, tooling - using a model from Gartner or Everest Group.
2. **Set business-centric objectives.** Skip "implement a data catalog" and aim for "cut marketing analytics report generation by 30%." That framing keeps governance tied to business value and executive sponsorship.
3. **Build a hybrid starter kit.** Borrow structure (data domains, metadata management) from DAMA, controls (GDPR, CCPA) from COBIT or NIST, and a simple RACI matrix for Owners, Stewards, and Custodians on one domain.
4. **Pilot, measure, iterate.** Launch in the chosen domain, track KPIs against the business objective, and use stakeholder feedback to refine the framework before expanding further.
A working governance program treats data as a strategic asset rather than a compliance cost - the framework choice matters less than whether the pilot ships and the roadmap gets funded past year one.
---
Ready to find an implementation partner? The vetted firm profiles on the [Data Engineering Companies Index](/data-governance/) cover consultancies with real governance-framework experience on Snowflake and Databricks. For the operational playbook that pairs with framework selection, see [data governance best practices](/insights/data-governance-best-practices/) and [data governance strategies](/insights/data-governance-strategies/).
---
## A Practical Data Governance Framework Template for 2026
Source: https://dataengineeringcompanies.com/insights/data-governance-framework-template/
Published: 2025-12-06T06:56:57.085958+00:00
Description: A practical data governance framework template covering policies, RACI roles, processes, and KPIs, plus a phased rollout plan you can run without a big governance team.
TL;DR: Key Takeaways
Practical over Theoretical: Avoid complex, academic models. Start with a "Minimum Viable Governance" approach that solves immediate business problems to build momentum.
The 4 Pillars: Every framework rests on four pillars: 1. Policies/Standards (Rules), 2. Roles/Responsibilities (RACI/Ownership), 3. Processes (Workflows), and 4. Metrics/KPIs (ROI).
Defined Accountability: Success requires clear roles: Data Owners (Strategy/Budget), Data Stewards (Tactical Quality), and Data Custodians (Technical IT).
Phased Rollout: Don't boil the ocean. Secure executive sponsorship, then launch a 90-day pilot on a high-impact domain (e.g., "Customer Data") to prove value.
Tool Selection: Process comes before technology. Define your governance workflows first, then select tools (Catalogs, Lineage) that automate those specific processes.
A data governance framework template needs four parts: policies and standards, defined roles (a RACI matrix), operational processes, and metrics that prove ROI. Skip the 40-page academic model. Start with one high-impact domain, assign owners, and expand from there.
This guide walks through each pillar, gives you a sample RACI matrix, and lays out a 90-day rollout plan you can run without a dedicated governance team.
## Why Do Most Data Governance Initiatives Fail?
Most data governance programs fail because they launch with top-heavy frameworks - dozens of roles and encyclopedic policies before any team sees value. The business reads this as bureaucracy, momentum stalls, and the program dies before a single dataset actually improves.
A successful program skips the all-encompassing plan and starts with a scalable foundation that solves one immediate business problem first.
> A data governance framework isn't a static document. It's a living system that adapts to your organization's maturity, technology, and strategic priorities. The goal is tangible progress, not theoretical perfection.
This guide is built around a **data governance framework template** designed for phased rollouts - quick wins first, broader adoption after.
### Why Does Data Governance Matter Now?
Executives increasingly rank data governance above emerging technology investments like generative AI, because the payoff is tangible: cleaner data for analytics and fewer regulatory headaches. The cost of skipping it shows up in fines, not just inefficiency.
Under GDPR, regulators can fine noncompliant companies up to €20 million or 4% of global annual turnover, whichever is higher ([GDPR Article 83](https://eur-lex.europa.eu/legal-content/EN/TXT/?uri=CELEX%3A32016R0679)).
A practical framework manages that risk while still moving fast enough to matter - it's a launchpad for a program that delivers measurable results early, not a compliance tax.
### What Are the Core Components of a Data Governance Framework?
A data governance framework template rests on four pillars: policies and standards (the rules), roles and responsibilities (a RACI matrix), processes and workflows (how issues get resolved), and metrics (proof it's working). The table below breaks down what each pillar covers.
| Component | Purpose and Key Elements |
| :------------------------ | :---------------------------------------------------------------------------------------------------------------------------------------------------- |
| **Policies & Standards** | Establishes the high-level rules for data: quality standards, security classifications, access protocols, and data lifecycle management. |
| **Roles & Responsibilities** | Defines accountability using a RACI matrix for roles like Data Owners, Stewards, and Custodians to clarify duties and decision rights. |
| **Processes & Workflows** | Outlines standard operating procedures for critical activities, including data issue resolution, new data source onboarding, and metadata management. |
| **Metrics & KPIs** | Answers the question: "Is this working?" Establishes KPIs to track data quality improvements, compliance adherence, and business ROI. |
This structure also helps when you're evaluating outside help - see our guide on [creating a data engineering RFP template](/rfp-template/) for how to translate these pillars into vendor requirements.
## Building Each Pillar of the Framework
Each pillar has a specific job. Together they turn data from a liability you manage defensively into an asset you can actually trust.

The sections below cover each pillar in more detail, moving from high-level policy to hands-on implementation.
### How Do You Write Data Policies People Will Actually Follow?
Treat data policies as your data ecosystem's constitution: high-level principles for how data gets managed, accessed, and used. Keep them concise and tied to business objectives, not technical jargon, and focus only on the areas that carry real risk or opportunity.
* **Data Quality Standards:** Define what "good" means for critical data domains like "Customer" or "Product." A practical standard might be: "All customer records must have a valid email address and a 98% field completion rate for key attributes."
* **Data Security and Classification:** Define sensitivity levels (e.g., Public, Internal, Confidential) and specify handling requirements. For example: "All data classified as Confidential must be encrypted at rest and in transit."
* **Data Lifecycle Management:** Establish rules for data retention, archival, and deletion. This is critical for controlling storage costs and ensuring regulatory compliance.
### Who Owns Data Governance - Owner, Steward, or Custodian?
Three roles cover most governance programs: the Data Owner is a senior business leader accountable for a domain's quality, security, and value; the Data Steward is a subject-matter expert responsible for day-to-day data quality; the Data Custodian is IT staff who manage the underlying systems without owning the data itself.
* **Data Owner:** A senior business leader (e.g., VP of Sales for sales data) who is ultimately **accountable** for the quality, security, and value of a specific data domain. They own strategic decisions and budget.
* **Data Steward:** A subject matter expert **responsible** for the tactical, hands-on management of data. This is often a business user, like a senior marketing analyst, who understands the data's context and use cases.
* **Data Custodian:** An IT or data engineering professional who manages the technical systems where data resides. They implement security controls and maintain infrastructure but don't own the data itself.
A RACI (Responsible, Accountable, Consulted, Informed) matrix is a simple, effective tool for eliminating ambiguity between these three roles.
> **Pro Tip:** Don't attempt to document every data process at once. Select one high-impact activity, like onboarding a new data source, and build a RACI for it. Getting this single process right prevents future conflicts and delays.
This sample RACI for onboarding a new marketing data source clarifies responsibilities and workflows.
### Sample RACI Matrix for New Data Source Onboarding
| Activity/Task | Data Owner | Data Steward | Data Engineer | Business Analyst |
| :--- | :--- | :--- | :--- | :--- |
| **Approve new data source request** | A | R | I | C |
| **Define business requirements** | C | A | I | R |
| **Assess data quality of source** | I | R | C | C |
| **Build data ingestion pipeline** | I | C | R | I |
| **Validate data post-ingestion** | C | R | A | C |
| **Document new source in catalog** | I | R | C | I |
| **Grant user access to data** | A | R | C | I |
This level of clarity distinguishes a functional data governance program from a purely theoretical one.
### What Does a Data Steward Actually Do Day to Day?
Data Stewardship is the operational core of governance - stewards define business terms, resolve data inconsistencies, and enforce policy within their domain. To do that, they rely on a **Data Catalog**: a central, searchable inventory of assets that bridges business and IT.
Essential catalog features include:
* **Business Glossary:** A repository of officially approved, plain-language definitions for key business terms.
* **Data Lineage:** A visual map tracing data's journey from origin through transformations to its final destination. This is indispensable for impact analysis and troubleshooting.
* **Metadata Management:** Rich context about the data, including its owner, steward, quality scores, and security classification.
### How Do You Enforce Access Control and Measure Governance ROI?
Enforce data security with least-privilege access - **Role-Based Access Control (RBAC)** assigns permissions to roles like "Sales Analyst" rather than individuals. Then track defensive, offensive, and adoption metrics, because measurement is what justifies the program's budget next year.
* **Defensive Metrics:** Demonstrate risk reduction (e.g., "**40% decrease in compliance audit findings**").
* **Offensive Metrics:** Highlight value creation and efficiency (e.g., "**15-hour reduction in weekly data cleaning time for analysts**").
* **Adoption Metrics:** Track program integration (e.g., "**Percentage of critical data elements with an assigned steward**").
## How Do You Adapt This Template to Your Organization's Size?
A template is a starting point, not a finished program. Force it onto your organization as a rigid, one-size-fits-all document, and it becomes shelfware - impressive on paper, ignored in practice.
### How Should Governance Change By Company Size?
Governance needs scale with headcount. A corporate-grade model stifles a 50-person startup's agility; a startup's lean approach can't handle a 5,000-employee enterprise's complexity. Match the rigor to your organization's actual size and risk profile.
#### For Startups and Small Businesses (<200 Employees):
* **Implement "Minimum Viable Governance."** Focus on one or two critical data domains, such as "Customer" or "Sales."
* **Consolidate roles.** A single tech-savvy business lead can often serve as both Data Owner and Steward initially.
* **Start with a business glossary.** A simple wiki page documenting the top 20-30 business metrics is a powerful first step to establish a common language.
#### For Mid-Sized Companies (200-2,000 Employees):
* **Formalize stewardship.** Officially designate Data Stewards from business units and make it a defined part of their role.
* **Establish a lean governance council.** A small, cross-functional group that meets quarterly to prioritize initiatives and resolve data conflicts.
* **Invest in a basic data catalog.** Move beyond spreadsheets and wikis. Lightweight, automated cataloging tools are necessary to map data assets and ownership at this scale.
#### For Large Enterprises (>2,000 Employees):
* **Adopt a federated model.** A centralized governance team sets standards and policies, while domain-specific teams manage their own data assets.
* **Automate governance controls.** Manual oversight is not feasible. Rely on automated tools for access control, data masking, and quality monitoring.
* **Integrate governance into the M&A playbook.** Make data governance a core component of due diligence and post-merger integration to prevent the creation of new data silos.
> The goal is not to achieve the highest level of governance maturity. The goal is to implement the *right* level of governance for your organization's current needs, allowing it to evolve as you grow.
### How Do You Map Governance Policy to Snowflake, Databricks, or BigQuery?
Generic governance policies are useless if they ignore your platform's native controls. Map data classification to Snowflake object tagging, center stewardship on Databricks Unity Catalog, and enforce column-level rules through BigQuery's IAM and Policy Tags - each platform already has the enforcement mechanism built in.
* **On [Snowflake](https://www.snowflake.com/en/):** Map your data classification policy directly to [**Object Tagging**](https://docs.snowflake.com/en/user-guide/object-tagging). Detail the use of **Dynamic Data Masking** and **Row-Access Policies** in your access control rules to protect PII.
* **On [Databricks](https://www.databricks.com/):** Center your framework around the [**Unity Catalog**](https://www.databricks.com/product/unity-catalog). Define stewardship and cataloging processes as workflows within Unity Catalog, using its built-in lineage for audits and setting granular access controls.
* **On [Google BigQuery](https://cloud.google.com/bigquery):** Integrate policies with Google Cloud's IAM and Data Catalog. Specify how BigQuery [**column-level security and Policy Tags**](https://cloud.google.com/bigquery/docs/column-level-security-intro) will enforce rules for sensitive data at scale.
This platform-aware approach is what makes a framework enforceable rather than aspirational. Regulated industries like finance and healthcare depend on it - see [data analytics in the insurance industry](/insights/data-analytics-in-insurance-industry/) for a sector-specific example. Embed these technical controls into your documented processes, and the template stops being a PDF and starts being how work actually gets done.
## How Do You Roll Out a Data Governance Framework?
Roll out governance in phases, not all at once. Secure an executive sponsor, assemble a lean cross-functional council, pick one high-impact pilot with a 90-day scope, and communicate every win, in that order. This is a change-management exercise as much as a technical one - you're shifting how the organization treats data, not just installing a tool.
### Who Should Sponsor a Data Governance Program?
Before writing a single policy, get a dedicated executive sponsor who treats governance as a business enabler, not a compliance burden. Without someone who can break down political barriers and secure budget, the program stalls regardless of how good the framework is.
When pitching for sponsorship, focus on business outcomes:
* **To the CFO:** Emphasize mitigating regulatory fines and accelerating the financial close process.
* **To the CMO:** Frame it as creating a single source of truth for customer data to increase campaign ROI.
* **To the COO:** Focus on operational efficiency gains from eliminating redundant data and manual reporting.
### Assemble a Lean Governance Council
Form a small, cross-functional governance council. Avoid creating a bloated bureaucracy. The council's role is to:
1. Prioritize data governance initiatives based on business impact.
2. Serve as the final authority on data definition and ownership disputes.
3. Approve high-level data policies before enterprise-wide rollout.
The council should include the executive sponsor, key business data owners, and representation from the data/IT team to ensure decisions are both strategic and technically feasible.
### Select a High-Impact Pilot Project
Resist the urge to solve all data problems simultaneously. Choose one well-defined pilot project with a high probability of success, a clear business problem, an engaged stakeholder, and a scope that can be delivered within **90 days**.
A common example is tackling the "Customer" data domain. If Sales and Marketing have conflicting customer lists, the pilot can focus on defining "customer," assigning stewards, setting quality rules, and establishing a single, trusted source.
> The right pilot project is critical. An early, visible win creates the success story needed to justify program expansion and secure broader organizational buy-in.
### Develop a Communication Plan
Communicate progress continuously as you execute the pilot. The goal is to demystify data governance and demonstrate its tangible benefits.
Celebrate all wins, no matter how small:
- Did you reduce the time to generate a weekly sales report from four hours to ten minutes? Announce it.
- Did you merge two conflicting customer databases? Explain how this will improve marketing campaign effectiveness.
By framing every update around solving a business problem, you change the narrative. Data governance becomes a valuable service that enables better decision-making, not a restrictive set of rules.
A solid internal framework is also a competitive edge. Globally, 74 countries have open data policies, but only 30 back them with enforcement-ready regulations, a gap that makes a strong internal framework a real differentiator. [See how governance regulation varies by region.](https://www.cigionline.org/articles/the-global-landscape-of-data-governance/)
## What Tools Should You Buy, and What Pitfalls Should You Avoid?
A common mistake is to focus on technology selection before defining processes. Your process should dictate the tool, not the other way around. Defining your processes first clarifies exactly what capabilities you need, preventing over-investment in complex, feature-rich platforms.
The data governance market is projected to grow from $5.38 billion in 2026 to $18.07 billion by 2032, pushed by regulatory pressure and demand for clean data to feed AI systems ([Fortune Business Insights](https://www.fortunebusinessinsights.com/data-governance-market-108640)). That growth means a crowded field of vendors, one more reason to lock down your process before you shop for tools.
### What Should You Ask Vendors During a Data Governance RFP?
Lead vendor conversations with a checklist built from your defined processes, not a generic feature list. Ask how the tool discovers assets across your actual stack, how it visualizes lineage in your environment, and how it turns written policy into automated enforcement.
* **Automated Data Cataloging:** "How does your tool discover and profile assets across our specific tech stack, including [Snowflake](https://www.snowflake.com/en/), [Databricks](https://www.databricks.com/), and our legacy systems?"
* **Data Lineage Mapping:** "Demonstrate end-to-end lineage using a complex, real-world example from our environment." The output must be understandable to both business analysts and engineers.
* **Policy Enforcement:** "How does the tool translate our written policies into automated rules within our data platforms?"

As the graphic illustrates, securing sponsorship and proving value through a pilot project builds the justification for larger technology investments.
### What Are the Most Common Data Governance Mistakes?
Three mistakes derail most governance programs: policies that block legitimate data access, jargon that never connects to business outcomes, and treating governance as a one-time project instead of an ongoing one. All three are avoidable with the right framing.
> **Key Insight:** A data governance framework that slows down the business will be ignored. The goal is to enable faster, more confident decisions, not to create bureaucratic roadblocks.
* **Creating Policies That Inhibit Innovation:** Governance should establish guardrails, not cages. Overly restrictive policies that prevent analysts from accessing data for exploration will be counterproductive.
* **Failing to Connect to Business Outcomes:** Translate technical goals into business impact. Instead of "improving data quality," aim to "reduce customer churn by 5% by providing the sales team with more accurate data."
* **Treating Governance as a One-Off Project:** A data governance framework is a living program that requires continuous attention, communication, and adaptation as the organization and its data evolve.
Snowflake and Databricks both ship native governance features strong enough to delay a third-party tool purchase for a while. Our comparison of [Snowflake vs. Databricks governance capabilities](/snowflake-vs-databricks/) breaks down what each platform handles natively.
By focusing on process first, linking every effort to business value, and avoiding these common pitfalls, you can build a sustainable program and make smarter technology investments when the time is right.
## Frequently Asked Questions
Even the most practical data governance template will generate questions during implementation. Here are direct answers to common queries from teams moving from planning to execution.
### How Do I Get Business Users to Actually Care?
Stop using the term "data governance." Business users in marketing or sales are not motivated by policies or compliance frameworks; they are motivated by solving problems that make their jobs easier.
Connect your governance work directly to their daily pain points. Instead of announcing a new data quality policy, launch a pilot to create a master "Customer" data set. When the sales team gains a single, reliable view of their accounts, they will become your strongest advocates.
> Frame every initiative as a solution to a specific business problem. A success story about reducing report-building time by 30% by eliminating conflicting data sources is far more persuasive than any policy document.
Ultimately, speak their language. When you can draw a direct line from your program to improved lead scoring or faster business insights, you have secured their buy-in.
### What Is the Difference Between Data Governance and Data Management?
Data management builds the infrastructure (roads and bridges), while data governance sets the rules of the road (traffic laws and signs). They are interdependent.
* **Data Management** encompasses the technical, hands-on work: building data pipelines, managing cloud storage, configuring security, and running ETL/ELT jobs. It is the operational implementation.
* **Data Governance** is the strategic layer that provides the framework for data management. It defines accountability, establishes quality standards, and sets the processes for using data securely and ethically.
In short, data management is the *execution*, while data governance is the *direction and oversight*. A data engineer building a pipeline is practicing data management; the standards they follow for quality and security are dictated by governance.
### Should We Build Our Own Tools or Buy a Solution?
For most organizations, a hybrid approach is the most effective path. Get the most out of your existing tools before considering a large-scale platform purchase.
* **On [Snowflake](https://www.snowflake.com/en/):** Master native features like object tagging, dynamic data masking, and row-access policies.
* **On [Databricks](https://www.databricks.com/):** Center your governance efforts around the [Unity Catalog](https://www.databricks.com/product/unity-catalog) for lineage, access control, and discovery.
* **For documentation:** Start with a well-organized Confluence or SharePoint space for your initial business glossary and steward directory.
This "build-light" approach forces you to define your processes first. Let your operational maturity drive technology acquisition. Only consider commercial solutions when manual processes become a clear bottleneck, such as when you need automated lineage tracing across multiple complex systems.
If you're still deciding which model to anchor your program on, compare the eight canonical [data governance framework examples](/insights/data-governance-framework-examples/) - DAMA-DMBOK, COBIT, EDM Council DCAM, and others - side by side before customizing this template.
### How Do We Measure the ROI of a Data Governance Program?
Demonstrate how governance impacts the bottom line by measuring both defensive and offensive value. Establish a baseline for these metrics before you begin and track them quarterly to create a compelling narrative of progress.
| ROI Category | Key Metrics to Track |
| :--- | :--- |
| **Defensive ROI** | • Time saved by analysts no longer manually cleaning and reconciling data. • Reduced cloud storage costs from eliminating redundant and trivial data. • Quantified risk reduction from avoiding potential compliance fines. |
| **Offensive ROI** | • Faster time-to-insight for critical analytics projects. • Measurable lift in sales from cross-selling campaigns powered by trusted data. • Higher marketing campaign ROI from more accurate audience segmentation. |
---
This template covers the core structure; execution still depends on picking the right governance model for your maturity level and knowing which practices actually move the needle. Compare canonical approaches in [data governance framework examples](/insights/data-governance-framework-examples/), or check the tactical checklist in [data governance best practices](/insights/data-governance-best-practices/) before you finalize your rollout.
If you're evaluating outside help, 11 of the 86 firms profiled in the [Data Engineering Companies Index](/data-governance/) name data governance among their service capabilities.
---
## Practical Data Governance Strategies for the Modern Data Stack
Source: https://dataengineeringcompanies.com/insights/data-governance-strategies/
Published: 2026-01-06T09:49:19.340121+00:00
Description: Discover data governance strategies you can implement in cloud environments with practical KPIs, frameworks, and real-world value.
A data governance strategy is the operational plan for treating data as a business asset: policies and standards, defined ownership, a searchable catalog, quality checks, lineage tracking, and security controls, all tied to a specific business outcome. Most programs fail not from a lack of technology but from being run as a bureaucratic checklist instead of a function that earns its budget.
Governance is also a narrower specialty than it might seem. Only 11 of the 86 firms profiled in the [Data Engineering Companies Index](/data-governance/) name it among their core capabilities, a much smaller pool than the firms that list migration or analytics work. That makes vetting a partner's actual governance depth, not just their willingness to add it to a proposal, the harder part of the decision.
What this guide covers:
* The **seven operational components** of a governance program, from policy to lineage.
* A **phased implementation roadmap** that avoids the "boil the ocean" failure mode.
* **Platform-specific governance patterns** for Snowflake and Databricks.
* **KPIs for proving governance ROI** to executives, plus the pitfalls that most often derail a program.
## Why is data governance a business imperative in 2026?
Data governance is the operating system for a company's information assets, not a discretionary IT project. When it works, it directly enables AI development, financial reporting, and customer analytics instead of blocking them - the common failure mode is treating it as an abstract rule-writing exercise disconnected from business priorities.
Think of governance as the wiring inside a building. It's invisible when it works, but nothing else runs safely without it. High-value functions like AI development, financial reporting, and customer analytics all depend on the trusted, secure foundation that governance provides underneath them.
### Connecting Governance to Business Outcomes
The primary reason governance programs fail is a disconnect from tangible business goals. They become abstract exercises in rule-writing and role assignment without a clear "why." An effective strategy starts with a business case that justifies the investment and defines the expected return.
That requires shifting the conversation from technical jargon to business impact.
* **For AI and Machine Learning:** Governance ensures models train on high-quality, unbiased data, which leads to accurate predictions and decisions people actually trust. Without it, you're running a "garbage in, garbage out" cycle that undermines the AI investment.
* **For Analytics and Business Intelligence:** It establishes a single source of truth, so every dashboard and report tells a consistent story. That eliminates conflicting metrics and lets leadership make decisions without arguing over whose numbers are right.
* **For Regulatory Compliance:** A well-run governance program is the primary defense for meeting regulations like GDPR. It creates auditable data lineage and access controls, which are non-negotiable for passing audits and avoiding financial penalties.
> Data governance works when it shifts from controlling data to helping people use it. The goal is to make it easy for teams to find, trust, and act on data to solve real business problems.
### The Cost of Inaction
Ignoring data governance is an active acceptance of risk. Poor data quality shows up as flawed decisions, wasted analyst time re-checking numbers, and missed revenue opportunities - costs that compound quietly until someone asks why the dashboard doesn't match the invoice. A well-executed governance strategy converts that ongoing liability into a competitive asset.
For a deeper look into structuring your initiative, see this [data governance framework template](/insights/data-governance-framework-template/), or if you're still evaluating which model fits, compare eight proven [data governance framework examples](/insights/data-governance-framework-examples/) - DAMA-DMBOK, COBIT, DCAM, and others - to see how the right structure prevents common failures. A modern data governance strategy isn't about restriction, it's about creating the conditions for growth without the risk.
## What are the seven essential components of a governance strategy?
A data governance strategy breaks into seven operational components: policies and standards, roles and responsibilities, stewardship, a data catalog, data quality, data lineage, and security and compliance. Together they work as both a planning framework and a checklist for evaluating tools and implementation partners.
### 1. Policies and Standards
Data policies define the acceptable use, security protocols, and privacy requirements for your data ecosystem. Standards are more granular - they provide specific implementation instructions, such as naming conventions for database schemas or required formats for customer addresses. Without these foundational rules, data practices become inconsistent, which drives up operational chaos and compliance risk.
### 2. Roles and Responsibilities
A plan is useless without people to enforce it. Governance requires clearly defined roles that establish accountability at every level, from the senior Data Owner who is ultimately accountable for a business domain down to the Data Steward who understands the data's context and manages it day to day. Ambiguity about who owns what is one of the fastest ways to stall an initiative.
### 3. Data Stewardship
Data stewardship is the practice of assigning formal ownership for critical data assets. It functions like a property deed for a dataset - it gives a domain expert both the authority and the responsibility to maintain its value. This model turns governance from a top-down mandate into a distributed, collaborative effort, because the people who best understand the data are the ones managing it.
> A data steward with real ownership behaves differently than one with abstract responsibility. When someone holds the official deed to a data asset, they're far more likely to invest the effort to keep it accurate, secure, and valuable for the rest of the organization.
### 4. Data Catalog
A data catalog is the central, searchable inventory of an organization's data assets. Without one, finding the correct dataset turns into an inefficient, tribal-knowledge-based process. A modern catalog from a vendor like [Alation](https://www.alation.com/) or [Atlan](https://atlan.com/) provides rich metadata - ownership, column definitions, quality scores, and lineage - which turns data discovery into a self-service function.
### 5. Data Quality
Data quality is the set of processes and metrics used to confirm data is fit for its intended purpose. Quality rules function as "purity tests" for information, checking for:
* **Accuracy:** Is the customer's email address valid?
* **Completeness:** Is the shipping address field populated in all records?
* **Consistency:** Is the product ID format uniform across all systems?
* **Timeliness:** Is yesterday's sales data available for analysis this morning?
Poor data quality erodes trust and leads to flawed business decisions.
### 6. Data Lineage
Data lineage provides a complete, auditable map of a data point's journey through organizational systems - tracking its path from the original source, through every transformation, to its final destination in a BI dashboard or AI model. This visibility is essential for root cause analysis and a non-negotiable requirement for compliance and auditing.
### 7. Security and Compliance
Security and compliance measures make sure data is accessed and used only by authorized people for legitimate purposes, enforced through controls like role-based access, encryption, and data masking. Compliance ensures the organization adheres to external regulations like GDPR and CCPA. Strong security and compliance functions are the enforcement layer that protects all the other components.
## How do people, process, and technology fit together in a governance framework?
An effective governance strategy is not a static policy document. It rests on three interdependent pillars - people, process, and technology - and a gap in any one of them compromises the whole initiative.
Think of it as a high-performance engine. The *people* are the mechanics who understand how each part functions and interacts. The *processes* are the standardized service manuals they follow, which keep results consistent. The *technology* is the diagnostic equipment that catches issues before they cause a failure. All three are required for the engine to run.
This balanced approach is what turns governance from a theoretical concept into a practical function that creates measurable value.
As this illustrates, a well-structured governance system is the foundation for producing data the organization can trust and use effectively.
### The People: Defining Roles and Responsibilities
Effective governance requires clear accountability. That starts with assigning ownership for data assets - defining who is responsible for specific data domains and their associated quality, security, and usage.
Core roles that must be defined include:
* **Data Owners:** Senior leaders who are ultimately accountable for a specific data domain (Customer, Product, and so on). They don't manage data day to day but are responsible for its security, quality, and ethical use, with final authority on access policies.
* **Data Stewards:** Subject matter experts embedded within business units who understand the data's context and meaning. They define business terms, set data quality rules, and resolve data issues, acting as the liaison between business and IT.
* **Data Governance Council:** A cross-functional steering committee made up of Data Owners and key stakeholders from IT, security, legal, and other core functions. The council sets strategic direction, ratifies enterprise-wide policies, and resolves cross-departmental conflicts.
How these roles get implemented depends on the organization's structure and culture, which makes the choice of organizational model a critical early decision.
#### Comparing Data Governance Organizational Models
A comparison of the three primary models for organizing a data governance program, outlining their pros, cons, and ideal use cases to guide strategic decisions.
| Model | Key Characteristics | Best For | Potential Challenges |
| :--- | :--- | :--- | :--- |
| **Centralized** | A single, central team (often within a CDO office) sets and enforces all data governance policies across the enterprise. | Organizations in highly regulated industries or those with a top-down culture requiring strict, uniform control. | Can create bottlenecks, be slow to adapt to specific business unit needs, and may suffer from a lack of business buy-in. |
| **Decentralized** | Each business unit manages its own data governance independently with minimal central oversight. | Highly diversified conglomerates or organizations where business units operate with significant autonomy. | Results in inconsistent standards, data silos, and makes enterprise-wide analytics extremely difficult. |
| **Federated** | A central team sets enterprise-wide standards and provides tools, while domain-level stewardship is delegated to business units. | Most modern, large organizations. Balances central control with business-level agility and contextual expertise. | Requires strong communication and collaboration to function effectively; can introduce coordination complexity. |
The federated model gives most organizations the best balance, combining centralized standards with distributed, domain-specific expertise.
### The Processes: Driving Consistency Through Action
With roles defined, standardized processes serve as the operational backbone of the governance strategy. These processes translate abstract policies into concrete, repeatable actions - the standard operating procedures for an organization's data.
> A documented process eliminates ambiguity. When a data quality issue arises or a new data set is onboarded, every stakeholder understands their responsibilities and the required actions.
Key processes to formalize include:
* **Metadata Management:** A clear workflow for how data is defined, cataloged, and tagged. This includes documenting business definitions, data lineage, and ownership in a central repository to keep a common vocabulary.
* **Data Quality Monitoring:** A repeatable system for identifying, assessing, and remediating data quality issues. This typically involves automated rules that flag anomalies and a defined workflow for stewards to investigate and resolve them.
* **Access Control and Provisioning:** A formal process for requesting, approving, and periodically reviewing data access. This protects sensitive information while providing necessary access with a clear audit trail.
For a deeper dive, our guide on [data governance best practices](/insights/data-governance-best-practices/) covers actionable steps for implementing these workflows.
### The Technology: Enabling Governance at Scale
Technology is the pillar that automates and enforces the rules and processes you've defined. In 2026, manual governance doesn't hold up against the volume and complexity of enterprise data - automation is a necessity for scaling any governance initiative, not an optional upgrade.
Demand reflects that reality: governance tooling has grown from a niche compliance purchase into a standard line item for any company running data at scale, as manual spreadsheet-based governance simply stops working past a certain size.
A modern governance tech stack typically includes these core components:
* **Data Catalogs:** These tools function as a searchable inventory for all data assets, using metadata to help users discover, understand, and trust available data. Leading platforms include [Alation](https://www.alation.com/), [Collibra](https://www.collibra.com/), and [Atlan](https://atlan.com/).
* **Policy Enforcement Engines:** These platforms translate business rules into automated controls, such as masking sensitive PII or applying row-level security based on a user's role.
* **Data Quality Platforms:** Specialized solutions that continuously monitor data pipelines for anomalies, profile data sets to identify issues, and provide dashboards for tracking key quality metrics.
By integrating people, process, and technology into a cohesive framework, an organization can build a governance system that holds up at scale and adapts as the business changes.
## How should you phase a governance implementation roadmap?
Governing all data at once burns out the team before it delivers any value - the roadmap below breaks the initiative into four stages, each building on the last, instead of attempting one theoretical big-bang rollout.
A well-designed governance framework is worthless if it stays a document nobody acts on. The most common failure mode is trying to govern all data at once, which reliably leads to resource exhaustion and project collapse before any value gets delivered. A phased, iterative approach is the only path that consistently works.
### Phase 1: Assess and Align
This initial phase is dedicated to discovery and alignment. Before building anything, you need to understand the current state and connect governance goals to specific business priorities.
**Key activities:**
* **Stakeholder Interviews:** Engage business leaders, analysts, and IT to identify their most significant data-related pain points. Determine which reports are untrusted and where the most serious compliance risks lie.
* **Data Inventory Audit:** Conduct a high-level inventory of critical data systems. Map where sensitive data lives and identify the most glaring gaps in data quality or security.
* **Business Case Development:** Connect identified pain points to financial impact - for example, link poor customer data quality directly to a measured decrease in marketing campaign ROI.
The objective isn't to solve problems yet but to build a prioritized list of issues worth solving, backed by a compelling business case.
### Phase 2: Design and Pilot
With a clear focus, design the initial governance components and test them in a small-scale pilot. A successful pilot builds credibility and produces lessons for the broader rollout.
Select a pilot project that is highly visible and delivers real business value - addressing data quality issues that affect the quarterly sales forecast, for example.
> A pilot's real goal isn't fixing one problem, it's creating a success story people talk about. A well-executed pilot that cleans up the data behind a critical sales forecast is the most effective way to get executives interested in the broader program.
**Pilot project steps:**
1. **Define Scope:** Narrow the focus to specific data elements - customer account status, deal size, and close date, for example.
2. **Assign Roles:** Formally appoint a Data Owner and a hands-on Data Steward for this dataset.
3. **Implement Standards:** Define a limited set of data quality rules and document them in a minimalist data catalog, such as a structured wiki page.
The desired outcome is a measurably improved result - a more accurate sales forecast, for example - and a documented, repeatable playbook.
### Phase 3: Scale and Automate
With a successful pilot complete, expand the program methodically, moving from one business domain to the next (Sales to Marketing, then Finance). At this stage, replace pilot-phase spreadsheets with enterprise-grade tools: a dedicated data catalog, automated data quality monitoring, and policy enforcement tooling.
This is the phase where the governance strategy transitions from a project into an operational program.
### Phase 4: Optimize and Evolve
Data governance is not a one-time initiative. This final phase focuses on continuous improvement as new regulations, data sources, and business requirements emerge.
**Key activities:**
* **Monitor Metrics:** Continuously track data quality scores, catalog adoption rates, and the volume of data-related support tickets.
* **Gather Feedback:** Regularly ask data stewards and consumers what's working and what needs improvement.
* **Evolve the Framework:** Update policies and standards to address new challenges, such as the adoption of generative AI or expansion into new international markets.
## What does governance look like on Snowflake and Databricks?
Generic governance playbooks don't map cleanly onto Snowflake or Databricks - both are complex, cloud-native ecosystems with their own built-in controls. Getting governance right on either platform means mastering those native features instead of bolting on generic rules or expensive third-party tools.
Success comes down to mastering the built-in security and governance features these platforms ship with, since they're designed to operate at cloud scale. That's the only practical way to secure large-scale data assets without creating bottlenecks that slow down analytics and innovation.

### Tactical Governance Patterns for Snowflake
Snowflake provides a suite of features for enforcing fine-grained control directly within the platform. The strategy is to manage access and protect data at the source rather than relying on external tools. An effective approach layers several native features to build a resilient security posture.
The most effective strategy combines three core capabilities:
1. **Dynamic Data Masking:** This feature hides sensitive data within a column based on the user's role at query time. A policy can be set so only users with the `HR_ANALYST` role see a full Social Security Number, while everyone else sees `***-**-****`. The underlying data stays unchanged; the mask applies on the fly, so there's no data duplication.
2. **Row-Access Policies:** These policies control which rows a user can see, which matters for multi-tenant analytics or departmental data segregation. A policy can ensure a sales manager for the `EMEA` region only sees customer records where the `Region` column equals `EMEA`. These policies attach directly to tables and are enforced automatically on every query.
3. **Object Tagging:** Tagging provides the organizational metadata to manage governance policies at scale. Applying tags like `PII: TRUE` or `DATA_SENSITIVITY: CONFIDENTIAL` to tables and columns lets you automate policy application - a single masking policy can be written to apply to any column tagged `PII: SSN`, which secures that data class across the entire warehouse.
> Layering role-based access control with dynamic masking, row-access policies, and object tagging gives you a system that runs on policy, not manual permissions. That's how you scale governance instead of getting buried managing access to thousands of individual tables.
### Unifying Governance on Databricks with Unity Catalog
Databricks integrates data warehousing, data engineering, and machine learning. The key to governing this hybrid environment is **Unity Catalog**, which serves as a central governance layer for all data and AI assets across every Databricks workspace. Skipping it means giving up the platform's built-in governance layer for something weaker.
Effective governance on Databricks means centralizing control through Unity Catalog's features.
* **Centralized Access Control:** Unity Catalog lets you define user and group permissions in one place using standard SQL (`GRANT`, `REVOKE`). Those rules are then enforced consistently across notebooks, jobs, SQL queries, and ML models, which closes security gaps that come from disparate permission models.
* **Automated Data Lineage:** Unity Catalog automatically captures and visualizes data lineage down to the column level. That lets a data steward trace an anomalous metric on a dashboard back through every transformation, which speeds up troubleshooting and builds trust in the data.
* **Unified Auditing:** All governance-related actions, including data access and permission changes, are captured in a central audit log. That provides a comprehensive record for compliance checks and security investigations - non-negotiable for regulated industries.
These platform-native features have to be part of a broader security strategy. It's worth understanding the wider context of [cloud data security challenges](/data-governance/): while Unity Catalog governs Databricks assets, the underlying cloud storage still needs its own security controls.
Ultimately, the most effective data governance strategies for [Snowflake](https://www.snowflake.com) and [Databricks](https://www.databricks.com) come from mastering their built-in features and embedding governance directly into data workflows.
### Evaluating Partners and Consultancies for Platform Governance
If you're bringing in a consultancy to implement governance on Snowflake or Databricks, the primary filter is fluency with each platform's built-in governance tools. A partner who immediately recommends expensive external tools may lack the technical depth to get the most out of the platform you already own.
Your Request for Proposal should include specific, technical questions to cut through marketing claims.
**Critical RFP questions:**
* **For Databricks:** "Detail your process for implementing Unity Catalog in a multi-workspace environment. How do you manage cross-catalog data access and centralize audit logs for compliance?"
* **For Snowflake:** "Explain how you would architect a solution using Dynamic Data Masking, Row-Access Policies, and Object Tagging to enforce access controls on sensitive financial data at both the column and row level."
A competent response includes real-world examples, discusses potential implementation challenges, and shows a clear understanding of how these features solve concrete business problems - GDPR compliance or intellectual property protection, for example.
Beyond native tools, manual governance doesn't scale. The best partners apply a software engineering mindset, using infrastructure-as-code tools like Terraform or policy-as-code frameworks with [dbt](/insights/dbt-implementation-partners/) to manage permissions, apply policies, and provision access. Ask directly: "Describe your methodology for implementing governance-as-code. Can you show an example of how you've automated data quality rule enforcement within a CI/CD pipeline?"
#### Vendor Evaluation Checklist for Cloud Data Governance
Use this table to distinguish true platform experts from generalists during your vendor selection process.
| Evaluation Category | Key Questions to Ask | Red Flags to Watch For |
| :--- | :--- | :--- |
| **Platform-Specific Expertise** | How have you used Snowflake's Object Tagging and Databricks' Unity Catalog to automate policy enforcement? Provide a specific, real-world example. | Vague answers that list features without explaining how they solve a business problem. Pushing third-party tools before fully exploring native capabilities. |
| **Automation and Governance-as-Code** | Can you walk us through your process for managing permissions and data quality rules as code? Which tools (e.g., Terraform, dbt) do you prefer and why? | A focus on manual processes, UI-based configurations, and spreadsheets. No clear methodology for integrating governance into CI/CD pipelines. |
| **Business Acumen and ROI** | How do you connect governance initiatives to measurable business outcomes like revenue growth or cost savings? How do you build a business case for leadership? | Answers are purely technical (e.g., "number of policies implemented"). They struggle to explain the "so what" for the business. |
| **Organizational Change** | What is your framework for establishing a data stewardship program that actually gets adopted by business teams? | A top-down, command-and-control approach. No mention of communication plans, training, or building a collaborative data culture. |
| **Integration Experience** | Describe a project where you integrated Snowflake or Databricks with an enterprise data catalog like Collibra or Alation. What were the challenges? | Limited or no experience with enterprise catalog integrations. They treat the cloud platform as an isolated silo. |
For a broader evaluation of consultancies specializing in this area, our guide to [data governance consulting services](/insights/data-governance-consulting/) covers what to look for and how to structure the selection process.
## How do you measure the ROI of a governance program?
Governance is a business investment, and proving its ROI means translating activities into KPIs executives already track. A balanced scorecard across operational, business, and financial metrics draws a direct line from governance work to outcomes leadership actually cares about.
### Operational Metrics: The Engine Room KPIs
Operational KPIs measure the efficiency and effectiveness of the governance program itself. They track the performance of data teams and processes, serving as leading indicators of future business value - the diagnostic gauges for your governance engine.
* **Data Quality Issue Resolution Time:** The average time required to remediate a data quality error from detection to resolution. A decreasing trend demonstrates improved workflow efficiency and steward effectiveness.
* **Percentage of Critical Data Elements Under Governance:** The proportion of critical data elements (`customer_id`, `product_sku`, and similar) with an assigned owner, defined quality rules, and formal stewardship. An increasing percentage indicates program maturity and risk reduction.
* **Data Catalog Adoption Rate:** The percentage of target users (analysts, data scientists) actively using the data catalog monthly. High adoption indicates the tool is providing value by enabling self-service data discovery and trust.
### Business Metrics: Connecting Governance to Performance
Business metrics demonstrate how improved governance helps other departments hit their own objectives. These are the KPIs that capture the attention of stakeholders.
> The most powerful way to demonstrate value is to show how your data governance strategy accelerates someone else's success. Frame your ROI in terms of their objectives, not your own.
A few examples:
* **Time-to-Insight for Analytics Teams:** Measure how long it takes the analytics team to go from a business question to a final report. Effective governance cuts the time spent on data discovery and preparation, which otherwise eats up a large share of an analyst's week.
* **Reduction in Compliance Reporting Errors:** Track the number of errors and manual corrections required for regulatory reports (GDPR, CCPA) before and after implementing stronger data controls. This provides a direct link between governance and risk mitigation.
### Financial Metrics: The Bottom-Line Impact
Financial metrics translate operational and business improvements into monetary terms. These KPIs justify the budget and continued investment in the data governance strategy.
* **Cost Savings from Data Redundancy Elimination:** Calculate the direct cost savings from decommissioning redundant databases, storage, and data pipelines identified through governance efforts. This often lowers cloud infrastructure and software licensing costs.
* **Increased Revenue from Improved Data Accuracy:** Connect improved data quality to revenue generation - a retailer, for example, can measure the lift in marketing campaign conversion rates after cleansing its customer database. The formula is straightforward: `(Revenue with governed data) - (Revenue with ungoverned data) = ROI`.
Tracking metrics across these three tiers lets you build a narrative showing how operational improvements (faster issue resolution) lead to business acceleration (quicker analytics), which in turn drives financial results (higher sales). That's what proves data governance is a value-creation engine, not a cost center.
## What governance pitfalls derail otherwise well-designed strategies?
Even a well-designed data governance strategy can fail during execution. Success depends not just on picking the right framework but on anticipating and avoiding predictable traps that derail initiatives.

Many initiatives fail because they treat governance as a one-time project. That's a fatal flaw, since data is a dynamic asset that keeps changing and growing.
### Pitfall 1: Treating Governance as a Project
Viewing data governance as a project with a defined end date guarantees its failure. Once the initial setup is complete and the project team disbands, the system starts to decay. Policies go stale, stewards disengage, and the program's value erodes.
* **Red Flag:** The initiative is described with project-based language, like "the governance project will conclude by Q4." That signals the organization sees it as a temporary task, not a permanent function.
* **Corrective Action:** Frame governance as an ongoing program from the start. That means securing a permanent operational budget (OPEX) instead of a one-time project fund (CAPEX), standing up a governance council, and writing governance responsibilities into official job descriptions.
### Pitfall 2: Neglecting Business Outcomes
A common error is focusing too much on technical details - metadata catalogs, data cleansing - without connecting them to business objectives. If stakeholders can't see a direct link between governance work and their goals, they'll pull their support.
> A governance program that can't articulate its value in terms of business ROI reads as a cost center. It needs to directly enable key objectives, like accelerating analytics, improving customer segmentation, or ensuring regulatory compliance.
Regulatory pressure is a major driver of adoption, with many organizations citing compliance as their primary motivation for investing in governance. That positions governance as a business necessity, not an optional IT project.
### Pitfall 3: Trying to Boil the Ocean
Attempting a comprehensive, enterprise-wide framework from day one almost always leads to analysis paralysis. The scope becomes unmanageable, planning drags on indefinitely, and the team fails to deliver anything tangible before it burns through its political capital.
* **Red Flag:** The initial roadmap tries to govern every data domain across all business units at once. This approach is rarely executable.
* **Corrective Action:** Adopt an iterative, agile approach. Start with one high-impact business problem within a single, well-defined data domain (Customer or Product, for example). Deliver a quick win that solves a real pain point, then use that success to build momentum and secure support for the next phase.
## What does global data policy mean for multinational governance strategies?
A governance strategy built only for domestic rules breaks down the moment a company operates across borders. Multiple overlapping privacy laws and industry standards mean global organizations need jurisdiction-aware controls, not a single one-size-fits-all policy.
Regulators, standards bodies, and industry alliances now shape data policy in dozens of countries at once, and the list keeps growing. That density of overlapping rules is what makes a single global policy template obsolete for any company operating in more than one market.
> A data governance strategy that isn't fluent in multi-jurisdictional compliance is incomplete. This isn't just about avoiding fines - it's about building a data architecture that holds up under regulatory scrutiny in every market you operate in.
### What This Means for Vendor Selection
This global complexity directly affects partner selection, particularly for modern data platforms like Snowflake or Databricks. Expertise in multi-jurisdictional compliance is now a baseline requirement for any consultancy supporting a global data program.
When vetting a data consultancy, extend your technical evaluation to assess their understanding of the global regulatory environment.
* **Ask About Specific Regulations:** Inquire about their direct experience implementing controls that satisfy GDPR in Europe, CCPA in California, and PIPEDA in Canada concurrently.
* **Probe Data Residency Solutions:** Challenge them on their strategies for managing data residency and cross-border data transfers. How do they handle data sovereignty laws in practice?
* **Evaluate Their Monitoring Framework:** How do they keep pace with changing regulations, and how do they translate new legal requirements into actionable data policies within your systems?
Selecting a partner with this expertise is a strategic decision that builds a more resilient data infrastructure capable of supporting global business growth.
## Common Questions We Hear About Data Governance
Several key questions consistently arise when organizations start exploring data governance. Here are direct, practical answers.
### How Do We Start With Limited Resources?
Don't attempt to govern everything at once. The most effective approach on a limited budget is a small-scale, high-impact pilot project.
Identify a single business problem clearly caused by poor data quality - an inaccurate sales forecast or a time-consuming compliance report, for example. Focus all initial effort on solving that specific issue. A clear, measurable win, even a small one, provides the evidence needed to secure buy-in and resources for a broader program.
> Data governance on a shoestring budget isn't about doing less, it's about doing the right things first. A single, measurable win in a high-visibility area is worth more than a dozen half-finished initiatives.
### Should Our Strategy Be Centralized or Federated?
For most modern organizations, a purely centralized, top-down model is too rigid and slow. A federated or hybrid approach is typically more effective.
A central governance council should establish enterprise-wide policies, core standards, and shared tools to keep things consistent. But day-to-day responsibility for data quality and stewardship needs to live within the business domains - the marketing team knows marketing data best; the finance team knows financial data best. This "hub-and-spoke" model balances central oversight with domain-specific expertise and agility, and it keeps the central team from becoming a bottleneck.
For a side-by-side comparison of centralized, decentralized, and federated structures, including their ideal use cases, see the [organizational models table](#comparing-data-governance-organizational-models) in the framework section above.
### What's the Real Difference Between Data Governance and Data Management?
These terms are often confused but represent distinct concepts.
**Data management** covers the entire operational infrastructure for handling data - the databases, pipelines, and storage systems used to ingest, transport, and process information. It is the "how" of day-to-day data operations.
**Data governance** is the framework of rules, policies, and standards that ensures this infrastructure operates correctly, securely, and efficiently. Governance provides the rulebook; management executes the plays. See [data governance vs. data management](/insights/data-governance-vs-data-management/) for a fuller breakdown of where the two overlap and where they don't.
### How Do I Get the Business to Actually Care About a Governance Program?
The key is to shift the focus from governance terminology to business problems.
No business leader is motivated by "improving metadata," but they care about helping their sales team find trustworthy customer data faster. Frame every governance initiative in terms of a tangible business outcome: reducing risk, saving time, or creating new revenue opportunities.
> The way to win over the business is to find a specific, high-visibility pain point in one department and solve it. Use that small win, backed by clear metrics, as your internal case study. Success spreads on its own after that.
Start with a pilot project. If the marketing team spends days each quarter manually cleaning campaign lists, address that specific problem. The positive feedback from that team becomes your most effective tool for winning broader organizational buy-in.
### Should We Build Our Own Governance Tool or Just Buy One?
For most companies, buying a dedicated data governance tool is the more strategic decision. Building a comparable solution from scratch is a significant software engineering undertaking.
It involves not just building an application but committing to the long-term maintenance of a complex system that includes a data catalog, automated lineage, and policy engines - which requires a dedicated product team.
Commercial tools from vendors like [Alation](https://www.alation.com/), [Collibra](https://www.collibra.com/), or [Atlan](https://atlan.com/) provide this functionality out of the box, which lets your team focus on the higher-value work of defining and applying governance policies. A custom-built tool risks becoming a resource drain, while a commercial solution can act as a real accelerator for your governance program. When evaluating vendors, prioritize solutions that integrate cleanly with your existing data stack, such as [Snowflake](https://www.snowflake.com) or [Databricks](https://www.databricks.com), and can scale with your organization's needs.
Choosing a framework is the easier half of this problem. The harder half is finding a partner who can actually implement platform-native governance instead of layering on generic tools - use the [vendor evaluation checklist](#vendor-evaluation-checklist-for-cloud-data-governance) above, and cross-reference it against a broader look at [data engineering vendor evaluation criteria](/insights/data-engineering-vendor-evaluation-criteria/) before you sign anything.
---
## Data Governance vs. Data Management: A Practical Comparison
Source: https://dataengineeringcompanies.com/insights/data-governance-vs-data-management/
Published: 2026-02-15T09:01:38.492408+00:00
Description: Understand the critical differences in the data governance vs data management debate. Learn how to align strategy and operations for a modern data platform.
Data governance vs. data management comes down to strategy versus execution. **Data governance** sets the policies, standards, and decision rights for how an organization treats data as an asset. **Data management** is the operational work of applying those policies across the data lifecycle - moving, storing, cleaning, and securing the data itself. Neither replaces the other: a platform without governance runs on inconsistent rules, and governance without management is a policy document nobody enforces.
## What Is the Difference Between Data Governance and Data Management?
Governance defines the rules: who owns a dataset, what quality bar applies, and who can access what. Management executes those rules by building pipelines, running databases, and enforcing security controls day to day. One sets direction; the other builds and runs the system.
Teams often use the two terms interchangeably, which blurs who owns what and leads to duplicated tooling and unclear escalation paths when something breaks. The clearest way to separate them: governance is the blueprint for a house - foundation requirements, electrical codes, room layout - and data management is the crew that builds it, laying pipe and running wire against that blueprint.
Skip either half and the failure mode is predictable. Data management without governance produces inconsistent silos, where five teams define "active customer" five different ways because no one owns the definition. Governance without management stays theoretical - a policy binder no pipeline ever enforces. Mastering both is what turns data into a functional enterprise asset instead of a strategy no one implements or a toolset with no direction.
For the operating model itself, see [practical data governance strategies](/insights/data-governance-strategies/), which maps the process, and the [data governance framework template](/insights/data-governance-framework-template/), which gives you a four-pillar starting structure.
### Data Governance vs. Data Management: A Quick Comparison
| Dimension | Data Governance (Strategic Framework) | Data Management (Operational Execution) |
| :--- | :--- | :--- |
| **Core Purpose** | Establishes accountability, policies, and standards for data as a strategic asset. | Implements the processes and systems for collecting, storing, protecting, and using data. |
| **Primary Focus** | The "why" and "what" - defining data-related rules, roles, and decision rights. | The "how" - executing data lifecycle tasks from ingestion to archival. |
| **Key Activities** | Policy creation, data stewardship, compliance monitoring, and metadata definition. | Data integration (ETL/ELT), database administration, data warehousing, and quality control. |
| **Business Scope** | Enterprise-wide, cross-functional, focused on strategic outcomes and risk mitigation. | Primarily technical and operational, focused on specific projects, systems, and platforms. |
Governance sets the direction; management builds and runs the system that follows it.
## Why Does This Distinction Matter for Your Data Strategy?
Conflating governance and management causes real damage: engineering teams build technically sound pipelines that violate compliance rules, or governance writes policies no one on the technical side ever implements. The gap shows up first - and gets expensive fastest - in AI projects, where ungoverned training data creates legal and model-quality risk at the same time.
A model is only as reliable as its training data. Without a governance layer defining consent, PII handling, and lineage, even a well-built pipeline on [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/) will produce unreliable, biased, or non-compliant output - the same "garbage in, garbage out" problem, just at enterprise scale with real financial and legal exposure attached.

### How Do AI and Regulation Raise the Stakes?
Regulations like the EU AI Act require documented proof of how training data was sourced, labeled, and used - proof that only exists if a governance framework produced it. Data management then executes what governance defines.
Consider a practical example:
* **Data Governance** sets the policy: "All customer data used to train personalization algorithms must have documented consent and be fully anonymized."
* **Data Management** builds the solution: data engineers write ETL pipelines that automatically apply masking functions to personally identifiable information (PII) before it reaches a training environment.
Skip the governance rule, and engineering can ship a technically clean pipeline that still leaks sensitive data - turning a working AI model into a legal liability.
### How Does Governance Move From Cost Center to Advantage?
Treating governance as a compliance checkbox misses the point. It's what lets analysts and data scientists build on data without re-verifying its accuracy or provenance every single time. That trust compounds: fewer disputes about whose numbers are right, faster sign-off on new use cases, less rework when a report reaches the board.
> Data governance is what turns data from a raw, risky liability into a reliable, strategic asset - it gives teams the confidence to build on data without re-checking it constantly, from analytics dashboards to generative AI training sets.
Market data backs the shift: the global data governance market grew from $1.81 billion in 2020 to a projected $5.28 billion by 2026, a 20.83% CAGR, with cloud-based solutions holding 72.44% of market share in 2025 ([Arizton, via GlobeNewswire](https://www.globenewswire.com/en/news-release/2021/08/25/2286422/28124/en/Data-Governance-Market-Size-to-Reach-Revenues-of-USD-5-28-Billion-by-2026-Arizton.html)). Legal and compliance functions are now driving governance budgets alongside IT, not just reviewing them after the fact.
### How Does This Build the Business Case for CTOs?
For CTOs and Heads of Data, the case is simple: a powerful data platform without governance is a Formula 1 car with no traffic laws - technically impressive, operationally reckless. A cohesive strategy needs both.
A strategy that integrates both disciplines ensures that:
* **Data is trustworthy and reliable**, leading to better business decisions.
* **Regulatory compliance is built in**, not bolted on during a last-minute panic.
* **Data initiatives deliver ROI** because teams can use high-quality data safely and effectively.
For what "good" actually looks like in execution, see the [10 data governance best practices for 2026](/insights/data-governance-best-practices/), covering frameworks, lineage, data contracts, and access control.
Governance provides the strategy and the rulebook; management provides the operational muscle to carry it out. Neither works alone.
## Who Owns Governance vs. Management?
Governance roles are strategic - Data Owners, Data Stewards, and a Governance Council set policy and don't touch infrastructure. Management roles are tactical - Data Engineers, DBAs, and Data Architects build and run the systems that enforce those policies.
Clear organizational structure is what turns the governance-versus-management split from theory into daily practice. Without it, accountability blurs, work gets duplicated, and teams end up arguing over who owns a broken pipeline instead of fixing it.
Think of it as a highway: the governance team designs the blueprint, sets speed limits, and defines the rules of the road. The management team paves the asphalt, paints the lines, and keeps traffic flowing. Keeping the two separate is what makes a data culture both innovative and compliant.
### What Does the Governance Team Own?
Governance roles decide the "what" and "why": who's accountable for a data domain, what quality bar applies, and who ratifies enterprise-wide policy. They don't write pipeline code.
Key governance roles typically include:
* **Data Owner:** A senior business leader with ultimate accountability for a specific data domain, like "customer data" or "product data." They make final decisions on data quality standards, access rights, and security to ensure alignment with business goals.
* **Data Steward:** A subject matter expert, usually embedded within a business function, who handles the day-to-day stewardship of a data domain. They define what each data element means, set quality rules, and investigate the root cause of any issues.
* **Governance Council:** A cross-functional committee of Data Owners and other key leaders. This group is the final authority for ratifying enterprise-wide data policies, resolving inter-departmental disputes, and providing executive oversight for the governance program.
A documented data governance policy is what translates these roles into concrete, assigned responsibilities instead of abstract goals.
### What Does the Management Team Own?
Management roles decide the "how": Data Engineers build the pipelines, DBAs administer databases and access, and Data Architects design the system that has to support both governance rules and day-to-day operations.
Common data management roles include:
* **Data Engineer:** The builders. They construct and maintain the data pipelines that extract, transform, and load data. They are tasked with implementing the data quality checks and security protocols defined by Data Stewards.
* **Database Administrator (DBA):** A DBA is responsible for the performance, security, and availability of databases. They execute the access control policies set by Data Owners, ensuring only authorized individuals can see specific data.
* **Data Architect:** This person designs the overall structure of the organization's data ecosystem. Their job is to ensure the system is scalable, efficient, and able to support both governance rules and practical management needs.
> A common failure point in the data governance vs. data management relationship is when governance policies are created in a vacuum without consulting the technical teams responsible for implementation. Collaboration between Data Stewards and Data Engineers is what makes the split actually work.
Here is a real-world workflow. A healthcare provider's **Governance Council** decides on a new policy: all patient Personally Identifiable Information (PII) must be masked in non-production environments. The **Data Owner** for patient data approves this. The **Data Steward** for patient records then defines the specific masking rules (e.g., replace the last five digits of a Social Security Number with 'X').
Finally, the management team executes. The **Data Engineering** team modifies their ETL pipelines to apply this masking logic, while the **DBA** confirms that production database access controls remain locked down. This complete workflow, from policy decision to production change, shows how the two disciplines work in partnership.
## How Do Processes and Tools Connect Governance to Management?
Governance rules only matter once they're wired into the pipeline - a data catalog that surfaces a masking policy before a query runs, or a policy engine that blocks an unauthorized join. Without that link, governance stays a document and management runs without guardrails.

### Which Tools Support Governance Processes?
Governance processes are the decision-making layer: setting the rules of the road for an organization's data, establishing accountability, and defining a common vocabulary.
These high-level processes are enabled by a specific class of tools built for visibility and control:
* **Policy Creation and Stewardship:** The human side of governance, where Data Stewards and Owners collaborate to create business glossaries, define data quality standards, and set access rules. This means documenting what the data *means* and who's allowed to use it.
* **Compliance Audits:** Systematically checking that data handling practices align with regulations like **GDPR** or **CCPA**, as well as internal security policies. This creates a provable record of adherence.
* **Key Enabling Tech:** The data catalog is the operational hub for governance. A modern catalog from a vendor like [Alation](https://www.alation.com/) or [Collibra](https://www.collibra.com/) acts as a searchable inventory of all your data assets, making policies discoverable and linking them directly to the datasets they govern. Policy engines then automate enforcement of the access controls stewards define.
> The real value of governance tech is making policies *active*, not passive documents in a shared drive. A good data catalog surfaces a rule to a data analyst at the moment they're about to run a query.
### Which Tools Support Management Processes?
Data management is where theory becomes practice - the hands-on work data engineering and operations teams do to move, store, clean, and deliver reliable data to the business.
These activities rely on a different set of tools - built for execution, scale, and performance:
* **Data Integration and Transformation (ETL/ELT):** The core work of building data pipelines - ingesting data from source systems, cleaning and transforming it, and loading it into a warehouse or lakehouse.
* **Master Data Management (MDM):** A specialized process focused on creating a "single source of truth" for critical business data like customers, products, or suppliers, by consolidating data from multiple systems into one authoritative record.
* **Data Quality Monitoring:** The technical implementation of quality rules governance defines - building checks into pipelines to detect anomalies, validate formats, and measure accuracy over time. For more detail, see this guide on [data reliability engineering](/insights/data-reliability-engineering/).
* **Key Enabling Tech:** The toolkit here includes **ETL/ELT platforms** (like [Fivetran](https://www.fivetran.com/)), **data pipeline orchestrators** (like [Apache Airflow](https://airflow.apache.org/)), dedicated **MDM platforms** ([Informatica](https://www.informatica.com/), [Profisee](https://profisee.com/)), and specialized **data quality tools** ([Monte Carlo](https://www.montecarlodata.com/), [Great Expectations](https://greatexpectations.io/)).
### Which Tool Maps to Which Function?
| Tool Category | Primary Function | Supports Governance or Management | Example Vendors Or Tools |
| :--- | :--- | :--- | :--- |
| **Data Catalogs** | Discoverability, metadata management, business glossary, data lineage | Governance | Alation, Collibra, Atlan |
| **Data Quality Tools** | Data profiling, anomaly detection, rule-based validation | Both (Rules from Gov, Exec from Mgmt) | Monte Carlo, Great Expectations, Soda |
| **MDM Platforms** | Creating and managing a single source of truth for key entities | Management | Informatica, Profisee, Semarchy |
| **Data Warehouses/Lakehouses** | Storing, processing, and analyzing large volumes of structured data | Management | Snowflake, Databricks, Google BigQuery |
| **Access Control/Masking** | Enforcing rules on who can see what data, often at the platform level | Governance | Native platform features (Snowflake), Immuta, Okera |
| **ETL/ELT Tools** | Ingesting and transforming data from source to target systems | Management | Fivetran, dbt, Matillion |
Each tool has a center of gravity in either governance or management, even as more platforms add features that cross both.
### How Are Modern Platforms Bridging the Gap?
The lines are blurring as unified platforms like [Snowflake](https://www.snowflake.com/) and [Databricks](https://www.databricks.com/) add native features on both sides.
Snowflake is a clear example of the convergence:
* **For Data Governance:** role-based access controls (RBAC), object tagging to classify sensitive PII, and dynamic data masking policies - features a Data Steward configures directly on the data.
* **For Data Management:** a SQL engine, Snowpipe for continuous data ingestion, and scalable compute and storage - the core capabilities data engineers need to build and run pipelines.
When governance controls live inside the platform itself, enforcement gets simpler and more automatic. A steward defines a masking policy once, and it applies every time an engineer's transformation job or an analyst's query touches that data - a direct, working link between governance strategy and technical execution.
## How Do You Measure Governance and Management Performance?
Governance KPIs track risk and trust - stewardship coverage, compliance incidents, data literacy. Management KPIs track execution - pipeline uptime, query performance, master data accuracy. Both sets of numbers have to show up together to prove the program is actually working, not just running.
Without clear metrics, governance can feel like a bureaucratic drag and management can look like a cost center with no visible return. Performance has to be viewed through two different lenses: governance success is strategic, management success is operational.

### What Are Good Governance KPIs?
Governance tracks risk reduction, trust, and alignment with business goals - not pipeline speed, but the health and reliability of the entire data ecosystem.
Effective governance KPIs point to real business outcomes:
* **Percentage of critical data elements under stewardship:** This metric indicates maturity. How much of your most vital data has a dedicated owner accountable for its quality and use?
* **Reduction in data-related compliance incidents:** This is a direct measure of risk mitigation. Are you seeing fewer audit findings or regulatory fines this year compared to last?
* **Data literacy score improvements:** Tracked through simple surveys, this shows whether people across the organization understand and trust the data they're using.
> Data governance proves its worth not through speed, but through safety and confidence. A successful program turns compliance from a reactive fire drill into a predictable, systematic function auditors can easily verify.
### What Are Good Management KPIs?
Data management metrics are more concrete and technical. These KPIs track the efficiency and accuracy of the systems that move and transform data daily, giving engineering leads the numbers needed to justify resources or new tools.
Key management KPIs often include:
* **Data pipeline reliability (Uptime/SLA adherence):** What percentage of your data ingestion jobs finish on time without errors?
* **Query performance improvements:** How much faster are critical dashboards loading? Materially faster load times free up analyst time without adding headcount.
* **Master data accuracy:** In your MDM system, what percentage of customer or product records are complete, unique, and error-free?
### How Do KPIs Connect to Compliance?
A solid governance framework is the only practical path to sustainable regulatory compliance. You need documented policies, clear ownership, and auditable controls to satisfy regulators under laws like GDPR and CCPA. When these rules touch AI systems specifically, the bar gets higher still - documented consent, lineage, and audit trails become non-negotiable, not optional.
It's a two-way street. The governance team defines the rules for compliance, and the data management team builds the technical controls - data masking, access logging - that make them real. The KPIs from both sides together tell the full story of a data program that's efficient, secure, and trustworthy.
## How Do You Choose a Data Engineering Partner That Gets This Right?
Only 11 of the 86 firms profiled in the Data Engineering Companies Index name data governance among their service capabilities. Most data engineering shops build pipelines and stop there, which makes governance fluency one of the clearest signals of a partner worth trusting with your data platform.
The right partner doesn't just build what you ask for - they push back and build what you need: a platform that's powerful and trustworthy. That means evaluating methodology and philosophy, not just tool proficiency.
### What Questions Reveal Real Governance Expertise?
Any consultancy can list Snowflake or Databricks on their website. What separates the ones worth hiring is whether governance is built into their engineering workflow or bolted on afterward. How they answer process-oriented questions reveals which one you're dealing with.
Use these pointed questions to assess a potential partner's real capabilities:
1. **Governance Integration in Development**
* **Don't ask:** "Do you have experience with data governance?"
* **Ask this instead:** "Describe your process for embedding governance rules, like data quality checks and masking policies, directly into your CI/CD pipelines for data transformations."
2. **Measuring Data Quality as a Service**
* **Don't ask:** "Can you help us with data quality?"
* **Ask this instead:** "How do you measure and report on data quality as a managed service? Can you show us examples of data quality dashboards or reports you provide to clients?"
3. **Stewardship and Collaboration**
* **Don't ask:** "How do you work with our business teams?"
* **Ask this instead:** "Walk us through a past project where you collaborated with business-side Data Stewards. How did their input on data definitions and business rules directly influence the design of the data models and ETL logic?"
These questions force a partner to demonstrate their capabilities, not just claim them.
### What Should Your RFP Checklist Include?
A structured evaluation framework keeps you focused on strategic alignment instead of getting lost in technical jargon. The right partner proves they can both build the infrastructure (management) and enforce the rules that make it valuable (governance). When you're ready to select a team, a specialized [data governance consultant](/insights/data-governance-consulting/) can help.
**Essential Partner Evaluation Criteria**
| Evaluation Area | What to Look For | Red Flags |
| :--- | :--- | :--- |
| **Methodology** | A clear, documented approach for integrating governance checks into every stage of the data lifecycle. | Treating governance as a separate, final "step" or a box to be checked before go-live. |
| **KPIs & Reporting** | Proactive suggestions for both operational (management) and strategic (governance) KPIs. | A focus on technical metrics like pipeline speed without connecting them to data trust or quality. |
| **Team Structure** | Evidence of roles or training that bridge the gap between engineering and business stewardship. | A team composed entirely of engineers with no proven experience working with business stakeholders on policy. |
| **Tooling Philosophy** | A platform-agnostic approach that prioritizes solving your business problems over pushing a specific vendor's tools. | Insisting on using a specific toolset without a clear justification tied to your governance and management needs. |
> The real test of a data engineering partner isn't pipeline uptime - it's whether the business actually trusts the data enough to act on it.
Use this checklist to weigh a partner's ability to deliver a platform that's both well-governed and well-managed - the combination that generates lasting business value.
## Frequently Asked Questions
### Can You Have Data Management Without Data Governance?
Yes, but it's a recipe for disaster. Data management without governance is like building a house without a blueprint. You can lay pipes and run wires (the **data management** activities), but without an architectural plan (**data governance**), you'll create a chaotic, unreliable, non-compliant system. This ad-hoc approach leads to data silos and technical debt that gets exponentially harder to resolve later.
### Where Should Our Organization Start First?
For most organizations, the best starting point is a small, focused data governance initiative. Instead of launching a massive, enterprise-wide program, select one critical data domain - like "customer" or "product" - and define ownership and quality rules for it.
> Start by defining the "what" and "why" for a single, high-value data asset. Once you have a clear governance mandate for that specific area, your data management team can execute on it. This ensures your first steps deliver tangible business value.
This targeted approach lets you achieve quick wins and build momentum. Once the governance rules are clear for that first domain, your data management team has a precise roadmap to follow for implementation.
### How Does AI Impact The Need For Both?
AI and machine learning raise the stakes for both disciplines dramatically. The data governance vs. data management discussion gets amplified because AI models are entirely dependent on high-quality, trustworthy training data.
* **Data Governance** provides the ethical and compliance guardrails - policies for data usage, bias detection, and model transparency, all essential for navigating regulations like the EU AI Act.
* **Data Management** delivers the technical muscle - building the pipelines needed to clean, label, and version the enormous datasets required to train and retrain AI models reliably.
Without strong governance, AI becomes a legal and reputational risk. Without effective management, the models simply fail to perform.
### Are Data Catalogs A Governance Or Management Tool?
[Data catalogs](https://atlan.com/what-is-a-data-catalog/) sit at the intersection of both, but their primary function is to **enable governance**. Think of a catalog as the central inventory for all your data assets, making governance policies discoverable and actionable.
While data management teams use the catalog to find and understand data for their projects, its core purpose is to operationalize governance - surfacing context, lineage, and quality metrics directly inside the user's workflow, so abstract policies become tangible and enforceable.
---
Data governance and data management work as a pair, not a choice. Only 11 of the 86 firms profiled in the Data Engineering Companies Index name data governance among their service capabilities - browse the [data governance firm directory](/data-governance/) to compare the ones that do.
---
## 10 Data Integration Best Practices for 2026's Revenue Engine
Source: https://dataengineeringcompanies.com/insights/data-integration-best-practices/
Published: 2025-12-04T06:47:42.807563+00:00
Description: Master our 10 data integration best practices for 2026. Drive revenue with actionable insights on ELT, data contracts, AI, and hybrid architectures.
Data integration best practices for 2026 come down to a handful of decisions made early: load raw data first and transform it inside the warehouse (ELT over ETL), enforce data contracts at the source instead of cleaning up bad data downstream, build connectors as modular components instead of one-off scripts, and instrument observability from ingestion through to the dashboard. Skip any of these and the integration layer turns into deadweight that stalls projects instead of feeding them.
ELT-style transformation is common enough among data engineering specialists that 20 of the 86 firms profiled in the [Data Engineering Companies Index](/data-pipeline/) list dbt among their capabilities - the harder question for most buyers isn't whether a firm knows the tooling, but whether they apply it with the discipline this guide covers.
What this guide covers:
* **ELT versus ETL** and when the schema-on-read pattern actually pays off.
* **Data contracts** that reject bad data at the source instead of after it lands.
* **Hybrid batch and streaming architecture** built around a single event hub.
* **Governance-as-code** controls that keep pace with GDPR, HIPAA, and SOC 2 obligations.
## 1. Why should data integration start with business outcomes, not tools?
The most common reason integration projects fail is a missing link to measurable business value: the technology gets built before anyone agrees on what it's for. Start every project by mapping data flows directly to a specific outcome, like a unified customer view or a churn-reduction target, before choosing a single tool.
A team that needs to cut time-to-insight for a churn model from 48 hours to 4 can work backward from that number: pull activity data from Segment, support tickets from Zendesk, and billing data from Stripe into a Snowflake warehouse that feeds both the prediction model and a live dashboard. The KPI decides the architecture, not the other way around.
### Actionable Implementation Tips
* **Co-create a one-page charter with executives.** List the measurable goal (faster reporting, lower churn) before naming a single source or sink, then reverse-engineer the data flow from there.
* **Reverse-engineer sources and sinks from the goal.** Once the KPI is fixed, the required systems and delivery targets follow from it instead of being guessed at upfront.
* **Revisit the charter at each milestone.** Keep the business owner in the loop so scope changes trace back to the original outcome. See [what a data platform is built to do](/insights/what-is-a-data-platform/) for how these pieces fit into a broader architecture.
## 2. Why is ELT replacing ETL as the default approach?
ELT (extract, load, transform) loads raw data straight into a cloud warehouse and defers transformation to the warehouse's own compute, instead of transforming data in a separate engine before it lands. That matters because most organizations now run data across more than one cloud, and rigid pre-load transformation logic doesn't survive a source schema changing underneath it.
A team modernizing an on-premise warehouse can use a tool like Fivetran to load raw Salesforce, Marketo, and database data into Snowflake, then use dbt models to clean, join, and aggregate that data inside the warehouse itself, using its elastic compute instead of a separate transformation server.
### Actionable Implementation Tips
* **Route ingestion through a single ELT orchestrator**, such as dbt combined with Airflow, so every source lands through the same schema-on-read pattern.
* **Let the warehouse absorb schema changes.** ELT tolerates a source adding or renaming a column better than a rigid pre-load transform does, because raw data lands first and the transform logic adapts after.
* **Treat the transform layer as version-controlled code**, not ad hoc SQL scripts, so changes are reviewable and repeatable. See [ETL tools compared](/insights/etl-tools-comparison/) for how the major platforms differ on this.
## 3. Where does AI actually help in data integration?
Manual schema mapping doesn't scale once an organization is reconciling dozens of sources with drifting field names and formats. AI tools can infer likely mappings between source and target schemas from metadata, and flag schema drift before it breaks a downstream pipeline, cutting the manual reconciliation work that used to fall entirely on data engineers.
A sales operations team building its own dashboards benefits when a tool scans metadata across Salesforce, the warehouse, and a finance ERP, and suggests that `Account_ID` and `Customer_Number` refer to the same entity. When an unexpected value shows up in a source field, the same system can quarantine the affected records and alert a data steward instead of letting bad values flow into a report unnoticed.
### Actionable Implementation Tips
* **Deploy metadata-driven mapping tools**, like Collibra or an open-source cataloging stack, to infer relationships between systems instead of hand-mapping every field.
* **Configure automatic quarantine for anomalies.** Data that deviates from the expected schema should get held for review, not loaded silently.
* **Keep a person in the loop on the alerts.** AI-suggested mappings and anomaly flags need a data steward to confirm them before they become policy.
## 4. How do data contracts prevent integration failures?
Data silos and downstream breakage usually trace back to the same root cause: nobody agreed on the shape of the data before it started flowing. A data contract, defined as code (a Protobuf schema, an OpenAPI spec, a dbt YAML file), sets a quality gate at the source so malformed or incomplete data gets rejected before it enters the pipeline instead of being cleaned up after the fact.
An e-commerce team can require every supplier product feed to include a non-null SKU and price, and a validly formatted image URL. When a supplier submits a feed that fails that contract, a CI/CD check run with a tool like Great Expectations rejects the API call with a specific error instead of letting bad listings reach the storefront.
### Actionable Implementation Tips
* **Enforce contracts in CI/CD**, not just in documentation. A data producer's push should fail the pipeline if it doesn't pass schema, freshness, and accuracy checks.
* **Set explicit thresholds in the contract** - freshness under 5 minutes, a duplicate rate under 0.01% - so "good enough" is a defined number, not a judgment call.
* **Version contracts alongside the schema.** A change to a producer's data shape should go through the same review as a code change. See [data contracts in data engineering](/insights/data-contracts-in-data-engineering/) for the format options.
## 5. When do you need real-time streaming instead of batch?
Most "urgent" data needs are actually well served by frequent micro-batches, not true sub-second streaming - streaming is expensive to build and operate, so reserve it for cases where the latency genuinely matters to the business. The practical pattern is a central event hub, like Kafka or a managed equivalent, that both real-time and batch consumers read from, so you're not maintaining two separate ingestion paths.
A payments team can publish every transaction to a Kafka topic, where a Flink application scores fraud risk in real time and triggers an alert within milliseconds, while a separate batch job reads the same topic every 15 minutes to load transaction history into Snowflake for model retraining. Both consumers read the same event stream; only the processing cadence differs.
### Actionable Implementation Tips
* **Make the event hub the single ingestion point.** Route both streaming and batch consumers through it instead of building separate pipelines for each.
* **Reserve streaming for latency-sensitive use cases** - fraud scoring, live alerting - and batch-load the rest on a frequent schedule.
* **Partition by source or tenant** to keep the hub scalable as more consumers get added.
## 6. Why build connectors as modular, containerized components?
A pile of one-off integration scripts, each written for a specific source-target pair, becomes a maintenance burden the moment a vendor changes an API. Packaging each connector as a Docker container, using something like Debezium for change data capture, decouples the integration logic from any one source or target, so a connector can be replaced or upgraded without touching the rest of the pipeline.
A support team that needs a full order-and-ticket history in seconds, not minutes, can pair a Debezium container streaming changes from the production Postgres database with a separate container polling the Zendesk API. Both publish to the same Kafka topic in a standard format, feeding a materialized view that powers a single customer dashboard.
### Actionable Implementation Tips
* **Catalog connectors in a central Git repo**, treated as version-controlled code rather than one-off scripts scattered across servers.
* **Provision with Infrastructure as Code.** Terraform or an equivalent should define exactly how each connector container gets deployed and configured.
* **Standardize the output format across connectors** (JSON, Avro) so downstream consumers don't need source-specific parsing logic.
## 7. How do you automate governance and compliance?
Manually enforcing access controls and PII rules doesn't hold up under GDPR, HIPAA, or SOC 2 obligations at any real scale. Define data policies, access controls, and PII tagging in version-controlled files, then apply them automatically as part of the pipeline's deployment, so compliance is built into the system instead of layered on after an audit finds a gap.

A healthcare analytics team can tag columns like `patient_ssn` and `diagnosis_code` as protected health information directly in a dbt YAML file, so a post-hook macro automatically masks those columns and restricts access to a specific analytics role every time the models run. Access and policy changes get logged automatically for the audit trail, rather than reconstructed after the fact.
### Actionable Implementation Tips
* **Auto-generate lineage maps for sensitive data** so you always know where PII moved, not just where it started.
* **Tie masking and access rules to the tag, not the table.** Policy defined once in code should apply everywhere that tag appears.
* **Route governance checks through CI/CD and alerting.** A policy violation should block a deploy the same way a failing test does. See [data governance best practices](/insights/data-governance-best-practices/) for the fuller framework, and Article 25 of the GDPR for the underlying data-protection-by-design requirement.
## 8. How do you query data across clouds without moving it?
Replicating data between clouds just to run a single query is expensive and slow at scale. Query federation, using an engine like Trino paired with an open table format like Apache Iceberg, lets you query data sitting in S3, Azure Data Lake Storage, and Google Cloud Storage as if it were in one database, without copying it anywhere first.
An analyst who needs a single view of North American sales in Azure and European sales in AWS can point a BI tool at a Trino cluster configured with connectors to both stores and a shared Hive Metastore, then run one query that joins both regions on the fly.
### Actionable Implementation Tips
* **Deploy a federation engine on top of existing stores** rather than building a new consolidated warehouse from scratch.
* **Expose one unified catalog** that maps to every underlying cloud store, so analysts don't need to know where data physically lives.
* **Partition and format files deliberately** (Parquet, Z-ordering), since federated query performance depends heavily on how the source files are laid out.
## 9. What does end-to-end data observability require?
Pipeline monitoring alone (job succeeded or failed) misses the more common failure mode: the job ran fine but produced silently wrong data. Real observability tracks data-aware metrics, freshness, volume, schema, at every stage from ingestion through the dashboard, so an anomaly gets caught before it reaches a business decision.
A retailer scaling to thousands of stores can attach metrics collectors to Kafka message lag, Spark job duration, and warehouse insert counts, feed all of it into a shared dashboard, and set an alert to fire if the volume of processed records drops sharply within a short window, catching a source-side outage before anyone downstream notices missing numbers.
### Actionable Implementation Tips
* **Instrument every stage, not just ingestion.** Transformation jobs and BI dashboards need the same freshness and volume checks as the raw load.
* **Centralize metrics in one dashboard** so a data engineer and a business stakeholder are looking at the same signal, not separate tools.
* **Alert on deviation from normal, not a fixed threshold alone**, since a fixed volume threshold breaks the first time the business itself grows or shrinks. See [data pipeline monitoring tools](/insights/data-pipeline-monitoring-tools/) for a rundown of the category.
## 10. Why should you audit and retire integration pipelines regularly?
Integration pipelines accumulate the way unused subscriptions do: nobody remembers to cancel the ones that stopped earning their keep. Track each pipeline's operational cost against its downstream business value, and review the portfolio on a fixed schedule, so a legacy pipeline nobody looks at doesn't quietly consume engineering time that could go toward something that matters.
A quarterly review might find that three pipelines feeding a rarely used legacy dashboard cost real money in compute every month but serve only a couple of users. Retiring them and reallocating the freed engineering time to a higher-priority project, like a new customer lifetime value model, is a defensible trade once the cost and usage numbers are on the table.
### Actionable Implementation Tips
* **Tag every pipeline with cost and business value** so the portfolio review has real numbers to work from instead of institutional memory.
* **Run the review on a fixed cadence** (quarterly works for most teams) rather than waiting for a budget crisis to force the conversation.
* **Set a bar for new pipelines**, not just old ones - a proposed pipeline should clear the same value threshold as the ones already in production.
## Turning ten practices into one system
These practices reinforce each other more than they stand alone. Outcome mapping decides what to build; ELT and modular connectors decide how; data contracts and governance-as-code decide what's allowed to flow; observability and quarterly audits decide what keeps running. Skip one and the risk doesn't disappear - it shows up later, in a bigger cleanup or migration project.
Most teams underinvest in the two practices that don't show results immediately: contracts at the source and quarterly portfolio audits. Both take real work up front and pay off months later, which makes them easy to skip under deadline pressure and expensive to have skipped once something breaks.
If you're evaluating a partner to help build or fix an integration layer, [compare data engineering consulting firms](/data-engineering-consulting-firms/) on published rates and platform focus rather than sales pitches, and use the ten practices above as the actual scorecard: ask how a firm handles data contracts and observability, not just whether they have "done integrations before."
---
## Data Lakehouse vs Data Mesh: A 2026 Decision Guide
Source: https://dataengineeringcompanies.com/insights/data-lakehouse-vs-data-mesh/
Published: 2026-04-21T07:24:22.41949+00:00
Description: Choose the right architecture for your enterprise. A detailed comparison of data lakehouse vs data mesh on cost, governance, performance, and vendor selection.
Your CTO asks a simple question: should we standardize on a lakehouse, or move to data mesh? The wrong answer locks you into the wrong team design as much as the wrong platform. That’s why the usual architecture diagrams miss the core issue.
Most leadership teams hit this decision at the same moment. The central data team has become a queue manager for the rest of the company. Product, finance, operations, and AI teams all want faster access to data. At the same time, nobody wants a sprawl of poorly governed pipelines across Snowflake, Databricks, dbt, Airflow, and three cloud accounts.
What follows isn’t a definitional tour. It’s a buyer’s guide for engineering leaders making a platform and consulting decision under real delivery pressure. It's also a decision most vendor conversations already assume an answer to: 66 of the 86 firms profiled in the [Data Engineering Companies Index](/snowflake-vs-databricks/) work with Snowflake and 64 work with Databricks, so the platform question rarely stays open for long. The operating-model question does.
## The Strategic Crossroads Facing Every Data Leader
A common pattern shows up in enterprise modernization programs. The company has already invested in cloud data infrastructure on AWS, Azure, or GCP. It has some mix of warehouse workloads, raw object storage, and orchestration. It has also learned that centralization solves one class of problems and creates another.
A **data lakehouse** appeals to the CTO who wants one governed platform, one storage backbone, and fewer duplicated pipelines. A **data mesh** appeals to the CTO who wants each business domain to stop waiting on a central team. The decision sounds technical, but it determines who owns quality, who funds platform work, and who gets blamed when AI initiatives stall.
If you’re resetting your architecture, it helps to start from [a modern data strategy](https://www.statspresso.com/blog/data-strategy-for-startups) rather than from tooling preferences. The architecture has to follow the operating model you can sustain.
### The real tension is operational
The lakehouse choice says: build a strong platform core, enforce standards centrally, and drive efficiency through shared storage, governance, and compute patterns.
The mesh choice says: give domains ownership, force data product accountability closer to the business, and accept that governance has to become federated rather than fully centralized.
| Decision dimension | Lakehouse bias | Data mesh bias |
|---|---|---|
| **Primary bottleneck** | Central platform fragmentation | Central team backlog |
| **Operating model** | Shared platform with central stewardship | Domain ownership with federated standards |
| **Talent pattern** | Strong platform engineering bench | Domain-aligned engineers and product-minded data owners |
| **Consulting need** | Migration, optimization, governance implementation | Org redesign, self-serve platform, domain enablement |
| **Failure mode** | Efficient platform, slow business response | Fast domains, inconsistent quality |
> The architecture debate is usually a proxy for an org design problem. If you don’t resolve the org question first, the platform decision won’t hold.
## An Architectural and Technology Stack Deep Dive
The technical stack matters because the implementation burden differs sharply. In a lakehouse, the platform team unifies storage, metadata, security, and processing patterns. In a mesh, the platform has to support decentralization without turning every domain into its own infrastructure shop.
### What a lakehouse actually looks like in production
A modern lakehouse usually sits on object storage such as S3, ADLS, or GCS, with open table formats such as **Delta Lake, Apache Iceberg, or Apache Hudi**. Compute comes from engines such as Spark, Flink, or Presto-family query layers. Governance sits in a catalog and policy layer. In practice, that often means Databricks with Unity Catalog, or a Snowflake-centered model with native governance and external table patterns.
The technical reason enterprises like it is straightforward. According to [QodeQuay’s architecture analysis](https://www.qodequay.com/data-mesh-lakehouse-architecture), lakehouses support **ACID transactions, schema evolution, time travel, and optimized storage formats**, which lets teams run BI reporting and ML training on the same dataset without duplication. The same analysis notes that tuning techniques like **Z-ordering, bloom filters, secondary indexing, and materialized views** can improve query performance, though lakehouses can still lag purpose-built warehouses for purely structured workloads by **20% to 50% in some cases**.
That trade-off is easy to miss in consulting proposals. A partner can sell “one platform for everything,” but your finance reporting workloads may still need careful modeling, clustering, and compute isolation to perform predictably.
For a more detailed technical primer on platform design, this guide to [lakehouse architecture patterns](https://dataengineeringcompanies.com/insights/what-is-lakehouse-architecture/) is useful before you write an RFP.
> **Practical rule:** If your consulting partner can’t explain partitioning, table maintenance, workload isolation, and catalog design in concrete terms, they aren’t ready to lead a serious lakehouse migration.
### What a mesh actually requires
A **data mesh** isn’t a storage engine. It’s a way of assigning responsibility. Domain teams own data products. A central enablement team provides shared capabilities such as cataloging, identity controls, lineage, templates, observability, and platform standards.
That means the technology stack is broader and less uniform. You still use storage and compute somewhere, often on Databricks, Snowflake, BigQuery, or a mix. But you also need product interfaces, metadata standards, discoverability, reusable dbt patterns, orchestration templates in Airflow or managed equivalents, and governance automation that domain teams can use without waiting for the center.
If your team is comparing implementation paths, this review of [data pipeline tools](https://www.thirstysprout.com/post/best-data-pipeline-tools) is a practical supplement because the architecture choice changes which orchestration, transformation, and observability tools become first-class.
### The hidden implementation issue
The hard part in **data lakehouse vs data mesh** isn’t choosing between Databricks and Snowflake. It’s deciding where engineering complexity should live.
- **In a lakehouse**, complexity sits in platform design, optimization, and shared governance.
- **In a mesh**, complexity sits in domain enablement, interface contracts, and federated standards.
- **In both cases**, dbt, orchestration, and governance tooling only work if ownership boundaries are explicit.
The strongest consulting teams know this and design delivery around operating responsibilities, not just around Terraform modules and ingestion accelerators.
## Comparing Ownership and Governance Models
The biggest difference between these models is governance. Not governance as policy documents. Governance as daily control over schemas, SLAs, quality checks, and release decisions.
### Lakehouse governance is centralized by design
In a lakehouse model, the platform team typically owns ingestion standards, storage conventions, identity and access patterns, data quality frameworks, and curated serving layers. Domain teams consume and sometimes contribute, but the center defines the contract.
This works well in regulated environments and in organizations where the business already expects shared services. It also fits Snowflake and Databricks programs where leadership wants a controlled migration from fragmented marts and legacy ETL.
The upside is clarity. The downside is queue formation. Every exception request lands with the same platform team.
### Mesh governance is federated and heavier to operate
According to [Starburst’s comparison of data mesh and data lakehouse](https://www.starburst.io/blog/data-mesh-vs-data-lakehouse/), data mesh prioritizes decentralized socio-technical scalability by distributing ownership to domain teams and can reduce ingestion delays by **30% to 50%** in large organizations through distributed ETL. The same analysis is equally clear about the cost of that model: mesh requires higher organizational maturity and domain owners who can ensure data product quality.
That sounds attractive until you staff it. Someone in each domain has to own semantics, documentation, lifecycle decisions, and producer-consumer agreements. That person isn’t just a data engineer. They need enough business context to act like a product owner.
Here’s the governance split in practical terms:
- **Lakehouse governance**
- **Who sets standards:** Central platform and governance leads
- **Who enforces quality:** Usually central engineering with shared checks
- **Who resolves disputes:** Platform leadership or architecture board
- **Mesh governance**
- **Who sets standards:** Small federated governance group
- **Who enforces quality:** Domain teams
- **Who resolves disputes:** Cross-domain governance forum with executive backing
A useful reference point for leaders designing those controls is this guide to [data governance strategies](https://dataengineeringcompanies.com/insights/data-governance-strategies/), especially if your consulting scope includes operating model design rather than only platform build-out.
The video below is worth sharing with architecture and product leaders together, not just the data team, because mesh fails when the business treats data ownership as somebody else’s problem.
> In a lakehouse, governance is a platform competency. In a mesh, governance is a management discipline.
## Enterprise Performance and Cost Implications
CTOs usually ask about storage and compute first. That’s reasonable, but incomplete. The larger cost difference often comes from who you need to hire, how many teams need to coordinate, and how much rework appears after the first release.
### Where lakehouses win financially
Lakehouses are winning current enterprise adoption because they package performance and governance into a migration path most organizations can execute. The [2025 comparative study in the International Journal of Innovative Research in Management and Physical Sciences](https://www.ijirmps.org/papers/2025/1/232302.pdf) reports a **50% reduction in data processing time** and a **30% improvement in data processing efficiency** for lakehouse implementations. The same study says **33.6% of organizations** treat lakehouses as a strategic priority for unified BI and ML workloads, **67% of organizations** expect lakehouses to handle the majority of analytics within three years, and **19% of respondents** cite cost efficiency as the main reason for adoption.
Those numbers matter because they map directly to consulting economics. A lakehouse migration usually lets one partner deliver storage redesign, ingestion consolidation, governance setup, and workload optimization within one program structure. That lowers coordination overhead.
### Where mesh gets expensive
Mesh doesn’t just add tooling. It adds operating layers. You need self-serve templates, metadata controls, enablement, domain onboarding, and an escalation model for cross-domain quality disputes. If your consulting partner prices mesh close to a straightforward lakehouse migration, they’re underestimating the work or implicitly assuming your internal teams will absorb it.
The cost issue isn’t only day one. Mesh spreads engineering responsibility deeper into the organization, which improves responsiveness when domain teams are mature. It becomes wasteful when domains don’t have enough technical depth to own pipelines and data products properly.
### The budget question CTOs should ask
Ask vendors where they expect your marginal cost to rise after go-live.
- **For lakehouse programs**, primary cost risk sits in compute optimization, table maintenance, and a central team becoming a delivery choke point.
- **For mesh programs**, primary cost risk sits in duplicated effort across domains, uneven quality practices, and the need for stronger senior hiring in each business unit.
- **For both**, migration cost is less important than the operating model you can afford for three years.
The blunt assessment: if your main objective is platform consolidation on Snowflake or Databricks with better BI and AI readiness, lakehouse usually delivers the cleaner economic case. If your main objective is reducing central backlog across many independent business units, mesh can justify its higher organizational burden.
## Choosing Your Path Ideal Use Cases and Anti-Patterns
Architects get into trouble when they treat both models as equally valid for every enterprise. They aren’t.
### Choose lakehouse when the platform has to unify before it can scale
A lakehouse is the stronger choice when you’re consolidating fragmented analytics stacks, rationalizing storage, or trying to support BI and ML from one governed data foundation. It fits especially well when:
- **Your organization is still platform-led**. A central data team already owns standards and can enforce them.
- **Your industry is compliance-heavy**. Central policy enforcement and auditability matter more than domain autonomy.
- **You’re modernizing to Databricks or Snowflake**. The migration path aligns with how these platforms are bought, staffed, and governed.
- **Your consulting scope is execution-heavy**. You need pipeline migration, medallion-style modeling, dbt adoption, orchestration cleanup, and governance rollout.
Anti-patterns show up fast. Don’t force a lakehouse-first model when business units already behave like independent product organizations with their own engineering leadership and hard delivery deadlines. You’ll centralize cost, then decentralize work through side channels anyway.
### Choose mesh when your bottleneck is organizational, not storage
Mesh becomes the better fit when your core problem is that a central team can’t keep up with domain demand and shouldn’t try to. It works best when:
1. **Business units already own engineering outcomes**
Data ownership maps naturally to existing product or domain structures.
2. **Data products differ materially by domain**
Finance, operations, risk, and customer platforms need different semantics, SLAs, and release cadences.
3. **You can fund enablement, not just infrastructure**
Mesh only works when the platform team builds guardrails, templates, discovery, and federated governance support.
The anti-pattern is common: a mid-sized company with one data team, limited senior talent, and no appetite for domain ownership decides to “do data mesh” because it sounds modern. That usually creates duplicated pipelines, inconsistent definitions, and a catalog full of untrusted assets.
> If your leaders won’t assign named business-domain owners for data products, you don’t have a mesh plan. You have a decentralization slogan.
### The consulting implication
Lakehouse projects need consultants who can migrate and optimize platforms. Mesh programs need consultants who can redesign operating models, not just infrastructure. That’s a different kind of partner. Many firms can implement Airflow, dbt, Databricks, and Snowflake. Fewer can coach domain teams, define federated governance, and leave behind a workable product model for data - see this guide to [data mesh consulting](/insights/data-mesh-consulting/) for what to screen for.
## The Emerging Reality The Lakehouse-Mesh Hybrid
The strict **data lakehouse vs data mesh** framing no longer reflects where enterprise programs are going. The market is moving toward hybrid models that use lakehouse as the technical foundation and mesh as the ownership model.
The strongest evidence comes from [Databricks’ analysis of lakehouse and data mesh adoption](https://www.databricks.com/blog/databricks-lakehouse-and-data-mesh-part-1). It reports that **hybrid lakehouse-mesh adoption surged 150% in 2025 for AI/ML pipelines**, and that **40% of Databricks’ top global customers** now run a mesh concept on top of a lakehouse foundation. The same analysis says this approach boosts scalability **4x**, and notes that Unity Catalog updates for federated governance cut cross-domain access latency by **70%**.
### Why the hybrid model is winning
This structure solves the central contradiction.
The lakehouse gives you shared storage, open table formats, ACID behavior, and common governance primitives. The mesh model tells you who owns which data product, who publishes it, and who is accountable when quality slips. One handles the technical substrate. The other handles the operating model.
That’s why the hybrid path is becoming the sensible recommendation for large Snowflake and Databricks migrations. It avoids two bad extremes:
- **Pure centralization**, where every team waits on the same platform group
- **Pure decentralization**, where domains reinvent standards and multiply integration work
### What this means for consulting engagements
A hybrid program changes what you should buy from a partner. Don’t ask for “lakehouse implementation” or “data mesh transformation” as isolated workstreams. Ask for a phased model:
- **Foundation phase**
Central storage, catalog, security model, CI/CD, baseline orchestration, shared quality tooling
- **Domain enablement phase**
Templates for data products, ownership model, documentation standards, service boundaries
- **Federation phase**
Cross-domain governance, discoverability, SLA management, escalation rules
> The right partner for a hybrid model can talk credibly about both Unity Catalog or Snowflake governance primitives and the non-technical mechanics of domain accountability.
## Your Decision Framework An RFP-Ready Checklist
Most RFPs fail because they ask vendors to compare platforms without forcing an honest assessment of the client’s operating model. Use this checklist before you issue the brief.
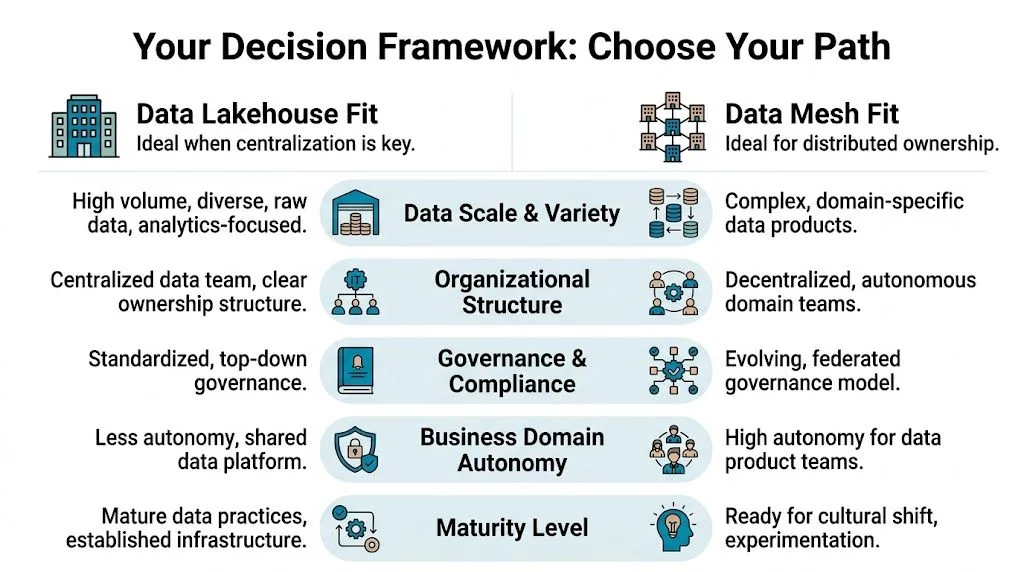
### Score the organization before you score the vendors
| Evaluation area | Leans lakehouse | Leans mesh |
|---|---|---|
| **Org structure** | Centralized data or platform authority | Strong domain autonomy across business units |
| **Primary goal** | Consolidation, governance, cost control | Speed, local accountability, parallel delivery |
| **Talent model** | Strong platform engineers, fewer domain data owners | Senior domain engineers and product-minded owners |
| **Governance style** | Top-down standards and approvals | Federated standards with local enforcement |
| **Workload pattern** | Unified BI, reporting, shared ML datasets | Domain-specific products and local SLAs |
| **Partner requirement** | Migration and optimization depth | Change management and operating model depth |
### Questions to put into the RFP
Don’t ask vendors whether they “support” both architectures. Everyone says yes. Ask these instead:
- **Ownership design**
Who owns data quality, schema evolution, and product documentation after go-live?
- **Platform boundary**
Which controls stay centralized, and which responsibilities move to domains?
- **Tooling fit**
How will the vendor implement dbt, orchestration, cataloging, lineage, and observability under the chosen model?
- **Talent transfer**
Which roles must the client hire or backfill for the architecture to survive beyond the consulting engagement?
- **Failure handling**
What happens when one domain publishes low-quality data that another domain depends on?
### The decision rule I’d use with a client CTO
Pick **lakehouse** if your enterprise needs a governed common platform now, and your domains aren’t staffed to act as data product teams.
Pick **mesh** if your business units already run with meaningful autonomy, and leadership is willing to assign durable accountability for data products inside those units.
Pick **hybrid** if you’re a large enterprise on Snowflake or Databricks and need central technical standards with distributed ownership.
The wrong move is buying a mesh story from a vendor that only knows centralized platform delivery, or buying a lakehouse migration from a vendor that ignores the backlog problem driving the change.
## Frequently Asked Questions for Engineering Leaders
### Can we start with a lakehouse and evolve toward mesh
Yes. In fact, that’s the cleaner path for many enterprises. Start by standardizing storage, governance, and core pipelines. Then move selected domains toward data product ownership once the shared platform is stable. This sequence reduces technical sprawl while giving leadership time to test whether domains will actually own quality and lifecycle decisions.
### Does a mesh mean we need multiple platforms
No. Mesh is an ownership model, not a mandate for separate infrastructure per domain. Many organizations run domain-owned data products on a common platform. The question isn’t whether teams share Snowflake, Databricks, BigQuery, or object storage. The question is whether domains own the contract and lifecycle of the assets they publish.
### Where do dbt and Airflow fit in each model
In a lakehouse, dbt often standardizes transformation logic on top of a common platform, while Airflow or a managed orchestrator coordinates centralized workflows and dependencies.
In a mesh, the same tools can still work, but the operating pattern changes. Templates, guardrails, and reusable components become more important than centralized control. The platform team’s job is to make the paved road easy enough that domains don’t bypass it.
### How should we measure success
Measure success in terms of delivery behavior, platform reliability, and trust in data products.
For a lakehouse, the strongest signals are whether you reduced duplicate pipelines, improved workload performance, and tightened governance without slowing delivery. For a mesh, the strongest signals are whether domains publish usable, documented, trusted data products and resolve quality issues without escalating everything to the center.
### Is mesh just a trend, or is it durable
The market signals say it’s durable, but not as a replacement for lakehouse everywhere. The [2025 comparative study](https://www.ijirmps.org/papers/2025/1/232302.pdf) cited earlier in this guide found that 67% of organizations expect lakehouses to handle the majority of analytics within three years. That’s the clearest signal available: decentralization is growing, but lakehouse remains the dominant practical foundation.
### What should we do next
Run a short architecture and operating model assessment before you talk to vendors. Document current bottlenecks, identify who can own data products, and decide whether your problem is platform fragmentation, central backlog, or both.
Then issue an RFP that tests delivery model, governance design, and talent assumptions. If you need a structured shortlist, cost benchmarks, and evaluation criteria for consulting partners, use the buyer tools and firm comparisons at [DataEngineeringCompanies.com](https://dataengineeringcompanies.com).
---
## A Data Lineage Tools Comparison Framework for Engineering Leaders
Source: https://dataengineeringcompanies.com/insights/data-lineage-tools-comparison/
Published: 2026-03-05T07:08:23.747011+00:00
Description: Cut through the noise with this data lineage tools comparison. Evaluate top vendors on architecture, integration, and pricing for your modern data platform.
Data lineage tools split into two architectures: automated, parser-based systems that trace SQL and code programmatically down to the column level, and catalog-driven systems where stewards manually map data to business context. The right choice depends on whether your primary problem is operational - debugging broken pipelines - or governance - satisfying auditors and building a trusted data dictionary. Most enterprise stacks eventually need both.
This guide compares the two architectures against the platforms you actually run: Snowflake, Databricks, BigQuery, dbt, and Airflow. Only 11 of the 86 firms profiled in the [Data Engineering Companies Index](/data-governance/) list data governance among their core capabilities, which is a good reason most teams end up building lineage requirements into a broader consulting engagement instead of shopping for a standalone tool in isolation.
What this guide covers:
* Untangling complex SQL transformations buried in warehouses like Snowflake or BigQuery.
* Tracking data flow across multi-cloud environments (AWS, Azure, GCP).
* Integrating with the modern data stack, including dbt and [Airflow](https://airflow.apache.org/).
The decision is not just about features - it's about matching a tool's architecture to your primary problem, whether that's operational stability, data governance, or change management.
### Three ways to categorize lineage tools
Your first decision point is the architectural approach that fits your needs. It defines the tool's capabilities, its limits, and its value to your organization.
| Category | Primary Strength | Best For |
| :--- | :--- | :--- |
| **Automated Parsers** | Deep, technical, column-level lineage | Engineering teams needing root cause analysis and impact analysis. |
| **Catalog-Driven** | Rich business context and governance | Enterprise-wide governance, compliance, and data discovery. |
| **Open-Source** | Maximum flexibility and no license cost | Teams with strong engineering resources to build and maintain their own solution. |
The rest of this guide walks through that decision in detail, plus a platform-by-platform integration checklist and an RFP framework you can run against actual vendors.
## What's the real difference between automated and catalog-driven lineage tools?
Automated tools parse your code and query logs to build lineage programmatically, down to individual columns. Catalog-driven tools rely on data stewards to manually declare connections between technical assets and business context. The architecture you pick determines who can use the tool day to day and how much ongoing upkeep it needs.
### Automated, Parser-Based Architecture
Automated tools connect directly to your data stack - databases, transformation layers like dbt, BI platforms, and source code repositories - then parse SQL query logs, transformation scripts, and BI metadata to construct a column-level map of how data actually moves.
* **Who it's for:** data engineers, analytics engineers, and BI developers.
* **Best at:** root cause analysis and impact analysis. When a dashboard breaks, an engineer traces the failure upstream through the transformations that produced it.
* **Main benefit:** column-level lineage with low manual upkeep once it's configured. This scales with the complexity of the stack instead of a governance team's headcount.
* **The catch:** initial setup is involved - it needs broad permissions to access and parse metadata - and the resulting map reflects technical reality accurately but with little business context attached.
Automated lineage is built to answer "what broke this pipeline" in minutes by pointing to the exact code and column responsible. That capability sits next to [data pipeline monitoring](/insights/data-pipeline-monitoring-tools/): lineage tells you what's connected, monitoring tells you when it breaks.
### Manual and Catalog-Driven Architecture
In this model, lineage is declared, not discovered. These tools, usually part of a broader data catalog, prioritize business context: stewards manually connect technical tables and columns to glossary entries, governance policies, and ownership records. Our [data catalog tools comparison](/insights/data-catalog-tools-comparison/) covers how catalog platforms differ from pure lineage tools if you're weighing both.
* **Who it's for:** business users, data stewards, compliance officers, and auditors.
* **Best at:** enterprise governance and compliance reporting, giving non-technical stakeholders a trusted view of where sensitive data comes from and how it's used.
* **Main benefit:** a business-centric lineage map that's easy for anyone to read, tying technical assets to the rules and regulations that govern them.
* **The catch:** it's a manual, labor-intensive process that doesn't scale without a fully staffed governance team, and lineage - often only at the table level - goes stale the moment a pipeline changes without a corresponding catalog update.
### Architectural Showdown: A Clear Choice
The differences in philosophy show up directly in practice.
| Evaluation Criterion | Automated Lineage (e.g., Manta, Octopai) | Manual/Catalog-Driven Lineage (e.g., Collibra, Alation) |
| :--- | :--- | :--- |
| **Primary Goal** | Technical troubleshooting & impact analysis | Business governance & compliance |
| **Granularity** | **Column-level**, highly detailed | **Table-level**, high-level & conceptual |
| **Scalability** | High; scales with the complexity of the data stack | Low; scales with the size of the governance team |
| **Accuracy** | High; reflects the "as-is" technical reality | Dependent on human upkeep; becomes stale |
| **Setup Effort** | High initial configuration, low maintenance | Low initial setup, high ongoing maintenance |
| **Key User** | Data Engineer / Analytics Engineer | Data Steward / Business Analyst / Auditor |
| **Context** | Technical context (code, queries, transformations) | Business context (glossary, policies, ownership) |
If your team is dealing with broken pipelines and unclear blast radius from code changes, an automated, parser-based tool fits. If the driving need is an enterprise governance framework and audit-ready documentation, a catalog-driven approach gives you that business context, but budget for the ongoing manual effort it requires.
## Which platform integrations actually matter for Snowflake, Databricks, and dbt?
A tool's value comes from how deeply it integrates with the platforms you actually run, not how many connectors are on the sales sheet. Shallow, table-level lineage for systems like Snowflake, Databricks, BigQuery, dbt, and Airflow is close to useless operationally - what matters is whether the tool can parse the messy logic inside those systems.
### Differentiating by Platform Integration Depth
Test vendors against the specific nuances of your environment, not a generic demo. A tool's ability to correctly parse column-level lineage from a deeply nested dbt macro is a real differentiator - many tools fail here, unable to unpack the logic and map dependencies accurately. The same test applies to orchestration: tracing data through a complex Airflow DAG, or any [data orchestration platform](/insights/data-orchestration-platforms/), requires understanding how data actually passes between tasks, not just that the tasks ran in sequence.
Integration depth, not connector count, is the differentiator that holds up once a stack spans more than one cloud and more than one processing layer.
### An Evaluation Framework for Stack Integration
Cut through marketing claims with a structured evaluation of how each tool performs in your actual stack. Score every vendor against these criteria:
* **Connector Maturity:** basic connectivity, or can it parse complex, platform-specific logic like Snowpark UDFs or Databricks notebooks?
* **Granularity of Capture:** can it reliably deliver **column-level lineage** for your most important platforms, or does it degrade to table-level lineage when transformations get complex?
* **Support for Platform Features:** how well does it handle Snowflake Streams, the Databricks Unity Catalog, or dbt exposures?
* **BI vs. Processing Support:** some tools trace lineage well into BI platforms like Tableau but are weak on the processing side with Spark or Airflow. Identify which part of the stack matters most to you.
A lineage tool that can't answer these questions cleanly in a proof of concept won't hold up in production. Test the specific edge cases in your own stack, not the vendor's rehearsed demo.
## Which lineage tool fits your use case?
A lineage tool without a clear problem to solve is an expensive diagramming utility. Match the tool's architecture to your highest-priority use case - root cause analysis, governance and compliance, or change impact analysis - rather than buying on feature count.
### Use Case 1: Operational Root Cause Analysis
A critical dashboard breaks at 3 a.m. The on-call engineer doesn't need a business glossary - they need column-level lineage that traces the anomaly back through the transformations that touched it.
Automated, parser-based tools like [**Manta**](https://manta.io/) are built for this moment, parsing SQL queries, dbt models, and ETL jobs to show engineers the precise point of failure in the code. When incident response is the priority, pick a tool with detailed, code-aware lineage over one built primarily for business context.
### Use Case 2: Enterprise Data Governance and Compliance
The goal here is not firefighting - it's satisfying auditors, proving compliance with regulations like GDPR, and maintaining a trusted enterprise data dictionary. That's a business-meaning problem more than a code problem.
Catalog-first platforms like [**Collibra**](https://www.collibra.com/) are built for this: they link physical data assets to the business glossary, data owners, and governance policies. The lineage is often conceptual, at the table level, but it supplies the business context that compliance and governance teams need for reporting and audits. Our [data governance best practices](/insights/data-governance-best-practices/) guide covers how to build that program end to end.
### Use Case 3: Change Impact Analysis
Your team is about to ship a schema change and needs to know what it will break downstream. This is proactive risk management - catching broken dashboards and failed pipelines before they happen, not after.
Tools with strong impact analysis, such as [**Alation**](https://www.alation.com/), let engineers simulate the ripple effects of a proposed change, showing which reports, ML models, and data products a column modification will touch, so teams can coordinate changes and avoid production failures. This overlaps with the discipline behind [data contracts](/insights/data-contracts-in-data-engineering/): both are ways of making downstream dependencies explicit before you break them.
## What should be in your lineage tool RFP checklist?
Choosing a lineage tool is a significant investment that deserves more than a vendor demo. Run each finalist through a structured RFP across three areas - technical and integration capability, governance and security, and usability - and treat a vague answer in any of the three as a red flag.
### Technical and Integration Capabilities
This is where you determine if the tool can actually handle your environment.
* **Lineage Capture Method:** how is lineage captured - by automatically parsing query logs and code, or by relying on manual declaration?
* **Granularity:** does it provide true **column-level lineage** or just table-to-table flows? Demand proof, not a slide.
* **Platform-Specific Parsing:** how well does it interpret the reality of your stack, including complex dbt macros, historical [Snowflake](https://www.snowflake.com/en/) queries, or lineage inside the [Databricks](https://www.databricks.com/) Unity Catalog?
* **API Access:** is there a well-documented API for programmatic access to lineage metadata?
* **Real-Time Support:** can it handle streaming data? Ask how it visualizes lineage from sources like [Kafka](https://kafka.apache.org/).
* **Extensibility:** can your team write custom parsers for proprietary or unsupported data sources?
### Governance and Security
A lineage tool has visibility into where your sensitive data lives and moves, so it needs to meet your security and governance requirements from day one, not after deployment.
* **Role-Based Access Control (RBAC):** can you restrict visibility for sensitive data pipelines or metadata based on user roles?
* **Identity Provider Integration:** does it integrate with your SSO provider (e.g., Okta, Azure AD)?
* **Audit Trails:** does the platform log all user actions and changes to lineage?
* **Policy Integration:** can you link an asset's lineage directly to its data classification, owner, or access policies?
### Usability and Adoption
A technically powerful tool is worthless if your team won't use it. User experience matters as much as the back-end engine.
* **Visualization Quality:** is the lineage graph clean, navigable, and useful, or just visual noise?
* **Search and Discovery:** during a production incident, how quickly can an on-call engineer find a broken asset and trace it back to its source?
* **Collaboration Features:** can users add comments, tag owners, or certify assets as "trusted" within the tool?
A common failure mode is a tool that produces technically accurate but unusable lineage graphs. If your engineers can't find what they need during an incident, the tool has failed, regardless of how complete its lineage graph is on paper. Score usability with the same rigor you apply to connector depth.
## How do you make the final decision?
After evaluating features and architectures, the decision comes down to your primary goal: giving engineers technical visibility to fix pipelines, or giving auditors and stewards a governed view of the business. Most teams eventually need both, but buy first for the one that's actually broken today.
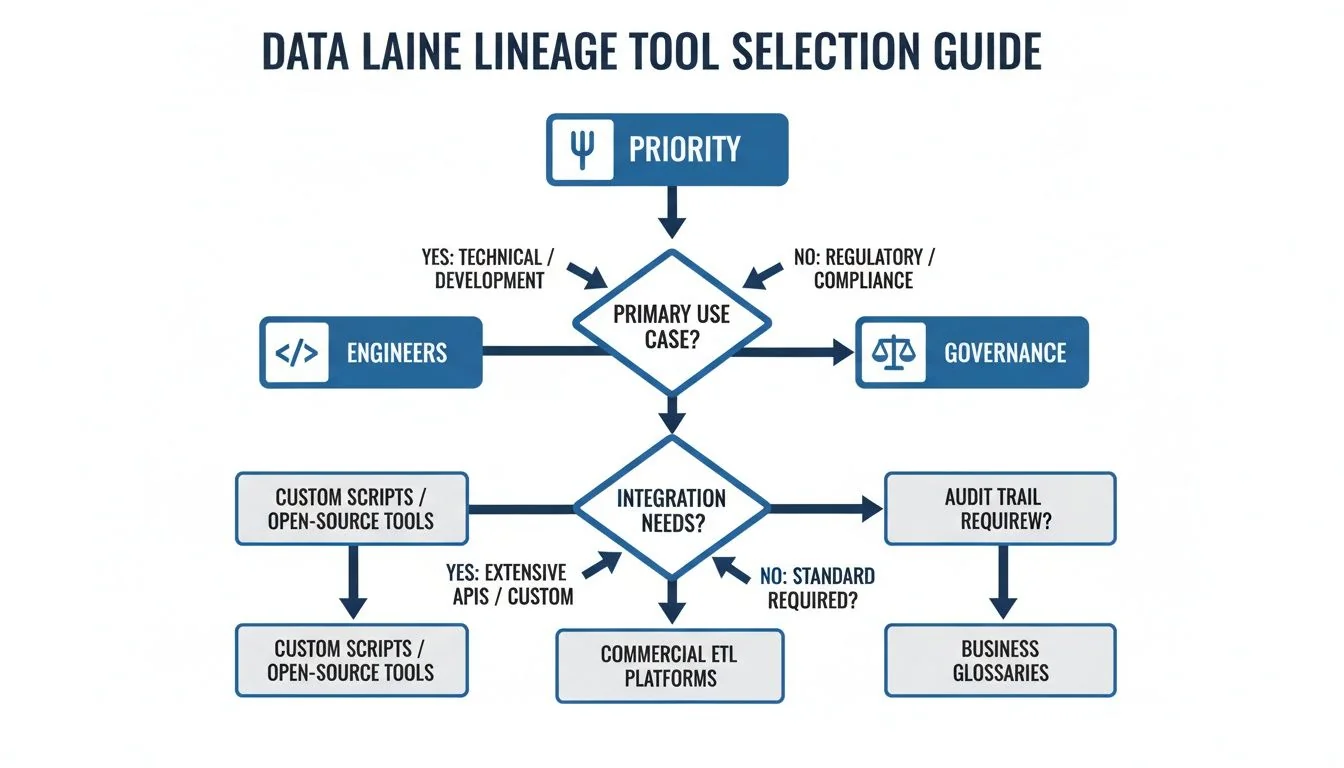
The flowchart above splits the decision into two starting points: the needs of your data engineering team, or the requirements of your enterprise governance program.
### Engineer-Centric vs. Governance-Centric Paths
If your priority is giving data engineers technical visibility to fix broken pipelines in code-heavy environments like [dbt](https://www.getdbt.com/) or [Airflow](https://airflow.apache.org/), an automated, parser-based architecture is the better starting point. A tool like Manta delivers the column-level detail engineers need for root cause and impact analysis.
If your priority is an enterprise governance framework that keeps auditors satisfied, a catalog-first platform like [Collibra](https://www.collibra.com/) makes more sense. These tools connect technical metadata to business glossaries and policies, which is what compliance reporting actually requires.
### Your Immediate Next Steps
A hands-on evaluation beats another round of vendor slide decks.
1. **Define your top two use cases.** One highly technical (debugging a specific, troublesome pipeline) and one business-focused (certifying a critical regulatory report).
2. **Run a focused proof of concept.** Do not try to test everything at once. Pick one vendor from each category - one parser-based, one catalog-first - and test both against a single, difficult pipeline in your own environment.
3. **Score the results.** Use the RFP checklist above to score how each tool performed on your specific use cases, not the vendor's canned demo.
A short POC against your actual pipelines gives you evidence of which architecture earns its cost, instead of a debate that stays theoretical.
## Frequently Asked Questions
These are the most common questions engineering leaders face when evaluating data lineage tools.
### What Is the Biggest Mistake When Choosing a Data Lineage Tool?
The biggest mistake is being impressed by a long list of connectors. A vendor might show a slide with 50 logos, but that's often marketing fluff. What matters is the *depth* of the connectors for the systems most critical to your business, whether that's [dbt](https://www.getdbt.com/), your main BI tool, or a core ETL orchestrator. A real comparison requires digging deep: does the tool provide only table-level lineage, or can it trace all the way down to the column level through complex logic? The quality of lineage from your most important sources determines the project's success.
### How Do Open Source Tools Like OpenLineage Compare to Commercial Vendors?
This is a classic build-vs-buy decision. Open-source frameworks like [OpenLineage](https://openlineage.io/) are powerful and flexible but are not a complete solution on their own. They require a real engineering commitment to implement collectors, build a user interface, and maintain the system. Commercial tools deliver value faster with a polished UI, pre-built parsers, and enterprise support, in exchange for a license fee. Open source gives you full control but carries a high total cost of ownership paid in engineering hours. A commercial tool speeds up time-to-value, assuming the price fits your budget.
### Can a Data Lineage Tool Integrate with Both Snowflake and Databricks?
Yes. Most modern tools are built for a multi-cloud, multi-platform world. The real question is not *if* they can connect to both [Snowflake](https://www.snowflake.com/en/) and [Databricks](https://www.databricks.com/), but how well they stitch the lineage together *across* them. A good POC test is tracing a single data flow from a Databricks job, into a Snowflake table, and finally out to a [Tableau](https://www.tableau.com/) dashboard. Can the tool show you that entire journey as one connected, unified graph? This common scenario is a frequent failure point for less mature platforms - make vendors prove it.
---
Choosing the right lineage tool is only half the evaluation - finding a firm that can implement and maintain it is the other half. **DataEngineeringCompanies.com** profiles data engineering firms with transparent capabilities across Snowflake, Databricks, and cloud data projects, so you can compare implementation partners the same way you compare tools. [Find a data engineering partner.](https://dataengineeringcompanies.com)
---
## The Real Cost and Timeline of a Data Mesh Consulting Engagement
Source: https://dataengineeringcompanies.com/insights/data-mesh-consulting/
Published: 2026-03-09T07:20:57.35363+00:00
Description: A guide to data mesh consulting for engineering leaders. Learn to scope projects, select partners, and implement a data mesh that delivers business value.
A data mesh consulting engagement runs in three phases: strategic advisory (4-6 weeks), pilot implementation (3-6 months), and full-scale transformation (12-24+ months), with a working pilot typically costing $150,000 to $400,000. Data mesh is not a single project - it's a phased, socio-technical shift that hands data ownership to business domains instead of a central team. This guide lays out the benchmarks, phases, team roles, and vendor-evaluation criteria you need to build a business case and pick a partner who can actually deliver on it.
Governance is the differentiator to screen for: only 11 of the 86 firms profiled in the [Data Engineering Companies Index](/data-governance/) list data governance among their core capabilities, and federated governance is exactly what a mesh initiative lives or dies on.
### Why can't you build a data mesh with internal teams alone?
The core problem data mesh solves is the monolithic data bottleneck: a central data team turns into a service desk, buried under tickets from business units waiting on data, and that model stops scaling once the organization grows past a certain size. Data mesh inverts this by handing ownership of data products to the domains that know the data best - marketing, finance, or logistics.
This is a socio-technical change, not a platform migration, and that's exactly why internal-only attempts tend to stall out. Technical teams can stand up the infrastructure fine, but without dedicated change management, domain teams keep routing requests back to the central team out of habit, and governance rules never get formalized. A qualified data mesh consulting partner reduces that risk with a playbook that addresses technology, governance, and culture in parallel, not technology alone.
### Centralized Bottleneck vs. Decentralized Data Mesh
The architectural and organizational differences are stark. A centralized model creates dependencies; a data mesh is built for autonomy and speed.
| Attribute | Traditional Monolithic Architecture | Data Mesh Architecture |
| :--- | :--- | :--- |
| **Data Ownership** | A central data team owns the platform, pipelines, and data models. | Business domains (e.g., Sales, Marketing) own their data as a product. |
| **Team Structure** | One large, specialized central team serves the entire organization. | Small, cross-functional teams are embedded within each business domain. |
| **Architecture** | A single data lake or warehouse acts as the single source of truth. | A distributed network of interoperable "data products." |
| **Bottlenecks** | The central team is a bottleneck for all data requests and changes. | Bottlenecks are localized; domain teams are self-sufficient. |
This isn't just an architectural preference. Decentralization is what lets domain experts build directly against their own data products instead of filing a ticket and waiting - when that loop tightens, the feedback cycle for a new analytics use case shrinks from months to days.
> By decentralizing data ownership, organizations move accountability to the source, so those who create the data also own its quality, documentation, and evolution - a stark contrast to relying on a backlogged central BI team.
An expert consultant's job is to implement the four core principles of data mesh:
* **Domain Ownership:** Assigning data accountability to the business domains that create and understand it.
* **Data as a Product:** Treating data as a first-class product with defined SLAs, documentation, and a dedicated owner.
* **Self-Serve Infrastructure:** Building a platform that lets domains manage their data products with high autonomy.
* **Federated Governance:** Establishing a set of global rules for security, interoperability, and quality that all domains must follow.
This is distinct from a data fabric, which focuses on connecting disparate data sources through a metadata layer rather than fundamentally changing ownership. For a detailed comparison, see our guide on [what is a data fabric?](/insights/what-is-data-fabric/) A data mesh consultant ensures these principles become an executed reality, not just architectural diagrams.
## How do you scope a data mesh consulting engagement?
A data mesh engagement scopes into three phases matched to organizational maturity: strategic advisory (4-6 weeks) for organizations new to the concept, pilot implementation (3-6 months) to build the first data product, and full-scale transformation (12-24+ months) to roll it out enterprise-wide. Picking the wrong entry point for your starting maturity is the most common way these engagements go over budget.
### Data Mesh Engagement Models & Timelines
Engagements fall into three phases, each with a distinct objective, timeline, and cost structure.
* **Strategic Advisory (4-6 weeks):** This is the mandatory starting point for any organization new to the concept. A consultant assesses your technical and organizational readiness, identifies high-impact business domains for a pilot, and delivers a strategic roadmap. The primary deliverable is a compelling business case with ROI projections to secure executive sponsorship. Jumping straight to implementation without this alignment phase is the leading cause of failure.
* **Pilot Implementation (3-6 months):** This phase moves from strategy to execution. The consultant works hands-on with a single, selected business domain to build its first data product. This involves setting up the minimum viable self-serve platform on [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/), defining data contracts, and establishing the initial federated governance rules. A successful pilot serves as a concrete, repeatable blueprint for the rest of the organization.
* **Full-Scale Transformation (12-24+ months):** Following a successful pilot, the engagement shifts to scaling the data mesh across the enterprise. The consultant's role transitions from hands-on implementation to strategic guidance. They help onboard additional domains, mature the self-serve platform with more advanced capabilities, and formalize the federated governance council. This is a long-term partnership focused on embedding data mesh principles into your company's operating model.
> A data mesh consultant's role is to translate the four core principles - domain ownership, data as a product, a self-serve platform, and federated governance - into a step-by-step execution plan that works within your company's culture and tech stack. This is what prevents a data mesh from becoming another failed IT initiative.
Choosing the right entry point matters. An organization new to the concept should start with the strategic advisory phase to build alignment. Attempting a full-scale rollout from a standing start leads to wasted budget, team burnout, and a loss of stakeholder trust. Each phase builds on the last, delivering tangible value that justifies the next stage of investment.
## What are the four phases of a data mesh implementation?
A data mesh implementation runs through four phases: assessment and strategy (4-6 weeks), pilot domain onboarding (2-4 weeks), self-serve platform development (3-5 months), and scaling with federated governance (ongoing). Each phase validates the next before you commit more budget, instead of front-loading risk into one enterprise-wide rollout.
### Phase 1: Assessment and Strategy (4-6 Weeks)
The engagement begins with a rapid, intensive discovery phase. Consultants embed with leadership and technical teams to identify the primary business drivers for the data mesh. They map current data-related pain points to specific business outcomes that will be improved, such as reducing time-to-market for analytics or improving data quality for AI models. This phase also includes a candid assessment of your organization's readiness - evaluating technical skills, data governance maturity, and the cultural appetite for change. The key deliverable is a detailed roadmap that includes a business case, a high-level target architecture, and a recommendation for the first pilot domain.
### Phase 2: Pilot Domain Identification and Onboarding (2-4 Weeks)
Selecting the right first domain is critical. The ideal pilot candidate is a business domain that experiences significant data friction but is not overwhelmingly complex, led by a team that is enthusiastic about pioneering a new approach. A marketing analytics team struggling to get a unified view of customer data is a common and effective choice.
> A successful pilot is the single most important factor in a data mesh initiative. It is your internal proof-of-concept. It creates momentum, secures buy-in from skeptics, and gives you a repeatable playbook for everyone else.
Once selected, consultants work with the pilot domain team to define its first data product. This involves defining clear boundaries for the data, establishing formal data contracts (the API for the data), and setting service-level objectives (SLOs) for quality, freshness, and availability.
### Phase 3: Self-Serve Platform Development (3-5 Months)
In parallel with pilot onboarding, the platform engineering team, guided by consultants, builds the *minimum viable platform* (MVP) required for the pilot domain to succeed. The goal is not a feature-complete platform, but a functional core that enables autonomy. This typically involves configuring a cloud data platform like [Snowflake](https://www.snowflake.com/) or [Databricks](https://www.databricks.com/) and integrating essential tools for:
* **Data Ingestion and Transformation:** Using standards like [dbt](https://www.getdbt.com/) and [Airflow](https://airflow.apache.org/).
* **Data Discovery:** Implementing a data catalog so the new data product is discoverable.
* **Access Control:** Establishing the foundational guardrails for federated security.
### Phase 4: Scaling and Federated Governance (Ongoing)
With a successful pilot, the initiative shifts to scaling. The artifacts, infrastructure-as-code, and lessons from the pilot are codified into a playbook for onboarding subsequent domains. The consultant's role evolves from direct implementation to strategic enablement. They help establish the federated governance council, a cross-functional body comprising representatives from data domains and the central platform team. This council becomes the long-term owner of the mesh, responsible for evolving the standards, policies, and platform capabilities as the ecosystem grows.
## Who needs to be on your data mesh delivery team?
A data mesh delivery team needs four roles that don't exist in a traditional centralized setup: a data mesh strategist, domain-oriented data engineers embedded in business units, data product managers, and platform engineers who build the shared self-serve infrastructure. Your consulting partner's job is to supply the senior expertise to stand this structure up and transfer the skills to your internal team, not to staff it permanently.
Each role brings a different discipline: strategic vision, domain knowledge, product thinking, and platform engineering.
### Key Roles for a Data Mesh Initiative
Your delivery team is a hybrid of external consultants and internal staff. These are the critical roles required for a successful implementation:
* **Data Mesh Strategist (Consultant):** The senior guide for the initiative. This consultant crafts the strategic roadmap, secures executive buy-in, helps identify pilot domains, and designs the federated governance model.
* **Domain-Oriented Data Engineer (Internal/Consultant):** Embedded directly within a business unit (e.g., Marketing, Supply Chain), this engineer builds, tests, and maintains the data products for that specific domain.
* **Data Product Manager (Internal/Consultant):** This critical role applies a product management discipline to data. They own the lifecycle of a data product, ensuring it is discoverable, well-documented, reliable, and provides clear value to its consumers.
* **Platform Engineer (Internal):** This team builds and operates the underlying self-serve data platform, enabling domain teams to create and manage their data products autonomously.
The market for this expertise has grown accordingly, as more organizations look for consultants who have done this before rather than trying to build the playbook from scratch in-house.
### Data Mesh Consulting Team Roles and Rate Benchmarks
Budgeting for this work starts with understanding that data mesh roles sit above general data engineering rates. Across the [86 firms profiled in the Index](/insights/data-engineering-consulting-rates-2026/), hourly rates for data engineering work overall run $45-250, with a $100 median - but the senior, cross-functional roles a data mesh needs (strategist, domain architect, platform lead) tend to land in the upper part of that range or above it, closer to the market bands below.
| Consulting Role | Key Responsibilities | Typical Hourly Rate (USD) |
| :--- | :--- | :--- |
| **Data Mesh Strategist** | Defines vision, roadmap, governance; secures executive buy-in. | **$250 - $400+** |
| **Domain-Oriented Data Engineer** | Builds, tests, and deploys data products within a business domain. | **$175 - $275** |
| **Data Product Manager** | Manages data product lifecycle, from ideation to consumer value. | **$180 - $280** |
| **Platform Engineer** | Builds and maintains the self-serve data platform infrastructure. | **$170 - $260** |
These rates vary based on geography, consultant experience, and engagement complexity, but serve as a reasonable baseline for financial planning.
## How do you select a qualified data mesh consultant?
Vet a data mesh consultant on evidence, not pitch decks: demand specific past engagements, ask what business outcomes resulted, and interview the actual architects who would work on your account, not the account team that sold you. An unqualified partner will re-label your existing data warehouse as a "mesh," skip the cultural change work entirely, and burn through budget without producing anything different from what you already had.
Push past the pitch: ask what business outcomes previous engagements achieved, how organizational resistance was managed, and which specific data products got shipped.
### Evaluation Checklist for Data Mesh Consulting Partners
Use this checklist in your RFP to force vendors to provide specific, verifiable evidence of their capabilities.
| Category | Evaluation Criteria |
| :--- | :--- |
| **Technical Expertise** | **1.** Do they have deep, hands-on implementation experience with [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/)? Ask for certified architect numbers. **2.** Can they demonstrate prior work building self-serve data platforms with tools like [dbt](https://www.getdbt.com/) and [Airflow](https://airflow.apache.org/)? **3.** What is their experience implementing data catalogs and federated governance tools? |
| **Delivery Methodology** | **1.** Can they articulate a clear, domain-driven agile methodology? Request a sample project plan. **2.** How do they operationalize "data as a product"? Ask for their definition of a data contract and SLOs. **3.** What is their framework for identifying and prioritizing pilot domains? |
| **Change Management** | **1.** What is their plan for upskilling your internal teams? A good partner works to make themselves obsolete. **2.** How do they facilitate collaboration between central platform teams and decentralized domain teams? **3.** Can you speak with 2-3 past clients about their experience with the consultant's change management capabilities? (This is non-negotiable). |
### Critical Red Flags to Watch For
Be vigilant for consultants who lack substance behind the buzzwords.
* **The Technology-Only Pitch:** The biggest red flag is a firm that cannot clearly articulate how data mesh differs from a modern data warehouse. If their proposal focuses exclusively on technology and glosses over the socio-technical principles of domain ownership and federated governance, they do not understand the paradigm.
* **The One-Size-Fits-All Plan:** A rigid, templated implementation plan is another warning sign. Real data mesh consulting is adaptive, tailoring the approach to your organization's specific structure, maturity, and culture.
* **Weak Governance Expertise:** A consultant's value is heavily tied to their ability to implement a modern governance framework. Our [data governance best practices](/insights/data-governance-best-practices/) guide is a useful benchmark for what that should look like.
For a broader view of the specialist market, our overview of [data engineering consulting services](/insights/data-engineering-consulting-services/) is a good starting point.
## Next Steps: From Evaluation to Action
The theory is sound, but execution is what matters. A successful data mesh initiative starts with small, visible wins that build momentum and secure organizational buy-in. Do not attempt a "big bang" transformation.
Here is a three-step plan to move from concept to execution.
### Step 1: Build a Compelling Business Case
Secure executive sponsorship by framing the initiative in terms of business outcomes, not technology. Use the architectural comparisons and phase breakdown in this guide to connect data mesh principles to specific business problems. Show how decentralized data ownership will let the marketing team accelerate campaign analysis or help the supply chain team get a unified view of inventory. Translate the technical shift into speed, efficiency, and better decision-making.
> A data mesh is as much a cultural shift as it is a technical one. Getting executive sponsorship by clearly answering the "why" is the single most important thing you can do before a single line of code is written.
### Step 2: Conduct a Pilot Readiness Assessment
With executive support, identify your pilot project. Find a business domain that is experiencing significant data friction but is also culturally ready to pioneer a new way of working. A team that is technically capable but consistently blocked by the central data queue is an ideal candidate. A win here becomes your internal success story and the blueprint for expansion.
### Step 3: Shortlist Qualified Consulting Partners
With a business case and pilot domain identified, begin your partner search. Use the evaluation checklist from this guide to create a targeted RFP and shortlist 2-3 qualified firms. Focus your evaluation on finding a partner with verifiable, real-world experience building domain-driven data products and, equally important, guiding the organizational change required to make the transformation stick. A structured evaluation is the best way to see past sales pitches and identify a partner who has actually executed this playbook before.
## Frequently Asked Questions About Data Mesh Consulting
When engineering leaders get serious about data mesh, these are the first questions they ask. Here are the direct answers.
### What is the typical cost of a data mesh pilot?
Budget $150,000 to $400,000 for a data mesh pilot. This covers a 3 to 6-month engagement focused on launching your first data product.
The cost is driven by three factors:
1. **Domain Complexity:** A complex domain like finance or supply chain requires more discovery and data modeling, pushing costs higher.
2. **Platform Maturity:** If your underlying platform ([Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/)) is new, more consulting time is needed to build foundational self-serve capabilities.
3. **Team Readiness:** A team unfamiliar with data product thinking, CI/CD, and agile methods requires more hands-on coaching, increasing the cost.
### Can we implement data mesh without external consultants?
You can, but the risk of failure is high. Data mesh is an organizational change initiative disguised as a technology project. Consultants provide two key advantages: acceleration and de-risking. They bring a proven playbook for both the technical platform build and, more critically, the change management required to overcome internal resistance. Internal-only projects often reinvent technical wheels while failing to address the cultural inertia that stalls the project. The cost of delays and a failed initiative almost always exceeds the consulting fees.
### Does data mesh work with our existing Snowflake or Databricks platform?
Yes. Data mesh is an architectural and organizational approach, not a product that replaces your cloud data platform. Snowflake and Databricks are both solid foundations for it - their native data sharing, granular security controls, and integration with tools like [dbt](https://www.getdbt.com/) are the building blocks for creating and managing autonomous data products. Your consultant's job is to put these features to work implementing the data mesh principles, not to replace your platform.
## Putting the Data Mesh Business Case Into Practice
These four phases and four roles work as a system: skip the strategic advisory phase and you skip the executive alignment that funds everything after it; skip the pilot and you have no proof point to sell scaling on; skip federated governance and domain autonomy turns into domain chaos. The cost and timeline benchmarks above are useful, but the real diagnostic in every one of these questions is organizational readiness, not technology.
If you're still deciding whether mesh is the right architecture at all, [data lakehouse vs. data mesh](/insights/data-lakehouse-vs-data-mesh/) covers that fork. Once you're ready to talk to partners, the evaluation checklist above doubles as an RFP scorecard, and the [data engineering consulting firms directory](/data-engineering-consulting-firms/) is where to start building your shortlist.
---
## Data Migration Best Practices: A Technical Blueprint for 2026
Source: https://dataengineeringcompanies.com/insights/data-migration-best-practices/
Published: 2026-01-19T09:18:15.917466+00:00
Description: Explore data migration best practices for a smooth, low-risk transition. Learn planning, testing, and post-migration steps in this practical guide.
Data migration best practices come down to five disciplines: inventory the data before moving it, cut over in phases instead of one big bang, validate quality at every step, prepare the people who depend on the data, and keep monitoring after go-live. Skipping any one of them is what turns a migration into a budget overrun or a rollback nobody planned for.
This guide covers ten practices for migrating to platforms like Snowflake or Databricks, plus a comparison table for choosing between big-bang, trickle, and hybrid cutover patterns. Migration work is common enough among data engineering specialists that 78 of the 86 firms profiled in the [Data Engineering Companies Index](/data-migration-companies/) name data migration among their capabilities - the harder part is finding a partner who does it well, not just one who lists it.
What this guide covers:
* **Data discovery and dependency mapping** before project kickoff.
* **Phased rollout strategies** using pilot programs to contain technical and business risk.
* **Security and governance controls** embedded from day one, not layered on after launch.
* **FinOps-driven cost management** to control cloud spend once the migration is complete.
## 1. Why does data migration start with a full assessment and inventory?
A migration without a full inventory is one of the most common causes of project failure. Before moving a single byte, catalog every data source, map its lineage, assess its quality, and flag dependencies and embedded business rules - the goal is a clear answer to what data exists, where it lives, who owns it, its quality, and what regulations (GDPR, HIPAA) apply to it.
This step determines everything downstream. A healthcare organization that catalogs Protected Health Information (PHI) upfront can architect a compliant cloud environment from the start instead of reworking it later. A retail chain that documents dependencies between its POS, inventory, and CRM systems avoids data integrity issues when it moves to a platform like Databricks.
### Actionable Implementation Tips
* **Automate discovery.** Manually cataloging petabytes of data doesn't scale. Tools like Collibra, Alation, or the open-source OpenMetadata speed up inventory and lineage mapping.
* **Engage business stakeholders early.** Technical teams identify data, but only business users can explain its value, usage, and criticality - bring them in to classify data and validate business rules.
* **Build a data dictionary.** The key deliverable is a metadata repository that serves as a single source of truth for your data assets. See this [cloud migration assessment checklist](/insights/cloud-migration-assessment-checklist/) for a structured starting point.
* **Prioritize sensitive data first.** Tag data subject to compliance and security requirements early so controls are built into the migration design from the start, not bolted on later.
## 2. Why use a phased migration with pilot programs instead of a big-bang cutover?
A "big bang" cutover concentrates all the risk into a single event. A phased approach breaks the migration into manageable stages - starting with non-critical workloads or pilot programs - so the architecture, tooling, and validation process get tested in a low-risk environment before business-critical systems move. Issues that would otherwise surface during a high-stakes production cutover get caught during the pilot instead.
An enterprise retailer migrating to a Databricks lakehouse can start with non-real-time reporting data. Success in that phase builds confidence and produces a playbook for migrating more sensitive, customer-facing analytics workloads next - and lessons from early phases sharpen the budget estimates for later ones.
### Actionable Implementation Tips
* **Define phase-specific success criteria.** Before each phase, set measurable targets - 99.9% data validation accuracy, a specific query performance benchmark, or pilot-group sign-off.
* **Pick a representative pilot.** Choose a workload representative of future migrations in data type and complexity, but not mission-critical - an insurance company might pilot with historical claims data before touching core underwriting systems.
* **Document and iterate.** Log lessons, technical issues, and process changes from each phase in a runbook to speed up the next one.
* **Plan for parallel operations.** Source and target systems will coexist during a phased migration - allocate resources to manage both environments and keep data consistent until final cutover. Use the execution-pattern table below to choose between big-bang, trickle, and hybrid cutovers.
## 3. What does a data quality validation and testing framework need to cover?
Skipping a rigorous testing framework guarantees corrupted data, broken processes, and lost user trust. Compare source and target data on accuracy, completeness, and consistency - not just row counts, but data types, referential integrity, and business logic - as a built-in stage of the migration pipeline, not an afterthought.

A financial institution needs to validate every transaction record to prevent reconciliation errors. A healthcare provider migrating patient records to Snowflake needs automated quality checks to protect data integrity for HIPAA compliance and patient safety. Without this validation, the new system just inherits unreliable data - and the project's ROI along with it.
### Actionable Implementation Tips
* **Automate with modern tooling.** dbt tests and the open-source Great Expectations library let you codify data quality checks directly into transformation pipelines.
* **Tier your validation rules.** Classify tests as critical (financial totals, unique keys), important (address formatting), and informational - this focuses remediation on what actually matters.
* **Define acceptable variance upfront.** A zero-variance target is often impractical at scale; agree on tolerance levels with business stakeholders before you start.
* **Involve business analysts.** Data stewards and analysts understand business context that technical teams often miss, so bring them into test design to make sure data is functionally valid, not just technically correct.
## 4. Why does data migration need a change management plan?
A technically flawless migration can still fail if the people using the data aren't prepared for it. Identify every affected group - from executive sponsors to frontline analysts - and tailor training and communication to each. This is the human-centric counterpart to technical execution: it manages expectations and turns resistance into adoption.
Without a change management strategy, adoption falters and data quality can degrade even after a technically clean migration. A healthcare network that assigns "change champions" at each facility can speed adoption and keep data entry consistent. A manufacturing firm that puts its executive steering committee behind a Databricks rollout secures alignment across business units.
### Actionable Implementation Tips
* **Assign a dedicated change lead**, separate from the technical project manager, focused solely on stakeholder engagement, training, and communication.
* **Translate technical benefits into business language.** Instead of "we're moving to Snowflake for scalability," tell the finance team "quarterly reports will run in minutes instead of hours."
* **Recruit champions and early adopters.** Peer-to-peer influence from enthusiastic users often beats top-down corporate messaging.
* **Schedule training close to go-live** to maximize retention.
* **Keep feedback loops open** - a dedicated Slack channel or regular forum where users can ask questions and see them addressed. The [Prosci ADKAR Model](https://www.prosci.com/methodology/adkar) is a useful framework for structuring this.
## 5. Why should ETL/ELT pipelines be automated during migration?
Manually managing pipelines during a migration invites inconsistency, errors, and delays. Treat pipelines as code - version-controlled, tested, and deployed through CI/CD - so every data load runs the same transformation rules and quality checks without manual intervention, the most common source of migration failure.
In modern cloud environments like Snowflake or Databricks, data volume and velocity make manual pipeline management impossible. A SaaS company using a tool like Fivetran can automate real-time replication from transactional databases into Snowflake. A Databricks implementation using Apache Airflow to orchestrate ingestion into Delta Lake enforces quality rules automatically before data reaches ML models.
### Actionable Implementation Tips
* **Choose orchestration tools that fit your platform.** Apache Airflow or Azure Data Factory for Databricks; for Snowflake, look at its partner ecosystem - dbt, Fivetran, Matillion.
* **Make transformations idempotent** so re-running a process after a failure doesn't create duplicate data.
* **Set up proactive alerting** so the data engineering team hears about pipeline failures, schema drift, or quality issues immediately, not after someone notices bad numbers downstream.
* **Version control everything** - pipeline definitions, SQL/Python scripts, and configuration files in Git - for collaboration, rollback, and an audit trail.
## 6. How should security and governance be handled during migration?
Treating security as a post-migration concern is a critical mistake. Define access controls, encryption standards, and data masking rules from the outset, so the new environment meets GDPR, HIPAA, or SOC 2 requirements before it goes live - not after an audit flags the gaps.

Addressing security early prevents costly architectural rework and the risk of breaches or fines. A European retail company migrating to Snowflake can implement dynamic data masking and row-level access policies to comply with GDPR from the initial load. A financial services firm can use Databricks Unity Catalog for fine-grained access controls on PCI-DSS data.
### Actionable Implementation Tips
* **Start from zero-trust.** Grant users and systems only the minimum access required to do their job.
* **Use native platform security features.** Databricks and Snowflake both ship with granular controls - column-level security, tag-based masking policies, and Unity Catalog.
* **Map regulatory requirements during the initial assessment**, not afterward, so compliance shapes the migration design instead of retrofitting it.
* **Document every security decision** - configurations, access changes, transformation logic - for audits. See [data governance best practices](/insights/data-governance-best-practices/) for a fuller framework.
## 7. How do you keep cloud costs under control after migrating?
Lifting-and-shifting legacy inefficiencies into the cloud guarantees a budget overrun. Treat cloud resources as a metered utility from day one: right-size compute clusters, pick efficient storage formats, optimize the costliest queries, and assign financial accountability - performance and cost are the same problem in the cloud.
An inefficient query doesn't just run slowly - it burns expensive compute credits. A retail company on Databricks can use autoscaling to match compute to demand instead of paying for idle clusters. A tech firm can cut its Snowflake warehouse bill meaningfully just by rewriting a handful of inefficient queries.
### Actionable Implementation Tips
* **Monitor spend from day one.** AWS Cost Explorer, Azure Cost Management, or a third-party platform for granular visibility.
* **Build a cost allocation model** that maps spend back to business units or projects - a "showback" or "chargeback" model that creates accountability.
* **Apply the 80/20 rule to queries.** Profile workloads, find the 20% of queries burning 80% of compute, and target those for refactoring.
* **Default to efficient formats.** Parquet or ORC for storage; schedule non-critical batch jobs for off-peak hours.
* **Review quarterly.** Cost optimization isn't a one-time project - revisit spending, new opportunities, and forecasts every quarter.
## 8. What documentation does a migration need to leave behind?
Skipping documentation creates technical debt that shows up months later, once the migration team has moved on. Keep a living record of architectural decisions, data lineage maps, and operational runbooks that explains not just what was done but why - that's what makes the system maintainable long after go-live.
A financial services firm can use detailed runbooks to resolve a critical pipeline failure fast instead of reverse-engineering the system under pressure. A manufacturing company with documented data architecture can walk an auditor through compliance without scrambling.
### Actionable Implementation Tips
* **Document as you go**, not after the fact - start on day one and update iteratively.
* **Standardize with templates and version control.** Store technical docs and configuration-as-code in Git; Confluence or GitBook work well for shared knowledge bases.
* **Assign clear ownership** for each documentation artifact so it's someone's actual job, not an afterthought.
* **Explain the reasoning, not just the steps.** Why this ETL tool? Why this data model? That context is what future engineers actually need.
## 9. Why does a dedicated vendor team matter more than headcount?
A transactional vendor relationship, staffed with shared or rotating people, creates context-switching and knowledge gaps. A dedicated model - where the same architects and engineers stay on your project - moves faster, because that team builds real understanding of your data and business objectives instead of relearning it every sprint.
A financial services firm retaining dedicated cloud architects for a multi-year migration keeps architectural decisions consistent from year one to year three. A large retailer with a dedicated Databricks consulting team can move faster on bespoke data models than one relying on a shared resource pool.
### Actionable Implementation Tips
* **Name key personnel in the SOW.** The Statement of Work should name the lead architect and senior engineers and specify their time commitment (e.g., 100% allocation).
* **Verify the proposed team.** Ask for resumes and interview the actual lead architect and senior engineers, not just the account team that pitched you.
* **Set a fixed communication cadence** - daily stand-ups, weekly stakeholder reporting, and a defined escalation path.
* **Require a knowledge transfer plan in the contract**, starting early in the engagement rather than in the final weeks.
* **Plan for post-launch support.** Build in a hypercare period (30-90 days minimum) with the same dedicated team, not a rotating support desk.
## 10. Does the work end at cutover?
No. Treating cutover as the finish line is a common and costly mistake. A successful migration moves into a continuous cycle of monitoring performance, cost, data quality, and user adoption - borrowing from SRE and FinOps practices to keep answering whether the platform is meeting SLAs, costs are under control, and users are actually adopting it.
Ongoing monitoring is what validates the business case. A SaaS company monitoring its Snowflake environment can track query performance and cost together, optimizing inefficient workloads before they hurt both. A healthcare system tracking Databricks uptime and adoption metrics can confirm clinicians can reliably reach the data they need.
### Actionable Implementation Tips
* **Set baselines during the pilot.** Use pilot-phase performance data as the pre-cutover benchmark for measuring post-migration success.
* **Share dashboards.** Datadog, New Relic, or native cloud monitoring tools showing performance, cost, and adoption metrics in one place.
* **Run FinOps reviews monthly.** Deep-dive the highest resource-consuming queries and users, and act on what you find.
* **Build a feedback loop with users.** Their qualitative experience should drive what gets prioritized next.
## Which migration execution pattern should you choose?
The right pattern depends on how much downtime, operational overlap, and rollback complexity the project can absorb - **big bang for small, downtime-tolerant systems; trickle for business-critical systems that need continuity; hybrid for larger estates with a mix of independent and interdependent workloads.** Select it during discovery, before pipelines are built, not after.
| Pattern | How it works | Best fit | Main trade-off |
|---|---|---|---|
| **Big bang** | Move the scoped workload during one planned cutover window. | Small, well-understood systems that can tolerate downtime. | The shortest transition period, but the highest concentration of cutover risk. |
| **Trickle** | Move data and workloads in stages while source and target run in parallel. | Business-critical systems that require continuity and incremental validation. | Lower cutover risk, but more time spent reconciling two live environments. |
| **Hybrid** | Migrate low-risk domains in stages, then cut over tightly coupled components together. | Larger estates with a mix of independent and interdependent workloads. | More flexible, but coordination and dependency management are harder. |
Regardless of the pattern, define rollback triggers before execution. Record who can stop the cutover, how writes will be reconciled, which validation checks must pass, and how the source system will be restored if the target fails acceptance testing. For phased work, assign explicit ownership for source-to-target reconciliation until the legacy environment is retired.
## Top 10 Data Migration Best Practices Comparison
| Practice | Implementation complexity | Resource requirements | Expected outcomes | Ideal use cases | Key advantages |
|---|---:|---|---|---|---|
| Comprehensive Data Assessment and Inventory | High - time-intensive audit | Data discovery tools, analysts, stakeholder time | Complete inventory, risk & compliance visibility | Large legacy migrations, regulated environments | Reduces surprises, enables accurate planning |
| Phased Migration Approach with Pilot Programs | Medium-High - multi-phase orchestration | Pilot environments, QA, parallel operations | Validated architecture, gradual cutover, early wins | Complex systems, business-critical workloads | De-risks migration, builds internal expertise |
| Data Quality Validation and Testing Framework | Medium-High - test design & automation | Testing tools (dbt/Great Expectations), data stewards | High data integrity, auditable validation | Finance, healthcare, analytics-sensitive projects | Catches issues pre-go-live, supports compliance |
| Clear Change Management and Communication Plan | Medium - organizational coordination | Change leads, trainers, communication channels | Higher adoption, fewer workarounds, stakeholder alignment | Enterprise rollouts, user-facing platform changes | Increases adoption, reduces resistance |
| Automated Data Pipeline and ETL Validation | High - engineering & orchestration work | Orchestration tools, engineers, monitoring | Reliable, timely data delivery; fewer manual errors | Real-time analytics, high-volume ingestion | Scales reliably, improves operational efficiency |
| Security, Compliance, and Data Governance Framework | High - policy + technical controls | Security architects, RBAC, masking & logging tools | Regulatory compliance, reduced breach risk | Regulated industries, sensitive data migrations | Prevents violations, simplifies audits |
| Performance Optimization and Cost Management | Medium - ongoing tuning effort | SQL experts, cost tools, monitoring | Lower cloud costs, improved query performance | High-query workloads, cost-sensitive orgs | Reduces spend, improves user experience |
| Documentation and Knowledge Transfer | Low-Medium - disciplined upkeep | Technical writers, runbooks, training sessions | Preserved institutional knowledge, faster onboarding | Long-term operations, vendor transitions | Enables self-service, aids troubleshooting |
| Vendor Partnership and Dedicated Resource Models | Medium - contractual setup & governance | Dedicated vendor team, TAMs, SLAs | Continuity, accountability, faster issue resolution | Large engagements, limited internal capacity | Improves ownership, accelerates delivery |
| Post-Migration Monitoring, Optimization, and Continuous Improvement | Medium - sustained process commitment | Monitoring platforms, analysts, dashboards | Ongoing ROI, proactive optimization, trend visibility | Mature platforms, continuous delivery environments | Sustains value, identifies optimization opportunities |
## Putting the Blueprint Into Practice
These ten practices work as a system, not a checklist to complete in order. Assessment defines scope; phasing controls risk; testing catches what assessment missed; change management gets people to actually use what you built; and monitoring proves the investment was worth it. Skip a step and you shift the risk to a later, more expensive phase instead of removing it.
The practice most teams underinvest in is the boring one: documentation and post-migration monitoring. Both pay off months after go-live, long after the project team has moved to the next thing - which is exactly when a skipped runbook or an unmonitored cost spike becomes expensive.
If you're still choosing between platforms, [data warehouse vs. data lake](/insights/data-warehouse-vs-data-lake/) covers the architecture decision, and [Snowflake to Databricks migration](/insights/snowflake-to-databricks-migration/) covers moving between the two most common lakehouse targets. Once you're migrating, the ten practices above double as a scorecard for vetting a [migration partner](/data-migration-companies/) - ask how they handle each one, not just whether they've done migrations before.
---
## A Practical Guide to Data Modeling Techniques for Modern Data Platforms
Source: https://dataengineeringcompanies.com/insights/data-modeling-techniques/
Published: 2026-01-08T08:34:48.821939+00:00
Description: Explore data modeling techniques and practical guidance across relational, dimensional, and Data Vault models for Snowflake, Databricks, and more.
Data modeling techniques are the blueprints for organizing information inside a data platform. The three that matter for most engineering teams are the relational model, the dimensional model, and Data Vault, and each is built for a different job: relational for transactional integrity, dimensional for fast analytical queries, Data Vault for auditable, source-agnostic integration. Picking the wrong one for the job doesn't show up as a modeling error, it shows up months later as slow dashboards and an inflated cloud compute bill.
This guide walks through how each model works, how the choice plays out specifically on Snowflake and Databricks, and how to apply all three to the same e-commerce scenario so the trade-offs are concrete rather than theoretical.
## Why does choosing the right data model matter more once you're on the cloud?
Data modeling is the architectural design phase for your data infrastructure, and the technique you pick has to match the intended business outcome. Get the match wrong and you end up with slow queries, inflated cloud compute costs, and a data platform that produces reports nobody trusts.
This guide is a practical walkthrough for data engineers and technical leaders: how each model affects analytics performance, scalability, and cost, particularly on cloud platforms like [Snowflake](https://www.snowflake.com/en/) and [Databricks](https://www.databricks.com/). The model you choose is the foundation everything else in the platform gets built on.
### Why data modeling still matters when storage is cheap
Cheap cloud storage and powerful compute make it tempting to load raw data into a lake and defer structure until later. That approach usually produces a "data swamp" - an unreliable, disorganized repository that isn't usable for serious analytics. Data modeling is what keeps that from happening.
A well-designed data model delivers tangible benefits:
* **Clarity and Consistency:** It establishes a single source of truth by enforcing business rules and defining data relationships in an unambiguous, structured manner.
* **Performance Optimization:** By organizing data around its query patterns, a proper model reduces query latency and, with it, compute cost.
* **Scalability:** It provides a framework that can absorb new data sources and changing business requirements without a full architectural overhaul.
* **Effective Governance:** It simplifies lineage tracking, quality checks, and compliance reporting by giving you a clear, logical map of the data.
### Where today's modeling techniques came from
The relational model, formalized by Edgar F. Codd in 1970, introduced the tables-and-keys structure that still runs the majority of transactional systems today. It became the industry standard by the late 1980s, replacing the hierarchical databases that came before it, and its core ideas have outlasted several generations of hardware since.
New techniques developed since then were built for analytics at scale, not to replace that foundation. Architectures like the lakehouse don't substitute for data modeling. They're a new environment where the same modeling principles get applied. For more on how a lakehouse compares to a traditional warehouse, see our guide on [data warehouses vs. data lakes](/insights/data-warehouse-vs-data-lake/).
## What are the three core data modeling techniques, and when should you use each one?
Data modeling means choosing a philosophy for how information gets organized. The three techniques below aren't rigid rulebooks. They're strategic frameworks, and understanding the "why" behind each one is what lets you match the right technique to the right business problem.
### 1. The Relational Model: Optimized for Data Integrity
The relational model, typically implemented in its **Third Normal Form (3NF)**, is the most established approach. Its core philosophy is the elimination of data redundancy to ensure data integrity. It deconstructs data into its smallest logical components, storing each in a separate, normalized table.
For example, a single customer order is atomized into tables for customers, orders, order line items, and products. This structure is the gold standard for data integrity. If a customer's address changes, the update occurs in a single location, and the change is instantly propagated through relationships.
This focus on write-efficiency and consistency makes the relational model the standard for **Online Transaction Processing (OLTP)** systems. These are the databases that power daily business operations like e-commerce transactions, banking, and inventory management.
### 2. The Dimensional Model: Optimized for Analytical Queries
While the relational model excels at writing and updating data, its highly normalized structure is inefficient for analytics. Answering a simple business question can require joining numerous tables, resulting in slow and complex queries. The **dimensional model**, developed by Ralph Kimball, was engineered to solve this problem.
Its philosophy is to organize data for intuitive browsing and fast query performance. The model centers on a **fact table** (containing quantitative metrics like sales totals) surrounded by descriptive **dimension tables** (providing context like time, location, and product). This structure is known as the [**star schema**](/insights/snowflake-schema-and-star-schema/).
Data is intentionally "denormalized," reintroducing some redundancy to simplify the structure. A sales fact table holds key metrics (revenue, quantity) and is linked directly to dimension tables for date, customer, and product. This design enables BI tools to efficiently slice and dice data, answering questions like, "What were total sales by product category in the Northeast last quarter?" with minimal latency.
> By prioritizing query performance and business usability over storage efficiency, dimensional modeling became the foundation of modern analytics. It is designed for read-heavy reporting workloads where speed and simplicity matter most.
### 3. The Data Vault Model: Optimized for Scalability and Auditability
Modern data ecosystems are characterized by a high volume of disparate data sources and evolving business rules. Both relational and dimensional models can be brittle in this environment; integrating a new source often requires significant re-engineering. The **Data Vault** model was designed specifically to handle this complexity with agility and full auditability.
Its philosophy is to ingest raw data from source systems with complete traceability and historical context, *without* applying business logic upfront. It organizes data into three core components:
* **Hubs:** Store unique business keys (e.g., Customer ID, Product SKU). They represent the core business entities.
* **Links:** Define the relationships or transactions between Hubs (e.g., a link connecting a specific customer to a purchased product).
* **Satellites:** Contain the descriptive, time-stamped attributes associated with Hubs or Links (e.g., a customer's address or a product's price), capturing all historical changes.
This structure is highly resilient. Integrating a new data source involves adding new Hubs, Links, and Satellites without altering the existing model. This makes Data Vault an excellent choice for the raw integration layer of a data warehouse, providing a fully auditable, scalable foundation from which curated, business-focused data marts can be built.
### Comparing Data Modeling Techniques at a Glance
This table breaks down the primary goals and trade-offs of the three core philosophies to help guide selection.
| Technique | Primary Goal | Best For | Key Weakness |
| :--- | :--- | :--- | :--- |
| **Relational (3NF)** | Eliminate Redundancy & Maximize Integrity | Transactional Systems (OLTP) | Complex and slow for analytical queries. |
| **Dimensional** | Optimize for BI & Fast Query Performance | Data Warehouses & Analytics (OLAP) | Can be less flexible for integrating new sources. |
| **Data Vault** | Maximize Scalability & Auditability | Raw Data Integration Layers | Overly complex for direct BI querying. |
The optimal model is context-dependent. The choice must align with the specific objective, whether it's processing transactions with high fidelity, enabling rapid business insight, or building a foundation for enterprise data that can absorb whatever comes next.
## How does your modeling choice drive cloud platform costs?
In on-premise data warehouses, a suboptimal data model showed up as slow reports. In the cloud it shows up as a bill: every inefficient query burns compute credits, and your data modeling technique is one of the biggest levers you have over that spend.
Consumption-based pricing models from platforms like [Snowflake](https://www.snowflake.com/en/) and [Databricks](https://www.databricks.com/) have shifted the economic calculus. Compute is now the primary cost driver, not storage. This reality requires a re-evaluation of data modeling efficiency. A model considered efficient a decade ago can be a financial liability in the cloud.
### Snowflake and the Power of Denormalization
Snowflake's architecture is optimized for high-speed analytical queries and rewards models that align with its strengths. Running an analytical query on a highly normalized **Third Normal Form (3NF)** model requires the query engine to perform multiple complex joins, piecing together data from numerous tables.
Each join consumes processing power, spinning up virtual warehouses and accruing compute credits. While 3NF is ideal for eliminating redundancy in OLTP systems, it is an inefficient and costly approach for analytics in a consumption-based cloud data warehouse.
This is where a denormalized dimensional model, such as a **star schema**, becomes a cost-optimization tool.
> By pre-joining and denormalizing data into wide fact and dimension tables, you dramatically reduce the complexity of analytical queries. Instead of multi-table joins, analysts execute simple, direct queries that Snowflake's engine processes with high efficiency, minimizing warehouse usage and controlling costs.
Aligning the data model with the platform's architecture is a critical cost management strategy. In Snowflake, implementing a star schema is not just a performance tactic; it is an economic decision.
### Databricks, The Lakehouse, and Medallion Architecture
The [Databricks](https://www.databricks.com/) lakehouse environment prioritizes flexibility and scalability, particularly for managing diverse and evolving data sources. The **Data Vault** modeling technique is highly effective in this context, especially when paired with the **Medallion Architecture**.
The Medallion Architecture (Bronze, Silver, Gold) is a data quality and lifecycle management framework, not a data modeling technique itself. It provides a logical progression for refining data, and different modeling techniques are applied at each layer.
* **Bronze Layer:** Raw, unaltered data lands here. Minimal to no modeling is applied.
* **Silver Layer:** Data is cleansed, conformed, and integrated. This layer is the ideal home for a Data Vault model. Its structure accommodates schema changes from source systems and provides a fully auditable historical record without prematurely applying business rules.
* **Gold Layer:** Data is aggregated and optimized for specific business use cases. This layer is almost always built using dimensional models (star schemas) to serve high-performance, user-friendly datasets for BI and analytics.
This hybrid approach draws on the strengths of multiple techniques. The Data Vault in the Silver layer provides a scalable and governed foundation. From this stable core, multiple purpose-built, cost-effective star schemas can be provisioned in the Gold layer, ensuring analytics are both fast and based on trusted, auditable data.
The infographic below illustrates the core philosophies behind these different modeling approaches.

This visual comparison clarifies how Relational, Dimensional, and Data Vault models are each optimized for different objectives - integrity, analytics, or auditability - which in turn dictates their cost and performance on cloud platforms.
## How do the three models answer the same business question differently?
Modeling the same e-commerce order data three ways, as a normalized 3NF schema, a dimensional star schema, and a Data Vault, reveals what each technique actually optimizes for. Asking all three the same question, "what were total sales by category last quarter," shows exactly where the complexity moves.

### Example 1: The 3NF Relational Model
The relational model in **Third Normal Form (3NF)** prioritizes the elimination of data redundancy, making it ideal for operational databases that must process transactions with high efficiency and integrity.
For our e-commerce scenario, a single customer order is atomized into multiple specialized tables. Each piece of information is stored once.
* `Customers`: Contains only customer data (CustomerID, Name, Address).
* `Products`: Contains only product information (ProductID, ProductName, Category).
* `Orders`: Records core transaction details (OrderID, CustomerID, OrderDate).
* `Order_Items`: Links orders to products and stores line-item details (OrderItemID, OrderID, ProductID, Quantity, Price).
**Answering the Question:**
To calculate total sales by category, an analyst must write a query that joins `Orders` to `Order_Items` and then joins that result to `Products`. While this ensures data consistency, the join complexity makes it computationally expensive and slow for recurring analytical workloads.
### Example 2: The Dimensional Star Schema
The dimensional model reshapes the same data for analytical performance. The goal is to create an intuitive structure for fast querying, resulting in a **star schema**.
The model is built around a central **fact table** (numeric measures) linked directly to descriptive **dimension tables** (context).
* **`fct_orders` (Fact Table):** Contains the core numeric measures like `quantity_sold` and `total_sales_amount`, along with foreign keys (`customer_key`, `product_key`, `date_key`) that reference the dimension tables.
* **`dim_customer` (Dimension Table):** Contains all descriptive customer attributes (name, location, segment).
* **`dim_product` (Dimension Table):** Contains all product attributes, including `name`, `brand`, and `category`.
* **`dim_date` (Dimension Table):** A dedicated table for time-based analysis, with columns for day, month, quarter, and year.
> The power of the star schema lies in its simplicity. We intentionally denormalize some data (e.g., storing the product category directly in `dim_product`) to eliminate the complex joins required by the 3NF model.
**Answering the Question:**
An analyst writes a simple query joining the `fct_orders` table directly to `dim_product` and `dim_date`. They can filter by `quarter` in the date dimension and group by `category` in the product dimension. This clean, direct query path is what enables the rapid response times expected from modern BI tools.
### Example 3: The Data Vault Model
A **Data Vault** model prioritizes auditability, scalability, and the non-destructive integration of data from multiple source systems.
It deconstructs the business process into its fundamental components: Hubs, Links, and Satellites.
* **`hub_customer` & `hub_product` (Hubs):** Store only the unique business keys for core entities (`CustomerID`, `ProductID`). They are the "nouns" of the business.
* **`link_order` (Link):** Documents the relationship (transaction) between Hubs. It holds the keys for `hub_customer` and `hub_product`, plus the order identifier. It represents the "verb."
* **`sat_customer_details` & `sat_product_details` (Satellites):** Contain the descriptive, time-stamped attributes for each hub. For example, `sat_customer_details` stores the customer's name and address with load dates, providing a complete historical record of all changes.
**Answering the Question:**
Generating the sales report from a raw Data Vault requires joining Hubs, Links, and Satellites to reconstruct the business context. Due to this complexity, a Data Vault is rarely queried directly by end-users for BI. Instead, it serves as a durable, auditable foundation, a single source of truth, from which user-friendly dimensional models (star schemas) are built for the final analytics layer.
## What changes once a data model moves from whiteboard to production?
A data model isn't a diagram, it's the operational core of your data platform: its structure dictates your ETL/ELT pipeline logic, your [modern data stack](/insights/modern-data-stack/) tooling choices, and how much governance work happens automatically versus manually.
Implementing a data model in a production environment is where theory meets the complexities of real-world data operations. Its design also sets the foundation for how you handle [data contracts between teams](/insights/data-contracts-in-data-engineering/) that produce and consume the same data.
### How Your Model Shapes Your Pipelines
The structure of your data model defines the logic for your ETL (Extract, Transform, Load) or ELT (Extract, Load, Transform) pipelines. The two are intrinsically linked. A mismatch creates brittle, inefficient processes that are difficult to maintain.
Different models require different pipeline logic:
* **Dimensional Models:** Building a star schema requires transformation-heavy pipelines. They must join data from multiple sources, calculate derived metrics, and manage slowly changing dimensions *before* loading the final, curated data into fact and dimension tables.
* **Data Vault Models:** In contrast, loading a Data Vault is typically a simpler, more direct process. Pipelines are designed to insert raw, unaltered data into Hubs, Links, and Satellites with minimal transformation. The complex business logic is applied downstream when building the consumption layer.
> The decision is not about which approach is "easier" but about where to manage complexity. A dimensional model front-loads the transformation work to optimize query performance. A Data Vault simplifies the initial ingestion to maximize auditability and flexibility, deferring complex transformations to the final stage.
### Building Governance Directly Into Your Model
An effective data governance strategy is impossible without a well-designed data model. The model provides the structural map needed to manage data quality, track lineage, and enforce compliance.
The choice of **data modeling technique** directly impacts governance capabilities. A Data Vault, for example, is inherently designed for auditability. Its structure captures historical changes and source system metadata by default, making data lineage a built-in feature rather than an add-on.
A dimensional model, conversely, acts as a governance checkpoint. By enforcing business rules and consistency during the loading process, it ensures that data exposed to analysts is already cleansed and conformed, providing a trusted single source of truth for reporting.
### Taming Schema Evolution and Setting Standards
Business requirements and source systems change. New fields are added, old ones are deprecated, and definitions evolve. How a data model handles this **schema evolution** determines its long-term viability.
Discipline around standards and tooling is non-negotiable.
1. **Enforce Naming Conventions:** A consistent schema for naming tables and columns (e.g., using prefixes like `fct_`, `dim_`, `stg_`) makes the data warehouse immediately comprehensible and maintainable.
2. **Mandate Documentation:** Every table, column, and transformation requires a clear, accessible description. This is essential for long-term maintenance and onboarding new team members.
3. **Adopt dbt-Style Tooling:** Tools like [dbt](https://www.getdbt.com/), used by 20 of the 86 firms profiled in the [Data Engineering Companies Index](/data-engineering-consulting-firms/), have become central to modern data engineering because they let teams define standards, automate data quality tests, and version-control transformation logic, turning governance policy into executable code.
By putting a disciplined process in place for managing change, you build a data model that can adapt without fracturing. This also positions you to properly evaluate engineering partners on their ability to build systems that hold up as requirements change.
## Which Data Modeling Approach Should You Actually Use?
There's no single best data modeling technique. The right one depends on whether you're optimizing for transaction integrity, analytics speed, or auditability, and most cloud platforms end up using more than one at different layers. Here are direct answers to the questions data leaders and their teams ask most.
### Which Data Model Is Best for AI and Machine Learning?
There is no single "best" model; the right choice depends on the specific AI/ML application.
For **feature engineering**, a denormalized, wide-table format is typically most effective. This involves creating a single, feature-rich table that aggregates all the variables a model might need. Such tables are often derived from a dimensional model (the Gold layer in a Medallion Architecture), providing ML algorithms with a flat, easy-to-consume dataset.
However, for applications requiring high auditability, such as fraud detection systems that must trace transactions to their source, a **Data Vault** model is invaluable. Residing in the Silver layer, it provides the untransformed, historical data needed to source trustworthy features.
The final **feature store** consumed by an ML model will almost always be a denormalized view. The underlying Dimensional or Data Vault models provide the governed, structured foundation to create those features reliably and repeatably.
### Can We Mix and Match Different Data Models?
Yes, and it is a modern best practice to do so. A hybrid approach that combines multiple data modeling techniques within the same data platform typically provides the most flexible and powerful solution.
A highly effective pattern is to use a [Data Vault](https://www.snowflake.com/guides/what-data-vault) in the integration layer (the "Silver" layer). It is designed to ingest raw data from diverse sources and maintain a perfect, auditable record. From this central vault, multiple data marts using **dimensional models** (star schemas) can be provisioned for different business domains.
> This strategy combines the scalability and audit trail of a Data Vault with the query performance and business-friendliness of dimensional models, delivering the best of both worlds.
### How Does the Medallion Architecture Fit into All This?
The **Medallion Architecture** (Bronze, Silver, Gold) is not a data modeling technique itself. It is a data quality and lifecycle framework that organizes the flow of data from raw to refined. Think of it as the factory layout, while data modeling techniques are the machinery within it.
They work together as follows:
* **Bronze Layer:** Raw data ingestion. Minimal or no formal modeling is applied.
* **Silver Layer:** Data is cleansed, validated, and integrated. This is the ideal layer to implement a normalized (3NF) or **Data Vault** model to create a single source of truth.
* **Gold Layer:** The presentation layer for analytics and BI. It is almost always built using **dimensional models** like star schemas, since they're what typically feeds a [semantic layer](/insights/what-is-a-semantic-layer/) and serves end-user queries.
### Is the Inmon vs. Kimball Debate Still Relevant?
The core principles are still relevant, but their implementation must be adapted for the cloud. The classic Inmon approach - a highly normalized, enterprise-wide data warehouse feeding smaller, dependent data marts - was designed for on-premise systems where storage was the primary cost constraint.
Cloud economics are inverted. On platforms like [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/), storage is inexpensive, while compute is the primary cost driver. Executing complex joins across a massive 3NF warehouse is financially inefficient.
The modern interpretation retains Inmon's principle of a governed, central source of truth but updates the implementation. Instead of a strict 3NF core, many architects now use a **Data Vault** or Ralph Kimball's bus architecture as the central hub, which then feeds the dimensional models. This provides the integrated core Inmon advocated for, but in a structure that is optimized for the cloud's cost model.
## Choosing the Model That Fits Your Platform
The right technique depends on the job, not on which one is trendiest. Relational for transactional integrity, dimensional for fast BI queries, Data Vault for auditable integration of many source systems, and on most cloud platforms today, some combination of the three doing different jobs at different layers. If you're evaluating a firm to help implement one of these, the [Data Engineering Companies Index](/data-engineering-consulting-firms/) profiles engineering firms by the platforms and modeling approaches they actually work with, not just by what they claim to do.
---
## A Practical Guide to Data Orchestration Platforms
Source: https://dataengineeringcompanies.com/insights/data-orchestration-platforms/
Published: 2025-12-09T06:49:21.394562+00:00
Description: Discover how modern data orchestration platforms power AI, cloud-native stacks, and real-time workflows. Compare top tools and build a strategy that scales.
A data orchestration platform manages the dependencies, retries, and monitoring for every task in a data pipeline, so a transformation only fires after its source data has loaded and passed validation. The practical choice most teams face is open-source tools you run yourself, such as Airflow, Dagster, and Prefect, versus managed cloud-native services, such as AWS Step Functions and Google Cloud Composer, that trade some control for lower operational overhead.
Orchestration and the transformation layer overlap constantly in practice - 20 of the 86 firms profiled in the [Data Engineering Companies Index](/data-engineering-consulting-firms/) list dbt among their capabilities, and most production Airflow or Dagster deployments end up orchestrating dbt runs somewhere in the DAG.
What this guide covers:
* How orchestration differs from a scheduler, and why that difference matters for reliability.
* Where AI is genuinely changing the orchestration layer, and where the marketing gets ahead of the product.
* How to match a platform to your architecture: event-driven, data mesh, or MLOps.
* What to evaluate before you commit: governance, AI/MLOps fit, and cost.
## What does a data orchestration platform actually do?
A data orchestration platform tracks dependencies between pipeline tasks and only runs a job once its prerequisites are actually met, replacing fixed-time scheduling with logic that reacts to real pipeline state.
Early data workflows relied on time-based tools like cron, which executed scripts on a fixed schedule with no awareness of data availability or the status of upstream jobs. That's similar to an airport dispatching flights on a rigid timetable regardless of weather or runway traffic - it works until it doesn't, and when it fails it tends to fail badly.
Modern data orchestration platforms track dependencies instead of just time. A transformation job only starts after the source data has been ingested and validated, which is what stops one upstream hiccup from cascading into a dozen downstream failures.
### What separates orchestration from scheduling?
An orchestrator gives you one place to see the state of every pipeline, which matters once a data estate has dozens of sources, tools, and destinations feeding into it. The capabilities that distinguish a real orchestrator from a scheduler:
* **Dependency management.** Explicit, graph-based relationships between tasks - a failure in one node pauses or reroutes what depends on it.
* **Automated error handling.** Retry logic, alerting, and failure notifications that cut down on manual firefighting.
* **Observability and lineage.** Logs, monitoring dashboards, and lineage that show where data came from and what happened to it along the way.
* **Event-driven triggers.** The ability to react to a new file landing in cloud storage, not just a fixed clock time.
Fragmented, hard-to-monitor pipelines are a common reason data teams struggle to get consistent value out of otherwise-good data. Turning siloed, manually watched processes into dependency-aware, automated workflows is what makes timely BI reporting and production ML deployment possible in the first place.
### How orchestration platforms compare to traditional schedulers
| Capability | Traditional schedulers (e.g., cron) | Modern data orchestration platforms |
| :--- | :--- | :--- |
| **Triggering** | Time-based (e.g., run at 2 AM) | Event-driven, API calls, time-based, and manual |
| **Dependencies** | None; tasks are independent | Complex, graph-based dependencies (DAGs) |
| **Error handling** | Minimal; script must handle its own errors | Automated retries, alerting, and failure logic |
| **Observability** | Limited to system logs; no central view | Centralized UI, logging, monitoring, and lineage |
| **Scalability** | Limited to a single machine | Distributed architecture for massive scale |
| **Flexibility** | Rigid and difficult to change | Code-as-configuration; dynamic and adaptable |
Moving from a scheduler to an orchestrator is what makes pipelines reliable and auditable instead of a pile of cron jobs someone half-remembers. See [data integration best practices](/insights/data-integration-best-practices/) for the practices that pair with a good orchestration layer.
## How is AI actually changing orchestration platforms?
AI is moving orchestration from alerting a human about a failure to diagnosing and fixing it directly - catching a schema change or data quality anomaly and triggering a correction automatically, instead of waiting on manual intervention.

Vendors including Prefect and [Databricks Workflows](https://www.databricks.com/product/workflows) are building agents directly into the orchestration layer for this purpose. Operational complexity in the underlying data pipelines is one of the reasons AI pilots stall before reaching production, which is exactly the bottleneck AI-infused orchestration targets. The [AI orchestration platform market is projected to grow substantially through 2034](https://market.us/report/ai-orchestration-platform-market/), which tracks with how much enterprise budget is now going toward managing AI workloads rather than just building them.
### From reactive to predictive operations
The real shift happens when a system moves from reacting to failures to anticipating them: analyzing historical run data to scale compute ahead of a known peak, or flagging a likely data quality issue before it reaches downstream tables. Done well, this can meaningfully cut the time engineers spend diagnosing incidents, though the actual gains depend heavily on how mature the existing pipeline observability already is.
That shift changes what data engineering teams spend their time on: less time chasing down why a DAG failed at 3 a.m., more time on the pipelines and models that actually move the business.
### What does a hybrid batch-streaming setup look like in practice?
The practical first step toward more autonomous orchestration is a hybrid trigger model that handles real-time events without abandoning scheduled batch work. For example, a pipeline could:
* **Listen to a Kafka stream** to trigger real-time validation and anomaly detection.
* **Scale resources dynamically** when an unusually large file lands in cloud storage.
* **Retry a failed task with more memory** based on what past failures for that specific task actually looked like.
This hybrid pattern is the foundation most teams will need before taking on more autonomous, agentic orchestration - systems that pick a compute engine for a workload or rewrite a query for performance without a human in the loop. That's a capability most organizations are still a couple of years from needing to architect around.
## Should you choose an open-source or cloud-native orchestrator?
Choosing a data orchestration platform means picking between the control of open-source tools and the lower operational overhead of managed cloud-native services. Neither path is inherently better; the right one depends on your team's skills, your architecture, and how much infrastructure you actually want to own.
### The case for open source
[Apache Airflow](https://airflow.apache.org/) remains the default open-source choice, and it offers real control over how tasks run with no vendor lock-in. A common pattern is running Airflow on Kubernetes through a managed service like [Astronomer](https://www.astronomer.io/) or AWS MWAA, which combines the flexibility of open source with someone else handling the cluster operations.
The Airflow UI's DAGs view gives engineers a single place to monitor recent runs and spot failures immediately, and that kind of centralized visibility is a big part of why Airflow displaced so many bespoke cron setups in the first place.
Open-source tools tend to show up in organizations building data stacks meant to last years, not just survive the next platform migration. An open-source orchestrator running on Kubernetes scales cost-effectively and keeps you out of a single cloud provider's stack, which matters for teams that value architectural independence over convenience.
Running dbt models as tasks inside Airflow DAGs also simplifies governance: declarative, version-controlled transformations make compliance audits across multi-cloud environments far more straightforward than untangling ad hoc scripts. If you're weighing Airflow against [Dagster or Prefect](/insights/airflow-vs-prefect-vs-dagster/) specifically, the differences matter more for asset-centric and event-driven use cases than for straightforward batch ETL.
### The case for cloud-native and serverless
Cloud-native serverless platforms like [AWS Step Functions](https://aws.amazon.com/step-functions/) and [Google Cloud Dataflow](https://cloud.google.com/dataflow) are built into their respective cloud ecosystems and bill on a pay-per-use basis, which suits event-driven orchestration well. Instead of managing clusters, you define the workflow logic and pay for active execution time.
This model tends to make the most financial sense for teams that don't want to own infrastructure operations at all. The [cloud orchestration market is projected to more than triple by 2032](https://www.coherentmarketinsights.com/industry-reports/cloud-orchestration-market), which tracks with how many teams are moving ETL workloads, like S3-to-BigQuery pipelines, onto serverless orchestrators.
Practices that get the most out of cloud-native orchestration:
* **LLM-driven query generation.** Lets pipelines adapt to new analytical requirements without manual code changes for every new query shape.
* **Infrastructure as code.** Partitioning tasks with Terraform builds in resilience against schema evolution and keeps deployments consistent and version-controlled.
* **A clear cost case.** A well-run serverless setup typically pays for itself faster than a comparable self-hosted one, which is the argument that actually gets a migration approved.
The decision between open-source and cloud-native data orchestration platforms comes down to your team's skills, budget, and how much infrastructure ownership you actually want. Open source gives you control and flexibility; cloud-native gives you simplicity and less to operate.
## How do you match orchestration patterns to modern architectures?
Simple, linear pipelines don't hold up against real-time event processing, decentralized data ownership, and production machine learning - the right orchestration pattern depends on which of these three problems you're actually solving.

### Event-driven, real-time orchestration with Dagster's asset model
Moving from nightly batch processing to real-time insight requires a shift from task-centric to asset-centric orchestration. [Dagster](https://dagster.io/) is built around this idea: the model centers on the data assets a pipeline produces, not just the code that generates them.
This asset-centric approach fits low-latency pipelines well, such as Kafka streams landing in Delta tables, because it makes the relationships between data assets visible instead of buried in task logs - a real advantage when debugging complex dependency chains. Teams running Dagster for real-time fintech pipelines report fewer incidents tied to silent schema drift, since failures surface at the asset level instead of downstream.
Handling volatile streams from sources like IoT devices also requires backpressure management and automated lineage tracking, so a burst of incoming data doesn't overwhelm the system. Done well, this cuts down on false alerts and shortens the time it takes to trace an incident back to its source. See [data pipeline architecture examples](/insights/data-pipeline-architecture-examples/) for more on how these patterns fit together.
### Data mesh orchestration with decentralized domains
As organizations scale, a centralized data team inevitably becomes a bottleneck. Data mesh addresses this by distributing data ownership to individual business domains, which requires an orchestration platform that supports federated, self-serve environments rather than one team gatekeeping every pipeline.
[Prefect](https://www.prefect.io/) and [Mage](https://www.mage.ai/) are well-suited to this pattern. They support domain-owned pipelines with federated catalogs, so teams like marketing and finance can manage their own data products while still contributing to a shared ecosystem:
* **Domain-owned pipelines.** Each team is directly accountable for the quality and freshness of its own data products.
* **Federated catalogs.** A shared metadata layer with clear SLAs supports self-serve data discovery across domains.
* **Outcome-based metrics.** Defining data freshness SLAs and similar outcome metrics keeps the architecture adaptable as requirements shift.
This model scales well because it distributes ownership instead of routing every request through one central team, and it lets domains build on their own data products without waiting on a bottleneck upstream.
### A production MLOps orchestration stack
MLOps pipelines chain together experiment tracking, feature versioning, model deployment, and inference monitoring, and the orchestration layer has to manage that entire lifecycle, not just the training run.
A common pattern is sequencing MLflow experiments into [Prefect](https://www.prefect.io/) or [Airflow](https://airflow.apache.org/) flows for an end-to-end path from feature store to inference. That stack typically includes:
1. **MLflow for experiment tracking** - logs parameters, metrics, and model artifacts for reproducibility.
2. **DVC for versioning** - version control for large datasets and models, the equivalent of Git for code.
3. **A feature store** - centralizes feature engineering so training and serving stay consistent.
4. **CI/CD via GitHub Actions** - automates testing and deployment for both pipeline code and models.
A reproducible stack like this is what lets a team move an AI product from prototype to something that actually ships reliably, instead of re-solving the same deployment problems on every release.
### Matching patterns to platforms
| Architecture pattern | Recommended platform(s) | Key enabling feature | What it's good for |
| :--- | :--- | :--- | :--- |
| **Event-driven & asset-centric** | Dagster, Kestra | Declarative, software-defined assets | Real-time systems where fast incident resolution matters |
| **Data mesh & decentralized domains** | Prefect, Mage, Dagster | Multi-tenancy, federated governance, domain isolation | Cross-team collaboration and faster data product delivery |
| **End-to-end MLOps** | Prefect, Airflow, Kubeflow | Strong integrations with MLflow, DVC, and dynamic workflow generation | Reproducible AI/ML workflows and faster model deployment |
| **Streaming-first unified processing** | Flink on Databricks | Unified batch/stream APIs, exactly-once processing | Low-latency event processing at large scale |
There's no single "best" orchestrator here, only the best fit for the architecture you're actually running. Use this table as a starting point, then validate it against your own team's skills and the specific problems you're trying to solve.
## How should you evaluate and select an orchestration platform?
Evaluate an orchestration platform on how it performs under real production load, not on a feature checklist - test governance, AI/MLOps fit, and cost behavior against your own workloads before committing to one.
Choosing an orchestration platform is a multi-year commitment. A tool that looks fine in a demo can fall apart under real load, so evaluate how it performs under stress and whether it scales as your organization's needs change, not just what it can do on day one.
### What should you check for governance and compliance?
Governance has to be built into the orchestration logic itself, not bolted on afterward. Look for these features specifically:
* **Automated PII redaction.** The platform should identify and mask personally identifiable information in transit, supporting compliance with regulations like GDPR.
* **Immutable audit trails.** A clear, unchangeable log of data access, transformations, and user actions is non-negotiable for audits.
* **Metadata versioning.** Enforcing data contracts across pipelines through metadata versioning gives you a defensible architecture as regulations evolve. See [data pipeline monitoring tools](/insights/data-pipeline-monitoring-tools/) for the observability layer that pairs with this.
Platforms that treat compliance as a first-class workflow, rather than a separate audit step tacked on at the end, tend to hold up better as regulatory requirements change.
### How well does the platform support AI and MLOps workflows?
Modern analytics increasingly runs on multi-modal AI pipelines, including retrieval-augmented generation (RAG) workflows that chain together LLMs, vector stores like [Pinecone](https://www.pinecone.io/), and human-in-the-loop validation steps. Your orchestrator needs to manage these multi-step processes as first-class work, not as an afterthought bolted onto a batch-ETL tool.
A platform's ecosystem is a good proxy for how well it will hold up here. Look for solid integrations with CI/CD tools like [GitHub Actions](https://github.com/features/actions), data quality frameworks like [Great Expectations](https://greatexpectations.io/), experiment trackers like [MLflow](https://mlflow.org/), and versioning tools like [DVC](https://dvc.org/) - that combination is what lets teams scale AI from pilot to production without losing track of data provenance.
### How should you think about cost across hybrid architectures?
As more data gets generated at the edge, orchestrating hybrid edge-to-cloud flows becomes a real cost lever, not just a technical nicety. The [market for edge management and orchestration platforms is projected to grow roughly fourfold by 2034](https://www.custommarketinsights.com/press-releases/edge-management-and-orchestration-platforms-market-size/), which reflects how much ingestion work is moving closer to where data is actually generated.
Tools like [Apache NiFi](https://nifi.apache.org/) are a common choice for drag-and-drop scaling at the edge, particularly in manufacturing and IoT contexts. A good orchestrator here offers a modular framework with geo-fencing and auto-failover to meet tight latency SLAs, which matters more each year as data residency requirements get more specific by region.
Use a structured evaluation instead of a vendor demo to compare platforms against your own workloads - test governance, AI/MLOps support, and cost behavior with your own data before signing anything.
## Frequently asked questions
### What's the difference between data orchestration and workflow scheduling?
A scheduler, like cron, is a simple timer that starts a single, isolated task at a specific time. It has no awareness of dependencies or the broader process around it.
A data orchestration platform works more like an air traffic controller managing interconnected flights: it knows Task B can't start until Task A finishes successfully, manages retries and alerts across the whole process, and can be triggered by events like a file arriving in an S3 bucket. Scheduling is one component of orchestration, not a substitute for it.
### Should I choose an open-source tool or a cloud-native service?
There's no universally correct answer here - it depends on your team's expertise, budget, and long-term strategy.
* **Choose open-source tools** like [Airflow](https://airflow.apache.org/) or [Dagster](https://dagster.io/) if you need maximum flexibility and control and want to avoid vendor lock-in. The trade-off is that you own the operational burden of running the infrastructure.
* **Choose cloud-native services** like [AWS Step Functions](https://aws.amazon.com/step-functions/) or [Google Cloud Composer](https://cloud.google.com/composer) if rapid development and minimal infrastructure management matter more than control. These are typically serverless, pay-per-use, and integrate tightly with their parent cloud ecosystem.
Plenty of organizations run both, using open source where they need control and managed services where they don't.
### Can one platform handle both batch and streaming data?
Yes - unifying batch and streaming under one management framework is a defining feature of modern orchestration platforms, and it removes the need for separate, siloed systems for each. See [stream processing vs. batch processing](/insights/stream-processing-vs-batch-processing/) for how the two models differ at the processing layer.
[Dagster](https://dagster.io/) and [Prefect](https://www.prefect.io/) are both built with this hybrid model in mind, using software-defined assets and event-driven triggers to react to real-time events from sources like Kafka with the same mechanics they use for scheduled batch jobs. A genuinely hybrid system lets a pipeline trigger from a message queue, a schedule, an API call, or a manual action, all through one consistent interface.
### How does orchestration work in a data mesh?
Orchestration in a data mesh architecture is decentralized to match the principle of distributed data ownership. Instead of one monolithic orchestrator, responsibility is split across business domains.
In practice, each domain, such as marketing, sales, or finance, runs its own orchestration instance for its own data products. The central platform team's job shifts from running every pipeline to providing standardized tools, templates, and best practices that domain teams build on. Domain teams, as the actual experts on their own data, take responsibility for building and operating their pipelines, which tends to speed up development once the initial setup is done.
---
For the pipeline layer that orchestration sits on top of, see [modern data stack](/insights/modern-data-stack/) for how ingestion, transformation, and BI tooling fit around it, or browse the [Data Engineering Companies Index](/data-pipeline/) for firms that build and run these systems for a living.
---
## 10 Data Pipeline Architecture Examples for Modern Data Stacks
Source: https://dataengineeringcompanies.com/insights/data-pipeline-architecture-examples/
Published: 2025-12-08T06:59:31.584727+00:00
Description: Explore 10 practical data pipeline architecture examples, from batch ELT to Data Mesh. Get insights on Snowflake, Databricks, Kafka, and more for 2026.
TL;DR: Key Takeaways
No "One-Size-Fits-All": Success comes from aligning architecture (Batch vs. Streaming) with specific business latency needs and budget, not chasing trends.
Latency Costs Money: Real-time streaming (Kappa/Lambda) typically runs several times the TCO of batch. Only choose sub-second latency if the business value of immediate action justifies the premium.
ELT is the New Standard: Loading raw data first and transforming it in the warehouse (ELT) offers greater flexibility and speed than rigid legacy ETL pipelines.
Decoupling Wins: For scale, use Microservices or Data Mesh principles to break monolithic pipelines into independent, domain-owned services.
Open Formats Age Better: Data Lake pipelines built on open formats like Iceberg keep unstructured data and AI workloads adaptable without a full rewrite.
A data pipeline architecture is the set of components - ingestion, storage, transformation, and orchestration - arranged to move data from source systems into a form the business can query or act on. Which arrangement fits depends mostly on one question: how fast does this data need to be usable? Batch pipelines that run overnight, streaming systems that react in milliseconds, and several hybrids in between all answer that question differently, at different costs.
The 10 examples below cover the architectures data teams actually run in production: batch processing, stream processing, Lambda, Kappa, ETL, ELT, microservices-based pipelines, data mesh, serverless, and data lake. For the full pattern library plus a directory of the firms that implement them, see the [Data Pipeline Architecture hub](/data-pipeline).
Each section covers when the pattern fits, its typical tech stack, and the trade-off that decides whether it's worth the added cost and complexity.
## 1. Batch Processing Pipeline
Batch processing pipelines collect data over a defined period - hourly, daily, or weekly - and process it in a single, scheduled job rather than handling it in real time. This model optimizes for throughput and cost-efficiency over latency, making it the default choice for reporting, ETL, and workloads like end-of-day financial reporting or nightly ML model retraining that do not require sub-hour data freshness.
A retail company, for instance, uses a batch pipeline to aggregate all daily sales transactions from its stores overnight. This data is then loaded into a data warehouse like Snowflake, where it is transformed using dbt and made available for business intelligence analysts the next morning.
### Strategic Breakdown
* **When to Use:** Ideal for periodic, non-urgent tasks like daily reporting, payroll processing, and large-scale data transformations for analytics. It excels where the cost of real-time infrastructure is unjustified.
* **Core Benefit:** High throughput and exceptional cost-effectiveness. By processing data during off-peak hours (e.g., overnight), it optimizes resource utilization on platforms like Amazon EMR or Databricks, minimizing computational costs.
* **Common Tech Stack:**
* **Orchestration:** Apache Airflow, Prefect, Dagster
* **Processing:** Apache Spark, dbt (for in-warehouse transformation), Amazon EMR
* **Storage/Warehouse:** Amazon S3, Google Cloud Storage, Snowflake, BigQuery
> **Key Insight:** The primary trade-off with batch processing is data freshness. Stakeholders must accept a defined level of data latency in exchange for lower operational costs and simpler system design.
### Actionable Takeaways
* **Implement Idempotency:** Design processing jobs to be idempotent, meaning they can be re-run with the same input to produce the same result. Recovering from failures without corrupting data depends on this.
* **Optimize Batch Windows:** Continuously monitor the duration of batch jobs. If run times extend into business hours, use data partitioning or increase cluster size to parallelize the workload and reduce execution time.
* **Add Checkpointing:** For long-running jobs, implement checkpointing. This allows the job to resume from its last successful state after a failure, saving significant time and compute resources.
## 2. Stream Processing Pipeline
Stream processing pipelines process data continuously as it arrives, with millisecond-to-second latency, instead of waiting on a scheduled batch. Data flows as unbounded streams, enabling immediate transformations, aggregations, and responses - the backbone of event-driven systems like fraud detection, IoT monitoring, and real-time personalization, where the value of data decays fast and immediate action matters.
For example, a financial institution uses a streaming pipeline for fraud detection. As each credit card transaction occurs, the event is published to an Apache Kafka topic. A streaming application built with Apache Flink immediately consumes this data, enriches it with historical user behavior, and runs it through a fraud model to block suspicious transactions in real time. This model prioritizes low latency and immediate action over high-throughput batch analysis.
### Strategic Breakdown
* **When to Use:** Essential for time-sensitive applications like real-time fraud detection, IoT sensor data monitoring, dynamic pricing engines, and live application performance monitoring. It excels where the value of data decays rapidly with time.
* **Core Benefit:** Minimal latency. It enables organizations to react to events as they happen, creating immediate operational value and responsive user experiences.
* **Common Tech Stack:**
* **Messaging/Ingestion:** Apache Kafka, AWS Kinesis, Google Cloud Pub/Sub
* **Processing:** Apache Flink, Apache Spark Streaming, ksqlDB
* **Storage/Analytics:** Druid, ClickHouse, Rockset
> **Key Insight:** The main challenge in stream processing is managing state and ensuring correctness under failure conditions. Handling out-of-order events and maintaining exactly-once processing semantics requires a more complex, carefully tested system design compared to batch pipelines.
### Actionable Takeaways
* **Implement Backpressure Mechanisms:** Your pipeline must handle traffic spikes without crashing. Streaming frameworks like Flink and Spark Streaming have built-in backpressure protocols that automatically slow down data ingestion when downstream operators are overwhelmed.
* **Choose Appropriate Windowing Strategies:** Analyze data over specific time intervals using windowing techniques. Use **tumbling windows** for fixed, non-overlapping periods (e.g., minute-by-minute counts), **sliding windows** for overlapping periods (e.g., a 30-second average updated every 5 seconds), and **session windows** to group user activity.
* **Design for Statelessness Where Possible:** Whenever feasible, design processing logic to be stateless. Stateless transformations are simpler to scale and recover from failures. For stateful operations like aggregations, use the managed state capabilities of your chosen streaming framework to ensure fault tolerance.
## 3. Lambda Architecture
The Lambda Architecture is a hybrid pattern designed to deliver both low-latency, real-time insights and comprehensive, accurate historical analysis. It achieves this by running parallel batch and streaming data pipelines. This dual-path approach addresses the inherent trade-offs between speed and accuracy, making it a powerful model for complex systems that cannot sacrifice either dimension.
For instance, a social media platform might use a Lambda Architecture to rank content. A "speed layer" provides immediate, approximate rankings based on recent user interactions, while a "batch layer" recalculates comprehensive, long-term relevance scores overnight using all historical data. A serving layer then merges these two views to present the most up-to-date and accurate content ranking to users.
### Strategic Breakdown
* **When to Use:** Ideal for systems requiring both real-time updates and deep, accurate analytics, such as fraud detection, recommendation engines, and dynamic ad targeting. It's best suited for complex use cases where data mutability and reprocessing are critical requirements.
* **Core Benefit:** Fault tolerance and data integrity. The immutable, append-only batch layer serves as the ultimate source of truth, allowing the entire dataset to be recomputed to fix errors or update logic. The speed layer provides low-latency data, which can be discarded and corrected by the next batch run.
* **Common Tech Stack:**
* **Data Ingestion:** Apache Kafka, Amazon Kinesis
* **Speed Layer:** Apache Flink, Spark Streaming, ksqlDB
* **Batch Layer:** Apache Spark, Amazon EMR, Databricks
* **Serving Layer:** Druid, Pinot, Cassandra, or custom data marts in Snowflake/BigQuery
> **Key Insight:** The main challenge of the Lambda Architecture is operational complexity. Maintaining two separate codebases for the batch and speed layers can lead to significant engineering overhead and potential for logic drift between the two paths.
### Actionable Takeaways
* **Unify Batch and Speed Logic:** Use frameworks that allow code reuse between batch and stream processing, such as Apache Beam or Spark Structured Streaming APIs. This minimizes the risk of the two layers producing inconsistent results.
* **Implement a Consistent Serving Layer:** Your serving layer must efficiently merge views from the batch and speed layers. Design it to handle potential data overlaps and resolve conflicts, ensuring a consistent and coherent view is presented to end-users.
* **Consider the Kappa Architecture:** For use cases where reprocessing the entire dataset is feasible with a streaming engine, evaluate the Kappa Architecture. This simpler pattern eliminates the batch layer, using a single stream processing engine for both real-time and historical computation.
## 4. Kappa Architecture
The Kappa Architecture simplifies the Lambda Architecture by unifying all data processing into a single stream-based path. Instead of maintaining separate batch and real-time layers, it treats all data as an ordered, immutable log of events. The core idea is that the entire history of data can be reprocessed from this log to generate new views or correct errors, eliminating the need for a separate batch layer.
For example, a fintech company uses this pattern to process its massive stream of payment events. If a new fraud detection model is developed, it can be deployed against the live stream for new transactions and also replayed against the historical event log to re-evaluate past transactions. This ensures consistency and simplifies system maintenance by removing redundant codebases.
### Strategic Breakdown
* **When to Use:** Best suited for systems where real-time analytics matter most and business logic evolves frequently. It excels in use cases like real-time fraud detection, IoT sensor monitoring, and live user activity tracking where the ability to reprocess historical data with new logic is a key requirement.
* **Core Benefit:** Radical simplification and operational consistency. By removing the batch layer, it eliminates the complexity and potential for divergence between two separate codebases, making the system easier to manage, debug, and evolve.
* **Common Tech Stack:**
* **Event Log/Message Queue:** Apache Kafka, Azure Event Hubs, Google Cloud Pub/Sub
* **Stream Processing:** Apache Flink, ksqlDB, Spark Structured Streaming
* **Serving Layer/Storage:** Druid, Elasticsearch, a key-value store like Redis, or a materialized view in a data warehouse like Snowflake.
> **Key Insight:** The entire architecture hinges on the reliability and immutability of the unified event log. The ability to retain and efficiently replay large volumes of historical events is the central trade-off for eliminating the complexity of a separate batch processing layer.
### Actionable Takeaways
* **Design for Immutability:** Treat your event log as an immutable, append-only source of truth. This principle is non-negotiable and underpins the architecture's ability to reliably reconstruct state.
* **Version Schema and Logic Explicitly:** As your processing logic evolves, you must version it explicitly. This allows you to know exactly which logic was applied to which events during replay, ensuring deterministic and repeatable outcomes.
* **Monitor Log Retention and Compaction:** Carefully manage the retention policies of your event log (e.g., Kafka). For stateful applications, use log compaction to retain the latest value for each key indefinitely, preventing the log from growing to an unmanageable size while preserving the necessary state.
## 5. ETL (Extract-Transform-Load) Pipeline
The ETL pipeline is a classic, highly structured architecture. It involves extracting raw data from sources, transforming it in a specialized processing server to meet business and quality standards, and loading the structured, cleansed data into a target data warehouse. This pattern is foundational for traditional business intelligence, prioritizing data integrity and consistency before it reaches the end-user.
For example, a healthcare provider might use an ETL pipeline to pull patient records from multiple clinic EMR systems, billing software, and lab databases. The transformation stage would involve standardizing patient IDs, anonymizing sensitive information to comply with HIPAA, and structuring the data into a star schema. This prepared data is then loaded into an enterprise data warehouse like Teradata for regulatory reporting and clinical analysis.
### Strategic Breakdown
* **When to Use:** Suited for scenarios requiring complex data transformations, rigorous data cleansing, and strict schema enforcement before data is made available for analysis. It is common in legacy enterprise environments and industries with heavy compliance requirements like finance and healthcare.
* **Core Benefit:** High data quality and reliability. By transforming data before loading, ETL ensures that the target system contains only clean, consistent, and analysis-ready data. This simplifies downstream analytics and BI processes.
* **Common Tech Stack:**
* **Orchestration:** IBM InfoSphere DataStage, Informatica PowerCenter, Talend
* **Processing:** Proprietary ETL tools, Apache Spark, custom scripts
* **Storage/Warehouse:** Teradata, Oracle Exadata, Microsoft SQL Server
> **Key Insight:** ETL's primary trade-off is inflexibility. The predefined schemas and transformations mean that new analytical requirements often necessitate a lengthy redesign of the ETL jobs by a specialized data engineering team.
### Actionable Takeaways
* **Implement Modular Transformation Logic:** Design your transformation steps as independent, reusable modules. This allows for easier testing, maintenance, and modification of specific business rules without overhauling the entire pipeline.
* **Prioritize Comprehensive Data Validation:** Perform data validation checks immediately after extraction to catch source system errors early. This prevents "garbage in, garbage out" scenarios and reduces complex error handling during the transformation stage.
* **Document Transformation Rules Meticulously:** Every business rule, data cleansing step, and calculation must be thoroughly documented. This is critical for data governance, auditing, and onboarding new team members who need to understand how raw data becomes finished analytical output.
## 6. ELT (Extract-Load-Transform) Pipeline
ELT pipelines invert the traditional ETL model: raw data loads directly into a cloud data warehouse or lakehouse first, then gets transformed there using the platform's own compute engine. This is the dominant modern pattern for analytics because it decouples ingestion from transformation, making raw data immediately available while enabling flexible, SQL-based modeling via tools like dbt.
For example, a marketing tech company can use Fivetran to extract raw advertising data from platforms like Google Ads and Facebook Ads and load it directly into Snowflake. Once the data lands, dbt (data build tool) runs SQL-based transformations that clean, model, and aggregate the data into analytics-ready tables for performance dashboards. This gets data in front of analysts faster than waiting on a separate transformation stage.
### Strategic Breakdown
* **When to Use:** Ideal for organizations using cloud-native data warehouses like Snowflake, BigQuery, or Redshift. It is perfectly suited for analytics and BI use cases where data scientists and analysts benefit from having access to both raw and transformed data.
* **Core Benefit:** Flexibility and speed to insight. By decoupling the extract/load from the transform step, data is available for use much faster. It also democratizes data transformation, allowing analysts who are proficient in SQL to build and maintain their own data models.
* **Common Tech Stack:**
* **Orchestration:** Apache Airflow, Dagster, Prefect
* **Extraction/Loading:** Fivetran, Stitch, Airbyte
* **Warehouse/Processing:** Snowflake, Google BigQuery, Amazon Redshift, Azure Synapse
* **Transformation:** dbt (data build tool), Coalesce
> **Key Insight:** ELT shifts the processing burden from a separate transformation engine to the data warehouse itself. This uses the elastic compute power of the cloud but requires careful monitoring of warehouse costs to avoid unexpected expenses.
### Actionable Takeaways
* **Govern Raw Data:** Since raw, untransformed data is stored in the warehouse, establish strong data governance policies. Use separate schemas or databases to clearly distinguish between raw, staging, and production-ready data layers to prevent misuse.
* **Embrace Incremental Models:** Design your dbt transformations using incremental models. This ensures that you only process new or changed data on each run, which dramatically reduces warehouse compute costs and improves pipeline performance.
* **Implement Post-Load Validation:** Use data quality tools like Great Expectations or dbt's built-in testing capabilities to validate data *after* it has been loaded and transformed. This ensures data integrity and builds trust among stakeholders.
## 7. Microservices-Based Data Pipeline
The microservices-based data pipeline applies principles of service-oriented architecture to data processing. Instead of a monolithic script, the pipeline is decomposed into a collection of small, independent, and loosely-coupled services. Each service handles a single task, such as data ingestion, validation, enrichment, or loading, and communicates with others through APIs or message queues.
This modular approach is used by companies like Netflix and Spotify to manage their complex data ecosystems. For instance, an event-driven pipeline might use one microservice to ingest user clickstream data into Kafka, another to validate its schema, a third to enrich it with user profile information, and a final one to load the processed data into a real-time analytics database. This pattern offers real flexibility and independent scalability for each pipeline stage.
### Strategic Breakdown
* **When to Use:** Best for large organizations with multiple data teams, real-time processing requirements, and a need for technological diversity. It shines in event-driven systems where different parts of the pipeline have varied scaling needs.
* **Core Benefit:** Extreme agility and resilience. Teams can develop, deploy, and scale their services independently, using the best technology for each specific job (e.g., Python for an ML model service, Go for a high-concurrency ingestion service). This also isolates failures, preventing one faulty component from bringing down the entire pipeline.
* **Common Tech Stack:**
* **Orchestration/Communication:** Apache Kafka, RabbitMQ, AWS SQS/SNS, Kubernetes
* **Processing/Frameworks:** AWS Lambda, Google Cloud Functions, Spring Boot (Java), FastAPI (Python)
* **Storage/Warehouse:** Varies by service; could include Cassandra, Redis, Snowflake, BigQuery
> **Key Insight:** The primary trade-off is operational complexity. A microservices architecture introduces significant challenges in deployment, monitoring, and distributed data management that require mature DevOps and platform engineering practices.
### Actionable Takeaways
* **Standardize API Contracts:** Implement strong, versioned API contracts (e.g., using OpenAPI or gRPC/Protobuf) to ensure stable communication between services. Clear contracts prevent downstream breakages when one service is updated.
* **Use Asynchronous Communication:** Rely on message brokers like Kafka or RabbitMQ for inter-service communication. This decouples services, improves fault tolerance by buffering data, and allows consumers to process messages at their own pace.
* **Implement Distributed Tracing:** In a distributed system, tracking a single data record's journey is difficult. Use tools like Jaeger or DataDog to implement distributed tracing, which provides essential visibility for debugging and performance optimization across service boundaries.
## 8. Data Mesh Architecture
The data mesh architecture is a cultural and organizational paradigm that moves away from centralized, monolithic data platforms to a decentralized, domain-oriented model. Instead of a single team managing all data pipelines, this model treats data as a product, with individual business domains taking ownership of their data from ingestion to consumption. Each domain team is responsible for building, maintaining, and serving its data pipelines and datasets through well-defined, standardized interfaces.
This approach, popularized by Zhamak Dehghani, contrasts sharply with traditional architectures by promoting federated governance and a self-service data platform. For instance, a retail company's "Marketing" domain would own its customer campaign data, while the "Logistics" domain would own its supply chain data, with each making their data products discoverable and accessible. This reduces bottlenecks on a central data team and aligns data ownership with business expertise.

### Strategic Breakdown
* **When to Use:** Best suited for large organizations with multiple business domains where a centralized data team becomes a bottleneck. It thrives in environments aiming to increase data agility, accountability, and scalability across autonomous teams.
* **Core Benefit:** Enhanced scalability and business agility. By decentralizing data ownership, data mesh lets domain experts build data products that directly address their needs, accelerating time-to-value.
* **Common Tech Stack:**
* **Orchestration:** Often domain-specific (e.g., Airflow for one, Dagster for another) but governed by central principles.
* **Processing:** Databricks, Snowflake, dbt, Spark (selected by domain teams).
* **Self-Service Platform:** Often built on cloud primitives (AWS/GCP/Azure), with tools like DataHub or Amundsen for discovery.
> **Key Insight:** Data mesh is fundamentally a socio-technical paradigm. The primary challenge is not the technology but the organizational change required to shift from a centralized mindset to distributed ownership and federated governance.
### Actionable Takeaways
* **Start with a Pilot Program:** Begin your data mesh journey with two or three willing and capable business domains. Use this pilot to establish patterns, test governance frameworks, and demonstrate value before a broader rollout.
* **Define Clear Data Contracts:** Implement "data contracts" as formal agreements between data producers and consumers. These contracts should define schema, service-level objectives (SLOs), and quality metrics to ensure reliable, high-quality data products.
* **Invest in a Self-Service Platform:** A core tenet of data mesh is abstracting complexity. Build or invest in a central data platform that provides self-service tools for infrastructure provisioning, data discovery, and security, enabling domain teams to focus on creating value. A well-defined [data governance framework is essential](https://dataengineeringcompanies.com/insights/data-governance-framework-template/) to making this self-service model successful and secure.
## 9. Serverless Data Pipeline
The serverless data pipeline is a cloud-native architecture that eliminates direct infrastructure management. Instead of provisioning and managing servers, this model uses fully managed services that automatically scale and execute code in response to events. This pay-per-execution approach is ideal for lightweight, event-driven data processing tasks.
For example, a media company could use an AWS Lambda function that triggers whenever a new image is uploaded to an S3 bucket. The function automatically resizes the image, adds a watermark, and stores the processed versions back in S3. This entire workflow operates without any dedicated servers, scaling from a few uploads to thousands per minute without manual intervention.
### Strategic Breakdown
* **When to Use:** Perfect for event-driven tasks like real-time data enrichment, simple ETL/ELT transformations, and reacting to changes in data streams or object storage. It excels in scenarios with unpredictable or bursty workloads where maintaining idle compute resources is not cost-effective.
* **Core Benefit:** Substantial reduction in operational overhead and TCO. Since the cloud provider manages the underlying infrastructure, teams can focus entirely on writing business logic. The pay-per-use model ensures you only pay for the compute time you consume.
* **Common Tech Stack:**
* **Compute:** AWS Lambda, Google Cloud Functions, Azure Functions
* **Orchestration/Triggers:** Amazon EventBridge, Google Cloud Pub/Sub, Azure Event Grid
* **Storage/State:** Amazon S3, DynamoDB, Google Cloud Storage, Firestore
> **Key Insight:** The main trade-off is the constraint on execution duration and resources. Serverless functions are designed for short-lived, stateless tasks, making them unsuitable for long-running, computationally intensive jobs that are better handled by platforms like Spark.
### Actionable Takeaways
* **Design for Idempotency:** Ensure your functions can be safely retried without creating duplicate data or side effects. Event-driven systems can sometimes deliver the same event more than once, and idempotency is key to building a resilient pipeline.
* **Minimize Cold Starts:** A "cold start" is the initial latency experienced when a function is invoked for the first time. To reduce this impact on performance-sensitive applications, use features like AWS Lambda's Provisioned Concurrency to keep a set number of functions warm.
* **Keep Functions Small and Focused:** Adhere to the single responsibility principle. Each function should do one thing well, such as validating a record or enriching a single field. This improves modularity, makes testing easier, and simplifies debugging.
## 10. Data Lake Pipeline Architecture
The data lake pipeline is an architecture designed for ingesting vast quantities of raw data in its original format. Unlike traditional warehouses that require upfront data modeling (schema-on-write), this pattern loads structured, semi-structured, and unstructured data directly into a scalable storage layer like Amazon S3. This "schema-on-read" approach provides maximum flexibility, allowing data scientists to apply structure later based on specific use cases.
A healthcare organization, for example, might use a data lake pipeline to ingest everything from structured EMR records and semi-structured HL7 messages to unstructured physician notes and DICOM imaging files. This raw data is stored centrally, enabling diverse future applications like predictive diagnostics or operational efficiency analysis without having to re-ingest data for each new project. This model trades upfront schema design for flexibility later, prioritizing comprehensive data collection over immediate structure.

### Strategic Breakdown
* **When to Use:** Essential for organizations dealing with high data variety and volume, especially when future use cases are not fully defined. It is the go-to architecture for large-scale AI/ML model training, exploratory data science, and log analytics.
* **Core Benefit:** Unmatched flexibility and scalability. By decoupling storage from compute and retaining raw data, it supports a wide array of current and future analytics workloads without being constrained by a predefined schema.
* **Common Tech Stack:**
* **Orchestration:** Apache Airflow, Dagster, AWS Step Functions
* **Processing:** Apache Spark, Databricks, Amazon EMR
* **Storage & Table Formats:** Amazon S3, Azure Data Lake Storage (ADLS), Google Cloud Storage; with Delta Lake, Apache Iceberg, or Hudi for reliability.
* **Cataloging:** AWS Glue Data Catalog, Collibra, Alation
> **Key Insight:** Without strong governance, a data lake can quickly devolve into a "data swamp" - a repository of poorly documented, low-quality, and unusable data. The success of this architecture hinges on metadata management, cataloging, and data quality frameworks being in place from day one.
### Actionable Takeaways
* **Implement a Medallion Architecture:** Structure your data lake into distinct zones (e.g., Bronze for raw data, Silver for cleansed/validated data, and Gold for business-level aggregates). This layered approach provides a clear path from raw ingestion to analysis-ready data.
* **Prioritize a Data Catalog:** Deploy a data catalog tool early to automatically capture metadata, track lineage, and make data discoverable. This is non-negotiable for enabling self-service analytics and maintaining order as the lake grows.
* **Use Open Table Formats:** Build your data lake on open table formats like Apache Iceberg or Delta Lake. They bring critical database-like features such as ACID transactions, time travel, and schema evolution directly to your files in cloud storage, dramatically improving data reliability.
## Which data pipeline architecture fits which use case?
Batch ELT handles most reporting and analytics workloads at the lowest cost and complexity. Streaming and its hybrids (Lambda, Kappa) cost more and add operational overhead but deliver sub-second data. The table below maps each architecture to its complexity, resource footprint, and ideal use case.
| Architecture | Implementation complexity | Resource requirements | Expected outcomes | Ideal use cases | Key advantages |
|---|---:|---|---|---|---|
| Batch Processing Pipeline | Low-Medium - mature, simpler ops | Scheduled high compute, storage, ETL tooling | High throughput, high latency, strong transactional consistency | Nightly reports, bulk ETL, model retraining | Cost-effective, easy monitoring and recovery |
| Stream Processing Pipeline | High - real-time stateful systems | Continuous compute, brokers (Kafka), low-latency infra | Low latency, continuous throughput, near-real-time insights | Fraud detection, monitoring, real-time personalization | Immediate responses, efficient continuous processing |
| Lambda Architecture | Very High - dual-layer coordination | Batch + stream infra, storage, serving layers | Combines accurate batch results with low-latency views, eventual consistency | Use cases needing both accuracy and speed | Balances batch accuracy with streaming speed |
| Kappa Architecture | High - simpler than Lambda but stateful | Reliable event log (Kafka), stream processors, replay storage | Low latency, replayable event processing, state versioning | Event sourcing, real-time analytics with replay | Single code path, easier maintenance than Lambda |
| ETL (Extract-Transform-Load) Pipeline | Medium - well-understood pattern | ETL tools, scheduled compute, data warehouse | High data quality, batch latency, structured outputs | Traditional data warehousing, BI, governed reporting | Strong governance, lineage, and data quality controls |
| ELT (Extract-Load-Transform) Pipeline | Medium - relies on warehouse capabilities | Cloud warehouse compute (Snowflake/BigQuery), storage, SQL expertise | Fast ingestion, flexible schema-on-read, scalable transforms | Modern analytics stacks, big-data transformations | Uses warehouse compute, more flexible schema |
| Microservices-Based Data Pipeline | High - distributed systems complexity | Container orchestration, messaging, observability, infra per service | Modular, independently scalable components; variable latency | Complex, decoupled processing, multi-team organizations | Independent deploys, fault isolation, tech diversity |
| Data Mesh Architecture | Very High - organizational and technical change | Self-service platforms, governance tooling, cross-domain teams | Domain-aligned data products, decentralized ownership, varied consistency | Large enterprises seeking domain autonomy and scale | Domain ownership, faster domain-level insights, reduced central bottlenecks |
| Serverless Data Pipeline | Low-Medium - simpler infra, constrained runtimes | Cloud functions, managed services, pay-per-execution | Event-driven, auto-scaling, suitable for short-lived tasks | Sporadic workloads, lightweight ETL, event-driven transforms | No infra management, cost-effective for variable loads |
| Data Lake Pipeline Architecture | Medium-High - governance required to avoid sprawl | Large object storage (S3), metadata/catalog, compute for transforms | Scalable raw-data ingestion, flexible analytics, risk of data swamp | Data discovery, ML feature stores, storing diverse formats | Flexible schema-on-read, cost-effective storage at scale |
## How much do complexity, cost, and latency vary across these architectures?
Complexity and cost climb as latency drops. Batch ELT runs on the cheapest infrastructure at the highest latency; Lambda and Data Mesh carry the highest relative TCO and implementation complexity. The table below breaks down all 10 architectures on these three axes.
| Architecture | Complexity | Relative TCO | Data Latency | Best First Choice For |
|---|---|---|---|---|
| Batch ELT | Low | $ | Hours-Days | Analytics, reporting, ML retraining |
| Stream Processing | High | $$$ | Milliseconds | Fraud detection, IoT, real-time dashboards |
| Lambda Architecture | Very High | $$$$ | Seconds + batch | Recommendation engines, dual-latency needs |
| Kappa Architecture | High | $$$ | Seconds | Event-driven ML, fintech audit trails |
| ETL (legacy) | Medium | $$ | Hours | Compliance-heavy, legacy warehouse systems |
| ELT (modern) | Low-Medium | $$ | Minutes-Hours | Cloud-native analytics stacks (dbt + Snowflake/BigQuery) |
| Microservices Pipeline | High | $$$ | Variable | Multi-team orgs, independently scalable stages |
| Data Mesh | Very High | $$$$ | Variable | Enterprise scale, domain ownership model |
| Serverless Pipeline | Low-Medium | $ | Event-driven | Sporadic workloads, lightweight transforms |
| Data Lake Pipeline | Medium-High | $$ | Hours | ML feature stores, raw data archival |
*Cost tiers are relative, not absolute - actual spend depends on data volume, cloud provider, and team size. Streaming and its hybrids need always-on compute and low-latency brokers, which is why they land in the $$$-$$$$ range even at modest data volumes. That cost gap shows up in how firms staff for it: of the 86 vetted firms in our [directory](/data-pipeline), only 15 list Kafka or streaming-specific expertise versus 66 that list Snowflake, roughly one streaming specialist for every four warehouse-first shops - which tracks with batch/ELT being the default production pattern and streaming staying reserved for genuinely latency-sensitive work.*
## How do you decide which data pipeline architecture to build?
Match the architecture to how fast the business needs to act on the data, not to what's trending. Batch ELT is the default for reporting and ML retraining; reach for streaming, Lambda, or Kappa only when the cost of stale data outweighs the cost of always-on infrastructure.
These 10 patterns span traditional batch ETL to the decentralized Data Mesh model, and there is no single "best" one. An ELT pipeline powered by Snowflake and dbt might be perfect for a lean analytics team, while a Kafka-centric Kappa architecture is what a fintech company needs for real-time fraud detection. Treat these as flexible starting points, not rigid prescriptions - most production systems end up as a hybrid, borrowing pieces from several of these examples.
### Synthesizing the Core Takeaways
Several cross-cutting themes emerge from these architectures. These principles should guide your decision-making, ensuring the pipeline you build today is resilient and scalable.
* **Latency is a Business Decision, Not Just Technical:** The cost and complexity delta between a 24-hour batch refresh (Batch ELT) and a sub-second streaming update (Kappa Architecture) is immense. Engage business stakeholders to quantify the value of speed. Ask: "What revenue is gained, or what cost is saved, by having this data available in a minute versus a day?" This conversation dictates investment in complex tools like Flink or sticking with cost-effective orchestrators like Airflow.
* **The "T" in ETL vs. ELT Defines Your Cost Model:** The choice between transforming data before loading (ETL) or after (ELT) has profound financial implications. ELT pushes transformation costs to your cloud data warehouse's compute engine (e.g., Snowflake, BigQuery). This offers flexibility but can lead to unpredictable costs if not governed properly. Traditional ETL contains costs within dedicated transformation tools but can create bottlenecks.
* **Decoupling is Your Scalability Insurance Policy:** Architectures like Microservices and Data Mesh champion decoupling. By breaking monolithic pipelines into smaller, independent services, you gain resilience and scalability. If your ingestion component fails, it doesn't bring down your entire analytics reporting system. This modularity is critical for complex environments.
> **Strategic Insight:** Treat your data pipeline as a product, not a project. This mindset shifts the focus from a one-time build to continuous improvement, monitoring, and alignment with evolving business needs. Your architecture must be designed for iteration.
### Your Actionable Path Forward
Translating architectural theory into a functional system requires a disciplined approach. Ground your strategy in an assessment of your current state and future goals.
1. **Audit Your Use Cases, Not Your Tools:** Begin by mapping critical business processes to their data requirements. Categorize each by latency (batch, near real-time, real-time), volume, and transformation complexity. This use-case inventory is your most valuable tool for selecting the right architectural pattern.
2. **Conduct a Skills and Resources Gap Analysis:** Be brutally honest about your team's expertise. Do you have deep Kafka and Kubernetes experience for a streaming architecture, or is your team's strength in SQL and Python, making a dbt-centric ELT model more pragmatic? The most elegant architecture is useless if your team cannot effectively maintain and troubleshoot it.
3. **Prototype with a Bounded Scope:** Select one high-value, low-risk use case from your audit. Build a proof-of-concept (POC) using your chosen architecture. This exercise will uncover hidden complexities, validate your cost assumptions, and provide a tangible demonstration of value to stakeholders.
A pipeline built on the wrong pattern shows up later as ballooning warehouse bills, stale dashboards, or an on-call rotation nobody wants. Get the architecture right once, and the tool choices underneath it - Airflow vs. Dagster, Snowflake vs. Databricks - become much easier decisions.
---
**DataEngineeringCompanies.com** maintains a directory of 86 vetted data engineering firms if you need outside help implementing one of these patterns. Before you build, stress-test the pattern against your latency requirements using our [data pipeline testing best practices](/insights/data-pipeline-testing-best-practices); once it's running, [pipeline monitoring tools](/insights/data-pipeline-monitoring-tools) catch failures before they reach a dashboard. If cost is the open question, our [cost estimation guide](/insights/data-pipeline-cost-estimation-guide) breaks down TCO by architecture and cloud platform.
---
## Data Pipeline Cost Estimation Guide 2026
Source: https://dataengineeringcompanies.com/insights/data-pipeline-cost-estimation-guide/
Published: 2026-02-22T08:00:00.000Z
Description: How much does a data pipeline cost to build and run? Complete breakdown by pipeline type, cloud platform, team model, and project scope - with rate benchmarks from 86 verified data engineering firms.
A simple single-source pipeline runs $15,000-$50,000 to build; a full legacy-to-cloud migration runs $100,000-$500,000+. **Estimating a pipeline's true cost means pricing two separate categories - implementation (what you pay a firm or team to build it) and infrastructure (what you pay cloud providers to run it) - and sizing both before the project starts.**
This guide breaks down the five cost drivers, benchmarks by pipeline type, cloud infrastructure costs by platform, and implementation cost by project scope, based on DataEngineeringCompanies.com's analysis of 86 verified data engineering firms.
## What Drives Data Pipeline Cost?
Five variables set pipeline cost: data volume, latency requirement, source/destination complexity, team model, and compliance requirements. Volume and latency mainly drive infrastructure spend; team model and compliance mainly drive implementation spend. Streaming and multi-source projects cost the most because they compound several drivers at once.
**1. Data volume.** Pipelines processing 1GB/day have fundamentally different infrastructure requirements than pipelines processing 1TB/day. Volume affects compute, storage, and egress costs linearly - and sometimes super-linearly for streaming systems.
**2. Latency requirement.** Batch pipelines (hourly or daily) are the cheapest architecture. Streaming pipelines (sub-second to seconds) cost 3-5x more for equivalent volume because they require always-on compute clusters (Kafka brokers, Flink job managers) rather than on-demand execution.
**3. Source and destination complexity.** A pipeline connecting one Postgres database to one Snowflake table costs far less than one integrating 15 source systems (SaaS APIs, event streams, databases, files) into a normalized warehouse. Each source adds ingestion logic, schema mapping, error handling, and monitoring overhead.
**4. Team model.** Pure US-based teams bill $120-$300/hr. Blended onshore/offshore teams bill $80-$160/hr. Offshore-primary teams bill $50-$120/hr. The same pipeline scope can cost 2-3x more depending on team composition.
**5. Compliance requirements.** Healthcare (HIPAA), financial services (SOC 2, GDPR), and government projects add 20-40% to implementation cost due to encryption requirements, audit logging, access control, and documentation overhead.
## How Much Does Each Type of Data Pipeline Cost?
Simple batch ELT pipelines run $15,000-$50,000 to build and $200-$1,000/month to run. Streaming pipelines cost the most: $75,000-$250,000 to build and $2,000-$15,000/month to operate, because they need always-on compute rather than on-demand execution.
| Pipeline Type | Infrastructure Cost/Month | Typical Implementation Cost | Timeline |
|---------------|--------------------------|----------------------------|----------|
| **Simple batch ELT** (1 source → warehouse, daily) | $200-$1,000 | $15,000-$50,000 | 2-6 weeks |
| **Multi-source batch ELT** (5-15 sources, hourly) | $500-$3,000 | $40,000-$150,000 | 6-16 weeks |
| **Streaming pipeline** (Kafka + Flink/Spark) | $2,000-$15,000 | $75,000-$250,000 | 8-20 weeks |
| **Serverless pipeline** (AWS Glue / ADF / Dataflow) | $500-$5,000 | $30,000-$120,000 | 4-12 weeks |
| **Data platform migration** (legacy → cloud warehouse) | $1,000-$5,000 | $100,000-$500,000+ | 12-26 weeks |
| **Data mesh implementation** (5+ domains) | $5,000-$25,000 | $200,000-$1,000,000+ | 6-18 months |
Infrastructure costs assume moderate volume (50-500GB/day). Streaming costs include managed Kafka (Confluent Cloud or MSK).
## What Does Cloud Infrastructure Cost by Platform?
Monthly infrastructure cost for a mid-size pipeline (100GB/day) ranges from about $180 on AWS Glue to $5,000 on Confluent Cloud for a streaming setup. Snowflake and Databricks fall in between; cost is driven more by cluster sizing and query complexity than by raw data volume.
### Snowflake ELT Pipeline (Batch)
For a mid-size organization processing 100GB/day:
| Component | Cost/Month |
|-----------|-----------|
| Compute (2 XS warehouses, 8hr/day) | $400-$800 |
| Storage (3TB) | $70-$120 |
| Data transfer (egress) | $50-$150 |
| **Total** | **$520-$1,070/mo** |
Snowflake's compute costs scale with query complexity and concurrency, not just volume. Proper clustering keys and materialized views can reduce compute 30-60%.
### Databricks Spark Pipeline (Batch + Some Streaming)
| Component | Cost/Month |
|-----------|-----------|
| DBUs (job clusters, 4hr/day avg) | $800-$2,000 |
| Cloud VM instances (pass-through) | $300-$800 |
| Storage (Delta Lake) | $100-$200 |
| **Total** | **$1,200-$3,000/mo** |
Databricks costs are highly variable based on cluster sizing. Over-provisioned clusters are the #1 source of surprise Databricks bills - right-sizing and spot instances typically cut costs 40-60%.
### Kafka Streaming Pipeline (Confluent Cloud)
| Component | Cost/Month |
|-----------|-----------|
| Kafka brokers (3-node, 3TB storage) | $1,500-$3,000 |
| Flink processing (2 CUs continuous) | $800-$1,500 |
| Schema Registry + connectors | $200-$500 |
| **Total** | **$2,500-$5,000/mo** |
Streaming infrastructure costs are largely fixed - you pay for always-on brokers and processing capacity regardless of actual throughput. This is why batch pipelines have a strong cost advantage at low-to-medium throughput.
### AWS Glue (Serverless Batch)
| Component | Cost/Month |
|-----------|-----------|
| Glue jobs (100 DPU-hours/month) | $44 |
| Glue crawlers | $10-$30 |
| S3 storage (5TB) | $115 |
| **Total** | **$170-$190/mo** |
AWS Glue is extremely cost-effective for sporadic or variable workloads. At consistent high-volume processing, EMR clusters become cheaper.
## How Much Does Implementation Cost by Project Scope?
Implementation cost scales with scope: $15,000-$50,000 for a single-source ETL pipeline, $40,000-$150,000 for a multi-source platform, $75,000-$250,000 for a streaming architecture, and $100,000-$500,000+ for a full legacy-to-cloud migration.
### Scope 1: Single-Source ETL ($15,000-$50,000)
Typical for: Connecting one SaaS tool (Salesforce, Hubspot, Stripe) to a cloud warehouse.
What's included:
- Source connector setup (Fivetran, Airbyte, or custom)
- Data warehouse schema design
- dbt transformation models (5-20 models)
- Basic data quality tests
- Scheduling (Airflow or orchestration platform)
- Documentation and knowledge transfer
Timeline: 3-8 weeks.
### Scope 2: Multi-Source Data Platform ($40,000-$150,000)
Typical for: Building a central analytics warehouse from 5-15 sources.
What's included:
- All Scope 1 items × number of sources
- Source-to-target mapping documentation
- Staging, intermediate, and mart layer dbt models (50-200 models)
- Data catalog setup
- Monitoring and alerting
- BI tool connection (Tableau, Looker, Power BI)
Timeline: 8-20 weeks.
### Scope 3: Streaming Architecture ($75,000-$250,000)
Typical for: Real-time fraud detection, live dashboards, IoT data processing.
What's included:
- Kafka cluster setup and configuration
- Stream processing jobs (Flink or Spark Streaming)
- Event schema design and Schema Registry
- Exactly-once delivery guarantees
- Fault tolerance and replication setup
- Consumer application integration
- Load testing and performance tuning
Timeline: 10-24 weeks.
### Scope 4: Full Platform Migration ($100,000-$500,000+)
Typical for: Moving from on-premises Hadoop/Teradata/Oracle to a modern cloud warehouse.
What's included:
- Legacy system audit and inventory
- Migration strategy and roadmap
- Parallel run and cutover planning
- All Scope 2 items
- Historical data backfill
- User acceptance testing
- Post-migration optimization
Timeline: 4-12 months.
## What Do Data Engineering Firms Actually Charge?
Hourly rates across the 86 firms profiled in the Data Engineering Companies Index run $45-$250 (median $100). The spread reflects firm type, team location, and specialization more than raw skill level - a Snowflake specialist at an offshore-primary firm can bill less than a generalist at a global integrator.
| Firm Type | Hourly Rate | Typical Project Minimum |
|-----------|-------------|------------------------|
| Global system integrators (Accenture, Deloitte) | $150-$300/hr | $150,000+ |
| Mid-market boutiques (Hashmap, Phdata, Sigmoid) | $100-$200/hr | $50,000+ |
| Offshore-primary firms (Kanerika, Softserve) | $50-$120/hr | $25,000+ |
| Blended nearshore firms (Avenga) | $80-$150/hr | $40,000+ |
Rate variation by specialization:
- **Snowflake specialists:** $120-$180/hr
- **Databricks specialists:** $130-$200/hr
- **AWS pipeline specialists:** $100-$160/hr
- **Streaming/Kafka specialists:** $140-$220/hr (premium for streaming expertise)
- **Data governance specialists:** $120-$180/hr
## How Do You Reduce Pipeline Costs?
Cut infrastructure cost by right-sizing compute, defaulting to batch over streaming, partitioning tables, and using spot instances. Cut implementation cost by scoping tightly before signing, using managed ingestion tools instead of custom connectors, and starting with the free tier of your transformation tool.
### Infrastructure Cost Reduction
**Right-size compute.** Over-provisioned Databricks clusters and always-on Snowflake warehouses are the two largest sources of cloud waste. Run a cost audit: what was actual utilization vs. provisioned capacity over the last 30 days?
**Choose batch where latency allows.** If your business users need data updated once per hour, a streaming pipeline that processes events in real-time costs 3-5x more for zero business benefit. Default to batch and only add streaming when latency requirements justify the cost.
**Use partitioning and clustering.** Properly partitioned and clustered Snowflake and BigQuery tables reduce query scan costs 50-90% for analytics workloads. This is free to implement and often the highest-ROI optimization.
**Run spot and preemptible instances.** Databricks and EMR jobs can run on spot instances at 60-80% discount. Batch pipelines with checkpointing are ideal for spot - a failure resumes from the last checkpoint, not the beginning.
### Implementation Cost Reduction
**Define scope tightly before signing.** The #1 source of pipeline project overruns is scope creep: additional sources, new transformation requirements, or changed destinations discovered mid-project. A well-scoped SOW with a change control process prevents 30-50% of budget overruns.
**Use managed ingestion tools (Fivetran, Airbyte).** Custom connectors to common SaaS sources (Salesforce, Stripe, Shopify) take 3-6 weeks to build from scratch. Fivetran or Airbyte connectors for these sources cost $300-$2,000/month but eliminate weeks of bespoke engineering at $100-$200/hr.
**Start with dbt Core before dbt Cloud.** dbt Core is free and handles most transformation needs. dbt Cloud adds scheduling, a UI, and job orchestration - valuable but not needed on day one. Delay the $100+/month SaaS cost until you've validated the data model.
## Related Resources
For the full pattern library and a directory of firms that build these pipelines, see the [Data Pipeline Architecture hub](/data-pipeline/). To model your own project's budget interactively, use the [data engineering cost calculator](/data-engineering-cost-calculator/).
- [Stream Processing vs. Batch Processing](/insights/stream-processing-vs-batch-processing/) - decision framework for latency vs. cost tradeoffs
- [How to Build Data Pipelines](/insights/how-to-build-data-pipelines/) - engineering principles that affect total cost of ownership
- [Data Pipeline Monitoring Tools](/insights/data-pipeline-monitoring-tools/) - observability costs and tool comparison
- [Your Data Pipeline Cost Guide](/insights/data-pipeline-cost-guide/) - a budgeting framework for total cost of ownership across all five spend categories
---
## Your Data Pipeline Cost Guide: How to Benchmark & Budget for Consulting Engagements
Source: https://dataengineeringcompanies.com/insights/data-pipeline-cost-guide/
Published: 2026-03-29T10:09:44.189033+00:00
Description: Engineering leaders: This data pipeline cost guide offers consulting benchmarks, platform comparisons, & a budgeting framework. Optimize your spending.
A mid-market data pipeline draws its budget from three places: cloud infrastructure, platform licensing, and the engineers and consultants who build and run it. That last category is usually the largest line item, which is why hourly rates deserve as much scrutiny as your cloud bill - across the 86 firms profiled in the [Data Engineering Companies Index](/data-engineering-consulting-firms/), published rates run $45-250/hr with a median of $100. This guide breaks total cost of ownership into five layers, unpacks the three biggest cost drivers, and gives you a five-step framework for building a budget you can defend to finance instead of guessing.
## What are the five layers of data pipeline total cost of ownership?
Total cost of ownership for a data pipeline runs across five areas: cloud infrastructure, platform licensing, engineering and consulting talent, orchestration and monitoring tooling, and data governance. Missing any one of them in your budget is what turns a tight estimate into a mid-year overrun.
Unaddressed technical debt in a pipeline is what quietly inflates every one of those categories over time - a schema that never got documented or a job that never got refactored shows up later as extra engineering hours, extra compute, or both.
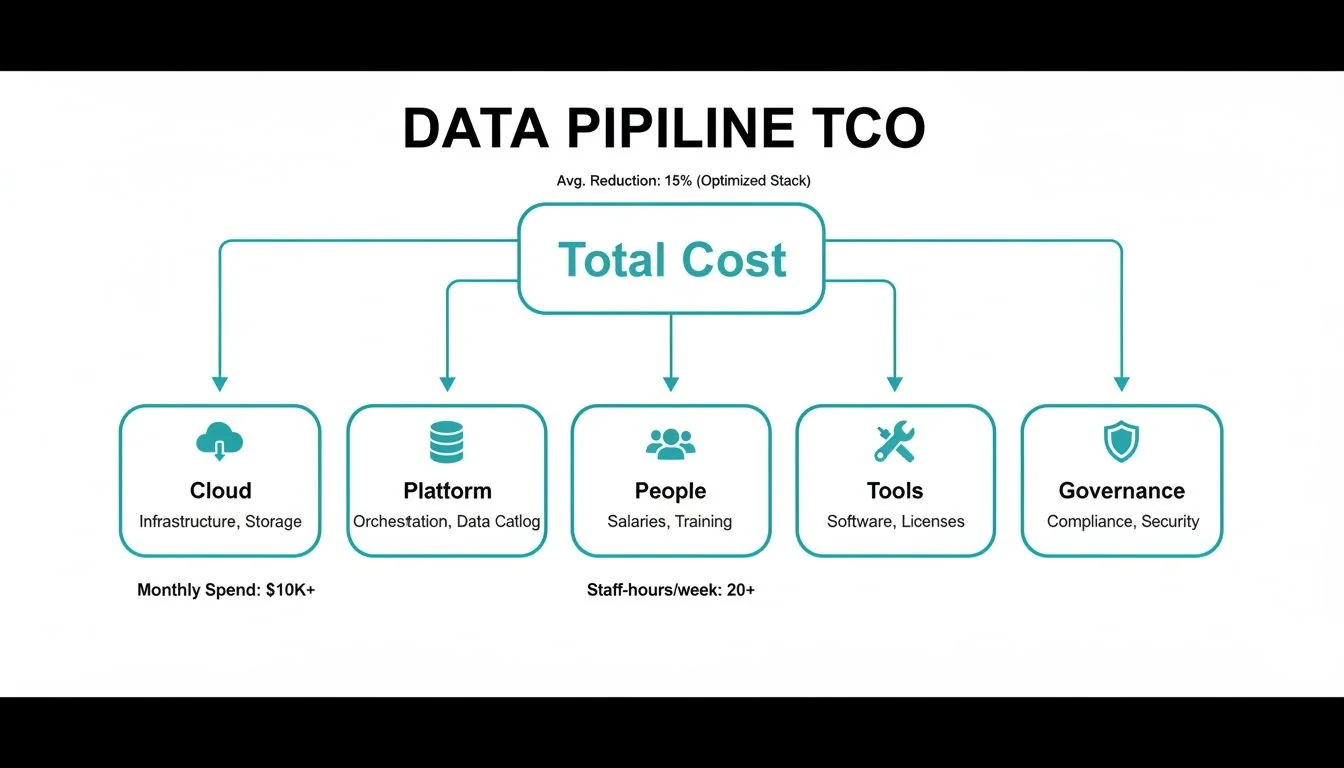
This breakdown points to one thing worth remembering: people - your engineers and consultants - represent the largest share of the budget. At the same time, governance and specialized tooling are consistently underfunded, and that gap tends to surface later as data quality problems and access-control gaps.
## What are the three largest cost drivers behind data pipeline spend?
When a data pipeline budget spirals, the cause is almost always one of three factors: cloud infrastructure spend, platform licensing, or talent costs. Get a handle on these three and the rest of the budget mostly falls into place.
### What drives cloud infrastructure costs?
Your cloud invoice is the cost foundation, and the biggest surprise on it usually isn't compute or storage - it's data egress, the cost of moving data out of your cloud or between regions. Egress gets missed during architecture design and then shows up prominently on the first real bill.
Each cloud provider presents its own cost challenges:
* **[AWS](https://aws.amazon.com/):** A vast service portfolio with pricing that's genuinely hard to model. Data egress fees are a common source of budget surprises when they aren't explicitly accounted for upfront.
* **[Azure](https://azure.microsoft.com/):** The default choice for Microsoft-centric organizations. Pricing for services like [Azure Data Factory](https://azure.microsoft.com/en-us/products/data-factory) spans multiple billing dimensions - DIUs and vCore-hours - that need to be tracked separately.
* **[GCP](https://cloud.google.com/)/[BigQuery](https://cloud.google.com/bigquery):** Generally cleaner pricing and strong performance. The risk is cost escalation from high query volumes when SQL isn't optimized for BigQuery's slot-based architecture.
### How do Snowflake and Databricks licensing costs work?
Both platforms bill by consumption rather than seat count, so understanding the billing unit matters more than reading the price sheet. **[Snowflake](https://www.snowflake.com/en/)'s** credit model is consumed by virtual warehouse uptime; **[Databricks](https://www.databricks.com/)'s** DBU model is tied to cluster runtime.
The outcome is the same either way: a poorly written, long-running query burns budget. It just shows up as a different line item depending on which platform you're on.
### How much does engineering and consulting talent cost?
Talent is the single largest line item in most data engineering budgets, and it's a straightforward supply and demand problem - the pool of engineers with real production experience on modern platforms hasn't grown as fast as demand for them. If you want to put a number on what a strong team actually returns, [data engineering ROI measurement](/insights/data-engineering-roi-measurement/) walks through how to track it against your own baseline instead of an industry average.
Across the 86 firms profiled in the Data Engineering Companies Index, published hourly rates span **$45-250/hr** with a median around **$100/hr**. Large IT services and offshore-heavy shops cluster at the low end, boutique cloud-platform specialists sit in the middle, and elite strategy firms sit at the top. For the full breakdown by firm type and typical project minimum, see [data engineering consulting rates 2026](/insights/data-engineering-consulting-rates-2026/).
A blended team that pairs onshore oversight with nearshore or offshore delivery can stretch a budget further without giving up quality - the rates guide above breaks down which firm types are set up to support that model.
## Which consulting engagement model fits your project?
Selecting the wrong engagement model is the fastest way to blow your budget. The commercial structure has to match how well-defined your project's scope and goals already are, or you end up paying for your consultant's learning curve, or locked into a scope that stopped being relevant weeks ago.
### When does time and materials pricing make sense?
With time and materials (T&M), you pay for hours worked plus direct costs. This gives you maximum flexibility, which makes it the right fit for projects with an undefined path - architectural discovery, agile development, anything where nobody yet knows exactly what "done" looks like. The tradeoff is that the risk sits with you: if scope expands or unexpected complexity shows up, you pay for the extra time.
**Contractual tip:** mandate a "right to replace" clause for underperforming resources, and negotiate a "not to exceed" (NTE) cap on hours to keep weekly burn in check.
### When does a fixed-price engagement make sense?
A fixed-price agreement sets one price for a well-defined scope of work. This works when requirements are locked - a data migration from a legacy system to Snowflake where source and target schemas are already mapped, for example. Risk shifts to the consulting firm, which gives them a direct incentive to work efficiently.
**Red flag:** be wary of a vendor pushing a fixed-price deal on a project with a lot of unknowns. Either they've baked a large contingency buffer into the price and you're paying for it anyway, or they're setting you up for aggressive change orders on anything not spelled out explicitly in the original SOW.
### When does an outcome-based agreement make sense?
This is the most aligned engagement model: a significant portion of consultant payment ties directly to hitting specific, measurable business goals - reducing data processing costs by a set percentage, or hitting a defined data quality score, for example.
It builds a real partnership, but it requires high trust and metrics mature enough to verify the outcome cleanly. It works best for optimization projects where ROI is directly measurable.
## How do you build a data-driven pipeline budget in five steps?
Guesswork has no place in a data engineering budget. A defensible number ties every dollar to a specific business outcome. Five steps take you from an abstract estimate to a concrete, data-backed proposal:
1. **Baseline current costs.** Audit every dollar you currently spend: pull your cloud bills from [AWS](https://aws.amazon.com/), [Azure](https://azure.microsoft.com/), or [GCP](https://cloud.google.com/), tally software licenses for [Snowflake](https://www.snowflake.com/en/), [Databricks](https://www.databricks.com/), or [Fivetran](https://www.fivetran.com/), and review every active consulting agreement. That gives you a factual starting point instead of a guess.
2. **Scope the future state.** Define the "why" behind the project. What specific business outcome drives it - a new data product, self-serve analytics for marketing, something else? Tying the technical work to a real outcome is what makes the eventual budget defensible.
3. **Estimate platform and infrastructure costs.** Model costs using official pricing calculators from your cloud and data platform vendors. Run a few scenarios for compute, storage, and data transfer so you understand how usage actually translates into fees.
4. **Calculate engineering effort.** Budget for the people. Break the project into phases - discovery, design, build, test, deploy - estimate sprints or person-weeks for each, and apply the benchmark rates for whichever engagement model you've chosen.
5. **Add a contingency buffer.** No project goes exactly as planned. Add 15-20% to the total estimate. That's not padding - it's a realistic provision for the technical hurdles and scope adjustments that show up on almost every project, and it signals to finance that you've actually thought this through.
A modeling tool turns these five steps into an actual number: adjust inputs like project timeline or team composition and see the total cost move in response. Model your own scenario with the [data engineering cost calculator](/data-engineering-cost-calculator/).
## How does FinOps keep pipeline costs under control?
Managing dynamic, consumption-based cloud costs against a static annual budget is a losing battle. FinOps is the discipline of tracking that spend close to real time instead of reconciling it once a quarter. A spreadsheet can't catch an inefficient query or an over-provisioned cluster burning money as it happens - only active monitoring can.
### From manual tracking to automated cost control
Monthly spreadsheet reviews can't keep pace with consumption-based billing. More teams are shifting toward automated anomaly detection that flags an unexpected spike in compute or storage the day it happens, instead of at the end of the billing cycle. Architectures with heavy cross-region data transfer are a recurring source of surprise cloud bills, and idle or over-provisioned resources routinely account for a meaningful share of total spend at organizations that haven't automated cost oversight yet.
### Core FinOps strategies for data pipelines
Applying FinOps isn't about watching a dashboard - it's implementing specific practices that change how your team actually operates.
* **Automated showback and chargeback:** This creates accountability. Attribute cloud costs automatically to the specific teams, projects, or products that generated them. When engineers see the direct financial impact of their code, they write more efficient code.
* **Continuous resource rightsizing:** Your workloads aren't running at peak all the time. Use monitoring tools to continuously track resource utilization, and automatically scale down or pause idle or oversized compute clusters and virtual warehouses.
* **Reserved instances and savings plans:** For predictable, baseline workloads like daily ETL jobs, don't pay on-demand prices. Committing to reserved capacity with your cloud provider cuts compute costs substantially - check your provider's own pricing calculator for the exact discount at your commitment level.
These practices turn cost management from a monthly postmortem into something closer to a live optimization loop, and they make cost awareness part of how your engineering team already works, not a separate finance exercise bolted on afterward.
## What's the fastest way to get pipeline costs under control?
Three moves deliver the fastest results: audit what you're already spending against the benchmarks above, score your team's FinOps maturity honestly, and model your next project's total cost before you go ask for budget.
### Step 1: Audit current spend
Establish a clear baseline. Use the budget framework above to audit your current data stack spend in full, then line up actuals against the benchmarks for cloud, platforms, and engineering. This exercise alone tends to surface your top three cost drivers and expose the outliers that need urgent attention.
### Step 2: Evaluate FinOps maturity
Get your data and finance teams in a room for an honest assessment. Review your current cost management practices against the FinOps strategies above. Are you actually rightsizing resources, or letting them run? Do you have showback in place? This conversation reveals the gap between where you are and where you need to be. Explore [Snowflake cost optimization](/insights/snowflake-cost-optimization/) next if warehouse spend is where your biggest gap sits.
### Step 3: Model your next project's TCO
Stop making budget requests based on gut feelings. For your next major data initiative, use the [data engineering cost calculator](/data-engineering-cost-calculator/) to model total cost of ownership. Plugging in your project specifics generates a defensible estimate that accounts for platform fees, engineering work, and contingency - and turns your budget request from a wish list into a number finance can actually evaluate.
Together, these three steps bring immediate clarity to your spending and make it easier to decide, faster, on every data investment that follows.
## Data Pipeline Cost FAQs
These are the questions engineering leaders ask most often once they start digging into data pipeline costs.
### How much should a data pipeline cost?
There's no single number - it depends on data volume, pipeline complexity, and your team's size and location. For a fuller cost breakdown by pipeline type and project scope, see the [data pipeline cost estimation guide](/insights/data-pipeline-cost-estimation-guide/).
The allocation across categories matters more than the total. A reasonable starting split looks like:
* **Engineering & consulting:** 40-60%
* **Data platform licensing ([Snowflake](https://www.snowflake.com/en/), [Databricks](https://www.databricks.com/)):** 15-25%
* **Cloud infrastructure ([AWS](https://aws.amazon.com/), [Azure](https://azure.microsoft.com/en-us), [GCP](https://cloud.google.com/)):** 15-20%
* **Orchestration & monitoring tools:** 5-10%
* **Data governance & quality tools:** 5-10%
A significantly different split is worth investigating - it usually signals an imbalance somewhere upstream.
### What is the biggest hidden cost in data pipelines?
The biggest hidden cost is inefficient engineering. It isn't a salary line - it's a force multiplier that quietly inflates every other cost category, showing up as poorly designed architecture that burns cloud credits, or as engineers spending hours on manual fixes instead of automation.
An inefficient team doesn't just cost more in salary; it actively drives up platform and infrastructure spending through avoidable rework. That's why choosing the right delivery partner is one of the highest-impact financial decisions on a data engineering project.
### How can I justify the cost of a new data pipeline?
Stop leading with cost - lead with value. Frame the investment around total cost of ownership and return on investment, and connect it to specific business outcomes.
Build your business case around three questions:
* What new revenue does this data make possible?
* What operational costs get eliminated by automating manual reporting?
* What's the financial risk of making decisions on stale or inaccurate data?
When you can show the pipeline is an engine for growth rather than an IT line item, getting leadership buy-in gets a lot easier.
***
Stop guessing. Get clear, defensible numbers for your next data project. **DataEngineeringCompanies.com** provides transparent rate bands, detailed firm profiles, and a suite of tools to help you select the right data engineering partner with confidence. [Find your expert match today](https://dataengineeringcompanies.com).
---
## The Top 12 Data Pipeline Monitoring Tools for Enterprise Teams
Source: https://dataengineeringcompanies.com/insights/data-pipeline-monitoring-tools/
Published: 2026-01-11T09:21:51.535366+00:00
Description: Discover the 12 best data pipeline monitoring tools for 2026. Our expert guide provides practical, no-fluff reviews to help you choose the right solution.
Data pipeline monitoring tools catch what a broken dashboard won't tell you until it's too late: a schema change in an upstream API, a corrupted file that landed in S3 three days ago, a job that quietly stopped refreshing. Some tools watch pipeline runs and orchestration health; others watch the data itself, checking freshness, volume, schema, and row-level quality. Most mature data teams end up running one of each, not one instead of the other.
This guide reviews twelve tools worth shortlisting for a Snowflake, Databricks, BigQuery, or Airflow-based stack, each with a real technical trade-off, not just a feature list. The category earns its budget line because of what sits downstream: 68 of the 86 firms in the [Data Engineering Companies Index](/data-pipeline/) list analytics and BI work among their core capabilities, and a stakeholder-facing dashboard is usually the first place a silent pipeline failure shows up.
What this guide covers:
* **Core capabilities** and what actually differentiates each platform from the others.
* **Where each tool fits** - orchestration-native, warehouse-native, agent-based, or dbt-native.
* **Implementation notes**, common pitfalls, and pricing signals from public sources.
* **A comparison table and a selection framework** for narrowing your shortlist before a demo.
## 1. Monte Carlo Data: Data Observability Platform
Monte Carlo is an end-to-end data observability platform, making it a strong contender among data pipeline monitoring tools for enterprises. Its core capability is its automated, low-configuration approach to anomaly detection. The platform monitors data warehouses, lakes, ETL processes, and BI tools to proactively identify and alert on issues like freshness, volume discrepancies, schema changes, and data quality rule failures without requiring extensive manual setup.
The platform's primary differentiator is its deep, field-level data lineage. This allows data teams to perform rapid root-cause analysis when an issue is detected and conduct impact analysis to see which downstream dashboards or reports are affected. This feature matters for building trust in data assets and managing stakeholder communication during data incidents. The built-in incident management and triage workflows also streamline the resolution process directly within the platform.
### Key Details & Evaluation Pointers
* **Ideal Use Case:** Organizations with complex, cloud-native data stacks (Snowflake, Databricks, BigQuery) that need broad, automated monitoring and deep lineage visibility to reduce "data downtime." Its mature feature set is well-suited for established data teams.
* **Implementation Note:** Onboarding is relatively streamlined thanks to its wide range of native connectors. A key evaluation step is mapping critical data assets to its monitoring tiers to manage costs effectively. Understanding your modern [data pipeline architecture examples](https://dataengineeringcompanies.com/insights/data-pipeline-architecture-examples/) will help you scope the implementation correctly.
* **Pricing:** Pricing is not public and is customized based on data volume, connector count, and feature tiers. Engagement with their sales team is required for a quote. It is also available via cloud marketplaces (like AWS), which can simplify procurement.
* **Limitations:** The premium pricing model may place it out of reach for smaller teams or early-stage companies. Organizations seeking a fully self-hosted solution will need to look at other options.
**[Visit Website](https://www.montecarlodata.com)**
## 2. IBM Databand: Pipeline Observability
IBM Databand focuses specifically on pipeline-level observability, making it an excellent choice for teams whose primary pain point is the health and reliability of their data orchestration and ETL/ELT jobs. The platform provides deep visibility into job run-states, durations, and data SLAs, integrating directly with popular orchestrators like Airflow. Its strength is in catching operational issues, such as a job that runs too long or fails unexpectedly, and tying that failure back to its impact on specific datasets.

Databand's operational focus and enterprise backing set it apart. While other tools focus more on warehouse-native data quality checks, Databand excels at monitoring the processes that move and transform the data. It provides live process views and executive dashboards that give a clear, high-level overview of pipeline health, which matters for operational teams managing complex workflows and strict delivery timelines. This process-centric approach makes it a valuable data pipeline monitoring tool for ensuring operational integrity.
### Key Details & Evaluation Pointers
* **Ideal Use Case:** Data engineering teams heavily reliant on orchestrators like Airflow who need to improve the reliability and performance of their data pipelines. It's a strong fit for organizations that value enterprise-level support.
* **Implementation Note:** Onboarding involves integrating Databand's SDK with your data orchestrator. The key to a successful evaluation is to instrument a few critical or problematic pipelines first to see the immediate value in run-time alerting and historical performance analysis.
* **Pricing:** Databand offers publicly listed pricing tiers for entry-level usage, which is an advantage for teams needing to budget without an extended sales cycle. Pricing is based on usage and feature sets, with higher tiers for large-scale deployments.
* **Limitations:** While it monitors dataset freshness and schema, its data quality capabilities are less extensive than platforms focused purely on data-at-rest observability. Teams needing deep, automated, field-level anomaly detection within the warehouse may need to supplement it with another tool.
**[Visit Website](https://www.ibm.com/products/databand)**
## 3. Acceldata: Data Observability Cloud (ADOC)
Acceldata's Data Observability Cloud (ADOC) offers a broad, multi-layered approach to data monitoring that extends beyond typical data quality checks into platform reliability and cost governance. It is designed to provide visibility across the entire data lifecycle, covering data-in-motion and data-at-rest. The platform offers core data quality features like freshness checks and anomaly detection, but its unique value is the integration of these signals with operational performance and spend metrics from underlying data platforms.

This holistic view makes Acceldata a strong candidate for organizations looking to correlate data reliability issues with infrastructure performance or budget overruns. For example, a team can investigate if a sudden drop in data quality is linked to a poorly optimized query that is also driving up compute costs. Enterprise tiers further enhance its capabilities with advanced features like data reconciliation, which validates data consistency between source and target systems, a critical function for financial services and compliance-heavy industries.
### Key Details & Evaluation Pointers
* **Ideal Use Case:** Organizations that need to manage not only the quality of their data pipelines but also the operational health and cost-efficiency of their data platforms (like Databricks, Snowflake, and on-prem Hadoop). It's a fit for teams where platform administration and data engineering responsibilities are closely linked.
* **Implementation Note:** Given its broad scope, a phased implementation is recommended. Start by connecting it to a critical data platform to monitor data quality and platform signals, then expand to cost governance. The availability of a free trial and marketplace procurement can accelerate evaluation.
* **Pricing:** Pricing is customized and requires direct engagement for a quote. Acceldata is available via cloud marketplaces like AWS, which can simplify billing and procurement. Note that marketplace listings often show illustrative pricing, so a formal quote is necessary for accurate budgeting.
* **Limitations:** The platform's extensive feature set can present a steeper learning curve compared to more narrowly focused tools. Smaller teams may find the breadth of capabilities overwhelming if their primary need is just data quality monitoring.
**[Visit Website](https://www.acceldata.io)**
## 4. Soda: Data Observability and Data Quality
Soda is a developer-friendly data observability platform that emphasizes embedding data quality checks directly into data pipelines using its open-source core and SodaCL (Soda Checks Language). This "shift-left" approach allows teams to treat data quality as code. The platform is designed for fast onboarding, allowing users to quickly configure monitors and gain visibility through automated anomaly detection and metric monitoring.

What sets Soda apart is its blend of a no-code setup for business users and a checks-as-code experience for technical teams. This duality makes it an adaptable choice for organizations at different stages of data maturity. Its proprietary algorithms for metrics observability, combined with features like historical data backfilling and record-level detection, provide explainable and actionable alerts. Direct integrations with data catalogs and incident management tools like Opsgenie or PagerDuty route quality issues to the right team without extra glue code.
### Key Details & Evaluation Pointers
* **Ideal Use Case:** Teams looking for a fast-to-implement data quality solution that can scale from a single project to an organization-wide program. Its checks-as-code philosophy is particularly well-suited for engineering-led data teams that want to integrate monitoring into their CI/CD processes.
* **Implementation Note:** Start with the free tier to connect up to three datasets. This is a practical way to evaluate SodaCL and the platform's core alerting capabilities on a non-critical data pipeline before committing to a broader rollout. The no-code interface is a fast way to get initial monitors running.
* **Pricing:** Soda offers a transparent pricing model, including a free tier for small-scale use. Paid plans are typically priced on a per-dataset basis, which can be cost-effective for targeted monitoring but may become expensive for organizations wanting to monitor a vast number of data assets.
* **Limitations:** The per-dataset pricing model, while transparent, can be a potential cost-scaling issue for enterprises with thousands of tables to monitor. Organizations requiring deep, column-level lineage across the entire data stack may find its capabilities less extensive than more enterprise-focused platforms.
**[Visit Website](https://www.soda.io)**
## 5. Bigeye: Enterprise Data Observability
Bigeye is a data and AI trust platform with a strong emphasis on observability driven by data lineage. It's a powerful option among data pipeline monitoring tools for organizations managing large or intricate data stacks. The platform provides automated monitoring coverage for core metrics like volume, freshness, and schema, using anomaly detection to catch issues before they impact downstream consumers.

The platform's standout feature is its lineage-aware root-cause analysis, which helps teams quickly pinpoint the source of a data quality failure. Another key differentiator is its support for monitoring-as-code through "Bigconfig," allowing data teams to define and manage monitoring rules via YAML and a CLI. This approach enables version control, programmatic updates, and direct integration into existing CI/CD workflows, a useful feature for mature engineering teams.
### Key Details & Evaluation Pointers
* **Ideal Use Case:** Large enterprises or scale-ups with complex data environments that prioritize a programmatic, code-based approach to data quality monitoring. It's particularly well-suited for teams wanting to integrate observability into their DevOps practices.
* **Implementation Note:** To get the most out of Bigeye, teams should be prepared to adopt its monitoring-as-code philosophy. This may require an initial setup investment but pays off in scalability and governance. Properly mapping its capabilities aligns well with strong [data governance best practices](https://dataengineeringcompanies.com/insights/data-governance-best-practices/).
* **Pricing:** Bigeye does not list pricing publicly. A customized quote is provided after a demo and consultation to understand the scale of your deployment.
* **Limitations:** The platform's code-centric approach might present a steeper learning curve for less technical business users or teams accustomed to purely UI-driven tools. Its enterprise focus means it may be overkill for smaller organizations with simpler needs.
**[Visit Website](https://www.bigeye.com)**
## 6. Kensu: Real-time, Lineage-aware Data Observability
Kensu offers a distinct, agent-based approach to data observability that focuses on prevention. Instead of only monitoring data at rest in a warehouse, its agents are embedded directly within data-producing and consuming applications. This allows Kensu to collect detailed, real-time metrics and lineage information at the point of use, catching data quality issues before they propagate downstream and impact business intelligence reports or machine learning models.

The platform's core strength is its "Data Observability at the Source" methodology. By understanding how data is being created and used in real-time, its anomaly detection can provide immediate context for root-cause analysis. This deep, lineage-aware context is valuable in highly regulated industries like finance or healthcare, where proving data integrity and tracing provenance is a compliance requirement. This makes Kensu a compelling option among data pipeline monitoring tools for organizations prioritizing proactive issue resolution.
### Key Details & Evaluation Pointers
* **Ideal Use Case:** Organizations in regulated industries or those with mission-critical applications that cannot tolerate data quality failures. It is best suited for teams that want to prevent bad data from entering their systems rather than just cleaning it up afterward.
* **Implementation Note:** The agent-based deployment requires instrumentation within your application runtimes (e.g., Spark, Kafka, Python scripts). This is a more involved setup than connector-based tools, so evaluating the integration effort with your specific tech stack is a necessary first step.
* **Pricing:** Kensu does not publish its pricing. A custom quote must be obtained by engaging with their sales team and is typically based on the number of agents, data volume, and required features.
* **Limitations:** The need to deploy agents can introduce additional complexity and a potential performance overhead compared to agentless solutions. This approach may be a barrier for teams looking for a simple, non-intrusive monitoring setup.
**[Visit Website](https://www.kensu.io)**
## 7. GX Cloud (Great Expectations Cloud): Test-Driven Data Quality and Monitoring
GX Cloud builds upon the widely adopted open-source framework, Great Expectations, offering a managed, collaborative environment for defining and validating data quality. Its core strength is a "test-driven" approach where teams codify data expectations as version-controlled test suites. This makes it a powerful tool for enforcing data contracts and ensuring data adheres to specific, known business rules as it moves through pipelines.

The platform centralizes the management of these expectations, validation results, and alerting. It integrates directly into existing CI/CD workflows and orchestration tools like Airflow or dbt, letting developers embed data quality checks straight into their data transformation and loading processes. By treating data quality as code, GX Cloud lets data teams build more reliable, predictable pipelines and catch issues before they hit downstream consumers.
### Key Details & Evaluation Pointers
* **Ideal Use Case:** Developer-centric data teams that want to embed explicit, code-based data quality tests directly into their pipelines. It is excellent for organizations standardizing on a "data contracts" framework and building on tools like dbt.
* **Implementation Note:** Getting started is straightforward, especially for those familiar with the open-source version. The key is to strategically identify critical validation points in your pipeline and build out reusable "Expectation Suites" that can be applied to multiple datasets.
* **Pricing:** GX Cloud offers a free developer tier for individuals and small projects. Paid Team and Enterprise tiers are available with more advanced features for collaboration, security, and support, requiring contact with their sales team for a quote.
* **Limitations:** This is not a turnkey observability platform; it excels at validating known conditions rather than automatically discovering unknown data issues. Teams seeking broad, automated anomaly detection for freshness or volume may need to supplement it with other data pipeline monitoring tools.
**[Visit Website](https://gxcloud.com)**
## 8. Prefect Cloud: Orchestration with Built-in Monitoring
Prefect Cloud is a workflow orchestration platform that approaches monitoring from the perspective of pipeline execution and health. Its strength lies in providing deep visibility into the state of data flows themselves. It offers a full-featured UI with dashboards that track flow and task runs, logs, retries, and adherence to service-level agreements (SLAs), making it a strong tool for the operational integrity of your data stack.

The platform is code-first and flexible, working with nearly any programming language or data stack while allowing your data to remain within your own VPC. Its built-in alerting and notification system ensures that teams are immediately aware of failures, crashes, or late runs. This makes Prefect a strong choice for teams who want to unify workflow orchestration and core operational monitoring into a single system before adding more specialized data quality tools.
### Key Details & Evaluation Pointers
* **Ideal Use Case:** Engineering-centric teams that need a powerful, code-based orchestration tool with integrated operational monitoring. It excels in environments where the primary concern is the success, failure, and performance of the pipeline code itself.
* **Implementation Note:** Adoption is fast due to its Python-native feel and minimal infrastructure requirements. The key is to instrument your existing code with Prefect's decorators. A major benefit is its hybrid model, where the control plane is managed, but execution and data stay in your environment.
* **Pricing:** Prefect offers a generous free Hobby tier for individuals or small projects. Paid plans are seat-based, offering predictable costs that scale with team size rather than data volume. Optional serverless compute credits are also available.
* **Limitations:** While it excels at operational monitoring, it is not a data observability tool. Deep column-level lineage, data quality validation, and anomaly detection require integration with other dedicated data pipeline monitoring tools.
**[Visit Website](https://www.prefect.io)**
## 9. Dagster Cloud: Asset-based Orchestration and Observability
Dagster Cloud tightly couples orchestration with observability. Its core philosophy revolves around "data assets" (like a table, a file, or a machine learning model), which provides an intuitive way to monitor data health. Instead of just monitoring pipeline runs, Dagster tracks the status and history of each asset, offering built-in lineage, run metadata, and log capture directly within the orchestration environment.

This asset-first model is particularly effective for organizations that are treating their data outputs as products. The platform's visual asset graph makes it easy to understand dependencies and trace issues back to their source. Built-in sensors and alerting mechanisms allow teams to define health checks and receive notifications on materialization events, making it a developer-centric solution that combines pipeline execution with deep, contextual monitoring.
### Key Details & Evaluation Pointers
* **Ideal Use Case:** Developer-heavy data teams looking for an integrated tool that handles both orchestration and observability. It is particularly well-suited for organizations adopting a data-as-a-product strategy, where the health and lineage of individual assets matter most.
* **Implementation Note:** Dagster's power comes from defining your pipelines in code as a graph of assets. The learning curve involves adopting this specific programming model. A good evaluation step is to refactor a small, existing pipeline to see how its monitoring capabilities simplify troubleshooting. It's a leading choice for teams evaluating modern [data orchestration platforms](https://dataengineeringcompanies.com/insights/data-orchestration-platforms/).
* **Pricing:** Dagster Cloud offers transparent, usage-based pricing with a free tier for individuals and clear entry points for teams, including a 30-day free trial. Enterprise features require contacting sales for a custom plan.
* **Limitations:** While it offers strong observability, it's not a standalone, agent-based monitoring tool; it primarily monitors pipelines defined and run within its own ecosystem. Teams seeking to monitor disparate systems without re-architecting them into Dagster may need a different solution.
**[Visit Website](https://dagster.io)**
## 10. Astronomer (Astro): Managed Apache Airflow with Monitoring
Astronomer provides a fully managed, enterprise-grade platform for Apache Airflow. Rather than offering a broad, agnostic observability layer, Astro focuses on the operational health and monitoring of Airflow DAGs (Directed Acyclic Graphs). It provides built-in alerting, high availability, audit logging, and deep performance insights specific to Airflow environments, making it one of the more relevant data pipeline monitoring tools for Airflow-centric teams.

The platform's key differentiator is its deep expertise and contribution to the open-source Airflow project, which translates into deep support and a feature set that addresses common operational pain points. For teams running complex orchestration, Astro simplifies deployment, scaling, and troubleshooting. It effectively abstracts away the infrastructure management complexities of running production Airflow, allowing data engineers to focus on building reliable pipelines rather than maintaining the orchestrator itself.
### Key Details & Evaluation Pointers
* **Ideal Use Case:** Organizations that have standardized on Apache Airflow for data pipeline orchestration and require a production-grade, managed service with enterprise support, security features like SSO, and guaranteed uptime SLAs.
* **Implementation Note:** The transition from self-hosted Airflow to Astro is well-documented. A key evaluation step is analyzing your current resource consumption (CPU, memory) to select the right deployment size, as this directly impacts cost. The platform is available on all major cloud marketplaces (AWS, GCP, Azure), simplifying procurement.
* **Pricing:** Astronomer offers transparent, usage-based pricing. Costs are calculated per hour based on the size and number of Airflow deployments and worker nodes you run. This component-based model provides predictability but requires careful resource planning.
* **Limitations:** Its primary focus is Airflow. While it can orchestrate tasks across various tools, the monitoring and observability features are centered on Airflow's health, not the data quality within the pipelines themselves. It must be paired with other tools for end-to-end data observability.
**[Visit Website](https://www.astronomer.io)**
## 11. Elementary Data: dbt-Native Data Observability (OSS + Cloud)
Elementary is a data observability tool built specifically for the dbt (data build tool) ecosystem. It offers both an open-source package and a managed cloud platform, providing a clear adoption path for teams of all sizes. Its core value is integrating deeply with dbt projects, allowing data teams to define data quality tests, freshness checks, and volume monitors directly within their existing dbt workflows, embracing an "observability-as-code" philosophy.

The platform excels at generating detailed, column-level lineage and exposure reports directly from your dbt project artifacts. This tight integration means that when a model fails or data quality issues are detected, engineers can immediately see the upstream causes and downstream impacts without leaving their core development environment. The cloud version extends these capabilities with features like AI-assisted triage and SOC 2 Type II compliance, making it a compelling upgrade path for organizations scaling their dbt usage.
### Key Details & Evaluation Pointers
* **Ideal Use Case:** Data teams whose transformation layer is standardized on dbt. It's a good fit for organizations wanting to embed monitoring directly into their data transformation code and for those who prefer starting with an open-source solution before committing to a commercial platform.
* **Implementation Note:** Getting started with the open-source version is straightforward for anyone familiar with dbt, requiring just a `pip install` and some configuration in your `dbt_project.yml`. Evaluating the cloud platform involves connecting your Git repository and data warehouse, with the key benefit being zero-maintenance infrastructure.
* **Pricing:** The open-source package is free. The cloud version offers several tiers with pricing available upon request. A key commercial advantage is that plans are based on user seats and features rather than table count, which can be cost-effective for large projects.
* **Limitations:** Its primary strength is also its main limitation. Organizations with heterogeneous data stacks or significant non-dbt transformation pipelines will find it less comprehensive than broader data observability platforms.
**[Visit Website](https://www.elementary-data.com)**
## 12. AWS Marketplace: Buy/Subscribe to Data Observability Tools
While not a monitoring tool itself, AWS Marketplace is a strategic platform for procuring and managing data pipeline monitoring tools. It functions as a digital catalog where organizations can find, buy, and deploy software from third-party vendors directly within their AWS environment. This significantly streamlines the often-cumbersome procurement process for enterprise tools, allowing teams to use existing AWS agreements and billing structures.

The primary advantage of using AWS Marketplace is the financial and administrative efficiency it offers. It allows companies to put their committed AWS spend (EDP) toward software purchases, which is a major benefit for budget management. The platform simplifies vendor onboarding and consolidates billing into a single AWS invoice, reducing administrative overhead. This makes it a useful resource for teams looking to accelerate the adoption of data observability solutions like Monte Carlo or Acceldata without getting bogged down in lengthy procurement cycles.
### Key Details & Evaluation Pointers
* **Ideal Use Case:** Enterprises with existing AWS Enterprise Discount Program (EDP) commitments looking to simplify procurement and consolidate vendor billing. It's also ideal for teams wanting to quickly trial and deploy pre-vetted data pipeline monitoring tools.
* **Implementation Note:** When evaluating a tool, check its availability and pricing model on the Marketplace. Use the "Private Offers" feature to negotiate custom pricing and terms directly with the vendor, which can lead to better rates than standard public listings.
* **Pricing:** Varies by vendor. The Marketplace supports diverse models, including pay-as-you-go, annual subscriptions, and custom contracts. Pricing is often integrated directly into your monthly AWS bill.
* **Limitations:** Not every data observability vendor is available, and some may offer limited SKUs or deployment options compared to direct sales channels. Some listings still require manual sales engagement for a final quote, slightly diminishing the "click-to-deploy" convenience.
**[Visit Website](https://aws.amazon.com/marketplace)**
## Data Pipeline Monitoring: 12-Tool Comparison
| Product | Core features | UX / Quality | Best for (Target audience) | Unique selling points | Pricing / Procurement |
|---|---|---|---|---|---|
| Monte Carlo Data: Data Observability Platform | End-to-end observability; anomaly detection; field-level lineage; incident workflows | Mature incident triage; deep lineage; broad connector coverage | Enterprises needing broad stack coverage and deep lineage | Field-level lineage; mature incident management; available via cloud marketplaces | Public pricing limited; sizing usually via sales; marketplace buying available |
| IBM Databand: Pipeline Observability | Pipeline run-state, duration & SLA alerts; dataset freshness/schema monitors; dashboards | Transparent entry pricing; enterprise-grade support and security options | Large enterprises seeking vendor backing and predictable entry costs | Published entry tiers; IBM global support and integrations | Published entry pricing for base tiers; higher tiers increase cost |
| Acceldata: Data Observability Cloud (ADOC) | Freshness, schema drift, anomaly detection; pipeline reconciliation; cost governance | Broad platform signals; enterprise controls; free trial available | Teams needing data quality + platform reliability and cost governance | Platform-level signals across infra and data; AWS Marketplace listings | Pricing by quote; marketplace may show illustrative contracts |
| Soda: Data Observability and Data Quality | Metrics observability; record-level detection; backfilling; data contracts | Fast onboarding; no-code monitors; free tier for small use | Teams wanting a lightweight, fast-to-start data quality solution | Free tier; explainable anomalies; low-cost Team plan | Free tier (up to 3 datasets); per-dataset pricing can scale with assets |
| Bigeye: Enterprise Data Observability | Volume, freshness, schema monitoring; lineage-aware RCA; monitoring-as-code | Designed for large/complex stacks; enterprise integrations | Organizations with complex data stacks needing codified monitoring | Monitoring-as-code (Bigconfig); deep lineage-enabled RCA | No public pricing; demo / sales engagement required |
| Kensu: Real-time, Lineage-aware Data Observability | Agent-based in-app metrics; real-time anomaly detection; impact analysis | Prevention-focused; close-to-consumer telemetry | Regulated environments needing prevention and detailed lineage | Agent-based real-time monitoring; prevention-first approach | Pricing not public; may require runtime agents and sales engagement |
| GX Cloud (Great Expectations Cloud): Test-Driven Data Quality | Managed expectation suites; validation runs; dataset alerting | Developer-friendly; open standard; free developer tier | Dev teams adopting test-driven data quality and standards | Popular open standard; strong community; dbt/Airflow friendly | Free developer tier; Team and Enterprise paid tiers available |
| Prefect Cloud: Orchestration with Built-in Monitoring | Flow/run dashboards; alerts, retries, SLAs; RBAC | Orchestration-first monitoring; predictable seat-based UX; free Hobby tier | Teams prioritizing orchestration with integrated monitoring | Seat-based predictable billing; VPC-friendly deployments | Seat-based pricing; free Hobby tier; optional serverless credits |
| Dagster Cloud: Asset-based Orchestration & Observability | Asset graph & lineage; materialization history; logs & sensors | Strong developer UX; asset-first model; trial periods | Developer teams building data products and asset-centric pipelines | Asset-first lineage and observability; clear small-team entry prices | Clear entry prices for solo/small teams; enterprise via sales |
| Astronomer (Astro): Managed Apache Airflow with Monitoring | Managed Airflow; alerting, SSO, audit logs, HA; deployment pricing | Production-grade Airflow; enterprise SLAs and support | Teams running Airflow in production wanting managed service | Deep Airflow expertise; transparent component pricing; marketplace buy | Usage-based deployment pricing (per-hour by size); marketplace options |
| Elementary Data: dbt-Native Data Observability (OSS + Cloud) | dbt-native monitors; column-level lineage; performance monitoring; AI triage | OSS path to start; cloud plans emphasize observability-as-code | dbt-centric projects and analytics engineering teams | dbt-native focus; OSS + cloud offering; unlimited tables in cloud plans | OSS free option; cloud tiers require contacting sales for pricing |
| AWS Marketplace: Buy/Subscribe to Data Observability Tools | Centralized procurement; private offers; consolidated AWS billing | Speeds procurement; simplifies vendor management | Buyers seeking consolidated billing and faster procurement | Consolidated AWS billing; private offers and contract templates | Pricing varies by vendor; some listings require seller engagement |
## How do you choose the right data pipeline monitoring tool for your stack?
Match the tool to where your failures actually happen, not to a feature checklist. Comprehensive platforms like Monte Carlo and Acceldata cover the most ground - warehouse, lake, and BI layer together. Focused tools like Elementary or GX Cloud go deeper into one layer, usually dbt or CI/CD, and orchestrators like Prefect and Dagster monitor pipeline execution rather than data quality itself.
That split is the real distinction in this list: some tools watch the pipeline run, others watch what the pipeline produces, and a couple - Monte Carlo, Acceldata - try to do both. Treat "monitoring" as several disciplines (freshness, volume, schema, lineage, execution health) instead of one checkbox, and pick tools that cover the disciplines you're actually missing today, not the ones a demo makes sound most impressive.
Reactive troubleshooting, waiting for a stakeholder to flag a broken dashboard, is the default failure mode without monitoring in place. The alternative is embedding checks directly into pipeline and orchestration code so problems surface before they reach a report or a model. Which tool gets you there depends on your architecture and your team's maturity as much as any single feature list.
### A practical framework for narrowing the list
Selecting a data pipeline monitoring tool is less about finding the "best" product and more about matching the tool to your problem, your stack, and your budget:
**1. Define your core problem.**
* **Is it data quality?** If your primary pain point is silent data errors corrupting BI reports, tools like Soda, Bigeye, or GX Cloud, with their deep focus on data quality checks and validation, should be at the top of your list.
* **Is it pipeline reliability?** If your data engineers spend most of their time debugging failed DAGs and SLA breaches, you need strong operational visibility. Look at orchestration-native solutions like Dagster, managed services like Astronomer, or a dedicated pipeline observability tool like IBM Databand.
* **Is it data discovery and trust?** For large enterprises where a "data swamp" is a real concern, comprehensive data observability platforms like Monte Carlo or Acceldata provide the lineage and automated monitoring needed to build trust and understand data asset dependencies.
**2. Align with your stack's center of gravity.**
* **Snowflake/Databricks centric:** Your evaluation should heavily favor tools with deep, native integrations and optimized performance for these platforms.
* **dbt-native:** If dbt is the heart of your transformation layer, a tool like Elementary offers tight integration and a developer-centric workflow that will resonate with your analytics engineers.
* **Open-source and self-hosted:** For teams requiring maximum control, building on open-source foundations (like Great Expectations or Soda Core) might be the most strategic, if resource-intensive, path.
**3. Evaluate total cost of ownership, not just licensing.**
* **Implementation overhead.** How many engineering hours will deployment, configuration, and integration take? A cheaper tool with a high implementation burden can end up costing more than the "expensive" option.
* **Maintenance and scaling.** Does the tool scale automatically, or will it need dedicated headcount as data volume and pipeline complexity grow?
* **Training and adoption.** A tool your team won't actually use doesn't deliver value regardless of its feature list. Favor solutions with clear documentation that both engineers and business users can pick up quickly.
### Your next step
Picking a monitoring tool is a real decision, but it doesn't need to be a six-month evaluation. Start with a pilot on a single high-impact pipeline, ideally one that's already caused a data incident, and score two or three candidates against it using the framework above. A working pilot gives you concrete numbers, setup time, false-positive rate, time-to-detection, that justify a broader rollout, and it beats another round of vendor demos.
---
A monitoring tool only closes half the gap. Setting up alerting rules, defining SLAs, and building the on-call process around them is implementation work, and it's often where in-house teams run out of time. If you need help scoping or deploying one of these platforms, the [Data Engineering Companies Index](/data-engineering-consulting-firms/) lists vetted firms by specialty, and [data reliability engineering](/insights/data-reliability-engineering/) covers the operational practices that make a monitoring tool actually pay off.
---
## 10 Actionable Data Pipeline Testing Best Practices for 2026
Source: https://dataengineeringcompanies.com/insights/data-pipeline-testing-best-practices/
Published: 2026-02-24T06:50:18.606515+00:00
Description: Discover 10 actionable data pipeline testing best practices. This guide covers everything from unit tests to chaos engineering for modern data stacks.
**Data pipeline testing best practices span ten layers: data quality validation, unit tests on transformations, integration tests across the full flow, schema drift checks, load testing, regression automation, lineage and impact analysis, snapshot/idempotency checks, chaos engineering, and observability built into the test suite itself.** A pipeline that runs to completion isn't the same as one that produced correct data - the failures that matter most rarely throw an error; they quietly corrupt a table that a dashboard or a model then trusts.
The ten practices below move testing beyond a pass/fail run check into something that actually verifies the data. Each section covers what the practice catches, which tools teams use for it, and concrete implementation tips you can act on this sprint.
## 1. What Is Data Quality Validation Testing?
Data quality validation testing checks the accuracy, completeness, consistency, and timeliness of data at defined checkpoints, before it loads into a warehouse or analytics platform. It's the automated gatekeeper that stops "garbage in, garbage out" from reaching a dashboard. See [what data quality testing entails](https://www.trackingplan.com/faqs/what-is-data-quality-testing) for the underlying concept.
Catching null values in critical fields, wrong data types, or duplicate records at this stage protects everything downstream. Great Expectations, Soda, and dbt's built-in tests are the frameworks teams reach for most. A retailer, for example, might use Great Expectations to confirm every transaction record has a valid `order_id` and a positive `transaction_amount` before it lands in Snowflake.
### Actionable Implementation Tips
- **Prioritize by Business Impact:** Begin by defining data quality rules for the most critical data elements that directly affect key business outcomes. Do not attempt to validate everything at once.
- **Layer Your Validations:** Implement checks in stages: first, basic schema validation (data types, column names), then business logic checks (e.g., order status transitions), and finally, statistical anomaly detection (e.g., an unusual spike in daily sales). This layered approach provides more targeted feedback.
- **Set Realistic Thresholds:** Configure your tests to balance sensitivity with the risk of false positives. A rule that fails a pipeline for a single null value in a non-critical field can cause more disruption than it prevents.
- **Visualize Quality Metrics:** Create dashboards to track validation results, failure rates, and data quality trends over time. This provides visibility to stakeholders and helps quantify the health of your data assets. For a deeper dive, see the guide to [managing data reliability](/insights/data-reliability-engineering/) across your organization.
## 2. How Does Unit Testing Work for Data Transformations?
Unit testing for data transformations means testing a single function or SQL model in isolation: feed it a small, controlled dataset and verify it produces the exact expected output. Isolating the logic from live databases and APIs makes tests fast, repeatable, and deterministic, so bugs surface at the cheapest possible stage.
For teams building complex transformations on Databricks or Snowflake, this isn't optional. A Databricks team, for instance, can use `pytest` to validate a PySpark function that calculates customer lifetime value, checking edge cases like new customers or returns before the logic ever touches production-scale data.
### Actionable Implementation Tips
- **Use Framework-Specific Tooling:** For SQL-based transformations, lean on `dbt test` to validate assumptions directly within your models (e.g., `unique`, `not_null`, `relationships`). For Python or Scala code in environments like Databricks, use standard testing libraries such as `pytest` or `ScalaTest`.
- **Test for Edge Cases, Not Just the "Happy Path":** Your unit tests should deliberately cover scenarios like null inputs, empty data frames, duplicate records, and extreme or unexpected values. This is what separates fragile pipelines from resilient ones.
- **Mock External Dependencies:** To achieve true isolation, mock any calls to external systems like databases, APIs, or other microservices. This ensures your test is evaluating only the transformation logic itself, not the state of its dependencies.
- **Integrate into CI/CD:** Embed unit tests directly into your continuous integration (CI) pipeline. Configure your workflow to automatically run these tests on every commit and block any code from being merged if the tests fail, preventing broken logic from ever reaching production.
## 3. What Is Integration Testing for Data Pipelines?
Integration testing runs the complete pipeline flow, from ingestion through transformation to final output, against realistic data and real (not mocked) dependencies, to confirm every component works as a system rather than in isolation. It's the layer that exposes issues unit tests structurally cannot see, like mismatched schemas between stages or misconfigured permissions.
A data platform team might test a Databricks medallion architecture end to end: raw data lands in a bronze zone, business rules produce a clean silver dataset, and the gold layer aggregates it for analytics. An e-commerce team might do the same across a pipeline that ingests from Shopify, Salesforce, and a custom event stream, transforms it in Snowflake, and loads the result into a BI tool.
### Actionable Implementation Tips
- **Mirror Production Environments:** Create separate staging or QA environments that closely replicate your production configuration, including network rules, access permissions, and resource allocation. This ensures your tests are representative of real-world conditions.
- **Use Realistic Data Subsets:** Run integration tests against recently refreshed, anonymized subsets of production data. This approach provides a realistic test bed for data volume and complexity without compromising data privacy.
- **Test Failure and Recovery:** Intentionally test error scenarios to validate your pipeline's resilience. Simulate failed API calls, network timeouts, or malformed data to ensure your error handling and recovery procedures function as expected.
- **Validate Stage-by-Stage Integrity:** Implement checks for row counts and checksums between key pipeline stages. A discrepancy between the source record count and the count after an ETL join can quickly pinpoint data loss or duplication issues. See how these components fit together in the guide to modern [data pipeline architecture](/insights/data-pipeline-architecture-examples/).
## 4. How Do You Test for Schema Drift?
Schema validation and evolution testing catches "schema drift" before it breaks a pipeline: a framework that detects when fields are added, removed, or change type, and confirms the pipeline handles that change gracefully rather than failing outright. It matters most on Snowflake and Databricks, where semi-structured sources make schemas fluid by default.
When an upstream API adds a new field or a feed changes a column from an integer to a string, schema tests act as an early warning system rather than a production incident. dbt model contracts, Confluent Schema Registry, and Great Expectations are the common tools here. A marketing team ingesting ad platform data, for example, can use automated schema tests to flag a new metric column and confirm it's mapped correctly before it causes mismatches downstream.
### Actionable Implementation Tips
- **Implement Automated Schema Inference:** For sources like JSON or Parquet, use tools that can automatically infer the schema and compare it against a known-good version. This immediately flags any new, missing, or altered fields.
- **Establish a Schema Registry:** Create a centralized, version-controlled repository for your data schemas (e.g., using Apache Avro or Databricks Unity Catalog). This registry becomes the "source of truth" for what data structures your pipeline expects.
- **Test for Breaking Changes:** Configure your CI/CD pipeline to explicitly test for breaking schema changes. If a pull request modifies a data model in a way that removes a column or changes a data type, the build should fail, forcing a deliberate review and migration plan.
- **Document and Version Schema Migrations:** For any intentional, major schema change, document the migration procedure and assign a version number. This practice, borrowed from software engineering, brings discipline to data model evolution and simplifies rollbacks if needed.
## 5. How Do You Load-Test a Data Pipeline?
Performance and load testing simulates real data volumes, frequencies, and concurrent processing scenarios to confirm a pipeline still meets its SLAs under pressure, not just on a quiet day with sample data. It checks execution time, resource use, and whether peak demand turns quality checks into bottlenecks.
Apache JMeter, Locust, and native cloud benchmarking services are the usual tools. A retailer can stress-test its e-commerce pipelines before Black Friday to confirm they hold up under a traffic spike an order of magnitude above normal; a financial institution can validate that daily risk calculations finish inside a strict regulatory window.
### Actionable Implementation Tips
- **Test with Production-Like Configurations:** Use cluster sizes and configurations that mirror your production environment. Testing on underpowered infrastructure will yield misleading results and mask potential scalability issues.
- **Simulate Concurrency:** Don't just test one pipeline in isolation. Run multiple pipelines concurrently to simulate a real-world scheduler's workload and uncover resource contention problems (CPU, memory, I/O).
- **Isolate and Stress Transformations:** Identify the most computationally expensive or slowest transformations in your pipeline. Create specific tests that hammer these specific steps with large data volumes to find their breaking points.
- **Monitor and Document Key Metrics:** Track execution time, memory and CPU usage, and cloud costs during tests. This data is essential for making informed decisions about cluster sizing, auto-scaling policies, and performance tuning.
- **Test Failure Recovery Under Load:** An often overlooked step is verifying how the system recovers from a failure while under heavy load. Confirm the pipeline can fail gracefully and resume without data loss or corruption. For methodology, see this guide to [load performance testing](https://goreplay.org/blog/boosting-application-performance-load-testing/).
## 6. What Is Regression Testing Automation for Pipelines?
Regression testing automation re-runs a suite of tests on every code change, infrastructure update, or schema migration to verify nothing that previously worked just broke. It's what lets a team move fast without every deploy being a gamble on downstream dashboards.
A data team using dbt can configure CI/CD to run a full test suite on every model change before deployment. Changes to an Apache Airflow DAG can similarly be checked against historical test cases to confirm processing logic still behaves the same way.
### Actionable Implementation Tips
- **Start with High-Impact Scenarios:** Don't attempt to build a complete regression suite from day one. Begin by creating automated tests for the most critical pipeline paths and for every bug discovered in production. This ensures your most valuable data flows are protected first.
- **Integrate with CI/CD:** Embed your regression test suite directly into your continuous integration and continuous deployment pipeline. Use version control branching strategies, like feature branches, and configure your system to automatically block deployments when a regression test fails.
- **Maintain High-Quality Test Data:** Your regression tests are only as good as the data they run on. Maintain a stable, versioned set of test data that covers key business scenarios, edge cases, and historical anomalies, not just simple technical validations.
- **Monitor Test Performance and Flakiness:** A flaky test, one that passes and fails intermittently without any code changes, can erode trust in your test suite. Actively monitor test execution times and failure rates, and immediately investigate the root cause of any instability to keep the process reliable.
## 7. How Does Data Lineage Testing Work?
Data lineage and impact analysis testing verifies the accuracy of a pipeline's dependency map: documenting and validating the path data takes from source to consumption, and confirming which transformations depend on which tables and columns. In enterprise pipelines, this is what makes it possible to scope tests and plan safe deployments instead of guessing at blast radius.
Before deploying a change, the lineage graph shows exactly which downstream models, dashboards, and reports it will touch. A financial services platform, for instance, needs to trace lineage from source transaction systems through risk calculations to final regulatory reports to prove data integrity. dbt's native graph visualization and governance platforms like Atlan or Collibra automate the discovery and mapping of these relationships at scale.
### Actionable Implementation Tips
- **Start with Automated Lineage Capture:** Use the built-in lineage features of your tools. dbt’s graph visualization, Databricks Unity Catalog, and Snowflake’s access history provide immediate dependency insights with minimal manual effort.
- **Integrate Lineage into Code Reviews:** Make it a standard practice for developers to review the dbt graph or lineage diagram as part of every pull request. This helps catch unintended dependencies or circular references before they are merged.
- **Use Lineage for Targeted Testing:** When a source table or an upstream model changes, use the lineage graph to define the exact scope of your integration and regression tests. This focuses testing effort where it's most needed and accelerates release cycles.
- **Maintain a Data Dictionary:** Supplement automated lineage with business context. A data dictionary should document not just the technical path but also the business purpose of transformations, providing a complete picture for auditors and new team members.
## 8. What Is Snapshot Testing and Idempotency Validation?
Snapshot testing and idempotency validation confirm two things: that running a pipeline twice on the same input produces identical results (idempotency), and that unintended changes to complex logic get caught by comparing new output against a stored "snapshot" of a known-good result. It's a check unit and quality tests don't cover on their own - whether output stays consistent over time.
A snapshot captures an expected state, like a final report or an ML feature set, and flags any deviation on later runs, which matters most where a small logic change has large downstream consequences. dbt's `snapshot` macro, built for tracking slowly changing dimensions, popularized the pattern for dimensional data.
### Actionable Implementation Tips
- **Focus on Critical Outputs:** Don’t snapshot everything. Start by capturing snapshots for high-impact transformation outputs like key business metric tables, final aggregated reports, or feature tables used in production ML models.
- **Implement Hash-Based Comparisons:** For very large datasets, storing and comparing full snapshots is inefficient. Instead, generate a hash (e.g., MD5) of the output data and compare the hash values. A change in the hash indicates a change in the data.
- **Exclude Non-Deterministic Fields:** Your comparisons will consistently fail if you include fields that naturally change on every run, such as `last_updated_timestamp` or randomly generated IDs. Exclude these columns from your snapshot comparisons to avoid false positives.
- **Version Your Snapshots:** Treat your snapshots like code. Store them in version control (like Git) alongside your pipeline code. When an intentional change is made, update the snapshot and commit it as part of the same release, creating a clear audit trail.
- **Establish a Review Process:** Create a workflow for reviewing and approving snapshot changes. When a test fails, a developer or data analyst must determine if the change was intentional (a valid logic update) or a bug. If intentional, the new snapshot is approved and becomes the new baseline.
## 9. What Is Chaos Engineering for Data Pipelines?
Chaos engineering intentionally injects failures into pipeline infrastructure - API timeouts, resource constraints, sudden data inconsistencies - to see how error handling, retry logic, and recovery mechanisms actually behave, rather than assuming they work. In a distributed pipeline, some component will eventually fail; this is how you find out before it does.
Popularized by Site Reliability Engineering and tools like Chaos Monkey, the practice hardens systems against partial outages. An e-commerce platform could simulate a third-party shipping API failure to confirm its pipeline reroutes orders to a backup provider instead of losing them. A data team could simulate a cluster node failure to verify jobs reschedule automatically and data integrity holds after recovery.
### Actionable Implementation Tips
- **Start in Pre-Production:** Never begin chaos testing in a live production environment. Isolate your experiments to staging or development environments to understand the impact without affecting real users or business operations.
- **Document Failure Scenarios:** Before injecting any failures, clearly define the expected behavior. What should happen when a database connection drops? How should the system recover? This documentation becomes your test case.
- **Establish a Baseline with Monitoring:** Implement comprehensive monitoring and alerting *before* starting chaos tests. You need clear visibility into the system's steady state to accurately measure the impact of an injected failure and confirm that alerts trigger as expected.
- **Validate Recovery and Consistency:** The test doesn't end when the system comes back online. The final step is confirming all data is consistent and complete after recovery, with no records dropped or corrupted.
- **Schedule Regular Chaos Days:** Treat resilience testing as a recurring event, not a one-time check. Schedule regular "chaos days" or automated experiments quarterly to continuously validate that new code changes or infrastructure updates haven't introduced new weaknesses.
## 10. What Is Observability and Test-Driven Monitoring?
Observability and test-driven monitoring writes tests for your monitoring itself - confirming the metrics, logs, and traces you're capturing are actually the ones you'll need to diagnose a failure fast. It shifts the pipeline from reactive firefighting to proactive detection by treating observability as code rather than an afterthought bolted on post-incident.
A data platform team might monitor pipeline execution duration and alert when a job runs meaningfully longer than its historical baseline. A transformation team might track row-count metrics at each stage of a dbt project, using anomaly detection to flag drops or spikes that signal data loss or duplication. See [what data observability is](/insights/data-pipeline-monitoring-tools/) for the underlying concept.
### Actionable Implementation Tips
- **Define Baselines and Test Thresholds:** Establish baseline performance metrics (e.g., execution time, CPU usage, data volume) for every pipeline under normal conditions. Implement tests that confirm alerts trigger at appropriate thresholds (e.g., a Z-score above 3) without generating excessive false positives.
- **Implement Structured Logging:** Enforce a structured logging format (like JSON) with consistent field names across all pipeline components. This makes logs easily queryable and allows you to write tests that validate specific events are being logged correctly during pipeline execution.
- **Use Distributed Tracing:** In multi-component or microservices-based pipelines, implement distributed tracing using standards like OpenTelemetry. This allows you to trace a single data record's journey across various systems, which is invaluable for pinpointing bottlenecks or failure points.
- **Link Alerts to Runbooks:** Create clear, actionable runbooks that detail the steps for resolving specific alerts. Associate each alert directly with its corresponding runbook to reduce mean time to resolution (MTTR) and ensure a consistent response from the on-call team.
## 10-Point Comparison of Data Pipeline Testing Best Practices
| Practice | Implementation complexity | Resource requirements | Expected outcomes | Ideal use cases | Key advantages |
|---|---:|---|---|---|---|
| Data Quality Validation Testing | Moderate-high: define/rule across stages | Validation frameworks, compute, monitoring | Prevents bad data, earlier error detection | Production pipelines, BI, regulated domains | Reduces downstream debugging, enforces SLAs |
| Unit Testing for Data Transformations | Low-moderate: per-transformation tests | Test frameworks, dev time, test fixtures | Correct transformation logic, fast feedback | dbt/Snowflake/Databricks development | Fast feedback, safe refactoring, CI support |
| Integration Testing for Pipeline End-to-End Flows | High: full-path execution and orchestration | Staging env, production-like data, time | Validates handoffs, uncovers integration faults | Complex multi-component pipelines, vendor evaluation | Catches issues missed by unit tests, verifies lineage |
| Schema Validation and Evolution Testing | Moderate: schema capture and drift rules | Metadata store, schema registry, tooling | Detects schema drift, prevents structural breaks | Semi-structured data, evolving APIs, IoT feeds | Enables graceful evolution, improves governance |
| Performance and Load Testing for Pipelines | High: stress and sustained load scenarios | Production-scale infra, load generators, monitoring | Ensures scalability, identifies bottlenecks | Peak traffic events, SLA-critical jobs | Informs capacity planning, uncovers performance limits |
| Regression Testing Automation | Moderate-high: maintain comprehensive suites | CI/CD, baseline datasets, test maintenance | Prevents regressions, supports rapid deployments | Frequent releases, mature engineering teams | Blocks unintended changes, documents expected behavior |
| Data Lineage and Impact Analysis Testing | Moderate: capture and validate metadata | Lineage tools, metadata capture, catalogs | Maps dependencies, enables targeted testing | Large enterprise pipelines, change management | Enables impact analysis, reduces blind deployments |
| Snapshot Testing and Idempotency Validation | Moderate: capture and compare outputs | Snapshot storage, diff tools, hashing | Detects subtle output changes, ensures idempotency | SCDs, reporting outputs, ML feature pipelines | High confidence in outputs, catches subtle regressions |
| Chaos Engineering and Resilience Testing | High: controlled failure injection practice | Failure injection tools, monitoring, safe envs | Validates recovery, exposes hidden failure modes | Mission-critical systems, resilience maturity programs | Reveals single points of failure, improves recovery |
| Observability and Test-Driven Monitoring | Moderate: monitoring-as-code and tests | Observability stack, dashboards, alerts | Faster detection and diagnosis, continuous metrics | Production monitoring, SRE/DataOps practices | Proactive detection, reduces time-to-diagnosis and MTTD |
## How Do You Operationalize a Testing Strategy?
The ten practices above share one thread: treating data pipelines as software assets that need the same engineering discipline as application code. Getting from inconsistent, manual validation to a mature automated suite takes months, not a sprint - the goal is a culture where data developers own the reliability of what they ship, not a checklist run once before launch.
### The Core Principles
* **Automate Everything:** Manual testing is a bottleneck and a point of failure. Aim for a setup where every code commit triggers unit tests, then regression tests against production-like data, all inside CI/CD - no one has to remember to run anything.
* **Test Data, Not Just Code:** A pipeline can execute flawlessly and still produce garbage data. Data quality validation, schema checks, and snapshot testing confirm the pipeline produces *correct* output, not just that it *ran*.
* **Shift Left and Shift Right:** Testing isn't one gate before deployment. Shifting left means unit and data quality tests during development; shifting right means observability, monitoring, and chaos engineering that keep validating pipeline health after it's live.
* **Implement Progressively:** Skip the big-bang rollout. Most teams start with basic data quality checks (`dbt tests`, Great Expectations) and unit tests on the most complex business logic, then layer in integration, performance, and regression testing as the team and platform mature. 20 of the 86 firms profiled in the Data Engineering Companies Index name dbt in their stack - a reasonable signal that dbt-native testing is the default starting point for most teams, not a niche choice.
> **Key takeaway:** the cost of skipping this isn't hypothetical - it shows up as broken dashboards, eroded stakeholder trust, and decisions made on bad data. Every incident a test suite catches before production is one less fire to fight after.
### A Path Forward
1. **Start Small:** Pick one critical pipeline. Add automated data quality checks at key stages and unit tests for its most complex transformation. Wire both into CI/CD and track the effect on stability and developer confidence.
2. **Standardize and Scale:** Turn the pilot into templates other teams can reuse. Document the patterns rather than leaving them tribal knowledge.
3. **Measure and Improve:** Track Mean Time to Detection for data bugs, the share of pipelines with automated coverage, and production incident counts. Use those numbers to justify the next round of investment.
Related reading: how to [evaluate a data engineering partner](/insights/data-engineering-partner-selection/), how to [monitor pipelines in production](/insights/data-pipeline-monitoring-tools/), and the broader practice of [data reliability engineering](/insights/data-reliability-engineering/).
---
## Data Reliability Engineering A Guide for CTOs
Source: https://dataengineeringcompanies.com/insights/data-reliability-engineering/
Published: 2026-04-16T07:27:59.467067+00:00
Description: Learn what Data Reliability Engineering (DRE) is, why it matters, and how to implement it. A complete guide for leaders evaluating data engineering partners.
Data reliability engineering (DRE) is the discipline of keeping data systems trustworthy on every run, not just once: freshness, completeness, schema stability, incident response, and repeatable recovery, all treated as measurable targets instead of hopes. If your data team spends its week babysitting broken pipelines, late tables, and executive dashboards that don’t reconcile, that isn’t a tooling problem. It’s a missing DRE practice.
That distinction matters when you’re hiring a consulting partner. Plenty of firms can stand up Snowflake, Databricks, dbt, Airflow, BigQuery, or a lakehouse on AWS and call it done. Far fewer can build a platform that stays trustworthy after the implementation team leaves.
I’ve seen both outcomes. The first implementation looked polished in demos and collapsed under production pressure because nobody owned freshness, incident response, or failure patterns. The second worked because we treated data reliability engineering as an operating model, not a feature. That’s the bar to use when evaluating consultants for enterprise data engineering, cloud migration, and data pipeline architecture.
## What is data reliability engineering, and why does it matter now?
Most leadership teams still frame broken data as a quality issue. They’re wrong. A one-time data check doesn’t fix a recurring failure mode - it just resets the clock until the next one. DRE exists to close that gap by making freshness, completeness, and schema stability into things a team actively monitors and owns.
### What DRE actually fixes
**Data scientists and data engineers spend 30% or more of their time firefighting data downtime incidents** instead of creating stakeholder value, according to [Monte Carlo’s research on data reliability](https://www.montecarlodata.com/blog-what-is-data-reliability/). That’s the number that should reset this conversation.
If your Airflow DAG succeeds but the upstream schema changed, your dbt models still build garbage. If your Snowflake load finishes but your executive KPI arrives late, the business still experienced downtime - the job status was never the thing that mattered.
A real DRE practice focuses on questions like these:
- **Freshness:** Is the critical table updated when the business needs it?
- **Completeness:** Did all expected records land?
- **Schema stability:** Did upstream producers break the contract?
- **Incident handling:** Who gets paged, how fast, and what happens next?
- **Recovery:** Can the team isolate and fix the issue without a war room?
Weak consulting reveals itself fast. Firms implement dashboards and call it observability. They scatter ad hoc tests in dbt and call it governance. They hand over a runbook no one will use and call it operational readiness.
> **Practical rule:** If the partner can’t define what “data downtime” means for your highest-value pipelines, they’re selling data quality theater.
### Stop accepting reactive operations
The right posture is proactive: instrument critical assets, set reliability expectations, and monitor for drift before a CFO catches it in a board deck. This [overview of automated anomaly detection](https://www.metricswatch.com/blog/automated-anomaly-detection) is a useful primer on the shift from manual checking to system-driven detection.
The buying implication is simple. If you’re selecting a consultancy for Snowflake, Databricks, AWS, Azure, or BigQuery modernization, DRE belongs in the scope from day one. Not after migration. Not after the first outage. Day one.
## How does DRE differ from SRE and data engineering?
Data engineering builds the pipelines, SRE keeps infrastructure available, and DRE owns whether the data itself stays trustworthy over time - three distinct jobs that teams routinely lump together, which is exactly why reliability work falls through the cracks. Making the split explicit is the fastest way to fix accountability.
Teams often struggle with data reliability engineering because accountability is muddy. Data engineers think platform reliability belongs to SRE. The SRE team thinks data validity belongs to analytics engineering. Everyone is partly right, which means nobody is fully responsible. [Google’s own SRE book](https://sre.google/sre-book/table-of-contents/) frames SRE as keeping services reliable and performant at the infrastructure level - a different job than keeping the data flowing through that infrastructure trustworthy.
### The cleanest way to split responsibility
[Altimetrik’s DRE overview](https://www.altimetrik.com/blog/data-reliability-engineering-best-practices/) draws the distinction clearly: data reliability engineering is a specialized subset of data operations, while DataOps covers broader concerns such as cost management and access controls. DRE owns test automation, SLO creation, incident management, and root cause analysis.
Here’s the practical breakdown.
| Function | Primary concern | Typical ownership | Failure they care about |
|---|---|---|---|
| Data Engineering | Build and maintain pipelines, models, and platform integrations | Data engineers, analytics engineers | Jobs fail, transformations break, dependencies drift |
| SRE | Keep services and infrastructure available and performant | Platform engineering, SRE | Compute outage, orchestration instability, service latency |
| DRE | Keep data products reliable over time | DRE lead, senior data/platform team, or embedded reliability owners | Stale data, silent bad data, broken contracts, recurring incidents |
### What this means in real delivery work
In a modern stack, the boundaries are straightforward:
- **Data engineering builds the path.** That includes ingestion, transformation, orchestration, and warehouse design.
- **SRE keeps the runtime healthy.** Think cluster stability, cloud resource posture, service uptime, and platform alerts.
- **DRE protects the data promise.** Freshness, completeness, quality over time, and repeatable recovery.
If your consultant says “our engineers do all of that,” press harder. Generalists can launch fast, but reliability failures usually hide in the handoffs.
### The anti-pattern to avoid
The most common failure pattern looks like this:
1. A consultancy builds ingestion into Snowflake or Databricks.
2. They add a few dbt tests.
3. They deploy Airflow or managed orchestration.
4. They leave without reliability ownership, escalation rules, or data SLOs.
That isn’t a DRE practice. That’s a project handoff with optimism.
> Data reliability engineering starts where implementation-only consulting usually stops.
Ask every partner where DRE lives after go-live. If they can’t point to named responsibilities across platform, pipelines, and incident response, expect the burden to fall back on your internal team.
## What are the core principles of a DRE practice?
A real DRE practice runs on a small set of operating principles: business-relevant SLOs, testing before production, observability with lineage and context, procedural incident response, and statistics used to set thresholds instead of guesses. None of them are glamorous. All of them matter.
### Start with SLOs that the business actually feels
If your main revenue dashboard must be ready before executives start the day, state that as an explicit reliability target: critical ETL jobs complete before the reporting window, or freshness stays under the threshold the business needs.
That’s what separates DRE from vague quality goals. Engineers need a target they can monitor and defend.
### Test pipelines before production embarrasses you
Most firms over-index on production monitoring and under-invest in testing. That’s backwards.
Your partner should build:
- **Schema tests** in dbt or equivalent transformation layers
- **Pipeline tests** around ingestion and orchestration logic
- **Contract checks** between source systems and downstream consumers
- **Deployment gates** in CI/CD before changes hit production
If they only talk about dashboard validation, they’re inspecting outputs too late. Start from [dbt’s own testing documentation](https://docs.getdbt.com/docs/build/data-tests) for what a full test suite covers beyond `not_null` and `unique`, then extend into a broader [pipeline testing strategy](/insights/data-pipeline-testing-best-practices/) that covers ingestion and orchestration, not just transformation.
### Observability needs lineage and context
Alerts without context are noise. Good DRE instrumentation tells you what broke, what changed, which downstream models are affected, and who owns the fix.
That’s why observability should cover:
- freshness
- volume anomalies
- schema drift
- lineage impact
- incident routing
For a closer look at what to instrument and where, see this [overview of data pipeline monitoring tools](/insights/data-pipeline-monitoring-tools/).
> The first useful alert answers two questions immediately. What failed, and who has to act?
### Incident response has to be boring
That’s a compliment. Mature reliability work is procedural.
For every critical pipeline, your consultancy should define:
| Element | What good looks like |
|---|---|
| Trigger | Alert tied to a specific failure condition |
| Owner | Named responder, not a shared inbox |
| Triage | Clear first checks and dependency map |
| RCA | Root cause documented and reviewed |
| Prevention | Test, monitor, or design change added after the incident |
### Use statistics where they improve operations
Reliability engineering isn’t guesswork. The [Weibull distribution](https://python.plainenglish.io/statistics-in-reliability-engineering-and-data-science-b498df8474f7) is a standard tool for modeling failure rates with shape and scale parameters, which makes it useful for predicting pipeline failures and setting uptime targets - like 99.9% - on statistical grounds instead of a guess.
You don’t need a consultant who throws equations into slides. You need one who can use failure history to set sensible thresholds, distinguish noisy anomalies from real risk, and tune alerts so the team trusts them.
## How mature is your organization’s DRE practice?
Most organizations are less mature than they think. A few dbt tests, some dashboards, and a Slack alert for failed jobs puts most teams in the reactive middle, not in a mature state. Score your posture honestly, dimension by dimension, before you hire anyone.
### DRE maturity model
| Dimension | Level 0 Ad-Hoc | Level 1 Reactive | Level 2 Proactive | Level 3 Automated |
|---|---|---|---|---|
| Testing | Manual spot checks after issues surface | Basic tests on selected models | Standardized tests across critical pipelines | Test coverage embedded in CI/CD with enforced gates |
| Observability | Teams notice issues from users or dashboards | Alerts on failed jobs only | Monitoring covers freshness, volume, schema, and lineage on priority assets | Detection, triage context, and routing are automated |
| Incident response | No runbooks, heroics drive recovery | Tickets and chats coordinate response | Defined runbooks and RCA process for major failures | Incident workflows trigger ownership, escalation, and post-incident fixes automatically |
| Ownership | Responsibility is shared and unclear | Platform or data team informally handles incidents | Named owners exist for core datasets and pipelines | Ownership is mapped by asset, dependency, and business criticality |
| Governance | Policies exist on paper | Some documentation and access controls | Reliability standards align with governance processes | Governance, lineage, and operational controls are connected in one operating model |
| Consulting partner fit | Partner talks tools | Partner offers monitoring setup | Partner can define SLOs and incident process | Partner delivers reliability as an embedded operating capability |
### How to use the model honestly
Don’t average yourself upward. A team with solid dashboards and weak incident ownership isn’t “advanced.” It’s uneven.
Score each domain separately and look for the bottleneck. In most organizations, one of these is the primary blocker:
- **No named owner for critical datasets**
- **No service level expectations for freshness or completeness**
- **No repeatable RCA discipline**
- **No production-aware testing before releases**
- **No distinction between platform uptime and data reliability**
### What buyers get wrong
Leaders often choose a consultancy based on platform logos and migration references. That tells you whether they can build. It doesn’t tell you whether they can stabilize - and it doesn’t tell you whether they treat governance as a real deliverable rather than an afterthought. Only 11 of the 86 firms profiled in the [Data Engineering Companies Index](/data-governance/) list governance as an explicit capability, so ask directly instead of assuming it’s bundled into the DRE scope.
> Buy for your weakest operational muscle, not for the prettiest architecture diagram.
If your team is Level 0 or Level 1 in incident response and ownership, you don’t need more generic implementation capacity. You need a partner that can establish operating discipline around Snowflake tasks, Databricks jobs, Airflow DAGs, dbt deployment workflows, and governance controls that survive change.
## What does a phased DRE rollout look like?
A phased rollout works because it forces prioritization: stabilize the critical path first, build repeatability into delivery second, and add predictive controls only once the basics hold. Trying to run all three at once is the fastest way to kill the initiative.
Don’t try to boil the ocean. The fastest way to stall data reliability engineering is to announce an enterprise program, buy a new observability tool, and leave ownership unresolved.
### Phase 1: Stabilize the critical path
Start with the assets that hurt the business when they fail. Usually that means revenue reporting, finance, customer operations, or model inputs for production systems.
Focus on these moves first:
- **Pick critical pipelines:** Name the jobs, tables, and dashboards that matter most.
- **Set basic reliability expectations:** Define what “on time” and “usable” mean for each one.
- **Create runbooks:** Give responders a first-step checklist for common failures.
- **Instrument core alerts:** Watch freshness, job failure, and schema changes on those assets.
This phase is where consulting partners earn trust. If they insist on broad platform rollout before identifying your critical path, they’re optimizing for billable scope.
### Phase 2: Build repeatability into delivery
Once the main pain is visible, move upstream into engineering workflow.
That means:
| Area | What to implement |
|---|---|
| CI/CD | Tests and deployment gates for dbt, SQL, and pipeline changes |
| Contracts | Clear source-to-target expectations for schemas and critical fields |
| Ownership | Dataset and pipeline owners documented in the platform or catalog |
| RCA | Standard post-incident reviews tied to preventive actions |
This is the point where DRE stops being an operations patch and becomes part of how your data platform ships changes.
### Phase 3: Add predictive and adaptive controls
Only after the basics are stable should you add advanced capabilities.
That includes anomaly detection, richer lineage-driven triage, and selective automation that can isolate or quarantine bad data before it spreads. In Databricks environments, that often means tightening reliability around streaming or model-serving dependencies. In Snowflake-centric stacks, it often means hardening orchestration and downstream consumption patterns.
### What to demand from a consultancy in each phase
A good partner should produce tangible artifacts, not vague progress reports:
- **Phase 1:** asset inventory, alert map, runbooks, ownership matrix
- **Phase 2:** test strategy, CI/CD controls, SLO definitions, RCA template
- **Phase 3:** anomaly policy, lineage-based escalation, selective self-healing design
If they can’t tell you what they’ll leave behind after each phase, you’re buying activity, not capability.
## How do you calculate the ROI of data reliability?
The strongest ROI case for DRE is operational, not a trust argument: faster detection and faster resolution free up engineering time, reduce executive disruption, and cut the rework that follows bad data. Build the case from concrete cost buckets before you ask for budget.
Most DRE business cases are weak because they lean on trust language. Trust matters. It doesn’t secure budget.
### Use a simple ROI frame
According to [Metaplane’s overview of data reliability engineering](https://www.metaplane.dev/blog/data-reliability-engineering-definition-for-modern-data-stack), teams that adopt DRE observability report materially faster issue resolution, and most mid-market data teams still have no formal way to calculate the ROI of that investment. That gap is the opening: teams feel the pain and still fail to quantify it.
Build the case from four buckets:
- **Engineering time recovered:** hours currently spent on triage, reruns, root cause hunts, and manual reconciliation
- **Business interruption avoided:** delayed reporting, broken downstream processes, executive escalations
- **Rework reduced:** repeated fixes for recurring incidents
- **Consulting and tooling investment:** implementation, enablement, and operating overhead
Hourly rates for data engineering consultants in the index run from $45 to $250, with a median around $100 - a useful anchor when you’re sanity-checking a partner’s DRE proposal against [current market rates](/insights/data-engineering-consulting-rates-2026/).
### What to measure before the project starts
If you don’t baseline these, your consultancy can claim success without proving it.
Track:
| Metric | Why it matters |
|---|---|
| Time to detect | Shows whether monitoring is working |
| Time to resolve | Captures operational drag |
| Incident recurrence | Reveals whether RCA changes are sticking |
| Critical asset downtime | Ties reliability to business-facing systems |
| Engineer effort on firefighting | Shows reclaimed capacity |
One practical explainer on the economics of reliability is below.
### The procurement question that matters
Ask every consulting firm this: **How will you prove that reliability improved in operational terms, not just tool adoption?**
Good answers include baseline measurement, post-implementation comparisons, and a short list of target outcomes tied to your most important pipelines. Bad answers focus on feature rollout, dashboard counts, or “best practice alignment.”
If the partner can’t model ROI against your current incident load, your CFO won’t trust the proposal, and your engineering team shouldn’t either.
## What DRE patterns matter most for AI/ML and modernization projects?
AI and modernization projects expose weak data reliability engineering faster than classic BI ever did: batch reporting can limp along on manual checks, but feature pipelines, near-real-time scoring, and GenAI retrieval flows can’t. The pressure point is almost always change - source contracts move, schemas evolve, and model inputs drift until the team sees degraded outcomes.
### Pattern one: schema contracts for moving sources
[Bigeye’s write-up on the data reliability engineer role](https://www.bigeye.com/blog/a-day-in-the-life-of-a-data-reliability-engineer) points to undetected schema drift as one of the most common root causes of data incidents on AI projects. That tracks with what fast-moving product teams see in practice - it’s the default failure mode, not an edge case.
For modernization projects, enforce [schema contracts](/insights/data-contracts-in-data-engineering/) at ingestion boundaries, especially when you’re migrating from legacy ETL into dbt, Airflow, Snowflake, Databricks, or BigQuery.
What to require:
- versioned schemas for producer teams
- explicit handling of new, missing, or type-changed fields
- quarantine paths for invalid records
- alerts tied to contract breaches, not just failed jobs
### Pattern two: focus monitoring on high-impact assets
The same source argues for 80/20 monitoring: put observability effort into the small set of high-impact tables that actually drive retraining and business outcomes, instead of instrumenting everything equally. Monitoring everything at the same level of rigor is lazy architecture disguised as completeness.
For AI/ML workloads, your high-impact assets are usually:
- feature tables feeding production models
- labels and training sets
- event streams used for online inference
- governance-sensitive joins and enrichment data
> Watch the assets that change business outcomes, not the assets that are easiest to instrument.
### Pattern three: reliability gates in modernization programs
Cloud migrations often fail after cutover because firms treat reliability as a post-migration optimization. It isn’t.
If you’re moving from on-prem ETL or fragmented warehouses into a modern stack, put these gates into the program plan:
1. Critical pipeline reliability criteria before go-live
2. Source and target reconciliation rules
3. Runbooks for rollback, replay, and incident routing
4. Ownership mapping across engineering, analytics, and platform teams
That’s especially important in regulated sectors, where the technical migration is only half the job. The other half is proving that the new platform behaves consistently under production change.
## How do you vet a DRE-capable consulting partner?
Most consultancies now claim they do observability, governance, and reliability. Don’t ask whether they do DRE - ask them to prove it with named ownership, a sample SLO, and a real runbook, not a slide deck.
### The questions that expose substance fast
Use this checklist in your RFP or technical diligence sessions.
#### Delivery model
- **Who owns data reliability after launch**
- **Which roles cover platform uptime, pipeline health, and data correctness**
- **What artifacts do you deliver besides code**
#### Reliability design
- **Show us a sample data SLO you’ve implemented**
- **How do you define and measure data downtime**
- **How do you distinguish job success from data success**
#### Tooling and implementation
- **How do you implement testing in dbt, orchestration, and CI/CD**
- **Which observability signals do you monitor on critical assets**
- **How do you map lineage from source breakage to downstream impact**
#### Incident operations
- **Show a sample runbook for a critical pipeline failure**
- **What does your RCA process look like**
- **How do you prevent repeat incidents after the fix**
#### Knowledge transfer
- **What training do you provide to internal owners**
- **What operating cadence do you recommend after handoff**
- **How do you avoid creating consultant dependency**
### The red flags
You should lower a firm’s score immediately if you hear any of these:
- **“We’ll add tests later.”** Reliability that starts after implementation usually never catches up.
- **“Our platform partner handles that.”** Tool vendors don’t own your operating model.
- **“We monitor everything.”** That usually means they haven’t prioritized business-critical assets.
- **“We’ve done lots of migrations.”** Migration experience isn’t proof of reliability engineering.
- **“Your data engineers can absorb incident response.”** They can, but then they stop building.
> The right consulting partner leaves you with a stronger operating system, not just a working stack.
For teams formalizing vendor diligence, this [due diligence checklist](/insights/data-engineering-due-diligence-checklist/) is worth using alongside your RFP process.
The next step is simple: shortlist firms that can show DRE artifacts, not just platform certifications. If you’re comparing partners for Snowflake, Databricks, AWS, Azure, BigQuery, governance, or data pipeline architecture work, use the [Data Engineering Companies Index](/data-engineering-consulting-firms/) to screen providers by capability, delivery fit, and consulting scope before you start demos.
---
## A Pragmatic Guide to Data Strategy Consultation for ROI
Source: https://dataengineeringcompanies.com/insights/data-strategy-consultation/
Published: 2026-02-08T08:25:11.846404+00:00
Description: A practical guide to data strategy consultation: what it delivers, when to hire one, typical costs, and how to vet a partner before you sign.
A data strategy consultation is a time-boxed engagement, typically 6 to 12 weeks, where an outside team audits your current data capabilities, defines a target architecture, and builds a phased execution plan tied to specific business outcomes: revenue growth, cost reduction, or a named AI initiative. The output isn't a slide deck. It's a plan that says what to build, in what order, and how you'll know it worked.
This guide covers what a consultation should deliver, when it's worth commissioning one, what it costs, and how to vet a vendor before you sign a Statement of Work. Rates vary sharply by engagement type and firm size, which is one reason vague proposals are hard to benchmark - more on that in the cost section below.
What this guide covers:
* **The three-pillar deliverable structure** - current-state audit, future-state roadmap, execution plan.
* **The specific triggers** that justify hiring outside help instead of building in-house.
* **Realistic cost bands** by consultant tier, and the contract models behind them.
* **A vendor evaluation checklist and red-flag list** for choosing a partner without getting burned.
## What does a data strategy consultation actually deliver?
A competent engagement produces three things: an evidence-based audit of your current data stack and team skills, a future-state architecture blueprint tied to specific business goals, and a phased execution plan with a KPI framework attached - not a set of slide-deck recommendations you have to translate into action yourself.
You wouldn't put up a building without an architectural plan. The architect doesn't lay bricks, but the plan they produce determines whether the structure is sound, functional, and fit for purpose. A data strategy consultant plays the same role for your data ecosystem: they build the technical and operational roadmap that guides every subsequent data decision, investment, and project.
For any organization competing seriously in 2026, particularly given the demands of AI initiatives and multi-cloud platforms, this planning step isn't optional. Without a coherent strategy, data initiatives fragment into expensive projects disconnected from the business needs they were meant to serve.
### From ambiguous goals to a concrete roadmap
A primary function of a **data strategy consultation** is translating high-level business ambitions into an actionable plan. It forces the organization past generic goals like "become more data-driven" and into a specific, sequenced set of actions. The roadmap should specify what needs to be built, who owns it, and how success gets measured.
The table below summarizes the core deliverables you should expect from any competent data strategy engagement.
### Core components of a data strategy engagement
| Component | Core Objective | Tangible Outcome |
| :--- | :--- | :--- |
| **Current-State Assessment** | Establish an objective, evidence-based baseline of current capabilities. | A detailed audit of existing data architecture, governance processes, and team skills, identifying critical gaps. |
| **Future-State Vision** | Define the target data ecosystem required to meet business objectives. | A collaboratively designed technical and operational blueprint for the ideal data platform, tailored to specific goals. |
| **Value Realization Plan** | Create the step-by-step implementation guide. | An actionable playbook detailing phased rollouts, talent requirements, and a KPI framework to measure ROI. |
This structured approach builds a sustainable data capability that delivers measurable results, rather than chasing whatever technology is trending that quarter.
### Aligning technology with business value
Demand for this kind of guidance is significant. The Big Data Consulting Market, a key segment of data strategy consulting spend, is projected to reach **USD 7.38 billion in 2025** and grow to **USD 13.97 billion by 2030**, according to [Mordor Intelligence's market report](https://www.mordorintelligence.com/industry-reports/big-data-consulting-market). That growth reflects a real need for organizations to get outside help modernizing data platforms in support of AI and other critical initiatives.
> A successful consultation ensures that every dollar invested in data technology - whether for a cloud warehouse or an AI model - is tied to a specific, measurable business outcome. It cuts spending on technology for its own sake and directs resources toward initiatives that actually move the business.
The final output isn't just a document. It's a shared plan that turns data from a liability into a strategic asset.
## What are the three pillars of a data strategy engagement?
Every effective data strategy breaks into three sequential phases: a diagnostic audit of what you have, a blueprint for what you need, and a phased plan for closing the gap - each tied to a measurable business outcome rather than a technology wish list.
This three-pillar structure keeps every action deliberate and every dollar invested tied to a quantifiable outcome. The goal is a direct line from technical data work to a measurable improvement in the bottom line.
### Pillar 1: The current-state audit
You cannot map a route to a destination without knowing your starting point. The first pillar is a diagnostic analysis of your existing data ecosystem - a technical and operational audit where consultants act as objective investigators mapping your entire data environment.
This audit is a holistic review covering three areas:
* **Technology and Architecture:** An under-the-hood examination of your current data stack, pipelines, and storage. Consultants assess everything from ingestion methods to the performance and cost efficiency of your analytics platforms.
* **Processes and Governance:** How you manage, protect, and use your data - data quality protocols, access controls, and compliance with relevant regulations.
* **People and Skills:** A strategy is only as good as the people executing it. This component assesses the data literacy and technical capability of your teams to identify skill gaps.
The output is an objective, evidence-based report on what's working, what's broken, and where the biggest risks and opportunities sit. This foundation is non-negotiable for building a realistic strategy.
### Pillar 2: The future-state roadmap
With a clear read on the "as-is," the process shifts from diagnosis to design. This pillar builds a detailed blueprint for your ideal data environment - not a technology wish list, but a plan that aligns your data capabilities with your primary business goals over the next **three to five years**.
A critical part of this phase is making platform and tooling decisions. The roadmap determines whether a platform like [Snowflake](https://www.snowflake.com/en/) fits your business intelligence needs, or whether [Databricks](https://www.databricks.com/) is the better fit for machine learning workloads. These calls should be grounded in the specific use cases identified during the audit, not vendor preference.
> The future-state roadmap translates business objectives into a technical and operational blueprint. It answers the question: "What capabilities do we need to build to hit our revenue, efficiency, and growth targets?"
This blueprint details the target architecture, the required governance framework, and the team structure to support it - a shared plan that aligns everyone from the executive team to individual engineers.
### Pillar 3: The value realization plan
The final pillar turns the strategic blueprint into a step-by-step execution plan. A roadmap that never gets implemented is worthless. This phase focuses on the practical "how" and "when," breaking the future-state vision into sequenced, manageable projects.
This plan covers three operational details:
* **Phased Implementation:** A rollout schedule that prioritizes quick wins to build momentum and prove early ROI, while working through larger foundational projects over time.
* **Talent Development:** The training and hiring needed to close skill gaps identified in the audit, so the team is ready for new technologies and processes.
* **KPI Framework:** Clear metrics that track progress and tie every activity back to business value - the evidence needed to prove the investment's ROI.
This pillar is what turns a **data strategy consultation** into a living playbook rather than a one-time report.
## When should you bring in a data strategy consultant?
Three situations reliably justify the cost: a major cloud or platform migration, an AI initiative sitting on a shaky data foundation, or a data-quality problem that's already undermining decisions. Waiting past any of these points usually costs more than the engagement would have.
### You are planning a major cloud or platform migration
Migrating to a new platform - moving to [Snowflake](https://www.snowflake.com/en/), for example, or modernizing a legacy warehouse - is far more than a simple lift-and-shift. Without a clear strategic roadmap, these projects routinely exceed budget, miss deadlines, and fail to deliver the value they were sold on.
A consultant acts as the architect hired before construction begins. Their job is to make sure the new platform is designed not just for current needs but for scale as AI and other future requirements arrive, and to help you avoid architectural mistakes that lock you into an inefficient system for years.
### You are launching an AI initiative on a weak data foundation
AI and machine learning models are only as good as the data behind them. A common and expensive mistake is investing heavily in AI talent and tools before fixing foundational data issues. If your data is siloed, inconsistent, or untrustworthy, the AI initiative is set up to fail before it starts.
This is exactly the scenario a **data strategy consultant** is built for. They start with a realistic assessment of your data ecosystem:
* **Data Quality Audit:** Identify and quantify the data quality issues that will undermine your models.
* **Pipeline Design:** Design the automated data pipelines your data science team actually needs.
* **Governance for AI:** Establish the processes needed to track data lineage and monitor model accuracy over time.
This preparatory work is what gives an AI investment a realistic shot at ROI.
### Poor data quality is undermining decision-making
If meetings are consumed by debates over whose numbers are right, or executives have stopped trusting the reports in front of them, that's a data integrity crisis, not a technical inconvenience. It leads to flawed strategies, missed opportunities, and wasted resources.
> When trust in data erodes, decision-making reverts to gut instinct, and the investment in analytics tools and talent stops paying off. A consultant is brought in to rebuild that trust by finding the root cause and implementing a durable fix.
They'll help establish a data governance framework, assign clear ownership for key data assets, and put systems in place to keep data accurate and consistent - making reliable data the default rather than the exception. Demand for this kind of work is a real driver of consulting-market growth: the global consulting market is projected to grow from **USD 1.06 trillion** to **USD 1.32 trillion by 2029**, with data specialists representing a meaningful share of that expansion, according to [Expert Network Calls' 2025 consulting industry outlook](https://expertnetworkcalls.com/71/consulting-industry-trends-outlook-2025).
## What does a data strategy consultation actually cost?
Costs track scope, complexity, and the seniority of the team assigned - a well-defined, four-week technology audit costs far less than a twelve-week engagement that also redesigns your governance model and trains your team. Aligning on a pricing model upfront keeps the partnership matched to your budget, timeline, and risk tolerance.
### Common engagement structures
A proposal's price is always tied to a specific engagement model, and each model fits different kinds of projects:
1. **Time & Materials (T&M):** A flexible pay-as-you-go model billed on actual hours worked. It fits projects with undefined scope - initial discovery, or complex problem analysis - but carries the risk of budget overruns if hours aren't closely managed.
2. **Fixed-Price Project:** A set price for a clearly defined scope and deliverable list. It offers budget predictability and suits well-understood projects like a current-state audit or roadmap development. The main risk is **scope creep**: anything outside the original agreement triggers a change order and additional cost.
3. **Retainer:** A set monthly fee that reserves a block of a consultant's time for ongoing advisory work. This fits long-term guidance after the strategy phase - overseeing implementation, or acting as an advisor to a data governance council.
For a closer look at how these models play out in practice, see our guide to [data engineering consulting services](/insights/data-engineering-consulting-services/).
### Expected cost benchmarks
A single price for a **data strategy consultation** doesn't exist, but the bands below, based on provider type, are a reasonable way to benchmark a proposal and spot an outlier.
The table below covers common hourly rates and typical project fees for an engagement spanning **4-8 weeks**.
| Consultant Tier | Typical Hourly Rate (USD) | Typical Project Fee (4-8 Weeks) |
| :--- | :--- | :--- |
| **Independent/Freelance** | $150-$300 | $25,000-$60,000 |
| **Boutique/Specialist Firm** | $250-$450 | $60,000-$150,000 |
| **Global Consulting Firm** | $400-$800+ | $150,000-$500,000+ |
These figures shift with geography, the seniority mix of the team, and how specialized the technical skills required are - a project needing niche MLOps expertise will command a premium over a general assessment.
Note these bands are for high-level strategy engagements, not the hands-on data engineering work that typically follows. Among the 86 firms profiled in the [Data Engineering Companies Index](/insights/data-engineering-consulting-rates-2026/), hourly rates for build-and-implementation work run $45-$250, with a median around $100 - useful context if a strategy proposal quotes $400+/hour for what turns out to be mostly discovery and workshops.
> It helps to reframe this spending. A data strategy consultation isn't a project expense - it's an investment in the organization's decision-making infrastructure, one that should generate ROI well beyond its initial cost through improved efficiency, new revenue streams, and reduced risk.
## What should a vendor evaluation checklist for a data strategy consultant include?
Score every candidate on three axes: platform and tooling expertise, industry-specific experience, and delivery methodology. Request named team bios, real case studies with quantified outcomes, and a documented communication cadence before you sign anything.
This checklist gives you a vendor-agnostic framework for comparing partners on what actually matters. Build these criteria into your Request for Proposal and use them as a scorecard during interviews - the goal is a choice based on demonstrated capability, not a polished pitch.
### Technical expertise and platform fluency
First: can they actually execute the work? A competent data strategy consultant needs deep, demonstrable expertise in the technologies relevant to your current and future needs. Superficial familiarity is a red flag - you need a team with hands-on experience building real solutions.
Probe with specific questions:
* **Platform Certifications:** Do their consultants hold advanced certifications in platforms like [Snowflake](https://www.snowflake.com/en/), [Databricks](https://www.databricks.com/), [AWS](https://aws.amazon.com/), or [Google Cloud](https://cloud.google.com/)? Ask for anonymized proof of the certified experts who'd actually be assigned to your project.
* **Architectural Depth:** Can they articulate the trade-offs between architectural patterns - data mesh versus a data lakehouse, for instance - and apply that thinking to your specific business context?
* **Modern Data Stack Knowledge:** Ask them to detail their experience across the full modern data stack, from ingestion (**Fivetran**, **Airbyte**) and transformation (**dbt**) to BI and visualization (**Tableau**, **Power BI**).
### Industry specialization and contextual understanding
A generic data strategy is a failed data strategy. Your business has its own regulatory pressures, competitive dynamics, and operational complexity, and a consultant needs to understand that context before they can help. A partner with a track record in your industry will move faster and deliver a more relevant roadmap.
Look for evidence of real industry experience:
* **Relevant Case Studies:** Request detailed case studies from your industry - a high-level summary isn't enough. You need the business problem, the solution implemented, and, most importantly, the **quantifiable business outcomes** achieved.
* **Regulatory Knowledge:** How have they handled compliance challenges specific to your field - [HIPAA](https://www.hhs.gov/hipaa/index.html) in healthcare, or [GDPR](https://eur-lex.europa.eu/legal-content/EN/TXT/?uri=CELEX%3A32016R0679) for consumer data?
* **Business Acumen:** Do they understand your business well enough to discuss your challenges using your industry's terminology and KPIs, not just technical jargon?
> A consultant's value isn't just their technical skill - it's their ability to apply it to your specific business problems. A firm that has solved similar challenges for your competitors brings a perspective and a playbook of what actually works in your market.
### Delivery methodology and engagement style
How a consultant works matters as much as what they deliver. Their engagement model and communication style need to fit your team's culture, or you get friction, missed deadlines, and a well-crafted strategy nobody ever implements.
Get clarity on their operational approach:
* **Methodology:** Do they run a rigid waterfall process or a more agile, iterative one? For data strategy, agile is usually the better fit - it lets the plan evolve as discovery surfaces new information.
* **Communication Cadence:** What's their standard protocol - weekly status updates, stakeholder check-ins, executive presentations?
* **Team Composition:** Who's actually doing the work? Insist on meeting the core team assigned to your project, not just the senior partner who closed the deal.
Scoring each potential partner against these criteria systematically turns a subjective choice into a data-driven decision. For a more structured version of this process, see our guide on [how to choose a data engineering company](/how-to-choose-data-engineering-company/).
## What red flags signal a bad data strategy partner?
Watch for four warning signs: heavy buzzword use without concrete specifics, a rigid one-size-fits-all methodology, vague deliverables, and a bait-and-switch where the senior team that pitched you disappears after the contract is signed. Each one predicts a wasted engagement.
Selecting the wrong partner is more than a waste of money - it's a setback that can derail your objectives for years. A polished sales presentation can mask a lack of substance, so approach these conversations with healthy skepticism.
### They overuse buzzwords
Be wary of consultants who lean on jargon - "AI-powered synergy," "digital transformation frameworks" - without connecting it to a concrete action or a measurable outcome for your business. It's often a way to sound impressive while hiding a shallow understanding of the actual work. A good consultant simplifies complex ideas instead of dressing them up.
> If a consultant can't explain their value without industry buzzwords, they're selling a trend, not a solution. Their job is to solve *your* specific problems, not to demonstrate their vocabulary.
**Example:** A vendor proposes an "AI-driven data fabric solution" but goes vague when asked which specific data sources it integrates, what business questions it answers, or how it improves a metric your team actually tracks.
### They pitch a one-size-fits-all solution
If a potential partner presents a rigid, pre-packaged methodology as the *only* approach, that's a problem. Every company has its own mix of data systems, business goals, and internal culture. A good **data strategy consultation** gets tailored to your reality, not forced into a template.
This inflexibility usually means they care more about scaling their internal process than about understanding your specific problem. The best partners listen first and adapt their approach second.
### Their deliverables are vague
A strong proposal is specific about what you'll actually receive. Promises like "enhanced data insights" or "a strategic roadmap" without further detail are a red flag.
* **Look for:** A detailed list of tangible artifacts - a Current-State Assessment with gap analysis, a Future-State Architecture Diagram, a phased implementation plan with clear milestones and timelines.
* **Ask about:** How success gets measured. A competent partner wants to collaborate on defining KPIs that tie the project directly to business value.
### The bait-and-switch tactic
This is common and damaging. During the sales process you meet the firm's senior experts, and their strategic vision impresses you. Once the contract is signed, they vanish, and the project gets handed to a junior team you've never met.
To prevent it, insist on meeting the actual people who'll be working on your project *before* signing. Get their bios and, more importantly, get their specific roles and time commitments written into the Statement of Work. A successful partnership runs on that kind of transparency - the same principle covered in our guide to [data engineering partner selection](/insights/data-engineering-partner-selection/).
## Common questions about data strategy consultation
### How long does a data strategy consultation take?
Every engagement is different, but a comprehensive **data strategy consultation** typically falls in the **6 to 12-week** range - enough time to deliver real value without turning into an open-ended project.
A typical timeline breaks down as:
* **Weeks 1-3 (Discovery & Assessment):** A deep dive into your current data systems, workflows, and team skills to establish an accurate baseline.
* **Weeks 4-8 (Future-State Design):** Collaborative design through workshops and working sessions to define the target architecture and build the roadmap.
* **Weeks 9-12 (Finalization & Handoff):** Findings get documented in a detailed implementation plan, including financial models (TCO/ROI), and the engagement wraps with a presentation of the playbook to leadership.
### What is the difference between data strategy and data governance?
This distinction matters. Think of it as building a city.
**Data strategy** is the master blueprint - it answers the "what" and "why." It decides which districts get built (sales analytics, operational dashboards), explains why they matter to the city's growth, and shows how they connect to the overall vision. It's the high-level plan for using data to hit business objectives.
**Data governance**, by contrast, is the building codes, zoning laws, and inspectors - the "how." It sets the rules, standards, and controls that keep every structure safe, reliable, and functioning correctly. Governance is what makes your data accurate, secure, and trustworthy. See our [data governance strategies guide](/insights/data-governance-strategies/) for how to build that layer, following practices similar to what [Snowflake's access control model](https://docs.snowflake.com/en/user-guide/security-access-control-overview) and [Databricks Unity Catalog](https://docs.databricks.com/en/data-governance/unity-catalog/index.html) are both built to enforce.
You can have a brilliant strategy, but without a solid governance foundation underneath it, it will eventually fail.
### Why can't our internal team build its own data strategy?
Your internal team has business knowledge you can't buy. But an external consultant brings capabilities that are hard to replicate in-house. An effective **data strategy consultation** combines your team's institutional knowledge with an outside expert's broader perspective - see our comparison of [data engineering consulting vs. in-house teams](/insights/data-engineering-consulting-vs-in-house-team/) for how that trade-off plays out in practice.
Consultants offer three specific advantages:
1. **Cross-Industry Experience:** They've seen what works - and what doesn't - at other companies, and bring proven solutions that help you skip common, costly mistakes.
2. **Dedicated Focus:** Your internal team is juggling daily operational work. A consultant's only job is delivering a high-quality strategy on schedule.
3. **Objective Neutrality:** Every organization carries internal politics and biases. An outside partner can challenge long-held assumptions and build consensus across departments without being tangled in internal dynamics.
> The point of a consultation isn't to replace your team - it's to strengthen it. The best outcome combines an expert's broad experience with your team's deep business understanding, producing a better strategy in a fraction of the time it would take to build alone.
## Turning the strategy into a vendor decision
A data strategy consultation is only worth the cost if it ends in a roadmap someone actually executes. Use the three-pillar deliverable structure to judge a proposal, the cost bands above to sanity-check the price, and the red-flag list to catch a mismatched partner before you sign. If you're ready to compare firms directly, browse vetted profiles in the [Data Engineering Companies Index](/data-engineering-consulting-firms/).
---
## Data Warehouse vs. Data Lake: A Practical Decision Guide
Source: https://dataengineeringcompanies.com/insights/data-warehouse-vs-data-lake/
Published: 2025-12-14T07:05:06.99046+00:00
Description: Choosing between a data warehouse vs data lake? This guide cuts through the noise with practical comparisons of architecture, cost, and real-world use cases.
A data warehouse stores structured, pre-processed data on a fixed schema, optimized for fast, reliable business intelligence. A data lake stores raw data in its native format at low cost, trading structure for the flexibility that data science and machine learning work need. Most organizations that scale past a certain size end up running both, which is why the data lakehouse - a hybrid combining warehouse governance with lake economics - has become the default target architecture for new builds.
This guide compares the two on architecture, cost, and performance, then maps common use cases like BI dashboards, fraud detection, and genomic research to the right platform. It also covers the data lakehouse, the model most vendors have converged on. Sixty-eight of the 86 firms in the [Data Engineering Companies Index](/data-engineering-consulting-firms/) list analytics and BI work among their capabilities, and 64 list ML/AI work - roughly the same warehouse-versus-lake split you're deciding between, which is one reason this choice comes up in nearly every vendor conversation.
What this guide covers:
* **The core architectural difference** between schema-on-write (warehouse) and schema-on-read (lake).
* **Real cost and performance trade-offs**, not just the headline storage price.
* **Which workloads fit which platform**, mapped to concrete use cases.
* **The data lakehouse**, and why Snowflake and Databricks have both moved toward it.
## How do you choose between a data warehouse and a data lake?
The choice isn't about which platform is better, it's about which is the correct tool for the job. A warehouse is like a meticulously organized library where data is cataloged and placed in a precise spot for quick retrieval - essential for BI teams who need consistent, reliable answers for operational reporting.
A data lake is a reservoir, ingesting data from countless sources in its raw, unfiltered state. This suits data scientists and ML engineers who need original, untouched material to build and validate models, where the value of the data is often discovered through exploration rather than known in advance. This distinction is central to building an effective [modern data stack](/insights/modern-data-stack/).
### At a Glance: Key Distinctions
This table summarizes where each architecture fits.
| Attribute | Data Warehouse | Data Lake |
| :--- | :--- | :--- |
| **Primary Users** | Business analysts, decision-makers | Data scientists, ML engineers, researchers |
| **Data Structure** | Structured, processed (schema-on-write) | Raw, semi-structured, unstructured (schema-on-read) |
| **Processing Model** | Schema enforced on ingestion (ETL) | Schema applied during analysis (ELT) |
| **Core Use Case** | Business intelligence, analytics, reporting | Data exploration, ML/AI, predictive analytics |
| **Agility** | Less flexible; optimized for query speed | Highly flexible and scalable |
Each system serves a different audience and outcome. One prioritizes order and speed for known questions; the other prioritizes flexibility for discovering unknown ones.
The market has shifted a lot of new spend toward object storage, because a schema-on-read model cuts raw storage costs by a wide margin compared to a managed warehouse. But that flexibility comes with a real cost of its own: a large share of early data lake deployments turned into "data swamps" - ungoverned, undocumented collections of files nobody trusted enough to use, because teams skipped governance to move fast. That failure pattern is what pushed vendors toward the data lakehouse, a hybrid model built to combine the strengths of both architectures.
## What are the core architectural differences between a warehouse and a lake?

A warehouse forces structure onto data before it's stored (schema-on-write); a lake stores data raw and applies structure only when it's queried (schema-on-read). That single design choice cascades into how each system handles ETL, storage format, and who can use the data without an engineer's help.
A traditional data warehouse is engineered as a high-performance relational database, built on a schema-on-write model that forces structure onto data as it's ingested via an Extract, Transform, Load (ETL) pipeline. This upfront structuring is a deliberate trade-off: it takes real planning, but it delivers fast, reliable queries, which is why it's been the backbone of business intelligence for decades.
### What makes up a data warehouse's architecture?
In a warehouse, the schema acts as a strict blueprint, forcing incoming information into a predefined model before it's stored. This guarantees that when an analyst runs a report, the data is already clean, consistent, and optimized for queries.
Key architectural components include:
* **ETL Pipelines:** Data is transformed *before* being written to the warehouse. This is where data quality rules and business logic get enforced.
* **Columnar Storage:** Data is stored by columns instead of rows, which speeds up analytical queries that typically only touch a subset of columns from a large table.
* **Relational Database Engine:** A SQL-based engine tuned for complex joins and aggregations on structured data keeps dashboards and reports responsive.
> The core promise of a data warehouse is predictable performance. By investing in structure on the way in (schema-on-write), you cut computational work on the way out, which is how you get sub-second query responses for reporting.
### What makes up a data lake's architecture?
A data lake is built for flexibility using a schema-on-read model: data is ingested in its raw, native format, and structure is applied only when the data is queried. The goal is to capture everything first and decide how to use it later.
This suits exploratory analysis and machine learning, where access to raw, unfiltered data matters. The underlying technology is fundamentally different:
* **Object Storage:** Data lakes run on scalable, low-cost object storage systems like [Amazon S3](https://aws.amazon.com/s3/) or [Azure Blob Storage](https://azure.microsoft.com/en-us/products/storage/blobs), which can hold any file type - CSV, JSON, images, audio.
* **Decoupled Compute and Storage:** The storage layer is separate from the compute layer, so each can scale independently and you can point different engines, like [Spark](https://spark.apache.org/) or Presto, at the same data for different jobs.
* **Open File Formats:** Data is stored in open-source columnar formats like Parquet or ORC, which give you the speed benefits of columnar storage without vendor lock-in.
The schema-on-read model shifts the work from ingestion to analysis - data loads "as-is," and it's the data scientist or analyst's job to apply a schema at query time. That's a lot of agility, but it demands more technical skill from the people using it. Understanding this trade-off is the first step in the data warehouse vs. data lake decision.
## What do data warehouses and data lakes actually cost to run?
Storage price is the smallest part of the cost comparison. A data lake's raw storage costs far less than a warehouse's, but the engineering, governance, and compute needed to make that raw data usable often erase the savings once you look at total cost of ownership (TCO).
### What's included in the total cost of ownership?
With a data warehouse, costs are usually bundled into a predictable package: storage, query compute, and platform maintenance. That's straightforward to budget for well-defined BI workloads.
Data lakes have a more fragmented cost structure. Raw storage is cheap, but you need to account for the engineering effort to build pipelines, enforce governance, and manage compute clusters - and those operational costs can eat the storage savings.
A complete financial picture includes:
* **Storage Costs:** For raw data volume, lakes have a clear advantage.
* **Compute Costs:** Warehouses optimize compute for structured SQL. Lakes need powerful, often costly compute engines like Spark for large-scale processing.
* **Engineering and Maintenance:** Lakes demand real data engineering overhead for pipeline management, quality checks, and performance tuning.
* **Governance and Security:** Building governance and security into a data lake is a resource-intensive project, not something you get out of the box.
### How does performance differ between the two workloads?
Performance isn't about which platform is "faster" overall, it's about which is faster for a specific job. A warehouse is a Formula 1 car, unbeatable on a specific track, while a lake is a versatile, all-terrain vehicle.
A data warehouse is engineered for one job: sub-second query responses for business intelligence. Its schema-on-write model, columnar storage, and tuned SQL engines all point toward answering structured analytical questions fast. Platforms like [Snowflake](https://www.snowflake.com/) cache results and run complex joins across billions of rows to keep dashboards feeling interactive.
> For BI and reporting, warehouse performance isn't negotiable. When an executive needs to drill into quarterly sales figures, the system has to answer instantly. The upfront structuring is the price paid for that speed.
A data lake, by contrast, is built for the parallel processing that data science and machine learning need. It handles huge volumes of raw, unstructured data that would overwhelm a traditional warehouse. Schema-on-read gives data scientists room to apply different schemas on the fly and run exploratory analysis without a rigid structure getting in the way.
Platforms like [Databricks](https://www.databricks.com/), built on Apache Spark, are designed to spread large computational jobs across big clusters - useful for training an ML model on petabytes of image data or running complex simulations, where raw throughput matters more than sub-second latency.
The trade-off is real: object storage costs a fraction of managed warehouse storage per terabyte, but that price gap doesn't account for compute. Warehouses answer structured queries dramatically faster because their SQL engines are purpose-built for that one job, while a lake's flexibility means more of the performance burden falls on whichever compute engine you point at it. Organizations that tried to run both BI and ML workloads on a warehouse alone have run into real budget problems chasing performance the architecture wasn't built for - part of why hybrid, lakehouse-style platforms have picked up so much of the market.
## Which workloads fit a warehouse, and which fit a lake?
Match the architecture to the job, not the other way around. If you're powering executive dashboards that need instant, reliable answers, a warehouse is the right call. If you're enabling data scientists to explore raw data for a model that doesn't exist yet, a lake is.

The flowchart shows the intended business outcome, whether high-speed BI or flexible AI development, as the main fork in the road that points you to the right architecture.
### When should you choose a data warehouse?
A data warehouse is the right choice when speed, structure, and reliability aren't negotiable. It's the system of record for critical operational and strategic reporting - the schema-on-write model guarantees that every query runs against clean, validated, business-ready data.
Classic warehouse scenarios include:
* **Financial Reporting:** For quarter-end closing, regulatory filings, and shareholder reports, data has to be structured, aggregated, and auditable. A warehouse gives you a single source of truth.
* **Sales Analytics and Performance Dashboards:** Sales leaders need immediate answers on quota attainment, pipeline health, and regional performance - a warehouse is built for the sub-second query responses that interactive, drill-down analysis needs.
* **Retail Inventory Management:** Effective stock management and supply chain optimization depend on clean transactional data, which a warehouse is built to process and analyze efficiently.
> Rationale: These workloads run predictable queries against well-understood, structured datasets, repeatedly. The upfront investment in defining a schema and building ETL pipelines pays off in query performance and data trustworthiness.
### When is a data lake the right fit?
A data lake is the platform of choice when the priority is flexibility, scale, and discovering insights you haven't defined yet. It's built to handle data variety and volume, which makes it the foundation for advanced analytics, machine learning, and any workload involving raw or semi-structured data. Schema-on-read lets analysts and data scientists explore data without a predefined model getting in the way.
A data lake earns its place in these situations:
* **Predictive Maintenance with IoT Data:** Terabytes of sensor data - logs, metrics, vibration readings - get ingested into a data lake, where data scientists build ML models to predict equipment failure.
* **Customer Sentiment Analysis:** Analyzing unstructured text from social media, product reviews, and support chats needs a repository that can store it all in its native format for natural language processing (NLP).
* **Genomic Research:** Storing petabytes of raw genomic sequences needs the affordable, scalable storage and parallel processing a data lake provides.
> Rationale: In exploratory, ML-driven workloads, preserving raw, untouched data matters most. A data lake's ability to store any data in its native format gives data scientists room to experiment, iterate, and discover patterns that a rigid warehouse schema would have hidden or destroyed.
### Which architecture fits which use case?
This table maps common business scenarios to the recommended architecture, to translate a business need into a technical starting point.
| Use Case | Primary Data Type | Recommended Architecture | Key Rationale |
| :--- | :--- | :--- | :--- |
| **Executive BI Dashboards** | Structured (Sales, Finance) | **Data Warehouse** (e.g., Snowflake, BigQuery) | Needs sub-second query performance and consistent data for trusted reporting. |
| **Customer 360 Analytics** | Mixed (CRM, Weblogs, Social) | **Data Lakehouse** (e.g., Databricks) | Blends structured customer data with unstructured behavioral data for a complete view. |
| **Fraud Detection** | Semi-structured (Transactions, Logs) | **Data Lake** or **Lakehouse** | Needs real-time analysis of massive, streaming datasets to spot anomalous patterns. |
| **Product Recommendation Engine** | Unstructured (Clickstream, User Behavior) | **Data Lake** | The model needs raw, granular user interaction data to train effectively. |
| **Supply Chain Optimization** | Structured (ERP, Logistics Data) | **Data Warehouse** | Relies on querying structured, historical data to model and forecast logistics. |
| **Scientific Research (Genomics)** | Unstructured (Sequence Files, Images) | **Data Lake** | The priority is low-cost storage for petabyte-scale raw data and flexible, large-scale compute. |
The pattern here is clear: the more structured and operational the need, the better a fit the data warehouse. The more exploratory and data-science-driven the goal, the more you lean toward a data lake or the hybrid lakehouse. Define the business problem, the nature of the data, and who's using it, and the right architectural path gets a lot clearer.
## What is a data lakehouse, and why did it emerge?

A data lakehouse adds a metadata and governance layer on top of a data lake's cheap object storage, so it can deliver warehouse-style performance and governance without a separate warehouse system. It emerged because the old binary choice - structured but rigid warehouse, or flexible but ungoverned lake - created real friction between BI teams and data scientists.
The goal is a single, unified platform for all data workloads, from BI reporting to AI model training. The lakehouse is a practical engineering answer to that friction: it cuts data duplication, simplifies architecture, and establishes a single source of truth.
### What technology powers the lakehouse?
A lakehouse works by putting a metadata and governance layer directly on top of a data lake's object storage. Open table formats are the core technology behind that layer.
These formats bring warehouse-like reliability to the lake:
* **[Apache Iceberg](https://iceberg.apache.org/):** Built for massive analytic datasets, Iceberg provides schema evolution, time travel (querying historical data versions), and partition evolution without rewriting entire tables.
* **[Delta Lake](https://delta.io/):** This open format brings ACID transactions (atomicity, consistency, isolation, durability) to big data workloads, so multiple users can write to the lake concurrently without corrupting data.
These formats add database functionality to data lakes, enabling data quality and schema enforcement on low-cost object storage - a capability that used to be exclusive to data warehouses. For a deeper dive, see our guide on [what lakehouse architecture is](/insights/what-is-lakehouse-architecture/).
> The lakehouse model changes the equation by bringing structure to the lake, instead of moving data to a separate structured system. It enables ACID transactions, schema enforcement, and versioning directly on open file formats, delivering warehouse performance on lake economics.
### How are Snowflake and Databricks approaching the lakehouse?
Major cloud data platforms have moved hard into the lakehouse model, because siloed data systems don't hold up for modern businesses.
**Databricks** built its platform around its own open format, Delta Lake, positioning itself as a [pure-play lakehouse](https://www.databricks.com/glossary/data-lakehouse). It's strong at unifying data engineering, data science, and BI, which makes it a solid choice for companies with heavy AI and ML needs.
**Snowflake** has adapted its [cloud data platform](https://docs.snowflake.com/en/user-guide/warehouses-overview) to incorporate lakehouse principles. With Snowpark and support for unstructured data via external tables in formats like Iceberg, Snowflake now lets users run complex data science workloads alongside core BI and analytics inside its governed ecosystem.
This is a market response to a real problem: warehouses get substantially more expensive when they're asked to manage the unstructured data that now makes up most of what enterprises store. That pressure is a major factor behind the lakehouse market's growth, [projected to climb from $14 billion in 2026 to $112.6 billion by 2035](https://www.fortunebusinessinsights.com/data-lake-market-108761). Hybrid systems address the data swamp problem by pairing lake economics with warehouse-style governance, which is the point of the architecture in the first place.
## What is the difference between a data warehouse and a database?
A database is built for OLTP (Online Transaction Processing) - it runs day-to-day operations like processing a sale or updating inventory in real time. A data warehouse is built for OLAP (Online Analytical Processing) - it stores historical data for reporting and trend analysis. One records what's happening now; the other explains what happened over time.
The architectural split runs deeper than purpose. Databases typically use row-oriented storage and a normalized schema (often Third Normal Form) to keep transactions fast and consistent. Data warehouses use columnar storage - the same principle a lakehouse's open table formats build on - paired with a denormalized model like a star schema, trading some redundancy for faster analytical queries across millions of rows.
## Frequently Asked Questions
The data lake versus data warehouse decision raises practical implementation questions. Here are direct answers to the most common ones.
### How Do You Stop a Data Lake from Becoming a Data Swamp?
A "data swamp" is a data lake that has devolved into a repository of ungoverned, undocumented, and untrustworthy data, which makes it useless. Preventing that means putting governance in place from day one.
Practical steps include:
* **Implement a Data Catalog:** A catalog scans and indexes datasets automatically, capturing metadata like source, owner, and refresh frequency so data is discoverable and understandable.
* **Assign Clear Data Ownership:** Every dataset in the lake needs a designated owner responsible for its quality, documentation, and access rights.
* **Enforce Metadata Standards:** Require all incoming data to be tagged with essential metadata. Raw data without context is just noise.
* **Automate Data Quality Checks:** Set up automated pipelines to scan data on arrival, flagging anomalies, missing values, or formatting errors before they contaminate the lake.
> Governance isn't a restrictive chore, it's what makes a data lake usable. Strong governance builds trust and drives adoption; its absence guarantees failure.
### Which Is Better for Real-Time Analytics?
The answer depends on what you mean by "real-time."
For operational dashboards that need instant answers to business questions (a live sales tracker, for example), the data warehouse remains the better choice. Its architecture is built to serve structured data with very low latency for SQL queries.
For analyzing massive, high-velocity streams of semi-structured data, like IoT sensor feeds or website clickstreams, a data lake or lakehouse is the right architecture. These systems are built to handle constant ingestion and processing with engines like [Apache Spark Streaming](https://spark.apache.org/streaming/) or [Flink](https://flink.apache.org/). The goal isn't sub-second SQL response, it's real-time pattern detection and anomaly identification within the data stream.
### Can a Small Business Actually Use a Data Lake?
Yes, provided they start with a focused approach. A small business doesn't need a petabyte-scale implementation. Cloud platforms like [Amazon S3](https://aws.amazon.com/s3/) or [Azure Data Lake Storage Gen2](https://azure.microsoft.com/en-us/products/storage/data-lake-storage) let businesses start small and pay only for what they use.
A small business can use a data lake to:
* Centralize raw customer data from websites, CRMs, and social media.
* Store unstructured feedback from support tickets for future sentiment analysis.
* Archive historical transactional data cost-effectively without upfront formatting.
The key is to start with one specific, high-value problem and expand as needs evolve, rather than trying to build an all-encompassing lake from day one.
### How Does Governance Differ Between a Warehouse and a Lake?
The governance models are fundamentally different.
In a data warehouse, governance is centralized and preventative. Data is structured before it's written (schema-on-write), so quality checks, transformations, and access controls get applied during the ETL process. By the time data is queryable, it's already been vetted.
In a data lake, governance is more decentralized and reactive. Because raw data is ingested (schema-on-read), governance policies have to be applied after the fact, using a different set of tools and processes.
| Governance Aspect | Data Warehouse Approach | Data Lake Approach |
| :--- | :--- | :--- |
| **Data Quality** | Enforced at ingestion via ETL | Monitored continuously with automated checks |
| **Access Control** | Table, row, and column-level security | File and object-level permissions, often tag-based |
| **Schema Management** | Centrally defined and strictly enforced | Schema is discovered and applied at query time |
| **Data Lineage** | Tracked through defined ETL pipelines | More complex; requires specialized tools to trace data flows |
The lakehouse architecture addresses this by bringing warehouse-style governance features, like ACID transactions and schema enforcement, directly to the data lake, which makes for a more unified and manageable model.
### Is the Data Warehouse Obsolete?
No, but its role has changed. The traditional on-premise data warehouse is being replaced by scalable cloud platforms. For its core job, powering high-performance BI and reporting on structured data, the modern data warehouse remains the best tool.
Early predictions that data lakes would replace warehouses turned out wrong; they solve different problems. Today, the warehouse operates as one component within a broader data ecosystem, often alongside a data lake or as part of a lakehouse. It's the clean, reliable last mile for delivering curated, business-critical insights.
## Putting the architecture decision into practice
The warehouse-versus-lake decision isn't permanent, and it isn't binary for most organizations past a certain size - plenty run a warehouse for BI, a lake for ML, and a lakehouse to avoid maintaining both long-term. If you're scoping a warehouse build, [how to build a data warehouse](/insights/build-a-data-warehouse/) and [star schema data modeling](/insights/snowflake-schema-and-star-schema/) cover the design side in more depth. Once you know which architecture you're leaning toward, [Snowflake vs. Databricks](/snowflake-vs-databricks/) is the next comparison worth reading before you start vetting vendors.
---
## A Practical Guide to Databricks Delta Lake
Source: https://dataengineeringcompanies.com/insights/databricks-delta-lake/
Published: 2026-01-31T09:55:35.924433+00:00
Description: How Databricks Delta Lake adds ACID transactions, schema enforcement, and time travel to data lake storage, plus the architecture, features, and costs to know before adopting it.
Databricks Delta Lake is an open-source storage layer that adds ACID transactions, schema enforcement, and version history to data already sitting in cloud object storage. It runs directly on top of Amazon S3, Azure Data Lake Storage, or Google Cloud Storage - no migration required - and turns a folder of Parquet files into a table a BI dashboard or ML pipeline can actually trust.
## What Is Databricks Delta Lake?
Delta Lake is an open-format storage layer, created by Databricks and now governed as an independent [Linux Foundation project](https://www.linuxfoundation.org/press/press-release/the-delta-lake-project-turns-to-linux-foundation-to-become-the-open-standard-for-data-lakes), that adds database-style reliability directly on top of Parquet files in cloud storage: ACID transactions, schema checks, and a full change history, with no proprietary lock-in.
A traditional data lake is like a warehouse with no inventory system. Data from multiple sources is continuously dropped off and piled up, creating disorganized stacks. When an analytics team needs specific information, they must sift through chaotic, unreliable data, unsure of its completeness or version. This operational reality leads to untrustworthy reports and stalled AI projects.
Delta Lake functions as the modern inventory management and quality control system for this warehouse. Instead of requiring a data migration, it layers directly over existing cloud storage, organizing files and tracking every change. It delivers the transactional integrity of a database at the scale of a data lake.
### Turning Unreliable Data Swamps into Assets
At its core, Delta Lake was engineered to solve data unreliability at scale. Without it, data teams face recurring operational issues that introduce real business risk:
* **Corrupted Data Pipelines:** A single failed job can leave tables in a partially updated state, compromising all downstream reports and models.
* **Inaccurate BI Reports:** Business leaders may make decisions based on dashboards pulling from inconsistent or stale data, leading to flawed strategies.
* **Failed AI Model Training:** Machine learning models are sensitive to data quality. Training on incomplete or dirty data produces unreliable predictions, wasting time and compute.
Delta Lake addresses these challenges by implementing **ACID transactions** for data lakes, a feature previously exclusive to databases. Databricks open-sourced the project in 2019 and handed governance to the Linux Foundation later that year, a move meant to make the format usable well beyond Databricks' own customer base. Its central innovation is an append-only transaction log that records every change, ensuring data integrity and consistency.
For a CIO or head of data, the value proposition is direct: Delta Lake turns an unpredictable "data swamp" into a reliable, high-performance asset, so the data feeding critical analytics and AI initiatives is consistently trustworthy.
This reliability is what makes [lakehouse architecture](/insights/what-is-lakehouse-architecture/) possible - a model that combines the flexibility of a data lake with the guarantees of a data warehouse.
## What Is the Core Architecture of Delta Lake?
Delta Lake's reliability comes from three components working together: a transaction log that tracks every change, open Parquet files that hold the data, and a compute engine (typically Spark) that reads both. None of it is magic - it's a straightforward design that happens to solve a hard problem.
### The Transaction Log: Your Data's Single Source of Truth
The core of Delta Lake is the **transaction log**. This is a directory named `_delta_log` located alongside the data files in cloud object storage like Amazon S3 or Azure Blob Storage. It serves as an immutable ledger for the data table.
Every change - insert, update, delete, or merge - is recorded in this log as a discrete, atomic "commit" file. The log is the single source of truth for the table's state at any point in time. This mechanism enables **ACID transactions** (Atomicity, Consistency, Isolation, and Durability) on top of cloud storage, which was not originally built for that kind of workload.
When a query is initiated, the engine first consults the transaction log to identify which data files constitute the latest, correct version of the table. This eliminates issues like reading partially written data from a failed job, since only completed transactions are ever included in the official table version.
### Why Delta Lake Uses Open Formats Instead of a Proprietary One
A common misconception is that Delta Lake is another proprietary file format designed for vendor lock-in. In reality, its architecture builds on top of existing open-source formats: data is still stored in standard, compressed **Apache Parquet files**, and Delta Lake acts as a management layer, using the transaction log to track which Parquet files to read for a given query.
This provides two advantages: the query performance of a columnar format like Parquet combined with the transactional reliability of a database. It also avoids hard lock-in - the underlying data remains a collection of Parquet files that other tools can read directly.
By pairing an immutable transaction log with standard Parquet files, Delta Lake keeps data both reliable and open. Transaction history and metadata stay separate from the raw data, adding structure without hiding it inside a closed system.
### How the Compute Engine Uses the Log and the Files
The third piece is deep integration with a compute engine, most notably **Apache Spark**. The log and the Parquet files provide the structural blueprint; the compute engine does the actual work. When a command runs, Spark reads the transaction log, determines the table's current state, and executes the query across the cluster.
For instance, Time Travel works by having Spark read an older version of the transaction log to reconstruct a prior table state. Schema enforcement works by having Spark validate incoming data against the schema defined in the log before writing a new file. Spark provides the processing power; Delta Lake supplies the guardrails.
### Core Components of Delta Lake Architecture
| Component | Technical Function | Business Impact |
| :--- | :--- | :--- |
| **Transaction Log (_delta_log)** | Records every data change as an ordered, atomic commit in JSON and Parquet files. | Prevents corrupted pipelines, leading to trustworthy BI reports and reliable AI models. |
| **Data Files (Parquet)** | Stores the actual table data in an open-source, columnar format for efficient compression and querying. | Avoids vendor lock-in and keeps the cost-efficiency of standard cloud storage, reducing total cost of ownership. |
| **Compute Engine (Spark)** | Reads the transaction log to determine the current state of the data and executes all read/write operations. | Powers features like Time Travel and schema enforcement, improving governance and reducing debugging time. |
Together, these three components bring structure and reliability to the data lake without sacrificing its flexibility or cost profile.
## What Features Does Delta Lake Add on Top of the Architecture?
The architecture provides the foundation; the practical features solve the day-to-day problems data teams actually run into - undoing bad writes, catching bad schemas, running row-level updates, and keeping queries fast as tables grow.
The diagram below shows the transaction log acting as the single source of truth, directing the compute engine to the correct version of the data files. No operation proceeds without the log's validation - it works like an air traffic controller for data, keeping every read and write safe, orderly, and consistent.

### Time Travel: Your Data's Undo Button
**Time Travel** provides version control for data tables. Because every change is recorded in the `_delta_log`, you can query or restore a table to any previous state.
This is a critical operational feature. If a production ETL job fails and corrupts a table, an engineer can roll back to the version just before the job started, resolving the issue in minutes instead of hours.
Time Travel turns a potential data crisis into a manageable operational task: an instant recovery plan for failed jobs, a tool for auditing historical changes, and a way to reproduce ML models on the exact data they were trained on. It gives teams a safety net to move fast without risking irreversible data corruption.
### Schema Enforcement and Evolution
A common failure point in data pipelines is when unstructured data enters a clean table, breaking downstream processes. Delta Lake prevents this with **schema enforcement**: by default, it rejects any write operation that does not match the table's schema. If a process attempts to write a string into an integer column, Delta Lake blocks the write, catching data quality issues at the source instead of hours later in debugging.
For planned changes, **schema evolution** allows new columns to be added to a table's schema without downtime, so the platform can adapt as data sources and business requirements change.
* **Enforcement:** Protects data integrity by ensuring all records conform to the defined structure.
* **Evolution:** Lets new columns be added without costly downtime.
### Row-Level SQL: MERGE, UPDATE, and DELETE
Performing row-level updates or deletes in a traditional data lake was historically complex and expensive, often requiring a rewrite of entire partitions. Delta Lake brings standard SQL commands like **MERGE**, **UPDATE**, and **DELETE** to the lakehouse, which enables several concrete use cases:
1. **Change Data Capture (CDC):** The `MERGE` command efficiently applies a stream of inserts, updates, and deletes from a source database, simplifying table synchronization.
2. **GDPR and CCPA Compliance:** A "right to be forgotten" request can be fulfilled with a targeted `DELETE` statement, removing specific records from petabyte-scale tables.
3. **Data Corrections:** Bad records can be fixed with a targeted `UPDATE` instead of rebuilding the entire dataset.
### Built-in Performance Boosts
Delta Lake includes automated optimization features to maintain query performance as tables grow. The two most important are **compaction** (via the `OPTIMIZE` command) and **Z-Ordering**.
Streaming data ingestion can create thousands of small files, which degrades query performance. Compaction merges these small files into larger, optimally sized ones, improving read speeds.
**Z-Ordering** is a data-skipping technique that physically co-locates related information within data files. By clustering data on frequently queried columns, it lets the query engine skip large amounts of irrelevant data - faster queries for BI dashboards and ad-hoc analysis, and lower compute costs.
## Does Delta Lake Actually Improve Performance and Cut Costs?
Yes, in the cases Databricks and its customers have published, largely because compaction and Z-Ordering reduce how much data a query has to scan. Less data scanned means faster queries and a smaller compute bill - the mechanism is straightforward even if the size of the savings varies by workload.
### How Performance Optimization Cuts Costs
Every query against a data lake incurs compute costs; the longer a query runs and the more data it scans, the higher the cost. **Z-Ordering** acts as an index for data in cloud storage - by physically grouping related information, it lets the query engine bypass large blocks of irrelevant data, similar to searching an organized library instead of a disorganized one.
The `OPTIMIZE` command addresses the "small file problem" common in streaming pipelines by compacting many small files into fewer, larger ones. That reduces metadata overhead and improves read performance, which lowers both query time and compute cost.
Mastercard is a documented example: according to Databricks' own [customer case-study roundup](https://www.databricks.com/blog/data-intelligence-action-100-data-and-ai-use-cases-databricks-customers), Mastercard implemented Delta Lake and reported an **80% reduction in query times** and **70% less storage space**, which supported real-time processing of credit-card transaction data for machine learning at scale. By layering Delta's transaction log over their existing Parquet files, they replaced brittle ETL jobs with reliable, versioned tables and automated the small-file compaction that had been slowing queries down.
### Calculating the Total Cost of Ownership
A full analysis has to include Total Cost of Ownership (TCO), not just compute and storage - engineering time spent debugging broken pipelines is a real cost. Delta Lake's ACID transactions keep data in a consistent state, so a job either completes successfully or fails cleanly without corrupting what's already there. That has a direct operational effect:
* **Reduced Engineering Hours:** Data engineers shift from firefighting broken pipelines to building new, value-generating products.
* **Faster Time-to-Market:** A reliable data foundation lets teams ship new analytics and ML models more quickly.
* **Higher Team Productivity:** Analysts and data scientists can trust the data, which speeds up decision-making.
The TCO case for Delta Lake rests as much on reclaimed engineering time and fewer stalled pipelines as it does on raw infrastructure savings.
## How Does Delta Lake Compare to Snowflake?
The comparison usually comes down to one architectural choice: Delta Lake separates storage (your cloud bucket, open Parquet format) from compute, while Snowflake bundles both into a proprietary, managed system. Pick based on whether direct file access and multi-engine flexibility matter more to you than a fully managed, walled-garden experience.
The primary distinction is in data formats and storage. Delta Lake data resides in the customer's own cloud object storage (e.g., Amazon S3) in the open-standard Parquet format, with the Delta protocol providing structure and reliability on top. [Snowflake](https://www.snowflake.com/), in contrast, integrates storage and compute into a proprietary, highly optimized system - a smooth user experience, but one that abstracts away direct control over the underlying files.
### Architectural Trade-Offs
The Databricks approach favors an open ecosystem and direct ownership of raw data, which matters for AI and machine learning workloads where direct file access in open formats is often a requirement for model training. Delta tables can be read by a variety of engines, which is a real advantage for organizations that want to avoid single-vendor dependency.
Snowflake's architecture behaves more like a cloud-native data warehouse, optimized for high-performance BI and SQL analytics with minimal administrative overhead. That convenience and query speed are genuine strengths; the trade-off is less data portability and less direct access than Delta Lake provides.
Delta Lake underpins a large share of [Databricks'](https://www.databricks.com/) business: the company crossed a [$4 billion annual revenue run-rate in Q2 2025, with its AI products alone surpassing a $1 billion run-rate](https://www.databricks.com/company/newsroom/press-releases/databricks-surpasses-4b-revenue-run-rate-exceeding-1b-ai-revenue), and more than 650 customers now spend over $1 million a year on the platform. Databricks was also named a Leader in [Gartner's 2025 Magic Quadrant for Cloud Database Management Systems](https://www.databricks.com/blog/databricks-named-leader-2025-gartner-magic-quadrant-cloud-database-management-systems) - external signals of how far the open lakehouse model built on Delta Lake has traveled.
### Databricks Delta Lake vs. Snowflake: A Practical Comparison
| Feature/Aspect | Databricks Delta Lake | Snowflake |
| :--- | :--- | :--- |
| **Data Format** | Open (**Delta** protocol over **Parquet** files) | Proprietary internal format |
| **Storage Control** | Customer-managed cloud object storage | Snowflake-managed storage |
| **Vendor Lock-In** | Lower risk due to open formats | Higher risk due to proprietary ecosystem |
| **AI/ML Integration** | Deep, native integration with ML frameworks | Strong SQL support; ML integration is evolving |
| **Ecosystem** | Open-source friendly; supports various tools | Integrated, walled-garden ecosystem |
| **Primary Use Case** | Unified platform for data engineering, BI, and AI | High-performance SQL analytics and BI |
If the priority is a flexible data asset that serves both BI and advanced AI workloads without locking you into one vendor, Delta Lake's open architecture is the stronger fit. If the priority is a high-speed, low-maintenance SQL warehouse, Snowflake is a legitimate alternative. For more detail, see our full [Snowflake vs Databricks](/snowflake-vs-databricks/) comparison.
## How Do You Migrate to Delta Lake?
Migrating an existing Parquet data lake to Delta Lake is usually simpler than teams expect, because the `CONVERT TO DELTA` command upgrades a Parquet table in place - adding a `_delta_log` alongside the existing files without rewriting any data. Start with one pipeline, not a wholesale migration.

A good starting point is a single, high-visibility ETL pipeline currently built on raw Parquet files, ideally one known for data quality issues. Focusing initial efforts here lets you demonstrate the practical benefits of ACID transactions and schema enforcement to stakeholders quickly, using these [data migration best practices](/insights/data-migration-best-practices/) to guide the process.
### Structuring for Success with the Medallion Architecture
After an initial success, structure the entire lakehouse for quality and scale using the **Medallion Architecture**, which organizes data into three quality tiers:
* **Bronze Tables:** Raw data ingested directly from source systems. This layer serves as an immutable, auditable archive.
* **Silver Tables:** Data from the Bronze layer is cleaned, filtered, joined, and enriched. This is where inconsistencies are resolved to create a reliable, single source of truth.
* **Gold Tables:** Highly aggregated, purpose-built datasets that power BI dashboards and analytics applications, delivering fast, trustworthy insights to business users.
This tiered system acts as a data quality checkpoint, catching and resolving issues early in the pipeline so the final Gold tables are built on clean data.
### Evaluating Your Implementation Partner
Delta Lake's popularity shows up in who builds on it: 64 of the 86 firms profiled in the Data Engineering Companies Index list Databricks as a core platform. When vetting one of those [Databricks consulting partners](/databricks-consulting/), ask targeted questions beyond the sales pitch:
1. **Migration Experience:** Ask for specific examples of Parquet-to-Delta migrations. What challenges came up, and how were they resolved?
2. **Governance Expertise:** Ask about hands-on experience with **Unity Catalog** - fine-grained access controls, secured tables, and data lineage tracing for other clients.
3. **Performance Tuning:** Request case studies on performance work. How have they used Z-Ordering, liquid clustering, or file compaction to speed up queries or cut costs? Ask for measurable results, not generalities.
A partner with demonstrable, hands-on experience in these areas will help build a secure, efficient, and scalable Delta Lake implementation - not just manage the migration.
## Common Delta Lake Questions
### Is Delta Lake a Databricks-Only Thing?
No. While [Databricks](https://www.databricks.com/) created Delta Lake and continues to be a primary contributor, **Delta Lake is an open-source format** governed by the Linux Foundation. It can be used with other processing engines, including open-source [Apache Spark](https://spark.apache.org/), Flink, and Presto, and your data stays in your own cloud storage (e.g., AWS S3, Azure Data Lake Storage) in a format you control.
### How Is This Different from a Regular Data Warehouse?
A traditional data warehouse typically couples compute and storage in a closed system - scaling one often means scaling both. In a Delta Lake architecture, compute and storage are decoupled: data sits in low-cost object storage, and compute clusters scale independently as needed. See our full [data warehouse vs. data lake](/insights/data-warehouse-vs-data-lake/) breakdown for the underlying distinction.
Delta Lake provides database-like reliability directly on data lake files, supporting workloads from raw data ingestion to structured BI tables, which makes it suitable for both traditional analytics and the AI workloads that strain most warehouses.
### What's the Best Way to Move from Parquet to Delta?
The recommended approach is to start with a project that offers a quick win with minimal risk, using the `CONVERT TO DELTA` command - a one-line operation that upgrades a Parquet table in place by adding a transaction log alongside the existing files. It does not rewrite the data, so it's fast and cheap to run.
A proven plan for a first migration:
* **Pick a Target:** Select a dataset visible enough to demonstrate value but not so critical that issues would cause major disruption. A table with known data quality problems is a good candidate.
* **Run the Command:** Execute `CONVERT TO DELTA`, pointing it at the directory of Parquet files.
* **Point Your Pipelines:** Update existing data jobs to read from and write to the new Delta table instead of the raw Parquet files.
* **Show Off:** Verify downstream processes are working, then use `MERGE` or `OPTIMIZE` to demonstrate the new capabilities to your team.
This incremental approach proves the value of Delta Lake quickly and builds the case for broader adoption.
---
## A CTO's Guide to Databricks Unity Catalog Implementation
Source: https://dataengineeringcompanies.com/insights/databricks-unity-catalog-implementation/
Published: 2026-03-24T10:28:03.088537+00:00
Description: A proven guide for CTOs on Databricks Unity Catalog implementation. Get actionable frameworks for architecture, governance, migration, and CI/CD.
A [Databricks Unity Catalog](https://www.databricks.com/product/unity-catalog) implementation replaces scattered, workspace-level permissions with one governance model across your entire data estate: a single metastore, identity-provider-driven groups, a domain-based catalog structure, and CI/CD-managed grants. Get the metastore architecture and the governance model right at the start - both are expensive to unwind once production workloads depend on them.
### What metastore architecture should you choose?
A metastore is the top-level container for your catalogs, schemas, tables, and views, so most organizations should use a **single metastore per cloud account** (one for AWS, one for Azure). It centralizes governance, keeps cross-workspace queries in one unified namespace, and cuts administrative overhead. Multiple metastores are only worth the added complexity when a specific constraint forces the split.
A multi-metastore approach is a tactical choice driven by specific constraints:
* **Data Residency Mandates:** If regulations like GDPR require both data and its metadata to remain within a geographic boundary, a separate metastore per region is mandatory.
* **M&A Scenarios:** Integrating an acquired company with a disparate cloud environment and governance model often warrants a separate metastore to avoid a complex and risky consolidation project.
* **Strict Billing Isolation:** If internal chargeback models require absolute financial separation between business units, multiple metastores provide that hard fence, though this is often achievable with tagging in a single-metastore setup.
Outside of those specific triggers, default to one metastore per cloud account.
### How do single and multiple metastores compare?
Most teams should default to a single metastore per cloud account. Use this table to check whether a specific compliance, M&A, or billing-isolation requirement in your organization overrides that default before you commit to an architecture that's expensive to reverse.
| Factor | Single Metastore (Per Cloud Account) | Multiple Metastores | Recommendation for Engineering Leaders |
| :--- | :--- | :--- | :--- |
| **Governance** | Centralized, simplifying cross-workspace policy enforcement and auditing. | Decentralized, requiring separate administration for each metastore. Increases complexity. | Default to a single metastore unless a strict compliance or structural requirement dictates otherwise. |
| **Data Sharing** | Direct. A unified namespace allows direct queries between workspaces. | Complex. Requires [Delta Sharing](https://www.databricks.com/product/delta-sharing) to share data across metastore boundaries, adding overhead. | If cross-team collaboration is a priority, a single metastore provides the path of least resistance. |
| **Operational Overhead** | Lower. One metastore to manage, secure, and back up. | Higher. Each metastore adds administrative burden and increases the risk of configuration drift. | A single metastore lowers total cost of ownership (TCO) by reducing operational toil. |
| **Compliance** | Meets most standards. Can be complex for strict data residency. | Handles strict data residency and sovereignty requirements directly. | Only use multiple metastores if mandated by your legal or compliance team for specific regions. |
## How should you design governance and access control in Unity Catalog?
Structure catalogs around business domains, not technical teams: a `marketing` catalog with `campaign_analytics` and `customer_segmentation` schemas, not a `marketing_team_catalog`. Layer in attribute-based access control (ABAC) so permissions follow group and data attributes automatically instead of manual, one-off grants.
Domain-based catalogs stay legible as headcount and org structure change, because data ownership maps to the business function that understands the data, not to whichever team happens to own the pipeline this quarter.
### Should you use attribute-based access control (ABAC)?
Static role-based access control (RBAC) doesn't scale: every new hire, team change, or project needs a manual permission update. ABAC grants access dynamically based on user, data, and request attributes instead, so permissions update themselves when group membership changes.
> By structuring access around attributes like a user's department, project role, or data sensitivity tags, you create a self-managing system that scales governance without scaling the administrative team.
For example, a policy can grant `SELECT` access on any table tagged `financial_reporting` to any user in the `Finance_Department` group. When a new analyst joins finance, their identity provider (IdP) group membership grants the correct permissions automatically - no tickets, no manual `GRANT` statements. A fintech firm can use the same mechanism to mask PII columns for most users while giving a small, authorized compliance team full visibility.
### What does a working governance framework look like?
A documented object hierarchy prevents expensive refactoring later. Four elements do most of the work: catalogs mapped to business units, schemas mapped to data domains, IdP groups mapped to functional roles, and tags that drive automated ABAC policies based on data sensitivity.
* **Catalogs for Business Units:** Assign top-level catalogs to major business functions like `sales`, `product`, and `finance`.
* **Schemas for Data Domains:** Within each catalog, use schemas to group related datasets (e.g., `sales.quarterly_forecasts`, `product.user_telemetry`).
* **Groups for Functional Roles:** Map your IdP groups to functional roles (`Data_Analysts_Sales`, `Data_Scientists_Product`).
* **Tags for Data Sensitivity:** Use tags like `PII`, `Confidential`, or `Public` on tables and columns to drive automated ABAC policies.
This layered model cuts down on the object-level permissions that are nearly impossible to audit at scale. See our guide on [data governance best practices](/insights/data-governance-best-practices/) for strategies that apply beyond Unity Catalog specifically, or the broader [data governance](/data-governance/) overview if this is one piece of a larger initiative.
## How do you integrate identity providers with Unity Catalog?
Sync your identity provider (Azure AD, Okta, Google Workspace) to Databricks via SCIM so the user and group lifecycle - creation, updates, deactivation - happens automatically. Map IdP groups to Databricks groups and grant permissions to groups, not individuals, so IdP changes propagate without manual admin work.
Unity Catalog's governance model only works if the principals inside it map to real people and services. That mapping happens through **SCIM (System for Cross-domain Identity Management)**, the only method that scales past a handful of users: it makes Databricks a live mirror of your IdP, so a status or role change there updates Databricks access automatically, with no lingering permissions left behind from someone who left six months ago.
### How do you set up SCIM provisioning?
Configure a SCIM connector between your IdP - [Azure Active Directory](https://azure.microsoft.com/en-us/products/active-directory), [Okta](https://www.okta.com/), or [Google Workspace](https://workspace.google.com/) - and your Databricks account. This pushes user and group identities directly into Databricks.
Your primary task is mapping existing IdP groups to Databricks groups. An IdP group named `azuread-finance-analysts` maps to a `finance-analysts` group in Databricks. You grant permissions to the Databricks group, and the IdP manages its membership - the same pattern behind modern [Identity and Governance Administration (IGA)](https://reclaim.security/blog/identity-and-governance-administration/).
> The litmus test for a successful SCIM setup: your platform team **never** manually adds a user to a group in Databricks. The entire user and group lifecycle - creation, updates, and deactivation - is fully automated and driven by the IdP.
### How do you manage service principals and group naming conflicts?
While user syncing is straightforward, **service principals** - non-human accounts for automated jobs - require deliberate management. Don't use a single, over-privileged service principal; create dedicated service principals for distinct functions and grant them least-privilege access. A service principal for a marketing pipeline shouldn't have access to finance data.
A common pitfall is IdP group name conflicts (e.g., multiple "Analysts" groups). Resolve this before syncing by enforcing a unique naming convention in your IdP, such as `finance_analysts_us` and `finance_analysts_eu`, so they map to distinct groups in Databricks instead of colliding.
## How do you migrate from Hive Metastore to Unity Catalog?
Migrate in phases, never as a single cutover. Assess your Hive Metastore for unsupported formats and access conflicts, pilot on a lower-stakes workload, then use the `SYNC` command to clone tables, views, and permissions - validating data integrity, pipeline health, and query performance before you decommission Hive.
For existing [Databricks](https://www.databricks.com/) users, this is the most delicate phase of implementation. A "big bang" cutover risks broken pipelines and business disruption; a phased, controlled migration is the only approach that holds up in production.
The process begins with an assessment of your current Hive Metastore. Databricks provides tools to scan your environment, flagging dependencies, unsupported table formats, and potential access control conflicts. That scan gives you a clear inventory of what to move, what to fix before moving, and the true scope of the project - a thorough assessment phase is what catches most migration blockers before they turn into production incidents.
### Why pilot the migration on a lower-stakes workload first?
Select a pilot team for migration, but not your most business-critical workload. The marketing analytics team is often a good candidate: its data is typically high-volume but less operationally sensitive than finance or core product data.
The pilot is a sandbox to validate the migration process, refine automation scripts, and surface edge cases in a low-stakes environment.
> The goal of the pilot isn't speed; it's learning. Document every step, error, and resolution. That documentation becomes your playbook for migrating the rest of the organization.
### How do you validate a migration before decommissioning Hive?
The core technical tool is the `SYNC` command, which clones tables, views, and permissions from Hive Metastore into Unity Catalog. For external tables, `SYNC` is particularly useful since it registers them in Unity Catalog without moving the underlying data - though it can't handle every complex object or non-standard configuration, so budget time for those manually.
**Post-Migration Validation Checklist:**
After migrating a workload, validate its integrity before decommissioning the legacy Hive assets.
* **Data Integrity:** Run `COUNT(*)` and checksums on key tables in both Hive and Unity Catalog to confirm an exact match.
* **Pipeline Health:** Trigger dependent data pipelines and ML jobs to confirm they complete without errors.
* **Permissions Audit:** Use test accounts from different user groups to verify they can access required tables and are blocked from restricted ones.
* **Query Performance:** Execute representative user queries against the new Unity Catalog tables and compare runtimes against Hive Metastore benchmarks. Performance should match or beat the old baseline.
## How do you automate Unity Catalog governance with CI/CD?
Manage every catalog, schema, and grant as Terraform code reviewed through pull requests, not through the UI. When a team requests a new schema, a merged PR provisions it with the correct permissions automatically - no support ticket, no manual `GRANT` statement, and a full audit trail of every change.
Managing [Databricks Unity Catalog](https://www.databricks.com/product/unity-catalog) permissions through the UI doesn't scale and adds risk. For an enterprise deployment, treating catalog configuration as code via CI/CD means every change - from creating schemas to granting permissions - is version-controlled, tested, and auditable.
Defining your catalog structure in an Infrastructure-as-Code (IaC) tool like [Terraform](https://www.terraform.io/) eliminates configuration drift. Governance moves from a reactive, ticket-based process to an automated one: when a new team needs resources, the pipeline provisions catalogs, schemas, and group permissions without a platform administrator touching anything by hand.
### Example: Onboarding a Project via Terraform
A data science team needs a sandbox for "Project Alpha." A developer opens a pull request with a simple Terraform file instead of filing a support ticket.
```hcl
# 1. Provision a new schema for the project
resource "databricks_schema" "project_alpha" {
catalog_name = "analytics"
name = "project_alpha_sandbox"
comment = "Sandbox for Project Alpha data science team."
owner = "data_platform_admins"
}
# 2. Grant usage and creation rights to the project team's group
resource "databricks_grant" "project_alpha_usage" {
schema = databricks_schema.project_alpha.id
principal = "project_alpha_ds_team"
privileges = ["USE_SCHEMA", "CREATE_TABLE"]
}
```
Once the pull request is approved and merged, the CI/CD pipeline executes the plan, creating the schema with the correct permissions. This closes the gap left by ad-hoc manual changes.
> The governing rule: **no manual `GRANT` statements in production.** All permissions for users, groups, and service principals go through version-controlled code. It's the only way to keep the system auditable at scale.
Managed this way, Unity Catalog becomes a reliable, scalable part of your DevOps toolchain rather than a manually administered side system.
## How do you optimize cost and performance after implementation?
Use Databricks system tables to audit access patterns, query performance, and data lineage, then turn on Predictive Optimization (automated `OPTIMIZE`/`VACUUM`) and Liquid Clustering. Predictive Optimization compacts small files and purges stale data without manual tuning; Liquid Clustering replaces static partitioning with clustering based on actual query patterns.
Deployment isn't the finish line. Once Unity Catalog is live, the focus shifts to cost savings and performance gains, and system tables are the primary tool for finding both - they provide a built-in audit trail of what's being queried, how fast, and by whom.
### Which automated optimization features matter most?
* **Predictive Optimization:** Automatically runs `OPTIMIZE` and `VACUUM` commands. It compacts small files that degrade query performance and purges old, unreferenced data, cutting cloud storage costs without any manual scheduling.
* **Liquid Clustering:** Often replaces rigid, traditional partitioning. It groups data based on actual query patterns, simplifying table management and improving performance without constant manual tuning.
> To keep the broader cloud bill in check, pair this with general [cloud cost optimization best practices](https://www.buttercloud.com/blog/cloud-cost-optimization-best-practices) rather than treating Unity Catalog's tools as the whole strategy.
System tables identify the operational issues; Predictive Optimization and Liquid Clustering resolve most of them automatically. For a deeper look at the table format mechanics underneath both features, see [optimizing with Databricks Delta Lake](/insights/databricks-delta-lake/).
## Top Questions on Unity Catalog Implementation
These are the most frequent questions from engineering leaders planning a Unity Catalog implementation.
### What is a realistic implementation timeline?
For an organization already on Databricks, a standard implementation project takes **8-12 weeks**, covering metastore setup, IdP integration, governance model design, CI/CD automation, and migrating a pilot business unit. That timeline holds up against a market with real depth: 64 of the 86 firms profiled in the Data Engineering Companies Index list Databricks as a core platform, so delivery teams with hands-on experience at this exact scope of work aren't hard to find. A greenfield Databricks deployment takes longer, since Unity Catalog setup becomes part of a larger platform build-out.
### Can Unity Catalog govern data outside of Databricks?
Yes. Unity Catalog is built on open standards, supporting modern table formats like Delta Lake and [Apache Iceberg](https://iceberg.apache.org/) - the same open formats behind a [lakehouse architecture](/insights/what-is-lakehouse-architecture/). That lets other Iceberg-compatible engines like [Snowflake](https://www.snowflake.com/), [BigQuery](https://cloud.google.com/bigquery), and [Trino](https://trino.io/) interoperate with data governed by Unity Catalog.
> The primary capability here is Lakehouse Federation, which lets Unity Catalog directly query and manage permissions on data in external databases like PostgreSQL or MySQL without ETL. This creates a single control plane over data Unity Catalog doesn't own directly, cutting down on silos and vendor lock-in.
### How does Unity Catalog support AI/ML governance?
Unity Catalog gives the machine learning lifecycle a single source of truth for data, models, and unstructured assets, so responsible-AI requirements have something concrete to point at during an audit.
* **End-to-end data lineage** shows precisely which data was used to train a specific model version, making audits straightforward.
* **Volumes** enable governance of unstructured data (images, audio, PDFs), which matters for many modern AI applications.
* **ML models are treated as first-class citizens**, allowing the same governance policies applied to sensitive tables to apply to models.
That integrated approach makes the entire model lifecycle auditable, so teams can scale AI without losing track of compliance requirements.
---
Planning a Databricks Unity Catalog implementation or a broader governance overhaul? See how [Databricks consulting](/databricks-consulting/) engagements are typically scoped, or start with our [data governance](/data-governance/) overview if Unity Catalog is one piece of a larger initiative.
---
## dbt Implementation Partners: Who Can Tame Your DAG in 2026?
Source: https://dataengineeringcompanies.com/insights/dbt-implementation-partners/
Published: 2025-12-19T00:00:00.000Z
Description: Choosing the right dbt Labs partner for your analytics engineering transformation. We compare Premier vs. Specialized boutique partners.
Anyone who can write SQL can start a dbt project. Few people can architect a dbt project with thousands of models that still runs a full build in under an hour. That gap - between "knows dbt" and "can scale dbt" - is what you're actually hiring a partner to close. Only 20 of the 86 firms in the [Data Engineering Companies Index](/data-engineering-consulting-firms/) name dbt as a core capability, which is a smaller pool than you'd expect given how standard the tool has become - most generalist data engineering shops still treat it as a nice-to-have rather than a specialty.
## Should you host dbt yourself or pay for dbt Cloud?
Running dbt Core on your own infrastructure costs nothing in license fees but shifts the cost onto your engineering team, which now owns container orchestration, secrets management, and CI/CD. dbt Cloud costs roughly $100 per developer per month for the Team plan, with custom Enterprise pricing above that, but it removes most of that operational burden.
The math usually favors dbt Cloud once you're paying consultants anyway. A partner billing $200 an hour to build a custom ECS runner is solving a problem that a license far cheaper than their invoice already solves. dbt Cloud's Slim CI feature only rebuilds modified models instead of the whole DAG, which can meaningfully cut warehouse compute costs on Snowflake or BigQuery. Its semantic layer also lets tools like Tableau or Looker query metrics directly from one definition, instead of each BI tool reimplementing the same logic differently. Check [current dbt Cloud pricing](https://www.getdbt.com/pricing) before you budget, since plans and limits change.
## What kind of dbt partner do you actually need?
The right partner depends on whether your problem is modeling, warehouse performance, or enterprise governance - not all three firms do all three well.
**Modern data stack natives** were built around dbt, Fivetran, and Snowflake from day one. Firms like Brooklyn Data (now part of Velir), Montreal Analytics, and Datacoves fall in this category. They tend to set the best practices for macros, packages, and Jinja automation rather than just follow them, which makes them a strong fit for greenfield builds, modernizing legacy pipelines, or standing up a center of excellence.
**Platform specialists** treat dbt as one piece of a specific warehouse ecosystem. phData focuses on Snowflake, Lovelytics on Databricks. Their edge is knowing how to write dbt code that doesn't quietly inflate your warehouse bill - useful when the project is really about migration or performance tuning, with dbt as the transformation layer underneath.
**Global systems integrators** - firms like Slalom and Deloitte - bring governance, security, and change-management muscle that boutique shops usually can't match. They're the right call for large enterprise deployments where legal and compliance sign-off is the actual bottleneck, not the SQL.
## What is dbt Mesh, and why does it change who you should hire?
dbt Mesh splits a single monolithic project into domain-specific sub-projects - marketing, finance, sales - that reference each other through defined interfaces instead of one shared codebase. See [dbt Labs' own guide to mesh architecture](https://docs.getdbt.com/best-practices/how-we-mesh/mesh-1-intro) for the underlying concepts.
Most developers who list "dbt certified" on a resume have only worked inside a monolith. Mesh requires real fluency with model contracts, public and private model interfaces, and cross-project refs - skills that don't show up on a standard certification. Before signing a contract, ask a candidate directly whether they've implemented model contracts and how they handle breaking changes across a mesh architecture. If the answer is vague, that's the signal.
## What should you budget for dbt talent?
| Role | Typical rate | What they deliver |
| :--- | :--- | :--- |
| Junior analytics engineer | $80-110/hr | Writes SQL models and tests under supervision |
| Senior analytics engineer | $140-180/hr | Designs DAG structure, writes macros, tunes query performance |
| dbt architect | $200-300/hr | Sets up mesh, CI/CD, role-based access control, and governance |
Rates for dbt specialists sit toward the higher end of what the broader consulting market charges - across the 86 firms in the index, rates span $45-250/hr with a median around $100, and most dbt architecture work lands above that median given the specialized skill involved.
## How do you test whether a partner actually knows dbt at scale?
Before signing a statement of work, ask the partner to review one of your existing pull requests or walk through their approach to a few concrete scenarios. The quality of the answer tells you more than any case study.
Ask how they handle incremental models with schema drift. "We just do a full refresh" is a red flag; "we use the `on_schema_change` config or a custom macro to handle column evolution" tells you they've hit this problem before. Ask about their documentation strategy - "we write it at the end" versus "we enforce `persist_docs` and require a description in YAML for every model before merge" separates teams that treat docs as real infrastructure from teams that treat it as cleanup. Ask whether they use open-source testing packages; a partner reaching for `dbt_utils` for surrogate keys or `elementary` for pipeline observability is already working the way [dbt's own testing documentation](https://docs.getdbt.com/docs/build/data-tests) recommends, rather than reinventing it.
## Conclusion
dbt has effectively won the argument over how analytics transformation gets done. The remaining question isn't whether to use it, but who can run it at scale without the DAG turning into unmanageable spaghetti. Hire a partner who has scar tissue from scaling multiple dbt projects, not one who just passed the certification exam. If you're weighing dbt against the rest of your stack, [modern data stack](/insights/modern-data-stack/) and [data modeling techniques](/insights/data-modeling-techniques/) cover the surrounding architecture decisions, and the [Snowflake consulting](/snowflake-consulting/) and [Databricks consulting](/databricks-consulting/) hubs are a starting point if your dbt work is tied to a specific warehouse migration.
---
## A CTO's Guide to Ecommerce Data Engineering
Source: https://dataengineeringcompanies.com/insights/ecommerce-data-engineering/
Published: 2026-03-13T07:41:04.515629+00:00
Description: Build a high-performance ecommerce data engineering architecture. Compare platforms, integration patterns, and vendor selection criteria for maximum ROI.
**Ecommerce data engineering** is the work of turning order, clickstream, and inventory data from platforms like [Shopify](https://www.shopify.com/), [Google Analytics](https://analytics.google.com/), and your ERP into pipelines that support personalization, demand forecasting, and fraud detection. Three decisions define the work: how you store data (warehouse or lakehouse), how you move it (batch or streaming), and how you keep it trustworthy (contracts, tests, and observability).
## How Should You Architect an Ecommerce Data Platform?
**Your data architecture decides whether you can support dynamic pricing, real-time fraud detection, and supply chain optimization.** Merging clickstream data with point-of-sale records and support-chat transcripts into a single recommendation engine requires sub-second query performance - which is a storage and compute decision, made long before anyone opens a BI tool.
### Should You Use a Data Warehouse or a Data Lakehouse?
**A data warehouse suits predictable, structured data like sales figures and customer lists; a data lakehouse suits mixed structured, semi-structured, and unstructured data used for AI and ML work.** Most growing ecommerce teams outgrow a warehouse-only design once they need to analyze product images, review text, or clickstream at scale.
* **Data Warehouse:** A traditional, structured repository built for predictable data like sales figures and customer lists. It's a familiar environment for analytics teams running SQL for BI and reporting.
* **Data Lakehouse:** A hybrid model that combines the flexibility of a data lake with the management features of a warehouse. It handles structured, semi-structured, and unstructured data, which makes it the better fit for AI and machine learning tasks like sentiment analysis on reviews or processing product images.
For most growing ecommerce businesses, a lakehouse architecture (built on [Databricks](https://www.databricks.com/) or [Snowflake](https://www.snowflake.com/)) is the more durable choice: it covers standard BI needs today while leaving room for machine learning work later. A coherent [first-party data strategy](https://www.metricmosaic.io/blog/first-party-data-strategy) has to sit on top of this decision, not precede it.
A technical design only pays off once it's mapped to core business domains - marketing, fulfillment, customer service - so the platform serves the teams that actually depend on it. Our guide to [retail data engineering](/retail-data-engineering/) covers this domain-driven approach in detail.
## What Are the Core Ecommerce Data Source Integrations?
**An ecommerce data platform is only as good as its integrations.** The modern ecommerce stack is a sprawling collection of tools, and integration is usually where projects stall: API changes (schema drift) and legacy system quirks force teams into repeated cycles of fixing broken pipelines instead of building new capability.
### Should You Use Batch or Streaming Ingestion?
**Batch ingestion moves data on a schedule and fits work that doesn't need an immediate reaction, like daily sales summaries; streaming ingestion moves data event-by-event and fits real-time needs like fraud detection or on-site personalization.** Batch is cheaper and simpler to run - streaming costs more engineering time to build and operate.
* **Batch Ingestion:** Data is collected and moved on scheduled intervals (hourly, daily). Reliable and cost-effective for information that doesn't require immediate action. Tools like [Fivetran](https://www.fivetran.com/) and [Airbyte](https://airbyte.com/) handle this well.
* **Use Cases:** Daily sales summaries, ERP inventory syncs, pulling order histories from [Shopify](https://www.shopify.com/) or Magento (Adobe Commerce).
* **Streaming Ingestion:** Data flows event-by-event in near real-time. More complex to implement, but necessary when the business needs to react instantly. This is the domain of tools like [Apache Kafka](https://kafka.apache.org/) and [Amazon Kinesis](https://aws.amazon.com/kinesis/).
* **Use Cases:** Real-time fraud detection, personalizing on-site user experience, analyzing clickstream events from [Segment](https://segment.com/).
### How Do Data Contracts Prevent Pipeline Failures?
**A data contract is a formal, programmatic agreement between a source system and its destination that defines expected structure, semantics, and data quality.** Schema drift - a source API changing its structure without warning - is the most common cause of ecommerce pipeline failure; contracts with built-in schema validation flag or quarantine violations automatically instead of letting them corrupt downstream tables.
Building this validation directly into ingestion is what separates a data ecosystem teams can trust from one they're constantly firefighting. For a deeper dive, read our guide on [cloud data integration strategies](/insights/cloud-data-integration/).
## Snowflake or Databricks: Which Fits Ecommerce Better?
Choosing your central data platform is a 5-10 year bet on your company's analytics and AI direction. The decision usually comes down to [Snowflake](https://www.snowflake.com/en/) and [Databricks](https://www.databricks.com/). Their capabilities increasingly overlap, but their core designs still suit different ecommerce priorities.
Your use case dictates the technical path. Fraud detection needs a streaming pipeline; end-of-day sales reporting is a better fit for cheaper batch jobs.
### Snowflake for Structured Analytics
If your world revolves around SQL and delivering clean, structured data to business analysts, [Snowflake](https://www.snowflake.com/en/) is built for the job. Its architecture, which separates storage from compute, matches the spiky query patterns of retail well - quiet periods followed by heavy query volume during a marketing campaign launch.
Snowflake fits these scenarios:
* **BI and Reporting:** Giving analysts fast, reliable access to sales, marketing, and inventory data for dashboards in tools like Tableau or Power BI.
* **Cross-Company Data Sharing:** Sharing live inventory levels with a supplier or sales data with a marketing partner without building custom pipelines.
* **Predictable BI Cost Control:** For analytics-heavy workloads, paying for compute by the second usually costs less than running clusters 24/7.
### Databricks for Advanced AI and Real-Time Data
When your roadmap includes ambitious AI projects and real-time customer experiences, [Databricks](https://www.databricks.com/) is the stronger option. Built by the creators of Apache Spark, it's designed for large-scale processing and machine learning on messy, unstructured data like product images, customer reviews, and support chats.
Databricks is the better fit when you need to:
* **Real-Time Personalization:** Ingesting and acting on clickstream data to update a recommendation engine on the fly needs the low-latency streaming that's native to Databricks.
* **Complex AI Models:** Fraud detection algorithms or demand forecasting models that learn from massive, varied datasets are what Databricks was built for.
* **Unstructured Data:** Analyzing product photos for defects or sifting through support transcripts for sentiment are tasks where Databricks' toolset has a clear edge.
### Platform Comparison for Ecommerce Workloads: Snowflake vs. Databricks
This table breaks down how each platform stacks up against the criteria that matter most to ecommerce engineering leaders.
| Criterion | Snowflake | Databricks | Recommendation for Ecommerce CTOs |
| :--- | :--- | :--- | :--- |
| **Primary Use Case** | **Business Intelligence**, reporting, and analytics on structured/semi-structured data. The "single source of truth." | **Machine Learning** and **AI** at scale, real-time data processing, and advanced analytics on all data types. | If your priority is democratizing data for business analysts, start with Snowflake. If you're building a future on AI, lean toward Databricks. |
| **Core Architecture** | SQL-native Data Cloud with decoupled storage and compute. Highly optimized for SQL queries. | Lakehouse platform built on open-source **Apache Spark**. Unifies data warehousing and data science. | Snowflake's architecture offers simplicity for BI. Databricks' offers flexibility for complex data science and engineering workflows. |
| **Data Types** | Excels with structured (**SQL tables**) and semi-structured (**JSON**, Avro) data. Unstructured support is improving but not native. | Natively handles **structured, semi-structured, and unstructured** (images, text, video) data with ease. | If your roadmap includes analyzing product images, reviews, or chat logs, Databricks has a significant advantage. |
| **Real-Time Capabilities** | Strong batch processing and improving near-real-time with Snowpipe Streaming. | Best-in-class real-time streaming with **Delta Live Tables** and Structured Streaming. Built for low-latency. | For true real-time personalization or fraud detection, Databricks is the more mature and capable choice today. |
| **Ease of Use for Analysts** | Extremely intuitive for anyone who knows **SQL**. The UI is clean and focused on querying data. | Steeper learning curve. Requires knowledge of **Spark**, Python/Scala, and notebooks. SQL is supported but not the only focus. | Snowflake is far easier to adopt for traditional BI teams, leading to faster time-to-value for reporting. |
| **Ecosystem & Interoperability** | Massive partner ecosystem for BI and ETL tools. Excellent for data sharing across organizations. | Deep integration with the **ML ecosystem** (MLflow, Hugging Face). Open standards (Delta Lake) promote flexibility. | Your choice depends on whether your key partners are in the BI world (Tableau, Fivetran) or the AI world (PyTorch, TensorFlow). |
There's no single "best" platform, only the best platform for your strategy. Snowflake provides a faster path to value for straightforward business intelligence; Databricks offers a higher ceiling for AI and real-time work.
## How Do You Implement Data Governance and Observability?
**In ecommerce, bad data hits revenue directly.** A pricing error, an out-of-stock item showing as available, or a GDPR violation causes immediate financial damage and erodes customer trust. Governance and observability aren't optional add-ons; they're what a serious data practice is built on.
Effective governance means building automated guardrails so data stays reliable, secure, and understandable. Without that trust, your analytics team spends its time questioning numbers instead of finding insights.
### How Do You Establish a Foundation of Trust?
Start with a single source of truth for metadata: a data catalog. Tools like Atlan or Alation trace data lineage automatically, showing exactly where a metric like "Average Order Value" originates and every transformation it undergoes. That traceability makes debugging faster and gives stakeholders a reason to trust the numbers.
Next, automate data quality as part of development by baking tests directly into your transformation logic. Integrating data quality tests into your [dbt](https://docs.getdbt.com/docs/introduction) models stops you from cleaning up messes and starts preventing them. A simple test can flag an unusual spike in "orders per hour" or a sudden drop in product prices before it reaches a BI dashboard.
### What Does Proactive Monitoring With Data Observability Catch?
**Quality tests catch known problems; observability platforms catch the unknown ones.** Platforms like Monte Carlo or Metaplane track the health of your data ecosystem across three signals:
* **Freshness:** Is inventory data updating every 15 minutes as expected?
* **Volume:** Did the customer event stream from the website suddenly drop to zero?
* **Schema:** Did a [Shopify](https://www.shopify.com/) API update add a new field and break a downstream model?
Automated alerts on these signals let engineers fix issues before business teams notice a problem, which moves the data practice from firefighting to a disciplined, automated operation. If you're still building this layer out, our guide on [data quality monitoring tools](https://www.metricswatch.com/blog/data-quality-monitoring-tools) covers the options in more depth.
## How Do You Evaluate a Data Engineering Partner?
Choosing a data engineering consulting partner is a high-stakes decision. Get it wrong and you're looking at blown budgets, project delays, and a brittle data stack that generates technical debt for years. Vetting has to get past the sales presentation to verifiable proof of expertise: does the firm have hands-on experience with the [Shopify](https://www.shopify.com/) API or real-time event streams from [Segment](https://segment.com/)? You need to see evidence, not slides.
### What Should You Look for Beyond the Technical Checklist?
Technical skill is table stakes - 68 of the 86 firms profiled in the [Data Engineering Companies Index](/) name analytics or BI among their capabilities, so that claim alone won't separate finalists. The best partners act as strategic advisors, challenging your assumptions and bringing delivery processes they've actually run before. Watch for the "bait-and-switch," where senior architects show up in the sales process but the proposal gets staffed with junior talent - a signal the A-team won't be building your project. For a shortlist focused specifically on analytics and BI delivery, see our [analytics consulting](/analytics-consulting/) guide.
To avoid these traps, score potential partners against a structured scorecard instead of a gut feeling.
### Data Engineering Partner Evaluation Checklist
This checklist, based on the methodology used at [DataEngineeringCompanies.com](https://dataengineeringcompanies.com/) to rank consulting firms, is a starting point for your own evaluation scorecard. Use it to structure your RFP and guide vendor conversations. Assign a weight from 1 (nice-to-have) to 5 (mission-critical) to each criterion to generate a quantitative score for a side-by-side comparison.
| Category | Evaluation Criterion | Weight (1-5) | Assessment Notes |
| :--- | :--- | :--- | :--- |
| **Ecommerce Expertise** | Proven projects with Shopify, Magento, or BigCommerce APIs. | **5** | Ask for specific, referenceable case studies. |
| **Ecommerce Expertise** | Experience building marketing attribution & LTV models. | **5** | Do they understand CAC, ROAS, and multi-touch attribution? |
| **Ecommerce Expertise** | Deep understanding of ecommerce data sources (orders, events, catalog). | **4** | Can they map out a typical ecommerce data schema from memory? |
| **Technical Depth** | Certified experts in your chosen platform ([Snowflake](https://www.snowflake.com/en/)/[Databricks](https://www.databricks.com/)). | **5** | Verify current certifications for the proposed team. |
| **Technical Depth** | Demonstrable experience with modern transformation tools like [dbt](https://www.getdbt.com/). | **4** | A data practice without dbt or an equivalent is worth asking about. |
| **Technical Depth** | Expertise in both batch and real-time ingestion patterns. | **4** | How would they handle a nightly product sync and a live clickstream? |
| **Delivery Methodology** | Clear, agile project management and communication plan. | **4** | How will they handle scope changes and report progress? |
| **Delivery Methodology** | Documented best practices for code, testing, and deployment. | **4** | Ask to see their internal standards or a sanitized example. |
| **Team Composition** | Senior architect and engineers named and guaranteed on the project. | **5** | Get resumes and insist on interviewing the key team members. |
| **Team Composition** | Evidence of low team turnover. | **3** | High turnover can derail a long-term project. |
| **Strategic Fit** | Acts as a strategic advisor, not just an order-taker. | **5** | Did they challenge your assumptions or suggest better approaches? |
| **Strategic Fit** | Transparent knowledge transfer and training plan for your team. | **4** | How will they ensure your team can own the platform long-term? |
| **Cost & Transparency** | Transparent, role-based rate benchmarks (e.g., Architect: $225/hr, Lead: $190/hr). | **4** | Compare their rates to market data from objective sources. |
| **References & Reputation** | Positive, relevant, and recent client references you can speak with. | **5** | Ask to speak with a reference from a project similar to yours. |
| **Security & Compliance** | Documented security policies and data handling procedures. | **4** | How do they ensure the security of your sensitive customer data? |
This checklist is about finding a partner, not just a vendor. The right firm delivers a solid platform and leaves your internal team more capable than it found them.
## Frequently Asked Questions
These are the most common questions from engineering leaders building an ecommerce data capability, with direct, evidence-based answers.
### What Are the First Three Data Pipelines an Ecommerce Business Should Build?
Focus on the pipelines with the biggest, fastest impact. Get these three right first.
1. **Single Source of Truth for Revenue:** Unify order data from platforms like [Shopify](https://www.shopify.com/) with payment details from gateways like [Stripe](https://stripe.com/). This becomes the reference source for all sales reporting, LTV models, and financial analysis.
2. **Marketing Attribution:** Pull in data from ad platforms ([Google Ads](https://ads.google.com/), Facebook Ads) and web analytics tools like [Google Analytics](https://analytics.google.com/). This pipeline builds an attribution model that answers where your best customers are actually coming from, and what they cost to acquire.
3. **Inventory and Catalog Sync:** Build a pipeline that syncs your product catalog with real-time inventory levels from your ERP or warehouse management system (WMS). This prevents overselling, which erodes customer trust fast and creates operational headaches.
### How Do I Justify the Cost of a Modern Data Stack to My CFO?
Frame the investment around three concrete business outcomes, not tech jargon.
1. **Revenue Lift:** A [modern data stack](/insights/modern-data-stack/) supports real-time personalization and recommendation features, which retailers commonly cite as a driver of higher average order value (AOV). Model what even a modest lift means for your top-line revenue before committing budget.
2. **Operational Efficiency:** Calculate the hours your marketing and finance teams spend manually compiling reports. Automating that work frees those hours for higher-value analysis - multiply the saved hours by average salary for a defensible cost case. A typical project timeline to reach this point is 4-6 months.
3. **Risk Mitigation:** Advanced analytics helps detect and reduce fraud losses that online retailers absorb as a routine cost of doing business. A solid data governance framework is also insurance against the fines tied to regulations like GDPR and CCPA.
### Should I Build Our Data Platform Internally or Hire a Consultant?
The decision is a classic build-vs-buy call that hinges on your team's skills and how fast the business needs results.
* **Hire a consultant if:** speed is the top priority. An experienced partner can deliver a production-ready platform on [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/) in **3-6 months**. A team learning and building at the same time can easily take over a year.
* **Build internally if:** you have time and the primary goal is developing deep technical expertise in-house. Slower, but it builds a long-term asset your team owns outright.
A hybrid model often works best: hire a consultant to design the architecture and train your team, then transition ownership to your internal engineers for ongoing development.
### What Are the Most Common Pitfalls in an Ecommerce Data Migration?
The biggest, most painful migration mistakes are almost always the same ones, and they're avoidable.
* **Underestimating Data History:** Teams focus on the new system and forget how messy the old one really is. They fail to plan for years of schema changes, manual data entry, and evolving business rules. This "data archaeology" work always takes longer than estimated.
* **Ignoring Business Users:** It's easy to get lost in technical details. Launch a new platform without rebuilding the dashboards finance and marketing depend on daily, and you'll disrupt the business and lose stakeholder trust in the process.
* **Hiring a Generalist for a Specialist's Job:** Don't hire a data firm that doesn't live and breathe ecommerce. If they don't understand the specifics of clickstream event data, order status changes, or multi-touch attribution, they'll build a system that needs a rebuild within a year.
---
To evaluate and choose a firm with confidence, compare the [top data engineering companies](/) on rates, platform focus, and ecommerce experience using research-driven profiles in a consistent format.
---
## Enterprise vs. Boutique Data Engineering Firms: How to Choose in 2026
Source: https://dataengineeringcompanies.com/insights/enterprise-vs-boutique-firms/
Published: 2025-12-19T10:00:00.000Z
Description: Compare global systems integrators and specialist data engineering firms by work shape, senior access, procurement risk, and total cost of ownership.
Decision in one sentence
Choose an enterprise systems integrator when scale, coordination, or procurement assurance is the hard constraint. Choose a boutique when specialist execution and senior decision density are the hard constraints. Choose a hybrid only when the handoffs are contractually clear.
The current [Data Engineering Companies Index dataset](/data/) contains 86 company records. Its numeric team-size fields run from 25 to 779,000, while published hourly lower bounds run from $45 to $250 with a $100 median. Those are directory fields, not realized billing rates or proof that one firm type delivers better outcomes.
Compare the delivery system with the production work you need to get accepted. This guide keeps the choice focused on firm structure, senior access, buyer-side risk, and total cost of ownership (TCO). The [enterprise data engineering hub](/enterprise-data-engineering/) covers enterprise certifications, SLAs, and the broader firm list; the [partner-selection framework](/insights/data-engineering-partner-selection/) covers the selection process after this decision.
## What is the difference between an enterprise systems integrator and a boutique data engineering firm?
An enterprise systems integrator combines data engineering with program management, cloud, application, and change capabilities across a large delivery network. A boutique specialist concentrates on a narrower technical domain and usually sells a smaller, more senior team. Neither label is a quality score.
| Factor | Enterprise systems integrator | Boutique specialist |
| :--- | :--- | :--- |
| **Primary constraint solved** | Coordinating many workstreams, regions, business units, and supplier requirements | Solving a defined platform, migration, modeling, or reliability problem with specialist practitioners |
| **Typical delivery shape** | Account leadership, architecture, project management, multiple delivery pods, and a wider bench | Named principal or architect, senior engineers, and a smaller delivery team |
| **Best initial fit** | Multi-workstream transformation, regulated procurement, global rollout, or a program that needs parallel capacity | A focused Snowflake, Databricks, dbt, warehouse, pipeline, or data-governance engagement |
| **Risk to test** | Whether the team that sold the work is the team that will build it, and how much junior or subcontracted capacity is included | Key-person continuity, bench depth, financial capacity, and the ability to cover the engagement if demand spikes |
| **Commercial proof to request** | Resourcing plan, senior allocation, escalation path, subcontractor disclosure, and contractual service commitments | Named team, backup plan, platform evidence, minimum project, rate assumptions, and a written handoff plan |
The examples in the current directory illustrate why the labels need context: [Accenture](/accenture/), [Deloitte](/deloitte/), and [TCS](/tata-consultancy-services-tcs/) sit alongside specialist records such as [Analytics8](/analytics8/), [Hakkoda](/hakkoda/), [Hashmap](/hashmap/), and [phData](/phdata/). The profile fields help create a shortlist; they do not replace project-specific verification.
## Which project constraints favor each model?
Enterprise firms fit programs where coordination, contractual assurance, and parallel staffing dominate. Boutiques fit contained technical work where senior attention and platform depth dominate. A hybrid model fits only when one accountable owner can control the boundaries between the two delivery systems.
| Project condition | Starting model | Evidence to request before shortlisting | Why it matters |
| :--- | :--- | :--- | :--- |
| Multiple countries, business units, or technology workstreams must move together | **Enterprise systems integrator** | Country and workstream staffing plan, escalation structure, subcontractor map, and named delivery owner | The main risk is coordination failure, not a missing implementation pattern |
| One platform migration or a contained modernization has a defined outcome | **Boutique specialist** | Named architect, comparable migration evidence, role-by-role estimate, acceptance criteria, and backup coverage | Senior decision density can matter more than a large bench |
| Technical depth is essential, but procurement requires a larger parent’s contracting capacity | **Hybrid or specialist under a larger parent** | Contracting entity, parent guarantees, named specialist team, access to parent capacity, and exit terms | The parent relationship is useful only if it changes the obligations you can enforce |
| The work is ongoing operations with incident coverage and predictable change queues | **Enterprise or managed specialist** | On-call roster, incident targets, runbooks, succession plan, and support pricing | Run-state resilience is a different requirement from a one-time build |
Do not use geography as a proxy for this decision. The [onshore, nearshore, offshore, and hybrid delivery guide](/insights/us-vs-offshore-data-engineering/) covers working-hour overlap, data access, and cross-border controls separately.
## What does the current directory data say about size and rates?
The directory does not produce a clean size-to-price rule. In the July 20, 2026 dataset, 3 of 86 records fall under 50 in the numeric team-size field, 34 fall between 50 and 499, and 49 are 500 or higher; lower-bound rates span $45–$250/hr with a $100 median.
| Directory field | Current value | How to use it |
| :--- | :--- | :--- |
| **Numeric team-size field** | 25–779,000 across 86 records | Use as a capacity screen; ask how many people can actually work on your stack and time zone |
| **Under 50 in the field** | 3 records | Test key-person cover, financial capacity, and what happens when the lead is unavailable |
| **50–499 in the field** | 34 records | Test whether the firm can provide a backup team without turning into a generic staffing vendor |
| **500+ in the field** | 49 records | Test named senior allocation, team substitution, subcontractors, and delivery-pod ownership |
| **Published hourly lower bound** | $45–$250/hr; $100 median | Use for an initial budget screen, not as a realized rate or market average |
The [directory statistics page](/data/) states the boundary clearly: these figures describe the published records in this directory, not the entire data engineering market. A firm’s team count also does not tell you whether its senior people will be available for your engagement.
## How should you compare total cost of ownership?
Compare the cost of an accepted production outcome, not the price of an hour. TCO includes vendor fees plus client coordination, rework, delay, security and procurement effort, and transition work. A higher rate can be rational when it removes work the buyer would otherwise absorb.
Use the same scope and assumptions for every finalist:
| TCO line item | Calculation to make | Question for the proposal |
| :--- | :--- | :--- |
| **Vendor delivery** | Sum of hours by role multiplied by each role’s rate | Which architect, engineer, QA, and delivery-management hours are included? |
| **Client coordination** | Internal review and decision hours multiplied by your loaded internal cost | How much access to your product, security, and domain teams does the plan assume? |
| **Rework** | Expected rejected deliverables, defect correction, backfills, and redesign | What tests and acceptance gates catch errors before they become your team’s work? |
| **Delay** | Business cost per week multiplied by the weeks between planned and accepted production use | What must be true for the date to hold, and who owns each dependency? |
| **Security and procurement** | Access reviews, legal work, audit evidence, and supplier onboarding | Which controls, attestations, subprocessors, and approvals are outside the quote? |
| **Transition** | Runbooks, paired delivery, training, shadowing, and access removal | What remains in your repositories and what does the final handoff include? |
The worksheet prevents a common mistake: comparing a boutique’s senior rate with an enterprise firm’s blended rate while ignoring the role mix and buyer effort behind each quote. The [data engineering consulting rates guide](/insights/data-engineering-consulting-rates-2026/) is the right place for market-rate context; this page uses rates only to explain the TCO decision.
## How should procurement and continuity change the choice?
NIST’s October 2024 [Cybersecurity Framework 2.0 supply-chain guide](https://csrc.nist.gov/pubs/sp/1305/final) treats the buyer as a “smart acquirer” and points to the GV.SC category for defining supplier requirements. Apply that logic to the partner’s criticality, access, accountability, and exit plan.
Use five gates before a firm reaches the final round:
1. **Criticality:** What would stop or degrade if this supplier failed during the migration or the first production month?
2. **Access:** Which people, repositories, environments, and data fields can the supplier access? Require named accounts, least privilege, and an audit trail where the project needs them.
3. **Accountability:** Who owns architecture decisions, acceptance, security exceptions, incident escalation, and the final handoff?
4. **Continuity:** What backup covers the lead architect, the delivery manager, and the platform specialist? What happens if the firm loses a key person or cannot staff the next phase?
5. **Contract and exit:** Which requirements belong in the MSA or SOW: security evidence, insurance, change control, deliverables, service commitments, IP ownership, access removal, and transition support?
Firm size can make some controls easier to evidence, but it does not replace the evidence. A boutique with a credible security program and a named backup can satisfy a contained engagement’s requirements; a global firm still needs to commit the people in its proposal. The [35-criterion vendor evaluation guide](/insights/data-engineering-vendor-evaluation-criteria/) covers the full verification scorecard.
## When does a boutique-at-scale or hybrid model make sense?
A hybrid partner can combine specialist platform knowledge with a larger parent’s contracting and delivery capacity, but the buyer must verify what the parent actually provides. Hashmap is a concrete historical example: NTT DATA announced the completed acquisition on January 4, 2021, and said Hashmap would operate as an NTT DATA company.
The structure is useful only when the contract and delivery plan make the relationship real. Ask:
- Which entity signs the MSA and carries the delivery, security, and liability obligations?
- Are the specialists named in the SOW, and can they be replaced only under an agreed process?
- Is the parent’s bench available to this project, or is it only a sales-deck reference?
- Which accelerators, code, and documentation belong to you at handoff?
- Does the commercial model reflect a specialist team, a global delivery pod, or both?
Read the [NTT DATA acquisition notice](https://www.nttdata.com/en-us/news/2021/hashmap-acquired) for the historical fact, then verify the current operating model in the [Hashmap profile](/hashmap/) and in the proposed contract. An acquisition or parent relationship is a structure to test, not a substitute for a named team.
## What should the hiring decision look like?
Start with the constraint that can make the project fail, then choose the delivery model that directly addresses it. Validate the proposed people and controls, normalize each quote into TCO, and only then use the wider partner-selection process to compare finalists.
1. **Name the failure mode.** Is the risk missed coordination, missing platform depth, insufficient continuity, or an unworkable procurement path?
2. **Classify the work.** Separate discovery, architecture, implementation, and run-state operations; one project may need more than one delivery model.
3. **Set non-negotiables.** Write down data access, required platforms, named roles, acceptance criteria, budget envelope, and exit conditions before vendor presentations shape the decision.
4. **Request comparable proof.** Ask every firm for the same role mix, assumptions, references, technical deliverables, and handoff evidence. Use the [partner-selection framework](/insights/data-engineering-partner-selection/) for the full process.
5. **Compare accepted outcomes.** Put each proposal through the TCO worksheet, then negotiate the clauses that protect the people, code, data access, and transition.
## What should you ask before signing?
Ask questions that expose the delivery system behind the brand: who will make decisions, who will write and review the code, what happens when a key person leaves, and which buyer-side costs or handoff obligations are missing from the headline rate.
1. Who specifically will work on the engagement, and what percentage of the delivery is allocated to each role?
2. What happens if the lead architect or platform specialist leaves before the next milestone?
3. Which hours, dependencies, security reviews, and change requests are outside the proposal?
4. What evidence supports the team’s claimed platform depth and comparable delivery experience?
5. What documentation, repository access, training, and transition support are contractual deliverables?
The answers should change the commercial comparison. If they do not, the proposals are probably hiding the real difference in role mix, risk, or buyer effort.
## Conclusion: choose the operating model, not the label
Choose an enterprise systems integrator when the program’s hard problem is scale, coordination, supplier assurance, or parallel delivery. Choose a boutique when the hard problem is specialist execution and senior decision density. Choose a hybrid when both are required and the contract proves how the handoffs work.
Use the [Data Engineering Companies Index](/data-engineering-consulting-firms/) to compare firms by rate, platform focus, industry, team size, and fit. Treat those fields as shortlist inputs, then verify the people and assumptions attached to your project.
Compare firms by fit, not label
Use the directory to compare data engineering partners by rate, platform, industry, team size, and engagement fit.
---
## Best ETL Tools for Data Integration: A Practical Comparison
Source: https://dataengineeringcompanies.com/insights/etl-tools-comparison/
Published: 2026-01-24T08:32:10.176166+00:00
Description: Compare Fivetran, Airbyte, Matillion, Informatica, AWS Glue, and dbt by connector reliability, CDC, schema drift, deployment, and pricing model.
The best ETL tool is the one that can move your highest-risk source reliably at a cost you can forecast. **Fivetran is a strong default for teams that want managed ELT with little connector maintenance. Airbyte fits teams that need deployment control or custom connectors. Matillion suits visual, warehouse-centered pipelines. Informatica fits complex enterprise estates. AWS Glue fits AWS-native engineering teams. dbt transforms loaded data; it is not a general-purpose ingestion replacement.** ETL is one layer of a larger [data pipeline](/data-pipeline/) - the tool you pick here needs to fit the ingestion, transformation, and orchestration choices you've already made elsewhere in the stack.
## Which ETL tool fits each operating model?
| Tool | Best fit | Deployment | Transformation | Pricing unit to model | Main tradeoff |
| :--- | :--- | :--- | :--- | :--- | :--- |
| **Fivetran** | Managed SaaS and database replication | Managed cloud | dbt integration and quickstart models | Monthly Active Rows, connection charges, model runs | Low maintenance, but row activity can make cost hard to predict |
| **Airbyte** | Custom sources and deployment control | Cloud or self-managed | Optional integrations | Capacity, credits, or infrastructure and labor | Flexible, but self-management transfers reliability work to your team |
| **Matillion** | Visual ELT around cloud warehouses | SaaS with deployed agents | Visual orchestration and SQL pushdown | Credits and underlying warehouse compute | Productive for SQL teams, but total cost spans two meters |
| **Informatica** | Hybrid estates, governance, and enterprise controls | Cloud and hybrid | Broad integration and transformation suite | Contracted capacity and consumption metrics | Deep capability with more implementation and administration overhead |
| **AWS Glue** | AWS-native batch and streaming integration | AWS serverless | Spark-based jobs and visual tooling | Data Processing Units and execution time | Strong AWS fit, but more engineering ownership than managed connector SaaS |
| **dbt** | Warehouse transformations after ingestion | Cloud or self-managed Core | SQL-based transformation and testing | Seats, model runs, orchestration, and warehouse compute | Excellent transformation layer, but it does not replace source extraction |
This is a category comparison. For the narrower managed-versus-open-source ingestion decision, see [Fivetran vs Airbyte](/insights/fivetran-vs-airbyte/).
## What is the best ETL tool for a modern data warehouse?
**Choose Fivetran when reducing pipeline maintenance is more important than controlling every connector. Choose Airbyte when custom sources, self-hosting, or connector code ownership are requirements. Choose Matillion when your team wants visual orchestration close to Snowflake, Databricks, or BigQuery.**
The destination does not decide the tool by itself. Start with the source that is hardest to replicate: a high-change transactional database, a rate-limited SaaS API, or a source with frequent schema changes. A tool that handles ten simple sources but fails on the critical one is not the right platform.
Treat dbt as a separate layer in this decision. Its core job is to turn data already in a warehouse into tested, documented models - see our [modern data stack](/insights/modern-data-stack/) guide for how the layers above and below ingestion fit together. Pairing an ingestion service with dbt is common because extraction reliability and transformation logic have different owners and failure modes. Among the 86 firms profiled in the Data Engineering Companies Index, only 20 name dbt directly in their stack, while 78 name data migration among their capabilities - transformation work is a narrower specialty than ingestion and migration.
## When is managed ELT worth the premium?
Managed ELT earns its premium when connector upkeep is distracting engineers from work unique to the business. Compare the annual vendor bill with the real cost of ownership:
- Engineering time spent responding to API changes, expired credentials, schema drift, and failed backfills.
- On-call coverage and the cost of stale or duplicated data.
- Destination compute used by loading, deduplication, and transformations.
- Security reviews, private networking, regional hosting, and audit requirements.
- Time needed to build a connector the catalog does not cover well.
Do not assume managed means maintenance-free. Your team still owns source permissions, data contracts, incident response, downstream tests, and cost controls. The vendor should remove connector mechanics, not accountability.
## How should you compare connector coverage and reliability?
Connector count is only a screening signal. Test connector depth with the exact objects and change patterns you use.
1. **Coverage:** Confirm required tables, fields, API endpoints, and regional variants. Check whether the connector is generally available, beta, community-maintained, or custom.
2. **Change data capture:** Verify the supported CDC method, source prerequisites, delete handling, and recovery after log retention expires.
3. **Schema drift:** Add, rename, and change the type of a test column. Observe whether the sync pauses, mutates the destination, or creates a new field.
4. **Recovery:** Interrupt a sync, rotate credentials, and trigger a backfill. Confirm checkpointing and duplicate handling.
5. **Freshness evidence:** Measure source-to-destination latency at normal volume and during peak activity.
6. **Observability:** Require per-connection logs, alerts, usage data, and an API or export that your monitoring stack can consume.
Run these tests on production-like data. A clean demo dataset does not expose rate limits, long transactions, large objects, or awkward deletion semantics.
## What costs sit outside the advertised price?
The headline unit rarely equals total cost. Fivetran measures connection usage using Monthly Active Rows, so updates and deletes affect consumption while initial syncs and certain resyncs are treated differently under its current rules. AWS Glue meters processing resources and duration. Matillion uses credits while transformations can also consume warehouse compute. Self-managed Airbyte adds infrastructure, upgrades, and support labor.
Build a 12-month model with these rows:
| Cost component | Evidence to collect |
| :--- | :--- |
| Vendor consumption | Export from a trial under normal source activity |
| Destination compute | Warehouse query and loading history |
| Network and storage | Cross-region transfer, staging, and retained raw data |
| Operations | Incidents, upgrades, connector fixes, and on-call time |
| Change | New sources, backfills, acquisitions, and volume growth |
| Exit | Historical reload, parallel run, and contract overlap |
Model changed rows, not just table size. A small table updated repeatedly can cost more than a large append-only table under row-activity pricing.
## When should you build instead of buy?
Build a connector when the source is proprietary, the extraction logic is a durable competitive capability, or vendor constraints cannot meet security and latency requirements. Buy when the source is standard and the work is mostly authentication, pagination, incremental state, schema handling, and retries.
A useful rule is to build only after naming the permanent owner. The initial connector may be small; the long-term product includes monitoring, replay, API-version migrations, tests, documentation, and incident response.
For a custom source, compare three options during the pilot: a vendor connector SDK, an open connector framework, and a small internal service. The best choice is the one your team can operate during an upstream outage, not the one that produces the shortest prototype. See [data pipeline architecture examples](/insights/data-pipeline-architecture-examples/) for how these ingestion choices play out across batch, streaming, and hybrid designs.
## How do you run a defensible ETL tool evaluation?
Use a four-week proof of concept with one difficult database source, one SaaS API, and one representative destination.
- **Week 1:** Define freshness, completeness, recovery, security, and cost acceptance criteria before installing tools.
- **Week 2:** Configure the same source objects and destination schemas in each finalist.
- **Week 3:** Test schema changes, deletes, credential rotation, backfills, and a forced interruption.
- **Week 4:** Compare evidence, including engineering hours and destination compute, then document the exit path.
Score capabilities by business impact rather than weighting every feature equally. If a failed finance pipeline delays close, recovery behavior deserves more weight than the number of prebuilt connectors.
## What should the final ETL decision record contain?
Record the selected tool, rejected alternatives, tested sources, observed latency, recovery results, security constraints, pricing assumptions, and the owner of each remaining operational task. Add a review trigger such as a major new source, a 2x volume increase, or a contract renewal.
That record prevents the tool from becoming an unquestioned default. Data integration platforms improve, pricing models change, and your source mix will shift. Revisit the evidence when the assumptions change, not on an arbitrary feature-release cycle.
If you need implementation help, compare [data pipeline consulting companies](/data-pipeline-consulting/). For reliability after ingestion, use the separate [data pipeline monitoring tools comparison](/insights/data-pipeline-monitoring-tools/).
---
## Fivetran vs Airbyte: An Enterprise TCO Analysis for 2026
Source: https://dataengineeringcompanies.com/insights/fivetran-vs-airbyte/
Published: 2026-04-14T07:26:25.231353+00:00
Description: Choosing between Fivetran vs Airbyte? This enterprise guide analyzes TCO, reliability, and connector quality to help you decide beyond the feature list.
Fivetran and Airbyte both move data from source systems into a warehouse, but they sell opposite operating models. Fivetran is a managed service: you pay a vendor to own uptime, connector maintenance, and schema handling. Airbyte is a more open platform: the entry price is lower, but more of that operational work shifts onto your own team, especially if you self-host. The real decision in **fivetran vs airbyte** isn't which tool is cheaper on a pricing page - it's whether you want to buy operational certainty or build it yourself.
Ingestion tooling choices like this one show up constantly in data engineering work: 78 of the 86 firms profiled in the [Data Engineering Companies Index](/data-migration-companies/) list data migration among their capabilities, and the ELT tool you pick here determines how much of that ongoing pipeline work your own team ends up owning versus handing to a vendor or an implementation partner.
This is fundamentally a data pipeline architecture decision. It shapes your ingestion operating model across Snowflake, Databricks, BigQuery, dbt, and orchestrators such as Airflow. Pick the wrong tool and you don't just overpay - you lock your data team into the wrong kind of work for years.
## Why isn't the Fivetran vs Airbyte decision just about price?
Airbyte usually wins the procurement screenshot: its cloud pricing starts lower and the open-source edition is free to run. That comparison is incomplete to the point of being misleading, because it ignores who absorbs the work of keeping pipelines running when source APIs change.
A principal architect looks at **total cost of ownership**, not the subscription page. Fivetran's list pricing is usage-based, billed per monthly active row, with a free tier up to 500,000 MAR and cost scaling from there as volume grows ([Fivetran pricing](https://www.fivetran.com/pricing)). Airbyte's plans run on volume-based or compute-based tiers, also starting free ([Airbyte pricing](https://airbyte.com/pricing)). Neither list price tells you what the platform costs to operate.
That first-pass view breaks down in production.
### What CTOs actually buy
You're not buying sync jobs. You're buying four things:
- **Operational certainty**. Will core pipelines keep running when source APIs change?
- **Team focus**. Will data engineers spend time on modeling and platform adoption, or on connector maintenance?
- **Risk posture**. Who owns uptime, support, and incident resolution?
- **Scalability path**. Does the platform get easier or harder to operate as the estate grows?
> **Practical rule:** If your team's competitive advantage isn't building and operating ingestion infrastructure, treat "flexibility" as a cost center unless it directly gives you access to a source you can't otherwise reach.
### The hidden asymmetry
Fivetran sells a managed service. Airbyte sells optionality.
That sounds abstract, but the consequences are concrete. Fivetran's model is opinionated and narrower. Airbyte's model is extensible and broader. The trade-off is that one pushes complexity onto the vendor, while the other gives your team the ability, and the burden, to absorb that complexity.
For enterprises, that burden compounds in second-order ways:
- Security review gets harder when you self-host and own more of the runtime.
- Staff planning gets harder when Kubernetes and connector debugging become part of the data platform remit.
- Roadmaps slip when warehouse migration teams get pulled into ingestion incidents.
- Data governance programs stall when engineers spend cycles stabilizing extractors instead of defining controls in dbt, catalogs, and access policies.
If you frame **fivetran vs airbyte** as a line-item software comparison, Airbyte often looks attractive. If you frame it as an operating model choice, the decision changes fast.
## What's the real difference in philosophy between Fivetran and Airbyte?
The divide isn't managed versus open source in the abstract. It's whether you want ingestion to be a software purchase your team consumes, or an internal operating function your team runs.
### Side by side for executives
| Dimension | Fivetran | Airbyte |
|---|---|---|
| Core philosophy | Managed ELT service with vendor-owned operations | Open-source and cloud ELT platform with more customer-owned decisions |
| Best fit | Enterprises optimizing for predictable delivery and lower platform labor | Technical teams willing to trade labor for flexibility and connector coverage |
| Connector posture | Curated, vendor-maintained catalog | Broad catalog with stronger long-tail and custom connector options |
| Cost pattern | Higher visible software spend, lower internal maintenance burden | Lower entry price, but operating cost can rise with support, hosting, and engineering time |
| Leadership question | Do we want to buy reliability as a service? | Do we want to build ingestion capability as part of the platform team? |
The strategic choice is easy to describe and easy to underestimate. Fivetran concentrates responsibility with the vendor. Airbyte distributes more of that responsibility back to your team, especially if you self-host or depend on custom connectors. The first-order difference is control. The second-order difference is who absorbs outages, schema drift, API changes, and connector regressions.
That second-order effect matters more than the headline price.
### The strategic split
Fivetran fits organizations that treat data ingestion as plumbing. The goal is to keep source systems flowing into the warehouse with minimal debate, minimal customization, and clear accountability when something breaks. That usually maps well to larger companies with strict delivery commitments, thin data platform teams, or a mandate to keep senior engineers focused on modeling, governance, and adoption instead of connector operations.
Airbyte fits organizations that treat ingestion as part of their product surface. It makes sense when proprietary APIs, internal systems, regional tools, or unusual security constraints make standard connectors insufficient. In those cases, flexibility has real economic value because it avoids waiting on a vendor roadmap. The trade-off is that flexibility becomes a staffing decision, not just a product feature.
> Fivetran optimizes for outsourced operational burden. Airbyte optimizes for retained architectural control.
Control is not automatically the better enterprise outcome. It pays off when you have the engineering depth to use it consistently, document it, support it, and keep it reliable under growth.
### My short version
Choose based on the team you expect to have 12 months from now, not the demo you saw this quarter.
If you want data engineers spending their time on semantic models, governance, and stakeholder-facing data products, Fivetran is usually the cleaner operating model. If you want the data platform team to own ingestion as a configurable internal service, Airbyte can be the better fit. For many enterprises, that distinction decides total cost of ownership more than licensing ever will.
## How do Fivetran and Airbyte differ in architecture and deployment?
Fivetran runs as a managed SaaS platform, with hybrid deployment options for on-premises processing in regulated environments. Airbyte offers both a cloud and a self-hosted path - the self-hosted route trades a lower list price for more infrastructure ownership on your team.
### Managed runtime versus owned runtime
Architecture decides who carries the pager. If you need a broader refresher on the ingestion design choices around orchestration, transformations, and warehouse loading, this comparison of [ETL tools](/insights/etl-tools-comparison/) is useful because it frames the tool choice inside full platform architecture rather than as a standalone procurement decision.
The implication is straightforward:
- With **Fivetran**, the vendor owns more of scaling, connector upkeep, and runtime reliability.
- With **Airbyte Cloud**, you get a partial transfer of that burden.
- With **self-hosted Airbyte**, your team owns much more of the platform surface.
### Security and compliance review
For regulated environments, architecture affects approval speed as much as features do.
A managed service usually shortens review on infrastructure operations because fewer runtime components sit inside your estate. A self-hosted platform often gives security teams more control over deployment boundaries, but it also gives them more to inspect: cluster configuration, secrets handling, upgrade discipline, logging, patching, and network patterns.
Many teams underestimate the cost of "more control." Security organizations don't just want control. They want evidence that the control is implemented consistently.
> When the ingestion platform is self-hosted, the question isn't whether you can secure it. The question is whether you can secure it repeatedly during upgrades, incidents, and team turnover.
### Team shape changes with the tool
The tooling choice changes who you need to hire or borrow from adjacent teams.
| Deployment concern | Fivetran impact | Airbyte impact |
|---|---|---|
| Platform operations | Lower internal burden | Higher burden, especially self-hosted |
| Kubernetes expertise | Usually minimal | Material requirement for self-hosted scale |
| Incident ownership | More vendor-led | More internal, especially for custom sources |
| Upgrade management | Mostly outsourced | Internal planning and testing burden |
That means Airbyte isn't just a product choice. It's a staffing decision. If your data engineering team already depends on a central platform or SRE function, Airbyte can fit cleanly. If your data team is expected to move quickly with limited infrastructure support, the same choice becomes friction.
### The architectural consequence most teams miss
The longer your source estate grows, the more architecture turns into governance. Every new connector becomes part of a control surface involving lineage, access, SLAs, and failure response.
A managed platform keeps that surface tighter. A framework expands it. Neither is inherently better, but only one of them reduces the number of systems your own team has to operate.
## Does a bigger connector catalog actually mean a better fit for your stack?
Connector count is a weak proxy for enterprise fit. What matters is the percentage of production-safe connectors for the systems tied to revenue, finance, compliance, and executive reporting - not the total number of logos on a comparison page.
Airbyte's larger catalog and low-code CDK make it attractive for teams with niche SaaS tools, internal APIs, or proprietary systems. That flexibility is real. It also shifts more responsibility to your engineers, because a connector only creates value if it stays current as source schemas, authentication methods, and API limits change.
### For enterprise use, a connector should be evaluated on:
- **Maintenance ownership**. Who patches the connector when the source platform changes behavior?
- **Schema evolution handling**. Does it absorb source changes cleanly, or does your team have to rework ingestion logic and downstream models?
- **Security controls**. Are features such as column-level blocking or hashing available natively?
- **Support model**. Is production support handled through a vendor SLA or a community issue queue?
- **Operational predictability**. Can the connector be trusted for regulated or business-critical datasets?
Those criteria matter more than the raw number of logos on a comparison page. A broad catalog increases option value. It does not reduce operating cost unless the connectors are consistently maintained. For a broader framework on evaluating integration tooling beyond the connector list, see [data integration best practices](/insights/data-integration-best-practices/).
Fivetran is stronger where standardization matters. Its vendor-maintained connectors for common enterprise systems reduce the odds that your team spends time tracing failures caused by source-side API changes or unexpected schema drift. That has second-order effects: fewer ingestion surprises means less rework in dbt, fewer broken dashboards, and fewer hours lost to cross-team incident coordination.
Airbyte is stronger where customization is part of the job. If you need to ingest an internal product API, support a niche application with limited market demand, or treat connectors as code inside your own platform engineering practice, Airbyte's CDK gives you a path that managed SaaS products usually don't.
That advantage has a cost profile many teams understate.
A custom or community connector can be inexpensive to start and expensive to keep. Every source change becomes an internal maintenance event. Every production incident requires someone who understands the connector code, deployment environment, and downstream dependencies. In small volumes, that's manageable. Across dozens of connectors, it turns into recurring platform work.
> A connector you can build quickly is not automatically a low-cost connector. The cost shows up later, in maintenance ownership, incident response, and upgrade testing.
### A better procurement lens
Ask each vendor, or your implementation partner, to classify connectors source by source.
| Connector question | Why it matters |
|---|---|
| Is it vendor-maintained or community-maintained? | Defines who owns break-fix work |
| How are source schema changes handled? | Affects downstream model stability |
| Which security controls are native? | Influences governance and approval effort |
| What support path exists in production? | Shapes time to resolution during incidents |
| Is the connector approved for regulated or high-impact data? | Separates experimental coverage from production-grade coverage |
This reframes the decision from connector quantity to connector liability. Enterprises rarely fail because they lack a connector in theory. They fail because too many connectors become small systems their own team has to operate.
## How reliable are Fivetran and Airbyte for enterprise-grade workloads?
Fivetran's enterprise argument rests on managed reliability. Fivetran cites an IDC-commissioned study on its own comparison page claiming an average annual benefit of $1.5 million per organization, $177,000 in annual operational cost savings, and 48% more productive data engineers, alongside a 99.9% uptime SLA across its 700+ connectors ([Fivetran vs Airbyte comparison](https://www.fivetran.com/compare/fivetran-vs-airbyte)). Treat vendor-commissioned figures like these as directional rather than independently audited.
### Reliability is a staffing issue
Leaders often treat uptime as a technical metric. It's also a people metric.
When pipelines break, someone has to:
- identify whether the problem sits in the source, connector, network path, warehouse, or transformation layer
- decide whether to retry, patch, backfill, or pause downstream jobs
- communicate impact to analytics, finance, product, and leadership
- absorb the cost of context switching across the engineering team
Fivetran reduces that burden by keeping connector operations inside the vendor boundary. Airbyte leaves more of it with your team, especially when self-hosted or when relying on community-maintained components.
### The SLA nuance matters
It's easy to compare headline uptime and conclude the gap is small. That reading is shallow.
The meaningful distinction isn't only platform uptime. It's **connector-level enterprise support coverage**. Airbyte's cloud offering provides a 99% uptime SLA only on its "Airbyte Managed" connectors, which Fivetran's own comparison materials put at roughly 15% of Airbyte's source connectors ([Fivetran vs Airbyte: features, pricing, services](https://www.fivetran.com/blog/fivetran-vs-airbyte-features-pricing-services-and-more)). That's a competitor's characterization of Airbyte's catalog, so treat the exact percentage as approximate, but the underlying point is worth verifying directly with Airbyte: ask which of your specific connectors carry an SLA before you commit to them for business-critical data.
That variation is tolerable for experimentation. It's a problem for payroll, revenue, regulated reporting, or migration-critical workloads.
### Schema drift is where production trust is won
Most ingestion incidents don't look dramatic at first. A source field changes. An API shifts behavior. A data type widens. Then a dbt model breaks, a dashboard goes stale, or a machine learning feature table drifts.
Fivetran's position is stronger where automatic handling of schema and API changes is mandatory and where CDC depth matters in database migrations to Snowflake or Databricks. Airbyte can serve these environments too, but the operating discipline has to come from your own team.
> Enterprise readiness isn't a feature checklist. It's the percentage of your ingestion estate that your organization can trust without heroic effort.
### Where Airbyte is still viable
Airbyte remains a valid enterprise choice when reliability engineering is deliberate, not accidental. Teams that standardize self-hosting, maintain certified connector standards internally, and treat ingestion as a platform capability can make Airbyte work well.
But that's a narrower set of organizations than most comparison posts admit. If your data team already struggles to keep Airflow, dbt, warehouse permissions, and observability in shape, adding ingestion runtime ownership will add to that pressure.
## What's the real total cost of ownership for Fivetran versus Airbyte?
The cheapest line item on a pricing page is often not the cheapest platform in production. A full TCO model has to include engineering time, infrastructure, connector maintenance, and security review, not just the invoice.
### Why list pricing misleads buyers
Airbyte's low entry price and open-source posture make it look financially safer at first glance. Fivetran's invoice is easier to notice because the vendor charges you directly. Airbyte often charges you indirectly, through engineering time, infrastructure, support processes, and reliability work that moves onto your team.
That distinction matters more than the starting subscription tier.
A realistic TCO model should account for:
- software or usage charges
- cloud infrastructure and networking
- platform engineering and SRE time
- connector maintenance and incident response
- security reviews, access controls, and compliance work
- delivery delays caused by ingestion instability
For teams estimating hosting and runtime costs, the [AWS Pricing Calculator](https://aws.amazon.com/aws-cost-management/aws-pricing-calculator/) is useful because it forces infrastructure into the model instead of treating self-hosting as a rounding error.
### The largest cost line is usually headcount
The central question isn't whether Airbyte can cost less. It can. The question is under what operating conditions it stays less expensive over two to three years.
Self-hosting Airbyte shifts work onto internal teams, especially around Kubernetes operations, upgrades, and maintenance, while managed tooling reduces that burden by absorbing more of the runtime responsibility into the vendor service ([Windsor's comparison of Fivetran and Airbyte TCO](https://windsor.ai/fivetran-vs-airbyte/) walks through this tradeoff in more depth). For an enterprise, that difference changes staffing plans, on-call design, and the amount of senior engineering capacity tied up in plumbing rather than data products.
In this situation, many business cases break.
A buying committee sees a lower software line item and assumes savings. The actual result can be one more platform that needs ownership, escalation paths, patching windows, connector QA, and someone accountable when the CFO dashboard is wrong at 7 a.m. If your team already runs Airflow, dbt, warehouse performance tuning, IAM, and observability, ingestion runtime ownership isn't free capacity. It's a new operational surface area.
### Build-versus-buy logic applies at the ingestion layer
The same economics behind broader platform decisions show up here in a smaller but more frequent form. Teams evaluating [build versus buy for a modern data platform](/insights/build-vs-buy-data-platform/) should apply the same discipline to ingestion, because connectors create recurring operational work, not one-time implementation work.
| TCO component | Fivetran | Airbyte |
|---|---|---|
| Budget predictability | Higher for team effort, lower for consumption spikes | Higher for software entry cost, lower for labor certainty |
| Infrastructure ownership | Minimal | Meaningful, especially self-hosted |
| Internal skill requirement | Data engineering and admin oversight | Data engineering plus platform ops, often Kubernetes |
| Cost volatility driver | Data volume, sync frequency, MAR-style pricing | Reliability work, connector upkeep, infra tuning, support load |
| Main financial risk | Vendor spend grows with usage | Internal labor grows with scope and criticality |
The non-obvious conclusion is that Airbyte becomes more attractive as your organization behaves more like a software platform company. If you already have strong internal SRE and platform engineering, and if ingestion ownership fits that operating model, Airbyte can be economically rational. If you don't, its apparent savings can turn into hidden payroll and slower delivery.
Here's a useful walkthrough before you finalize a financial model:
### My TCO view as an architect
For standard enterprise ingestion, Fivetran often has the lower real cost even when the annual contract is higher. You're buying fewer operational decisions, fewer failure modes, and fewer demands on scarce senior engineers.
Airbyte is the better economic choice in a narrower set of cases: unusual sources, a clear need for connector control, and a team that's already staffed to run data infrastructure as an internal product.
The mistake is treating open source as free. In enterprise environments, open source often means you pay in labor, response time, and execution risk instead of paying the vendor invoice.
## How do you actually decide between Fivetran and Airbyte?
Run the decision through operational criteria instead of product marketing. The checklist and RFP questions below are the two artifacts that make the choice defensible to a budget owner.
### Fivetran vs Airbyte decision checklist
| Evaluation Criteria | Favors Fivetran | Favors Airbyte |
|---|---|---|
| Core sources are mainstream SaaS and databases | Yes | No |
| Need custom or proprietary connectors | No | Yes |
| Team has limited Kubernetes or platform ops capacity | Yes | No |
| Enterprise support consistency matters across production pipelines | Yes | No |
| Vendor neutrality is a strategic requirement | No | Yes |
| Goal is fastest path to stable Snowflake or Databricks ingestion | Yes | No |
| Team wants to own connector logic as code | No | Yes |
| Governance and compliance are prioritized over flexibility | Yes | No |
### Questions to use in an RFP
Use these with vendors and implementation partners:
1. **Which required connectors are vendor-maintained versus community-maintained?**
2. **How are schema changes handled without manual remediation?**
3. **Who owns incident response for failed syncs in production?**
4. **What skills must exist in-house on day one and after handover?**
5. **What part of the runtime needs Kubernetes, DevOps, or SRE support?**
6. **How will the tool fit with dbt, Airflow, Snowflake, Databricks, or BigQuery already in scope?**
7. **What is the support path for regulated or business-critical data sources?**
8. **What work remains internal after the consultancy exits?**
### Final recommendation
Choose **Fivetran** if your leadership priority is speed, predictability, and reduced operational burden. Fivetran's own comparison materials lean into exactly this framing: automatic schema handling, 24/7 support on every connector, and consumption-based pricing are positioned as ways to compress rollout timelines and reduce migration risk ([Fivetran vs Airbyte: features, pricing, services](https://www.fivetran.com/blog/fivetran-vs-airbyte-features-pricing-services-and-more)).
Choose **Airbyte** if you have a strong internal platform mindset, expect significant custom-source work, and want your engineers to own the ingestion layer as a strategic capability.
> Buy Fivetran when ingestion is infrastructure you want to consume. Buy Airbyte when ingestion is infrastructure you want to operate.
For most enterprises, default to Fivetran unless there's a clear connector or control requirement that justifies owning more of the stack.
## How do you choose an implementation partner once you've picked a tool?
Your tool choice should dictate your partner shortlist. A Fivetran rollout partner needs to be excellent at source-to-target design, warehouse modeling, dbt conventions, governance mapping, and migration sequencing, with fast implementation and low drama as the core value. An Airbyte rollout partner needs that same data engineering skill plus comfort with platform operations, self-hosting patterns, release management, Kubernetes, and long-term support design.
According to DataEngineeringCompanies.com's analysis of the 86 data engineering firms in the Index, the strongest partner selections come from matching the consultancy's capability model to the operating burden of the tool, not just its badge list. Rates for this kind of work run $45 to $250 an hour across the Index, median around $100, so budget for that range before you scope the RFP - and weight it toward the higher end if you're hiring for Airbyte's platform-ops demands specifically. That distinction matters more with Airbyte because the implementation partner often shapes the runtime you'll inherit.
If they can't explain how they'll operationalize connector ownership after handoff, they're not the right partner.
A practical screen:
- **For Fivetran projects**, ask how they accelerate warehouse rollout and dbt adoption.
- **For Airbyte projects**, ask who owns upgrades, connector fixes, and cluster operations six months after go-live.
- **For both**, ask for a handover plan, governance model, and production support boundary.
If you're evaluating firms for an Airbyte implementation specifically, start with this shortlist of [data engineering consulting firms](/data-engineering-consulting-firms/) and screen for self-hosting and Kubernetes operations experience before you screen for connector count.
---
The next step is simple. Decide whether you want a managed ingestion service or an ingestion platform your team operates, then shortlist partners built for that exact operating model.
---
## Fixed Price vs. Time and Materials: An Analytical Guide for Data Leaders
Source: https://dataengineeringcompanies.com/insights/fixed-price-vs-time-and-materials/
Published: 2026-01-18T08:53:45.645164+00:00
Description: Deciding between fixed price vs time and materials? Get a clear, data-backed comparison to select the right model for your data engineering projects.
For data engineering work, pick Time and Materials (T&M) unless the scope is genuinely static: requirements shift, data sources surprise you, and a fixed-price contract punishes discovery instead of rewarding it. Fixed Price still wins for narrow, well-documented jobs like a lift-and-shift migration, where the deliverable is known before anyone writes code.
## What's the actual difference between Fixed Price and T&M?
Fixed Price sets one total cost for a defined scope; the vendor absorbs the risk of underestimating. T&M bills for actual hours and materials as work happens; the client absorbs that risk but pays only for effort actually spent, with full visibility into where the money goes.
Choosing between them isn't a pricing footnote - it sets who bears the cost when a migration turns up more technical debt than the RFP assumed, and how much say your team gets in a project that runs a year or longer.
Whether you're migrating to [Snowflake](https://www.snowflake.com/en/) or building a new AI/ML pipeline, exhaustive upfront planning is rarely realistic. New data sources, shifting business logic, and technical debt show up mid-project as a matter of course. The contract model decides how those surprises get handled - and paid for.
A Norwegian study of **35** public-sector software projects found **83%** of Time and Materials engagements succeeded, versus **38%** of fixed-price ones. The same analysis found that forcing exhaustive upfront planning for fixed-price contracts delayed kickoff by **20-30%** on average, without producing better outcomes. (Study cited via [BayTech Consulting's 2025 analysis](https://www.baytechconsulting.com/blog/time-and-materials-vs-fixed-price-2025), which discusses the original findings.)
> The operative question isn't "which model is cheaper?" It's "which model creates the right incentives for this project?" The answer depends on who should bear the risk of uncertainty - the client or the vendor.
| Feature | Fixed Price Model | Time & Materials (T&M) Model |
| :--- | :--- | :--- |
| **Primary Benefit** | Budget predictability and low financial risk | High flexibility and adaptability |
| **Best For** | Well-defined, stable, short-term projects | Complex, long-term, or evolving projects |
| **Scope Management** | Rigid; changes require formal change orders | Agile; scope can be adjusted iteratively |
| **Client Involvement**| Low day-to-day engagement required | High collaboration and regular feedback |
## Who carries the risk in each model?
In Fixed Price, the vendor carries nearly all the financial risk: they've committed to a scope and a price, so underestimated complexity eats their margin, not your budget. In T&M, the client carries the risk: you pay for whatever time and resources the work actually takes.

That difference shapes behavior on both sides. A vendor locked into a fixed price has an incentive to defend the original scope and resist changes, even useful ones, because every addition erodes their margin. A vendor on T&M has less reason to fight scope changes, but the client has to stay engaged to keep costs in check. Fixed Price buys a feeling of safety; T&M buys a working partnership, at the cost of closer oversight.
### How does budget control differ between the two?
Fixed Price gives you one number up front, which simplifies financial planning and stakeholder reporting - barring scope changes, there are no surprises. T&M gives you a variable total but a transparent one: detailed reporting shows exactly where every hour and dollar went, and you can scale resources up or down as priorities shift.
The trade-off is a predictable total versus visibility into a variable one. The right choice depends on whether your organization needs a fixed forecast more than it needs the ability to adapt spending to what the project actually requires.
### How is scope managed under each model?
A Fixed Price project runs on a **Statement of Work (SOW)** that spells out every feature and deliverable in advance; any deviation triggers a formal change-control process, with the delays and cost that implies. A T&M project typically runs on an **agile backlog** - a prioritized, living list of tasks that can be reprioritized sprint to sprint without renegotiating the contract.
That flexibility matters most when discovery is part of the job. If mid-project feedback on a data platform modernization suggests a better approach, a T&M team can pivot in the next sprint. A fixed-price team has to raise a change order first.
### Do the incentive structures actually differ, or is this a talking point?
They differ in a concrete way: under Fixed Price, a vendor protects margin by finishing as fast as possible, which can mean cutting corners on scalability or test coverage. Under T&M, the vendor is paid for the time either way, so there's less pressure to rush - and more room to fix technical debt properly, since client satisfaction (not a fixed invoice) determines whether the engagement continues.
### Which model demands more admin work, and when?
Fixed Price front-loads the admin burden: weeks or months of detailed requirements-gathering before development starts. T&M spreads it across the project instead - lighter upfront planning, but continuous engagement afterward: reviewing weekly progress, tracking burn rate, and sitting in on sprint planning.
---
### Core mechanics, side by side
| Project Dimension | Fixed Price Model | Time and Materials (T&M) Model |
| :--- | :--- | :--- |
| **Risk** | **Vendor** absorbs cost overruns; high risk for the delivery team if scope is underestimated. | **Client** absorbs cost overruns; high risk for the client if scope is unclear or expands. |
| **Budget** | **Predictable and fixed.** Set at the start, making financial planning simple. | **Flexible and variable.** Based on actual effort, offering transparency but less predictability. |
| **Scope** | **Rigid.** Defined in a detailed SOW; changes require a formal, often costly, process. | **Flexible.** Managed via an agile backlog; can be adapted sprint-by-sprint. |
| **Quality Focus** | Incentive is on **efficiency and speed** to protect profit margins. Can risk technical debt. | Incentive is on **thoroughness and quality** to ensure client satisfaction and continued work. |
| **Client Role** | Heavily involved upfront in defining scope, then steps back for oversight. | **Continuously involved** in prioritization, feedback, and budget management. |
| **Best For** | Well-defined, stable projects with zero ambiguity (e.g., a lift-and-shift migration). | Complex, evolving projects where requirements are likely to change (e.g., AI/ML pipelines). |
There's no universally correct choice here. It depends on how well-defined the project actually is, how much risk your organization can absorb, and how much flexibility the work genuinely needs.
## Why does a "cheaper" fixed-price bid often cost more in the end?
Because vendors price in a risk premium you never see itemized. A fixed-price quote typically includes a **20-30% cushion** over the vendor's actual cost estimate, to protect their margin against scope creep and estimation error - and if the project goes smoothly, that cushion becomes pure vendor profit that never returns to you.
A straight comparison of a fixed-price bid against a T&M proposal is misleading for exactly this reason: the fixed-price number already has a hidden buffer baked in, while the T&M number doesn't.
### How big is the fixed-price risk premium in practice?
A project that actually requires **$200,000** in effort commonly gets quoted at **$240,000-$260,000** once the vendor's risk cushion is added. You're pre-paying for contingencies that may never happen; if the team works efficiently, that premium is money you'll never see back.
> A fixed-price contract doesn't eliminate the cost of uncertainty - it transfers the risk to the vendor, and you pay a premium for the transfer. The real question is whether that insurance is worth the price.
This shows up clearly in data work: a **$100,000** fixed-price pipeline quote likely carries a **$20,000-$30,000** buffer for unknowns like shifting analytics requirements or a mid-project pivot between [Snowflake](https://www.snowflake.com/) and [Databricks](https://www.databricks.com/). According to [elitecoders.co's comparison of the two models](https://www.elitecoders.co/compare/fixed-price-vs-time-materials), a T&M engagement that skips this embedded buffer can come in well below the fixed-price equivalent over the life of a project.
### What makes T&M pricing transparent by comparison?
Because the invoice is the audit trail: you pay the agreed rate for actual hours worked plus materials, with no hidden buffer. If a task finishes faster than estimated, you keep the savings immediately - the cost structure has nothing to hide, unlike a fixed bid with an invisible margin built in. Run your own numbers with our [data engineering cost calculator](/data-engineering-cost-calculator/) before you commit to either model.
That transparency comes with a catch: it puts budget oversight on you, not the vendor. Without discipline, T&M can drift. Three controls keep it in check.
* **Weekly burn reports.** The vendor should report hours logged, progress against milestones, and remaining budget - non-negotiable, not optional.
* **Active prioritization.** Your team needs to be in sprint planning so engineering time stays pointed at the highest-value work.
* **Budget caps.** A not-to-exceed clause, or per-phase caps, keeps flexibility without an open-ended bill.
The real cost of a project isn't just the final invoice - it's the value of what got delivered, plus the ability to adapt when new information shows up. A T&M project that runs **10%** over budget but ships something aligned with current needs usually beats a fixed-price project that lands on budget but ships something already out of date.
## Which model fits which kind of data engineering project?
Match the model to how well the scope is actually known, not to how the vendor prefers to bill. A rule of thumb: T&M for anything involving discovery or experimentation, Fixed Price for anything repetitive and already fully specified.

### Cloud data platform modernization
Use T&M. Even when the end goal - moving off on-prem servers onto a modern cloud stack - is clear, hidden data dependencies and unexpected technical debt surface during implementation almost every time. T&M lets the team adjust sprint to sprint as those surface, so the final platform reflects what the business actually needs rather than a literal copy of the legacy system. Trying to pin a multi-year modernization to a fixed-price contract means defining every detail before you've seen the system - an approach that kills the discovery the project depends on.
### Snowflake or Databricks migration
Use a hybrid. Migrations to [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/) usually split into two phases with very different risk profiles: a predictable "lift-and-shift" of existing, documented warehouses, followed by optimization work - refactoring logic, rewriting queries, building new models to use the platform's features - that's inherently harder to scope upfront.
* **Phase 1 (lift-and-shift):** Fixed Price. The tasks are repetitive and the scope is stable.
* **Phase 2 (optimization and expansion):** T&M. The team needs room to explore the new platform without a rigid SOW boxing them in.
### AI and ML data pipeline development
Use T&M - it's close to the only workable option. Building pipelines for AI/ML is an experimental cycle of hypothesis, feature engineering, and iterative training, where requirements change based on what the model actually does. Locking that into a fixed price forces the vendor to chase the original (often wrong) scope instead of the better model that discovery would surface.
> Forcing an AI/ML project into a fixed-price contract sets it up to fail: it rewards delivering the original plan over delivering the right one, which misreads how exploratory work happens.
The same Norwegian dataset cited above found T&M models reaching **83%** success rates in comparable environments, versus **38%** for fixed-price. [BayTech Consulting's 2025 analysis](https://www.baytechconsulting.com/blog/time-and-materials-vs-fixed-price-2025) covers how fixed-price contracts can work against innovation-heavy projects specifically.
### What if I need some budget certainty without going full Fixed Price?
Three hybrid structures split the difference:
* **Capped T&M:** Standard T&M plus a not-to-exceed clause - flexibility with a hard ceiling on spend.
* **Fixed Price Per Sprint:** Each sprint is its own mini fixed-price engagement, so costs stay predictable in short intervals while the backlog can still be reprioritized before the next one starts.
* **T&M with Performance Incentives:** Part of the vendor's fee is tied to milestones or metrics, aligning incentives without sacrificing day-to-day flexibility.
## What should the contract and governance actually look like?
Picking a model is only step one - the SOW or MSA is what makes the model work in practice. Weak contracts lead to disputes and budget overruns regardless of which pricing model you picked.
### What does a well-built Fixed Price contract require?
Precision, in three specific places. Vague deliverables like "a user-friendly dashboard" don't hold up; you need measurable criteria - for example, "the sales dashboard loads in under **3** seconds with **50** concurrent users, with data latency under **15** minutes."
1. **Ironclad acceptance criteria** - testable, not descriptive.
2. **A defined change-control process** - who approves changes, and how fast.
3. **Milestone-based payment** - tied to delivery and formal acceptance, not just elapsed time.
> A Fixed Price contract is only as good as its precision. If a deliverable can't be defined with objective, testable criteria, it doesn't belong in a fixed-scope agreement.
### What clauses actually protect a T&M agreement?
The contract's job shifts from defining *what* gets built to controlling *how* the engagement runs.
* **Detailed rate cards** - locked-in hourly or daily rates by role for the duration of the contract.
* **Resource approval workflow** - no one bills time without written client sign-off first.
* **Transparent time tracking** - weekly timesheets broken down by task, not just total hours.
* **Budget caps or not-to-exceed limits** - a hard ceiling that still preserves T&M's flexibility.
### What reporting cadence keeps either model on track?
A **[data engineering RFP checklist](/data-engineering-rfp-checklist/)** is useful before you sign anything, but the cadence below is what keeps a signed contract honest:
| Reporting Cadence | Fixed Price Focus | Time and Materials Focus |
| :--- | :--- | :--- |
| **Weekly** | RAG Status on Milestones | Budget Burn vs. Actuals Report |
| **Bi-Weekly** | Demos of In-Progress Deliverables | Review of Sprint Burn-Down Charts |
| **Monthly** | Review of Change Request Log | Resource Utilization & Team Efficiency Report |
## How do you evaluate a vendor's contracting approach during procurement?
Watch how they answer, not just what they say. A vendor's stance on Fixed Price versus T&M tells you how they think about risk, change, and collaboration before you've signed anything.
* **For Fixed Price bids:** "Walk me through your change control process. What happens when a critical requirement shows up mid-project?" A vague answer is a red flag.
* **For T&M proposals:** "What reports do we get, and how often, to track burn and progress?" Look for specifics - weekly burn-down charts, direct dashboard access - not just a promise of "transparency."
* **For agile projects:** "Tell me about a time you hit unexpected technical debt. How did you communicate it, and how did the plan change under T&M?"
> How a vendor handles the unforeseen predicts their performance better than their opening quote does. A low fixed-price bid from an inflexible vendor often ends up costing more, through delays and rework, than a T&M engagement with a communicative team.
### What are the red flags?
* **Pushing Fixed Price for R&D work.** A vendor insisting on fixed price for an experimental AI/ML pipeline either misunderstands the work or has priced in a heavy risk premium.
* **Vague reporting practices.** If a T&M proposal is fuzzy on how time gets tracked and reported, that's a preview of weak project governance.
* **No access to senior talent.** If you can't talk to a senior architect during vetting, you're not actually evaluating the team that will do the work.
For a fuller evaluation framework, see [how to choose a data engineering company](/how-to-choose-data-engineering-company/). Rate expectations matter here too: across the 86 firms profiled in the Data Engineering Companies Index, hourly rates run $45-$250 (median $100), with 7 firms billing $200 or more - useful context for judging whether a quoted rate card is in line with the market. See the full breakdown in our [data engineering consulting rates guide](/insights/data-engineering-consulting-rates-2026/).
## Common questions
### Can a T&M project just run forever and blow the budget?
Yes, but only under lax governance - T&M isn't a blank check. Set a not-to-exceed clause, require weekly burn reports, and keep your team in sprint planning to control priorities. With those three controls in place, you get T&M's flexibility without open-ended risk.
### Is Fixed Price always cheaper for a well-defined project?
Not necessarily. A fixed-price quote almost always includes a **20-30%** risk premium the vendor keeps as profit if nothing goes wrong. For a genuinely well-defined scope, T&M can come in cheaper precisely because you're not paying for contingency planning you didn't need.
### How does a "Capped T&M" hybrid actually work?
It's standard T&M - you pay for hours worked at an agreed rate - with a hard budget ceiling added on top. You keep the ability to reprioritize as the project evolves, while still having a guaranteed maximum spend, which suits projects that need flexibility but operate under a fixed budget cap.
---
Choosing the right pricing model gets you halfway there; the other half is picking the right partner. Our [data engineering statement of work guide](/insights/data-engineering-statement-of-work/) covers how to translate whichever model you pick into a contract that actually holds up - and the [2026 directory](https://dataengineeringcompanies.com) profiles 86 firms by rate, platform focus, and fit signals if you're ready to shortlist vendors.
---
## A Guide to Fractional Data Engineering Services in 2026
Source: https://dataengineeringcompanies.com/insights/fractional-data-engineering-services/
Published: 2026-04-03T06:39:53.736254+00:00
Description: Explore fractional data engineering services. Learn when to hire, compare pricing, and find the right experts for your data platform and pipeline projects.
Fractional data engineering services give you a senior engineer's time in a fraction of a full-time role, typically 10 to 25 hours a week, embedded directly in your team. The model exists for a specific gap: you have a critical project on the roadmap, hiring a full-time senior engineer takes months you don't have, and a full consulting engagement is more scope and overhead than the problem needs.
These are not advisors handing over a slide deck. They are hands-on-keyboard builders who execute specific, high-impact work - a Snowflake migration, a new Databricks environment, an AWS infrastructure overhaul. The rate spread reflects how specialized this work is: across the 86 firms profiled in the [Data Engineering Companies Index](/data-engineering-consulting-firms/), hourly rates for engineering and staffing engagements run $45 to $250, with a median around $100 - senior fractional work typically prices toward the higher end of that range.
## What are fractional data engineering services?
The fractional model is built around embedding, not consulting drive-bys. A senior engineer joins your existing tools, your Slack, and your sprint cycle for their allotted hours each week, applying deep expertise exactly where you need it, without the overhead of a full-time hire or the rigid structure of a traditional consulting engagement.
## How does fractional compare to a full-time hire or project consultant?
A full-time hire is the right call for sustained, core team growth. A project consultancy fits a large, bounded transformation. Fractional sits between the two: lower commitment than an employee, faster to start than a consulting SOW, and focused on a specific problem rather than a broad mandate.
| Attribute | Fractional Services | Full-Time Hire | Project-Based Consulting |
| :--- | :--- | :--- | :--- |
| **Cost Structure** | Predictable monthly retainer, priced for senior-only talent. | Full salary, benefits, and overhead - typically the largest fixed cost of the three. | A large upfront project fee scoped to a Statement of Work. |
| **Commitment** | Low (month-to-month) | High (long-term employment) | Medium (project duration) |
| **Expertise Access** | Senior, specialized talent | Varies by hire | Team of mixed-level talent |
| **Integration** | Embedded within your team | Fully integrated | External, SOW-driven |
| **Time to Impact** | Days to weeks | Months (3-6+ for hiring and onboarding) | Weeks to months |
If you're weighing fractional against a staffing model instead, [data engineering staff augmentation](/insights/data-engineering-staff-augmentation/) covers that comparison directly.
## When does a fractional data engineer make sense?
Fractional engagements work best for a specific, high-stakes problem your current team can't absorb without derailing its own roadmap. If the need is broad and ongoing rather than a single deliverable, a full-time hire is usually the better fit. This scenario is common enough that it shows up across analyses of [why companies are turning to IT contractors](https://applyrecruiting.com/blog/why-more-companies-are-turning-to-it-contractors).
### Common triggers for a fractional engagement
* **Accelerate a critical migration.** Your team is keeping the lights on. A fractional expert leads a complex migration to a platform like [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/), architecting the new setup and managing the move while your team maintains operations.
* **Design scalable data architecture.** You are launching a new product and cannot afford for its data pipelines to fail at scale. A fractional architect designs the system from the ground up, applying proven patterns to get you to market faster and with less rework later.
* **Evaluate and implement new tooling.** A fractional engineer provides an outside, expert opinion on vendors for tools like [dbt](https://www.getdbt.com/) or [Airflow](https://airflow.apache.org/). They have seen what works in production and can guide selection and implementation.
* **Backfill a leadership gap.** Finding a Head of Data takes months. A fractional leader can step in to keep key initiatives on track, mentor the team, and provide direction, preventing a loss of momentum during the search.
This decision tree shows when a fractional hire makes the most sense.
When you have a specific, project-based need and a clear budget, the fractional model gives you a direct path to senior talent without the overhead and commitment of a full-time employee.
## How is fractional data engineering priced?
Fractional engagements typically fall into three structures - a monthly retainer, a block of hours, or a dedicated part-time arrangement - and pricing follows the structure rather than a flat hourly card rate agreed upfront.
Companies can put a senior data architect and an analytics engineer on retainer for under $10,000 per month, without recruitment fees, benefits, or long-term payroll commitments - a fractional team structure that works in practice, not just on paper.
### Three fractional engagement models
Most fractional arrangements fall into one of three structures.
| Engagement Model | Best For | Typical Structure |
| :--- | :--- | :--- |
| **Monthly Retainer** | Ongoing support, architectural oversight, and team mentorship. | A block of **20-40 hours** per month for a flat fee. |
| **Block of Hours** | A single, well-defined project with a clear deliverable. | A set number of hours purchased upfront for a specific goal, like a POC for [dbt](https://www.getdbt.com/) or [Apache Airflow](https://airflow.apache.org/). |
| **Dedicated Part-Time** | Long-term leadership on a major initiative, requiring deep team integration. | A consistent schedule, like **2-3 days per week**, functioning as a true team member. |
Retainers provide access to an expert, a block of hours completes a task, and a part-time role delivers project ownership. For a deeper look at how rates break down across specialties and seniority, see [data engineering consulting rates in 2026](/insights/data-engineering-consulting-rates-2026/). Our guide on [fixed-price vs. time-and-materials contracts](/insights/fixed-price-vs-time-and-materials/) also helps with procurement.
## Who actually does fractional data engineering work?
Fractional data engineers are senior specialists, not a training ground for junior talent. They've built, scaled, and repaired data platforms at established tech companies and fast-growing startups before going independent.
Only 3 of the 86 firms profiled in the [Data Engineering Companies Index](/data-engineering-consulting-firms/) have fewer than 50 employees - most vendors in this market are built around larger, retained teams, not individual specialists. That gap is part of what draws senior engineers toward fractional and independent work instead of staying inside a firm. They bring deep expertise in specific domains like [Snowflake](https://www.snowflake.com/en/) architecture, [Databricks](https://www.databricks.com/) optimization, or multi-cloud infrastructure across [AWS](https://aws.amazon.com/), [Azure](https://azure.microsoft.com/en-us), and [GCP](https://cloud.google.com/).
### Why senior engineers choose fractional work
Senior engineers go fractional to focus on solving hard technical problems, without the meetings, politics, and management overhead of a full-time leadership role. It lets them work across industries - fintech, healthcare, enterprise SaaS - without being tied to one company's org chart.
This is not an entry-level path. Market data on [the experience levels of fractional professionals](https://fractionus.com/blog/fractional-work-statistics-2025-income-market-data) shows that 72% of people doing fractional work have 15 or more years of experience, and 30.4% have more than 26 years. Only 6.4% have less than 10 years. The model is built on proven, senior-level expertise, not a side gig for people early in their careers.
## How do you evaluate and onboard a fractional partner?
Vetting a fractional partner isn't a standard interview - you're screening a specialist for their ability to deliver targeted impact fast. The right choice moves your roadmap forward in weeks; the wrong one burns budget and still leaves the problem unsolved.
### Evaluation checklist
Use this checklist to screen potential partners before signing a contract. For a more comprehensive guide, review [how to evaluate data engineering vendors](/insights/data-engineering-vendor-evaluation-criteria/).
* **Hands-on technical validation:** Ask for proof, not just a skills list. Are they certified in your platforms ([Snowflake](https://www.snowflake.com/), [Databricks](https://www.databricks.com/), AWS, Azure, GCP)? Probe their real-world experience with critical tools like [dbt](https://www.getdbt.com/) or [Apache Airflow](https://airflow.apache.org/).
* **Relevant case studies:** Vague success stories are a red flag. Demand case studies that mirror your data volume, complexity, and industry. They must walk you through the problem, the solution, and the measurable business results.
* **Clear communication cadence:** A strong partner proposes a communication plan, such as daily Slack stand-ups, weekly progress reports, and bi-weekly strategic check-ins.
* **Explicit knowledge transfer plan:** Ask directly: "What is your process for documenting work, training our team, and ensuring a clean handover?" A crisp answer indicates they plan to make your team self-sufficient, not keep you dependent on them.
* **Defined security and access protocols:** They must have standard operating procedures for secure system access, data handling, and a clean offboarding process.
### 30-day onboarding roadmap
A structured onboarding process is the best predictor of a successful fractional engagement. Ambiguity in week one creates drag that can last for months. If you need broader context first, external resources can help you [hire a data engineer](https://www.remotely.works/hire/data-engineer) with the right skills.
Use this 30-day plan for execution:
1. **Week 1: Access and alignment.** Grant necessary access to cloud consoles, code repositories, and project management tools. The kickoff meeting must establish a clear initial goal (e.g., "Audit our primary dbt project for performance bottlenecks") and introduce key team members.
2. **Week 2: Audit and quick wins.** The partner should audit your existing architecture, documentation, and code. By the end of the week, they must present initial findings and at least one quick win - a small, high-impact fix they can implement immediately.
3. **Weeks 3-4: Execution and reporting.** The partner executes on the primary objective. The agreed-upon communication rhythm should be active, with clear progress updates and immediate flagging of any roadblocks.
## What red flags signal a bad fractional hire?
The clearest warning sign is a pitch built from tech buzzwords instead of a clear rationale. If a provider can't explain why a specific platform fits your business problem, they're pitching what's comfortable for them, not what actually solves your problem. Choosing the wrong fractional partner sets you back months.
### Vague track record, unclear process
Pay close attention to their track record. If success stories lack specific metrics on performance gains or cost savings, the impact they delivered is questionable. A partner's inability to detail their offboarding process is a clear sign they intend to create vendor lock-in. A true expert builds systems your team can own and operate independently.
### Pricing red flags and overcommitment
Be wary of rigid contracts that lack clearly defined Service Level Agreements (SLAs). You need concrete commitments on response times and deliverables, not vague promises. Unusually low rates often mean you're getting a junior engineer disguised as a senior expert, which leads to technical debt down the line.
Finally, ask them directly about their current client load. A fractional engineer stretched across too many projects will lack focus, which shows up as missed deadlines, rushed work, and a partner too busy to give your project the attention it requires.
## Next Steps
If you have a specific, high-impact data engineering project blocked by your team's capacity, and you need senior-level expertise now, a fractional engagement is the most direct path to execution.
1. **Define the scope.** Identify the single most critical project. Write a one-page brief outlining the problem, the desired business outcome, and the key deliverable.
2. **Set the budget.** Based on the benchmarks above, determine a realistic monthly budget for a retainer or a fixed budget for a block-of-hours project.
3. **Initiate vetting.** Use the evaluation checklist in this guide to begin conversations with at least two potential fractional partners. Demand specific, evidence-based answers.
Don't let a critical data initiative stall while you search for a full-time hire. A fractional expert can be working on the problem within weeks.
---
## Healthcare Data Analytics Companies: 8 Consulting Firms Compared for 2026
Source: https://dataengineeringcompanies.com/insights/healthcare-data-analytics-companies/
Published: 2026-07-20T09:00:00.000000+00:00
Description: Compare 8 data-engineering consultancies serving healthcare analytics - rates, team size, and fit - plus how they differ from platforms like Arcadia and Health Catalyst.
"Healthcare data analytics companies" means two different things depending on what you're buying. One is a platform - productized software like Arcadia, Health Catalyst, or Innovaccer that you license and deploy. The other is a consultancy - a firm you hire to build the pipelines, integrate the clinical and claims data, or stand up one of those platforms for you. The 8 firms below are consultancies in our directory that serve healthcare and life-sciences clients; none of them are analytics-platform vendors, and none of them are Arcadia, Health Catalyst, or Innovaccer. Healthcare is one of several industries most of these firms serve - four have a deeper healthcare or life-sciences focus (ProCogia, ScienceSoft, Avenga, Element Data), and we flag that below. Our directory does not track HIPAA attestations or clinical certifications, so verify compliance credentials (HIPAA, HITRUST, SOC 2) directly with any firm before you shortlist them.
## Compare healthcare-analytics consultancies
| Firm | Rate | Team size | Best for | Wrong for |
| :--- | :--- | :--- | :--- | :--- |
| [Avenga](/avenga/) | $50-99/hr | 2500 | Regulated industries needing nearshore teams, life sciences and finance, with a security/governance focus | Buyers needing a dedicated data-engineering specialist rather than a broad software engineering firm |
| [Damco Solutions](/damco-solutions/) | $50-100/hr | 500 | Enterprise data modernization, Big Data solutions, and cloud migration | Buyers needing deep single-platform specialization (Snowflake Elite / Databricks Premier depth) |
| [Element Data](/elementdata/) | $150-225/hr | 40 | Microsoft-stack optimization and Power BI enterprise rollouts, with healthcare and public-sector focus | Buyers running AWS or GCP as the primary cloud, or any non-Microsoft delivery |
| [Entrans](/entrans/) | $75-150/hr | 100 | End-to-end data engineering, data lakehouse implementations, real-time streaming pipelines | Buyers with significant legacy-system integration needs (firm founded 2020, 100-person team) |
| [HCLTech](/hcl-technologies/) | $50-125/hr | 10000 | Large-scale legacy migrations and managed-services outsourcing, with life sciences among served industries | Sub-$100K scope, or buyers needing agile boutique delivery over a managed-services SI model |
| [Perficient](/perficient/) | $125-200/hr | 5000 | Digital transformation and enterprise data and analytics, with healthcare among served industries | Buyers whose primary criterion is an elite single-platform credential (Snowflake Elite / Databricks Premier) |
| [ProCogia](/procogia/) | $125-200/hr | 100 | Data consultancy and bioinformatics, enterprise data mesh, with life-sciences depth (client roster includes Roche) | Buyers needing a large parallel delivery bench or global contractual scale (100-person firm) |
| [ScienceSoft](/sciencesoft/) | $50-100/hr | 700 | Healthcare and financial services, compliance-focused data solutions, 35+ years in IT consulting | Buyers whose primary criterion is elite single-platform specialization over a generalist practice |
Firms are listed alphabetically. We do not rank firms by quality - use the best-for and wrong-for columns to narrow the list, then verify healthcare compliance and specialization directly with each firm before you send an RFP.
## 1. Avenga
Rate: $50-99/hr. Team: 2500. Minimum project: $25K+.
Avenga fits regulated industries that need nearshore delivery teams and a security/governance focus, with life sciences and finance among its core sectors. It is the wrong choice if you need a dedicated data-engineering specialist rather than a broad software engineering firm working across multiple disciplines.
## 2. Damco Solutions
Rate: $50-100/hr. Team: 500. Minimum project: $25K+.
Damco Solutions handles enterprise data modernization, Big Data solutions, and cloud migration work at a mid-market rate. It is the wrong fit when a project needs deep single-platform specialization - Snowflake Elite or Databricks Premier-level depth - rather than a generalist modernization practice.
## 3. Element Data
Rate: $150-225/hr. Team: 40. Minimum project: $20K+.
Element Data is a boutique firm built around Microsoft-stack optimization and enterprise Power BI rollouts, with healthcare and public-sector clients as a named focus. It is the wrong choice for buyers running AWS or GCP as their primary cloud, since its delivery model centers on non-Microsoft-adjacent work only at the margins.
## 4. Entrans
Rate: $75-150/hr. Team: 100. Minimum project: $25K+.
Entrans covers end-to-end data engineering, data lakehouse implementations, and real-time streaming pipelines. Founded in 2020 with a 100-person team, it is the wrong fit for buyers with significant legacy-system integration needs that require decades of accumulated migration experience.
## 5. HCLTech
Rate: $50-125/hr. Team: 10000. Minimum project: $100K+.
HCLTech is built for large-scale legacy migrations and managed-services outsourcing, with life sciences among the industries it serves. It is the wrong choice for sub-$100K scope, or for buyers who want agile boutique delivery instead of a managed-services systems-integrator model.
## 6. Perficient
Rate: $125-200/hr. Team: 5000. Minimum project: $100K+.
Perficient runs digital transformation and enterprise data and analytics programs, with healthcare named among its served industries. It is the wrong fit when a buyer's primary criterion is an elite single-platform credential - Snowflake Elite or Databricks Premier - rather than broad enterprise delivery.
## 7. ProCogia
Rate: $125-200/hr. Team: 100. Minimum project: $25K+.
ProCogia is a data consultancy with bioinformatics and enterprise data-mesh capability, and life-sciences depth backed by a client roster that includes Roche. It is the wrong choice for buyers who need a large parallel delivery bench or global contractual scale beyond a 100-person firm.
## 8. ScienceSoft
Rate: $50-100/hr. Team: 700. Minimum project: $10K+.
ScienceSoft brings 35+ years in IT consulting with named practices in healthcare and financial services, and a compliance-focused approach to data solutions. It is the wrong fit for buyers whose primary criterion is elite single-platform specialization rather than a generalist practice with broad domain coverage.
## What about healthcare analytics platforms like Arcadia, Health Catalyst, and Innovaccer?
These are productized healthcare-analytics platforms you license and deploy, not consultancies you hire, and none of them are in our directory. **Arcadia** (arcadia.io), founded in 2002, aggregates EHR, claims, and social-determinants data - over 170 million patient records across 2,600+ sources - on a lakehouse architecture built for value-based care. **Health Catalyst** (healthcatalyst.com, NASDAQ: HCAT) is a healthcare data platform and analytics suite that unifies clinical, financial, and operational data for population-health and value-based-care measurement. **Innovaccer** (innovaccer.com) offers a Healthcare Intelligence Cloud built on a Data Activation Platform that unifies patient and provider records - including an enterprise master patient index - for population-health analytics, used by large Epic, Oracle Cerner, and MEDITECH customers.
Choose a platform when you want prebuilt population-health or value-based-care measures out of the box. Hire a consultancy - the firms above - when you need custom infrastructure, data integration work, or help building out a platform you already own.
## What does a healthcare data analytics engagement involve?
A typical engagement covers clinical, claims, and EHR data integration; HIPAA-aware pipeline design; building a data lakehouse or warehouse for health data; BI and population-health dashboards; and machine learning applied to clinical data. Scope varies widely by firm and use case - confirm what's included before signing a statement of work.
## How much do healthcare data analytics consultants cost?
The 8 firms above span $50-225/hr, in line with our full 86-firm index range of $45-250/hr and median of $100/hr. Minimum project sizes run from $10K (ScienceSoft) to $100K+ (HCLTech, Perficient), so budget expectations depend heavily on which firm's scale matches your project.
## Platform vs. consultancy - which do you need?
If you want out-of-box population-health or value-based-care measures without custom build work, a platform like Arcadia, Health Catalyst, or Innovaccer fits. If you need custom data infrastructure, integration between systems, or help implementing a platform you've already licensed, hire one of the 8 consultancies above instead. See the platform section for the full comparison.
## How do you verify a firm's healthcare data compliance?
Our directory tracks rate, team size, and stated best-fit and wrong-fit use cases, but it does not track HIPAA attestations, HITRUST certification, or SOC 2 reports. Ask each firm directly for evidence - a signed Business Associate Agreement, an audit report, or a certification number - before you share protected health information or sign a contract.
## Which of these firms have the deepest healthcare focus?
ProCogia brings bioinformatics and life-sciences depth, including a Roche engagement. ScienceSoft runs an explicit healthcare practice alongside financial services. Avenga focuses on regulated industries including life sciences. Element Data names healthcare and public-sector work as a core specialty. The other four firms serve healthcare as one industry among several rather than a named focus area.
## Frequently asked questions
### Are these 8 firms the same as Arcadia, Health Catalyst, or Innovaccer?
No. Arcadia, Health Catalyst, and Innovaccer are productized healthcare-analytics platforms you buy and deploy. The 8 firms above are data-engineering consultancies you hire to build custom infrastructure, integrate data, or implement a platform - they are not vendors of a packaged analytics product.
### What's the smallest project these firms will take on?
ScienceSoft lists a $10K+ minimum, the lowest on this list. Element Data starts at $20K+. Avenga, Damco Solutions, Entrans, and ProCogia list $25K+ minimums. HCLTech and Perficient require $100K+, reflecting their enterprise scale and managed-services delivery model.
### How do I confirm a firm's HIPAA or HITRUST compliance before hiring?
Our directory doesn't track compliance credentials, so this has to happen directly with the firm. Ask for their current HIPAA Business Associate Agreement terms, any HITRUST or SOC 2 certification documentation, and references from prior healthcare clients before you share any protected health information.
### How many firms in your directory serve healthcare or life sciences?
37 of the 86 firms in our directory list healthcare or life-sciences capability. The 8 above are a subset selected for this guide based on verified rate, team size, and fit data; browse the full [Data Engineering Companies Index](/data-engineering-consulting-firms/) or the [healthcare data engineering firms](/healthcare-data-engineering/) hub to see the rest.
---
## How to Build Data Pipelines That Last
Source: https://dataengineeringcompanies.com/insights/how-to-build-data-pipelines/
Published: 2025-12-03T06:47:32.098949+00:00
Description: Learn how to build data pipelines that are reliable, AI-ready, and efficient. A practical guide to modern data engineering strategies.
Building a data pipeline that lasts comes down to four decisions made early: store data once on a lakehouse instead of splitting it across a lake and a warehouse, design outputs that AI workloads can consume without rework, break the pipeline into independently deployable stages instead of one monolithic DAG, and enforce data quality at the point of ingestion instead of cleaning it up downstream. Get those four right and orchestration, observability, and cost control mostly become a matter of picking mature tools and wiring them together correctly.
Twenty of the 86 firms profiled in the [Data Engineering Companies Index](/insights/dbt-implementation-partners/) list dbt among their capabilities, and most of what follows assumes a lakehouse table format paired with a transformation layer like it, not a pipeline built by hand from scratch.

What this guide covers:
* **Lakehouse architecture** and open table formats as the storage foundation.
* **AI-ready pipeline design** so RAG and fine-tuning don't require separate rework later.
* **Modular, containerized stages** and Change Data Capture for resilient schema evolution.
* **Data contracts, self-healing agents, orchestration, and cost accountability** so the pipeline stays reliable after launch.
## 1. Why build on a lakehouse instead of a separate warehouse and lake?
Running a data lake and a data warehouse as two systems means storing data twice, reconciling it constantly, and maintaining two sets of pipelines to keep them in sync. A lakehouse puts structured, semi-structured, and unstructured data on one low-cost object store with an open table format on top, so there's one copy of the truth.
The architectural debate is largely settled. [Delta Lake](https://delta.io/), [Apache Iceberg](https://iceberg.apache.org/), and [Apache Hudi](https://hudi.apache.org/) bring ACID transactions, schema enforcement, and time travel to data sitting in [Amazon S3](https://aws.amazon.com/s3/), [Azure Data Lake Storage](https://azure.microsoft.com/en-us/products/storage/data-lake-storage), or [Google Cloud Storage](https://cloud.google.com/storage), no different from what a proprietary warehouse would give you. That closes most of the gap that used to justify running two systems side by side. For a longer breakdown of the pattern, see [what lakehouse architecture actually replaces](/insights/what-is-lakehouse-architecture/).
### What open table formats actually add
* **ACID transactions.** Guaranteed atomicity, consistency, isolation, and durability mean no corrupted data from failed writes or concurrent jobs stepping on each other.
* **Schema enforcement and evolution.** Enforce schema on write to stop bad data before it lands, and evolve that schema over time without rewriting entire tables.
* **Time travel and versioning.** Every change creates a new version, so you can query a snapshot of your data from any point in time, useful for debugging, audits, or reproducing a model run.
> **Action:** Store everything once in S3, ADLS, or GCS, enforce schema on write with Spark, Flink, or Trino, and version tables the way you'd version code. That one decision removes a large share of the architectural complexity most teams carry into a migration.
### What makes a pipeline AI-ready from the start?
A pipeline that only outputs clean relational tables isn't ready for retrieval-augmented generation or fine-tuning, both of which need vector embeddings, chunked text, and knowledge-graph structures. Bolting that on after the fact usually means reprocessing data you already paid to move once.
Model teams commonly trace poor RAG or fine-tuning results back to source data that was never structured for those workloads in the first place. A lakehouse foundation makes that easier to fix, because vector and graph outputs can sit right next to the tables everyone already queries.
> **Action:** Output vector embeddings, knowledge-graph triples, and chunked text alongside your standard tables. Enforce data contracts and semantic versioning in a central registry so AI teams can consume new features without reprocessing historical data.
### Legacy vs modern data architecture
| Attribute | Legacy (Warehouse + Lake) | Modern (Lakehouse) |
| :--- | :--- | :--- |
| **Data Storage** | Duplicated across two separate systems, driving up storage cost and reconciliation work. | A single, unified storage layer on low-cost object storage. |
| **Data Types** | Structured data lives in the warehouse; unstructured data is often isolated and hard to use. | Structured, semi-structured, and unstructured data live in one place. |
| **Complexity** | Multiple ETL/ELT tools needed to move and sync data between the lake and warehouse. | A single set of tools for ingestion and transformation. |
| **Cost** | Higher total cost from redundant storage, compute, and data movement. | Lower total cost from inexpensive object storage and on-demand compute. |
| **AI-Readiness** | Requires separate pipelines to prepare data for ML, RAG, and fine-tuning. | Pipelines can output vector embeddings and other AI-native formats at the source. |
The modern lakehouse is as much a strategic decision as a technical one. It removes the silos that generated most of the reconciliation work, and it gives teams a foundation that's ready for AI-heavy workloads without a separate build-out.
## 2. Why do modular micro-pipelines beat monolithic DAGs?
A single, sprawling DAG (Directed Acyclic Graph) means one failed task can cascade through the whole pipeline and take everything down with it. Breaking ingestion, validation, enrichment, and serving into separate containerized services means a failure in one stage doesn't touch the others, and each piece can scale, update, or roll back on its own.
A real-world ingestion flow might look like this:
* **Ingestion:** A tool like [Debezium](https://debezium.io/) captures changes from a production database.
* **Transport:** Those changes stream as events into a [Kafka](https://kafka.apache.org/) topic.
* **Validation:** A [Flink](https://flink.apache.org/) job picks up the events and checks them against a predefined data contract.
* **Storage:** A dedicated writer service lands the clean, validated data into a [Delta Lake](https://delta.io/) table.
> **Action:** Containerize each stage (Debezium, Kafka, Flink validation, Delta writer) with [Docker](https://www.docker.com/) and orchestrate with [Kubernetes](https://kubernetes.io/) or an asset-based orchestrator like [Dagster](https://dagster.io/). You can then scale, update, or roll back one piece without touching the rest.
### How does Change Data Capture simplify schema evolution?
Change Data Capture reads every insert, update, and delete from a source database and streams it as an event, instead of running heavy batch queries against the live system. That single event stream replaces expensive re-extraction with a continuous, low-overhead feed of every change.
> **Action:** Capture every source change once with a tool like [Debezium](https://debezium.io/), land it as immutable events in Kafka, then materialize Slowly Changing Dimension Type 2 or latest-view tables downstream using [Apache Iceberg](https://iceberg.apache.org/) or [Delta Lake](https://delta.io/). You won't need to re-ingest historical data just because a source system added a column.

A single, unified layer like this removes the redundant, tangled paths found in legacy systems and creates a direct line from raw sources to whatever consumes the data next, a dashboard, a model, or another pipeline.
## 3. What should a data contract actually enforce?
A data contract is an enforceable agreement about a table's structure, meaning, and quality thresholds, similar to a service-level agreement for the data itself. Set it at the point where data enters the pipeline, and you reject bad records before they can pollute anything downstream. See [what a data contract needs to cover](/insights/data-contracts-in-data-engineering/) for a fuller framework.
Typical column-level rules include:
* **Null rates:** `email_address` null rate under 0.1%.
* **Cardinality bounds:** `customer_status` must be `active`, `inactive`, or `pending`.
* **Regex patterns:** `zip_code` must match `^\d{5}(-\d{4})?$`.
> **Action:** Define column-level rules in protobuf or avro schemas, or a platform like [OpenMetadata](https://open-metadata.org/). Route violations to dead-letter topics and alert owners in real time, so downstream teams stop losing time to data that should never have arrived.
Enforcing contracts at the entry point shifts the burden of quality from the data team to the teams actually producing the data. It becomes a shared responsibility instead of an engineering bottleneck.
### How do AI agents help pipelines self-heal?
Even a well-defined contract won't catch every failure mode. Agents wired into the orchestrator can watch task metadata after every run and respond to problems automatically, instead of paging someone in the middle of the night.
What they typically watch for:
* **Schema drift:** Did the input or output structure change unexpectedly?
* **Cardinality explosions:** Did a categorical column's unique values suddenly spike?
* **Data latency:** Is source data arriving late?
When an agent spots an anomaly, it doesn't just alert someone. It can trigger a recovery playbook: quarantine the bad micro-batch, retry with different parameters, or reroute the data.
> **Action:** Wire [LangChain](https://www.langchain.com/) or [CrewAI](https://www.crewai.com/) agents into your orchestrator (Airflow, [Dagster](https://dagster.io/), Prefect) to evaluate task metadata and trigger recovery playbooks. This pattern cuts incident resolution time from hours to minutes without needing an engineer to notice first.
## 4. What does modern orchestration and observability look like?
Declarative orchestration tools like [Dagster](https://dagster.io/), [Prefect](https://www.prefect.io/), and [Mage](https://www.mage.ai/) let engineers define what data assets should exist and their dependencies, then handle execution themselves. Paired with automated lineage and anomaly detection, that combination is what actually cuts root-cause time from hours to minutes, not the orchestrator alone.

### Default to declarative, low-code orchestration
The sweet spot is a platform that lets senior engineers ship faster while still producing production-grade, Git-backed DAGs.
> **Action:** Write transformations in SQL or Python, parameterize everything, and generate dynamic schedules from metadata. Treat orchestration as a configuration problem, not a software engineering one, without sacrificing governance.
### Make observability part of the design, not an afterthought
End-to-end lineage and automated anomaly detection need to be built in from day one so a broken pipeline produces an immediate, actionable answer instead of a guessing game.
> **Action:** Auto-generate lineage from dbt, Spark, and Flink, feed it into a tool like [Monte Carlo](https://www.montecarlodata.com/) or [Elementary](https://elementary-data.com/), and surface freshness and distribution alerts in the Slack channel your team actually watches.
### When does streaming actually beat micro-batch?
Most workloads described as needing "real-time" data are fine with a five- to fifteen-minute micro-batch, at a fraction of the infrastructure cost of true streaming and with no noticeable business impact. Reserve tools like [Flink](https://flink.apache.org/) or [Materialize](https://materialize.com/) for the cases where a delay of even a few seconds has a real cost, fraud detection or live inventory being the usual examples. See [stream processing vs. batch processing](/insights/stream-processing-vs-batch-processing/) for how to make that call.
> **Action:** Run serverless Spark or [dbt Core](https://www.getdbt.com/) on [Databricks](https://www.databricks.com/), [Snowflake](https://www.snowflake.com/en/), or [BigQuery](https://cloud.google.com/bigquery) as your default. Partition intelligently, and save true streaming for the handful of use cases with genuine sub-second requirements.
## 5. How do you tie pipeline cost to business value?
The right question isn't whether a pipeline is running, it's what business metric breaks if it goes down. Tag every pipeline, table, and dashboard with an owner and a value estimate, then review that list on a fixed schedule and sunset anything that can't justify its cost.
> **Action:** Tag every asset with cost-per-insight or revenue-attribution metadata, and run quarterly reviews where each pipeline owner has to defend its value in plain business terms. Anything that consistently can't gets put on a sunset list, and the freed-up budget funds the next high-impact project.
This kind of financial discipline is what separates teams that keep their platform lean from teams that quietly accumulate pipelines nobody remembers the purpose of.
## Common questions about building data pipelines
### What's the single biggest mistake teams make?
Falling for a specific tool instead of a durable architectural principle. A team gets excited about something like [Apache Spark](https://spark.apache.org/) Streaming, and every problem starts looking like a nail for that one hammer. The result is a massive, brittle pipeline that's a nightmare to change.
Build with a tool-agnostic, modular mindset instead. When each stage is containerized, swapping out the validation engine or the warehouse writer means replacing one component, not tearing down the whole system. That flexibility is what actually lets a pipeline outlast the team that built it.
### How do you convince leadership to invest in data contracts?
Shift the conversation from schemas and validation to cost and risk. Data contracts are the first line of defense against flawed business reports, which lead to expensive bad decisions.
> **A useful move:** Estimate how many hours your team spends each month chasing data quality fires, then multiply that by loaded salaries. That turns a technical ask into a dollar figure leadership already understands. For observability, frame it around the cost of downtime: clear, end-to-end lineage is what turns an hours-long investigation into a few minutes.
### Do you really need true real-time streaming?
For a narrow set of cases, yes: fraud detection and live inventory management are two where a delay of even a few seconds costs real money, and tools like [Apache Flink](https://flink.apache.org/) are the right call there. For most analytics dashboards and operational reports, a five- to fifteen-minute micro-batch feels real-time to the end user while staying dramatically simpler and cheaper to run. Push back on "we need it real-time" requests until you understand the actual business requirement behind them.
---
For platform-specific tradeoffs, [data warehouse vs. data lake](/insights/data-warehouse-vs-data-lake/) covers the underlying architecture decision, and [ten production pipeline architectures](/insights/data-pipeline-architecture-examples/) walks through real trade-offs instead of theory. Once you have a design, weigh it against a [pipeline cost estimate](/insights/data-pipeline-cost-estimation-guide/) before committing budget, and if you'd rather bring in a partner than build the whole stack in-house, the [Data Engineering Companies Index](/) lists 86 firms by platform focus, published rates, and fit.
---
## Where to Find and Vet Machine Learning Consulting Firms
Source: https://dataengineeringcompanies.com/insights/machine-learning-consulting-firms/
Published: 2025-12-25T07:40:44.121728+00:00
Description: A practical guide to seven resources for finding and evaluating machine learning consulting firms - organized by resource type, not ranked by quality.
Seven resources cover most of what you need to find and vet a machine learning consulting firm: two review platforms (Clutch, G2), two talent marketplaces (Upwork, Toptal), two cloud marketplaces (AWS, Azure), and a specialized data engineering directory. None of them gives a complete picture alone - each surfaces a different signal, and a sound vendor search draws on several in sequence.
This guide covers each one organized by resource type, not ranked by quality, plus a workflow for moving from a long list to a final decision. ML/AI is the single most common capability tag in the [Data Engineering Companies Index](/ai-data-engineering/) - 64 of the 86 profiled firms list it - which tells you the category is crowded with generalists claiming ML expertise alongside the specialists who actually have it. That gap is exactly what the evaluation steps below are built to catch.
> **Disclosure:** DataEngineeringCompanies.com publishes this guide and is one of the resources listed below. Evaluate it using the same criteria applied to every other resource in this list - no more, no less.
Each section breaks down how to use a platform's actual features to surface capable **machine learning consulting firms**, focused on the signals that matter when comparing vendors:
* **Verified Client Reviews:** Unfiltered feedback on project outcomes.
* **Platform Certifications:** Official validation of technical expertise.
* **Minimum Project Thresholds:** Filter by budget compatibility quickly.
* **Typical Hourly Rate Bands:** Set realistic cost expectations upfront.
## 1. Clutch: what does its Machine Learning Consulting category surface?
Clutch is an established B2B ratings and reviews platform, and its dedicated Machine Learning Consulting category is a practical starting point for a vendor search. It works as a filterable directory for narrowing a wide pool of potential partners down to a manageable shortlist using pre-qualification data - verified client feedback and quantitative project details that are often missing at the early stages of procurement.
Unlike generic business directories, Clutch goes into service specifics. Each firm profile includes a "Service Focus" matrix that breaks expertise down into areas like Natural Language Processing, Computer Vision, or Predictive Analytics, which helps you identify specialists rather than generalists. The platform's filtering is strongest for North American and European markets, with options down to U.S. states and major cities.
### Key features and how to use them
Clutch's value is in its filtering and transparent data. Focus on these features:
* **Financial Pre-Qualification:** Filtering by hourly rate band (for example, $100-$149/hr) and minimum project size (for example, $25,000+) is the fastest way to eliminate firms misaligned with your budget.
* **Verified Reviews & Scoring:** Look past the overall star rating. Read the full-length reviews, which are often based on phone interviews conducted by Clutch analysts, and check the sub-scores for quality, scheduling, and cost.
* **The Leaders Matrix:** Clutch publishes a quadrant-style "Leaders Matrix" that plots firms on "Ability to Deliver" against "Market Presence." It can be skewed by a firm's activity on the platform, so treat it as a guide, not a ranking.
* **Client Portfolio & Industry Focus:** Drill into each firm's portfolio for case studies and client lists, and cross-reference the stated "Industry Focus" against actual clients served to validate domain expertise.
* **Strategic Filtering:** Apply budget, target hourly rate, and location filters immediately, then narrow further by industry focus so you only see firms with relevant experience in sectors like healthcare, finance, or retail.
### Platform pros and cons
| Pros | Cons |
| :--- | :--- |
| **High Signal on Budgeting:** Publicly listed rate bands and project minimums help pre-qualify vendors quickly. | **Indicative Pricing Only:** Rates are bands, not firm quotes. Final pricing still requires direct outreach. |
| **Deep U.S. & European Coverage:** Strong filters for location, including specific U.S. states and cities. | **Potential for Paid Placement:** Prominent placements can be sponsored, which is disclosed but still influences visibility. |
| **Verified Client Feedback:** Detailed, interview-based reviews give an authentic view of project execution. | **Rankings Favor Profile Activity:** Firms that actively manage their profiles and solicit reviews tend to rank higher. |
> **Practical tip:** Use Clutch to build an initial long list of five to seven candidate firms. Filter by your non-negotiables - budget, location, core service focus like NLP - then use what you learn to draft your first RFI. See this [data engineering RFP checklist](https://dataengineeringcompanies.com/data-engineering-rfp-checklist/) for the questions worth asking at that stage.
**Website:** [https://clutch.co/developers/artificial-intelligence/machine-learning](https://clutch.co/developers/artificial-intelligence/machine-learning)
## 2. G2: how does the AI Development Services category compare to Clutch?
G2, known for its peer-to-peer software reviews, runs a similarly built-out platform for B2B services, including an AI Development Services category. It's a useful tool for cross-validating candidates found elsewhere and reading user sentiment. Where Clutch focuses on project-level detail, G2 leans on a familiar review interface to compare **machine learning consulting firms** by user satisfaction and market presence.
The platform's core strength is a transparent scoring methodology. It aggregates user reviews into satisfaction ratings and G2 Grid Reports, which plot vendors into four quadrants: Leaders, High Performers, Contenders, and Niche players. That visual layout is useful for spotting high-satisfaction "High Performer" firms that don't yet have the brand recognition of the market "Leaders."
### Key features and how to use them
To get value from G2, focus on its comparison and review-driven features:
* **G2 Grid & Scoring:** Use the interactive grid to shortlist visually, but don't stop at the "Leaders" quadrant - "High Performers" often deliver strong service with a smaller market footprint. Drill into the scoring breakdown for factors like "Ease of Doing Business With" or "Quality of Support."
* **Side-by-Side Comparisons:** Once you have a short list, use G2's comparison tool to build a feature-by-feature, review-by-review table across up to four firms on user satisfaction, industry focus, and company size.
* **Review Sentiment Analysis:** Read individual reviews for recurring themes rather than relying on the star rating alone. If clients consistently praise technical expertise but flag project management issues, that's a specific risk to probe in your own diligence.
* **Explore Related Categories:** G2's category structure is interconnected - from the AI Development page you can jump to "Data Engineering Services" or "Big Data Consulting" to check whether a candidate has the end-to-end capability your project needs.
### Platform pros and cons
| Pros | Cons |
| :--- | :--- |
| **Rich User Review Content:** Good for triangulating vendor sentiment and spotting recurring strengths or weaknesses. | **Limited Granular Pricing Data:** Mostly a "pricing available" flag rather than specific hourly rate bands or project minimums. |
| **Transparent Scoring Methodology:** The G2 Grid scoring is well documented. | **Services Coverage Maturing:** Services categories aren't as exhaustive as G2's software directories. |
| **Familiar B2B UX:** Intuitive for anyone who already uses G2 for software procurement. | **Review Volume Varies:** Newer or niche firms may have too few reviews to draw a reliable conclusion. |
> **Practical tip:** Use G2 as a validation step for a shortlist built on another platform. Before a call with a promising firm, read their G2 reviews and prepare specific questions from what you find - "I saw a review mentioning timeline communication issues, how have you addressed that?"
**Website:** https://www.g2.com/categories/ai-development-services
## 3. Upwork: when does hiring individual ML talent make more sense than a firm?
For staff augmentation or a focused, short-term project, Upwork is a leading freelance marketplace. Instead of engaging a full-service **machine learning consulting firm**, you hire individual ML engineers, data scientists, and consultants hourly or at a fixed price - a fit for a proof of concept, filling a specific skill gap, or a well-scoped task that doesn't need a full consulting engagement.
Upwork's advantage is speed and direct access: post a job and freelancers submit proposals, often within a day or two. Each consultant's profile shows work history, client ratings, portfolio, and a stated hourly rate, so you get visibility into market costs and individual capability before you talk to anyone. Its AI/ML Consultations feature also lets you book short, paid sessions with experts for architectural review or strategic advice - a low-cost way to vet several consultants before committing to a larger engagement.
### Key features and how to use them
* **Transparent Talent Profiles:** Scrutinize the "Work History and Feedback" section past the job title. Look for completed, high-value projects with detailed positive feedback relevant to your needs; a history of long engagements is a good reliability signal.
* **Geographic and Skill Filtering:** Use the "U.S. Only" filter if data residency or time zones matter, and combine it with skill tags like "PyTorch," "TensorFlow," or "Scikit-learn" to narrow the pool to specialists.
* **Project Catalog & Fixed-Price Engagements:** For a well-defined task like a recommendation-engine prototype, browse the Project Catalog for pre-scoped, fixed-price offers - a low-risk way to evaluate a consultant's work before a bigger commitment.
* **Escrow and Work Diary:** On hourly contracts, escrow holds payment until you approve the logged hours in the Work Diary, which protects your budget and creates accountability.
* **Upwork Enterprise:** For larger organizations that need more governance, the Enterprise tier adds curated talent, compliance support, and dedicated account management.
### Platform pros and cons
| Pros | Cons |
| :--- | :--- |
| **Fast Sourcing for POCs:** You can go from job post to a hired expert for a proof of concept in days. | **Buyer Diligence is Essential:** Talent quality varies, and vetting is on you. |
| **Clear Market Rate Visibility:** Publicly listed hourly rates give quick budget clarity. | **Limited Full-Lifecycle Services:** Solo consultants may not cover MLOps, security, or enterprise-grade support end to end. |
| **High Flexibility:** Scale an engagement up or down without a long-term commitment. | **Primarily for Augmentation:** Best for adding expertise to an existing team, not outsourcing an entire program. |
> **Practical tip:** When you post a job, be specific about your stack, the business problem, and the exact deliverable. A detailed brief attracts better proposals and lets freelancers estimate time and cost accurately.
**Website:** https://www.upwork.com/hire/machine-learning-experts/
## 4. Toptal: what makes its vetting process different from an open marketplace?
Toptal is an exclusive network of screened freelance talent, built around speed and a high acceptance bar - by its own account, only a small share of applicants pass its multi-stage screening. That makes it a fit when you need a specific, hard-to-find skill added to your team, like MLOps on Kubeflow or advanced generative AI fine-tuning.
Instead of browsing profiles, you submit project requirements and Toptal's internal team hand-matches you with a suitable expert, typically within a few days. That curated approach removes the friction of sourcing and vetting on your own, which makes Toptal a high-signal channel for elite contractors, interim ML leads, or small specialized teams. It also offers a managed delivery option for more structured, end-to-end execution beyond individual staff augmentation.
### Key features and how to use them
* **Rigorous Vetting Process:** Toptal's multi-stage screening tests technical expertise, problem-solving, and professionalism, so the candidates presented have already cleared a high bar.
* **Rapid Hand-Matching:** You submit a need rather than search. Be specific about the required stack (for example, PyTorch, TensorFlow, AWS SageMaker), project goals, and team dynamics - the more precise the brief, the better the match.
* **No-Risk Trial Period:** Toptal offers a trial with any matched expert. Use it to check communication style and team fit, not just technical skill; if it's not a match, you don't pay for the trial and can be re-matched.
* **Managed Delivery Option:** If your project needs more than augmentation, its managed delivery service adds project leadership - closer in structure to a traditional **machine learning consulting firm**.
* **On-Demand Talent:** Use this model to fill a specific skill gap or accelerate work already in flight: senior ML architects for initial design, MLOps engineers to productionize models, or data scientists for R&D.
### Platform pros and cons
| Pros | Cons |
| :--- | :--- |
| **High Signal on Talent Quality:** The tight acceptance bar filters out noise and connects you with senior experts. | **Premium Pricing:** Rates run higher than open freelance platforms, reflecting the talent's caliber. |
| **Fast Time-to-Hire:** Matching can place an expert on your project in days, not weeks. | **Individual-Focused Model:** The core offering is staff augmentation, not full-service strategic consulting. |
| **Access to Niche Skills:** Good for finding specialists in reinforcement learning, LLM optimization, or MLOps. | **Matching Depends on Brief Quality:** Match success depends heavily on how well you define requirements. |
> **Practical tip:** Use Toptal when you have a well-defined technical gap and need to fill it fast with a senior expert. It's less suited to ambiguous, strategic work where you need a firm to help define the problem in the first place. Come with a clear technical brief and an onboarding plan.
**Website:** [https://www.toptal.com/deep-learning](https://www.toptal.com/deep-learning)
## 5. AWS Marketplace: how does buying ML consulting through AWS change procurement?
For organizations built on Amazon Web Services, the AWS Marketplace has become a channel for sourcing **machine learning consulting firms** whose offerings are directly aligned to the AWS stack. It's a procurement-friendly catalog: you find and engage professional services providers with consolidated billing and governance already in place, so the consulting work plugs into your existing cloud investment instead of running around it.
The differentiator is direct integration with your primary cloud provider - you're browsing services built specifically for tools like Amazon SageMaker, Bedrock, and EKS. That fits projects like MLOps implementation, generative AI application development, or custom model training where you want to skip a disconnected procurement process.
### Key features and how to use them
* **Service-Specific Listings:** Search for specific offerings like "SageMaker JumpStart Implementation" or "Generative AI Strategy Assessment." Each listing details scope, deliverables, and the AWS Partner providing the service.
* **Private Offer Workflow:** Most professional services don't carry a public list price. Use "Request a private offer" to open a discussion, negotiate custom pricing and scope, and have the result billed directly through your AWS account.
* **Streamlined Procurement & Billing:** Engagements bill to your existing AWS account, which cuts the overhead of onboarding a new vendor for finance and procurement.
* **Partner Competency Validation:** Look for partners with an official AWS Competency - "Machine Learning" or "Data & Analytics" - which signals the firm has passed AWS's technical validation and shown proven customer success.
### Platform pros and cons
| Pros | Cons |
| :--- | :--- |
| **Streamlined Procurement:** Consolidates billing and vendor management into your existing AWS account. | **Opaque Initial Pricing:** Most listings require a "private offer" request, which makes early budget comparison harder. |
| **Enterprise-Friendly Governance:** Onboarding terms are familiar to corporate procurement. | **Selection Can Be Limited:** The catalog isn't as exhaustive as open directories and varies by region. |
| **Tight AWS Stack Alignment:** The consultants you hire are experts in the specific AWS services you use, like SageMaker or Bedrock. | **Diligence Still Required:** An AWS partnership doesn't guarantee fit - you still need to vet the firm's specific experience. |
> **Practical tip:** Use the AWS Marketplace when your project is definitively tied to the AWS stack and speed of procurement matters. Identify three or four partners with the relevant AWS Machine Learning Competency and send them a standardized scope of work so their private-offer proposals are comparable. For more on how these partners stack up, see this [comparison of AWS and Azure data partners](https://dataengineeringcompanies.com/insights/aws-vs-azure-data-partners/).
**Website:** [https://aws.amazon.com/marketplace/](https://aws.amazon.com/marketplace/)
## 6. Microsoft Azure Marketplace: what's different about buying fixed-scope engagements?
For organizations on the Microsoft stack, the Azure Marketplace is an efficient procurement channel for **machine learning consulting firms** that bypasses traditional vendor discovery with pre-packaged, fixed-scope offers inside the Azure platform. That fits a team that needs to deploy a targeted solution quickly - a two-week generative AI proof of concept or a four-week MLOps accelerator - with defined deliverables and a set price.
The core value is less procurement friction: you find, purchase, and deploy consulting services through your existing Microsoft Azure agreement and billing. That's a strong fit for organizations committed to Azure, OpenAI, or Databricks on Azure, since the available offers are designed around that specific stack.
### Key features and how to use them
* **Filter by Offer Type:** Start with "Consulting Services," then narrow by solution area, such as "AI + Machine Learning."
* **Defined Scopes and Deliverables:** Each listing is a productized service with a clear statement of work - look for offers like "AI-Powered Document Intelligence: 4-Week Implementation." That clarity speeds up internal budget approval compared with a custom proposal.
* **Integrated Procurement:** Transacting through your Microsoft Azure Consumption Commitment (MACC) simplifies billing and helps meet enterprise cloud spend goals.
* **Partner Vetting:** Listed firms are Microsoft Partners, which is a baseline level of vetting on Azure-stack technical capability. Look for advanced specializations in AI and Machine Learning specifically.
### Platform pros and cons
| Pros | Cons |
| :--- | :--- |
| **Transparent Scopes:** Clearly defined deliverables and timelines speed up internal approval and bypass lengthy RFPs. | **Limited Flexibility:** Fixed-scope offers may need change orders if your use case has complex or evolving requirements. |
| **Centralized Microsoft Billing:** Uses your existing Azure agreements and compliance frameworks. | **Regional & Publisher Variability:** Availability and pricing differ by partner and geography. |
| **Optimized for Azure Stack:** Engagements are tailored for Azure, OpenAI, and Databricks. | **Not a Discovery Platform:** Better for buying a known solution than for open-ended discovery of the best-fit partner. |
> **Practical tip:** Use the Azure Marketplace to stand up a proof of concept or pilot quickly and demonstrate the value of an ML initiative with minimal procurement overhead. Once the pilot succeeds, engage the same partner for a larger, custom-scoped project outside the marketplace.
**Website:** [https://azuremarketplace.microsoft.com/](https://azuremarketplace.microsoft.com/)
## 7. DataEngineeringCompanies.com: what does a specialized directory add that reviews don't?
**Best for:** Data-driven shortlisting of verified data engineering and ML consulting firms.
DataEngineeringCompanies.com is a specialized directory for organizations evaluating data engineering and machine learning consulting firms, aimed at technology and procurement leaders who want to cut vendor selection time using structured firm profiles, transparent rates, and shortlist tools.
*Note: This site publishes the guide you are reading. See the disclosure at the top of this article.*
Rather than relying solely on user-submitted reviews, the site profiles firms on structured signals - technical focus, public proof, market presence, rates, and official partner-directory evidence - with a documented methodology, which gives buyers some auditability before they make first contact.
### Key features and practical tooling
* **Cost Benchmarking:** The site publishes hourly rate bands ($45-$250/hr, median around $100/hr across profiled firms) for early-stage budgeting and comparison across vendors.
* **AI-Powered Shortlisting:** A matching quiz and filters for budget, industry, and platform expertise - Databricks (64 of 86 profiled firms), AWS (76 of 86), Snowflake, and others - surface a pre-vetted shortlist quickly.
* **RFP Acceleration:** The site includes an RFP checklist with detailed evaluation criteria to help teams prepare a thorough request for proposal.
* **Verified Partner Status:** Official partner tiers, such as Snowflake Elite and Databricks Premier, appear with verified badges as a signal of technical proficiency and strategic alliances.
| Feature | Details |
| :--- | :--- |
| **Primary Focus** | Specialized directory for data engineering and ML consulting |
| **Pricing Transparency** | Published hourly rate bands and platform/tag filters |
| **Verification** | Composite index of reviews, certifications, case studies |
| **Key Tools** | Match quiz, cost calculator, RFP checklist |
| **Best For** | CIOs, CTOs, procurement, and analytics leaders |
**Pros:**
* Structured firm profiles with a documented methodology.
* Practical buyer tooling - shortlisting quiz, cost calculator, and RFP checklist - in one place.
* Published rate bands that make early cost comparison easier.
**Cons:**
* Coverage is focused on the top 80-90 firms; hyper-niche or very small boutiques may not be represented.
* Pricing is presented in bands, so firm-specific quotes still require direct vendor contact.
* As the publisher of this guide, the site has an inherent commercial interest - weigh its profiles alongside independent sources like Clutch and G2.
**Website:** [https://dataengineeringcompanies.com](https://dataengineeringcompanies.com)
For a broader market view, see the guide to [where to find data engineering companies](https://dataengineeringcompanies.com/insights/where-to-find-data-engineering-companies/).
## Platform comparison
| Provider | Implementation complexity | Resource requirements | Expected outcomes | Ideal use cases | Key advantages |
|---|---:|---:|---|---|---|
| Clutch (Machine Learning Consulting) | Low - browse profiles and leaders matrices | Low-Medium - review client feedback and filter vendors | Pre-qualified vendor list with client reviews, rate bands, minimums | Finding ML consultancies, regional (US) searches, vendor pre-qualification | Verified client reviews, detailed profiles, strong US coverage |
| G2 (AI Development Services) | Low - side-by-side comparisons and filters | Low - read user reviews; limited granular pricing | Vendor sentiment triangulation and shortlist validation | Validating shortlists; exploring related categories (data engineering) | Rich user review content, documented scoring methodology |
| Upwork (Hire ML Engineers/Consultants) | Low-Medium - direct hiring; contractor management needed | Low-Medium - manage hires, escrow, contracts, tracking | Fast staffing for POCs or augmentation; variable deliverable scope | Rapid POCs, short-term staff augmentation, individual ML roles | Fast sourcing, transparent hourly rates, escrow and work tracking |
| Toptal (Vetted ML/Deep Learning Experts) | Low - hand-matching with rapid time-to-match | Medium-High - premium talent and higher hourly rates | Senior, high-signal talent or managed delivery for complex needs | Enterprise interim ML leadership, niche deep-learning skills, critical roles | Rigorous vetting, high signal-to-noise, no-risk trial, managed delivery option |
| AWS Marketplace (Professional Services: ML/GenAI) | Low-Medium - procurement via AWS with private-offer flows | Medium - centralized billing and AWS governance alignment | Procurement-friendly engagements aligned to AWS services | Enterprises buying AWS-aligned ML professional services and managed services | Streamlined procurement, consolidated AWS billing, enterprise terms |
| Microsoft Azure Marketplace (Consulting: AI/ML) | Low-Medium - fixed-scope/time-boxed offers simplify buying | Medium - Microsoft billing/compliance; change orders possible | Transparent fixed-scope POCs/accelerators and faster approvals | Azure/OpenAI/Databricks projects, short POCs and accelerators | Defined deliverables/pricing, centralized Microsoft purchasing and compliance |
| DataEngineeringCompanies.com | Low - discovery and shortlisting (research tool) | Low - minimal internal effort to shortlist; vendor negotiation still required | Auditable shortlist, transparent rate bands, RFP-ready briefs | Shortlisting data engineering consultancies, cloud migrations, analytics/ML enablement | Structured firm profiles, buyer tooling (quiz, calculator, RFP checklist) |
## From shortlist to selection: what's the actual workflow?
Move through these seven resources in sequence rather than jumping straight to sales calls: build a long list from review platforms, cross-reference it against a specialized directory, check tactical fit against talent networks, and confirm cloud-stack alignment before you commit. No single platform gives a complete picture - a sound selection process pulls from several sources to build one.
### A practical workflow
1. **Build your initial long list.** Use review-rich platforms like Clutch and G2 to generate a starting list. Apply non-negotiable filters - budget, location, core service focus such as NLP or MLOps - and cross-reference results between the two to find firms that appear on both.
2. **Cross-reference with a specialized directory.** Take your top five to eight candidates and check them against a directory like DataEngineeringCompanies.com. Compare published rate bands, capability ratings, and partner certifications against what you found on the review platforms.
3. **Assess tactical fit.** For niche skills or agile team augmentation, compare shortlisted firms against talent networks like Toptal or Upwork to benchmark individual expert rates against the blended rates quoted by full-service consultancies.
4. **Check tech-stack alignment.** Confirm whether your leading contenders are listed on the AWS or Azure Marketplaces. A strong presence with relevant competencies signals a deeper, certified partnership with the cloud provider and can simplify procurement and billing.
### Three pillars for the final evaluation
Apply this framework consistently across every firm on your final list:
1. **Technical alignment and proven expertise.** Does the firm have demonstrable, referenceable experience in your industry and with your chosen stack (Databricks, Snowflake, Azure ML)? Look past marketing case studies - ask for anonymized project architectures, code samples where appropriate, and direct access to references from clients who faced similar challenges.
2. **Operational and commercial fit.** Evaluate project management methodology (Agile, Scrum, or otherwise), communication protocols, and team composition. A lower hourly rate from a firm with poor communication and inefficient process usually costs more in delays and rework. Clarify minimum project size, contract flexibility, and the seniority mix of the proposed team.
3. **Strategic and cultural compatibility.** A successful ML initiative is a long-term partnership. The right **machine learning consulting firm** should act as an extension of your team - willing to challenge assumptions and tie recommendations to your business objectives, not just the immediate technical requirements.
> **Key insight:** The most common vendor-selection error is prioritizing a low hourly rate over proven, relevant expertise. A team that costs more but delivers a production-ready solution faster typically produces a better return and avoids the opportunity cost of a stalled project.
### What else matters before you sign
* **Communication and collaboration model.** How do they manage projects - Agile sprints, Waterfall, or a hybrid? Make sure their methodology fits your internal team's workflow.
* **Knowledge transfer and enablement.** A strong partner doesn't just build a solution, they train your team to own and operate it afterward. Ask about documentation standards, training sessions, and post-engagement support.
* **Business acumen.** Can they translate technical work into business outcomes? The right firm speaks in terms of ROI and total cost of ownership, not just precision and recall.
### Structuring your RFP
Once you have a short list of three or four firms, run a structured Request for Proposal that probes for the answers that matter:
* **Problem framing.** Do they simply accept your proposed solution, or do they offer alternative approaches?
* **Proposed architecture.** Ask for a high-level technical architecture to see how they think about scalability and maintainability.
* **Team allocation.** Request the specific profiles, not just roles, of the people who would work on your project, and insist on interviewing the proposed lead and senior engineers.
* **Risk mitigation.** What roadblocks do they anticipate, and how would they handle them? A mature firm is upfront about risk from the start.
Cross-reference every step against a specialized directory like the [Data Engineering Companies Index](/data-engineering-consulting-firms/) - firms with verified Databricks or Snowflake partner status carry a more concrete signal than marketing copy alone, and MLOps-specific needs are covered in more depth in [MLOps consulting services](/insights/mlops-consulting-services/).
---
## The CIO's Guide to Master Data Management Consulting
Source: https://dataengineeringcompanies.com/insights/master-data-management-consulting/
Published: 2026-03-23T10:09:24.989306+00:00
Description: Discover how master data management consulting can create value, evaluate firms, and structure engagements for measurable data results.
Master data management (MDM) consulting builds the systems and governance that turn fragmented customer, product, and supplier records into one trusted source of truth. It matters because AI personalization, supply chain optimization, and cloud-scale analytics all break when the master data feeding them is inconsistent - the engagement fixes the data foundation, not just the symptom. It's also a specialty, not a commodity: only 11 of the [86 firms profiled in the Data Engineering Companies Index](/data-governance/) list data governance among their core capabilities, which narrows the real shortlist fast.
An MDM engagement is not a data-cleansing project. It's an infrastructure build, and the architectural pattern and consulting partner you choose determine whether the result keeps working after the consultants leave or turns into one more one-off cleanup.
## When should you engage an MDM consulting firm?
Bring in MDM consultants when poor data quality becomes a measurable drag on operations and a blocker for strategic goals, not before. The urgency is real: the MDM software market is growing quickly, driven by business leaders demanding reliable data, not IT wanting cleaner databases.
Look for these specific trigger points within your organization:
* **Failed or Stalled Strategic Initiatives:** Your new CRM, ERP, or e-commerce platform fails to deliver expected value because it's running on inconsistent customer or product data.
* **Inability to Generate a 360-Degree View:** Your marketing, sales, and service teams operate with conflicting customer records, making personalization impossible and frustrating customers.
* **High Operational Overhead:** Your teams spend an excessive amount of time manually reconciling data between systems, leading to errors in fulfillment, billing, and reporting.
* **Compliance and Security Risks:** You cannot demonstrate a clear data lineage for critical data elements, exposing the business to risk under regulations like GDPR and [CCPA](https://oag.ca.gov/privacy/ccpa).
An MDM consulting engagement directly addresses these problems by implementing a centralized hub and a governance framework to create and maintain a "golden record" for each core business entity.
### The Engineering Value of MDM
For a CTO or VP of Engineering, the value proposition is straightforward: MDM creates a stable, reliable data foundation for the entire tech ecosystem.
* **Decouples Systems:** A central MDM hub decouples point-to-point integrations. Instead of dozens of fragile connections, systems subscribe to the master record, simplifying architecture and reducing maintenance.
* **Accelerates Analytics and AI:** Clean, consolidated master data is the prerequisite for trustworthy analytics. BI platforms and AI models fed by a master data source produce more accurate and reliable outputs, faster.
* **Enforces Governance Programmatically:** An MDM platform operationalizes your [data governance program](/insights/data-governance-best-practices/) by enforcing data standards, validation rules, and ownership workflows directly within the tool.
MDM consulting moves your organization from a reactive state of fixing data errors to a proactive state of preventing them at the source. That shift is what turns data from a liability into a strategic asset.
## What do MDM consulting engagements cost, and what do you get?
MDM engagements break into three tiers based on scope: strategic advisory to build the business case, single-domain implementation to deploy the platform, and a managed-services retainer once you're live. Rates across the [86 firms profiled in the Data Engineering Companies Index](/insights/data-engineering-consulting-rates-2026/) run $45 to $250 an hour, with a median near $100 - a useful sanity check against any MDM proposal before you compare the project totals below.
### 1. Strategic Advisory & Roadmap (2-4 months, $75k - $150k)
This is a blueprinting engagement for organizations that know they have a problem but need a clear plan. The focus is on building the business case and technical roadmap.
* **Decision:** "Which data domain should we tackle first, and what is the expected ROI?"
* **Core Deliverables:**
* **MDM Readiness Assessment:** An audit of a target data domain (e.g., Customer) identifying sources, quality issues, and business impact.
* **Business Case & ROI Analysis:** A financial model quantifying the cost of inaction vs. the expected benefits from operational savings and revenue uplift.
* **Data Governance Charter:** A foundational document defining data ownership, stewardship roles, and decision-making processes.
* **Platform Shortlist & TCO Model:** An unbiased recommendation of 2-3 MDM platforms ([Informatica](https://www.informatica.com/), [Semarchy](https://www.semarchy.com/), [Profisee](https://profisee.com/)) with a Total Cost of Ownership analysis.
### 2. Single-Domain Implementation (6-12 months, $150k - $400k)
This is the most common engagement model, focused on deploying an MDM platform for a single, high-value domain like Customer or Product.
* **Decision:** "How do we build, configure, and integrate an MDM hub to create a golden record for our customers?"
* **Core Deliverables:**
* **Configured MDM Platform:** A production-ready installation of the chosen MDM software in your cloud environment (AWS, Azure, GCP).
* **Technical Data Model:** The canonical schema for the master data entity.
* **Integration Pipelines:** Data pipelines built to ingest data from source systems into the MDM hub and syndicate the golden record to downstream consumers.
* **Match, Merge & Survivorship Rules:** The implemented business logic that identifies duplicates and programmatically creates the single source of truth.
* **Data Stewardship Workflows:** Configured UIs and processes for data stewards to manage exceptions and manual reviews.
### 3. Managed Services (Ongoing Retainer, $15k - $50k+/month)
After go-live, this model provides ongoing operational support for companies without a dedicated internal MDM team.
* **Decision:** "How do we ensure the MDM platform continues to deliver value and data quality remains high without hiring a full-time team?"
* **Core Deliverables:**
* **Platform Monitoring & Maintenance:** Proactive management of the MDM environment.
* **Data Quality Reporting:** Regular dashboards showing key metrics like match rates, completeness, and accuracy.
* **Data Stewardship-as-a-Service:** Execution of daily data stewardship tasks, such as resolving duplicates and validating new records.
The value of an MDM initiative is realized across key data domains, each solving a different business problem.
| Data Domain | Business Problem Solved | Key Metrics Impacted | Engineering Benefit |
| :--- | :--- | :--- | :--- |
| **Customer Data** | Inconsistent cross-channel experiences | Customer Lifetime Value (CLV), Churn Rate | A stable customer ID for all analytics. |
| **Product Data** | Slow time-to-market, high return rates | Product Launch Cycle Time, Order Accuracy | A single source of truth for e-commerce and ERP systems. |
| **Supplier Data** | Inefficient procurement, supply chain risk | Procurement Costs, Supplier Onboarding Time | Streamlined vendor management and risk assessment. |
| **Location Data** | Poor asset and territory management | Asset Utilization, Sales Territory Performance | Optimized logistics and sales operations. |
Choosing the right engagement model depends entirely on your organization's maturity. Start with a strategic advisory project if the business case isn't clear; move directly to implementation if the pain is well-defined and a budget is allocated.
## How do you evaluate MDM consulting partners?
Selecting the wrong partner is the leading cause of MDM project failure, and a polished deck is not evidence of capability. Score candidates against four pillars - technical and platform expertise, verifiable industry experience, implementation methodology, and strategic vision - and require concrete evidence in each, not general reassurances.
### MDM Consulting Partner Evaluation Checklist
| Evaluation Criterion | Weight (1-5) | Questions to Ask | Red Flags to Watch For |
| :--- | :---: | :--- | :--- |
| **Technical & Platform Expertise** | 5 | Show us your team's certifications for [Informatica](https://www.informatica.com/), [Semarchy](https://www.semarchy.com/), or [Profisee](https://profisee.com/). Describe a complex data integration you built between an MDM hub and a legacy system. | Outdated certifications. Answers that are generic and not platform-specific. Inability to discuss cloud-native architecture (AWS, Azure, GCP). |
| **Verifiable Industry Experience** | 5 | Provide two case studies from our industry (e.g., Fintech, Healthcare). How have you handled industry-specific data standards and compliance needs? | Case studies are from unrelated industries. The team is unfamiliar with your domain's regulations and terminology. A "one-size-fits-all" pitch. |
| **Implementation Methodology** | 4 | Walk us through your methodology for a single-domain MDM implementation. How do you define and operationalize a data stewardship program? | No documented methodology. A rigid, waterfall-only approach. Data governance is treated as a "Phase 2" item. |
| **Strategic Vision & Scalability** | 4 | How does this initial project set the foundation for a multi-domain enterprise MDM program? How will you measure and report on business ROI, not just technical metrics? | The proposal focuses only on the initial implementation. Success metrics are purely technical (e.g., "number of records matched"). |
| **Team & Culture** | 3 | Can we interview the proposed project lead and technical architect? How do you manage scope changes and technical disagreements? | A "bait-and-switch" where senior partners sell the deal, but junior staff deliver it. Poor communication during the evaluation process. |
> **The Litmus Test Question:** "Describe your process for designing, testing, and implementing survivorship rules for a customer golden record."
A partner with hands-on experience will describe a detailed, iterative process involving business stakeholder workshops, rule configuration in a sandbox, and quantitative testing. A weak partner gives a textbook definition instead. Their answer reveals their true level of expertise fast, which is exactly why [choosing the right partner](/insights/data-engineering-partner-selection/) matters more for a multi-domain MDM program than for a single one-off project.
## Which MDM architecture pattern fits your data stack?
MDM has four architectural patterns - registry, consolidation, coexistence, and transactional - and each determines how data flows and where authority lives. An experienced **master data management consulting** partner recommends the pattern that fits your maturity and goals, not just the one their platform implements best.
### The Four MDM Architectural Patterns
1. **Registry Style:** The MDM hub acts as an index, maintaining unique identifiers and pointing to master data in source systems without moving it. It identifies duplicates but doesn't create a central golden record. **Use Case:** Initial data discovery in complex, locked-down legacy environments.
2. **Consolidation Style:** Data is copied from source systems to the MDM hub, where it is matched, cleansed, and consolidated into a golden record. This hub then becomes the source of truth for analytics and reporting. **Use Case:** Powering a data warehouse or BI platform with clean data.
3. **Coexistence Style:** This pattern does everything the consolidation style does but also synchronizes the cleansed golden record back to the original source systems, gradually improving their data quality over time. **Use Case:** Improving both analytics and operational data quality simultaneously.
4. **Transactional Style:** The most authoritative pattern. The MDM hub becomes the system of entry for all new master data. All new customer or product records are created directly in the hub, ensuring consistent quality from inception. **Use Case:** Mature organizations aiming for complete control over master data creation.
### Integrating MDM with Snowflake, Databricks, and dbt
In a modern data stack, the MDM platform is an upstream, authoritative source. Its primary function is to feed clean, deduplicated, and enriched master data to your cloud data platform, whether it's [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/).
The integration pattern is direct:
1. Source system data (e.g., Salesforce, NetSuite) is ingested into the MDM hub.
2. The MDM platform applies matching and survivorship rules to create and maintain the golden record (e.g., `dim_customer_master`).
3. This master dimension table is replicated to a dedicated schema in your data warehouse.
4. Data transformation models built in tools like [dbt](https://www.getdbt.com/) join transactional data against this master dimension, ensuring all analytics are built on the single source of truth.
This architecture prevents analysts from having to perform ad-hoc customer deduplication in their queries, which is inefficient and error-prone. The MDM system centralizes this logic, guaranteeing consistency for all downstream data consumers. Your consulting partner must have demonstrable experience building these specific integration pipelines into modern cloud data platforms.
## How do you launch your first MDM initiative?
Prepare before the consultants arrive: define the business problem and quantify the pain in one data domain, shortlist three to five partners with relevant experience, then issue an RFP that forces vendors to prove strategic thinking, not just technical knowledge. Skipping this prep is what lets scope creep take over.
### Step 1: Define the Problem and Build the Business Case
Do not boil the ocean. Select one high-impact data domain - typically **Customer** or **Product** - where poor data quality creates the most friction. Quantify the business pain. Document the operational costs (e.g., hours spent on manual reconciliation), lost revenue (e.g., failed marketing campaigns), or compliance risks. This document is not an IT request; it is a business plan that will justify the investment and guide every decision.
### Step 2: Create a Focused Vendor Shortlist
Use industry-specific directories and analyst reports to identify **3-5 potential consulting partners**. Your primary filter must be verifiable experience in your industry (e.g., Retail, Fintech, Healthcare) and with your target tech stack (e.g., Azure + Profisee). Generalist firms without domain expertise introduce significant risk.
### Step 3: Issue a Value-Based Request for Proposal (RFP)
A strong RFP forces vendors to demonstrate strategic thinking, not just technical knowledge. It should include:
* Your business case and the quantified pain points.
* A clear definition of the initial project scope (the single data domain).
* Questions that probe their methodology, governance approach, and experience with ROI measurement.
Use a structured RFP checklist to ensure you ask the right questions. This level of preparation shifts the dynamic, allowing you to lead the evaluation process and select a partner who will deliver measurable results.
## What do engineering leaders ask about MDM consulting?
### What is the difference between Master Data Management and Data Governance?
**Data Governance** is the framework of rules, roles, and processes for managing all data assets. It's the "constitution." A [data governance consultant](/insights/data-governance-consulting/) helps you write the laws.
**Master Data Management (MDM)** is the specific technology and discipline used to enforce those laws for your most critical data (customer, product, etc.). It's the "court system" that actively creates and maintains the single source of truth. You cannot have effective MDM without governance, but MDM is the implementation that delivers tangible business value from that governance.
### How much does an MDM consulting project cost?
Budget ranges are fairly predictable once you know the domain count:
* **Single-Domain Proof-of-Concept / Implementation:** **$150,000 to $400,000**. This focuses on one domain (e.g., "Customer") to prove business value quickly.
* **Full Enterprise Multi-Domain Implementation:** **$750,000+**. This is a large-scale transformation program that integrates multiple master data domains across the enterprise.
Key cost drivers include the number of source systems, the initial data quality, and the complexity of the business rules for survivorship. Most organizations see a return within roughly two years of go-live.
### Should we use an on-premises or cloud MDM solution?
For nearly all use cases, a cloud-native SaaS MDM platform is the better choice: faster time-to-value, lower total cost of ownership, better scalability, and direct integration with modern data stacks like [Snowflake](https://www.snowflake.com/en/) and [Databricks](https://www.databricks.com/).
On-premises solutions are only worth considering for organizations with strict data residency requirements or security policies that prohibit cloud usage, and that choice comes with real trade-offs: higher capital expenditure, longer implementation cycles, and a permanent need for a specialized internal team to run the infrastructure. If your data ecosystem already lives in AWS, Azure, or GCP, a cloud MDM platform is the straightforward choice.
---
Ready to find a partner with the right expertise for your MDM initiative? **DataEngineeringCompanies.com** offers pre-vetted shortlists of top firms, transparent cost data, and practical frameworks to help you choose with confidence. Use our free [60-second vendor match quiz](/) to get started.
---
## Microsoft Fabric Consulting: 8 Azure-Capable Firms Compared for 2026
Source: https://dataengineeringcompanies.com/insights/microsoft-fabric-consulting-companies/
Published: 2026-07-20T09:00:00.000000+00:00
Description: Compare 8 Azure- and Power BI-capable firms for Microsoft Fabric consulting - rates, team size, and fit - plus how to verify certified Fabric (DP-600) expertise.
Microsoft Fabric is a unified SaaS analytics platform that combines Power BI, Azure Synapse Analytics, and Azure Data Factory into one product, built around OneLake as a single storage layer in the open Delta Parquet format. It became generally available on November 15, 2023. Below are 8 Azure- and Power BI-capable data engineering firms from our directory whose stack maps to Fabric's building blocks - Data Factory, Synapse Data Engineering, Synapse Data Warehousing, and Power BI.
Of the 8 firms, only [EY](/ey/) currently lists Microsoft Fabric by name in our records. The rest bring the Azure Synapse, Power BI, and Azure Data Factory foundation that Fabric consolidates, not a stated Fabric practice. Our directory does not track Microsoft Fabric certifications (the Fabric Analytics Engineer Associate exam, DP-600) or Microsoft Solutions Partner designations. If certified Fabric specialization is a requirement, verify it directly through Microsoft's [Fabric partner directory](https://www.microsoft.com/en-us/microsoft-fabric/partners) before you shortlist.
## Compare Fabric-capable firms
| Firm | Rate | Team size | Best for | Wrong for |
| :--- | :--- | :--- | :--- | :--- |
| [Celebal Technologies](/celebal-technologies/) | $50-100/hr | 1000 | Microsoft Azure specialists; Power BI and AI solutions | A platform other than Azure as the primary stack |
| [DataArt](/dataart/) | $50-100/hr | 3000 | Custom software development with embedded data engineering; European nearshore delivery | Deep single-platform specialization (Snowflake Elite / Databricks Premier depth) |
| [Devoteam](/devoteam/) | $100-175/hr | 11000 | European enterprises; cloud and cybersecurity specialists | Buyers outside Europe, or mid-market programs under $50K |
| [EY](/ey/) | $175+/hr | 5000 | Global compliance, audit-ready data platforms, and finance transformation | Engagements below its $200K+ minimum |
| [Kanerika Inc](/kanerika-inc/) | $75-150/hr | 200 | Intelligent automation and data analytics; Microsoft Azure specialists | Snowflake-primary programs without Azure |
| [ProCogia](/procogia/) | $125-200/hr | 100 | Data consultancy and bioinformatics; enterprise data mesh | Large parallel delivery bench or global contractual scale |
| [Wipro](/wipro/) | $50-100/hr | 200000 | Large-scale global enterprises; offshore delivery model | Mid-market buyers with sub-$100K scope |
| [XenonStack](/xenonstack/) | $50-100/hr | 500 | Agentic AI systems; real-time analytics; platform engineering | Traditional batch warehouse migration or Snowflake-primary delivery |
Firms are listed alphabetically. We do not rank firms by quality - use the best-for and wrong-for columns to narrow the list, then verify Fabric specialization directly with Microsoft before you send an RFP.
## 1. Celebal Technologies
Rate: $50-100/hr. Team: 1000. Minimum project: $25K+.
Celebal Technologies positions as a Microsoft Azure specialist, with named strength in Power BI and AI solutions; per their profile, they were named a Microsoft Partner of the Year across 2022-2025. It is the wrong choice for programs where a platform other than Microsoft Azure is the primary stack - its earned depth is Azure-first.
## 2. DataArt
Rate: $50-100/hr. Team: 3000. Minimum project: $50K+.
DataArt works across AWS, Azure, GCP, Databricks, Snowflake, and Spark, built around custom software development with embedded data engineering and European nearshore delivery. It is the wrong choice for buyers needing deep single-platform specialization, such as Snowflake Elite or Databricks Premier depth - its broad custom-build model is not a single-platform specialist.
## 3. Devoteam
Rate: $100-175/hr. Team: 11000. Minimum project: $50K+.
Devoteam serves European enterprises as a cloud and cybersecurity specialist, working across AWS, GCP, Azure, Snowflake, Databricks, Microsoft, and Salesforce. It is the wrong fit for buyers outside Europe needing a locally present partner, or mid-market programs under $50K where an 11,000-person consultancy's overhead outweighs a boutique.
## 4. EY
Rate: $175+/hr. Team: 5000. Minimum project: $200K+.
EY is the only firm on this list that lists Microsoft Fabric explicitly in our records, alongside Azure, Snowflake, and Databricks. It fits global compliance, audit-ready data platforms, and finance transformation work. It is the wrong choice for any engagement below its $200K+ minimum, or for buyers who don't need Big Four compliance, audit, or finance-data depth.
## 5. Kanerika Inc
Rate: $75-150/hr. Team: 200. Minimum project: $10K+.
Kanerika Inc focuses on intelligent automation and data analytics, positioning as a Microsoft Azure specialist across Azure Data Factory, Synapse, and Power BI, alongside AWS, GCP, Databricks, and Snowflake capability. It is the wrong fit for organizations whose primary platform is Snowflake without Azure, or programs needing delivery scale beyond a 200-person firm.
## 6. ProCogia
Rate: $125-200/hr. Team: 100. Minimum project: $25K+.
ProCogia runs data consultancy and bioinformatics work, including enterprise data mesh projects, with Azure listed first in its stack ahead of AWS, GCP, Snowflake, Databricks, and Spark. It is the wrong choice for buyers needing a large parallel delivery bench or global contractual scale - at 100 people it can't sustain multi-workstream enterprise staffing.
## 7. Wipro
Rate: $50-100/hr. Team: 200000. Minimum project: $100K+.
Wipro serves large-scale global enterprises through an offshore delivery model, across AWS, Azure, GCP, Snowflake, Databricks, SAP, and Hadoop. It is the wrong fit for mid-market buyers with sub-$100K scope, or anyone needing a nimble, low-overhead engagement.
## 8. XenonStack
Rate: $50-100/hr. Team: 500. Minimum project: $10K+.
XenonStack builds agentic AI systems, real-time analytics, and platform engineering work, which maps to Fabric's Real-Time Intelligence workload, across AWS, Azure, GCP, Databricks, Kafka, Spark, and Kubernetes. It is the wrong choice for buyers whose program centers on traditional batch warehouse migration or Snowflake-primary delivery.
## What does a Microsoft Fabric consulting engagement involve?
A Fabric engagement typically covers lakehouse and schema design in OneLake, Synapse Data Engineering and Data Warehousing work, Data Factory pipeline builds, and Power BI semantic models, plus migration from standalone Synapse or Power BI Premium capacity into Fabric's unified SaaS model. Some engagements add Copilot enablement. Scope varies by firm - confirm what's included before signing a statement of work.
## How much does Microsoft Fabric consulting cost?
Rates for the 8 firms above span $50-200+/hr, from Kanerika Inc's $75/hr floor to EY's $175+/hr. Across our full 86-firm index, rates run $45-250/hr with a median of $100/hr. Minimum project sizes for the firms above range from $10K to $200K+, tracking with team size and how enterprise-focused the firm is.
## How do you verify a firm's Microsoft Fabric expertise?
Our directory tracks rate, team size, platform list, and stated best-fit and wrong-fit use cases, but it does not track Fabric-specific certifications or Microsoft Solutions Partner designations. To confirm a firm holds the Fabric Analytics Engineer Associate credential (DP-600) or a relevant partner tier, check Microsoft's [Fabric partner directory](https://www.microsoft.com/en-us/microsoft-fabric/partners) directly.
## Which of these firms lead with the Microsoft stack?
EY is the only firm that lists Microsoft Fabric explicitly. Kanerika Inc and Celebal Technologies position themselves as Azure and Power BI specialists, naming Azure Data Factory, Synapse, and Power BI in their profiles. The remaining five firms are multi-cloud shops where Azure is one platform among several, alongside AWS, GCP, and Snowflake.
## When do you need a Fabric consultant vs in-house?
Bring in a consultant for platform-specific work your team hasn't done before - OneLake shortcut design, Synapse-to-Fabric migration, or rebuilding semantic models across Power BI and Fabric together. Handle Fabric in-house when your team already owns the Power BI and Azure Synapse environment being migrated, and the remaining work is routine pipeline maintenance.
## Frequently asked questions
### Which of these 8 firms explicitly list Microsoft Fabric in your directory?
Only [EY](/ey/) lists Microsoft Fabric by name in our records. The other seven firms - Celebal Technologies, DataArt, Devoteam, Kanerika Inc, ProCogia, Wipro, and XenonStack - list Azure, Power BI, or Azure Synapse capability, which forms the foundation Fabric consolidates, but not a stated Fabric practice.
### What's the smallest project these firms will take on?
Kanerika Inc and XenonStack list minimum project sizes of $10K+. Celebal Technologies and ProCogia list $25K+. DataArt and Devoteam list $50K+. Wipro lists $100K+, and EY lists $200K+, reflecting its Big Four compliance and finance-transformation focus.
### Does the DP-600 Fabric Analytics Engineer certification matter for hiring a consultant?
It can, if certified individual expertise is a requirement. DP-600 (Microsoft Certified: Fabric Analytics Engineer Associate) became generally available May 7, 2024. Our directory does not track which consultants or firms hold it - verify directly through Microsoft's [Fabric partner directory](https://www.microsoft.com/en-us/microsoft-fabric/partners) before you shortlist a firm on that basis.
### How many firms in your directory offer Azure services overall?
70 of the 86 firms profiled in our directory list Azure capability, and 21 list Power BI. The 8 above are a subset selected for this guide because their stack maps most closely to Fabric's building blocks; browse the full [Data Engineering Companies Index](/data-engineering-consulting-firms/) to see the rest.
---
## MLOps Consulting Services: A Buyer's Guide for 2026
Source: https://dataengineeringcompanies.com/insights/mlops-consulting-services/
Published: 2026-04-09T07:12:21.889183+00:00
Description: Find the right MLOps consulting services. This guide covers pricing, deliverables, RFP questions, and red flags for engineering leaders.
MLOps consulting services turn a model that works in a notebook into a system your platform team can run without you: production pipelines, a model registry, deployment gates, drift monitoring, and a named owner for what happens when the model breaks. Buy it as a data engineering decision, not an AI strategy exercise - you are paying for pipeline architecture and operating discipline, not slides about the future of AI.
I have hired MLOps consultants three times. Two engagements were worth every dollar because the consultants built production systems, documented handoff, and forced hard decisions on tooling and ownership. One was a slow-motion train wreck. The firm talked endlessly about AI strategy, delivered slideware, and left us with half-wired pipelines no internal team wanted to own.
ML/AI capability shows up in 64 of the 86 firms profiled in the [Data Engineering Companies Index](/insights/machine-learning-consulting-firms/) - the harder part is separating consultants who can actually operationalize a model from ones who can only talk about it.
## Why does a working ML model still fail to reach production?
A model that performs well in a notebook still needs a way to compute features in production, a deployment path nobody has to babysit personally, and a defined owner for retraining and rollback. Without those three things, the handoff from data science to engineering stalls indefinitely.
Engineering asks how the features will be computed in production. Nobody knows if training data matches serving data. The deployment script lives on one person's laptop. Retraining is manual. Nobody has defined rollback criteria. If the model starts drifting, there is no alerting path and no owner.
That is not a modeling problem. It is an operations problem.
The first successful MLOps engagement I ran fixed this by narrowing scope. We did not ask the consultants to "build our AI platform." We asked them to productionize one model, on one cloud stack, with one deployment path and one monitoring standard. That forced concrete decisions around Airflow, MLflow, containerization, registry gates, and incident ownership.
The failed engagement did the opposite. The consultants spent weeks "assessing maturity" while the team kept shipping manual workarounds. They never produced a deployment-ready architecture. They never connected model delivery to the same discipline you would expect from a [well-engineered CI/CD pipeline](https://kluster.ai/blog/cicd-best-practices). They treated ML as special enough to skip engineering rigor.
> If your model can only be deployed by the person who trained it, you do not have an ML capability. You have a fragile demo.
Good MLOps consulting services close the gap between notebook success and platform reality. They replace tribal knowledge with repeatable workflows your data engineers, ML engineers, and platform team can run.
## What deliverables should MLOps consulting actually produce?
Push vendors to name concrete artifacts across three areas: platform engineering, model lifecycle management, and governance. A proposal that talks about transformation but can't name deliverables in these terms is not specific enough to buy.
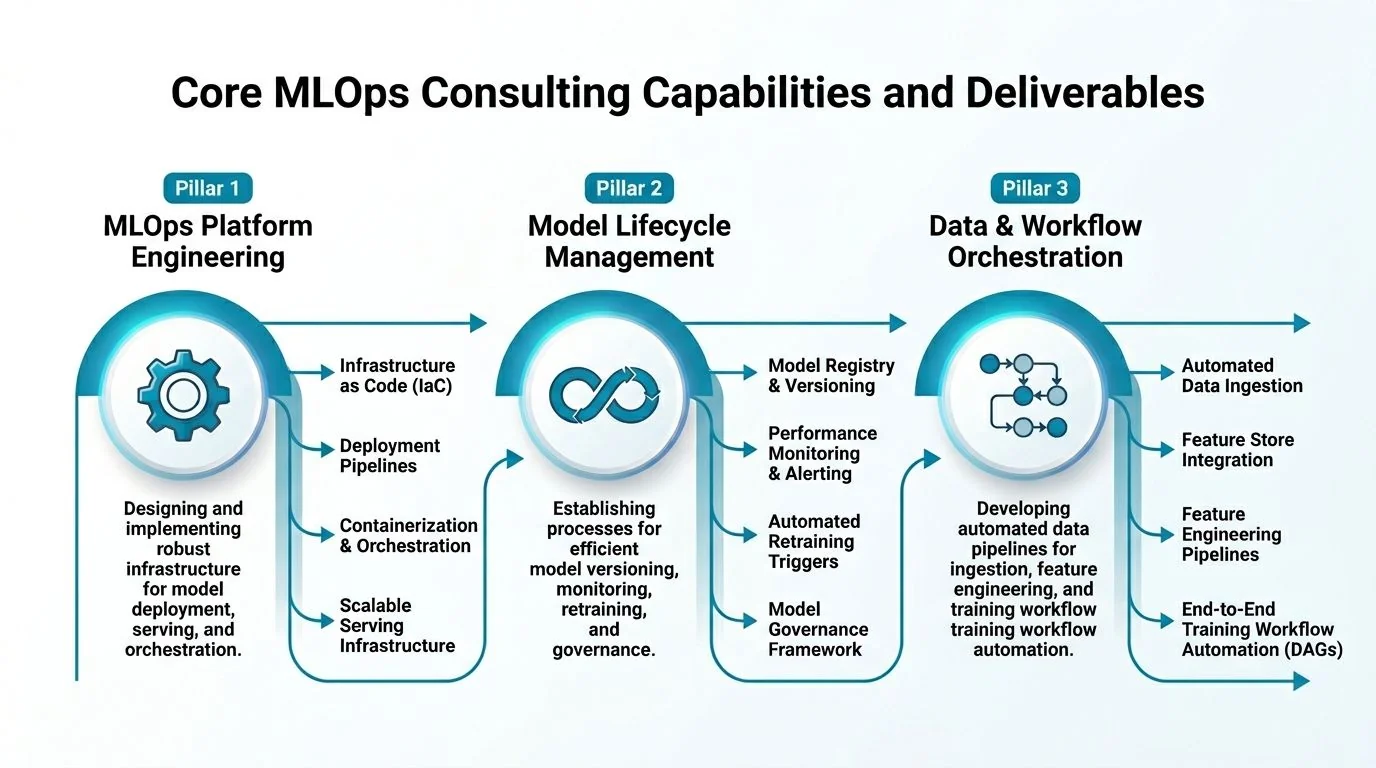
### Platform engineering deliverables
This is the foundation. If the vendor cannot talk clearly about cloud architecture, data movement, and environment reproducibility, stop the conversation.
A serious platform workstream usually includes:
- **Reference architecture:** A documented target architecture on AWS, Azure, or GCP that shows how training, registry, feature pipelines, batch inference, and real-time inference connect.
- **Infrastructure as code:** Terraform, Pulumi, or cloud-native templates for reproducible environments.
- **Environment standards:** Container build patterns, dependency management, secrets handling, access controls, and promotion paths across dev, staging, and production.
- **Platform fit decisions:** A clear recommendation on whether to center the stack on Databricks, SageMaker, Vertex AI, Azure ML, Kubeflow, MLflow, or a hybrid pattern tied to your data platform.
- **Integration points:** Explicit hooks into Snowflake, Databricks, dbt, Airflow, Kafka, BigQuery, Delta Lake, or your existing warehouse and orchestration layers.
The best consultants constrain the stack. They do not present ten "flexible" options. They explain why one stack fits your team's existing operational muscle.
### Model lifecycle deliverables
Many firms overpromise and underbuild in this area. Ask for the mechanics.
You want deliverables such as:
- **Experiment tracking and lineage:** Logged runs, datasets, parameters, artifacts, and model comparison history.
- **Model registry with promotion gates:** Defined criteria for when a model moves from candidate to staging to production.
- **CI/CD workflows for models and infrastructure:** Automated testing, packaging, deployment, and rollback controls.
- **Release patterns:** Shadow deployments, canary releases, staged approvals, and rollback logic tied to degradation signals.
- **Retraining rules:** Scheduled or event-driven retraining, drift-triggered retraining, and approval workflows for re-release.
A good consultant also specifies who owns each gate. Data science should not promote a model to production without review. Platform engineering should not block releases because the process was never codified.
> The actual deliverable is not "automation." It is a production path with named controls, known failure modes, and clear operators.
### Governance and monitoring deliverables
Regulated environments separate competent firms from tourists in this area.
Look for:
- **Data quality checks:** Schema validation, freshness checks, and threshold-based input validation.
- **Drift detection:** Monitoring for changes in input distributions and model behavior.
- **Performance dashboards:** Executive-readable views for business stakeholders and operational dashboards for on-call engineers.
- **Audit trails:** Versioning of training runs, datasets, parameters, approvals, and deployments.
- **Fairness and explainability controls:** Especially for healthcare and financial services use cases.
Consistent data quality standards are one of the cheapest ways to prevent MLOps failures - most drift alerts and broken retraining runs trace back to an upstream schema change or a null-handling rule nobody documented, not to the model itself.
### What a buyer should insist on
Use this as a minimum acceptance checklist.
| Deliverable area | What you should receive |
|---|---|
| Architecture | Cloud and platform reference architecture tied to your stack |
| Pipelines | Automated training and deployment workflows for at least one production model |
| Registry | Configured model registry with promotion criteria |
| Monitoring | Drift, performance, and operational alerting dashboards |
| Governance | Audit trail design, access controls, and documentation |
| Handover | Runbooks, ownership map, and internal enablement sessions |
If a proposal talks about transformation but does not name deliverables like these, it is not specific enough to buy.
## Which MLOps engagement model fits your situation?
Project-based engagements suit a defined platform build with a clear end state. Staff augmentation suits execution capacity when the architecture is already settled. Managed services suit ongoing operational coverage when your team doesn't want to run day-to-day model operations. Pick based on what's already decided internally, not on how a vendor packages the pitch.
Vendors sell the same core skills - architecture, pipeline engineering, monitoring - wrapped in very different commercial models, and matching the wrong wrapper to your situation is a common, expensive mistake.
### Project-based engagements
This is the right model when you need a platform build, migration, or remediation with a clear end state.
Use it for:
- **Net-new platform setup:** First production pipeline, first model registry, first observability layer.
- **Specific migration work:** Moving from ad hoc scripts to managed workflows on Databricks, SageMaker, or Vertex AI.
- **Delivery with handoff:** You want your team running the system after the engagement.
Avoid it when your scope is fuzzy or your internal owners are not named. A fixed-scope project without internal accountability turns into change-order theater.
### Staff augmentation
This works when your architecture is mostly settled and you need execution capacity.
It fits situations like:
- **Backfilling specialist skills:** An ML platform engineer, data engineer, or cloud infra lead.
- **Temporary acceleration:** You have a roadmap and need more hands to implement it.
- **Internal ownership stays strong:** Your managers still direct architecture and priorities.
I like this model least when the company expects the consultants to supply strategy. Augmented staff can build. They rarely fix a broken decision process.
### Managed services
This is the right choice when you want ongoing operational coverage for pipelines, deployments, monitoring, and incident response.
It makes sense when:
- **Your team is lean:** You do not want to run day-to-day model operations internally.
- **You need continuity:** Regular retraining, observability upkeep, compliance reporting, and support.
- **Operational discipline matters more than bespoke engineering:** Especially in stable, repeatable environments.
The downside is dependency. If the provider runs the system but never transfers knowledge, you rent capability instead of building it.
### The team structure I trust
The strongest engagements usually use a small delivery pod:
| Role | What they should own |
|---|---|
| Lead MLOps architect | Target architecture, tool decisions, delivery governance |
| MLOps engineer | CI/CD, registry, deployment workflows, monitoring |
| Data engineer | Feature pipelines, orchestration, warehouse and lakehouse integration |
| Cloud or platform engineer | IAM, networking, environments, infrastructure controls |
If a vendor shows up with strategy consultants and no senior hands-on engineer, walk away. MLOps gets won in implementation detail.
## What does MLOps consulting actually cost?
Across the 86 firms profiled in the Data Engineering Companies Index, hourly rates for data engineering and MLOps-adjacent work span roughly $45 to $250, with a median near $100. Principal-level architects and specialized MLOps engineers sit toward the top of that range; nearshore and offshore teams sit toward the bottom.
Most buyers ask the wrong pricing question. They ask, "What does MLOps consulting cost?" The useful question is, "What team, for what deliverables, over what time horizon?" High demand and a shallow pool of senior talent push rates up, especially for principal-level architects who can bridge cloud infrastructure, data engineering, and ML operations.
| Role tier | Where it typically falls in the $45-$250/hr range |
|---|---|
| US/UK-based principals | Top of the range |
| Senior engineers | Middle of the range |
| Nearshore or offshore resources | Bottom of the range |
Those bands are directional, not a quote. Cheap hourly rates often hide slow delivery, weak architecture, or a team mix that overuses junior engineers. Expensive rates are justified only when the vendor shortens decision cycles and avoids rework.
### What good pricing looks like
The cleanest proposals separate work into three buckets:
- **Discovery and architecture:** Current-state audit, target architecture, backlog, and acceptance criteria.
- **Implementation:** Pipeline build, infra setup, registry, deployment workflows, observability.
- **Enablement and handoff:** Runbooks, training, ownership transfer, and stabilization support.
If a vendor sends a single blended rate and no role mix, push back. For broader benchmarks on how data engineering firms structure rates and thresholds, see [data engineering consulting rates](/insights/data-engineering-consulting-rates-2026/).
### Minimum project thresholds matter more than hourly rates
Buyers often run into trouble here. Many firms will happily start a small engagement that has no chance of producing a usable production capability.
My rule is simple. If the budget cannot fund architecture, one real production pipeline, monitoring, and handoff, do not start. A partial MLOps implementation creates more operational complexity than it removes.
A video overview can help align non-technical stakeholders on what they are funding and why:
> Buy outcomes, not activity. A vendor that logs hours without leaving you with an operable system is expensive at any rate.
## What separates a strong MLOps vendor from a weak one?
Look for evidence in five areas: platform depth, data engineering fluency, real delivery artifacts, a plan for internal enablement, and proof they've handled your industry's compliance requirements. A vendor selling "AI transformation" instead of naming these five things is not ready to be hired.
If you want a useful parallel process for judging consulting rigor, this guide on [how to evaluate a DevOps consulting company](https://devopsconnecthub.com/top-companies/how-do-you-evaluate-a-devops-consulting-company-in-the-usa/) is worth reading. The same discipline applies here. Delivery quality shows up in architecture depth, operating model clarity, and handoff quality.
### Positive signals that predict a strong engagement
#### Platform depth
The vendor should have a clear point of view on your likely stack. Databricks and AWS anchor most specialist MLOps builds - 64 and 76 of the 86 profiled firms tag those platforms, respectively - so if you run Azure and Databricks, expect them to explain exactly how they handle MLflow, Delta Lake, orchestration, secrets, access boundaries, and deployment promotion. Generic "cloud-agnostic" talk is not enough.
#### Data engineering fluency
MLOps failures usually start upstream. The firm needs real strength in Airflow, dbt, Spark, warehouse-lakehouse integration, feature pipelines, and data quality controls. If they talk only about models, they are missing the hard part.
#### Delivery artifacts
Ask to see sample architecture diagrams, runbooks, release workflows, incident playbooks, and handover docs. Mature firms have these ready.
#### Internal enablement
The best vendors design for independence. They train your engineers, document the workflows, and leave behind systems your team can extend.
#### Industry fit
This matters most in regulated environments. Many firms skip compliance-specific needs like [HIPAA](https://www.hhs.gov/hipaa/for-professionals/index.html) or [FDA 21 CFR Part 11](https://www.fda.gov/regulatory-information/search-fda-guidance-documents/part-11-electronic-records-electronic-signatures-scope-and-application), which makes compliance-first architecture a decisive evaluation criterion in healthcare and finance.
### Red flags that should kill the deal
I would reject a vendor quickly for any of these.
- **They sell "AI transformation" before they define delivery scope.** Strategy language often hides weak implementation.
- **They cannot explain ownership after go-live.** If no one knows who runs retraining, rollback, alerting, and approvals, the platform will decay.
- **They have no view on your existing data platform.** MLOps has to fit Snowflake, Databricks, BigQuery, dbt, Airflow, and your cloud controls.
- **They dodge compliance specifics.** In healthcare and fintech, inability to discuss auditability, explainability, documentation, and regulated workflows is disqualifying.
- **They promise tool agnosticism as a virtue.** Breadth is useful. Lack of depth is expensive.
- **They do not include knowledge transfer.** That is how you end up dependent on the same firm for basic maintenance.
> The right vendor makes your internal team stronger. The wrong vendor makes your environment more confusing and your roadmap slower.
## What should an MLOps RFP actually ask?
A good RFP forces vendors to prove architecture depth, operational realism, and measurable success criteria instead of describing capabilities in the abstract. Ask for a reference architecture on your stack, a named deployment path with rollback triggers, and proposed KPIs, and score responses against those specifics, not the prose.
Most buyers never get a standardized scorecard from vendors, so proposals skip concrete KPIs unless the RFP forces the issue. Fix that here.
### MLOps Consulting RFP Evaluation Checklist
| Category | Key Question | Why It Matters |
|---|---|---|
| Technical architecture | Provide a reference architecture for an MLOps platform you have deployed on our target cloud and data stack. | Exposes whether the vendor has real implementation depth or generic diagrams. |
| Technical architecture | Show how training, feature computation, registry, batch inference, and real-time inference integrate with our warehouse or lakehouse. | Confirms they understand data engineering dependencies, not just model hosting. |
| Technical architecture | Which tools do you recommend for orchestration, registry, monitoring, and deployment, and why not the main alternatives? | Strong vendors can justify tradeoffs clearly. |
| Process and workflow | Describe the exact path from model training to production deployment. Include gates, approvals, and rollback triggers. | Forces operational detail instead of abstract "CI/CD" claims. |
| Process and workflow | What artifacts will be versioned across code, data, configurations, and models? | Reveals whether reproducibility is designed in. |
| Process and workflow | How will you onboard the first production model, and how will additional models reuse the same platform? | Distinguishes a one-off build from a scalable operating model. |
| Governance and security | Describe your approach to audit trails, access controls, lineage, and deployment approvals. | Necessary for enterprise controls and regulated use cases. |
| Governance and security | How do you detect data drift, model degradation, and upstream data quality failures? | Monitoring design is central to production reliability. |
| Governance and security | If we operate in healthcare or finance, how do you adapt the architecture for compliance-first deployment? | Exposes whether the vendor can handle regulated environments. |
| Commercials and ROI | Propose success metrics for the engagement, including time-to-production, deployment frequency, retraining automation, and pipeline failure reduction. | Prevents vague outcome claims and creates a scorecard. |
| Commercials and ROI | Break pricing out by role, workstream, and deliverable. | Lets buyers compare staffing models and challenge padding. |
| Commercials and ROI | What must our internal team provide for the project to succeed? | Serious vendors understand buyer-side responsibilities and dependencies. |
### Questions that expose weak vendors fast
These are my favorites in a live review:
- **Walk us through a failed production model deployment and how your architecture contained the issue.**
- **Show us a sample runbook for a drift alert.**
- **Explain what your team will hand over in week one, midpoint, and final transition.**
- **Name the decisions you expect us to make in the first two weeks.**
Weak firms answer with process theater. Strong firms answer with examples, documents, and tradeoffs.
> If the vendor cannot define success metrics before kickoff, they are not ready to be measured after kickoff.
## How do you build a shortlist of MLOps consulting firms?
Start with budget realism using the rate bands above, then build a longlist based on platform and industry fit rather than brand recognition. Run a five-step funnel - stack fit, industry exposure, minimum engagement fit, RFP screening, and a working session with two or three finalists.
The fastest way to narrow the field is to review specialist firm profiles and shortlists rather than broad agency directories. A practical place to start is this guide to [firms with real machine learning consulting depth](/insights/machine-learning-consulting-firms/).
Then run a disciplined funnel:
1. **Filter by stack fit:** Snowflake, Databricks, AWS, Azure, GCP, Airflow, dbt, MLflow, Kubeflow.
2. **Filter by industry exposure:** Healthcare, fintech, retail, or enterprise platform work.
3. **Check minimum engagement fit:** Do not waste time on firms that only want much larger programs than yours.
4. **Use the RFP checklist in screening calls:** Ask architecture and handoff questions early.
5. **Cut to two or three finalists:** Then do a working session, not just a sales demo.
Many buyers make the process too democratic at this stage. Procurement, data science, platform engineering, and security all deserve input. One executive still needs final decision rights. Without that, every vendor gets scored as "promising" and nobody gets selected.
## Frequently Asked Questions about MLOps Consulting
### Should we build an in-house team or hire consultants
Do both, in sequence.
Use consultants to design and implement the first production-ready platform, then transfer ownership to your internal team. That is the best pattern if you already have strong data engineering and platform talent. If you do not, the consultants should still build with handoff in mind.
Do not outsource core operational knowledge indefinitely unless you intentionally want a managed service model.
### What is a realistic timeline for an MVP MLOps platform
A realistic answer is "long enough to support one real production model safely."
I do not trust vendors who promise instant platform builds. A credible MVP includes architecture decisions, one productionized model path, environment setup, deployment workflow, monitoring, and handoff. If the proposal skips any of those, it is not an MVP. It is a demo.
### What is the difference between MLOps and general DevOps consulting
DevOps consulting focuses on software delivery pipelines, infrastructure automation, and runtime operations for deterministic applications.
MLOps adds data dependencies, model versioning, retraining logic, drift detection, experiment tracking, and non-deterministic behavior. That changes the architecture. It also changes the failure modes. A model can degrade without a code change. That is why general DevOps shops often miss critical ML-specific controls.
### How do we measure the ROI of an MLOps engagement
Start with operational metrics, not boardroom slogans.
Track:
- **Time from model-ready to production deployment**
- **Frequency of successful model releases**
- **Amount of manual intervention in retraining and deployment**
- **Pipeline failure frequency and recovery process**
- **Auditability of data, model, and deployment lineage**
The key is to baseline those before the engagement begins. If the vendor does not insist on that, insist on it yourself.
### What is the biggest mistake buyers make
They buy broad capability claims instead of narrow production outcomes.
The winning engagement usually starts with one model, one team, one cloud stack, and one clear set of deliverables. The losing engagement starts with vision decks, generic roadmaps, and "future-state AI operating models" disconnected from your actual data platform.
### What should the final handoff include
At minimum, I expect:
- Architecture documentation
- Infrastructure and pipeline code in your repos
- Runbooks for deployment, rollback, and drift response
- Ownership mapping
- Training sessions for engineering and operations
- A stabilization period with explicit exit criteria
If those are missing, the consultants did not finish the job.
---
## A Practical Guide to the Modern Data Stack in 2026
Source: https://dataengineeringcompanies.com/insights/modern-data-stack/
Published: 2025-12-12T07:13:00.08079+00:00
Description: Explore the modern data stack with this practical guide. Learn about its architecture, core layers, AI integration, and governance to drive real business value.
TL;DR: Key Takeaways
Decoupled architecture: Splitting storage from compute (ELT instead of ETL) lets teams scale each independently, which is why most migrations cut infrastructure spend 50-70% versus fixed on-premises capacity.
Five layers, not one tool: Ingestion (Fivetran, Airbyte), storage (Snowflake, Databricks), transformation (dbt), BI (Tableau, Looker), and activation (Reverse ETL) each do one job well instead of one vendor doing all five adequately.
Lakehouses are consolidating batch and streaming: instead of running two pipelines, unified platforms handle both on the same data, which is why they're gaining share against pure warehouses.
AI is absorbing the plumbing work: auto-generated ingestion, anomaly detection, and query suggestions are shifting data teams from writing scripts to reviewing them - the goal is closer to 80% strategy, 20% maintenance than the reverse.
Governance decides whether any of this survives contact with a compliance audit: data quality, lineage, access control, and observability aren't optional add-ons once the stack touches production decisions.
The modern data stack is a set of cloud-native tools - ingestion, storage, transformation, BI, and activation - that replace one monolithic system with modular, best-of-breed components wired together by APIs and SQL. **Fivetran or Airbyte move data in, Snowflake or Databricks store it, dbt transforms it, and Tableau or Looker turn it into decisions.** Because storage and compute are decoupled, each layer scales on its own, and a team can swap out any one tool without re-architecting the rest.
## Why did the modern data stack replace legacy systems?
**Legacy on-premises systems bundled storage and compute into one block, so scaling query performance meant buying more storage whether or not you needed it.** That coupling created capital-heavy, slow-to-scale infrastructure. The cloud broke the bundle apart: pay for compute and storage independently, and scale either one in minutes.
For decades, organizations ran on-premises systems defined by high upfront capital costs, slow and expensive scaling, and vendor lock-in. The core flaw was structural: storage and compute lived in the same box.
That meant scaling query performance required buying more storage at the same time, whether it was needed or not. The mismatch created bottlenecks that slowed analytics and delayed decisions for weeks or months.
Think of a legacy system as a restaurant with a fixed kitchen and dining room. To seat more diners (compute), you'd have to build a bigger, more expensive kitchen (storage) at the same time. A cloud-native stack adds tables on demand for a dinner rush without touching the kitchen, and you pay only for the capacity you use.
### Why does modularity beat an all-in-one vendor?
Splitting storage from compute is what makes the rest of the modular stack possible. It lets a team pick the best tool for each job - ingestion, storage, transformation, activation - rather than settling for one vendor's mediocre version of all four.
The payoff shows up in three places:
* **Pay-as-you-go elasticity.** Resources scale up or down in minutes, tying cost directly to usage. This is the mechanism behind the commonly cited 50-70% infrastructure savings versus maintaining on-premises servers.
* **Faster ingestion.** The ELT (Extract, Load, Transform) model loads raw data directly into cloud storage, preserving fidelity and cutting pipeline rebuild time from weeks to hours - analysts can iterate on transformations without re-ingesting from hundreds of sources.
* **Vendor independence.** Because the tools are interchangeable, a better or cheaper option can be swapped in without re-architecting the system around it.
The global data analytics market that this shift is feeding is projected to hit $132.9 billion by 2026 - this isn't a niche architectural preference, it's where the budget is already going.
### How do legacy and modern data stacks compare?
| Characteristic | Legacy data stack (ETL) | Modern data stack (ELT) |
| :--- | :--- | :--- |
| **Architecture** | Monolithic (compute & storage coupled) | Modular (compute & storage decoupled) |
| **Hosting** | On-premise servers | Cloud-native |
| **Cost model** | High upfront CAPEX, fixed costs | Pay-as-you-go OPEX, variable costs |
| **Scalability** | Slow, expensive, requires hardware procurement | Elastic, scales up or down in minutes |
| **Data model** | Extract, Transform, Load (ETL) - rigid | Extract, Load, Transform (ELT) - flexible |
| **Flexibility** | Locked into a single vendor's ecosystem | Best-of-breed tools from multiple vendors |
| **Data sources** | Primarily structured, relational data | Structured, semi-structured, and unstructured data |
| **Accessibility** | Limited to specialized data teams | Accessible to a wider range of business users |
For most organizations, migrating from a rigid, expensive legacy system to a modular, elastic stack has stopped being a strategic choice and started being table stakes for staying competitive.
## What are the 5 core layers of the modern data stack?
**A complete modern data stack has five layers: ingestion (moving data in), storage (a warehouse or lakehouse), transformation (turning raw data into modeled tables), BI and orchestration (dashboards plus job scheduling), and activation (pushing insights back into operational tools).** Skip a layer and the others absorb the gap, usually at a cost in reliability or trust.
Data moves through the stack the way materials move through a supply chain: ingested, stored, processed, and assembled into something usable, then delivered to the teams making decisions with it. Break any link and the chain stops, along with the ROI the stack was supposed to deliver.
### Layer 1: Ingestion
The data journey begins with **ingestion**: moving data from its source into a central storage system. Sources are numerous and varied - SaaS applications, production databases, real-time event streams.
Engineers used to write and maintain custom scripts that broke with every API change. Modern ingestion tools like [Fivetran](https://www.fivetran.com/) and [Airbyte](https://airbyte.com/) replace that with pre-built connectors that handle schema changes, authentication, and API maintenance on their own - see our [comparison of ETL tools](https://dataengineeringcompanies.com/insights/etl-tools-comparison/) for how the major options differ on connector reliability and CDC support.
### Layer 2: Storage
Once ingested, data needs a home. The **storage** layer is typically a cloud data warehouse or, increasingly, a **lakehouse** that blends a warehouse's query performance with a data lake's cheaper, more flexible storage.
That architecture lets organizations store large volumes of raw, unstructured data affordably while still running fast SQL queries against it. Snowflake alone shows up in the platform stack of 66 of the 86 firms in our directory (77%) - more than any other single warehouse or lakehouse platform we track, which tells you where the market has actually settled rather than where vendors say it's headed.
### Layer 3: Transformation
With raw data loaded, the next step is **transformation** - the "T" in **ELT**. Unlike legacy ETL, which transforms data before loading it, ELT loads raw data first.
That preserves the original data's fidelity and gives analysts room to model and reshape it as needed, without a full re-ingestion from the source. Using SQL-based modeling tools like [dbt](https://www.getdbt.com/), teams treat data logic like software: version control, automated testing, documentation. Even so, only 19 of the 86 firms in our directory (22%) list dbt explicitly among their platforms, despite it being the default choice for SQL-based transformation - a sign that most firms fold transformation work into a broader platform-migration engagement rather than sell it as a standalone specialty.
### Layer 4: Business intelligence and orchestration
This is where data becomes insight. **Business intelligence (BI)** tools connect to transformed data so users can build self-service dashboards, generate reports, and explore data on their own. Modern BI lets domain experts in marketing, finance, and ops answer their own questions, cutting their dependency on central data teams by an estimated 60-80%.
Behind the scenes, **orchestration** manages the schedules and dependencies of every ingestion and transformation job, so each step runs in the right order at the right time. Our guide on [data orchestration platforms](https://dataengineeringcompanies.com/insights/data-orchestration-platforms/) covers how tools in this layer differ on scheduling model and failure handling.
### Layer 5: Activation
The final layer, **activation**, is arguably the one most often skipped. A dashboard nobody acts on doesn't create value; value shows up when data gets pushed back into the operational tools teams use daily.
This practice, often called **Reverse ETL**, moves refined data from the warehouse into systems like Salesforce, Marketo, or ad platforms.
> Sending a fresh list of product-qualified leads directly into a sales rep's CRM is what activation looks like in practice. It closes the loop between analysis and action, turning the stack from a passive reporting tool into something that drives revenue directly.
## Should you use batch, micro-batch, or streaming?
**Batch processing is the default for most analytical workloads - weekly sales reports, monthly financial summaries - because it's the cheapest and simplest option. Streaming is for cases that can't wait milliseconds, like fraud detection or dynamic pricing. Micro-batching sits between the two.** The wrong choice either over-engineers a system that bleeds cash or under-builds one that fails when fresh data actually matters.
After the core layers are defined, one decision remains: what data latency does the business actually require? Batch, micro-batch, and real-time streaming carry very different cost and complexity profiles.
For most analytical workloads, batch processing is enough. Data is collected and processed on scheduled intervals - the most cost-effective, straightforward option, and the workhorse for most BI.
Some operations can't wait, though. A fraud detection system has to catch a malicious transaction in milliseconds, not hours. A dynamic pricing engine has to react to market changes instantly. A nightly batch job doesn't work for either.
### How much freshness do you actually need?
A true streaming architecture is complex, expensive, and requires specialized skills to run - and it's easy to over-buy it. A more pragmatic middle ground is **micro-batching**: processing data in small, frequent intervals, every five or ten minutes, instead of continuously. It delivers near-real-time freshness without the full overhead of streaming, and it's the right fit for most operational analytics use cases.
Align the choice with the actual requirement:
* **Batch processing:** historical analysis and BI reports where freshness measured in hours or days is fine.
* **Micro-batch processing:** operational dashboards and tactical decisions that need data updated every few minutes.
* **Real-time streaming:** automated, sub-second actions - algorithmic trading, IoT sensor alerts.
### Why are unified platforms replacing dual pipelines?
Supporting both batch and streaming used to mean building and maintaining two separate, redundant pipelines. Unified platforms remove that duplication.
> A lakehouse can handle both large batch queries and real-time streaming ingestion on the same data, through one engine, instead of maintaining a parallel pipeline for each. That convergence is what simplifies infrastructure and cuts maintenance overhead - not a marketing claim, just fewer moving parts to keep in sync.
The shift is directional: data warehouses and lakehouses remain the most common choices for new cloud builds, but teams increasingly prioritize unified, real-time platforms that converge both. That architectural convergence is a large part of what is driving sustained growth in the big data analytics market. To see the pattern applied, review these [data pipeline architecture examples](/insights/data-pipeline-architecture-examples/).
## How is AI changing the modern data stack?
**By 2026-2027, AI is expected to sit inside every layer of the stack rather than bolt onto it - auto-generating ingestion pipelines, flagging anomalies in storage, suggesting transformation logic, and answering business questions in plain language.** The practical effect is fewer hours spent on manual plumbing and more spent on the work that actually needs a person.
This is rebalancing how data teams spend their time. The old model - where 80% of hours went to manual "plumbing," writing scripts, fixing broken pipelines, managing infrastructure - is inverting, with AI automating the low-level tasks and freeing up that same 80% for higher-impact work.
### Where does AI show up in each layer?
* **Ingestion:** AI assistants can auto-generate ingestion pipelines from source schemas, cutting setup time from days to minutes.
* **Storage:** AI-powered anomaly detection inside the warehouse or lakehouse flags data quality issues or unusual usage patterns before they hit a report.
* **Transformation:** instead of writing SQL from scratch, analysts get suggestions for joins, optimizations, and data modeling.
* **Business intelligence:** natural language query (NLQ) is becoming standard - a non-technical leader can ask "What was our customer acquisition cost by channel last quarter?" and get an answer without writing SQL.
This conversational layer changes who can ask the question, not just how fast it gets answered. A business leader without deep technical training can now self-serve an insight that used to require a request to the data team.
### From manual plumbing to automated insights
The real shift is from answering questions to anticipating them. AI can surface predictive insights before anyone asks - "Sales for Product X are trending down and will likely drop 15% next quarter due to declining customer engagement in the Northeast" is the kind of statement this makes possible.
That moves the organizational default from reactive ("What happened?") to proactive ("What's likely to happen, and what do we do about it?").
None of this replaces the data team. It removes the low-value, high-effort work so the people on that team spend their time on the decisions AI can't make for them.
## Why do governance and observability matter?
**A modern data stack without governance and observability fails quietly at first, then all at once - business users stop trusting the numbers, and a compliance audit turns a small gap into a costly one.** Governance and observability are what make a stack reliable and auditable, not optional layers bolted on after the fact.
Building a modern data stack without governance and observability is like building a city with no zoning, no fire department, and no map. Early progress looks fast; the result is an environment nobody can actually manage.
Poor governance has derailed more modern data stacks than any tooling failure has. The moment business users stop trusting the data, the investment behind the stack stops paying off. A compliance audit that turns up a security gap can mean millions in fallout.
### What does "data as a product" mean?
The organizations that get this right treat data as a product: a data asset has to meet quality standards, be documented, and be easy for consumers - analysts, executives, AI models - to find and use reliably. That means governance gets built into every stage of the data lifecycle, not bolted on afterward as a fix.
### What are the core pillars of modern data governance?
| Pillar | Objective | Key tools & practices |
| :--- | :--- | :--- |
| **Data quality** | Ensure data is accurate, complete, and reliable. | Automated testing (e.g., [dbt tests](https://www.getdbt.com/), [Great Expectations](https://greatexpectations.io/)), data quality contracts, anomaly detection. |
| **Data lineage** | Map the complete journey of data from source to consumption. | Automated lineage tracking tools (e.g., [Atlan](https://atlan.com/), [Collibra](https://www.collibra.com/)), metadata management. |
| **Access control** | Guarantee that only authorized users can view or modify data. | Role-based access controls (RBAC), attribute-based access controls (ABAC), data masking for sensitive PII. |
| **Data discovery** | Make it easy for users to find, understand, and trust data. | Centralized data catalog with business glossary, metadata, and documentation. |
| **Observability** | Monitor the health and performance of the data stack before it fails. | Dashboards for pipeline latency, query performance monitoring, real-time alerting on failures or anomalies. |
### What happens when governance is neglected?
Observability is the operational side of governance - the dashboards and alerts that catch pipeline slowdowns, data quality degradation, or runaway query costs before they compound. It's the smoke detector, not the fire department.
> Ignoring governance costs more than the tools would have. Eroded trust leads to poor decisions, and compliance failures can mean millions in fines and lost opportunities - a hidden tax on the data investment that can eclipse what the tools themselves cost.
A modern data stack is only as valuable as the trust it commands. Embedding governance and observability from day one is what makes an ecosystem secure and trustworthy rather than just fast to stand up. For a deeper walkthrough, see our guide on [data governance consulting](https://dataengineeringcompanies.com/insights/data-governance-consulting/).
## How do you build a modern data stack that lasts?
**Build for the evolution, not just today's dashboards.** Business requirements will move from BI reporting to real-time AI and agentic workflows over the next 2-3 years, and a stack built only for today's reports guarantees a rip-and-replace project later. The fix is committing to open standards early, before switching costs make it expensive to change course.
Open standards and interoperability are what make that commitment real. Locking data into a proprietary format is a bet against your own flexibility later.
### Why do open table formats matter?
Adopting open table formats like [Apache Iceberg](https://iceberg.apache.org/) or [Delta Lake](https://delta.io/) decouples data from any single vendor's storage or compute engine - a universal adapter, in effect. That means swapping tools, upgrading components, or adopting new technology doesn't require a painful migration; the data stays portable, from basic analytics to the low-latency demands of generative AI.
### What comes after the "stack"?
The end state isn't a bigger collection of tools - it's a converged, AI-native system built on trusted, reusable **data products** that power agentic workflows. It's the difference between assembling a car from a kit and engineering one that drives itself: the components still matter, but the value is in how tightly they integrate into a system that runs largely on its own.
> The goal is a direct flow of insight from the data warehouse into operational actions. That's where a consistent, well-defined metrics layer earns its keep - it's what keeps the sales team and the C-suite looking at the same number.
That shift is what turns data from a cost center into a revenue driver.
### Why are data products and a unified metrics layer the north star?
Two principles do most of the work here:
1. **Data as a product.** Treat critical datasets as products with clear owners, quality SLAs, and documentation - reliable enough for both human and AI consumption.
2. **A unified metrics layer.** Define core business logic - "customer lifetime value," for instance - once, in a centralized semantic layer. This consistency is what makes automation and decision-making trustworthy; without it, the sales team and the C-suite end up arguing over numbers that were never the same number to begin with.
Getting these two right is what separates an adaptable data ecosystem from another stack that needs replacing in three years.
## Frequently asked questions
### What's the real difference between a modern and legacy stack?
The primary difference is the shift from rigid on-premises monoliths to modular, cloud-native architectures. Legacy stacks coupled storage and compute, forcing over-provisioning and high fixed costs. The modern stack decouples them, allowing independent scaling and a pay-as-you-go model that can cut infrastructure costs by 50-70%.
The other major shift is from ETL (Extract, Transform, Load) to ELT (Extract, Load, Transform). Loading raw data first and transforming it inside the warehouse preserves data fidelity and speeds up development, cutting pipeline rebuild time from weeks to hours.
### What are the must-have components?
A functional modern data stack needs five core layers. Miss one and it creates a bottleneck that erodes the stack's ROI.
* **Ingestion:** automated connectors pulling data from sources like SaaS apps and databases. [Fivetran](https://www.fivetran.com/) and [Airbyte](https://airbyte.com/) are the common choices.
* **Storage:** a scalable cloud data warehouse or lakehouse as the central repository. [Snowflake](https://www.snowflake.com/) and [Databricks](https://www.databricks.com/) lead here.
* **Transformation:** SQL-based modeling tools turning raw data into analytics-ready assets. [dbt](https://www.getdbt.com/) is the industry standard.
* **Business intelligence:** self-service analytics platforms for exploration and dashboarding. [Tableau](https://www.tableau.com/) and Looker are common choices.
* **Activation:** Reverse ETL tools pushing refined data from the warehouse back into operational systems like Salesforce or Marketo.
### How do you keep the costs of a modern data stack under control?
Cost control is what separates a well-run stack from a runaway cloud bill. It comes down to managing total cost of ownership, not just initial tool pricing - unchecked spend from idle clusters, duplicate data, or inefficient queries can exceed legacy costs fast.
Prioritize tools with built-in cost management: auto-scaling, query optimization, granular usage-based pricing. Ignoring TCO tends to produce technical debt disguised as modernization.
### Can you build a data stack that won't need a full rebuild later?
Yes, but it takes committing to open standards and interoperability from the start, and avoiding proprietary lock-in.
Building on open table formats like [Apache Iceberg](https://iceberg.apache.org/) or [Delta Lake](https://delta.io/) decouples data from any single vendor's compute engine or storage system. That keeps data portable, so adapting to new technology - from analytics to real-time AI - doesn't require a rip-and-replace overhaul.
---
Choosing the right architecture is one decision; choosing who helps you build it is another. Our [data pipeline hub](https://dataengineeringcompanies.com/data-pipeline/) lists firms filtered by platform migration and data modernization capability, with rates and minimum project size attached, so you can compare options against the layers covered here before you talk to anyone.
---
## 7 Top Nearshore Data Engineering Companies for 2026
Source: https://dataengineeringcompanies.com/insights/nearshore-data-engineering-companies/
Published: 2026-05-14T10:07:56.244661+00:00
Description: Our 2026 guide to nearshore data engineering companies vets 7 top firms on rates, platforms (Snowflake/Databricks), and minimums. Find your ideal partner.
The shortlist problem is getting worse, not better. More firms now market nearshore data engineering, but more options have not improved buyer clarity. They have increased noise, inflated platform claims, and made weak evaluation processes more expensive.
Selecting a data engineering vendor depends on technical compatibility, operational alignment, and accountability. A standard staff augmentation approach overlooks the essential decision factors: Snowflake versus Databricks alignment, dbt project design, orchestration standards, cloud foundation maturity, migration sequencing, governance ownership, and responsibility for on-call support when pipelines fail. In our analysis of 86 firms, the primary gap was not headline capability. It was delivery reliability once work moved past initial architecture and into ongoing platform operations.
That is why this list is intentionally narrow. It is not a generic directory. It is a vetted shortlist based on our proprietary review of 86 firms, with emphasis on concrete differentiators that technical leaders screen for: delivery frameworks, warehouse and lakehouse depth, platform specialization, engagement model flexibility, and evidence that the partner can support enterprise data programs after the first release. If your team needs a sharper procurement lens, use this [framework for evaluating data engineering vendors](/insights/data-engineering-vendor-evaluation-criteria/) before you issue an RFP.
Cost still matters. It just should not lead the process.
The stronger nearshore partners win on communication discipline, architectural judgment, and their ability to integrate with your internal platform team without slowing delivery. That trade-off shows up fast in data programs. A lower hourly rate does not help if the partner creates rework in your transformation layer, ships brittle orchestration, or needs heavy internal oversight to manage production quality.
Use this shortlist accordingly. Start with platform fit and delivery model, then pressure-test governance, observability ownership, and team composition. Engineering leaders do not need a long list. They need a partner that can ship, operate, and adapt without turning vendor management into a second full-time job.
If you want the founder-side lens before you brief procurement, read this [guide for SaaS founders on nearshore](https://ritenrg.com/blog/nearshore-service/).
## 1. Wizeline
[Wizeline](https://www.wizeline.com) belongs near the top of this shortlist because it can cover platform build and product-facing data work in the same engagement. That is a specific advantage for engineering leaders who need a partner that can ship pipelines, support warehouse design, and work closely with ML or application teams without creating a handoff problem between vendors.
That profile is not common. In our review of 86 firms, many looked credible on cloud migration or BI delivery, but fewer showed a clear operating model for data engineering that extends into AI enablement and product integration.
### Where Wizeline stands out
Wizeline's edge is delivery discipline. Its AI.R+ framework gives buyers an actual execution model to evaluate, not generic AI messaging, and it pairs that with cloud platform support across AWS, Azure, and GCP. For data leaders, that matters because partner quality usually breaks on coordination, not tool access. Ingestion, modeling, orchestration, observability, and release management need one team structure.
Wizeline is also an official Snowflake partner. If your roadmap centers on Snowflake modernization and you expect downstream AI use cases, that combination is stronger than stitching together one vendor for warehouse work and another for applied delivery.
It is a better fit for complex programs than for cheap capacity.
### What to watch
The trade-off is commercial clarity. Wizeline does not publish public pricing, and engagements are typically shaped through discovery. That is workable, but only if you control the process. Define role mix, architecture decision rights, delivery cadence, and production support ownership before kickoff.
Its geographic footprint also cuts both ways. Multiple hubs can improve coverage, but they can also produce a distributed team with uneven overlap if you do not specify location preferences and working hours upfront. If you are still comparing regional models, this breakdown of [US vs offshore data engineering trade-offs](/insights/us-vs-offshore-data-engineering/) is a useful calibration point before you finalize nearshore staffing assumptions.
Use this [vendor evaluation guide from DataEngineeringCompanies.com](/insights/data-engineering-vendor-evaluation-criteria/) before you sign. Ask for named technical leads, sample delivery plans, and a clear answer on who owns observability after go-live.
**Best fit**
- **Snowflake-led platform programs:** You need warehouse build, dbt-style transformation, orchestration, and AI-ready data pipelines under one delivery model.
- **Product and data teams working in parallel:** Your data roadmap depends on close coordination with application engineering or ML teams.
- **Leadership-heavy buying environments:** You want a partner with a structured delivery story that engineering, procurement, and executives can all evaluate quickly.
## 2. Gorilla Logic
[Gorilla Logic](https://gorillalogic.com) earns a place on this shortlist for one reason. It presents itself like an engineering delivery firm, not a generalist outsourcing vendor trying to stretch into data.
That distinction matters for technical leaders choosing among nearshore data engineering companies. In our review of 86 firms, very few combined a clear nearshore operating model with visible platform alignment across Snowflake, Databricks, streaming, and cloud-native analytics. Gorilla Logic did. If your backlog is full of pipeline rebuilds, lakehouse adoption, or warehouse modernization, that focus is more useful than a long menu of adjacent consulting services.
### Why Gorilla Logic makes the shortlist
Gorilla Logic is strongest when your internal team wants to keep architecture control and add execution capacity fast. It fits programs where staff engineers or principal architects own standards, while the partner handles pipeline implementation, orchestration work, integration, and testable delivery against a defined platform roadmap.
That makes it a good option for build-heavy environments. You are not buying a giant transformation layer. You are buying engineers who can work inside an existing delivery motion and contribute on the platforms most data teams are standardizing on.
Its public positioning also gives buyers a cleaner signal than many competitors in this category. You can tell what it wants to do well.
### Trade-offs
The trade-off is scope. Gorilla Logic looks stronger on platform engineering than on business-side analytics design, semantic modeling strategy, or industry-specific reporting requirements. If your program depends on deep healthcare, financial services, or regulatory analytics context, plan for additional expertise on your side or from a second specialist.
Commercial clarity is another point to press on. Pricing is proposal-based, which is normal in this segment, but technical leaders should not accept vague staffing language. Ask for the actual team shape, seniority mix, named technical leadership, and the boundary between platform build, data modeling, and production support. If you are still pressure-testing regional cost and collaboration assumptions, this guide to [US vs offshore data engineering trade-offs](/insights/us-vs-offshore-data-engineering/) is the right frame for that decision.
A nearshore partner only helps if the operating model is explicit. Set coding standards, review ownership, on-call expectations, and release cadence before work starts.
**Best fit**
- **Databricks or Snowflake platform delivery:** You need engineers who can contribute to modern warehouse or lakehouse implementation without a heavy consulting wrapper.
- **Architecture-led teams:** Your internal leads want decision rights, and the partner's job is execution, velocity, and day-to-day delivery.
- **Streaming and pipeline modernization:** You are rebuilding ingestion, orchestration, or low-latency data flows and need hands-on engineering depth more than business transformation support.
## 3. Encora
Encora is the right pick when delivery risk sits in migration mechanics, not in executive change management. In our review of 86 firms, Encora stood out for one specific reason: it pushes automation into the parts of data programs that usually slow down after architecture is approved, including mapping, metadata handling, and data quality workflows.
That matters if your bottleneck is execution across messy systems, multiple domains, and uneven source documentation.
### Where Encora is strongest
Encora's clearest differentiator is its Data Agents Ecosystem. For engineering leaders, the practical question is not whether the AI label sounds modern. It is whether the firm can reduce manual work in lineage capture, schema mapping, trust checks, and migration prep without creating a black box your team cannot govern.
Encora is strongest when those tasks are large enough to drag down delivery velocity on their own. If you are consolidating fragmented pipelines, standardizing metadata across business units, or cleaning up inconsistent mappings during a cloud migration, its accelerator-heavy model can help. That is a more specific value proposition than the generic “we build modern data platforms” pitch you will hear from half this market.
### What you need to pin down
Press hard on how much of the delivery model depends on Encora's proprietary tooling. Accelerators can improve speed. They can also create handoff problems if your internal team cannot inspect the rules, modify workflows, or take over operations cleanly after launch.
You should ask for a stack-specific walkthrough. Snowflake with dbt and Fivetran is one delivery pattern. Databricks on Azure with custom orchestration is another. Encora needs to show where its automation fits, what stays custom, and who owns governance decisions once the platform is in production.
Also test for senior architecture depth, not just bench size. Encora is easier to justify when the work includes repeatable migration and metadata-heavy implementation. It is less compelling if you mainly need a small group of senior specialists to co-design platform standards with your internal staff.
**Recommended when**
- **Multi-domain migration programs:** Several teams are moving at once, and mapping, lineage, and coordination work are slowing delivery.
- **Metadata and governance-heavy environments:** Your program depends on clear source-to-target logic, trust controls, and auditability.
- **Large execution-focused engagements:** You want a scaled nearshore team with cloud credibility and delivery accelerators, not a small advisory-led boutique.
## 4. Globant
[Globant](https://www.globant.com) belongs on a vetted shortlist for one reason: it is built for enterprise complexity. In our review of 86 firms, very few combine nearshore scale, executive-facing governance, and visible Databricks credibility at this level. If your data program spans business units, countries, and multiple platform teams, Globant is one of the safer choices.
That does not make it the default choice.
### Why technical leaders pick Globant
Globant fits programs where delivery risk comes from coordination, not raw implementation effort. You are dealing with architecture boards, security reviews, regional rollout constraints, and dependencies across data engineering, analytics, and AI teams. A smaller specialist can write pipelines. Globant is better suited to running the operating model around them.
Its Databricks recognition matters because it signals more than tool familiarity. It suggests repeatable enterprise delivery, partner alignment, and the ability to support lakehouse programs that need platform standards, migration planning, and executive oversight. For engineering leaders, that is the primary differentiator.
Globant's Data & Analytics Studio strengthens that position. It gives buyers a clearer path when the engagement needs more than staff augmentation and starts to look like a managed transformation program.
### Where Globant is a poor fit
Do not hire Globant for a tightly scoped build if speed and unit cost matter most.
If you need a small senior pod to tune dbt models, rebuild orchestration, or execute a contained Snowflake migration, Globant is usually heavier than necessary. You will pay for process, reporting layers, and governance structures that make sense in a large enterprise program and feel excessive in a focused engineering sprint.
This is the main trade-off. Globant reduces coordination risk in complex environments. It can also slow teams that want direct access to senior builders and fast decision cycles.
### What to verify before you sign
Ask how much of the delivery team will be hands-on data engineers versus program management and oversight. Large firms often look strong in the pitch and then load the account with coordination roles.
Push for a platform-specific delivery view. Databricks-led modernization, Snowflake-centric warehousing, and hybrid cloud data estates require different patterns for modeling, orchestration, governance, and cost control. Globant should show the exact team shape, review cadence, and ownership model it would use in your environment.
Also test for decision speed. Enterprise governance helps when your organization already runs with formal approvals and cross-functional controls. It becomes drag when your internal team wants weekly architecture decisions and fast iteration.
**Best fit**
- **Enterprise Databricks programs:** You need a nearshore partner with visible platform credibility and the structure to support a lakehouse rollout.
- **Multi-workstream transformations:** Several teams, regions, or stakeholder groups need one delivery partner with formal governance.
- **Programs with executive scrutiny:** Leadership expects reporting, risk controls, architecture checkpoints, and predictable escalation paths.
## 5. BairesDev
[BairesDev](https://www.bairesdev.com) makes this shortlist for one reason. Capacity.
Across our review of 86 nearshore firms, very few can staff data engineers fast while also covering adjacent needs like backend services, cloud setup, QA, and application changes. BairesDev can. That matters when your data roadmap is tied to a broader modernization program instead of a standalone warehouse rebuild.
That same breadth creates the selection risk. BairesDev is not the partner to hire on brand alone. It is the partner to hire with a tightly defined operating model, named technical leads, and explicit ownership boundaries.
### Why leaders choose BairesDev
Choose BairesDev when speed and coverage matter more than a highly opinionated platform play. If your team needs to stand up multiple pods across ingestion, transformation, BI support, and integration work, a large provider can reduce handoffs and procurement drag.
It also fits programs where data engineering sits inside a bigger delivery scope. A migration that includes API changes, application refactoring, test automation, and cloud infrastructure usually benefits from one partner that can staff across those lanes.
This is BairesDev's strongest differentiator in our analysis. Scale is the product.
### The trade-off
BairesDev's public positioning is broad, so technical buyers need to force precision early. Ask for the exact delivery shape by platform. Snowflake and Databricks work should not be presented as interchangeable staffing requests. The team should spell out who owns data modeling, orchestration, CI/CD, observability, cost controls, and production support.
Also push on seniority mix. Large firms can ramp fast, but fast ramp is not the same as strong architecture. If your internal team has already set platform standards, review cadences, and governance rules, BairesDev becomes much easier to use well. If you need the partner to define those standards from scratch, there are stronger options on this list.
**Use BairesDev when**
- **You need rapid team ramp:** Several workstreams need staffed pods quickly, with data work tied to broader engineering execution.
- **Your program goes beyond data engineering:** Platform work sits alongside app modernization, integrations, QA, or cloud migration.
- **You have strong internal technical leadership:** Your architects can set standards, review output, and keep a broad engagement technically disciplined.
## 6. Endava
[Endava](https://www.endava.com) is the firm to shortlist when delivery control matters as much as platform build speed. In our review of 86 nearshore providers, Endava stood out less for raw staffing scale and more for operating discipline: defined delivery methods, clearer reporting lines, and a better fit for programs that face architecture review, security gates, and formal release management.
That makes Endava a strong choice for regulated data work and large internal environments where undocumented decisions create expensive rework.
### Why Endava earns a spot
Dava.Flow is the differentiator. Technical leaders should care because a named delivery framework usually signals repeatability across discovery, build, governance, and handoff. That matters when the engagement includes lineage expectations, approval workflows, production support, or audit evidence. Endava is more credible here than firms that sell data engineering as generic pod-based augmentation.
It also fits organizations where data engineering has to work inside broader enterprise constraints. If your Snowflake or Databricks roadmap depends on security sign-off, architecture board approval, and coordinated releases across other systems, Endava is easier to use than a looser nearshore partner.
The trade-off is speed.
### Where it's less attractive
Endava can feel process-heavy for teams that already have strong internal standards and only need experienced engineers to execute backlog work. More structure helps in controlled environments, but it slows early mobilization and usually raises the minimum engagement size.
Platform depth also needs verification at the delivery-team level, not the brand level. Ask for the actual senior profiles proposed for Snowflake, Databricks, dbt, Airflow, and your cloud stack. Do not accept a general data modernization pitch if your program depends on one platform-specific architecture path.
> Ask Endava to show how it documents decisions, handles change control, measures delivery health, and transfers operational knowledge after go-live.
**Best fit**
- **Regulated data programs:** Healthcare, financial services, and other environments with audit, approval, and control requirements.
- **Enterprise delivery models:** Data engineering must align with architecture governance, security review, and formal release processes.
- **Build-to-operate transitions:** You need stable handoff, production telemetry, and a partner that can support run-state discipline.
## 7. Unosquare
[Unosquare](https://www.unosquare.com) is the best fit for leaders who want nearshore data engineering teams that behave like an extension of the in-house org. It doesn't carry the same brand weight as the largest global providers, but its integration model is attractive for teams that care about continuity, standards, and day-to-day collaboration.
That matters because one of the biggest blind spots in nearshore buying is retention. Demand for experienced data engineering practitioners consistently outpaces supply, and churn risk compounds quickly on long platform programs.
### Why Unosquare deserves attention
The company's Data & Analytics Center of Excellence is the signal to focus on. Centers of Excellence aren't automatically useful, but they matter when they support standards, upskilling, and consistency across squads. For buyers worried about delivery drift across pipeline design, governance practices, and cloud implementation patterns, that's more valuable than a flashy transformation narrative.
Unosquare also looks stronger for regulated sectors than many generic staff-augmentation firms. If your program touches healthcare or financial services, the ability to align with audit and data sovereignty expectations matters.
### The trade-off
The obvious concern is scale ceiling. For very large, multi-year transformations with dozens of parallel streams, you need to verify bench depth and leadership bandwidth. A good integration model doesn't guarantee massive program capacity.
Still, this is one of the better picks when you want a partner your internal team can absorb quickly without fighting a heavyweight delivery machine.
**Best fit**
- **Extension-team model:** Your leads want nearshore engineers embedded tightly with US-based product and data teams.
- **Standards-driven programs:** You care about reusable patterns, internal enablement, and long-term quality.
- **Retention-sensitive work:** Your platform roadmap spans many months, and continuity is a board-level concern.
## Top 7 Nearshore Data Engineering Companies Comparison
| Provider | Implementation complexity | Resource requirements | Expected outcomes | Ideal use cases | Key advantages |
|---|---:|---|---|---|---|
| Wizeline | Medium, end-to-end data + MLOps with AI-assisted delivery | Moderate nearshore teams across Mexico/Colombia; Snowflake/cloud expertise | Production-ready cloud data foundations and productized AI use cases | Stand up data platforms and MLOps; Snowflake-led projects | AI.R+ delivery methodology; Snowflake partnership; US-aligned nearshore hubs |
| Gorilla Logic | Medium, engineering and platform build focus | Moderate teams in Costa Rica/Colombia/Mexico with Databricks/Snowflake skills | Lakehouse and real-time analytics platforms | Real-time analytics, streaming, Databricks or Snowflake implementations | Clear modern tooling patterns; English-fluent nearshore teams |
| Encora | Medium, AI-driven accelerators to speed delivery | Scalable LATAM footprint (multiple nearshore centers); cloud partner credentials | Faster delivery with improved data quality, mapping, and metadata automation | Multi-domain modernization programs needing automation and scale | Data Agents ecosystem for automation; recognized Data & AI services |
| Globant | High, enterprise-scale, multi-country transformations | Large squads and multi-country delivery capacity | Complex, enterprise-grade data & AI transformations at scale | Large enterprises requiring broad program delivery and lakehouse expertise | Databricks partner recognition; ability to field large, cross-country teams |
| BairesDev | Medium, broad data + adjacent engineering services | Large talent bench for rapid team ramp across Azure/AWS stacks | Modernized data stack plus accelerated staffing for multi-workstream programs | Rapid staffing needs and programs combining data, apps, and cloud modernization | Fast team scaling; breadth across app dev, cloud, QA and data |
| Endava | High, governance- and telemetry-focused delivery | Enterprise delivery centers in LATAM; governance tooling and processes | Traceable, measurable outcomes with strong governance and controls | Regulated or complex programs needing auditability and governance | Dava.Flow methodology emphasizing traceability, governance, measurable value |
| Unosquare | Medium, managed squads integrated with US teams | Managed nearshore squads; Data & Analytics Center of Excellence | Integrated pipelines and compliant data solutions with team upskilling | Regulated industries and teams needing close integration with US product groups | Strong integration model; CoE for standards and upskilling |
## Your Next Step From Shortlist to Selection
Selection discipline matters more than shortlist quality. In our review of 86 nearshore firms, the biggest predictor of a bad outcome was not weak engineering talent. It was a weak buying process. Teams skipped clear decisions on architectural ownership, delivery accountability, staffing continuity, and post-launch support.
Treat this shortlist as a decision framework, not a directory.
Start with the shape of the work. A Snowflake modernization with dbt, governance, and BI handoff needs a different partner than a Databricks-heavy platform build, a regulated migration program, or a fast staff augmentation request tied to adjacent app and cloud work. Engineering leaders should force that distinction early because the wrong engagement model creates avoidable drag. A large transformation partner can overcomplicate a contained rebuild. A flexible staffing vendor can leave major gaps in architecture leadership and operational ownership.
That is why the firms on this list differ in ways that matter. Wizeline is a strong fit for warehouse modernization and AI-ready platform work. Gorilla Logic fits teams that want close day-to-day collaboration across modern cloud data stacks. Encora stands out when metadata, migration coordination, and quality automation are central to the brief. Globant and Endava make the most sense for enterprise programs with formal governance, cross-functional scope, and heavier delivery controls. BairesDev is easier to justify when speed of staffing and broader engineering coverage matter. Unosquare fits buyers who want integrated squads that behave like an extension of a US-based product and data team.
Run a structured evaluation. Ask every finalist the same questions and score the answers with evidence, not chemistry.
- **Architecture ownership:** Who makes the final call on platform design, data modeling, orchestration, security boundaries, and cost controls?
- **Platform depth:** What senior talent will work on Snowflake, Databricks, dbt, Airflow, Spark, cloud infrastructure, and observability?
- **Delivery model:** Is the partner selling managed outcomes, staff augmentation, or a hybrid? Where does accountability start and stop?
- **Team stability:** What is the expected rotation risk? How do they handle backfills, knowledge loss, and shadowing for key roles?
- **Operational handoff:** Who owns runbooks, incident response, SLAs, and stabilization after go-live?
- **Knowledge transfer:** What documentation is produced, who reviews it, and when does handoff begin?
Capacity will tighten as demand for nearshore engineering continues to rise, as noted earlier. Good firms get booked first. If your roadmap depends on a partner, start founder interviews, technical screening, and commercial review before the budget is fully approved.
Use the free RFP Checklist from DataEngineeringCompanies.com, with its 40 weighted evaluation criteria, to keep vendor calls consistent and expose gaps quickly. Then use the site's Data Engineering Cost Calculator to benchmark proposals against market norms instead of accepting packaging and rate-card spin.
One more rule. Nearshore proximity does not compensate for weak data engineering judgment. Your partner should be able to explain warehouse design trade-offs, batch versus streaming choices, dbt project structure, orchestration patterns, infrastructure as code, testing strategy, lineage, and observability without vague sales language. If they cannot do that in the first technical call, remove them from the process.
For a practical hiring lens on evaluating technical capability, this [guide on assessing technical depth without being technical](https://talantrix.com/resources/books/how-to-assess-technical-depth-without-being-technical/) is worth sharing with procurement and non-technical stakeholders.
---
DataEngineeringCompanies.com is an independent resource for evaluating data engineering consultancies. Its profiles and tools are built to reduce selection risk, improve cost transparency, and help teams choose the right partner for platform modernization, governance, and AI-ready data infrastructure.
---
## Parquet vs Avro: A Technical Guide to Big Data Formats
Source: https://dataengineeringcompanies.com/insights/parquet-vs-avro/
Published: 2026-02-18T10:28:31.253175+00:00
Description: Choosing between Parquet vs Avro? This guide provides a deep, practical comparison of performance, schema evolution, and use cases for data engineering.
Parquet is a **columnar storage format** built for fast analytical reads. Avro is a **row-based format** built for fast writes and flexible schema evolution. Choose Parquet for read-heavy analytics (data warehouses, lakehouses, BI dashboards); choose Avro for write-heavy ingestion (event streams, Kafka topics, schemas that change often).
## Parquet vs Avro Key Differentiators
| Criterion | Apache Parquet | Apache Avro |
| :--- | :--- | :--- |
| **Storage Layout** | Columnar (column-oriented) | Row-based (row-oriented) |
| **Primary Use Case** | Analytical queries, BI, data warehousing | Data serialization, event streaming (Kafka) |
| **Query Performance** | **Excellent** for analytical queries (reads a subset of columns) | **Fair**; slower for analytics as it must read entire rows |
| **Write Performance** | Slower due to columnar organization and sorting | **Excellent** due to simple append-only writes |
| **Compression** | Superior; groups similar data types for high compression ratios | Good; compresses entire rows, less effective than columnar |
| **Schema Evolution** | Supported but more rigid (schema is in the file footer) | Highly flexible; schema is part of the file, enabling easy evolution |
> **Technical Recommendation:** Use **Parquet** for analytical data stores like a data warehouse or data lakehouse, where query performance is the primary concern. Use **Avro** for the data ingestion layer, particularly in streaming architectures where write throughput and schema flexibility are critical.
Parquet's columnar layout lets query engines like [Apache Spark](https://spark.apache.org/), [Snowflake](https://www.snowflake.com/), and [Databricks](https://www.databricks.com/) read only the columns a query touches, skipping the rest. Avro's row-based layout serializes a whole record at once, which is efficient for capturing event streams from sources like [Apache Kafka](https://kafka.apache.org/) and keeps the schema tightly coupled to the data, so schema changes don't break existing consumers. The rest of this guide walks through why each design produces those tradeoffs, with benchmark numbers and a decision matrix at the end.
## How does storage architecture affect performance?
The physical layout on disk is the single difference that drives everything else: query speed, write speed, compression, and schema flexibility. Parquet groups values by column; Avro groups values by row. Everything downstream follows from that choice.
### How does Parquet's columnar layout work?
Parquet groups all the values from a single column together instead of writing out full rows. For a customer table, all `customer_id` values sit in one block, all `email_address` values in another, and so on.
This layout suits analytical (OLAP) queries. When an engine runs `SELECT AVG(order_value) FROM sales`, it reads the `order_value` column directly and skips the bytes on disk holding `customer_id`, `product_name`, and every other unused column - cutting I/O sharply.
This is called **projection pushdown**, and it's why Parquet is the default format for data warehouses and lakehouse platforms. **Of the 86 firms profiled in the Data Engineering Companies Index, 66 list Snowflake and 64 list Databricks - the lakehouse platforms where columnar formats like Parquet are the default.** Our guide on [Databricks Delta Lake](/insights/databricks-delta-lake/) explains how that platform builds on Parquet's strengths.
Consider this simple customer dataset:
**Customer Data Example**
| Customer ID | Email | City |
| :--- | :--- | :--- |
| 101 | test1@email.com | New York |
| 102 | test2@email.com | London |
| 103 | test3@email.com | Tokyo |
Parquet stores this data with each column's values grouped together:
* **Customer ID Block:** `[101, 102, 103]`
* **Email Block:** `["test1@email.com", "test2@email.com", "test3@email.com"]`
* **City Block:** `["New York", "London", "Tokyo"]`
### How does Avro's row-based layout work?
Avro serializes and stores an entire record - all its fields - as one continuous block of data. Using the same customer example, Avro writes each complete row in sequence.
This suits write-heavy systems that process whole records at once, such as event streaming with [Apache Kafka](https://kafka.apache.org/), where producers continuously emit new, complete events. Avro just appends the next serialized record to the file - a low-overhead operation.
For Avro, the physical layout looks like:
* `[101, "test1@email.com", "New York"]`
* `[102, "test2@email.com", "London"]`
* `[103, "test3@email.com", "Tokyo"]`
That structure makes writes fast but creates a bottleneck for analytics. To calculate the average `order_value` from an Avro file, a query engine has to read and deserialize every row - including columns it doesn't need - just to reach the one field it wants. That's why Avro runs substantially slower than Parquet on most analytical workloads.
## How much faster is Parquet than Avro for queries?
Independent Athena benchmarks show Parquet queries running roughly 2-6x faster than the same queries against Avro, with the largest gaps on selective queries that touch only a handful of columns out of many. The mechanism is projection and predicate pushdown, both unavailable to a row-based format.
Query engines like [Spark](https://spark.apache.org/), [Snowflake](https://www.snowflake.com/en/), and [Databricks](https://www.databricks.com/) are built to exploit this gap.
### What is projection pushdown?
Projection pushdown is the mechanism behind Parquet's query speed: because data is stored in columns, the engine reads only the columns a query needs. For a table with **200** columns where an analysis needs three, the engine reads just those three from disk and ignores the other 197.
An Avro-based query, by contrast, forces the engine to process every byte of every row to extract the same three columns. Reading less data means faster, cheaper queries. Our comparison of [Snowflake vs Databricks](/snowflake-vs-databricks/) covers how those platforms are built around columnar formats.
### What is predicate pushdown?
Predicate pushdown is how Parquet skips rows that can't match a filter. Parquet files are organized into blocks called **row groups**, and each row group stores metadata - including the min/max values for each column in that block.
When a query includes a filter like `WHERE order_date > '2025-11-01'`, the engine checks that metadata first. If a row group's date range doesn't overlap the filter, the engine skips the whole block without reading it.
> **Key Insight:** Projection pushdown narrows the *columns* read; predicate pushdown narrows the *rows* read. Avro, being row-based, supports neither.
### What do real benchmarks show?
In an independent Athena benchmark run by Chariot Solutions on a dataset of roughly 60 million clickstream events, Avro took 7.46 seconds to run a query while scanning 7.51 GB of data; Parquet completed the same query in 3.86 seconds while scanning 5.39 GB.[^1] Other queries in the same test showed even wider gaps - Parquet finished one query in 0.85 seconds against Avro's 4.81 seconds.
This kind of performance difference shows up directly in cloud bills, since most platforms charge for compute time or data scanned:
* **Lower compute costs:** shorter query execution times reduce virtual warehouse or cluster bills.
* **Reduced I/O charges:** fewer read operations from cloud storage like [Amazon S3](https://aws.amazon.com/s3/) or [Google Cloud Storage](https://cloud.google.com/storage) mean lower API costs.
* **Faster time-to-insight:** analysts and data scientists get results sooner.
## Does Parquet compress better than Avro?
Yes. Parquet's columnar layout almost always produces a smaller file than the same data stored in Avro, because compression algorithms work better against long runs of similar values than against mixed-type rows.
### How columnar layout maximizes compression
Compression algorithms like **Snappy** and **Gzip** shrink files by finding repeating patterns and replacing them with small references. The more uniform the data, the more patterns they find, and the higher the compression ratio.
Parquet's columnar layout groups all values from one column together - every `user_country` value, every `event_timestamp` - creating long, homogenous blocks that compress well.
Avro's row-based structure stores each record as a mix of data types: an integer ID, a string email, a timestamp, maybe a boolean flag. That heterogeneity within each row makes it harder for compression algorithms to find repeating patterns, so Avro files end up larger.
### How much storage does Parquet save in practice?
In the same Chariot Solutions benchmark, a dataset of 59.7 million events took 4.2 GB as Parquet versus 6.7 GB as Avro - a 37% reduction. A second run with 18.5 million events showed 1.3 GB for Parquet versus 2.1 GB for Avro, a 38% reduction.[^1] Smaller files also mean less data moved over the network and less data for a query engine to read off disk, compounding the query-speed advantage above.
### What does a compression difference like this mean in dollars?
A 35-40% storage reduction adds up at petabyte scale. Here's an illustrative scenario, not a specific vendor quote:
**Scenario: A 1 Petabyte (PB) Data Lake**
Assumptions:
* **Total Data Size:** 1 PB (1,000 TB)
* **Cloud Storage Cost:** $23 per TB/month (illustrative - check current pricing with your cloud provider)
* **Parquet Storage Savings:** a conservative 35% advantage over Avro, in line with the benchmark above
| Format | Storage Required | Monthly Cost | Annual Cost |
| :--- | :--- | :--- | :--- |
| **Avro** | 1,000 TB | $23,000 | $276,000 |
| **Parquet** | 650 TB | $14,950 | $179,400 |
| **Annual Savings** | | | **$96,600** |
At this illustrative rate, switching to Parquet saves close to $100,000 a year per petabyte managed, and the savings scale with data volume. Understanding the difference between a [data warehouse and a data lake](/insights/data-warehouse-vs-data-lake/) matters here too, since where you store the data affects both cost and performance.
## When does Avro outperform Parquet?
Avro wins on write throughput and schema flexibility - the two things that matter most for capturing data as it's generated, like real-time event streaming. For systems where the primary job is ingestion, not analysis, Avro is usually the better default.
### Why is Avro faster for writes?
Avro's row-based layout serializes an entire record and appends it to the end of the file - a simple, low-overhead operation that maximizes throughput.
Parquet has to do more work to write: it buffers incoming records, sorts them by column, and writes them into organized row groups. That buffering and sorting consumes CPU and memory and adds latency that can bottleneck real-time ingestion.
> **The Bottom Line:** Avro writes are simple appends. Parquet writes require buffering and sorting to build columnar blocks. That's the core tradeoff for any write-heavy workload.
This is why Avro is the standard serialization format for [Apache Kafka](https://kafka.apache.org/): capturing every message with minimal delay matters most in event-driven architectures, and Avro's write efficiency matches Kafka's throughput requirements.
### How does Avro handle schema evolution?
Avro embeds the writer's schema with the data, so a consumer can use its own ("reader's") schema to interpret it, keeping different versions compatible. That system supports three compatibility modes:
* **Backward Compatibility:** data written with a new schema can still be read by an older schema, as long as new fields have default values.
* **Forward Compatibility:** data written with an old schema can be read by a newer schema, since the new reader can ignore fields that no longer exist.
* **Full Compatibility:** both directions work, so producers and consumers on different versions can exchange data without coordination.
This flexibility keeps pipelines from breaking when a microservice adds a new field to an event. Parquet supports schema evolution too, but less flexibly - its schema lives in the file footer, and changes like reordering columns or altering nested types are harder to manage. For systems handling continuous streams from Kafka pipelines, event logs, or sensor data, that's a meaningful operational difference. [Confluent's writeup on Avro and Kafka](https://www.confluent.io/blog/avro-kafka-data/) goes deeper on how the schema registry fits in.
## Which format fits your use case?
The decision comes down to one question: is the pipeline's primary job reading data or writing it? Getting this wrong shows up as either slow, expensive queries (wrong choice: Avro for analytics) or ingestion bottlenecks and brittle pipelines (wrong choice: Parquet for streaming writes).
This video breaks down the core tradeoffs in practical terms.
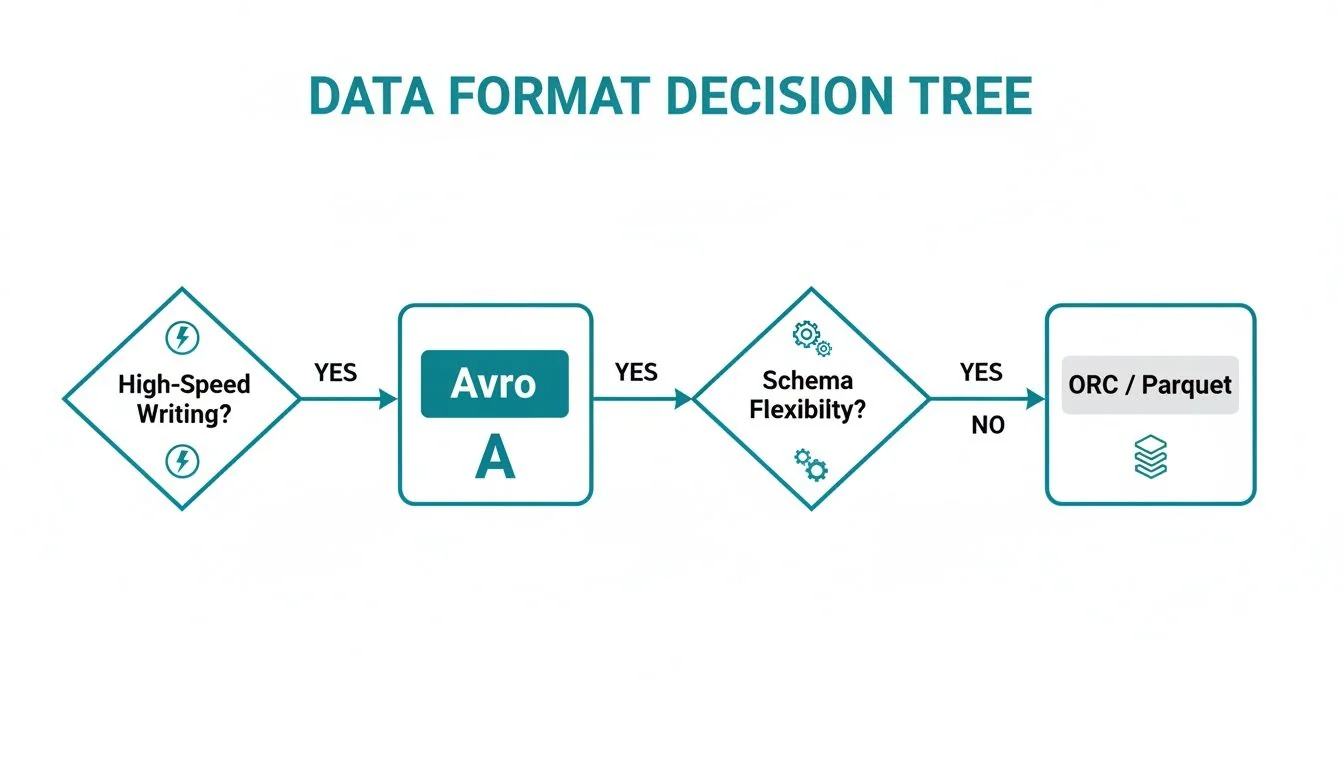
### When should you use Parquet?
For analytical queries, BI, or ad-hoc data exploration, Parquet is the clear choice. Its columnar layout matches the read-heavy patterns of platforms like [Snowflake](https://www.snowflake.com/en/) and [Databricks](https://www.databricks.com/).
Use Parquet when:
* **Powering BI dashboards:** tools like Tableau or Power BI benefit from fast column scanning and stay responsive.
* **Running ad-hoc analytical queries:** analysts and data scientists get shorter query times.
* **Building a data lakehouse:** high compression and efficient column access keep both storage and compute costs down.
### When should you use Avro?
For real-time data capture and pipeline resilience, Avro is the standard choice. Its row-based structure is built for fast writes and flexible schema management.
Choose Avro for:
* **Real-time event streaming with Kafka:** Avro is the default serialization format for [Apache Kafka](https://kafka.apache.org/) messages, thanks to low write latency and schema registry support.
* **A raw data landing zone:** schema evolution lets ingestion pipelines absorb changes from diverse sources without failing.
* **Inter-service communication:** in a microservices architecture, Avro gives producers and consumers a data contract they can evolve independently.
### Decision Matrix For Data Formats
| Use Case | Recommended Format | Key Rationale |
| :--- | :--- | :--- |
| **BI & Interactive Analytics** | Parquet | Columnar reads are extremely fast for the selective queries that power dashboards. |
| **Real-Time Event Ingestion** | Avro | Optimized for high-throughput writes and flexible schema evolution, ideal for Kafka streams. |
| **Data Science & ML Features** | Parquet | Efficiently reads only the specific columns (features) required for model training and inference. |
| **Raw Data Lake Staging Zone** | Avro | Handles evolving schemas from diverse sources without breaking ingestion pipelines. |
| **Archival & Cold Storage** | Parquet | Achieves the highest compression ratios, significantly reducing long-term storage costs. |
| **ETL/ELT Intermediate Steps** | Avro or Parquet | Depends on the step. Avro is better for row-level transformations; Parquet excels at aggregations. |
### Can you use both Parquet and Avro together?
Yes - most production pipelines do. A common multi-stage architecture uses Avro at the ingestion edge, where write speed and schema flexibility matter most, and converts to Parquet before analytics, where read speed matters most.
> **Key Insight:** A single format is rarely enough for an end-to-end pipeline. Using each format where its strengths apply is standard practice, not a compromise.
That architecture typically looks like:
1. **Ingestion (Avro):** raw event data lands from Kafka into a staging area of the data lake as Avro files, prioritizing write speed and schema flexibility at the entry point.
2. **Transformation and storage (Parquet):** a batch or micro-batch job, often using [Apache Spark](https://spark.apache.org/), reads the raw Avro data, cleans and transforms it, and rewrites it into a partitioned Parquet structure.
3. **Analytics (Parquet):** downstream consumers - queries, BI tools, ML models - read the optimized Parquet data and get fast, high-performance columnar reads.
This Avro-to-Parquet pipeline gets the benefit of both formats: resilient, high-throughput ingestion and fast, cost-effective analytics.
## Frequently Asked Questions
### Can I use Parquet with Kafka?
It's technically possible but an anti-pattern. [Kafka](https://kafka.apache.org/) is built for streaming a high volume of events with minimal delay, and Avro's simple, row-by-row serialization matches that job better than Parquet, which needs to buffer and sort data before writing.
Writing Parquet directly from a Kafka stream adds latency that undermines the point of using Kafka.
> **The Field-Tested Approach:** Use Avro for Kafka topics - it's fast for writes and integrates well with schema registries. Land raw Avro events in a staging zone (S3 or ADLS), then use a batch or micro-batch job to convert to Parquet for analytics.
### Which format do Databricks and Snowflake prefer?
Both [Databricks](https://www.databricks.com/) and [Snowflake](https://www.snowflake.com/) are built around **Parquet**. Their query engines are designed to exploit its columnar structure for predicate pushdown (reading only necessary rows) and projection pushdown (reading only necessary columns).
If they had to process Avro instead, their engines would need to read every row start to finish, degrading performance and raising compute costs. For analytics in any modern lakehouse or data warehouse, Parquet is the native format.
### How different is schema evolution in practice?
Substantial, and it directly affects pipeline resilience. Avro embeds the writer's schema with the data, so downstream consumers can handle new, missing, or renamed fields without failing - useful when ingesting raw data from multiple, uncontrolled sources.
Parquet's schema evolution is stricter: it handles new columns fine, but more complex changes are harder to manage. That makes Parquet better suited to final, curated datasets that have already been cleaned and structured for analysis - flexibility for ingestion, structure for analytics.
---
Format choice is one piece of a larger pipeline design. See how a [data warehouse compares to a data lake](/insights/data-warehouse-vs-data-lake/) for where processed Parquet data typically lands, check our [ETL tools comparison](/insights/etl-tools-comparison/) for the ingestion tools that write Avro into a landing zone, and read the [modern data stack overview](/insights/modern-data-stack/) for how both formats fit into a full pipeline.
[^1]: Keith Gregory, "Athena Performance Comparison: Avro, JSON, and Parquet," Chariot Solutions, 2023. https://chariotsolutions.com/blog/post/athena-performance-comparison/
---
## RAG vs LLM: The Data Engineering Decision Framework
Source: https://dataengineeringcompanies.com/insights/rag-vs-llm/
Published: 2026-07-23T10:29:04.616452+00:00
Description: RAG vs LLM: A guide for data engineering leaders. Compare architectures, costs, and platform integrations (Snowflake/Databricks) to choose the right AI pattern.
What's the fundamental question a CTO should ask before greenlighting **RAG vs LLM** for an enterprise build, do you want a model that knows things, or a data system that can prove them?
Treat this as an architecture decision, not a model preference. A **native long-context LLM** is a single inference endpoint, while **RAG** is a pipeline that adds ingestion, indexing, retrieval, and grounding around an LLM, which is why AWS frames RAG as connecting an LLM to external sources at query time before generating an answer ([AWS RAG overview](https://aws.amazon.com/what-is/retrieval-augmented-generation/)). IBM's framing is even more useful for architects, because it makes clear that RAG changed enterprise AI from model-centric to systems-centric, where **retrieval infrastructure**, **document indexing**, and **vector search** matter as much as model weights ([IBM on RAG](https://research.ibm.com/blog/retrieval-augmented-generation-RAG)).
| Criterion | Retrieval-Augmented Generation, RAG | Native Long-Context LLM |
|---|---|---|
| Data freshness | Strong, because the system retrieves current documents at query time | Weak unless the source material is already inside the prompt |
| Architecture | Multi-stage pipeline with ingestion, chunking, retrieval, and generation | Single computational endpoint |
| Governance | Better source grounding, but more corpus and retrieval risk | Simpler stack, but less direct traceability |
| Implementation effort | Higher, because it adds orchestration and retrieval layers | Lower, because it reduces pipeline components |
| Best fit | Dynamic, distributed, private enterprise knowledge | Whole-document reasoning and coherent synthesis |
If you need a practical way to think about stack choice, the logic in [tips for selecting a tech stack](https://getnerdify.com/blog/how-to-choose-technology-stack/) maps cleanly to this decision. Start with the business requirement, then choose the least complex architecture that still satisfies freshness, governance, and latency.
## Choosing Your AI Pattern A Strategic Engineering Decision
What should you greenlight for the new enterprise build, a retrieval pipeline around an LLM, or a long-context model with a thinner stack?
Choose the architecture from the data problem first. A **native LLM** keeps the system simpler, with fewer moving parts to build, monitor, and govern. **RAG** adds ingestion, chunking, retrieval, indexing, and grounding, which raises operational cost but gives you control over what the model can see.
AWS describes **RAG** as a pipeline that retrieves relevant context at query time and passes that context into the model, so the actual spend is not just model selection, it is document processing, vector search, permissioning, evaluation, and observability ([AWS RAG overview](https://aws.amazon.com/what-is/retrieval-augmented-generation/)). That is the part enterprise teams underestimate. They budget for the model and then inherit a data engineering program.
> **Practical rule:** if your use case depends on current facts from private systems, build the data pipeline first and choose the model second.
The fundamental decision is not which model is smarter. It is which architecture your team can operate without creating a maintenance burden. IBM's framing of **RAG** as a hybrid operating model is the right one for architects, because retrieval handles freshness and source grounding while the model handles reasoning and generation ([IBM on RAG](https://research.ibm.com/blog/retrieval-augmented-generation-RAG)).
If you are choosing a platform, be direct about the tradeoff. **Snowflake** is a better fit when your knowledge is already organized in governed tables and documents and you want to keep retrieval close to the warehouse. **Databricks** is a stronger fit when you need heavier ingestion, embedding pipelines, and more control over the data engineering layer. For any team making that call, the logic in [tips for selecting a tech stack](https://getnerdify.com/blog/how-to-choose-technology-stack/) applies cleanly. Start with the business requirement, then choose the least complex architecture that still meets freshness, governance, and latency.
## Architectural Deep Dive Pipeline vs Model
A native long-context LLM is the simpler architecture to operate. You send in a large, structured prompt, and the model reasons over that content in memory. For an enterprise data team, that smaller failure surface matters. There is no retrieval layer to tune, no chunking logic to debug, and no vector index to keep in shape.
### What RAG adds to the stack
RAG turns the problem into a data engineering pipeline. You ingest documents, split them into chunks, create embeddings, store them in a vector index, retrieve the closest matches, and pass those results into the model. Each step forces an architectural choice, from chunk size to metadata design to ranking quality.
That added machinery is the tradeoff. RAG gives you control over what the model sees, which is why it fits enterprises with large, changing corpora and strict source requirements. It also creates more failure modes, because weak retrieval can surface the wrong passage even when the model itself is performing well.
The operating cost is real. Every extra layer adds work for ingestion, permissions, evaluation, and observability, and those are the parts enterprise teams end up maintaining long after the demo is over. If you are building a governed knowledge base, the [AI powered knowledge base guide](https://gitdoc.ai/resources/ai-powered-knowledge-base) is a useful reference point for the operational shape of that work.
### Why this changed enterprise AI architecture
The architectural shift is not about the model getting smarter, it is about the system around it becoming the product. Once retrieval enters the design, the success metric moves from prompt quality to pipeline quality. Document normalization, lineage, vector quality, and access control start to dominate the implementation.
> The LLM is the response layer. The retrieval system is the trust layer.
For CTOs, that changes the platform decision. **Snowflake** works better when your knowledge already sits in governed tables and documents, and you want retrieval close to the warehouse. **Databricks** is the stronger choice when you need heavier ingestion, more custom embedding workflows, and tighter control over the data engineering layer. If your team already has disciplined data ops, RAG fits naturally. If your team wants fewer moving parts and lower operational burden, native long-context access is cleaner.
For teams making platform calls, [informing your cloud data strategy](https://dataengineeringcompanies.com/snowflake-vs-databricks/) is a practical lens because the stack you choose determines how much of the pipeline you own, how much governance you inherit, and how much ongoing maintenance the AI system will demand.
## Core Tradeoffs A Head to Head Comparison
Ask the wrong question and you'll pick the wrong architecture. The useful question is which system fits your data shape, governance load, and operating cost. RAG and long-context LLMs solve different enterprise problems, and the tradeoff is architectural, not philosophical. A 2025 evaluation found that long-context models answered **56.3%** of questions correctly versus **49.0%** for RAG, while long-context models solved more than **2,000** questions that RAG missed and RAG uniquely answered almost **1,300** questions. That is a real split in capability, not a minor tuning difference.
### The comparison that matters
| Criterion | Retrieval-Augmented Generation, RAG | Native Long-Context LLM |
|---|---|---|
| Accuracy on self-contained sources | Often weaker when the whole source fits in context | Stronger in the long-context setting, based on comparative evaluations |
| Accuracy on fragmented knowledge | Stronger when information is spread across many documents | Weaker if the evidence is distributed |
| Freshness | Strong, because updates happen in the corpus | Weak unless refreshed outside the model |
| Latency | Higher because retrieval adds steps | Lower because there's no retrieval layer |
| Operational burden | Higher, due to indexing, chunking, permissions, and evaluation | Lower, because the system is simpler |
| Governance | Better source traceability, but more corpus risk | Less retrieval risk, but less built-in evidence plumbing |
| Best use case | Policy, support, knowledge bases, current enterprise facts | Whole-document synthesis, summarization, coherent reasoning |
The core issue is not model intelligence. It is system fit. Long-context wins when the evidence already lives in one place and the task is to synthesize it cleanly. RAG wins when knowledge is scattered, changes often, or sits across systems that cannot be flattened into one prompt. The EMNLP paper and the 2025 evaluation point in the same direction, the better choice depends on how much retrieval work your team can carry, not on marketing claims ([EMNLP paper](https://aclanthology.org/2024.emnlp-industry.66.pdf)).
For a CTO, the operational cost matters as much as the answer quality. RAG adds chunking rules, embedding refreshes, access controls, retrieval evaluation, and index maintenance. That is a real data engineering program, and it gets more expensive as the corpus grows or the permission model gets stricter. Long-context LLMs cut most of that work out, which is why they are easier to run when the source material is already packaged for a single document or a bounded workspace.
Governance is the other dividing line. RAG gives you better source traceability, but it also creates more moving parts that can drift. Long-context systems reduce retrieval complexity, but they do not solve evidence management for you. If your team needs a build-versus-buy decision on the model layer itself, [exploring custom LLM options](https://magnitudemarketing.net/blog/custom-llm-development) is useful because it forces the same discipline around cost, control, and maintenance.
If your enterprise stack already centers on governed warehouse data, the link between architecture and platform choice becomes obvious. Use [informing your cloud data strategy](https://dataengineeringcompanies.com/snowflake-vs-databricks/) to decide whether you want retrieval close to the warehouse or more control in a custom data engineering stack.
## Platform Integration Snowflake vs Databricks
Snowflake and Databricks don't just support AI differently. They push teams toward different operating models. Snowflake Cortex AI is the cleaner choice when you want to keep retrieval close to governed data and reduce bespoke plumbing. Databricks is the better choice when you want deeper control over the retrieval pipeline, custom model work, and the surrounding MLOps surface.
### Snowflake for integrated RAG
Snowflake fits teams that want to stay close to SQL, governed tables, and managed analytics workflows. Cortex AI, vector search, and embedding functions lower the implementation burden, which is exactly what a conservative enterprise team needs when the priority is to ground answers in existing warehouse data without building a separate retrieval platform from scratch.
That makes Snowflake the safer default for data teams that already centralize content in the warehouse and want an enterprise-friendly path to RAG. It's not the most flexible route, but it is the one that keeps platform sprawl under control.
### Databricks for custom retrieval and model work
Databricks is the stronger fit when the consulting engagement needs custom orchestration, complex MLOps, or a more controlled approach to retrieval evaluation. Its lakehouse model gives platform teams more room to tune ingestion, governance, and model serving as a single workflow. That matters when the RAG system has to support multiple document types, custom ranking logic, or tight experimentation loops.
If I'm advising a CTO, I'd say this plainly. Choose Snowflake when you want faster adoption and less infrastructure variance. Choose Databricks when the AI program is broader than RAG and includes model iteration, retraining, or highly customized pipelines.
> **Decision rule:** Snowflake reduces friction. Databricks expands control.
For teams working through the cloud stack tradeoff, [informing your cloud data strategy](https://dataengineeringcompanies.com/snowflake-vs-databricks/) gives the most direct comparison. If you're still early in the decision, that's the right place to anchor the platform conversation before you commit to RAG implementation details.
## The Decision Framework When to Build a RAG Pipeline
If the answer has to stay coherent inside a single document, choose a native long-context **LLM**. If the answer depends on private, changing, or distributed enterprise data, build **RAG**. That is the cleanest decision line, and it matches the tradeoff described in comparative analysis of long-context and retrieval systems, including the [Meilisearch analysis](https://www.meilisearch.com/blog/rag-vs-long-context-llms).
Use this checklist to make the call.
1. **Is the data private, sensitive, or governed by strict source controls?** Choose **RAG**.
2. **Does the answer depend on live or frequently updated information?** Choose **RAG**.
3. **Do you need explainability, citations, or auditability?** Choose **RAG**.
4. **Is the source material a single document or a self-contained packet of documents?** Choose a **native LLM**.
5. **Is whole-document coherence the main requirement?** Choose a **native LLM**.
That is the steering committee answer I would give. Retrieval handles factual lookup. Long-context generation handles whole-document synthesis. Keep those jobs separate, because teams get into trouble when they ask one architecture to do both and then try to patch the gaps with more prompts, more retries, and more human review.
**RAG** also creates an operational burden that gets ignored in conceptual comparisons. You are not just wiring embeddings and a vector store. You are building ingestion, chunking, metadata management, permissions, refresh logic, and evaluation, and all of that has to sit inside the existing data stack. For enterprise teams, that is why the question is really about governance and maintainability, not which model sounds smarter.
The safety side matters too. Yellow.ai on RAG safety is clear that retrieved text can carry bad instructions or misleading context into the response path, which means the system is only as safe as the corpus behind it. That makes filtering, access control, and corpus curation required from day one, not optional later work.
For teams that need the pipeline work done properly, [architecting intelligent data supply chains](https://dataengineeringcompanies.com/insights/how-to-build-data-pipelines/) is the right reference point. The architecture only holds up if the data pipeline is operationally sound.
## Next Steps Scoping Your AI Data Engineering Project
Start with scope, not model selection. If you choose RAG, define the ingestion sources, chunking strategy, embedding pipeline, retrieval method, and evaluation plan before anyone writes production code. If you choose a native long-context approach, define the document format, prompt boundaries, and latency target so a straightforward use case does not turn into a brittle prompt jungle.
> **Governance first, then generation.** If the source corpus is weak, the output will be weak, no matter how good the model is.
RAG changes the operational risk profile. The retrieval layer inherits the safety of the corpus, so permissions, content validation, and corpus hygiene have to be built into the design from day one. Your implementation partner needs to understand that reality. Embeddings and APIs are not enough.
According to DataEngineeringCompanies.com's analysis of **86** data engineering firms, projects that fail to scope operational requirements upfront see a **40%** cost overrun. That is a planning failure, not a model failure.
Your next move is simple. Define a proof of concept, lock the acceptance criteria, and choose a partner that has built governed data pipelines, not just demoed them. If you are in Snowflake, Databricks, AWS, Azure, or GCP, the right consulting team should map the architecture to your existing platform, not force a generic AI stack onto your data estate.
If you are scoping a RAG or long-context project now, run a scoping workshop that maps your data sources, governance requirements, and platform constraints in one session. Benchmark the architecture against your current warehouse or lakehouse, then greenlight the build only when the retrieval path, evaluation plan, and ownership model are explicit.
---
## Redshift vs BigQuery: The 2026 Enterprise Decision Guide
Source: https://dataengineeringcompanies.com/insights/redshift-vs-bigquery/
Published: 2026-04-07T06:47:23.049306+00:00
Description: Deciding between Redshift vs BigQuery? Get a practical, enterprise-focused comparison of architecture, cost, performance, and vendor ecosystem risks.
Redshift and BigQuery solve the same problem, cloud data warehousing at scale, with opposite operating models. Redshift is a provisioned cluster you tune; BigQuery is serverless compute Google manages for you. Pick based on which one matches your actual query patterns and cloud footprint, not which one sounds more modern.
Treat this as an ecosystem decision, not a warehouse feature bake-off. The platform you choose shapes who you can hire, which consultancies can deliver well, how painful your migrations become, and whether finance trusts your cost model. Of the 86 data engineering firms profiled in the [Data Engineering Companies Index](/), 76 list AWS among their platforms and 56 list GCP - so the warehouse you pick also narrows which specialists you can realistically bring in.
Most Redshift vs BigQuery comparisons stay shallow and argue about speed in isolation. That's the wrong frame. A warehouse doesn't sit in isolation - it sits inside pipelines, governance, IAM, ML workflows, procurement, and partner delivery.
## Is this really just a Redshift vs BigQuery feature comparison?
No. If your team thinks this is Redshift versus BigQuery on features, step back - you're choosing between control inside AWS and elasticity inside GCP. That choice shows up in architecture reviews, FinOps meetings, and every consulting statement of work you sign for years.
The common assumption is that serverless always wins because it removes admin work. That assumption breaks down in enterprise environments with stable BI, large joins, governed semantic layers, and hard requirements for repeatable dashboard performance. In those conditions, tuned infrastructure beats abstracted infrastructure more often than teams expect.
Use this quick filter first.
| Decision area | Redshift | BigQuery |
|---|---|---|
| Operating model | Provisioned cluster | Serverless |
| Best fit | Stable BI and predictable reporting | Ad-hoc analysis and bursty workloads |
| Admin burden | Higher | Lower |
| Cost model | Provisioned capacity | Pay per query plus storage |
| Real-time ingestion | Native streaming (Kinesis/MSK) or Kinesis Firehose | Native streaming |
| Hiring profile | AWS data platform and performance tuning | GCP analytics and cost governance |
The wrong decision creates a slow, expensive consulting program. The right one sharpens delivery and aligns your warehouse with your cloud posture, operating model, and procurement realities.
> **Recommendation:** If your core business depends on repeatable reporting for executives, finance, or operations, start by trying to disprove Redshift. If your business depends on wide, exploratory analysis with variable demand, start by trying to disprove BigQuery.
## How do Redshift and BigQuery differ architecturally?
Redshift and BigQuery behave differently because they're built on different assumptions. One assumes you want to provision and tune. The other assumes you want Google to abstract the machinery.
### Redshift rewards teams that want control
Redshift is a cluster-based MPP system, which means performance isn't just a product feature - it's the result of choices your team or consultancy makes around distribution, sort keys, workload patterns, and maintenance.
That gives you control. It also gives you responsibility.
Redshift works well when your team has clear workload patterns and is willing to tune the platform for them: dashboards, recurring BI jobs, and large relational joins. If your data engineering function already lives in AWS, Redshift fits naturally with the rest of the estate. The trade-off is operational load - you don't get a zero-admin experience, and the platform expects competence in tuning and ongoing maintenance.
### BigQuery removes infrastructure decisions
BigQuery is serverless. Storage and compute scale independently, and Google assigns compute slots dynamically, which changes the staffing model as much as the technical model.
Teams can start fast, load data, query it, and skip cluster planning. That's attractive in consulting-led modernization work because it pushes effort into modeling, governance, and workload management instead of infrastructure setup. BigQuery also fits variable demand better - it's built for teams that don't want to pre-plan capacity for every spike.
A related comparison worth reading is [BigQuery vs Snowflake](/insights/bigquery-vs-snowflake/), especially if your team is also evaluating a broader warehouse shortlist.
### Ingestion and concurrency expose the key difference
Architecture stops being abstract here. BigQuery ingests through native streaming with serverless autoscaling. Redshift historically leaned on Amazon Kinesis Firehose for streaming pipelines, though AWS now also offers native streaming ingestion directly from Kinesis Data Streams and Amazon MSK into materialized views, without staging data in S3 first ([AWS's streaming ingestion documentation](https://docs.aws.amazon.com/redshift/latest/dg/materialized-view-streaming-ingestion.html)).
On concurrency, Redshift's default account quota is 50 query slots across manually defined workload management queues, confirmed directly in [AWS's Redshift quotas documentation](https://docs.aws.amazon.com/redshift/latest/mgmt/amazon-redshift-limits.html) - concurrency scaling clusters can add capacity beyond that. BigQuery historically capped interactive queries around 100 per project, but Google has since replaced that fixed ceiling with a dynamic query-queueing model that scales concurrency to available slot capacity rather than a hard number ([Google Cloud's query queues announcement](https://cloud.google.com/blog/products/data-analytics/bigquery-query-queues-is-now-ga/)).
That maps directly to consulting scope:
- **If you choose Redshift**, your partner needs strong AWS delivery skills - Glue, IAM, VPC design, streaming ingestion or Kinesis Firehose integration, workload tuning, and operational runbooks.
- **If you choose BigQuery**, your partner needs strong GCP analytics skills - slot management, cost controls, streaming design, and governance for self-service usage.
- **If you plan real-time analytics**, BigQuery is cleaner out of the gate.
- **If you plan controlled enterprise BI**, Redshift gives you more knobs and more accountability.
> **Architect's view:** Control is only an advantage if your team or partner knows how to use it. Otherwise, it becomes paid complexity.
## Which platform performs better for your workload?
Ignore vendor chest-thumping and match the platform to the workload - Redshift's own published benchmarks favor stable, join-heavy BI; BigQuery's design favors variable, exploratory queries where you can't predict tomorrow's access pattern.
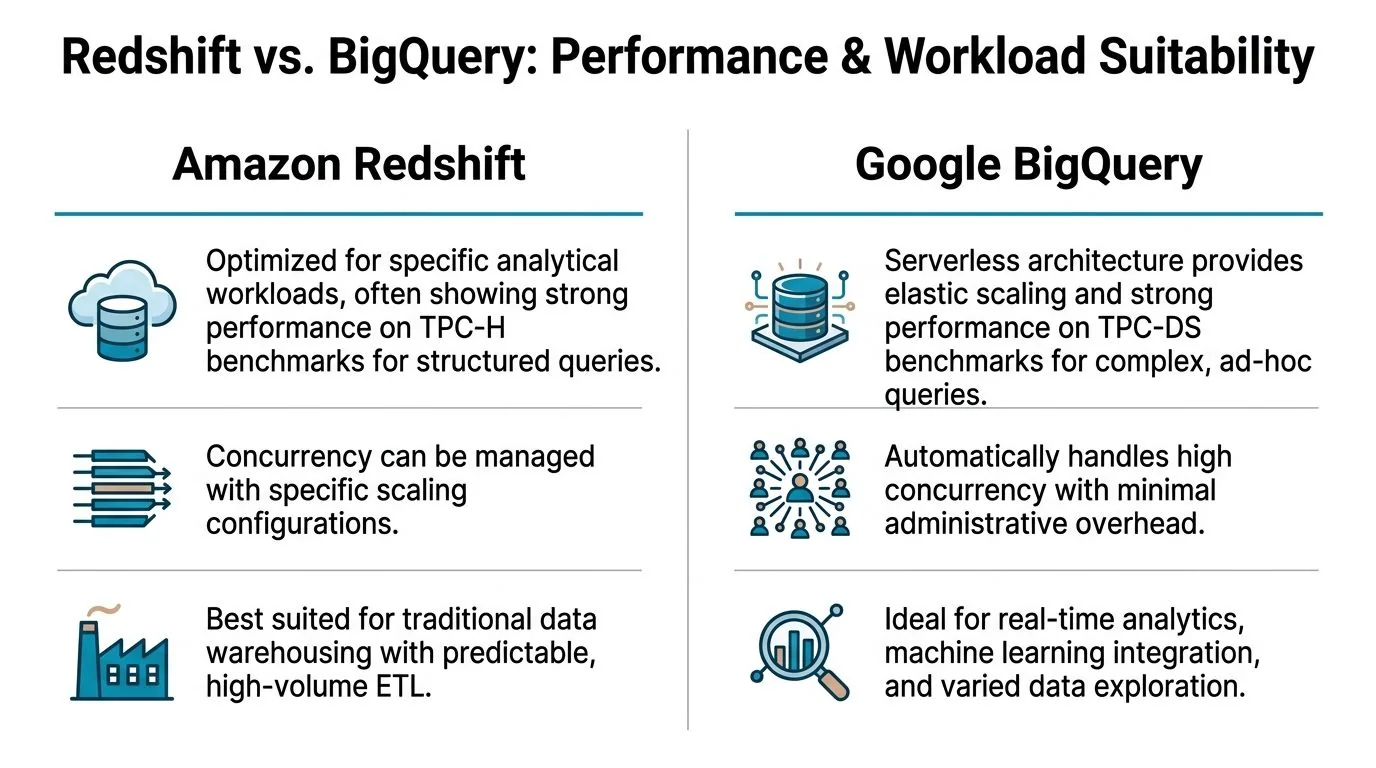
### For enterprise BI, Redshift has the stronger benchmark story
AWS publishes head-to-head benchmark results that are useful directionally, even though they come from the vendor with something to prove. In AWS's TPC-H benchmark at scale factor 1000, Redshift completed 18 of 22 queries with an average 3.6x faster elapsed time than BigQuery. In TPC-DS at 3TB scale, Redshift outperformed BigQuery on 94 of 99 queries by an average 6x faster elapsed time ([AWS's benchmark writeup](https://aws.amazon.com/blogs/big-data/fact-or-fiction-google-big-query-outperforms-amazon-redshift-as-an-enterprise-data-warehouse/)). Treat these as a starting hypothesis to test against your own workload, not a verdict - AWS ran and published them.
TPC-style tests aren't perfect, but they're directionally useful for the workloads many enterprises commonly run:
- repeated BI queries
- large joins
- governed dashboards
- scheduled reporting
- concurrency from business users hitting the same semantic layer
If your warehouse feeds Tableau, QuickSight, or a dbt-driven reporting stack all day, Redshift deserves the default position.
### For exploratory analysis, BigQuery is easier to run without planning
BigQuery wins a different argument. It's better for teams that don't know what they'll query tomorrow - data science, broad scans, experimental segmentation, feature prep, and bursty analysis fit its design. That's not just because it's serverless; the system tolerates variability better than a cluster you have to shape in advance. When a team wants to hit a massive dataset with irregular patterns, BigQuery is usually the less painful platform to operate.
Here's the practical rule:
| Primary workload | Better fit |
|---|---|
| Finance reporting | Redshift |
| Executive dashboards | Redshift |
| High-volume recurring BI | Redshift |
| Ad-hoc exploration | BigQuery |
| Variable data science workloads | BigQuery |
| Real-time streaming analytics pipelines | BigQuery |
The benchmark discussion is worth watching before you commit to a procurement direction.
### Concurrency is not the same as predictability
A lot of teams ask the wrong concurrency question. They ask "how many users can it handle?" The better question is "how predictably does it handle the workload mix we have?" Redshift is stronger when the pattern is known and tuneable. BigQuery is stronger when the pattern is volatile. Those are different operational promises.
Use this test in your architecture review:
1. **List your top ten warehouse queries by business importance.**
2. **Separate recurring queries from exploratory ones.**
3. **Measure who runs them and when.**
4. **Decide whether you value repeatability or elasticity more.**
5. **Choose the platform that fits the dominant pattern, not the aspirational one.**
Many teams over-index on future experimentation and underweight current reporting obligations. That's a mistake. If your board pack, finance close, and ops dashboards drive daily decisions, optimize for that reality first.
> **Decision rule:** Stable, business-critical SQL belongs on the platform built for repeatable performance. Unpredictable analytical spikes belong on the platform built for elastic compute.
## Which platform costs less: Redshift or BigQuery?
Neither is cheaper in every scenario - BigQuery's on-demand pricing rewards intermittent, well-scoped queries, while Redshift's reserved capacity rewards steady, predictable usage. The right answer depends on how consistent your query volume actually is.
### BigQuery is often cheaper when usage is intermittent
BigQuery's on-demand pricing is $6.25 per TiB of data scanned, with the first 1 TiB each month free; active storage runs about $0.02 per GB per month ([Google Cloud's official BigQuery pricing page](https://cloud.google.com/bigquery/pricing)). That model rewards sporadic, well-filtered queries and penalizes wide, unfiltered scans. Redshift instead prices by reserved cluster capacity (or Redshift Serverless compute units), so the bill tracks the hardware you provision rather than the bytes you touch.
Integrate.io's comparison of the two platforms estimates Redshift runs roughly 20% lower total cost of ownership for steady BI workloads, while BigQuery runs roughly 25% cheaper for ad-hoc analysis ([Integrate.io's guide](https://www.integrate.io/blog/redshift-vs-bigquery-comprehensive-guide/)). Treat those percentages as directional rather than a number to drop into a business case - they depend heavily on your query patterns and how disciplined your team is about scan size.
That maps cleanly to enterprise scenarios.
#### Scenario one: stable BI demand
If your teams run recurring dashboards every day on provisioned infrastructure, Redshift is usually the financially cleaner choice. You reserve capacity and know what you're paying for. Finance likes that. Procurement likes that. Platform teams like that.
#### Scenario two: bursty exploration
If analysts and data scientists query large datasets irregularly, BigQuery often wins. Paying by query is efficient when you're not keeping compute warm all day.
### TCO depends on people, not just compute
The headline price isn't the bill. Your total cost of ownership also includes the talent and consulting profile needed to operate the platform well.
Consider the hidden line items:
- **Redshift's hidden cost** is specialist effort - you need people who can tune performance and manage the cluster well.
- **BigQuery's hidden cost** is query sprawl - you need governance so teams don't run expensive scans without discipline.
- **Redshift's procurement upside** is reserved-instance savings and a more forecastable run rate.
- **BigQuery's operating upside** is lower admin burden and faster setup for new workloads.
A direct way to frame Redshift vs BigQuery with finance:
| Cost lens | Redshift | BigQuery |
|---|---|---|
| Budget predictability | Stronger | Weaker without controls |
| Elasticity | Weaker | Stronger |
| Admin overhead | Higher | Lower |
| Ad-hoc cost efficiency | Lower | Higher |
| Stable BI cost efficiency | Higher | Lower |
A consulting partner shouldn't just quote implementation cost - they should show how they'll control warehouse spend after go-live.
## How does platform choice affect migration and consultancy fit?
This is the part most technical comparisons skip. Redshift binds you tighter to AWS's services and hiring pool; BigQuery binds you tighter to GCP's analytics and AI stack. Both create real migration friction if you ever need to move.
### Redshift binds you more tightly to AWS
Redshift sits inside AWS and works naturally with Glue, SageMaker, and IAM. That's an advantage if your company already runs there - security reviews are easier, procurement is cleaner, and delivery is usually faster because the surrounding services are already approved and familiar. The downside is strategic rigidity: if multi-cloud flexibility matters, Redshift is the stickier choice.
### BigQuery is stronger in mixed analytics and AI workflows
BigQuery fits organizations leaning into Google's analytics and AI stack. It also handles direct external storage queries well, which can simplify some modernization patterns - a distinct advantage for teams building variable analytics products and ML-adjacent workflows.
Migrations into and out of BigQuery aren't frictionless, though. According to Polestar Analytics, BigQuery's nested data handling requires flattening when moving to Redshift, which complicates migration projects, and the same source notes that consultancies charge premiums for Redshift-to-BigQuery ports as part of broader modernization work ([Polestar Analytics' comparison](https://www.polestaranalytics.com/blog/amazon-redshift-vs-bigquery-technical-comparison)). That should influence your partner selection process immediately.
If you need help structuring that search, this guide to choosing a [cloud data warehouse consultant](/insights/build-a-data-warehouse/) is a practical starting point.
### What to demand from consulting partners
Don't hire a generic "modern data stack" firm and hope they can fake depth. Force platform-specific proof.
Ask Redshift consultancies for:
- **Performance tuning examples** involving sort keys, distribution decisions, and workload management
- **AWS integration depth** across Glue, IAM, networking, and ingestion services
- **Operational runbooks** for maintenance and scaling
- **Dashboard workload references** using BI tools such as Tableau or QuickSight
Ask BigQuery consultancies for:
- **Cost governance methods** for pay-per-query environments
- **Streaming architecture experience** for real-time ingestion
- **Data modeling approaches** for semi-structured and nested data
- **GCP integration depth** across analytics and AI services
> **Procurement rule:** Buy ecosystem competence, not slide-deck confidence. The warehouse is only one component of the delivery risk.
## Which platform should you actually choose?
You don't need a philosophical debate. You need a decision tool your leadership team can use this week - and it starts with mapping your actual workload mix, not your aspirational one, against the matrix below.
### Redshift vs BigQuery decision matrix
| Evaluation Criterion | Key Questions for Your Team | Favors Redshift If... | Favors BigQuery If... |
|---|---|---|---|
| Primary workload profile | Are most queries recurring, governed, and business-critical? | Reporting, BI, dashboards, repeatable joins dominate | Exploration, experimentation, and irregular scans dominate |
| Cost model | Do you need fixed budgets or elastic consumption? | You want predictable spend and reserved capacity economics | You want pay-for-use economics tied to real query demand |
| Team skills | Do you have platform engineers and tuning expertise? | Your team can manage tuning and ongoing optimization | Your team wants minimal infrastructure management |
| Concurrency pattern | Are workloads stable or bursty? | Business users hit known dashboards repeatedly | Users run varied analytical workloads at unpredictable times |
| Ingestion design | Is real-time streaming central? | Batch-heavy pipelines are acceptable | Native streaming is a core requirement |
| Ecosystem fit | Which cloud stack is strategically dominant? | AWS is the operational center of gravity | GCP is the analytics and AI center of gravity |
| Migration risk | Will data model translation be painful? | You're staying inside structured relational patterns | You benefit from nested or external-query-friendly designs |
| Consulting market fit | What partner profile do you need? | You want AWS-heavy delivery partners | You want GCP-heavy analytics specialists |
### Three executive recommendations
#### Choose Redshift when reporting pays the bills
Pick Redshift if your company runs on recurring BI, executive reporting, and governed analytics, especially when your stack already centers on AWS and your data team can handle tuning discipline. This fits finance-heavy, operations-heavy, and dashboard-heavy environments.
#### Choose BigQuery when variability is the business model
Pick BigQuery if your demand profile is irregular, your teams need fast experimentation, and you want to minimize infrastructure ownership. This fits analytics groups that live in wide scans, AI and ML prep, and evolving data products - and it fits a consulting program that starts fast with less platform engineering upfront.
#### Do not choose either in isolation
Your warehouse doesn't live alone. Review it with dbt, Airflow, ingestion, governance, IAM, BI tools, and ML plans in the same room - see [data warehouse vs. data lake](/insights/data-warehouse-vs-data-lake/) if the architecture question underneath this one is still open. If a consultancy can't discuss the whole platform, remove them from the process.
### RFP checklist for consultancy selection
Use this in your next vendor review.
1. **Platform depth**
Ask for recent delivery examples specific to Redshift or BigQuery, not generic cloud data work.
2. **Architecture stance**
Require a clear opinion on batch versus streaming, semantic layer design, and governance boundaries.
3. **Cost control plan**
For Redshift, ask how they tune and right-size. For BigQuery, ask how they prevent query cost drift.
4. **Migration method**
Require a written approach for schema translation, testing, rollback, and cutover.
5. **Operations handoff**
Ask what your internal team will own after launch and what specialist skills you still need to hire.
6. **Business workload mapping**
Make the partner map platform choices to actual workloads such as finance reports, product analytics, or ML prep.
### Best engagement pattern by starting point
| Your situation | Best consulting engagement |
|---|---|
| Existing Redshift environment with rising cost or latency | Fixed-scope performance and cost audit |
| New AWS warehouse for governed BI | Foundation build with tuning, IAM, and BI workload validation |
| New BigQuery adoption for analytics modernization | Foundation build with FinOps guardrails and streaming design |
| Redshift to BigQuery migration | Discovery-first migration assessment before any full build commitment |
| Unclear choice between both | Paid architecture assessment with workload replay and operating model review |
The strongest CTOs make this decision with discipline. They don't ask which platform is "best" - they ask which platform matches the company's workload, cloud strategy, partner market, and tolerance for operational complexity.
If your core workloads are stable, choose Redshift. If your workloads are variable and exploratory, choose BigQuery. If your partner can't explain the trade-offs in those terms, find another partner.
---
Specialist data engineering firms in the Index charge $45-250 an hour, with $100/hr the median - budget accordingly and use the checklist above to confirm a quote maps to real platform depth, not a generic pitch.
---
## A Practical Guide to Snowflake Cost Optimization
Source: https://dataengineeringcompanies.com/insights/snowflake-cost-optimization/
Published: 2026-02-27T07:00:04.703158+00:00
Description: Discover proven Snowflake cost optimization strategies. This guide covers compute, storage, and governance to help you reduce your Snowflake bill.
Snowflake cost optimization comes down to controlling three levers: warehouse size, how long warehouses sit idle, and how much data each query scans. Compute is almost always the biggest line item, so right-sizing warehouses and killing idle time deliver the fastest savings. The pay-as-you-go model rewards active management and punishes the "set it and forget it" habit that works fine on a fixed-cost, on-premises system.
## Why Snowflake Costs Escalate
[Snowflake's](https://www.snowflake.com/en/) consumption-based model is its biggest selling point and its biggest financial risk. Provisioning a powerful warehouse takes seconds, which is exactly what makes it easy to overspend.
Treating a consumption-based service like a fixed-cost system is a common and costly mistake. Companies often watch costs climb faster than data volume or business value, and it's rarely a platform flaw - it's a symptom of passive management. Understanding the cost structure is the first step toward control.
### What Drives Your Snowflake Bill
Your invoice breaks down into three components, and they don't carry equal weight.
* **Compute (Virtual Warehouses):** The processing engine for every query, and typically the largest cost component on the bill. Credits are billed per second whenever a warehouse is active, and - this is the part that surprises people - cost doubles with each warehouse size increase, not scales linearly.
* **Storage:** Compressed data stored in Snowflake, including data retained for Time Travel and Fail-safe. Usually a smaller share of the bill than compute, but it grows quietly if retention policies go unmanaged.
* **Cloud Services & Serverless Features:** Background processes like authentication, metadata management, and serverless tasks such as Snowpipe or Automatic Clustering. Normally a minor slice, but inefficient queries can push these costs up without warning.
> The goal of Snowflake cost management isn't cost reduction for its own sake - it's maximizing the value of each credit spent. An expensive query powering a high-revenue report is a sound investment. An idle warehouse burning credits over a weekend is a pure loss.
This guide covers three high-impact levers: **warehouse right-sizing** to match compute to actual workload needs, **aggressive auto-suspension** to stop paying for idle time, and **query optimization** to make every compute cycle count.
## How Do You Read a Snowflake Bill?
**A Snowflake invoice itemizes spend into compute, storage, and cloud services, with compute driving most of the total.** Start by pulling `QUERY_HISTORY` and `WAREHOUSE_METERING_HISTORY` to see which warehouses and queries are consuming credits before you touch any settings.
### The Warehouse Scaling Trap
Snowflake's "T-shirt" sizing (X-Small, Small, Medium, Large, X-Large...) looks simple, but the credit cost doubles with each step up. An X-Large warehouse doesn't cost incrementally more than a Small one - it costs **8 times more per hour** (16 credits versus 2), according to [Snowflake's documented warehouse credit table](https://docs.snowflake.com/en/user-guide/warehouses-overview). Leave an oversized warehouse running and that exponential curve empties a budget fast.
It's common to see quarterly Snowflake spend climb well ahead of data volume growth. When that happens, the gap is almost always compute - an oversized or poorly-suspended warehouse, not the underlying data - driving the increase.
Our [comparison of Snowflake vs. Databricks](/snowflake-vs-databricks/) walks through how the two platforms structure compute costs differently, which is useful context if you're weighing a migration rather than just tuning your current setup.
### Two Metrics Worth Tracking Today
1. **Cost per query.** Join `QUERY_HISTORY` and `WAREHOUSE_METERING_HISTORY` to calculate credit consumption per query. A high cost per query usually means an inefficient SQL statement or an oversized warehouse.
2. **Warehouse idle time.** The time a warehouse sits active without processing queries - pure waste. High idle time means your auto-suspend setting is too lenient.
## How Do You Cut Snowflake Compute Costs?
**Right-size warehouses, isolate workloads by job type, and set aggressive auto-suspend timers.** Compute is the largest line item on most Snowflake bills, so this is where optimization work pays off fastest - and none of it requires halting data initiatives, just eliminating waste from idle or oversized resources.
### Warehouse Right-Sizing Is Your Biggest Lever
The instinct to provision a bigger warehouse for "better performance" often just means paying for capacity nobody uses. Since each size increase doubles credit consumption, Large through 2X-Large warehouses run **8 to 32 times** the credits of an X-Small. Most routine workloads - data loading, standard BI queries - can't productively use more than 10-16 cores; anything beyond that is wasted spend.
A practical test: run the same query on two warehouse sizes. If it finishes in two minutes on a Medium and one minute fifty seconds on a Large, you're paying double the credits for a ten-second improvement.
#### Snowflake Warehouse Sizing Cost and Use Case Matrix
| Warehouse Size | Credits per Hour | Example Use Case | Optimization Tip |
| :--- | :--- | :--- | :--- |
| **X-Small** | **1** | Ad-hoc queries; development environments; light data loading. | Optimal for individual developers. Set an aggressive auto-suspend timer. |
| **Small** | **2** | Scheduled data ingestion (`COPY INTO`); BI dashboards with low concurrency. | Ideal for lightweight, automated tasks. Monitor query queuing to assess scaling needs. |
| **Medium** | **4** | Running dbt models for small to mid-sized projects; moderately complex transformations. | A solid default for many ELT/ETL jobs. Test against a Small warehouse to find the optimal size. |
| **Large** | **8** | Complex transformations on large datasets; initial data backfills. | Reserve for heavy-lifting; ensure it does not run idle. Isolate from other workloads. |
| **X-Large** | **16** | Intensive data science modeling; processing multi-billion row tables. | For exceptionally demanding jobs only. This size accrues costs rapidly; monitor it closely. |
| **Multi-Cluster** | **Varies** | High-concurrency BI dashboards with many active users (e.g., Looker, Tableau). | "Scale out" to handle user volume and prevent query queuing, rather than "scaling up." |
Credits per hour reflect [Snowflake's published Gen1 warehouse table](https://docs.snowflake.com/en/user-guide/warehouses-overview). Validate against your own workloads before locking in a size.
### Consolidate Warehouses and Isolate Workloads
"Warehouse sprawl" - every team or developer running a dedicated warehouse - is a common anti-pattern that leaves multiple underutilized warehouses burning credits. A better approach organizes warehouses around *workloads*, not teams:
* **Ingestion Warehouse (e.g., Small):** Dedicated to `COPY INTO` commands and other loading scripts.
* **Transformation Warehouse (e.g., Medium/Large):** For complex [dbt](https://www.getdbt.com/) models or other intensive ELT jobs.
* **BI & Analytics Warehouse (e.g., X-Small, Multi-cluster):** Optimized for concurrency across many simultaneous dashboard users.
Isolating workloads this way prevents a long-running transformation from blocking an executive dashboard query, and it lets you size each warehouse precisely instead of guessing at one number that has to work for everything.
### Scale Up vs. Scale Out: A Simple Framework
Once workloads are isolated, decide whether to "scale up" (bigger warehouse) or "scale out" (more clusters):
1. **Is the problem query *complexity*?** For a few large, complex queries - heavy joins, big aggregations - **scale up**. More memory and processing power gets the job done faster.
2. **Is the problem user *concurrency*?** For a high volume of smaller, faster queries - a popular BI dashboard, say - **scale out**. A multi-cluster warehouse handles that load without queuing users.
### Use Aggressive Auto-Suspend and Maximize Caching
Set **auto-suspend timers to 60 seconds** as a starting point. Every idle minute is wasted money, and a 5- or 10-minute timer that "feels safer" adds up to real unnecessary spend over a month.
Second, push teams toward query patterns that hit Snowflake's result cache. When the same query runs repeatedly - a common pattern for dashboards - Snowflake returns the cached result in milliseconds without spinning up a warehouse, which is effectively a free query. Standardized reports and consistent query patterns maximize cache hits.
## How Do You Cut Query and Storage Costs?
**Reduce the amount of data each query scans, and set retention periods deliberately instead of leaving defaults in place.** After warehouse compute, this is the next layer of savings - an unoptimized query is like asking a librarian to read every book to find one sentence, instead of pointing to the shelf.
### Master Your Queries to Minimize Data Scans
Every byte read from storage carries a cost, so reducing scanned data is the single most effective query optimization.
**Table clustering** helps when queries frequently filter on a specific column - a date or customer ID, say. Clustering physically co-locates data by that column's values, which cuts micro-partition scanning. Well-implemented clustering and query tuning can meaningfully reduce query costs on large tables by eliminating wasteful reads, though the exact savings depend heavily on your table's query patterns.
**Materialized views** pre-compute results for common, complex queries.
> A materialized view works like a pre-built summary. Instead of recalculating a complex sales metric every time an executive dashboard loads, Snowflake retrieves the pre-computed result - less compute, and near-instant load times for those workloads.
Finally, set **query timeouts**. A runaway query - an accidental cross-join on two large tables, for instance - can run for hours and rack up a massive bill. A `STATEMENT_TIMEOUT_IN_SECONDS` parameter at the warehouse or user level acts as a safety net that automatically kills queries past the limit.
### Get Strategic With Your Storage
Storage is usually a smaller share of the bill than compute, but unchecked data growth still adds up. The goal is balancing recoverability against cost.
The **Time Travel retention period** deserves a second look. Snowflake's default is 1 day for all editions; Enterprise Edition and higher lets you extend it up to 90 days. Raising that default to the 90-day maximum on a large, frequently updated table can meaningfully increase its storage footprint, so extend retention deliberately rather than as a blanket setting - see [Snowflake's Time Travel documentation](https://docs.snowflake.com/en/user-guide/data-time-travel) for the exact mechanics.
Two concrete moves:
* **Tiered retention:** short retention (1 day) for staging tables, moderate (7-14 days) for core business tables, and longer only where compliance requires it.
* **Transient tables:** for temporary data - intermediate ELT steps, for example - `TRANSIENT` tables skip the Fail-safe period and cap Time Travel at 1 day, which cuts their storage overhead substantially.
If your team is choosing between a warehouse-centric or lakehouse-style architecture in the first place, our [data warehouse vs. data lake guide](/insights/data-warehouse-vs-data-lake/) covers the cost tradeoffs of each approach.
### Squeeze Every Drop of Value from Caching
The **result cache** is worth building workflows around. Run an identical query twice and Snowflake serves the second result from cache without activating a warehouse - a real performance boost at zero compute cost.
This matters most for BI dashboards. Train analysts to use standardized filters and avoid non-deterministic functions like `CURRENT_TIMESTAMP()`, which break cache hits by making every query unique. Get that right and hundreds of dashboard users can share the cost of a single initial query.
## How Do You Build Lasting Snowflake Cost Governance?
**Tag every warehouse and query by team or project, set resource monitors with hard credit caps, and add third-party tooling once you outgrow native alerts.** Optimization erodes without ongoing governance - a one-time cleanup buys a few good months, not a lasting fix.
This isn't about restricting access. It's about making every dollar of spend attributable to a team, project, or cost center.
### Establish a Clear Tagging Strategy
You can't control what you can't measure, and you can't measure what you can't identify. Tag every compute resource - warehouses, tasks, queries - with at minimum:
* `team`: the owning team (e.g., `marketing-analytics`)
* `project`: the specific initiative (e.g., `q4-campaign-analysis`)
* `environment`: deployment stage (e.g., `prod`, `dev`, `test`)
A consistent tagging policy is the foundation for any showback or chargeback model - it turns an opaque total into a ledger business units can actually read. For more on setting up these policies, see our [data governance best practices guide](/insights/data-governance-best-practices/).
### Implement Proactive Resource Monitors
Finding out about a cost overrun at month-end is too late. Snowflake's built-in **resource monitors** are automated circuit breakers: set credit quotas for the account or individual warehouses, and configure actions at specific thresholds - email at 75% of the monthly quota, notify a wider team at 90%, and auto-suspend at 100%. That one setup turns a potential budget crisis into a routine notification.
### Where Third-Party Monitoring Tools Fit
Native Snowflake tools are good for hard limits; third-party cost platforms add deeper analysis on top. Their strengths:
* **Anomaly detection:** flagging sudden spikes in warehouse usage or query costs automatically.
* **Automated recommendations:** suggesting specific optimizations, like downsizing a warehouse or flagging unused tables.
* **Root cause analysis:** drilling down to the specific user, query, or dbt model behind a cost spike.
These tools act as a standing FinOps check on the account, closing the gap between high-level budget tracking and query-level analysis.
## When Should You Bring in a Snowflake Cost Optimization Partner?
**Bring in external help when budget overruns persist despite internal effort, when query performance is degrading and the cause isn't obvious, or when the team lacks deep Snowflake-specific FinOps expertise.** Even a skilled internal team hits diminishing returns eventually - 66 of the 86 firms profiled in the Data Engineering Companies Index list Snowflake as a core platform, which gives you a real pool of specialists to evaluate rather than a handful of generalists.
A specialist consultancy has usually seen architectural inefficiencies across many more Snowflake implementations than one internal team ever will. The trigger is often a specific event: a complex data migration where cost-effective architecture matters from day one, or the need for a third-party audit to validate the current strategy and surface hidden savings.
### Signs It's Time for an Expert
* **Persistent budget overruns:** the bill consistently exceeds forecast and your team can't pin down why.
* **Performance degradation:** queries slowing, dashboards lagging, business users noticing.
* **Missing specialized skills:** strong at data analysis, thin on Snowflake architecture, tuning, or FinOps practice.
* **No bandwidth for proactive work:** engineers are fully consumed by delivery, with nothing left for cost management.
A good partner should deliver savings that clearly exceed their fees within a few months, and should transfer enough knowledge that your team can sustain the improvements after the engagement ends. Our [directory of Snowflake consulting firms](/snowflake-consulting/) is a starting point for building a shortlist, and our [data engineering consulting rates guide](/insights/data-engineering-consulting-rates-2026/) will help you build the business case.
### RFP Checklist for Snowflake Cost Optimization Partners
| Evaluation Category | Key Questions to Ask | Desired Response / 'Green Flag' |
| :--- | :--- | :--- |
| **Proven Experience** | Provide case studies of Snowflake cost optimization projects with quantifiable results. | They readily share detailed case studies with specific, verifiable savings and performance gains. |
| **Technical Expertise** | Describe your team's certifications and direct experience with Snowflake features like clustering, caching, and warehouse management. | The team holds current Snowflake certifications and can discuss architectural patterns with specificity. |
| **Methodology & Process** | What is your process for auditing our environment? What tools do you use? How will you collaborate with our team? | A structured, phased approach: audit, recommend, implement, monitor - using a mix of native and third-party tools. |
| **Knowledge Transfer** | How do you ensure our team can maintain these optimizations after your engagement ends? | The proposal includes training sessions, documentation, and pairing their experts with your engineers. |
| **ROI & Pricing** | What is your pricing model? Can you project ROI based on our current spend and your initial assessment? | Flexible pricing (fixed-bid, retainer) with a conservative, evidence-based case for positive ROI. |
## Snowflake Cost FAQs
### What's the biggest slice of the Snowflake bill?
Compute is the largest cost driver for most accounts, tied to virtual warehouses billed per second while active. An oversized or idle warehouse burns through credits fast, which is why right-sizing, workload isolation, and aggressive auto-suspension are the highest-impact levers.
### How can I lower my Snowflake bill right now?
Two actions with immediate impact: change auto-suspend timers from the default 5 or 10 minutes down to **60 seconds**, and audit your most expensive warehouses for over-provisioning - if an X-Large is running simple BI queries, scale it down. Neither change touches your data or pipelines.
### Do I pay for queries that fail?
Yes. Snowflake bills for compute time regardless of query outcome. A query that runs five minutes before erroring out still costs five minutes of warehouse uptime, which is why query timeouts and SQL linting in your development workflow matter.
### Are "serverless" features actually free?
No. Snowpipe, Automatic Clustering, and materialized view maintenance are "serverless" because Snowflake manages the underlying compute - but you still pay for that compute as credits consumed by background services. Enabling automatic clustering on a large, infrequently-queried table is a common way to rack up background costs for little benefit. Evaluate the cost-benefit of each serverless feature before turning it on.
---
## Snowflake Schema and Star Schema: A Practical Guide for Modern Data Warehouses
Source: https://dataengineeringcompanies.com/insights/snowflake-schema-and-star-schema/
Published: 2026-02-07T10:10:13.555237+00:00
Description: Snowflake schema vs star schema explained: compare query performance, storage trade-offs, and real-world use cases to choose the right model for your data warehouse.
A **star schema** denormalizes dimension tables into flat, wide tables for fast, simple BI queries. A **snowflake schema** normalizes those same dimensions into smaller linked sub-tables to cut storage and enforce data integrity, at the cost of extra joins. Neither is better in general - the right pick depends on whether your workload is read-heavy dashboards or auditable, hierarchical reporting.
One distinction worth making before anything else: a snowflake schema is a data-modeling pattern, not the Snowflake cloud platform. You can build either a star or a snowflake schema on Snowflake, BigQuery, Redshift, or any SQL warehouse - the two share a name and nothing else.
## What's the difference between a star schema and a snowflake schema?
Both models organize a warehouse around a central **fact table** (the numbers - sales totals, order counts, clicks) surrounded by **dimension tables** (the context - who, what, when, where). The split is **normalization**: a star schema keeps each dimension as one flat table; a snowflake schema breaks dimensions into smaller, linked tables to remove repeated values.
| Feature | Star Schema | Snowflake Schema |
| :--- | :--- | :--- |
| **Primary Goal** | Query Speed & Simplicity | Storage Efficiency & Data Integrity |
| **Structure** | Denormalized (fewer, wider tables) | Normalized (more, narrower tables) |
| **Query Joins** | Fewer, simpler joins | More, complex joins |
| **Data Redundancy** | High (attributes are repeated) | Low (attributes stored once) |
| **Maintenance** | More complex for data updates | Simpler for data updates |
| **Ideal Use Case** | BI Dashboards & Ad-Hoc Reporting | Complex Enterprise Reporting & Analytics |
On modern cloud warehouses, the decision isn't just query speed versus storage - it's balancing ETL complexity, governance overhead, and how end users actually query the data. See [architecture of a data warehouse](/insights/architecture-of-a-data-warehouse/) for how schema design fits into the rest of the stack.
## How does a star schema work?
A star schema features a central fact table connected directly to surrounding dimension tables - no intermediate tables in between. In a retail model, a `Sales` fact table links directly to `Product`, `Customer`, and `Date` dimensions. A single `Product` table holds all related attributes (name, category, brand) in one place, which is deliberately redundant: it minimizes the joins a query needs to run.
* **Central Fact Table:** Holds foreign keys to each dimension alongside core numerical measures.
* **Dimension Tables:** Contain descriptive attributes and connect directly to the fact table.
* **Query Simplicity:** SQL queries are straightforward, typically requiring only a single join per dimension.
Fewer joins mean the database engine retrieves and aggregates data faster, which is why star schemas are the default for data marts and BI tools serving interactive dashboards.
## How does a snowflake schema work?
A snowflake schema starts from the same fact-and-dimension structure, then breaks large dimension tables into smaller, related sub-tables. Instead of one large `Product` dimension, a snowflake schema might use three linked tables: `Product` links to `Subcategory`, which links to `Category`. The category "Electronics" is stored once, not repeated for every product in it - the branching structure is what gives the schema its name.
This conserves storage and simplifies maintenance: updating a category name means changing one row in one table. The trade-off is query complexity, since reconstructing the full context now needs more joins. For a comparison of the underlying storage models, see [data warehouse vs. data lake](/insights/data-warehouse-vs-data-lake/).
## How do star and snowflake schemas compare on performance and cloud cost?
On platforms that bill compute and storage separately, this trade-off is as financial as it's technical. A star schema's flat structure needs fewer computational cycles, which typically means faster dashboards and lower compute bills. A snowflake schema's normalized hierarchy stores each attribute value once, which typically means a smaller storage footprint and lower storage bills.
For an analyst running BI queries, latency matters most. A star schema's single join per dimension lets query optimizers in platforms like [Snowflake](https://www.snowflake.com/en/) or [Google BigQuery](https://cloud.google.com/bigquery) build efficient execution plans. A snowflake schema forces queries through longer join paths - retrieving a full set of attributes might mean traversing `Product` to `Subcategory` to `Category` - which adds computational overhead even on modern engines.
Materialized views and query caching narrow this gap on cloud warehouses, but a star schema's structural edge for read-heavy workloads generally holds.
#### Star vs Snowflake Schema Key Trade-Offs Matrix
| Criterion | Star Schema (Optimized for Speed) | Snowflake Schema (Optimized for Integrity) |
| :--- | :--- | :--- |
| **Typical Compute Bill** | **Lower.** Fewer joins consume less processing power, ideal for high-frequency BI queries. | **Higher.** Multi-level joins require more computational resources, increasing costs for analytical workloads. |
| **Typical Storage Bill** | **Higher.** Denormalization creates data redundancy, increasing the total volume of data stored. | **Lower.** Normalization minimizes data duplication, resulting in a more compact and cost-effective storage footprint. |
| **ETL/ELT Cost Impact** | **Higher upfront transformation.** More complex logic is needed during data loading to denormalize and flatten source data. | **Lower upfront transformation.** The structure can more closely mirror normalized source systems, simplifying initial ingestion pipelines. |
| **Best Financial Fit** | Environments where query performance is the primary driver and the cost of compute outweighs the cost of storage. | Environments where storage efficiency is a top priority or where data integrity justifies slightly higher query latency. |
If self-service analytics for business users is the goal, the higher storage cost of a star schema is usually worth it. If you're managing large datasets where storage cost and data integrity both matter, a snowflake schema makes a stronger financial case.
## How does schema choice affect data pipelines and governance?
The choice determines where complexity lives: upfront in data engineering, or downstream in analytics and maintenance.
A star schema front-loads the work. Building wide, flat dimension tables means pre-joining and flattening data from multiple normalized source systems during ETL or ELT, which makes initial pipeline development more intensive. A snowflake schema often mirrors the structure of a transactional (OLTP) source system, so initial extraction can be closer to a one-to-one mapping - but the complexity reappears later, in the query layer and in managing referential integrity across interconnected tables.
A pipeline for a star schema might run one complex job to merge `product`, `category`, and `brand` data. A snowflake pipeline might run three simpler jobs to load each table separately, then carry the operational burden of managing the foreign keys that connect them.
On governance, the normalized structure of a snowflake schema is a natural fit for consistency: each fact is stored in one place, so a category-name change means updating a single row and having it propagate correctly everywhere. A star schema's redundancy pushes that risk onto the update process - if the same category name is duplicated across thousands of product rows, every instance has to be touched correctly or the data goes inconsistent. See [data governance strategies](/insights/data-governance-strategies/) for building frameworks around this.
If an auditable system of record is the priority, a snowflake schema's normalized design is the sturdier foundation. If the priority is fast, agile analytics and your team has the discipline to manage denormalized data correctly, a star schema's simplicity and speed usually wins.
## When should you choose a star schema vs a snowflake schema?

**Choose a star schema** when query speed and ease of use matter most - typically for BI users who need fast, responsive dashboards and the ability to slice, dice, and drill down on the fly.
* **Retail Sales Analytics:** An e-commerce team filtering by date, product category, or customer segment needs near-instant dashboard loads. A star schema with a central `Sales` fact table linked to flat `Product`, `Customer`, and `Date` dimensions delivers that.
* **Marketing Campaign Dashboards:** Dimensions like `Campaign`, `Channel`, or `Ad Group` are relatively static, so a star schema's fast query performance suits real-time monitoring of clicks, conversions, and cost per acquisition.
* **Web Analytics Reporting:** Most queries are simple aggregations - "total page views by country yesterday" - which a star schema handles well, letting non-technical users build reports in tools like [Tableau](https://www.tableau.com/) or [Power BI](https://powerbi.microsoft.com/en-us/) without help.
**Choose a snowflake schema** when data integrity, storage efficiency, or deeply nested hierarchies are the primary concern, even at the cost of somewhat higher query latency.
* **Financial Reporting Systems:** A multinational's chart of accounts is a deep hierarchy (`Account` -> `Sub-Ledger` -> `General Ledger`). A snowflake schema models it precisely, so an account-name change updates once and stays consistent across every report.
* **Complex Supply Chain Analytics:** `Geography` (`Store` -> `City` -> `Region` -> `Country`) and `Product` (`SKU` -> `Brand` -> `Category`) nest deeply for a global manufacturer. A snowflake schema reduces redundancy across that structure.
* **Human Resources Analytics:** Org charts and reporting lines are hierarchical and change often. Snowflaking the `Employee` and `Department` dimensions makes those fluid relationships easier to manage and keeps historical records accurate.
## Should you mix star and snowflake schemas in the same warehouse?
Yes, and in most cases you should. The most effective data architectures today are pragmatic hybrids rather than one model applied warehouse-wide.
A common pattern: use a normalized snowflake schema in the core, integrated layers of the warehouse to enforce data integrity, then denormalize into star schemas for user-facing data marts so BI analysts get the fast queries dashboards need. This isn't a compromise - it delivers a star schema's speed for analytics while keeping a snowflake schema's integrity for the data everything else is built on.
To decide per data mart or domain, work through three questions:
1. **What's the primary use case?** High-speed, ad-hoc BI dashboards point to a star schema. Structured, operational reporting in finance or compliance points to a snowflake schema's tighter governance.
2. **How complex are the data hierarchies?** Flat dimensions, like a `Date` table, work fine as a star schema. Deeply nested ones, like a product catalog (`SKU > Brand > Category`) or an org chart, are better modeled as a snowflake schema.
3. **What's your tolerance for storage cost versus query latency?** A star schema costs more storage but less compute; a snowflake schema costs less storage but more compute from extra joins. Model expected costs on your platform - [Snowflake](https://www.snowflake.com/en/) or [Google BigQuery](https://cloud.google.com/bigquery) - before committing.
## Common questions about star and snowflake schemas
### Has the star schema become obsolete?
No. Modern cloud platforms like Snowflake and BigQuery handle complex joins efficiently, but a star schema's simplicity and raw speed still win for most BI workloads. Its structure is intuitive for analysts and suited to the read-heavy pattern typical of dashboards and reporting - cloud advancements have narrowed the performance gap, not closed it.
### Does a snowflake schema always save money?
Not necessarily. A snowflake schema's normalized structure cuts storage costs, but it often shifts that cost to compute - reconstructing data through extra joins consumes processing power. On pay-per-compute platforms, a warehouse with frequent, complex queries can end up spending more on compute than it saves on storage. Model both sides before assuming normalization is the cheaper option.
## Where this fits in the wider stack
Of the 86 firms profiled in the Data Engineering Companies Index, 66 list Snowflake as a core platform. If your warehouse runs on Snowflake specifically, schema design interacts with platform features like clustering keys and query result caching - for help implementing either schema, see our directory of [Snowflake consulting partners](/snowflake-consulting/).
---
## Actionable Playbook for Snowflake to Databricks Migration
Source: https://dataengineeringcompanies.com/insights/snowflake-to-databricks-migration/
Published: 2026-03-27T10:37:02.476426+00:00
Description: Actionable playbook for engineering leaders: Snowflake to Databricks migration. Strategies for cost, execution & AI/ML value.
**A Snowflake to Databricks migration moves your warehouse workloads onto the Databricks Lakehouse platform** - consolidating BI, data engineering, and machine learning onto one system instead of stitching Snowflake to separate ETL and ML tools. It is a platform re-architecture, not a lift-and-shift: SQL and procedural logic get translated and rebuilt, and governance moves to Unity Catalog.
## Why Do Engineering Teams Migrate From Snowflake to Databricks?
**Teams move off Snowflake when the warehouse becomes a bottleneck for data science and ML work** - when the organization needs an integrated environment for engineering, analytics, and machine learning instead of a warehouse plus a separate stack of ETL and ML tools bolted onto it.
The primary business drivers for this migration are:
* **Lower Total Cost of Ownership (TCO):** Data stacks comprising Snowflake for warehousing, another tool for ETL, and a third for ML create redundant licensing and infrastructure fees. Consolidating on Databricks eliminates these costs.
* **Unified Governance:** Managing security, access, and compliance across multiple systems is operationally complex. Databricks Unity Catalog provides a single governance model for all data assets - from tables to ML models - simplifying administration.
* **Integrated AI/ML Capabilities:** Databricks, built on Apache Spark, is designed for large-scale data processing and machine learning. Teams no longer need to extract large datasets from the warehouse to train models, which accelerates development cycles.
This is not a niche trend. Multiple industry market-research firms put the global data lakehouse market on a sustained double-digit compound annual growth trajectory through the early 2030s, driven by the same consolidation logic described above. Staying on a warehouse-only platform carries a real opportunity cost as that shift continues.
> The core difference is architectural philosophy. Snowflake perfected the cloud data warehouse. Databricks built a unified platform for data and AI. For a deeper dive into their architectural differences, read our complete [Snowflake vs. Databricks comparison](/snowflake-vs-databricks/).
## How Do You Build a Pre-Migration Cost and Readiness Model?
**A Snowflake to Databricks migration succeeds or fails before a single line of code is translated.** Build a model that scores your codebase's complexity and maps it against a realistic total cost of ownership - without that analysis, you are budgeting and scheduling blind.
This process starts with a forensic audit of your current Snowflake environment. Inventory every asset: SQL queries, stored procedures, Snowpark jobs, UDFs, tasks, and data streams. This inventory forms the foundation of your migration plan.
### How Do You Quantify the Migration Effort?
**Score each asset's complexity after the inventory is complete.** A simple `SELECT` statement and a 2,000-line stored procedure with Snowflake-specific functions represent wildly different amounts of work, so a scoring system is what turns that gap into a plannable, prioritized timeline.
* **Low Complexity:** Standard ANSI SQL queries and basic views. These often migrate with near-zero-touch automation.
* **Medium Complexity:** Queries using proprietary Snowflake SQL functions, simple Snowpark dataframes, or Snowpipe ingestion. These require translation, but the patterns are well-understood and often automatable.
* **High Complexity:** Nested stored procedures, complex UDFs, streams, and tasks. This procedural logic cannot be directly translated; it must be manually re-architected into a Databricks notebook or a Delta Live Tables pipeline.
This scoring provides a quantifiable measure of technical debt, turning a vague "it's complex" into an actionable plan for prioritization and realistic timeline setting.
### How Do You Build a Realistic TCO Model?
**A Total Cost of Ownership model has to account for how differently Snowflake and Databricks structure compute, storage, and engineering cost - a simple license-to-license comparison misses most of the real difference.** The table below breaks out the cost drivers that actually diverge between the two platforms.
| Cost Factor | Snowflake Approach | Databricks Approach | Migration Implication |
| :--- | :--- | :--- | :--- |
| **Compute Model** | Bundled compute (Virtual Warehouses) with per-second billing. Sized T-shirt models (XS, S, M, etc.). | Unbundled compute (Databricks Units or DBUs) billed per-second. Granular control over VM types. | Databricks is often cheaper for consistent workloads if tuned properly. Snowflake is more cost-effective for sporadic, ad-hoc queries due to its auto-suspend feature. |
| **Storage** | Storage costs are separate from compute, billed at pass-through rates from the cloud provider plus a markup. | Uses your own cloud storage account (BYOS). You pay the cloud provider directly for storage. | Databricks offers direct control and potential savings on storage but requires you to manage the cloud storage lifecycle. |
| **Engineering Overhead** | Designed for ease of use, often requiring less specialized platform engineering. | Requires more skilled engineering (Spark, Scala, Python) to optimize infrastructure for price/performance. | Your team's existing skill set is a major cost factor. A Spark talent gap requires budgeting for training or consulting. |
| **Workload Specialization** | A single architecture for BI, analytics, and some data science. | Specialized runtimes and compute options for SQL, ML, and streaming, allowing for tailored optimization. | You must map Snowflake workloads to the correct Databricks cluster type to achieve cost-efficiency; a one-size-fits-all approach is expensive. |
A common and costly mistake is underestimating the cost of running parallel environments. During a phased migration, you will pay for **both** Snowflake and Databricks. This dual-cost period can last for months, and your budget must have a line item for it. Learn more about how these [economic models differ at Invene.com](https://www.invene.com/blog/snowflake-vs-databricks).
Factor in these real-world costs:
* **Engineering Effort:** Use complexity scores to estimate person-hours for code conversion, logic re-platforming, and testing.
* **Talent & Training:** Budget for hiring, training, or consultants if you lack Spark, Scala, or advanced Python skills.
* **Migration Tooling:** Include costs for any third-party automation tools for code translation or validation.
* **Egress Fees:** Snowflake charges data egress fees for the initial export of data to your cloud storage. This is a significant one-time cost.
## How Do You Translate Snowflake Workloads to Databricks?
**A Snowflake to Databricks migration is a translation project, not a "lift-and-shift."** The work maps Snowflake's proprietary, SQL-first environment onto the open standards of the [Databricks](https://www.databricks.com/) Lakehouse Platform - schema by schema, procedure by procedure.
### How Do You Map Snowflake Data Structures to Databricks?
**The first technical task is translating Snowflake DDL (Data Definition Language) into a format compatible with [Delta Lake](https://delta.io/),** which stores and manages data differently enough that a straight syntax swap is not sufficient.
* **Tables and Views:** Standard ANSI SQL tables and views will migrate with minimal changes. Automated tools can handle this, but manual inspection of views using Snowflake-specific functions is required.
* **VARIANT Type:** Snowflake’s proprietary `VARIANT` type for semi-structured data must be mapped to a `JSON` string or native `structs` and `arrays` in Delta tables. Queries must be rewritten to use Databricks' JSON parsing functions (`from_json`, `get_json_object`).
* **Time Travel:** Both platforms offer historical data querying. Snowflake's Time Travel is equivalent to Delta Lake's transaction log, which enables querying past table states via `VERSION AS OF` or `TIMESTAMP AS OF`. Scripts must be adapted to the new syntax.
> **Expert Tip:** The `VARIANT`-to-JSON conversion strategy is a common failure point. A migration plan must account for how this data will be stored, ingested, and queried in the new environment.
### How Do You Convert Procedural Logic and Ingestion Pipelines?
**Procedural code - business logic in stored procedures and UDFs - demands manual re-architecture, not automated translation.** Snowflake's JavaScript Stored Procedures have no direct equivalent. This logic must be refactored into a [Databricks Notebook](https://docs.databricks.com/en/notebooks/index.html) using Python or Scala. While more work upfront, this yields improved testability, version control, and integration with the PySpark ecosystem.
Simple SQL UDFs can be converted to Databricks SQL UDFs. Complex UDFs are best rebuilt as part of a notebook or a [Delta Live Tables (DLT)](https://www.databricks.com/product/delta-live-tables) pipeline for better long-term manageability.
### What Are the Key Snowflake to Databricks Feature Mappings?
**Snowpipe maps to Auto Loader, Tasks and Streams map to Delta Live Tables or Scheduled Jobs, and Stored Procedures map to Notebooks or SQL UDFs** - the table below covers the migration consideration for each.
| Snowflake Feature | Databricks Equivalent | Key Migration Consideration |
| :--- | :--- | :--- |
| **Snowpipe** | **Auto Loader** | Both offer automated file ingestion. [Auto Loader](https://docs.databricks.com/en/ingestion/auto-loader/index.html) provides superior schema inference and evolution, reducing manual DDL adjustments. |
| **Tasks & Streams** | **Delta Live Tables (DLT) or Scheduled Jobs** | Simple Snowflake Tasks can be replaced by Databricks Jobs. For CDC patterns using Streams and Tasks, re-architect them into a DLT pipeline for a more reliable, declarative framework. |
| **Stored Procedures** | **Notebooks (Python/Scala) or SQL UDFs** | Simple, self-contained procedures may map to SQL UDFs. Logic with loops, error handling, or complex branching must be refactored into a notebook. This is a manual but necessary upgrade. |
The security model must be translated carefully. Snowflake’s Role-Based Access Control (RBAC) and data masking policies have a strong equivalent in **Databricks Unity Catalog**. [Unity Catalog](https://www.databricks.com/product/unity-catalog) provides a unified governance layer for implementing fine-grained row- and column-level security across all data and AI assets.
## How Should You Structure a Phased Migration?
**A "big bang" migration from Snowflake to Databricks is a recipe for failure.** Break the work down by business domain or data product and run it as a phased, iterative execution instead - it de-risks the project and gives stakeholders visible progress along the way.
The process involves the parallel translation of three components: data schemas, business logic (SQL), and ingestion pipelines.
As the diagram illustrates, schema migration, logic conversion, and ingestion re-architecture are multi-threaded, not linear.
### Which Migration Tools Should You Use?
**Automation speeds up translation, but the right tool depends on how standard your SQL is.** There are three primary options:
* **[Databricks Lakebridge](https://www.databricks.com/solutions/migration/lakebridge):** Databricks' free, open tool for profiling, SQL conversion, and validation. It automates the bulk of routine SQL translation and is a reasonable starting point for most migrations.
* **Third-Party Tools:** Specialized vendors offer code translation tools that excel with complex, non-standard SQL or proprietary Snowflake features.
* **Custom Scripts:** For teams with deep engineering expertise, building custom conversion scripts offers total control but requires a significant development investment. This is only viable in unique situations.
For most projects, a hybrid approach is best: use Lakebridge for bulk conversion and have experts manually refactor complex or critical components. Automate what you can; re-architect where it counts. Our guide on [data migration best practices](/insights/data-migration-best-practices/) provides broader strategies.
### Why Is Validation Non-Negotiable in a Migration?
**Validation has to be continuous and multi-layered, not a final checkbox before cutover.** A migration without rigorous, parallel validation is just a data copy-and-paste exercise - you have to prove functional equivalence, performance, and cost before decommissioning Snowflake.
1. **Data Integrity Validation:** Perform cell-by-cell comparisons on data subsets to ensure perfect data transfer from source to target.
2. **Performance Benchmarking:** Run critical queries in both Snowflake and Databricks to prove that Databricks meets or exceeds performance SLAs.
3. **Financial Validation:** Monitor Databricks Unit (DBU) consumption against your TCO model to confirm projected cost savings.
This three-pronged validation approach is your defense against post-cutover surprises.
## How Do You Select the Right Migration Partner?
**Vet for certified, hands-on experience in both Snowflake and Databricks, not a generalist IT firm that dabbles in one.** Of the 86 firms profiled in the Data Engineering Companies Index, 64 list Databricks and 66 list Snowflake as a core platform; 78 name data migration among their capabilities. Listing a platform as a capability is not the same as fielding certified dual-platform migration experts - the checklist below is how you tell the two apart. Browse the [Databricks consulting directory](/databricks-consulting/) to compare vetted firms directly.
### Core Evaluation Criteria Checklist
Be wary of partners skewed toward one platform. A Snowflake-heavy team may try to force a Snowflake architecture onto Databricks, creating a more expensive, less efficient system.
Use this checklist when vetting partners:
* [ ] **Dual-Platform Experience:** Do they have certified experts and specific project references for both [Snowflake](https://www.snowflake.com/) and [Databricks](https://www.databricks.com/)? Demand case studies detailing a warehouse-to-lakehouse migration.
* [ ] **Unity Catalog Mastery:** Can they explain how they will map your Snowflake security and RBAC into a unified governance model on [Unity Catalog](https://www.databricks.com/product/unity-catalog)? A fumbled answer is a major red flag.
* [ ] **Automation Strategy:** Which tools do they use for code migration? Do they have a realistic commitment to an automation percentage and a proven method for combining automation with manual refactoring?
### Run a Structured Selection Process
Conduct a formal Request for Proposal (RFP) process. An RFP forces potential partners to provide detailed proof of their skills and transparent pricing, enabling a true apples-to-apples comparison.
A structured framework ensures you find a partner who will achieve the strategic goals of your migration, not just tick a technical box.
## Answering Your Snowflake to Databricks Migration Questions
Here are direct answers to the most common questions from engineering leaders.
### How Long Does a Typical Migration Take?
For a mid-sized company, a full migration takes **9 to 18 months**. The timeline depends on data volume, the complexity of custom logic, and the number of connected reports and dashboards.
Start with a pilot project on a single business unit or data product. This can be completed in **8 to 12 weeks** and provides a quick win. Timelines are most often derailed by a shallow pre-migration assessment and underestimating the time required for testing and validation.
### What Is the Biggest Technical Hurdle?
The biggest hurdle is untangling procedural logic from complex stored procedures and UDFs. While tools can automate standard SQL, this embedded business logic requires manual analysis, re-architecture, and rebuilding, typically in Python notebooks. This manual effort is a common source of budget overruns. Another challenge is transitioning from Snowflake's proprietary data sharing to the open **Delta Sharing** standard, which requires careful planning with external partners.
### Can We Run Snowflake and Databricks in Parallel?
Yes, and you must. Running both platforms side-by-side during a phased migration is the only safe approach. This dual-platform strategy acts as a safety net, ensuring business continuity.
Set up a data sync from Snowflake to your cloud storage (S3, ADLS Gen2). [Databricks](https://www.databricks.com/) can then ingest this data using tools like [Auto Loader](https://docs.databricks.com/en/ingestion/auto-loader/index.html). This keeps the new Databricks environment fresh for side-by-side validation of migrated pipelines.
> A dual-platform strategy is non-negotiable for a smooth transition. It allows for meticulous testing and a controlled cutover, but remember to explicitly budget for these overlapping costs, as you will be paying for both services during this period.
The objective of parallel operation is to migrate and validate workloads one by one, ensuring each performs correctly before decommissioning the original. This systematic cutover prevents post-migration failures.
---
A qualified partner needs certified, hands-on expertise in both Snowflake and Databricks, not just one. Compare vetted firms with proven migration methodologies in the [Databricks consulting directory](/databricks-consulting/), read the full [Snowflake vs. Databricks comparison](/snowflake-vs-databricks/) before you scope the project, or review broader [data migration best practices](/insights/data-migration-best-practices/) for the phases that apply beyond this one platform pair.
---
## Snowflake Partners vs. Databricks Partners: Who Should You Hire in 2026?
Source: https://dataengineeringcompanies.com/insights/snowflake-vs-databricks-partners/
Published: 2025-12-19T00:00:00.000Z
Description: Confused between hiring a Snowflake or Databricks partner? We compare the ecosystems, partner specializations, and how to choose the right expert for your data platform.
TL;DR: The 30-Second Verdict
Hire Snowflake Partners IF: Your goal is self-service BI. You need to serve SQL dashboards to hundreds of marketing and sales users with minimal maintenance. Look for partners with "SnowPro Advanced Architect" certifications.
Hire Databricks Partners IF: Your goal is AI and machine learning. You have large unstructured datasets, streaming workloads, or ML pipelines that need a lakehouse and Spark expertise. Look for relevant partner tier, industry accelerators, and named certified engineers.
The Hybrid Reality: Many enterprise data stacks use both platforms. The strongest partners can explain where Snowflake, Databricks, Unity Catalog, and open table formats such as Apache Iceberg should each own part of the architecture.
Hire a Snowflake partner for SQL-first analytics, governed self-service BI, and data sharing at scale. Hire a Databricks partner for machine learning pipelines, streaming data, and large unstructured datasets that need a lakehouse. Most enterprise data teams that use both platforms end up hiring a partner for each, since Snowflake and Databricks increasingly cover different parts of the same stack.
This guide breaks down the two partner ecosystems for leaders hiring in 2026. If you haven't picked a platform yet, start with our [Snowflake vs Databricks 2026 comparison](/snowflake-vs-databricks/) - 16 head-to-head decisions on architecture, pricing, AI/ML, and migration paths - then come back here to choose the partner.
## How do Snowflake and Databricks partner ecosystems differ?
**Snowflake partners mirror Snowflake's SQL-first, governed-BI focus: dbt, Fivetran, and Tableau/Looker skills, tuned for RBAC, SQL optimization, and data sharing. Databricks partners mirror its engineering-and-AI focus: Spark, Airflow, MLflow, and Unity Catalog skills, tuned for distributed computing and ML engineering.**
### What does a typical Snowflake partner look like?
Snowflake sells "The Data Cloud" - an appliance-like experience that just works.
* **The vibe:** Corporate, polished, SQL-centric.
* **Typical partner profile:** Focuses heavily on **dbt**, **Fivetran**, and **Tableau/Looker**. They are "Modern Data Stack" integrators.
* **Key skillset:** SQL optimization, Role-Based Access Control (RBAC), data governance, and data sharing.
### What does a typical Databricks partner look like?
Databricks sells "The Data Intelligence Platform" - a toolkit for engineering and AI.
* **The vibe:** Engineering-first, open source, Python/Scala-centric.
* **Typical partner profile:** Focuses on **Spark**, **Airflow**, **MLflow**, and **Unity Catalog**. They often come from a Big Data / Hadoop background.
* **Key skillset:** Distributed computing, Python, machine learning engineering, and CI/CD for data.
Of the 86 firms profiled in the Data Engineering Companies Index, 66 list Snowflake and 64 list Databricks as a core platform - most established data consultancies already support both, which is one reason the persona split above matters more than the platform choice alone.
---
## What partner certification tiers should you check?
**Look at the tier, not just the logo. Snowflake ranks services partners as Select, Premier, or Elite; Databricks awards Brickbuilder badges for industry-specific solutions and named "Delivery Partner of the Year" winners. Higher tiers signal more proven delivery experience, but verify references either way.**
### Snowflake partner tiers to watch
1. **Elite (top tier):** Snowflake lists Elite as its top services-partner tier. Treat it as a strong qualification signal, then verify relevant references and the named architects assigned to your project.
* *Examples:* phData, Slalom, Deloitte, Accenture.
* *When to hire:* Large-scale migrations, complex data sharing networks.
2. **Premier (mid tier):** Proven delivery capability, good for specific projects.
* *Examples:* Analytics8, Hashmap (NTT), Hakkoda.
* *When to hire:* Mid-market builds, specific dbt+Snowflake implementations.
3. **Select (entry tier):** Newer partners. Can be good value, but verify references heavily.
### Databricks partner tiers to watch
1. **Global Consulting Partners:** The large global systems integrators.
2. **Breadth vs. niche:** Databricks awards "Brickbuilder" badges for specific industry solutions (for example, "Brickbuilder for Manufacturing").
* *Pro tip:* Look for the **"Delivery Partner of the Year"** awards. These are competitive signals of actual customer success, not just sales volume.
---
## Why do open table formats like Apache Iceberg matter for hiring?
**Apache Iceberg lets data sit in an open format on S3 or ADLS that both Snowflake and Databricks can read, so you're no longer locked into hiring a partner tied to one platform. Ask any prospective partner directly how they handle Iceberg and interoperability.**
* **Old world:** Hire a partner to move data into Snowflake's proprietary format.
* **New world (2026):** Hire a partner to design an open lakehouse architecture that Snowflake can serve for BI and Databricks can process for engineering or AI workloads.
Ask prospective partners: *"What is your strategy for Apache Iceberg and interoperability?"*
* If they can't answer concretely, treat it as a warning sign.
* If they explain a unified storage layer strategy with governance, cost, and ownership tradeoffs, treat it as a promising sign.
---
## How do partner reference architectures affect your bill?
**Partners bring their own reusable reference architectures, and those choices shape your long-term bill, not just your build timeline. Snowflake partners can over-scan data and burn credits; Databricks partners can over-engineer Spark clusters that need constant DevOps upkeep. Ask about cost controls before signing.**
### Expense risk: the Snowflake partner
* **Risk:** Some partners optimize for *speed* by writing inefficient SQL that scans terabytes of data. This looks great on day one but inflates your credit consumption by day 90.
* **Audit question:** "How do you optimize for credit consumption? Do you implement resource monitors by default?"
### Expense risk: the Databricks partner
* **Risk:** They might over-engineer a solution using complex Spark clusters that require high-maintenance DevOps, when a simple SQL warehouse would have sufficed.
* **Audit question:** "Do you use serverless SQL for simple jobs, or do we need to manage cluster policies?"
---
## Which partner type fits your requirement?
| Requirement | Lean towards... | Why? |
| :--- | :--- | :--- |
| **Self-service BI for a large user base** | **Snowflake partner** | Snowflake's multi-cluster warehousing concurrency remains a strong fit for high-user BI. |
| **Complex unstructured data (audio/video)** | **Databricks partner** | Databricks' native support for unstructured data in Delta tables is stronger here. |
| **Data sharing with external vendors** | **Snowflake partner** | Snowflake's "Data Sharing" feature is one of the most mature B2B data exchange methods. |
| **Heavy Python/ML workloads** | **Databricks partner** | The notebook experience and MLflow integration are native home turf for data scientists. |
---
## Do you need a Snowflake partner or a Databricks partner?
**Snowflake partners tend to act like analytics engineers: clean models, reliable dashboards, and business logic. Databricks partners tend to act like software engineers: pipelines, latency, code abstraction, and adaptability. Most companies with both platforms eventually need both kinds of partners - start with whichever one solves your biggest immediate problem.**
If you already know which platform you need, browse [Snowflake consulting firms](/snowflake-consulting/) or [Databricks consulting firms](/databricks-consulting/) directly.
Find the Right Specialist
Use the directory to filter firm profiles by platform focus, rate band, industry experience, team scale, and fit signals.
---
## Stream processing vs batch processing: A Practical Decision Framework for 2026
Source: https://dataengineeringcompanies.com/insights/stream-processing-vs-batch-processing/
Published: 2025-12-11T07:12:41.752337+00:00
Description: Discover stream processing vs batch processing: learn when real-time data shines, when batch is enough, and how cost and latency shape your architecture.
Stream processing vs batch processing comes down to one question: does the cost of waiting for data exceed the extra engineering it takes to process that data the instant it arrives? Batch systems process data in scheduled, finite chunks; stream systems process each event as it happens. Neither is universally better - the right choice depends on how much money or risk a delay actually creates for whoever acts on the data.
Real-time streaming is also a specialist skill, not a default one. Only 15 of the 86 firms in the [Data Engineering Companies Index](/data-engineering-consulting-firms/) list streaming or Kafka work among their capabilities, which is worth checking before assuming a generalist data engineering firm can stand up a production Kafka pipeline. This guide lays out a decision framework for choosing between batch, micro-batch, and streaming, plus the cost and complexity trade-offs each one carries.
What this guide covers:
* **How to weigh the cost of data latency** against the added engineering cost of running data in real time.
* **Why micro-batching is the practical default** for most "near real-time" use cases.
* **The total cost of ownership gap** between batch and streaming, including the people cost, not just the infrastructure bill.
* **How to design a hybrid architecture** that uses batch and streaming for what each does best.
## 1. When does the added cost of streaming actually pay for itself?
Streaming is worth its added cost only when a person or a system needs to act on the data within minutes, and that action is worth real money - blocking a fraudulent transaction, adjusting a price, rerouting inventory. If nobody is going to do anything differently because the data arrived sooner, batch or micro-batch is the cheaper and simpler choice.
Map your highest-value business decisions to how fast they actually need data, not the other way around. Define freshness requirements as explicit service level objectives - for example, 99% of pricing decisions need data less than five minutes old - and build to that number instead of defaulting to real time because it sounds more advanced. A batch job that clears an hourly SLO is doing its job; upgrading it to streaming just adds cost without adding value.
### The engineering cost you can't design around
Streaming complexity doesn't go away with better tooling. Exactly-once semantics, state management, watermarking for late-arriving events, and replayability are hard distributed-systems problems that require senior engineers to build and operate correctly. Batch jobs, by contrast, are usually idempotent and simple enough for a mid-level engineer to own end to end. That gap in required skill and attention is the real driver of a streaming system's total cost, more than the cloud bill itself.
### Decision matrix for processing models
| Processing Model | Optimal Latency | Typical Use Case | Relative Cost & Complexity |
| :--- | :--- | :--- | :--- |
| **Batch Processing** | Hours to Days | Financial Reporting, ETL, ML Training | Low |
| **Micro-Batching** | Seconds to Minutes | Dashboard Refresh, Log Analytics | Medium |
| **Stream Processing** | Milliseconds to Seconds | Fraud Detection, Dynamic Pricing | High |
If your use case lands in the "High" row, you're in streaming territory and should budget accordingly. If it lands in "Low" or "Medium," start with batch or micro-batch and revisit only if the business case for speed gets stronger.
## 2. How do batch and stream processing differ architecturally?
Batch and stream processing start from different assumptions about the data itself. Batch systems work with a bounded, finite dataset that has a clear start and end; stream systems work with an unbounded, continuously growing sequence of events that never stops arriving.
### What does the batch processing model look like?
Batch is the older, more predictable model. Data accumulates in a data lake or file system over a period, and on a schedule, a processing engine like [Apache Spark](https://spark.apache.org/) reads the whole dataset, transforms it, and writes the result somewhere durable.
* **Data scope:** Large, static datasets, such as everything sold yesterday.
* **Execution:** Triggered on a schedule, like nightly at 2 AM.
* **State:** Mostly stateless. Each run is an independent execution.
* **Ideal workloads:** Financial reporting, data warehouse ETL, and training machine learning models, where completeness matters more than speed.
Systems like [Apache Hadoop](https://hadoop.apache.org/) were built specifically to process large volumes of data in discrete jobs, and that trade-off - answers only after the job finishes - is still the right one for most reporting and training workloads today.
### What does the stream processing model look like?
Stream processing is event-driven and always on. It ingests data continuously from sources like [Apache Kafka](https://kafka.apache.org/) and processes events individually or in small windows as they arrive; our guide to [streaming data platforms](/insights/streaming-data-platform/) covers how these systems are typically assembled.
The hard part is the gap between event time (when something actually happened) and processing time (when your system observed it). Late and out-of-order events are normal, not exceptional, and correcting for them requires techniques like watermarking.
Most valuable streaming jobs are also stateful. Calculating a running count of fraud flags over a five-minute window means the system has to remember prior events, not just react to the current one. That single requirement is what turns a streaming job from "read and forward" into a system that needs careful memory management, because state that isn't bounded will eventually cause out-of-memory failures and rising storage costs.
## 3. Why is micro-batching the practical default for most teams?
For most organizations, jumping straight from hourly batch to millisecond streaming is unnecessary and expensive. Micro-batching - collecting events into small windows of a few seconds to a few minutes, then processing them as a tiny batch - closes most of the latency gap without the operational weight of true continuous streaming.
Engines like [Spark Structured Streaming](https://spark.apache.org/docs/latest/structured-streaming-programming-guide.html) handle this natively: they process incoming data as a sequence of small batch jobs, which gives you near-real-time freshness while sidestepping the hardest parts of pure streaming, like complex state management.

### When is "good enough" latency actually good enough?
Micro-batching fits any use case where sub-minute freshness is fine, which covers more workloads than teams usually assume: operational dashboards, log analytics, and recommendation features all fall here. The business difference between data that's a few seconds old and data that's a few hundred milliseconds old is usually negligible - but the difference in engineering effort and cost between the two is not.
Treat micro-batching as the default for anything described as "near real-time." It captures most of the freshness benefit of streaming at a fraction of the complexity, and it's a much easier system to hire for, debug, and hand off between engineers.
## 4. What does streaming actually cost compared to batch?
Latency gets the attention, but total cost of ownership is what actually decides whether a streaming architecture is worth building. Streaming infrastructure has to run around the clock, highly available and fault-tolerant, because there's no next scheduled run to catch up on missed data - and that constant uptime shows up directly in the cloud bill.

### Where the real costs hide
The cost of streaming isn't mainly the compute instances. It's debugging out-of-order events, managing state without triggering memory failures, and guaranteeing exactly-once processing - problems that need senior engineers who cost more to hire and carry a heavier on-call load.
Batch pipelines don't have this problem. Because they're idempotent, they can be rerun safely, which makes troubleshooting straightforward enough for a mid-level engineer to handle during business hours. That personnel and support gap is a bigger driver of streaming's higher total cost than the infrastructure line item. If you're still deciding how much investment your pipelines actually need, [data integration best practices](/insights/data-integration-best-practices/) is a good place to start before committing to either model.
### Comparative cost analysis: batch vs. streaming
| Cost Factor | Batch Processing | Stream Processing | Key Consideration |
| :--- | :--- | :--- | :--- |
| **Infrastructure** | Scheduled, transient clusters; can scale to zero. | Always-on, high-availability clusters. | Streaming's constant resource allocation drives up baseline costs. |
| **Personnel** | Often maintainable by mid-level data engineers. | Requires senior or staff-level talent for state management and fault tolerance. | Higher salaries and more competition for that talent. |
| **On-Call Burden** | Low; failures can often wait until business hours. | High; requires round-the-clock monitoring and fast response. | Direct impact on team burnout and operational overhead. |
| **Debugging** | Simpler and isolated; jobs are idempotent and rerunnable. | Complex; involves timing, state, event order, and distributed systems. | Streaming issues can consume days of senior engineering time. |
Batch offers a predictable, contained cost model. Streaming adds real operational and financial weight that needs a clear, high-value business case behind it, not just a preference for "real time."
## 5. How do latency, throughput, and state interact in production?
Batch and stream processing optimize for different metrics. Batch is designed to maximize throughput on large, bounded datasets; streaming is designed to minimize latency on data that never stops arriving. A well-designed streaming system can deliver events in well under a second on modern cloud platforms, where the same insight from a batch job might take hours - but that speed comes with real engineering cost, most of it tied to state. [Data pipeline architecture examples](/insights/data-pipeline-architecture-examples/) is a useful reference for seeing these trade-offs in real designs.
### The hidden cost of stateful streaming
Low latency sounds simple until you add state. Windowed aggregations and joins require the system to remember past events, and if that memory isn't actively managed, it grows without bound. Unchecked state is one of the most common reasons production streaming deployments fail: out-of-memory errors and runaway storage bills, not bad business logic.
### How do you keep state from spiraling?
* **Set aggressive time-to-live limits.** A strict TTL on state data evicts old information automatically instead of letting it accumulate.
* **Tune your state backend.** For frameworks like [Apache Flink](https://flink.apache.org/), that means configuring the backend, commonly RocksDB, for memory allocation, caching, and compaction so performance and storage stay balanced.
Get this wrong and streaming's biggest advantage, speed, turns into its biggest liability: a system that's slow, expensive, and hard to debug at the same time.
## 6. Should you build a hybrid batch-and-streaming architecture?
At enterprise scale, the winning approach usually isn't choosing one model - it's using both for what each does best: streaming for low-latency serving, like fraud alerts or live dashboards, and batch for accuracy-critical work, like financial reporting or model training, where a corrected, complete dataset matters more than speed.
### Why a unified engine beats two separate codebases
The biggest risk in a hybrid setup is running two disconnected pipelines with separate codebases, which doubles the maintenance work and lets the two systems quietly disagree with each other over time. Unified engines like Databricks Lakeflow or Apache Flink support both batch and streaming from the same codebase, so you write the transformation logic once and run it in either mode.
That also makes the architecture easier to evolve. A pipeline that starts as a nightly batch job can move to near-real-time micro-batching later as a configuration change instead of a rewrite, if the business case for speed changes. Getting the orchestration layer right matters here - see [data orchestration platforms](/insights/data-orchestration-platforms/) for how to coordinate batch and streaming jobs without them stepping on each other.
### Design for replayability from day one
Treat your event log, such as a Kafka topic with long retention, as the source of truth. That makes backfills, bug fixes, and schema changes far less risky: a bug in your streaming logic no longer causes permanent data loss, because you can deploy the fix and replay the historical events through the corrected pipeline.
This makes batch and streaming complementary instead of competing. The streaming layer gives you immediate, provisional numbers for operational decisions, and the batch layer reprocesses the same events daily or hourly to produce the corrected, canonical version of the truth.
## Frequently Asked Questions

### When is pure stream processing actually necessary?
Pure streaming is required only when a person or an automated system has to act on an event within seconds. Real-time fraud detection, blocking a transaction before it settles, and dynamic pricing that adjusts to live demand are the clearest examples.
If the decision window is minutes rather than seconds, micro-batching is almost always the more practical choice: cheaper to run, easier to hire for, and simpler to operate. Reach for pure streaming only when the value of acting immediately clearly outweighs the added cost and complexity of running it.
### How do you migrate from a batch to a streaming architecture?
Avoid a big-bang cutover. Build the new streaming pipeline against the same source data as the existing batch job, and run both in parallel - "shadow mode" - for long enough to compare outputs and validate that the streaming logic matches the batch results.
Once you trust the streaming output and have monitoring in place, move downstream consumers over one at a time rather than all at once. This is much easier on a unified engine that supports both paradigms, since the cutover becomes a configuration change rather than a rewrite.
### What are the biggest mistakes teams make when adopting streaming?
The most common mistake is underestimating total cost of ownership. Teams focus on hitting low latency numbers and forget to budget for the senior engineering time, on-call rotations, and monitoring a production streaming system actually requires to stay reliable.
The second-biggest mistake is failing to manage state, which leads directly to runaway costs and instability. And a genuine amount of engineering time gets spent building streaming for problems that micro-batching would have solved just as well, for less money and less risk.
## Choosing the right model for your team
The decision comes down to the same question every time: is there a person or system on the other end of this data who will act differently if it arrives sooner, and is that action worth what streaming costs to run? If yes, build for it. If not, batch or micro-batch will do the job for less money and fewer late-night pages.
If you're deciding how the pipeline itself should be built once you've picked a model, [real-time data pipeline architecture](/insights/real-time-data-pipeline-architecture/) and [data pipeline monitoring tools](/insights/data-pipeline-monitoring-tools/) cover the next two decisions you'll need to make. And if you're vetting a partner to build any of this, the [data engineering firms directory](/data-engineering-consulting-firms/) is a place to start filtering by the capabilities that actually matter for your project.
---
## A Practical Guide to Streaming Data Platforms
Source: https://dataengineeringcompanies.com/insights/streaming-data-platform/
Published: 2026-01-10T09:15:53.597773+00:00
Description: A practical guide to understanding a streaming data platform. Learn core architectures, use cases, and how to choose the right tools for real-time results.
A **streaming data platform** ingests, processes, and analyzes data continuously as it's generated, instead of waiting for a scheduled batch job to load it hours later. That gap - reacting to an event in milliseconds versus querying it the next morning - is what separates real-time systems from traditional batch warehousing.
## Why Does Real-Time Processing Matter for a Business?
Historically, businesses ran on a store-then-analyze model: sales, clickstream, and log data piled up for hours or days before landing in a warehouse for reporting. That model still works for historical analysis, but it's too slow for decisions that need to happen while the event is still relevant. A streaming platform processes data in motion, so patterns get detected, events get reacted to, and personalization happens in milliseconds rather than after the fact.
### The Business Case for Streaming
Three patterns show up repeatedly across industries that adopt streaming:
* **Instant Personalization:** An e-commerce platform can process a user's clickstream in real time to immediately serve relevant product recommendations, directly impacting conversion rates.
* **Immediate Fraud Detection:** A financial institution can analyze transaction patterns as they occur, blocking a fraudulent purchase *before* it completes, rather than flagging it for review hours later.
* **Dynamic Operational Monitoring:** A logistics company can monitor vehicle and sensor data to predict maintenance needs or reroute fleets around emergent traffic issues, avoiding costly delays.
> A streaming data platform closes the gap between when an event occurs and when you can act on it. This "decision latency" is a primary competitive differentiator, where success is measured in seconds, not days.
The streaming analytics market itself reflects this shift: valued around **$23.4 billion in 2026**, it's projected to reach **$128.4 billion by 2030** - a 28.3% compound annual growth rate, according to [MarketsandMarkets](https://www.globenewswire.com/en/news-release/2023/08/17/2727181/0/en/Streaming-Analytics-Market-to-be-Worth-128-4-Billion-by-2030-Exclusive-Report-by-MarketsandMarkets.html).
### Batch Processing vs Streaming Data Platforms at a Glance
| Attribute | Batch Data Platform | Streaming Data Platform |
| :--- | :--- | :--- |
| **Data Scope** | Large, bounded datasets | Unbounded, continuous streams of events |
| **Latency** | High (minutes, hours, or days) | Low (milliseconds to seconds) |
| **Analysis** | Retrospective analysis of past events | Real-time analysis of current events |
| **Primary Use** | Historical reporting, BI dashboards | Live monitoring, alerting, instant actions |
| **Analogy** | A library for historical research | A reflex system that reacts as events happen |
The shift from batch to streaming is a transition from retrospective analysis to proactive operational control. One informs what happened; the other influences what happens next.
## What Are the Core Components of a Streaming Architecture?
**A streaming architecture has four components: ingestion (collecting raw events), processing (transforming them in flight), storage (persisting results for fast queries), and serving (delivering insights to dashboards and applications).** Each stage is typically owned by a different technology.
### The Ingestion Layer: The Data Entry Point
All data processing begins at the ingestion layer. Its function is to collect high-volume streams of raw data from diverse sources, such as application logs, user clickstreams, IoT sensor readings, and financial data feeds.
This component has to handle massive throughput without dropping data, and scale as volume grows. A standard technology for this layer is **[Apache Kafka](https://kafka.apache.org/)**, which functions as a distributed, durable commit log. It receives raw data from producers and organizes it into topics for subsequent processing.
### The Processing Engine: The Transformation Core
Once ingested, data moves to the stream processing engine. This is where real-time computation occurs. The engine consumes data streams from the ingestion layer and applies business logic, performs calculations, or enriches the data as it flows through the system.
Common operations include filtering irrelevant data, aggregating data into time windows (e.g., calculating the average transaction value over the last 60 seconds), or joining multiple streams to create a more complete contextual record.
> The core distinction from batch processing is that the query logic is applied continuously to the data in motion, rather than being executed against stored data at a later time.
Key technologies in this space include:
* **[Apache Flink](https://flink.apache.org/):** An engine known for stateful processing, enabling complex logic with very low latency.
* **[Apache Spark](https://spark.apache.org/) Streaming:** Often uses a micro-batch approach, processing events in small, discrete time windows for rapid analysis.
* **[Kafka Streams](https://kafka.apache.org/documentation/streams/):** A lightweight library that lets applications process data directly from Kafka topics without a separate processing cluster.
For a deeper look at how these pieces fit together end to end, see [data pipeline architecture examples](/insights/data-pipeline-architecture-examples/).
### The Storage Layer: The Real-Time Repository
After processing, the enriched data requires storage. While some of this data may be loaded into a system like [Snowflake](https://www.snowflake.com/en/) for long-term analysis, a streaming architecture also needs a storage layer optimized for fast queries on real-time data.
This layer must handle high-velocity writes from the processing engine and support equally fast reads to power live dashboards and applications.
### The Serving Layer: The Delivery Mechanism
Finally, the serving layer delivers the processed insights to their destination. This is the component that end-users and applications interact with directly - the real-time analytics dashboards for operations teams, the fraud alerts for financial services, the recommendation engines for e-commerce sites.
Technologies like **[Apache Druid](https://druid.apache.org/)** or **[ClickHouse](https://clickhouse.com/)** are often used here. Both are databases built to deliver sub-second query responses on large, streaming datasets. Together, these four components turn a constant flow of raw data into continuous business intelligence.
## True Streaming vs. Micro-Batch: Which Do You Need?
**True streaming processes each event the instant it arrives, at millisecond latency. Micro-batching collects events into short windows - usually a few seconds - before processing them together, trading a small delay for higher throughput and lower operational complexity.** The right choice depends on how much that delay actually costs you.
**True stream processing** (or native streaming) processes each data event individually the moment it arrives. This approach delivers latency measured in milliseconds, making it essential for use cases where every fraction of a second is critical.
**Micro-batch processing**, conversely, collects data into small batches over a short time window (typically a few seconds) and then processes each batch at once. It is significantly faster than traditional batch processing but introduces a small, inherent delay compared to true streaming.
### The Trade-Off: Latency vs. Throughput
* **Algorithmic Trading:** In financial markets, a delay of even a few milliseconds can result in significant financial loss. True streaming is required to analyze market data and execute trades at machine speed.
* **Real-Time Bidding:** In ad tech, ad placements are auctioned in the milliseconds it takes for a webpage to load. Micro-batching is too slow to compete effectively.
* **Critical Anomaly Detection:** For monitoring industrial equipment or utility grids, an immediate alert from a sensor anomaly can prevent a costly failure.
Micro-batching, however, often achieves higher throughput, since processing events in groups can be more computationally efficient. That makes it a practical choice for "near-real-time" use cases where sub-second latency isn't a strict requirement. For more detail, our guide on [stream processing vs batch processing](/insights/stream-processing-vs-batch-processing/) covers the decision in depth.
> The question is not which approach is superior, but which is appropriate for the specific business requirement. Applying true streaming to a dashboard that only needs 10-second refresh intervals is over-engineering. Using micro-batching for high-frequency trading is unviable.
### When Is Micro-Batching Good Enough?
Many business requirements are satisfied by rapid updates that don't demand millisecond-level immediacy. In these scenarios, the relative simplicity and often lower cost of a micro-batch architecture are advantageous.
Consider these common use cases:
* **Live Operational Dashboards:** An operations team monitoring website traffic or sales trends is well-served by data that refreshes every 5-10 seconds.
* **Log Analytics:** Aggregating and analyzing application logs to detect error spikes can be done effectively in small batches without impacting response time.
* **Near-Real-Time Personalization:** Updating product recommendations based on a user's recent clicks can occur within seconds and still feel instantaneous to the user.
Map your actual latency requirement to the processing model before you pick a stack - the gap between "instant" and "a few seconds" is often invisible to the end user but expensive to build for unnecessarily.
## What Business Problems Does Streaming Actually Solve?
**Four patterns account for most production streaming deployments: fraud detection, dynamic pricing, predictive maintenance, and live personalization. Each maps a real-time signal directly to a decision that has to happen before the moment passes.**

### Real-Time Fraud Detection in Finance
* **The Problem:** Financial institutions lose substantial revenue to fraud annually. Traditional batch systems detect suspicious activity hours or days later, by which time funds are lost and customer trust is damaged.
* **The Streaming Solution:** When a transaction occurs, the streaming platform ingests the data instantly. In milliseconds, it analyzes the customer's spending patterns, location, and purchase details against historical models, flagging anomalies before the transaction is approved.
* **The Bottom Line:** This proactive approach **blocks fraudulent transactions instantly**, preventing financial loss, while avoiding the false positives that come from reviewing transactions after the fact.
### Dynamic Pricing in E-Commerce
* **The Problem:** Static or manually updated pricing in e-commerce fails to capitalize on real-time market dynamics, such as a competitor's promotion, a sudden demand spike, or changing inventory levels.
* **The Streaming Solution:** By processing clickstream data, inventory levels, and competitor price scrapes in real time, a platform can continuously recalculate optimal pricing. If a competitor runs out of a popular item, the system can adjust the price upward. If an item isn't selling, it can be discounted to clear inventory.
* **The Bottom Line:** Dynamic pricing leads directly to improved profit margins and conversion rates, letting retailers respond to market shifts in real time - a capability unavailable to slower, batch-based systems.
> The core principle is to connect data directly to an outcome. Instead of analyzing what happened yesterday, the business can influence what happens in the next second.
### Predictive Maintenance in Manufacturing
* **The Problem:** Unexpected equipment failure in manufacturing causes production halts, schedule disruptions, and safety hazards. Maintenance is often reactive (fixing what's already broken) or based on fixed schedules that don't reflect actual equipment condition.
* **The Streaming Solution:** A streaming platform ingests a continuous flow of data from IoT sensors on machinery, monitoring variables like vibration, temperature, and energy consumption. Feeding these live streams into machine learning models lets the system flag subtle anomalies that predict impending failure.
* **The Bottom Line:** Predictive maintenance catches equipment problems before they cascade into a production stop, instead of after. That translates to fewer unplanned outages, lower repair costs, and a safer work environment.
### Live Customer Personalization in Media
* **The Problem:** Media and entertainment companies compete for user engagement. Generic content and irrelevant advertising lead to user churn.
* **The Streaming Solution:** A streaming platform tracks every user interaction in real time - content viewed, clicks, skips. This data instantly fuels personalized content recommendations and relevant ad serving. The live streaming market, valued at around **$100 billion in 2024**, shows the scale of this domain: platforms like Twitch depend on this infrastructure to manage analytics and monetization for millions of concurrent users, per [industry data](https://www.teleprompter.com/blog/live-streaming-statistics).
* **The Bottom Line:** Real-time personalization drives higher engagement, longer session duration, and better ad revenue. Relevant experiences build loyalty and increase customer lifetime value.
## How Do You Choose the Right Streaming Platform?
**Score candidates against your actual latency needs, ecosystem fit, total cost, and in-house skills before you look at vendor marketing - platform choice is a multi-year commitment that shapes team structure and budget, not just a technology pick.**
### Establish Your Core Evaluation Criteria
Before evaluating vendors, define your success criteria on a scorecard built from your own business and technical requirements:
* **Scalability and Elasticity:** How does the platform handle data volume spikes? Does it support automatic scaling to manage costs and performance without manual intervention?
* **Latency Guarantees:** Define your actual data freshness requirements. Is sub-second latency for critical operations necessary, or is near-real-time (a few seconds) sufficient for your use case?
* **Ecosystem Compatibility:** Verify native integrations with existing systems, particularly your data warehouse (e.g., [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/)) and BI tools that plug in without custom glue code - a core requirement of the [modern data stack](/insights/modern-data-stack/) approach.
* **Total Cost of Ownership (TCO):** Analyze costs beyond the initial license fee. Account for infrastructure, data egress, support, and the engineering resources required for maintenance.
* **Required Team Skills:** Assess whether your current team has the necessary skills in distributed systems engineering or if you'll need to hire or train personnel. Underestimating the skills gap is a common failure point.
> The optimal platform is not the one with the most features, but the one that best aligns with your team's skills, budget, and latency requirements. Over-engineering is as risky as under-provisioning.
Real-time infrastructure investment now underpins a large share of consumer-facing services, from media and gaming to payments and logistics, which is why streaming platforms have moved from a niche capability to a mainstream one.
### Right-Sizing Your Platform Approach
There are three primary approaches, and the best choice depends on your team's capabilities and project scale.
#### Streaming Platform Approach Selection Matrix
| Platform Approach | Typical Cost Band | Required In-House Skills | Best For |
| :--- | :--- | :--- | :--- |
| **DIY Open Source** (e.g., Self-hosted [Kafka](https://kafka.apache.org/) & [Flink](https://flink.apache.org/)) | $-$$ | **Deep Expertise:** Requires a dedicated team of engineers skilled in distributed systems, networking, and cluster management. | Organizations with highly specific requirements, a strong engineering culture, and the need for maximum control and customization. |
| **Cloud-Native Services** (e.g., [AWS Kinesis](https://aws.amazon.com/kinesis/), [Google Pub/Sub](https://cloud.google.com/pubsub)) | $$-$$$ | **Moderate Expertise:** Requires cloud architects and developers familiar with the specific cloud provider's ecosystem and IAM policies. | Teams already committed to a specific cloud provider who need to move quickly and offload infrastructure management for standard use cases. |
| **Managed Platform / SaaS** (e.g., [Confluent Cloud](https://www.confluent.io/confluent-cloud/), [Decodable](https://www.decodable.co/)) | $$$-$$$$ | **Low-to-Moderate Expertise:** Requires data engineers who can focus on building pipelines and business logic rather than managing infrastructure. | Companies that want the power of open-source standards like Kafka without the operational overhead, prioritizing speed-to-market and reliability. |
If you're also weighing scheduling and workflow orchestration alongside streaming, our [data orchestration platforms](/insights/data-orchestration-platforms/) comparison covers the batch side of that decision.
## Streaming Data Platform FAQ
### How Is a Streaming Platform Different from Event-Driven Architecture?
The two concepts are related but distinct.
**Event-Driven Architecture (EDA)** is an architectural pattern where software components communicate by producing and consuming events. This promotes loose coupling, allowing services to evolve independently.
A **streaming data platform** is the infrastructure that implements this pattern at scale for high-volume, real-time data flows. It consists of the technologies, like [Apache Kafka](https://kafka.apache.org/) and [Apache Flink](https://flink.apache.org/), that process continuous streams of events.
> A simple event-driven system can exist without a full streaming platform. However, a streaming data platform is inherently event-driven. The platform is the engine that enables the architectural pattern for data-intensive applications.
### How Does a Streaming Platform Fit in with Snowflake or Databricks?
A streaming platform complements, rather than replaces, systems like [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/). They work together, with real-time and historical data enriching each other in two directions:
1. **Stream to Warehouse:** The streaming platform processes events in real time and then lands the clean, structured data into a data warehouse or lakehouse. This builds a rich historical dataset for business intelligence, trend analysis, and machine learning model training.
2. **Warehouse to Stream:** The platform can also pull data *from* the warehouse to enrich real-time events. For example, as a stream of user clicks is processed, the system can fetch the customer's lifetime value from a table in Databricks to add context before triggering a personalized offer.
### What Are the Biggest Hurdles in Adopting a Streaming Architecture?
Transitioning from batch to streaming is a paradigm shift that involves operational and cultural changes. Three hurdles come up consistently:
* **The Skillset Gap:** The primary challenge is often human, not technical. It requires engineers proficient in distributed systems, stateful stream processing, and fault tolerance. Finding or training people who can work with unbounded data streams is a major consideration.
* **Data Governance and Quality:** In batch processing, there may be hours to detect and correct data quality issues. In a streaming environment, that window shrinks to milliseconds. Real-time data monitoring, schema enforcement, and automated quality checks are complex but essential for trusted output.
* **Cost Management:** Streaming platforms are "always on," which can lead to escalating cloud costs if not managed carefully. Disciplined capacity planning, effective auto-scaling policies, and continuous cost monitoring are necessary to prevent uncontrolled infrastructure spending.
Not every data engineering firm actually works with streaming systems. Of the 86 firms profiled in the [Data Engineering Companies Index](/data-pipeline/), 15 name streaming or Kafka expertise specifically - worth checking before you assume a generalist consultancy can staff a Flink or Kafka Streams build.
---
## The Engineering Leader's Guide to Supply Chain Data Platforms
Source: https://dataengineeringcompanies.com/insights/supply-chain-data-engineering/
Published: 2026-03-16T07:56:19.111578+00:00
Description: Explore expert supply chain data engineering strategies for resilient pipelines, modern architecture, and data platform selection for Snowflake and Databricks.
Supply chain data engineering is the work of replacing batch-processed, siloed analytics with pipelines that pull ERP, WMS, TMS, and IoT data together in close to real time, model it around a single source of truth, and serve it fast enough for forecasting, ETA, and inventory systems to act on. Legacy setups built for a predictable world can't do this: when a container is delayed or demand spikes, data that's a day old is already wrong, and the result is stockouts, bloated safety stock, and delivery estimates that are really just guesses.
Real-time work like this is a specialty, not a given capability every firm has. Only 15 of the 86 firms profiled in the [Data Engineering Companies Index](/retail-data-engineering/) list streaming or Kafka experience, which narrows the field fast if IoT and ETA pipelines are actually what you're hiring for. This guide covers platform architecture, the Snowflake vs. Databricks decision, data governance and MDM, the analytics use cases that pay off first, and how to evaluate a consulting partner.
## Why do legacy supply chain analytics systems fail?
Legacy analytics setups, typically pulling from a monolithic [ERP](https://www.oracle.com/erp/) or Warehouse Management System (WMS), can't keep up with the volatility of modern supply chains. That failure shows up in three places:
* **Increased Stockouts:** Inability to detect real-time demand surges means you cannot adjust inventory levels fast enough, leading to empty shelves and lost revenue.
* **Inflated Inventory Costs:** To buffer against uncertainty from poor data, you hold excess "just in case" stock. This ties up working capital and erodes profit margins.
* **Inaccurate Delivery ETAs:** Without a live, end-to-end view of logistics, delivery estimates are guesswork. This damages customer trust and operational efficiency.
The outdated flow, where siloed data sits trapped in slow, overnight batch jobs, creates the blind spots behind these failures. A modern data platform replaces it with a unified, near real-time engine, shifting the team from firefighting to proactive, data-driven decisions.
## What does a modern supply chain data platform architecture look like?
A modern supply chain data platform ingests data from your ERP, WMS, TMS, and IoT sensors, stores and transforms it in a lakehouse, and serves it to dashboards, forecasting models, and operational systems - each layer built to handle the data at the speed it actually needs to move.
### Core Architectural Layers
Your platform's architecture must handle the variety and velocity of supply chain data, selecting the right tool for each data source.
* **Ingestion:** This layer acquires the data. For structured data from SaaS platforms and databases, automated tools like [Fivetran](https://www.fivetran.com/) provide efficiency. For high-volume, real-time streams from IoT devices or logistics feeds, a streaming platform like [Apache Kafka](https://kafka.apache.org/) or a cloud-native service like AWS Kinesis is necessary.
* **Storage and Transformation:** Ingested data requires a flexible and powerful storage layer. A lakehouse architecture on a platform like [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/) is the current standard. It combines the raw storage capability of a data lake with the structured query performance of a data warehouse. Transformation is handled by tools like [dbt](https://www.getdbt.com/) (data build tool), which turns raw data into clean, analytics-ready models.
* **Serving:** This is the final layer where clean data drives decisions. It powers dashboards in BI tools like [Tableau](https://www.tableau.com/), feeds predictive demand forecasting models, or pushes insights back into operational systems to trigger automated actions.
Your team's ability to execute on this, from ingestion scripts to orchestration, determines how fast the platform goes from architecture diagram to production.
## Snowflake or Databricks: which platform fits supply chain data engineering?
The choice usually comes down to two platforms, and it isn't about which one is better in the abstract. It's about which one matches your primary objective: [Snowflake](https://www.snowflake.com/en/) for a BI-centric strategy built on partner data sharing, or [Databricks](https://www.databricks.com/) for an AI-first strategy built on custom modeling.
### Platform Comparison for Supply Chain Use Cases
[Snowflake](https://www.snowflake.com/en/) and [Databricks](https://www.databricks.com/) were built with different philosophies. Snowflake excels at SQL-based analytics and multi-enterprise data sharing. [Databricks](https://www.databricks.com/), born from Apache Spark, unifies data engineering and large-scale machine learning.
The following table provides an evaluation framework tailored for supply chain data engineering leaders.
| Criterion | Snowflake | Databricks | Leadership Recommendation |
| :--- | :--- | :--- | :--- |
| **Primary Use Case** | **BI & Analytics:** SQL-native, optimized for structured/semi-structured data analysis, reporting, and dashboarding. | **AI/ML & Data Science:** A unified platform for the entire machine learning lifecycle, from data prep to model deployment. | Choose **Snowflake** for a BI-centric strategy focused on enterprise-wide visibility. Choose **Databricks** for an AI-first strategy centered on custom modeling. |
| **Multi-Party Data Sharing** | **Best-in-Class:** Native Secure Data Sharing allows direct, secure data collaboration with suppliers, 3PLs, and retailers without data copies or ETL. | **Good (Open Standard):** Delta Sharing is an open protocol for sharing data, but lacks the integrated governance, marketplace, and ease-of-use of Snowflake's feature. | For building a collaborative data ecosystem with external partners, **Snowflake** holds a significant architectural advantage. |
| **Ease of Use & Adoption** | **Very High:** Its fully managed service and familiar SQL interface reduce the barrier to entry for analysts and data-savvy business users. | **Moderate to High:** Requires specialized engineering skills (Spark, Python/Scala). The learning curve for non-engineers is steeper. | **Snowflake** enables faster time-to-value for teams with strong existing SQL skills. |
| **Unstructured Data & ML** | **Improving:** Snowpark and native unstructured data support are advancing but are not the platform's core strength. Best for consuming ML outputs. | **Excellent:** The Lakehouse architecture is purpose-built to handle raw, unstructured data (images, text, sensor data) at scale for training ML models. | For advanced ML on diverse data types (e.g., computer vision for warehouse automation), **Databricks** is the superior choice. |
| **Cost Model & Governance** | **Usage-Based:** Separates storage and compute costs. This offers flexibility but requires diligent cost management to avoid unexpected bills. | **Usage-Based (DBUs):** Priced on Databricks Units (DBUs), which can be complex to forecast and optimize without deep expertise. | Both require strong governance. Snowflake's model is generally easier for finance and operations teams to understand initially. |
The decision hinges on your strategic center of gravity. For organizations prioritizing a collaborative data hub for reporting and visibility across a partner network, **Snowflake** is the path of least resistance. Its data sharing capability is a meaningful advantage for supply chain ecosystems that depend on moving data across company lines.
Conversely, for organizations whose strategy relies on building proprietary, large-scale ML models using diverse data sets (e.g., predicting port congestion from satellite imagery), **Databricks** is the purpose-built platform. It provides a unified workspace for data engineers and data scientists to collaborate on complex AI applications.
The strategic question underneath this choice, storing data in a warehouse built for structured analytics versus a lake built for raw and unstructured data, is covered in more depth in [data warehouse vs. data lake](/insights/data-warehouse-vs-data-lake/).
## What data modeling and governance does supply chain analytics need?
Supply chain analytics needs two things working together: dimensional modeling to organize fact and dimension tables for fast querying, and Master Data Management (MDM) to create one authoritative record per product, customer, supplier, and location. Without MDM, "Supplier X, Inc." in one system and "SuppX" in another get treated as different entities, and a basic question like total spend with a given supplier becomes unanswerable.
### Data Modeling and MDM
For supply chain analytics, **dimensional modeling** remains the most effective structure. It organizes data into "fact" tables (the numbers: order quantities, shipping costs) and "dimension" tables (the context: product, customer, location, time). This structure is highly optimized for fast querying by BI tools.
**Master Data Management (MDM)** is not optional. Core business entities like `Product`, `Customer`, `Supplier`, and `Location` exist in dozens of disconnected systems. MDM's objective is to create a single, authoritative "golden record" for each, establishing the source of truth an enterprise-wide view depends on.
### A Phased Framework for Data Governance
Implementing a massive, top-down governance plan is a recipe for failure. A pragmatic, phased approach delivers value quickly and builds organizational momentum.
1. **Phase 1: Assign Ownership & Establish Baselines.** Assign clear owners for critical data domains (e.g., `Product`, `Logistics`). Implement automated data quality checks within your pipelines to measure completeness, accuracy, and timeliness. You cannot improve what you do not measure.
2. **Phase 2: Implement Access Controls.** Define and implement role-based access controls (RBAC) to ensure users only access data relevant to their function. This is essential for securing sensitive commercial data and ensuring regulatory compliance.
3. **Phase 3: Automate & Scale.** Embed governance rules directly into your data pipelines using tools like [dbt](https://www.getdbt.com/). This transitions governance from manual spot-checks to automated, preventative enforcement, ensuring all new data conforms to standards from the moment of ingestion.
See [data governance best practices](/insights/data-governance-best-practices/) for a fuller framework behind these three phases.
## Which analytics and ML use cases deliver the most value?
Data engineering earns its return by moving supply chain analytics from descriptive reporting (what happened) to predictive and prescriptive use cases: demand forecasting that blends external signals, real-time ETA prediction from IoT and TMS feeds, and digital twins that stress-test the network before a disruption hits.
### Predictive Demand Forecasting
Traditional forecasting based on historical sales is insufficient. A modern approach integrates external signals, including weather data, economic indicators, social media trends, and competitor promotions, to build a more accurate picture of future demand.
* **Engineering Requirement:** Building reliable pipelines to ingest, clean, and integrate messy, diverse external data sources. The engineering team must also build a feature store to make these signals (e.g., a specific weather pattern) reusable across multiple ML models. Platforms like [Databricks](https://www.databricks.com/) are a natural fit due to their strength in handling unstructured data and integrated ML tooling.
### Real-Time ETA Prediction and Inventory Visibility
This use case provides live answers to two critical questions: "Where is my inventory?" and "When will it arrive?" It fuses real-time GPS data from Transportation Management Systems (TMS) and IoT sensors with external data on traffic, weather, and port congestion to calculate an accurate Estimated Time of Arrival (ETA).
* **Engineering Requirement:** The platform must support low-latency stream processing to analyze data as it arrives. This requires expertise in streaming technologies like [Apache Kafka](https://kafka.apache.org/) or [Amazon Kinesis](https://aws.amazon.com/kinesis/). See [stream processing vs. batch processing](/insights/stream-processing-vs-batch-processing/) for how to decide which parts of the pipeline actually need to run in real time.
### Network Optimization with a Digital Twin
A digital twin is a virtual simulation model of your entire supply chain network. It allows you to run "what-if" scenarios to stress-test your network's resilience against disruptions, such as a supplier shutdown, a blocked shipping lane, or a labor strike, before they occur.
* **Engineering Requirement:** The primary challenge is not the simulation itself, but the creation and maintenance of the complex, interconnected data model that mirrors physical reality. This is where Master Data Management (MDM) matters most. An inaccurate data foundation renders the digital twin useless.
## How do you evaluate a supply chain data engineering consulting partner?
A qualified partner combines platform depth, verifiable supply chain domain experience, delivery discipline, and transparent rate cards. Test each with a specific question rather than trusting a capabilities slide deck.
### 1. Technical Depth and Platform Expertise
A qualified partner must have demonstrable experience across both streaming (e.g., [Apache Kafka](https://kafka.apache.org/), [Amazon Kinesis](https://aws.amazon.com/kinesis/)) and batch processing architectures. According to analysis by [DataEngineeringCompanies.com](https://dataengineeringcompanies.com/) of 86 data engineering firms, top-tier consultancies provide architectural blueprints from past projects on platforms like [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/). Ask for them.
**Vetting Question:** "Show us an anonymized architecture diagram for a supply chain client where you integrated real-time logistics data with batch ERP data. Explain your choice of ingestion tools and transformation logic."
### 2. Verifiable Supply Chain Domain Experience
Pure technical skill is insufficient. The partner must understand the nuances of supply chain data: the complexities of EDI feeds, TMS and WMS schemas, and metrics like inventory turns and landed cost.
**Vetting Question:** "Describe a project where you had to build a master data model for 'Product' using data from a client's ERP, PIM, and WMS. What were the biggest data quality challenges and how did you resolve them?"
### 3. Delivery Discipline and Methodology
A vague project plan is a major red flag. The firm must operate with an agile methodology, clear sprint definitions, and transparent progress reporting.
**Vetting Question:** "Walk us through your process for managing a two-week sprint. What artifacts do you produce? How do you handle scope change or unforeseen technical debt discovered mid-sprint?"
### 4. Cost-Effectiveness and Rate Benchmarks
Focus on total cost of ownership and value, not the lowest hourly rate. An inexperienced, low-rate team often costs more in the long run due to rework and delays. A reputable partner provides transparent rate cards and realistic project cost forecasts tied to business value delivered.
**Vetting Question:** "Provide your rate card for the roles you propose for this project (e.g., Principal Data Engineer, Senior Consultant). What is your estimated timeline and cost for a 12-week MVP to establish a foundational data pipeline and two key BI dashboards?"
## What are the first steps for engineering leaders to take?
Start with a rapid, honest data maturity assessment across four questions: integration, latency, source of truth, and analytics capability. Then translate the gaps into a business case tied to P&L impact, not technical tasks.
### 1. Conduct a Rapid Data Maturity Assessment
Before charting a course, establish your baseline. This is not a formal audit but a rapid, honest assessment. Convene your team and answer these questions:
* **Data Silos:** What is our "integration" between the ERP, WMS, and TMS? Is it an API or a manual CSV export?
* **Data Latency:** Is the data used for critical operational decisions hours, days, or weeks old? What is the business impact of that delay?
* **Source of Truth:** If we ask three different teams for "on-time delivery performance," do we get three different numbers from three different reports?
* **Analytics Capability:** Are our analytics limited to historical reporting, or do we have any predictive capabilities in production?
The answers will define your problem statement and form the basis of your business case.
### 2. Build the Business Case and Assemble the Team
Frame the initiative in terms of business outcomes, not technical tasks. Connect platform investment directly to P&L impact. For example: "A 10% reduction in inventory carrying costs through improved forecasting," or "A 15% reduction in expedited freight spend through real-time shipment tracking."
The most powerful question to answer for the C-suite is: **"What is the cost of doing nothing?"** Quantify the financial impact of stockouts, excess safety stock, and manual reporting that your current state is already costing the business.
Simultaneously, prepare your organization for the required talent. Equip hiring managers with interview questions that specifically test for the skills needed to build these systems. When vetting partners, challenge them on their direct experience with messy supply chain data - their answers will quickly distinguish true experts from generalists.
***
Supply chain data engineering rewards specificity over generalist claims. [DataEngineeringCompanies.com](https://dataengineeringcompanies.com/) profiles firms by platform, capability, and industry vertical - browse the [data engineering consulting firms directory](/data-engineering-consulting-firms/) or the [retail data engineering hub](/retail-data-engineering/) to find partners who have actually built ERP-to-lakehouse pipelines, not just ones who say they can.
---
## US vs Offshore Data Engineering: Onshore, Nearshore, and Hybrid Decision Guide
Source: https://dataengineeringcompanies.com/insights/us-vs-offshore-data-engineering/
Published: 2025-12-19T00:00:00.000Z
Description: Compare onshore, nearshore, offshore, and hybrid data engineering models by work ambiguity, collaboration, data access, delivery controls, and total cost of ownership.
Decision in one sentence
Choose delivery geography by work shape, not hourly rate. Keep ambiguity, architecture decisions, and sensitive-data access close to the people who own the outcome. Move repeatable implementation to nearshore or offshore teams only when interfaces, review gates, and handoff are explicit.
This guide helps engineering and procurement leaders choose between onshore, nearshore, offshore, and hybrid data engineering delivery. It is a decision framework, not a ranking of countries or a list of “best” vendors.
Geography changes time-zone overlap, employment and data-access constraints, communication cost, and the shape of the contract. It does not determine engineering quality by itself. A senior offshore team with clear interfaces can outperform an onshore team with weak ownership; the buyer has to design the operating model that makes quality observable.
The rate calibration below uses the current rate fields in the [Data Engineering Companies directory](/data-engineering-consulting-firms/). The August 6, 2026 local snapshot ranged from $45 to $250 per hour, but it is a selected vendor dataset, not a regional wage survey. Recheck the live profiles before budgeting.
## Which delivery model fits your data engineering work?
The right delivery model depends on four variables: requirement ambiguity, time-zone overlap, data sensitivity, and the strength of the internal architecture owner. Onshore favors discovery and decision density; nearshore favors daily collaboration; offshore favors repeatable execution; hybrid separates architecture from capacity.
Start by classifying the work before comparing locations:
1. **Discovery and architecture:** Business rules are still changing, the data model is unsettled, or several executives must agree on scope.
2. **Platform implementation:** The target architecture is approved, interfaces are known, and the team needs to build pipelines, models, tests, and infrastructure.
3. **Run-state operations:** The platform needs monitoring, incident response, cost control, and predictable changes after launch.
One initiative can contain all three. Put discovery and architecture with the people who can resolve ambiguity, then move well-specified implementation to the delivery model that can meet the control and overlap requirements.
## How do onshore, nearshore, offshore, and hybrid models compare?
Onshore, nearshore, and offshore teams trade collaboration and control against staffing flexibility and sticker price. The comparison below describes operating conditions, not a quality ranking: every model depends on senior ownership, explicit interfaces, and measurable acceptance criteria.
| Model | Best fit | Main advantage | Main cost or risk | Minimum control |
| :--- | :--- | :--- | :--- | :--- |
| **Onshore** | Discovery, architecture, stakeholder-heavy change, or sensitive work | High working-hour overlap and fast business-context transfer | Usually the highest labor rate | Named decision-maker, clear scope, and the same delivery controls used for any partner |
| **Nearshore** | Iterative delivery that needs daily collaboration with a US-based team | More working-hour overlap than offshore with a broader staffing pool than local-only hiring | Regional availability, language, and seniority vary by provider | Contracted overlap hours, escalation path, role mix, and platform-specific technical screening |
| **Offshore** | Documented migrations, repeatable pipeline builds, testing, and defined support queues | Flexible capacity and lower listed starting rates in many vendor profiles | Async clarification, handoff failure, and wider access-control complexity | Internal architecture owner, written interfaces, protected code review, observability, and a tested handoff |
| **Hybrid** | Programs that need local decision density and distributed implementation capacity | Separates architecture leadership from execution capacity | More than one team boundary to coordinate | A RACI, one backlog, one source of truth, shared acceptance criteria, and explicit escalation rules |
Nearshore does not automatically mean “better offshore.” It means the time-zone and collaboration trade-off is different. Use the [nearshore company shortlist](/insights/nearshore-data-engineering-companies/) only after you know whether your program needs a platform specialist, an embedded team, or a managed outcome.
## What does current rate data actually tell you?
Directory rate fields can establish a budget screen, but they cannot prove that a region is cheaper or better. On August 6, 2026, the local directory snapshot showed listed starting rates from $45 to $250 per hour; use those values to challenge a proposal, then validate role mix, minimums, and deliverables.
| Listed starting-rate band | Use it as a screening question |
| :--- | :--- |
| **$45–$99/hr** | What senior architecture, review, and delivery-management time is included, and how much internal supervision will the team need? |
| **$100–$199/hr** | Which roles are actually assigned to the work, and is the premium buying platform depth, faster decisions, or a stronger operating model? |
| **$200+/hr** | What decision, risk, or specialist capability justifies the premium, and what measurable outcome will it protect? |
These are directory bands, not regional benchmarks. A vendor can use a blended team, subcontractors, or a different role mix behind the same starting rate. The [data engineering consulting rates guide](/insights/data-engineering-consulting-rates-2026/) covers the wider rate and engagement-model question; this page uses rates only to compare geography and delivery risk.
Ask every finalist for:
- the rate and expected hours for each role;
- the percentage of time assigned to architecture, engineering, QA, project management, and support;
- the minimum project size and change-order rules;
- the location of each assigned person and the working-hour overlap;
- the deliverables that remain with you when the engagement ends.
## When does a lower hourly rate become a higher total cost?
A lower hourly rate becomes a higher total cost when coordination, rework, delay, security review, or transition effort consumes the saving. Compare the price of an accepted outcome, not the price of an hour: TCO equals vendor fees plus internal coordination, rework, delay, security and procurement, and transition costs.
| Cost driver | What to measure before signing |
| :--- | :--- |
| **Coordination** | Internal hours spent clarifying requirements, reviewing work, resolving handoffs, and attending status meetings |
| **Rework** | Defects, rejected models, failed tests, and changes caused by unclear business rules or interfaces |
| **Delay** | The date when the platform, pipeline, or dataset becomes usable—not the date the first code is committed |
| **Security and procurement** | Data-processing reviews, access provisioning, audit evidence, legal work, and subprocessor approval |
| **Transition** | Runbooks, paired delivery, training, shadowing, backfill planning, and removal of vendor access |
This is why a low blended rate can be misleading. A team that needs constant internal correction has transferred work back to your organization. A higher rate can be rational when it buys a named architect, faster decisions, or a shorter path to an accepted production result. Ask vendors to show their assumptions; do not accept a percentage-saving claim without them.
## How should you control data access and cross-border risk?
Treat team location as a data-access and supplier-risk decision. The European Commission lists safeguards for personal data leaving the EEA, HHS requires a BAA when a cloud service provider handles ePHI on behalf of a covered entity, and NIST recommends supplier criticality based partly on data sensitivity and system access. Apply legal review to the facts of your project.
The [European Commission’s international-transfer guidance](https://commission.europa.eu/law/law-topic/data-protection/international-dimension-data-protection/rules-international-data-transfers_en) describes safeguards such as adequacy decisions, standard contractual clauses, binding corporate rules, certification, codes of conduct, and limited derogations. The [HHS cloud-computing guidance](https://www.hhs.gov/hipaa/for-professionals/special-topics/health-information-technology/cloud-computing/index.html) says a CSP can be a HIPAA business associate even when it stores encrypted ePHI without the decryption key, and that overseas storage belongs in the required risk analysis. The [NIST CSF 2.0 supply-chain guide](https://tsapps.nist.gov/publication/get_pdf.cfm?pub_id=958604) recommends identifying supplier criticality, documenting roles, and communicating requirements to suppliers.
Before granting access, document:
1. **Data boundary:** Which datasets, environments, fields, and logs can each role access? Use masked, synthetic, or least-privilege data where production access is not necessary.
2. **People location and compute location:** Record where personnel can log in from and where data is stored or processed. A US cloud region does not, by itself, describe remote human access.
3. **Transfer and processing terms:** Identify the applicable data-processing agreement, transfer mechanism, BAA, retention rule, and subprocessor approval path. This is a procurement checklist, not legal advice.
4. **Identity and evidence:** Require MFA, named accounts, time-bounded access, audit logs, access reviews, and a documented incident-notification path.
5. **Exit conditions:** Define return or deletion of data, revocation of credentials, transfer of documentation, and the evidence you receive at termination.
Do not use “HIPAA,” “GDPR,” or a security certification as a substitute for an access design. The contract, identity controls, data boundary, and operational evidence have to match the work.
## What should the delivery contract require?
A distributed data engineering contract should make ownership, change control, quality, and exit testable. Require one accountable architecture owner, one shared backlog, explicit acceptance criteria, protected code review, versioned data interfaces, production observability, and a handoff that your team rehearses before the vendor leaves.
Use these controls in the statement of work:
1. **Decision rights:** Name the person who approves architecture, data-model changes, security exceptions, and production releases. Document what the vendor can decide without approval.
2. **Working agreement:** Set required overlap hours, response targets, escalation rules, meeting cadence, and the handoff format for work that crosses time zones.
3. **Repository controls:** Keep code and infrastructure in your repositories. Require pull-request review and status checks before merges; [GitHub protected branches](https://docs.github.com/en/repositories/configuring-branches-and-merges-in-your-repository/managing-protected-branches/about-protected-branches) support required reviews, code-owner approvals, and required checks.
4. **Data interfaces:** For shared dbt models, use [model contracts](https://docs.getdbt.com/docs/mesh/govern/model-contracts) where the adapter and materialization support enforcement. Contracts define column names and types and can fail a build when the declared shape does not match the result.
5. **Breaking-change policy:** Use [dbt model versions](https://docs.getdbt.com/docs/mesh/govern/model-versions) or an equivalent interface policy for breaking changes. Set a deprecation date and migration window instead of forcing every downstream consumer to react without notice.
6. **Acceptance criteria:** Define the tests, freshness, completeness, performance, security evidence, documentation, and business sign-off required for each deliverable. Do not accept “pipeline completed” as an outcome.
7. **Run-state ownership:** Assign observability, incident response, on-call coverage, cost review, and bug-fix responsibility after go-live. Include runbooks and a support transition date.
8. **Exit and continuity:** Require documentation in your repository, paired delivery with internal engineers, named backups for critical roles, credential revocation, and a final knowledge-transfer exercise.
These controls make a distributed team auditable. They also make vendor comparison fairer: every finalist answers against the same operating contract.
## Which model should you choose?
Choose onshore when ambiguity and stakeholder access dominate; choose nearshore when daily collaboration matters and the architecture is reasonably clear; choose offshore when requirements are stable and an internal owner can enforce controls; choose hybrid when the work needs local decisions and distributed capacity.
| Your situation | Default starting point | Why |
| :--- | :--- | :--- |
| Requirements change weekly and business rules are still being discovered | **Onshore lead or team** | Fast context transfer reduces clarification delay while the problem is being defined |
| Architecture is approved and the team needs daily working-hour overlap | **Nearshore** | The delivery team can collaborate in the same workday without requiring a local-only staffing model |
| Work is repeatable, documented, and testable; an internal architect owns decisions | **Offshore or hybrid delivery** | The team can execute against stable interfaces while governance stays close to the owner |
| Data access is regulated or cross-border transfer is restricted | **Approved location model with masked data where possible** | The data boundary and legal basis determine the feasible staffing pool |
| A complex program needs architecture leadership and parallel implementation capacity | **Hybrid** | Separate the decision bottleneck from the repeatable build work without splitting accountability |
Use the [data engineering partner selection framework](/insights/data-engineering-partner-selection/) to evaluate a finalist after you have chosen the delivery model.
## What should you ask before signing?
A credible partner should answer the same operational questions as every other finalist: who decides, who accesses data, who reviews changes, who owns production, and what remains after exit. If the proposal answers only with geography, certifications, or a blended rate, it has not described delivery risk.
1. Who is the named architecture owner, and can I meet the people assigned to the work?
2. Which hours overlap with our team, and what happens when a blocker arrives outside that window?
3. What percentage of the budget goes to senior engineering, architecture, QA, project management, and support?
4. Which people, countries, environments, and data fields will have access?
5. What review gates, tests, contracts, runbooks, and acceptance criteria are included?
6. How are breaking changes approved, communicated, versioned, and retired?
7. What documentation and paired-delivery work is complete before handoff?
8. How are backfills, subcontractors, incidents, and credential revocation handled?
Use the answers to compare operating models—not to label one geography as universally superior. Review volatile rates, privacy requirements, platform capabilities, and vendor staffing again before the next procurement cycle.
Ready to compare data engineering partners?
Use the directory to compare firms by rate, platform, industry, and fit after you have chosen the delivery model.
*Review note: rates and vendor availability change. This page was refreshed on August 6, 2026. The cited HIPAA, data-transfer, cybersecurity, dbt, and GitHub sources describe their own frameworks and controls; confirm the legal and technical application with the responsible counsel and security owners.*
---
## 10 Actionable Vendor Management Best Practices for Data Engineering in 2026
Source: https://dataengineeringcompanies.com/insights/vendor-management-best-practices/
Published: 2026-01-01T09:17:05.916549+00:00
Description: Discover 10 actionable vendor management best practices for data engineering. Get practical insights on RFPs, SLAs, cost control, and risk reduction.
Vendor management for data engineering comes down to five disciplines: score candidates on a weighted framework before the RFP goes out, hold every finalist to the same rigorous RFP, track SLAs and delivery metrics once the contract is signed, keep pricing transparent and benchmarked against the market, and plan the exit before you need one. Skip any of these and a promising partnership turns into scope creep, a missed SLA nobody can enforce, or a vendor you can't get out of.
Rate cards vary widely across the market. Among the 86 firms in the [Data Engineering Companies Index](/data-engineering-consulting-firms/), hourly rates run $45 to $250, with a median around $100 - 35 firms bill under $100/hr, 44 sit between $100 and $200, and 7 charge $200 or more. That spread alone is a reason to benchmark before you negotiate, not after. See the [2026 rate guide](/insights/data-engineering-consulting-rates-2026/) for how those bands break down.
This guide covers ten practices for selecting, contracting with, and managing a data engineering vendor, plus a comparison table for weighing them against each other.
What this guide covers:
* **Selection and RFP discipline** for choosing the right partner before signing a contract.
* **Performance tracking and SLA enforcement** once the vendor is live.
* **Cost transparency and rate benchmarking** to keep budgets predictable.
* **Risk management and exit planning** so no single vendor becomes a single point of failure.
## 1. What should a vendor evaluation framework score before you talk to a single vendor?
A vendor evaluation framework should score technical capability, industry expertise, delivery track record, and AI/ML readiness - weighted and agreed internally before any vendor conversation starts, so the comparison stays defensible instead of a reaction to whoever pitches best.
Rushing past this stage is what produces misaligned scope, budget creep, and a re-platforming project eighteen months later. A weighted scorecard removes the guesswork: instead of a gut call after a good demo, you get a documented, comparable score for every finalist.
### Core Evaluation Pillars for Data Engineering Vendors
A useful evaluation framework checks vendors across a few dimensions specific to data engineering work:
* **Technical Capabilities:** Depth of experience on your target platforms - Snowflake, Databricks, or Google Cloud - plus pipeline orchestration (Airflow, Dagster), data modeling, and lakehouse architecture.
* **Industry & Domain Expertise:** A vendor who already understands your industry's specific constraints (healthcare compliance, financial services reporting) delivers value faster than one learning your domain on your dime.
* **Scalability & Delivery Quality:** Case studies and reference calls that verify the vendor has actually run projects at your scale, not just described the methodology.
* **AI/ML Enablement:** Whether the vendor can build data foundations that support MLOps and generative AI work, not just move data from one place to another.
> **Pro-Tip:** Weight the criteria to match the project. An AI-driven transformation might weight "AI/ML Enablement" at 35%; a straightforward cloud migration might weight "Technical Capabilities" and "Delivery Quality" at 30% each.
A formal scoring framework turns vendor selection into a repeatable process instead of a one-off decision. See [how to choose a data engineering company](/how-to-choose-data-engineering-company/) for a fuller evaluation model.
## 2. What does a rigorous data engineering RFP need to ask for?
A data engineering RFP needs to force every finalist to answer the same detailed questions on technical approach, team structure, pricing, and support model - identical questions produce comparable answers, which is what actually lets you score vendors instead of just liking one better.
A good RFP goes past surface-level questions about tools and probes how a vendor actually operates. Every finalist answering the same structured question set is what turns the selection into a scored comparison instead of a sales pitch contest.
### Key Components of a Data Engineering RFP
* **Technical & Platform Proficiency:** Their experience with your specific stack (Snowflake, Databricks, AWS, GCP), and their approach to data modeling, ETL/ELT development, and quality assurance in that environment.
* **Methodology & Team Structure:** Project management approach (Agile, Scrum), typical team composition at your scale, and their QA and testing protocols.
* **Commercial & Cost Structure:** Full transparency on pricing - day rates by role, retainer options, and how change requests get priced.
* **Governance & Support Models:** Post-launch support terms, incident-response SLAs, and experience implementing governance frameworks like GDPR or CCPA - an area vendors often gloss over until it's contract time.
> **Pro-Tip:** Separate mandatory requirements from "nice-to-have" capabilities in the RFP itself. It speeds scoring and filters out vendors that don't meet your core needs before you spend time on deeper evaluation.
A disciplined RFP process produces the comparative, documented data an informed decision needs. The [data engineering RFP checklist](/data-engineering-rfp-checklist/) has a fuller set of questions to pull from.
## 3. Which vendor performance metrics actually catch problems before they escalate?
Track a balanced set across service delivery, code quality, business impact, and security - leading indicators like code review velocity and test coverage catch problems weeks before lagging indicators like uptime would show them.
Translate business goals into specific, contract-embedded targets and review them regularly - that's what turns vendor management from subjective status updates into a fact-based read on the relationship's health.
### Core Metrics for Data Engineering Engagements
* **Service Delivery & Availability:** Pipeline uptime, migration milestone adherence, and support response times for critical incidents.
* **Data & Code Quality:** Test coverage, pull request resolution time, and the rate of post-deployment bugs or data quality incidents.
* **Business Impact & Efficiency:** Query performance improvements, new analytics use cases enabled, and cost-to-serve for the platform.
* **Security & Compliance:** Vulnerabilities identified and remediated within a set window, and pass rate on compliance audits.
> **Pro-Tip:** Don't only track lagging indicators like uptime. Code review velocity and test coverage trends often predict a performance problem before it shows up in a dashboard.
Tracking these metrics consistently gives quarterly business reviews something to actually discuss, and gives you a documented basis for a renewal or termination decision.
## 4. Why spread work across multiple vendors instead of using one?
A single vendor for every data need creates dependency risk and removes any competitive pressure on price or quality - splitting work by specialty (a Snowflake migration specialist, a separate Databricks ML team, a governance-focused firm) keeps you from being stuck if one relationship sours.
A portfolio approach means deliberately assigning different vendors to different parts of your data estate instead of handing everything to one generalist. That avoids lock-in and keeps the best-fit team on each specific problem.
### Core Pillars of a Diversified Vendor Strategy
* **Platform Specialization:** A certified Databricks partner for the lakehouse build, a separate boutique for BI dashboard work - each vendor working where they're actually strongest.
* **Service Line Distinction:** A global systems integrator for a multi-year cloud migration, a smaller consultancy for a fast, focused analytics project.
* **Risk Mitigation:** Spreading mission-critical pipeline work across more than one qualified vendor limits the damage if one vendor gets acquired, pivots, or simply underperforms.
* **Access to Niche Skills:** A specialized AI firm for a generative AI pilot, without disrupting the vendor running your core data warehousing.
> **Pro-Tip:** Build a vendor portfolio map showing each partner's responsibilities, platform ownership, and dependencies on the others. Review it quarterly for concentration risk and gaps.
Treating vendors as a portfolio rather than a single relationship is what makes a data organization resilient to any one partner's problems.
## 5. How do you keep vendor pricing transparent instead of getting surprised by it?
Insist on itemized rate cards by role and seniority, calculate total cost of ownership rather than just the hourly rate, and benchmark against the market at least once a year - rates for the same seniority level vary widely between firms, so a single quote tells you almost nothing on its own.
Rates vary by skill level, platform specialization, and geography - the goal isn't the cheapest vendor, it's a fair rate for the expertise the project actually needs.
### Key Components of Financial Governance
* **Detailed Rate Cards:** Costs broken down by role and seniority - Data Architect, Senior Data Engineer, ML Engineer, Data Analyst - not a single blended number.
* **Total Cost of Ownership:** Tooling, platform consumption, and contingency budget on top of the hourly rate, not instead of it.
* **Regular Market Benchmarking:** Compare rates against industry reports or a directory that tracks data engineering pricing before a renewal, not after you've already signed.
* **Volume and Term Incentives:** Negotiate reduced rates for retainers, volume discounts for larger teams, or fixed pricing for multi-year commitments.
> **Pro-Tip:** During the RFP, ask vendors to model the cost of a sample project using their actual proposed team and rate card. It turns an abstract rate sheet into a real number you can compare apples-to-apples.
Rate transparency and regular benchmarking keeps a vendor budget from becoming a surprise line item at renewal time. The [2026 data engineering rate guide](/insights/data-engineering-consulting-rates-2026/) breaks current market rates down by role.
## 6. What does a data engineering vendor contract need to cover?
A data engineering contract needs explicit terms on data security and compliance, IP ownership, SLAs with remedies, and an exit and transition plan - a Master Service Agreement plus detailed Statements of Work is the baseline, not boilerplate legal language reused from an unrelated engagement.

Codifying data security protocols, IP ownership, and dispute resolution up front prevents disputes later, and gives the vendor an unambiguous standard to deliver against.
### Core Components of a Data Engineering Contract
* **Data Security & Compliance:** Required certifications (SOC 2 Type II), adherence to GDPR or CCPA, encryption standards, and breach notification terms.
* **IP Ownership:** Explicit language that all deliverables - custom code, data models, pipeline configurations - belong to your organization, not the vendor.
* **SLAs:** Measurable targets for pipeline uptime, data latency, and support response, with service credits attached for missed targets.
* **Exit & Transition Plan:** A defined knowledge-transfer period, documentation handoff, and secure data deletion terms if the relationship ends.
> **Pro-Tip:** Standardize the MSA to speed up contracting for new projects, but customize each SOW with the specific deliverables, timelines, and acceptance criteria for that engagement.
Treating contract management as a strategic function rather than a legal formality is what makes it enforceable later. [Data governance best practices](/insights/data-governance-best-practices/) covers the related discipline of data stewardship in more depth.
## 7. What communication cadence actually keeps a vendor relationship aligned?
A tiered cadence works best: weekly technical standups, bi-weekly sprint planning, monthly status reviews for stakeholders, and quarterly business reviews for executives - each with a distinct audience and agenda, so information reaches the right people without burying anyone in meetings.
A breakdown in communication is behind most vendor relationship failures - misaligned priorities, missed deadlines, and budget overruns nearly always trace back to something that should have surfaced in a status meeting and didn't.
### A Cadence-Based Communication Framework
* **Weekly Standups:** Short, tactical 30-minute syncs between the technical teams - progress against the current sprint and immediate blockers, nothing more.
* **Bi-Weekly Planning:** A deeper session reviewing the upcoming sprint backlog and flagging dependencies or risks before work starts.
* **Monthly Status Reviews:** For project managers and business stakeholders - performance metrics, budget consumption, and progress against the roadmap.
* **Quarterly Business Reviews:** Executive leadership from both sides discussing partnership health, strategic alignment, and renewal terms.
> **Pro-Tip:** Document decision rights in an escalation matrix. A technical lead can approve a minor scope change within a sprint; a budget increase over a set threshold needs sign-off from a director during the monthly review.
A formal communication framework flags risks early and keeps decisions with the right stakeholders instead of stuck in someone's inbox.
## 8. How do you transfer knowledge from a vendor instead of staying dependent on them?
Write knowledge transfer into the SOW as a mandatory deliverable with acceptance criteria - documentation, training commitments, and pair-programming - and staff internal engineers to shadow the vendor team directly, because passive documentation alone rarely builds real internal capability.

Planning for the vendor's eventual departure from day one is what prevents the alternative: permanent reliance on one partner for basic operations.
### Core Pillars of an Effective Knowledge Transfer Strategy
* **Contractual Mandates:** The SOW should explicitly require documentation (architecture diagrams, data dictionaries, runbooks), training sessions, and pair-programming commitments.
* **Active Team Participation:** Dedicated internal engineers who shadow and work directly alongside the vendor team - passive observation doesn't transfer much.
* **Structured Mentorship:** Junior engineers pair-programming with the vendor's senior architects; for a Snowflake migration, the vendor training your DBAs on performance tuning directly.
* **Phased Transition:** A post-project advisory retainer where the vendor provides on-call support while your team takes over full ownership.
> **Pro-Tip:** Tie final payment to sign-off on the knowledge transfer plan - for example, your internal team independently resolving a set number of production issues using only vendor-provided documentation.
Knowledge transfer turns a short-term engagement into a lasting internal capability instead of a recurring dependency.
## 9. What red flags signal a vendor is becoming a risk?
Watch financial viability, staff turnover, certification status, and public reputation - a vendor facing internal turmoil or financial instability can put your data operations at risk even while current delivery still looks fine.
A scheduled review of a vendor's operational and financial health, done annually at minimum, turns vendor risk from a surprise into something you saw coming.
### Key Dimensions for Vendor Risk Assessment
* **Financial Viability:** Heavy reliance on one large client, a recent private equity acquisition, or negative public financial reporting can all signal instability ahead.
* **Organizational Stability:** Multiple senior engineers or the project lead leaving within a short window is a real warning sign, not a coincidence.
* **Operational & Compliance Integrity:** A lapsed Snowflake or Databricks certification can indicate declining investment in that technology stack.
* **Reputational Risk:** Industry forums, news coverage, and employee review sites like Glassdoor can surface systemic issues before they hit your project.
> **Pro-Tip:** Build a simple risk dashboard per strategic vendor - staff turnover, certification status, financial news - and review it quarterly, with a full assessment annually.
Catching these signals early keeps a vendor problem from becoming a project-derailing crisis. The [data engineering due diligence checklist](/insights/data-engineering-due-diligence-checklist/) has a fuller list of warning signs to check during selection and renewal.
## 10. How do you verify a vendor's claims before signing anything?
Cross-reference analyst reports, peer review platforms, and direct reference calls instead of relying on the vendor's own case studies - triangulating independent sources is what confirms technical expertise and delivery quality before you commit budget.
### Key Sources for Independent Validation
* **Analyst Reports:** Gartner, Forrester, and Everest Group evaluations benchmark vendors against peers on market presence and technical capability.
* **Peer Review Platforms:** Clutch.co and G2 carry verified customer reviews - read the detailed feedback, not just the star rating.
* **Partner Certifications:** Verify partnership status directly through official directories from Snowflake, Databricks, and AWS rather than taking a vendor's word for it.
* **Independent Comparisons:** A structured [vendor evaluation criteria checklist](/insights/data-engineering-vendor-evaluation-criteria/) applies a consistent methodology across firms, which is a useful cross-check against a vendor's own pitch.
> **Pro-Tip:** In reference calls, ask "Can you describe a time the project went off track and how the vendor responded?" instead of "Were you happy with them?" It reveals a lot more about how they actually handle problems.
Independent validation is the check against inflated claims and a poor-fit partnership - it's cheap insurance against a decision you'd otherwise be making on marketing material alone.
## Top 10 Vendor Management Practices Comparison
| Practice | Implementation complexity | Resource requirements | Expected outcomes | Ideal use cases | Key advantages |
|---|---:|---:|---|---|---|
| Vendor Selection Criteria and Evaluation Frameworks | Moderate - workshops to define/weight criteria | Low-Medium - stakeholders, scoring templates, time | Consistent, defensible vendor comparisons and faster decisions | Strategic vendor selection, enterprise platform choices | Reduces bias, aligns stakeholders, enables ROI-based decisions |
| Rigorous RFP Process | High - create, distribute, and evaluate detailed RFPs | High - procurement, technical reviewers, evaluation panels | Detailed proposals, uncovered hidden costs, documented commitments | Large/complex projects, regulated procurements, multi-vendor tenders | Standardizes comparisons, exposes scope gaps, improves contract enforceability |
| Performance Metrics and SLA Tracking | Medium - define SLAs, KPIs, dashboards, review cadence | Medium-High - monitoring tools, analysts, reporting effort | Objective performance visibility, early issue detection, accountability | Ongoing managed services, long-term engagements | Enables enforcement, supports renewals, drives vendor improvement |
| Diversified Vendor Portfolio | Medium - strategy, integration mapping, governance rules | Medium-High - vendor managers, integration planning, coordination | Reduced single-vendor risk and access to specialist capabilities | Large organizations needing best-of-breed capabilities | Lowers concentration risk, encourages competition, enables specialization |
| Transparent Cost Structures and Rate Benchmarking | Low-Medium - collect rate data and run benchmarks | Medium - market data subscriptions, procurement analysis | Better cost control, clearer budgeting, stronger negotiation position | Budget planning, contract renewals, pricing negotiations | Detects overpricing, clarifies cost drivers, improves negotiation leverage |
| Contract Management and Governance Frameworks | High - develop MSAs, SOWs, compliance and change processes | High - legal counsel, procurement, governance roles | Reduced legal/operational risk, clear obligations and exit provisions | High-value engagements, regulated or IP-sensitive projects | Protects IP/data, enforces obligations, enables orderly transitions |
| Regular Communication and Stakeholder Alignment | Low - define cadences, roles, and channels | Medium - participant time, coordination tools, agendas | Timely alignment, early risk identification, fewer surprises | Agile projects, distributed teams, multi-stakeholder programs | Improves transparency, reduces rework, strengthens relationships |
| Knowledge Transfer and Avoiding Vendor Lock-in | Medium - KT plans, documentation, training programs | Medium - internal FTEs for learning, vendor training time | Increased internal capability, lower switching costs, continuity | Migrations, platform builds, long-term operations | Builds internal skills, preserves tribal knowledge, reduces dependency |
| Regular Vendor Risk Assessments | Medium - set risk indicators, gather intelligence, review cycle | Medium - analysts, BI tools, background checks | Early detection of vendor distress, informed mitigation actions | Critical suppliers, high-availability services, significant financial exposure | Protects business continuity, supports due diligence, reduces surprise failures |
| Third-Party Verification and Peer Validation | Low-Medium - obtain analyst reports and references | Medium - analyst subscriptions, reference calls, verification work | Independent validation of claims and better shortlist confidence | Shortlisting vendors, executive approvals, high-stakes procurements | Objective benchmarking, reduces selection risk, supports stakeholder confidence |
## Putting These Practices to Work
These ten practices work as a system, not a checklist you complete once. Selection criteria set the bar; the RFP forces vendors to prove they clear it; SLA tracking confirms they keep clearing it after the contract is signed; and risk assessment plus exit planning make sure you're never stuck if a vendor stops clearing it. Skip a step and the risk doesn't disappear - it shows up later and costs more to fix.
### From Reactive Management to Proactive Partnership
Once a vendor is onboarded, the work shifts from procurement to governance.
* **Continuous Performance Monitoring:** Tracking specific SLAs and metrics - pipeline uptime, query performance, bug resolution time - replaces subjective status updates with numbers everyone can see.
* **Structured Governance:** Regular communication cadences and clear stakeholder alignment keep scope from drifting and keep the vendor's work tied to actual business goals.
* **Proactive Risk Management:** Regular risk assessments, a diversified vendor portfolio, and a real knowledge transfer plan remove single points of failure before they matter.
> **Key Takeaway:** Good vendor management isn't about policing partners. It's building a structure where good performance is the default outcome, not something you have to chase.
### Where the Real Return Comes From
The financial upside of disciplined vendor management goes beyond a lower hourly rate. Rate benchmarking and contract discipline matter, but the bigger gain is a vendor ecosystem that's actually reliable - one where your internal team can focus on strategy instead of managing surprises.
The most commonly skipped step is also the one with the longest payoff: documentation and post-migration monitoring. Both show their value months after go-live, which is exactly when a missing runbook or an unmonitored cost overrun gets expensive.
If you're still assembling your shortlist, [how to choose a data engineering company](/how-to-choose-data-engineering-company/) covers the selection process end to end, and [data engineering partner selection](/insights/data-engineering-partner-selection/) walks through weighing finalists once you have one.
---
## What Is a Data Platform? A Practical Guide for 2025
Source: https://dataengineeringcompanies.com/insights/what-is-a-data-platform/
Published: 2026-02-12T10:06:59.741129+00:00
Description: A data platform is the integrated system that ingests, stores, transforms, and serves data across an organization - not a single tool. Here's how the pieces fit together and how to pick a partner to build one.
A data platform is a company's central system for data processing and analysis. It is not a single database or tool - it's an integrated architecture that ingests raw data, processes it, and makes it available for business intelligence, analytics, and operational applications.
## How Is a Data Platform Different From a Data Warehouse?
**A data warehouse stores clean, structured data for historical reporting - it's static and retrospective. A data platform manages the entire data lifecycle: collection, storage, transformation, analysis, and application, across structured and unstructured data, moving a company from siloed information to coordinated, data-informed decisions.**
The warehouse is one component inside the platform, not a competing system. A warehouse answers known, well-structured questions against clean data. A platform is the operational system that feeds it - and everything else, including data science and application workloads - from raw collection through to serving.
### From Static Storage to an Active System
The fundamental shift is from passive data storage to an active, operational backbone. A data platform connects disparate systems and provides multiple teams with secure, efficient access to data.
This integrated approach supports a range of business functions simultaneously. The platform must be flexible enough to handle diverse data types and serve various end-users with different objectives.
* **For Business Analysts:** It supplies clean, reliable data for dashboards and reports in tools like [Tableau](https://www.tableau.com/) or [Power BI](https://powerbi.microsoft.com/en-us/).
* **For Data Scientists:** It provides governed access to both raw and processed data required for building and training machine learning models.
* **For Application Developers:** It can expose data through APIs to power customer-facing features, such as real-time personalization.
The table below outlines the key differences.
### Key Differences Between Traditional Warehouses and Modern Data Platforms
| Capability | Traditional Data Warehouse | Modern Data Platform |
| :--- | :--- | :--- |
| **Data Scope** | Primarily structured, historical data (e.g., sales records, financials). | All data types: structured, semi-structured, and unstructured (e.g., logs, images, social media feeds). |
| **Primary Goal** | Reporting and business intelligence (BI) on past performance. | Powers BI, real-time analytics, AI/ML models, and data-driven applications. |
| **Architecture** | Centralized and often rigid, designed for specific queries. | Decentralized, flexible, and scalable; supports diverse compute engines. |
| **Users** | Mostly business analysts and data professionals. | Serves the entire organization: analysts, data scientists, developers, and business users. |
| **Operational Focus** | Batch processing; data is updated periodically (e.g., nightly). | Supports both batch and real-time stream processing for up-to-the-minute insights. |
This comparison shows an evolution from a system of record that looked backward to an operational engine that drives the business forward.
### The Strategic Business Asset
A data platform is more than a technical solution; it's a strategic asset that fuels business growth and operational efficiency. It provides the capability to ingest, store, process, and analyze massive volumes of information at scale.
The economic impact is measurable. The U.S. data marketplace platform market, a component of this ecosystem, generated **USD 417.4 million** in revenue in 2024 and is projected to reach **USD 1,459.5 million** by 2030, according to [Grand View Research](https://www.grandviewresearch.com/horizon/outlook/data-marketplace-platform-market/united-states).
This growth highlights a critical reality: a company's ability to compete depends on how effectively it can turn raw data into measurable outcomes. A well-designed data platform is the infrastructure that enables this transformation by breaking down departmental silos and creating a single source of truth.
## What Are the Core Components of a Data Platform?
**A data platform is built from seven specialized, interconnected components: ingestion, storage, processing and transformation, metadata management, governance and security, orchestration, and serving. Each handles one stage of the data lifecycle, and vendors typically specialize in one or two rather than all seven.**
A data platform is not a single product you buy off the shelf - it's a system assembled from these building blocks, which is why designing the architecture or selecting vendors requires understanding each piece.
### 1. Data Ingestion
The first step is moving data into the platform. **Data Ingestion** is the process of collecting raw data from numerous sources - SaaS applications, internal databases, mobile devices, and IoT sensors - and loading it into a central storage layer.
Data arrives in different formats and at varying velocities. Some data is delivered in large, scheduled batches (e.g., nightly sales reports), while other data streams in continuously (e.g., website user clicks). The ingestion layer has to handle both without dropping records.
* **Batch Ingestion:** Tools like [Fivetran](https://www.fivetran.com/) or [Airbyte](https://airbyte.com/) are used to pull data on a schedule from applications, databases, and file systems.
* **Stream Ingestion:** For real-time data from IoT devices or application logs, technologies like [Apache Kafka](https://kafka.apache.org/) or [AWS Kinesis](https://aws.amazon.com/kinesis/) are standard choices.
The objective is to create automated, reliable pipelines that deliver raw data to the storage layer.
### 2. Data Storage
Once ingested, data requires a central repository. The **Data Storage** layer serves as the primary warehouse for all ingested data. Modern storage layers are designed for flexibility.
They must handle structured data (e.g., tables from a CRM), semi-structured data (e.g., JSON files from APIs), and unstructured data (e.g., images, text). This versatility is why modern data lakes and lakehouses are more powerful than rigid, traditional data warehouses. Typically, this layer is built on cost-effective, highly scalable cloud object storage, such as [Amazon S3](https://aws.amazon.com/s3/) or [Google Cloud Storage](https://cloud.google.com/storage).
### 3. Data Processing and Transformation
Raw data is rarely useful in its original state. The **Data Processing and Transformation** layer is where raw data is cleaned, structured, enriched, and aggregated to create analysis-ready datasets.
This is where data engineers build pipelines to convert raw data into trusted information assets. For example, a transformation job might join customer order data with marketing campaign information to calculate return on ad spend. Adhering to [data engineering best practices](https://www.datateams.ai/blog/data-engineering-best-practices) is critical for building a reliable platform.
> This transformation stage is where a significant amount of business logic gets encoded. Raw inputs turn into meaningful metrics - customer lifetime value, sales trends - which is what makes the data directly useful for business intelligence and decision-making.
### 4. Metadata Management
A complex system requires a detailed catalog to track every asset - its origin, location, and usage. **Metadata Management** serves as this central catalog for the data platform. It is the "data about your data."
This component captures technical details (e.g., data types, schemas) and business context (e.g., data ownership, metric definitions). A well-maintained metadata layer is what lets users find the data they need and trust where it came from - through discovery and lineage tracking.
### 5. Data Governance and Security
**Data Governance and Security** functions ensure that data is accurate, consistent, and handled in compliance with company policies and regulations like GDPR or CCPA.
This component covers several critical jobs:
* **Access Control:** Defining and enforcing permissions for who can view and modify which datasets.
* **Data Quality:** Establishing rules and monitoring to ensure data completeness and correctness.
* **Data Masking:** Obfuscating sensitive personally identifiable information (PII).
* **Auditing:** Maintaining a log of data access and changes for compliance purposes.
Without strong governance, a data lake can become a "data swamp" - an untrusted and insecure repository of unusable information.
### 6. Orchestration
An automated system requires a central controller to coordinate its various processes. **Orchestration** is the component responsible for scheduling, executing, and monitoring all data pipelines and workflows.
Tools like [Apache Airflow](https://airflow.apache.org/) or [Dagster](https://dagster.io/) are used to define the complex dependencies between tasks. For example, an orchestrator ensures a sales report transformation job only runs *after* the daily sales data has been successfully ingested. This automation enables the platform to operate reliably at scale. See how these components fit together in our guide to the [modern data stack](/insights/modern-data-stack/).
### 7. Data Serving and Access
Finally, the processed data must be delivered to end-users. The **Data Serving and Access** layer makes high-value data available to analysts, data scientists, and other applications.
This layer's implementation varies depending on the use case:
* **BI Dashboards:** Serving aggregated data to tools like [Tableau](https://www.tableau.com/) for executive reporting.
* **APIs:** Exposing clean data to power features in other software applications.
* **SQL Access:** Providing analysts direct access to run ad-hoc queries against the data.
An effective serving layer provides fast, reliable, and secure access, ensuring the value created within the platform reaches those who can act on it.
## Which Data Platform Architecture Should You Choose?
**The three dominant patterns are the modern data warehouse (best for standardized BI on structured data), the lakehouse (best for combining BI and AI/ML on one system), and the data mesh (best for large, federated organizations where a central team has become a bottleneck). The right choice depends on company size, goals, and structure.**
Selecting the right architecture is a strategic decision - what works for a startup will likely not scale for a large, regulated enterprise. It establishes the foundation for how an organization uses data for years: the right choice enables speed and agility, the wrong one leads to bottlenecks and technical debt.

Ingestion, storage, and processing are the foundation of every blueprint below - what differs is how each pattern organizes and governs them.
### The Modern Data Warehouse
The modern data warehouse remains a strong choice for companies focused on enterprise-wide business intelligence (BI). It functions as a highly organized, central repository for structured and semi-structured data. Its primary strength is creating a single, reliable source of truth for reporting and analytics.
This architecture is optimal when the main goal is to serve clean, governed data to business analysts using tools like [Tableau](https://www.tableau.com/) or [Power BI](https://powerbi.microsoft.com/en-us/). It is engineered for performance and simplicity, facilitating queries on historical data to answer well-defined business questions.
* **Best For:** Companies focused on standardized reporting, corporate BI, and establishing a single version of the truth for key business metrics.
* **Trade-Offs:** It can be rigid when handling raw, unstructured data and may create a bottleneck for advanced data science or machine learning experiments that require greater flexibility.
### The Lakehouse Architecture
The lakehouse is a hybrid model that combines the low-cost, flexible storage of a data lake with the management features and query performance of a data warehouse. Pioneered by companies like [Databricks](https://www.databricks.com/) and [Snowflake](https://www.snowflake.com/en/), it has become a standard for many modern data teams.
A lakehouse allows organizations to store all data types - structured and unstructured - in a single system. This architecture enables both traditional BI analytics and advanced AI/ML projects to run on the same data, eliminating the need for separate, siloed systems and reducing data duplication. See our full breakdown of [lakehouse architecture](/insights/what-is-lakehouse-architecture/) for the technical detail.
> A key advantage of the lakehouse is its direct support for data science workflows. Machine learning models can be trained on the full, raw dataset and then deployed alongside business intelligence dashboards, all under a single, unified governance framework.
### The Data Mesh
For large, complex organizations with numerous business units, the data mesh offers a decentralized alternative. Instead of a central data team building a monolithic platform, a data mesh puts individual domain teams in charge of owning and managing their own data as a "product."
In this model, teams for marketing, sales, and logistics are each responsible for building and maintaining their own data products. They make these products discoverable and accessible to the rest of the organization through a shared, self-service infrastructure - placing data ownership with the domain experts to support agility at scale.
* **Best For:** Large, federated companies where a central data team has become a bottleneck and domain-specific expertise is critical.
* **Trade-Offs:** This is not a simple implementation. It requires a significant cultural and organizational shift. Building the necessary self-service tools and federated governance is complex and demands a high level of data maturity across the company.
Whichever pattern a company chooses, it's built on a small set of cloud platforms in practice. Across the 86 firms profiled in the Data Engineering Companies Index, 76 list AWS, 70 Azure, 66 Snowflake, 64 Databricks, and 56 Google Cloud among their platforms - a rough proxy for where the implementation expertise actually concentrates. Each architectural blueprint is a different strategy for getting value out of that same underlying stack.
## How Does a Data Platform Drive Business Results?
**A data platform's technical architecture matters only if it delivers business value. Four applications show the direct link most clearly: hyper-personalization in retail, predictive maintenance in manufacturing, supply chain optimization in logistics, and real-time fraud detection in financial services.**

An effective data platform becomes the foundation for specific, high-impact business applications. It transitions from a passive data repository to an active engine for revenue generation, efficiency gains, and risk management.
Here are four concrete examples where a well-built platform translates directly into significant ROI.
### Powering Hyper-Personalization in Retail
Today's customers expect personalization. A **Customer Data Platform (CDP)**, a specialized application built on a data platform, enables this. It ingests data from every customer touchpoint - website clicks, app usage, in-store purchases, support calls - to create a unified view of each individual.
This complete profile allows a retailer to move beyond generic marketing. They can deliver personalized product recommendations, timed promotions, and relevant content. The business outcome is a direct increase in customer loyalty, higher average order values, and reduced churn - which is why CDP spending has grown fast enough to become its own software category over the past several years.
> By unifying disparate customer data streams, a CDP-powered data platform can identify high-value segments and predict which offers are most likely to convert. It turns raw data into a sales-driving asset.
### Enabling Predictive Maintenance in Manufacturing
In manufacturing, unplanned downtime is a primary source of lost revenue. A single equipment failure can halt a production line, costing a company hundreds of thousands of dollars per hour. A data platform helps prevent this by enabling **predictive maintenance**.
The platform ingests and analyzes large streams of real-time sensor data from machinery, such as temperature, vibration, and pressure. Machine learning models running on the platform identify subtle anomalies that signal an impending failure, often weeks in advance. This allows maintenance teams to schedule repairs during planned downtime, avoiding costly emergencies. The business benefits are clear:
* **Increased Asset Uptime:** Equipment operates longer and more reliably.
* **Reduced Maintenance Costs:** Repairs are scheduled efficiently rather than as expensive emergencies.
* **Improved Safety:** Potential failures are identified before they create hazardous conditions.
### Optimizing Supply Chains in Logistics
Logistics operates on thin margins, so efficiency directly determines profitability. A data platform provides the real-time visibility needed to manage complex supply chains. By integrating data from GPS trackers, warehouse management systems, weather forecasts, and traffic feeds, a company gains a live, comprehensive view of its entire operation.
This unified view powers analytics that can optimize truck routes to avoid delays, predict demand to prevent stockouts, and streamline warehouse workflows. For example, a logistics provider could automatically reroute a fleet to bypass a major traffic jam, saving fuel and ensuring on-time delivery. The result is a more resilient, efficient, and cost-effective supply chain.
### Accelerating Fraud Detection in Financial Services
For financial institutions, combating fraud is a high-stakes, ongoing effort. Legacy rule-based systems are often too slow to detect sophisticated fraud patterns. A modern data platform changes this by enabling real-time fraud detection using advanced analytics and machine learning.
The platform can process millions of transactions per second, analyzing numerous variables - amount, location, time, and user behavior - to score the risk of each one instantly. High-risk activities can be automatically blocked or flagged for human review, stopping fraud before it occurs. This not only prevents direct financial losses but also protects the institution's reputation and improves customer experience by reducing false positives.
## How To Select The Right Data Platform Partner
**Score prospective partners on four things: proven technical depth in your specific stack, relevant industry experience, a transparent delivery methodology, and the actual seniority of the team you'll get - not the one in the pitch. Weight technical stack expertise and industry experience heaviest, since those are hardest to fake convincingly.**
Technology selection is only one part of a successful data platform initiative. The expertise of the implementation partner is often the deciding factor, which means looking past sales presentations to assess a firm's actual capabilities - the step that de-risks the investment and prevents project failure.
The goal is not to find the cheapest hourly rate, but a strategic partner who can accelerate the timeline, avoid common technical pitfalls, and maintain focus on business value.
### Look For Proven Technical Expertise
Your partner must have deep, demonstrable experience with your chosen technology stack. Do not settle for vague claims of "cloud expertise." If you are building on [Snowflake](https://www.snowflake.com/en/), they need a proven track record of successful Snowflake projects. The same applies to [Databricks](https://www.databricks.com/), [Google BigQuery](https://cloud.google.com/bigquery), or any other core platform technology.
Ask for specific, anonymized case studies and referenceable clients. Inquire about their team's certifications and the complexity of past projects. Understanding the realities of [collaborating with a Snowflake partner](https://www.faberwork.com/latest-thinking/collaborating-with-faberwork-a-snowflake-partner), for example, can be very revealing. This level of detail separates firms with genuine hands-on skill from those who simply display logos on their website.
> A critical question to ask is about their migration experience. Have they successfully moved a company with a similar data footprint and complexity from a legacy system to your target platform? That’s a massive indicator of whether they can handle a high-stakes, challenging project.
### Verify Industry And Domain Knowledge
A data platform for a retail company will be fundamentally different from one for a financial services firm with extensive regulatory requirements. A partner with industry knowledge understands the specific challenges, data sources, and compliance hurdles relevant to your business.
This expertise leads to a faster, more effective project because they are not learning your industry at your expense. They can recommend industry-specific data models, suggest relevant KPIs, and build a platform that addresses the questions your stakeholders care about.
* **Retail:** Look for experience with Customer Data Platforms (CDPs), personalization engines, and supply chain optimization.
* **Finance:** They need deep knowledge of fraud detection, risk modeling, and regulatory reporting like **GDPR** or **CCPA**.
* **Manufacturing:** They should be familiar with IoT sensor data, predictive maintenance models, and production line analytics.
### Evaluate Their Delivery Methodology
Ask every potential partner to describe their project management process. A transparent, agile methodology is a positive indicator. It suggests a focus on iterative progress and continuous communication, delivering value in stages rather than attempting a high-risk "big bang" launch.
A clear methodology demonstrates discipline. It should define roles, outline communication cadences, and specify how scope changes are handled. If a firm cannot clearly articulate its project management process, it is a warning sign of potential disorganization and budget overruns. Our guide to [data engineering consulting services](/insights/data-engineering-consulting-services/) breaks down what to expect from a well-run engagement.
Finally, insist on knowing who will be on the team. Beware of the "bait and switch," where senior architects participate in the sales process but are replaced by junior developers after the contract is signed. Ask for the profiles of the *actual team members* who will be assigned to your project to ensure you are getting the experience you are paying for.
### Evaluation Checklist for Data Engineering Partners
To make the selection process more objective, use this scoring checklist. It helps vendor management and procurement teams compare potential partners using a consistent framework. Score each firm during the evaluation to facilitate a more data-driven decision.
| Evaluation Criteria | Weighting (1-5) | Partner A Score | Partner B Score | Key Observations |
| :--- | :--- | :--- | :--- | :--- |
| **Technical Stack Expertise** | **5** | | | *e.g., "Partner A has 12 Snowflake certifications, B has 3."* |
| **Relevant Industry Experience** | **5** | | | *e.g., "Partner B showed 3 retail case studies, A had none."* |
| **Data Migration Experience** | **4** | | | *e.g., "A migrated a larger, more complex legacy system."* |
| **Project Delivery Methodology** | **4** | | | *e.g., "A's agile process is well-defined; B's is vague."* |
| **Team Seniority & Composition** | **4** | | | *e.g., "Met the actual lead engineer from Partner B."* |
| **Client References & Case Studies**| **3** | | | *e.g., "Reference call with Partner A's client was glowing."* |
| **Cultural Fit & Communication** | **3** | | | *e.g., "Partner B's team felt more collaborative and direct."* |
After scoring each potential partner, tally the results. While the highest score is a strong indicator, also review the "Key Observations" column. Qualitative feedback and your team's overall impression can be the deciding factor between two closely-matched firms.
## Planning Your Data Platform Journey
Implementing a data platform is a journey, not a single project. The best approach is a clear, deliberate plan that recognizes the different roles of various leaders.
The goal is to build momentum, demonstrate value quickly, and align the organization. This starts with strong executive sponsorship and a business case that ties every dollar of investment to a measurable outcome.
### The Roadmap for CIOs and CTOs
As a CIO or CTO, your primary role is to define the high-level strategy and secure organizational alignment. You are responsible for building the organizational and financial foundation for the initiative.
1. **Construct the Business Case:** Frame the platform as an enabler of core business goals, not just a technology upgrade. For example, show how it could raise customer lifetime value or cut operational costs through predictive maintenance, then quantify the expected ROI against your own baseline numbers.
2. **Secure Stakeholder Buy-In:** Gain the support of other C-suite leaders. Walk the CFO through the financial model. Show the CMO how the platform will enable advanced personalization. Explain to the COO how it will drive operational efficiencies. Without this buy-in, securing budget and resources will be a struggle.
3. **Define a Phased Implementation:** Avoid a "big bang" rollout. Instead, lay out a multi-quarter roadmap. Start with a focused pilot project that can deliver a quick, high-impact win, then expand from there. This approach builds confidence and makes the overall investment more manageable.
### The Action Plan for Heads of Data
As a data leader, your focus shifts from broad strategy to tactical execution. Your job is to translate the high-level vision into a concrete plan that your team can implement.
> The most successful data platform projects begin with a laser focus on solving one specific, high-value business problem. Proving a quick win with a pilot project is the single best way to build momentum and secure funding for the broader initiative.
A methodical approach is essential. It ensures your team is prepared and that the first project delivers demonstrable value.
* **Conduct a Current-State Analysis:** Map your existing data sources, pipelines, and tools. Pinpoint the biggest bottlenecks and pain points - these represent the best opportunities for an early win.
* **Identify a High-Value Pilot Project:** Do not try to solve every problem at once. Select a single project with a clear business owner and trackable metrics. A good example is creating a unified customer view for the marketing team to improve campaign targeting. It is visible, valuable, and achievable.
* **Prepare Your Team for New Workflows:** A modern data platform changes how people work. Plan to upskill your team on new tools like [Snowflake](https://www.snowflake.com/) or [Databricks](https://www.databricks.com/). Define new governance processes and introduce concepts like data-as-a-product to foster ownership.
## Frequently Asked Questions About Data Platforms
Common questions that come up when planning a major data platform initiative, drawn from what CIOs, data leaders, and procurement teams ask most often.
### What’s the Real Difference Between a Data Platform and a Data Warehouse?
A traditional **data warehouse** is a component for storing and analyzing structured data, primarily for business intelligence reports. It is a highly organized archive.
A modern **data platform** is a complete ecosystem that manages the entire data lifecycle. It ingests, stores, processes, and serves all data types - structured and unstructured - to support a wide range of applications, from BI and analytics to data science and machine learning.
In short, a data warehouse is a critical *part* of a data platform, but it is not the entire system.
### How Long Does It Actually Take to Implement a Modern Data Platform?
The timeline depends on the scope. A focused proof-of-concept for a single business unit can be implemented and deliver value in as little as **3-6 months**.
A full, enterprise-wide rollout is a more extensive undertaking. A complete migration and modernization project is a strategic initiative that often takes **12-24 months** or longer.
The recommended approach is to implement in phases, aiming for small, incremental wins that deliver value along the way. An experienced partner can often meaningfully shorten these timelines by drawing on prior implementations and avoiding common pitfalls.
### Should We Build Our Own Platform or Buy a Managed Solution?
This is the classic "build vs. buy" decision, and there is no single correct answer.
Building a platform from scratch using open-source tools provides maximum control and customization. However, it requires a large, specialized, and expensive internal team for both initial development and ongoing 24/7 maintenance.
> Buying a managed cloud platform from a vendor like [Snowflake](https://www.snowflake.com) or [Databricks](https://www.databricks.com) significantly reduces the infrastructure management burden and accelerates time-to-value. For most companies, a hybrid approach is optimal: use a managed platform for the core foundation and work with expert partners to build the custom data pipelines and applications that provide a unique competitive advantage.
---
A data platform's architecture only pays off once data actually moves through it reliably. If you're still working out the mechanics of that movement, start with our guide to [data pipelines](/data-pipeline/), then compare the [modern data stack](/insights/modern-data-stack/) against your current tooling, and see how [data warehouses stack up against data lakes](/insights/data-warehouse-vs-data-lake/) if you're deciding where structured reporting should live inside the broader platform.
---
## What is a semantic layer? A Practical Guide for AI and BI Data Unification
Source: https://dataengineeringcompanies.com/insights/what-is-a-semantic-layer/
Published: 2026-01-25T08:56:12.6904+00:00
Description: Discover what is a semantic layer and how it unifies data for AI and BI, including Snowflake and Databricks.
A semantic layer is a layer of business logic that sits between raw data in your warehouse and the tools people use to analyze it. It translates technical fields like `fct_sales_rev_usd` into terms like "Total Revenue" that mean the same thing no matter who is asking or which tool they're using. The point is simple: when sales, finance, and marketing all ask for "quarterly revenue," they get the exact same number, calculated the exact same way.
This guide covers what a semantic layer actually does, the three architectural patterns you can choose between (embedded, universal, hybrid), and how to evaluate vendors and implementation partners. Metrics and BI work touches most data engineering engagements broadly - 68 of the 86 firms profiled in the [Data Engineering Companies Index](/analytics-consulting/) list analytics or BI capabilities - so the harder part is usually picking the right architecture for your organization, not finding someone who has built one before.
What this guide covers:
* **The core components** that turn raw tables into governed business metrics.
* **Three architectural models** - embedded, universal, and hybrid - and when each one fits.
* **A vendor and partner evaluation checklist** for technical fit and total cost of ownership.
* **Straight answers** to the questions data leaders ask most often, including where dbt fits.
## What is a semantic layer, really?
A semantic layer centralizes the business logic that would otherwise be scattered across spreadsheets, BI dashboards, and one-off SQL scripts, so every team works from the same definitions instead of inventing their own. Without it, a sales team and a finance team can report different revenue numbers for the same quarter, not because either is wrong, but because each defines "revenue" differently and pulls from different systems.
That mismatch is what a semantic layer is built to eliminate. It became a core part of enterprise BI in the early 2000s, when tools like Cognos and Business Objects first tackled the problem of standardizing conflicting departmental metrics, well before the modern cloud data warehouse existed.
A useful analogy is a GPS. A GPS doesn't hand you the raw grid of every road and intersection - it gives you a direct instruction: "Turn left in 200 feet." A semantic layer does the same thing for data. It hides the raw tables, cryptic column names, and join logic, and gives every user a simple, consistent business term instead.
> A semantic layer translates complex database tables and cryptic column names (`fct_sales_rev_usd`) into familiar business concepts (`Total Revenue`). It creates a single, reliable source of truth for business definitions and calculations.
This abstraction sits between your data sources and the people who need to make decisions from that data. It makes sure everyone in the organization, from a data scientist training a model to an executive reading a dashboard, is working from the same numbers. That consistency is what makes self-service analytics, accurate reporting, and reliable AI outputs possible in the first place.
### What are the core building blocks?
Every semantic layer, regardless of platform, is built from the same handful of components working together.
| Component | Technical function | Business purpose |
|---|---|---|
| **Data model** | Defines tables, columns, and the join relationships between them. | Maps raw data structures to business entities like "Customers," "Products," and "Sales." |
| **Metrics and measures** | Stores aggregations and calculations (SUM, AVG, COUNT) as code. | Creates consistent, reusable KPIs like "Total Revenue" or "Average Order Value." |
| **Dimensions and attributes** | Organizes descriptive, non-numeric data into hierarchies. | Lets users slice data by categories like "Region," "Product Category," or "Time Period." |
| **Access control** | Manages user permissions and data visibility rules. | Ensures users only see the data they're authorized to see. |
| **Query generation** | Translates user requests into optimized SQL or another query language. | Hides code complexity so non-technical users can ask complex questions directly. |
These components together provide the structure, logic, and security a consistent analytics experience depends on.
## How does a semantic layer fit into your data stack?
A semantic layer doesn't replace your warehouse or lakehouse - it sits on top of platforms like [Snowflake](https://www.snowflake.com/en/) or [Databricks](https://www.databricks.com/), making them usable for business purposes without every team writing its own SQL. It's the business logic layer positioned between your data infrastructure and everything that consumes it: BI dashboards, AI models, spreadsheets, and custom applications.
Its job is to be the one place `Customer Lifetime Value` is defined. Instead of that logic living in a thousand different reports, the semantic layer holds a single authoritative definition, so no matter which tool asks the question, the answer is the same.
### What are the core logical components underneath?
A semantic layer is built on three logical components that turn raw data into reliable business intelligence.
1. **The data model.** The foundational blueprint. It maps business entities like `customers`, `products`, and `orders`, and defines how they relate - for instance, how to join the `orders` table to the `customers` table without introducing duplicate rows or dropped records.
2. **The metrics store.** Where business logic lives, defined as code. It holds the one official formula for each KPI, so when someone asks for "YoY Growth," the calculation runs the same way every time.
3. **The access control layer.** The security boundary for your data. It enforces rules such as a regional sales manager only seeing performance data for their own territory, which is central to data governance.
> The real value of a semantic layer is decoupling business logic from both the underlying data storage and the front-end tools. That separation lets you switch BI tools or update a pipeline without rewriting hundreds of metric definitions.
This principle is a cornerstone of the modern data stack, which favors modular components over monolithic systems. See our guide to the [modern data stack](/insights/modern-data-stack/) for how these pieces fit together.
### What does this look like day to day?
Consider a marketing analyst building a dashboard to track campaign performance.
* **Without a semantic layer:** The analyst hunts for the right tables, guesses at joins, and hand-writes SQL to calculate `Cost Per Acquisition`. The process is slow, error-prone, and often produces numbers that don't match other reports.
* **With a semantic layer:** The analyst connects their BI tool and sees a clean list of terms like "Campaign Spend," "New Customers," and "Acquisition Cost." They drag these certified metrics into their report, confident the definitions are correct and governed.
This makes business users faster and more accurate on their own, and it frees the data engineering team from the queue of ad-hoc report requests so they can spend that time on the data infrastructure itself.
## What are the real payoffs?
Moving business logic into a semantic layer isn't just an architectural preference - it changes what both business users and data teams deal with day to day. For leaders, it means faster, more reliable answers. For technical teams, it means a cleaner, more scalable, and more secure data operation.
The core payoff is consistency. When every dashboard, report, and AI model pulls from the same metric definitions, trust in the numbers goes up, and that trust is what makes people actually use the data instead of falling back on gut calls.

### What does it change for business leaders?
For executives and analysts, the biggest win is a shorter distance between a question and an answer. Instead of waiting weeks for a new report or arguing over whose version of "revenue" is right, teams can pull the number themselves and trust it.
* **Faster time to insight.** Business users build their own reports without writing SQL or learning the database schema, and find answers in minutes instead of days.
* **One source of truth.** Standardizing KPIs like "Churn Rate" or "Customer Acquisition Cost" ends the arguments, because everyone works from the same definitions.
* **Better BI adoption.** People adopt tools they trust. A well-built semantic layer drives higher BI adoption because the data behind it is reliable and easy to find.
* **Stronger alignment across teams.** When sales, marketing, and finance use the same metrics, they're looking at the same picture, which makes planning conversations shorter and more useful.
> A semantic layer acts as a multiplier on an existing analytics program. It's what lets investments in data warehousing and BI tools actually pay off.
### What does it change for technical teams?
Business users see the benefit in their dashboards; data engineers and IT leaders feel it in their workflows. A semantic layer pulls logic out of pipelines, scripts, and BI workbooks and puts it in one place, which makes the whole stack easier to manage, govern, and scale.
Teams that adopt a well-governed semantic layer typically report shorter analytics delivery cycles and less time spent reconciling conflicting metric definitions across tools, because the definitions only exist once instead of once per report.
* **Shorter data prep cycles.** Joins, calculations, and filters get defined once, so data teams stop rebuilding the same logic for every request.
* **Simpler, cleaner pipelines.** Pulling business logic out of the ETL/ELT process makes pipelines simpler and easier to maintain.
* **Centralized security and governance.** Access controls live in one place, so security policy applies consistently across every tool and user, which simplifies audits.
* **A more adaptable data stack.** Swapping a BI tool or plugging in a new AI application no longer means rewriting hundreds of metric definitions.
A semantic layer moves data teams from answering ad-hoc report requests to maintaining a governed system that the business can query directly.
## Which semantic layer architecture should you choose?
The architecture you pick affects your data stack's flexibility, governance, and total cost of ownership. It comes down to one question: will your business logic live inside a single tool, or serve as a shared asset for the whole organization?
There are three architectural models, each with real trade-offs. Which one fits depends on whether you're a small team standardized on one BI tool or a large enterprise running dozens of them.
### What is the embedded model?
The embedded semantic layer is built directly into a specific BI or analytics tool - Looker's LookML or the data models inside [Power BI](https://powerbi.microsoft.com/en-us/) are common examples. All business logic, metric definitions, and relationships live inside that one platform.
This is the common starting point because it takes the least effort to set up, and it works well for analysts already inside that one tool. For a single department or a smaller team standardized on one platform, it's a fast, effective solution.
Its biggest strength is also its biggest weakness: the logic is trapped. If another team wants a different BI tool, or a data science team needs the same metrics in a Python notebook, they have to rebuild everything from scratch, which reintroduces the exact metric chaos a semantic layer is supposed to fix.
### What is the universal model?
The universal semantic layer is a standalone platform that acts as a central, independent hub for business logic. It connects to your warehouse on one side and serves consistent metrics to any tool on the other - BI dashboards, AI models, embedded analytics, or spreadsheets. [Cube](https://cube.dev/), [AtScale](https://www.atscale.com/), and the [dbt Semantic Layer](https://www.getdbt.com/product/semantic-layer) are the primary examples.
This model is built for interoperability at scale. It decouples business definitions from the tools that consume them, which is the only way to enforce consistency across an entire organization.
> The core idea is a single source of truth that isn't tied to any one department or use case - business logic becomes a reusable, governed asset instead of something rebuilt per tool.
The trade-off is another component to manage in your stack. But for a large organization with diverse analytics needs, the universal model tends to be the more durable choice: it avoids vendor lock-in and keeps everyone working from the same numbers. Our guide to [data modeling techniques](/insights/data-modeling-techniques/) covers the underlying concepts in more depth.
### What is the hybrid approach?
A hybrid model combines pieces of both. It usually starts with an embedded semantic layer, then gets extended over time to serve other tools through APIs or connectors - for example, a team builds its primary model in Power BI, then exposes an API so a data scientist can query that same model from a Jupyter notebook.
This is a pragmatic path for teams that want a quick start with an embedded model but want the door open to serve more use cases later.
It offers more flexibility than a purely embedded setup, but it can get complicated. Keeping the "core" embedded model in sync with external connections is genuinely hard, and you're unlikely to get the same level of governance as a dedicated standalone platform. How well it works depends on the quality of the primary tool's APIs and how disciplined your teams are about keeping things in sync.
### How do the three models compare?
| Architecture | Best for | Pros | Cons |
|---|---|---|---|
| **Embedded** | Small to mid-sized teams standardized on a single BI tool. | Tightly integrated with the host tool; easy to start; lower upfront cost | Creates data silos; logic isn't reusable; high risk of vendor lock-in |
| **Universal** | Large enterprises with diverse tools that need org-wide consistency. | True single source of truth; tool-agnostic; centralized governance | Adds a stack component; higher setup effort; needs dedicated management |
| **Hybrid** | Organizations evolving from a single-tool setup toward broader analytics. | Pragmatic migration path; more flexible than pure embedded; balances speed and scale | Can get complex to manage; governance can be inconsistent; depends on the primary tool's API quality |
A startup can succeed with an embedded model. A global enterprise will almost always need a universal one to hold consistency across the org. Hybrid is a bridge between the two, but it needs real planning to avoid becoming more complex than the problem it was meant to solve.
## How do you evaluate semantic layer vendors and partners?
Choosing the technology - and the partner who implements it - affects your data governance, architectural flexibility, and how well your analytics and AI initiatives actually work. A structured evaluation is what keeps you out of a costly rebuild two years in.
Look past the sales demo. Focus on how well a vendor integrates with your existing stack, how it holds up under real load, and whether it actually fits your specific goals.
### What should the technical evaluation cover?
Before booking a demo, get your technical team a checklist that covers how the product performs under load and adapts as the company grows, not just what it does today.
* **Platform compatibility.** Does it integrate natively with [Snowflake](https://www.snowflake.com/en/) and [Databricks](https://www.databricks.com/)? Ask specifically about query pushdown and data movement efficiency, not just "does it connect."
* **Modeling language and flexibility.** How are metrics defined and models built? A code-based approach (YAML or similar) matters for version control - Git integration is non-negotiable - and for fitting into a CI/CD workflow.
* **Scalability and performance.** Ask for benchmarks and real case studies that mirror your data volumes and query complexity, and find out how the system behaves under high concurrency.
* **Connectivity and API access.** A solid set of APIs (REST, JDBC/ODBC) is what lets you connect not just current BI tools but future AI applications and data science notebooks too.
### What should you ask a potential implementation partner?
Once you've shortlisted vendors on technical fit, the question shifts to who implements it. Real-world expertise matters as much as the technology - a good tool with an inexperienced team still fails.
1. **Metric consistency strategy.** "Walk us through how you'd keep a metric like 'Customer Lifetime Value' consistent across Power BI, Tableau, and a chatbot we're planning to build."
2. **A comparable use case.** "Show us a case study where you implemented a semantic layer for a data model as complex as ours. What were the actual hurdles?"
3. **Governance and security implementation.** "Describe how you implement row-level and column-level security, and how you integrate with our identity provider - Active Directory, Okta, or similar."
4. **Team enablement.** "What's the plan for post-implementation support and training? We need our internal BI developers self-sufficient, not dependent on you."
> A strong partner doesn't lead with a feature list. They focus on the business problem you're solving, and their answers show real depth on data architecture, governance, and the change management the rollout will need.
For teams bringing in outside help, our guide to [BI consulting services](/insights/bi-consulting-services/) covers what to look for in a partner.
### What does total cost of ownership actually include?
Look past the sticker price. The full total cost of ownership for a semantic layer includes several costs that don't show up in the initial quote.
* **Implementation and integration.** Professional services fees for setup, data modeling, and connecting to your existing stack.
* **Ongoing maintenance and support.** Annual support contracts, plus any specialized internal hires needed to run the platform.
* **Training and enablement.** What it takes to get your developers and analysts fully proficient on the new system.
* **Infrastructure and compute.** How the semantic layer's queries affect your warehouse consumption and credit usage.
Weighing the technology, the partner, and the long-term cost together is what leads to a decision you don't have to revisit in eighteen months.
## Semantic layer FAQ
### Is a semantic layer just a data warehouse view with a different name?
No. A data warehouse view pre-joins a few tables and stops there. A semantic layer adds a full layer of business context on top of the raw data.
A view is a saved SQL query. A semantic layer is a framework for metrics and governance - you define a metric like "Annual Recurring Revenue" once, and that single definition is used everywhere. It handles relationships and access rules, and serves consistent data to any connected tool, from BI dashboards to AI models. A view can't do any of that.
### How does a semantic layer fit with a data mesh architecture?
It's a practical enabler of data mesh. In a data mesh, different domains (teams) publish their own data products. A universal semantic layer acts as the federated governance layer across all of them, so someone in marketing can discover and use a data product from the finance team and trust what it means.
> A semantic layer provides the common business language different domains need to communicate. It bridges distributed data ownership and a shared understanding, which is what makes data mesh work in practice rather than just on a whiteboard.
### What is dbt's role in the modern semantic layer?
[dbt](https://www.getdbt.com/) has become central to this. It started with the "T" in ELT, and its role expanded with the [dbt Semantic Layer](https://docs.getdbt.com/docs/use-dbt-semantic-layer/dbt-sl), which lets teams define business metrics directly inside their dbt projects, alongside the data models that feed them. About 20 of the 86 firms in the [Data Engineering Companies Index](/insights/dbt-implementation-partners/) list dbt implementation as a specific capability, which is a reasonable signal of how mainstream this pattern has become.
This creates a code-based, version-controlled approach to metrics management. Business logic and data transformations live together, which makes both easier to govern and keep consistent - the same rigor and testing discipline already applied to data pipelines, applied to metrics too.
### Can a semantic layer improve AI and machine learning outcomes?
Yes. A model is only as good as the data it's trained on, and a semantic layer makes sure the features feeding a model come from standardized, governed metrics - which is a real defense against the "garbage in, garbage out" problem that derails a lot of AI projects.
A model predicting customer churn depends on a consistent definition of "active user" or "monthly recurring revenue." A semantic layer gives that model a governed feature store to pull from, which speeds up development and makes the resulting predictions more trustworthy.
---
Choosing the right implementation partner is one of the more consequential decisions in a data modernization project. At [DataEngineeringCompanies.com](/), we publish data-backed firm profiles so you can shortlist a partner with actual evidence instead of a sales deck. Start with the [data governance](/data-governance/) hub if governance and access control are your main constraint, or browse [firms with analytics and BI capabilities](/analytics-consulting/) if a semantic layer is step one toward better dashboards.
---
## What Is Data Fabric? A Practical Guide to Modern Data Architecture
Source: https://dataengineeringcompanies.com/insights/what-is-data-fabric/
Published: 2025-12-17T07:19:49.565821+00:00
Description: Confused about what is data fabric? This guide explains its architecture, compares it to data mesh, and shows how it solves today's complex data challenges.
A data fabric is an architectural approach that creates a unified, intelligent data layer across sources that stay where they are, whether on-premises, in the cloud, or at the edge. It uses active metadata, AI, and automation to connect, discover, govern, and deliver data on demand, without physically moving it into a central repository.
## What Does Data Fabric Mean in Practice?
Picture your company's data spread across a CRM, an ERP, and a cloud object store, each incompatible with the others. A data fabric connects those systems through a virtual layer instead of copying everything into one warehouse - it understands where data lives and how it relates, so you can query it as if it were already unified.
The older approach meant building ETL pipelines to physically move data into a central warehouse: slow, expensive, and prone to creating new silos. A data fabric skips that step. It doesn't move the data; it connects to it, using metadata to track what each piece means and how it fits together.
This isn't a theoretical concept. As more organizations run hybrid and multi-cloud environments, older integration methods struggle to keep pace, and analyst firms including Gartner have tracked steady growth in data fabric adoption as a response.
### What's the Core Idea Behind a Data Fabric?
The core principle is managing data in-situ - where it already lives - rather than replacing existing systems. An active metadata catalog is the engine behind this: it continuously scans connected sources, discovers data assets, profiles their contents, and maps how they relate to each other.
> A data fabric abstracts away the underlying complexity of where data sits. It lets data consumers focus on *what* they need, not *where* it is or *how* to reach it.
That metadata foundation supports a few key capabilities:
* **Unified access:** a single, often SQL-based interface to query data whether it's in [Snowflake](https://www.snowflake.com/en/), a legacy SQL server, or a SaaS application.
* **Automated governance:** security and compliance rules applied from a central control plane, so policy enforcement stays consistent across every source.
* **AI-assisted optimization:** machine learning handles data discovery, quality checks, and query optimization - work that used to be manual.
Connecting distributed data assets this way makes information easier to find, trust, and use in day-to-day business applications and analytics.
## How Does a Data Fabric Actually Work?
A data fabric works as a connector, not a container: it weaves an intelligent layer across your existing infrastructure instead of consolidating data into one system. The fabric sits between distributed sources and the people who need insights, turning fragmented information into something usable without a full migration project.
### What Is the Intelligent Metadata Catalog?
The **intelligent metadata catalog** is the core of a data fabric - an active system, not a static data dictionary. It continuously scans every connected source, from cloud data warehouses to legacy on-premise applications, to discover and contextualize data assets.
Using AI, the catalog profiles data, infers relationships between datasets, tracks lineage (where data came from and how it changed), and suggests business terminology. This "active metadata" builds a machine-readable semantic graph that both people and automated processes rely on.
> The catalog doesn't just list what data you have. It understands *what it means* and *how it connects*. That semantic understanding is what makes automated integration and governance possible.
### How Does Data Fabric Handle Data Integration?
Once the catalog maps where data lives, the fabric needs efficient ways to deliver it - this is **unified data integration**. Instead of locking into a single method like ETL, a fabric mixes several integration patterns based on what each task needs.
* **Data virtualization:** real-time, on-demand access through a logical view of data where it resides - useful when moving large volumes is impractical or latency matters.
* **Data streaming:** processes and delivers data in real time for event-driven cases like fraud detection or IoT analytics.
* **ETL/ELT automation:** when data movement is necessary (say, populating a warehouse), the fabric uses its metadata to automate and optimize those pipelines.
Choosing the right pattern for each task is a core strength of the approach. See these [data integration best practices](/insights/data-integration-best-practices/) for how the methods apply in different scenarios; a data fabric orchestrates all of them from one control plane.
### How Does Data Fabric Automate Governance and Security?
Managing security and compliance across hundreds of distributed systems is hard to do manually. A data fabric's **automated governance and security** layer defines policies for data quality, privacy, and access centrally, then enforces them everywhere.
A rule - say, "mask all personally identifiable information for users in the marketing group" - gets set once and enforced automatically, whether the data is queried from a SaaS tool or an internal database. Governance moves from reactive manual cleanup to a proactive part of the architecture itself.
### What Does the AI-Powered Orchestration Layer Do?
The **AI-powered orchestration** engine uses machine learning to automate and optimize data management on an ongoing basis. It analyzes query patterns to pick efficient execution plans, flags data quality anomalies, and recommends relevant datasets to analysts.
This reduces the operational load on data teams. The fabric adapts to new data sources and changing query loads on its own, and by handling that orchestration work, it frees data engineers and analysts to focus on higher-value work instead of pipeline maintenance.
## How Is Data Fabric Different From Data Mesh and a Lakehouse?
**Data fabric centralizes control over distributed data using technology and automation. Data mesh decentralizes ownership of that data to domain teams. A lakehouse centralizes storage, merging data lake and data warehouse into one platform.** The three terms get used interchangeably, but they solve different problems.
A **data fabric** is a technology-driven architecture that builds a virtual, integrated data layer across distributed systems. It centralizes *control* through automation and AI, making fragmented data feel unified without physically consolidating it.
A **data mesh** is a sociotechnical approach: it decentralizes data ownership, shifting responsibility from a central team to domain-specific teams (marketing, finance, and so on) who treat their data as a product. It's an organizational shift, not a piece of technology.
### What's the Philosophical Difference Between These Approaches?
The core distinction is centralization versus decentralization. A data fabric centralizes *control* and *governance* through a technology platform while data stays distributed - a top-down approach to abstracting complexity through automation.
A data mesh is bottom-up and people-centric. Its premise is that centralized data teams create bottlenecks and lack domain expertise, so domain experts should own the full lifecycle of their own data products instead.
The **data lakehouse** is a storage pattern: it merges the low-cost, flexible storage of a data lake with the structure and performance of a data warehouse, aiming for one centralized platform for both BI and machine learning workloads. For more detail, see [what lakehouse architecture entails](/insights/what-is-lakehouse-architecture/).
> A concise summary:
> * **Data Fabric:** Centralizes *control* over distributed data.
> * **Data Mesh:** Decentralizes *ownership* of distributed data.
> * **Lakehouse:** Centralizes the *storage* of data.
### Who Owns Governance in Each Model?
In a data fabric, governance is typically centralized: a core data or IT team defines policies for security, access, and quality, and the platform automates enforcement across every connected system.
Data mesh pushes toward **decentralized domain ownership** instead. Each business unit is responsible for its own data pipelines, quality, and API-based sharing, with global standards set centrally but implemented by individual domains.
A lakehouse usually reverts to centralized ownership, with a core data team managing the platform, infrastructure, and datasets the rest of the organization consumes.
### A Practical Comparison
The table below summarizes the differences. Which one fits depends on your organization's culture, technical maturity, and goals.
| Attribute | Data Fabric | Data Mesh | Data Lakehouse |
| :--- | :--- | :--- | :--- |
| **Primary Focus** | Technology-driven unification of distributed data | Organizational strategy for decentralized data ownership | Architectural pattern for unified storage and processing |
| **Data Location** | Leaves data in place (in-situ access) | Distributed across domains | Data is consolidated into a central platform |
| **Governance** | Centralized and automated by the fabric's technology | Federated; global standards with domain-level implementation | Typically centralized, managed by a core data team |
| **Implementation** | Technology-led; implement a platform to connect sources | Culture-led; requires organizational change and domain teams | Platform-led; build or buy a lakehouse platform |
| **Best For** | Organizations with complex, hybrid/multi-cloud environments that need unified access and governance without a major re-architecture. | Large, decentralized organizations with mature data teams in different business domains that can operate with autonomy. | Companies aiming to consolidate BI and AI workloads onto a single, cost-effective storage and compute platform. |
These architectures aren't mutually exclusive. An organization might use a data fabric to connect sources that feed a central lakehouse, or apply data mesh principles to how teams manage data products within that lakehouse. Understanding their individual strengths is the first step.
## What Business Problems Does Data Fabric Actually Solve?
**A data fabric makes existing data assets more accessible and valuable without a disruptive consolidation project.** It shows up most often in four places: a unified customer view, real-time analytics, simpler compliance, and faster AI/ML development.

### How Does Data Fabric Enable a 360-Degree Customer View?
Customer data is usually fragmented across CRMs, e-commerce platforms, support systems, and marketing tools. A data fabric connects to all of them and stitches together a virtual, unified customer profile on demand, without moving or duplicating the underlying data.
> A support agent can open a ticket and, in the same interface, see that customer's purchase history and marketing interactions - without logging into three separate systems. That improves service quality and first-contact resolution.
### How Does Data Fabric Support Real-Time Analytics?
Traditional analytics often runs on stale data from nightly batch jobs - too slow for fraud detection, supply chain logistics, or dynamic pricing. A data fabric gives direct, governed access to live operational data, querying transactional systems in real time for an accurate, current view of the business.
Cutting data integration timelines from weeks to days is one of the clearer competitive advantages organizations report, and it's part of why analyst firms like Gartner continue to track growing enterprise investment in data fabric architectures.
### How Does Data Fabric Simplify Compliance?
Managing compliance with GDPR, CCPA, and HIPAA across a distributed data environment is hard to do manually. A data fabric acts as a central control plane: policies get defined once and enforced automatically everywhere, which is why it shows up so often in [data governance](/data-governance/) strategy.
* **Consistent policy enforcement:** closes security gaps and inconsistent rule application between systems.
* **Automated data discovery:** the active metadata catalog identifies and classifies sensitive data, giving a clear view of regulatory risk.
* **Centralized auditing:** data lineage provides an audit trail of data access and usage, which simplifies compliance reporting.
### How Does Data Fabric Help AI and ML Teams?
Data scientists routinely report spending the majority of their time on data discovery, cleaning, and preparation rather than modeling - a persistent bottleneck for AI initiatives. A data fabric acts as a self-service data marketplace: one portal to discover, access, and blend governed, high-quality datasets from across the enterprise.
Removing that access friction is what shortens the time it takes to build, test, and deploy machine learning models.
## How Do You Implement a Data Fabric?
**Implementation works best as a phased, crawl-walk-run rollout rather than a single project: prove value with a narrow pilot, then expand.** Large enterprises with complex hybrid and multi-cloud footprints tend to get the most out of this approach, and North America's mature cloud infrastructure has made it a common early-adopter region.
### Phase 1: Discovery and Strategy
Effective data initiatives begin by solving a specific business problem, not by implementing technology for its own sake. This phase anchors the data fabric project to a tangible business outcome.
Identify a high-impact challenge where improved data access and integration could deliver measurable results, such as reducing customer churn or optimizing supply chain logistics. Map the data sources required to address this problem - whether in [Salesforce](https://www.salesforce.com/), [SAP](https://www.sap.com/), or other systems. Scope a small pilot project designed to deliver a quick win and build organizational confidence.
### Phase 2: Foundation and Pilot
With a clear objective, the next step is to build the core infrastructure and execute the pilot project. This involves laying the technical groundwork for future expansion.
1. **Select Core Technology:** Evaluate data fabric platforms based on their connectivity options, metadata management capabilities, and governance features relevant to the pilot.
2. **Build the Initial Catalog:** Connect the chosen platform to the handful of data sources identified in Phase 1. Allow the tool's automated discovery features to profile the data and build the foundational metadata graph.
3. **Execute the Pilot Use Case:** Deliver the data products or dashboards for the pilot project. The goal is to demonstrate that the data fabric approach provides faster, more reliable insights than existing methods.
> Successfully completing this phase turns "data fabric" from an abstract concept into a practical solution for a real business problem, securing stakeholder buy-in for broader adoption.
### Phase 3: Expansion and Automation
With the pilot's success validated, the final phase involves scaling the implementation. This means systematically connecting more data sources, onboarding more business units, and addressing more complex use cases based on a prioritized backlog.
As the fabric expands, its intelligent features become more powerful, automating more data quality tasks and query optimizations. Governance policies are refined and applied consistently across the growing ecosystem. The objective is to evolve the data fabric into an enterprise-wide, self-service data utility that provides governed access to trusted data for all authorized users.
## How Do You Choose the Right Data Fabric Platform?
**Evaluate a data fabric platform on four criteria: connector breadth, metadata and catalog intelligence, governance automation, and scalability.** The market is crowded with vendors, so a disciplined, criteria-based evaluation matters more than any single vendor's marketing claims.
Connector coverage should match what your stack actually runs. Across the 86 firms profiled in the Data Engineering Companies Index, 76 list AWS, 70 Azure, 66 Snowflake, 64 Databricks, and 56 Google Cloud among their platforms - a rough proxy for which integrations a data fabric platform needs to support well out of the box.
Get the platform choice wrong and you add complexity instead of removing it; get it right and it strengthens your entire data strategy.
### What Should You Evaluate When Comparing Platforms?
Four criteria matter most when comparing data fabric platforms:
1. **Connectivity and integration:** the breadth of pre-built connectors for databases, SaaS applications, and streaming platforms. A wide connector library cuts down on custom development work.
2. **Metadata and catalog intelligence:** the platform should use AI for automated data discovery, classification, and lineage tracking, with an **active metadata graph** that infers relationships and applies business context. Manual cataloging doesn't scale.
3. **Governance and security automation:** how well the solution centralizes policy management - defining access rules, data masking, and quality checks once and enforcing them across hybrid and multi-cloud environments.
4. **Scalability and performance:** whether the architecture handles your data volume and query complexity, including distributed query optimization and the ability to scale compute without creating bottlenecks.
For how these pieces fit together at the platform level, see the principles behind a [modern data stack](/insights/modern-data-stack/).
> The goal is a technology partner that *reduces* complexity, not one that adds another layer to it. The strongest data fabric implementations make data integration, governance, and delivery feel simple even when the underlying work isn't.
### What Should Your RFP Ask Vendors?
Write scenario-based questions that force vendors to demonstrate capability instead of describing it. Instead of "Do you support data governance?" ask: "Show how a single policy masks PII in both an on-premise Oracle database and a cloud-based Salesforce instance, at the same time."
That proof-based approach gets past generic sales pitches and gives you the evidence needed to pick a partner that can actually deliver on what a data fabric promises.
## Data Fabric: Frequently Asked Questions
Here are answers to some of the most common questions about data fabric architecture.
### Isn't This Just a Fancy Name for Data Virtualization?
No. **Data virtualization is a key technology *within* a data fabric, but it is not the entire architecture.** Data virtualization is the component that enables querying data from multiple sources without physically moving it.
A complete data fabric builds upon this capability by adding other essential layers, such as an AI-driven metadata catalog (a knowledge graph), automated data integration workflows, and a unified governance framework. Data virtualization is the engine; the data fabric is the entire vehicle, including the chassis, navigation, and security systems.
### Does This Mean I Have to Rip Out Everything I Already Have?
No. A core value proposition of a data fabric is that it is a **non-disruptive, complementary layer** that integrates with your existing technology investments.
Your data warehouses, data lakes, and operational databases remain in place. The fabric connects to them, making their data accessible through a unified interface. The goal is to enhance and integrate what you already have, not to initiate a costly "rip and replace" project.
> A data fabric's purpose is to get more value out of the data you already have by building bridges between silos, not by forcing a migration to a new platform.
### How Does This Actually Help with Data Governance?
A data fabric centralizes and automates data governance. Instead of manually applying policies across dozens of systems, you define security rules, access controls, and quality standards once within the fabric.
The fabric then automatically enforces these policies across every connected data source. For example, a rule to mask personally identifiable information (PII) is applied consistently whether a user is querying a CRM, a cloud data lake, or an on-premise database. This provides centralized control and a comprehensive audit trail, simplifying compliance with regulations like GDPR and CCPA.
### What's the Difference Between a "Logical" and a "Physical" Data Fabric?
This distinction is about how data actually gets handled.
* A **logical data fabric** primarily uses data virtualization. It leaves data in its original source and uses a semantic metadata layer to create a unified view for users - strong for real-time analytics and ad-hoc exploration.
* A **physical data fabric** focuses on the optimized movement and transformation of data. It may create performance-tuned data products or cache frequently accessed data in a central analytics platform - better suited for intensive analytics and machine learning workloads where query speed matters most.
Most production data fabric platforms blend both approaches, using an AI-powered orchestration engine to decide whether to virtualize a query (logical) or move the data (physical) based on the workload.
---
If your organization is weighing a data fabric against a fully decentralized approach, the guide to [data mesh consulting](/insights/data-mesh-consulting/) covers when domain-owned data products make more sense than a centralized fabric. And since governance is usually the deciding factor either way, compare a fabric's automated policies against manual [data governance](/data-governance/) programs before committing to an architecture.
---
## What Is HDFS: Architecture, Limitations & 2026 Guide
Source: https://dataengineeringcompanies.com/insights/what-is-hdfs/
Published: 2026-07-21T10:10:56.295662+00:00
Description: Learn exactly what is hdfs, its architecture, and limitations for modern data platforms. Our 2026 guide helps evaluate consultants for HDFS migration.
Most advice on **what is HDFS** is stuck in the Hadoop boom years. That advice is obsolete.
If you're a CTO, Head of Data, or enterprise architect, the pertinent question isn't what HDFS is, but whether your team should keep operating it, contain it, or migrate off it as part of a broader **data pipeline architecture** modernization program. In 2026, HDFS is rarely a greenfield choice. It's a legacy estate decision.
## Why 'What Is HDFS' Is The Wrong Question in 2026
The popular framing treats HDFS like a default building block for big data. It isn't.
A **2025 Gartner report notes that only 12% of new Hadoop deployments include HDFS as primary storage, as 78% of organizations running Hadoop today are actively migrating to cloud object storage (S3, ADLS, GCS) due to cost and latency limitations** ([bigdatatrunk.com coverage of that Gartner note](https://bigdatatrunk.com/top-50-interview-questions-for-hdfs/)). That should change how leadership evaluates every HDFS discussion.
### What leaders should ask instead
Stop asking for a definition. Ask these:
- **Is HDFS still aligned with the workload?** Batch-heavy, large-file pipelines are one thing. Elastic analytics, lakehouse patterns, and cloud-native AI pipelines are another.
- **What is the operating burden?** HDFS carries storage, cluster, replication, and metadata management concerns that modern cloud storage services abstract away.
- **What is the replacement path?** For many organizations, the primary design decision sits upstream and downstream from storage. Think Databricks, Snowflake, dbt, Airflow, and governance controls across AWS, Azure, or GCP.
> **Executive view:** HDFS is now a platform liability review, not a platform aspiration.
### When HDFS still deserves a seat at the table
There are still legitimate reasons to keep it for now:
- **Existing Hadoop dependencies** that would be expensive to re-platform immediately
- **Stable batch workloads** built around large sequential reads
- **Controlled on-prem environments** where cloud migration is constrained by policy or timing
But if you're launching a new analytics platform, building a new governed data lake, or hiring a consulting partner for platform selection, HDFS shouldn't be your assumed starting point. It should be the incumbent system your modernization plan evaluates against cloud object storage and managed data platform services.
## HDFS Architecture Through a Modern Lens
HDFS was built for a different era of data engineering. Understanding that architecture explains why it still works well in narrow scenarios and why it fails outside them.
**HDFS uses a master-slave architecture with a single NameNode storing filesystem metadata and DataNodes storing data in large blocks, typically 128 MB. This design reduces metadata overhead for sequential scans but consumes disproportionate NameNode memory for small files, limiting clusters to under 100 million files before performance degrades** ([Apache HDFS design documentation](https://hadoop.apache.org/docs/r1.2.1/hdfs_design.html)).
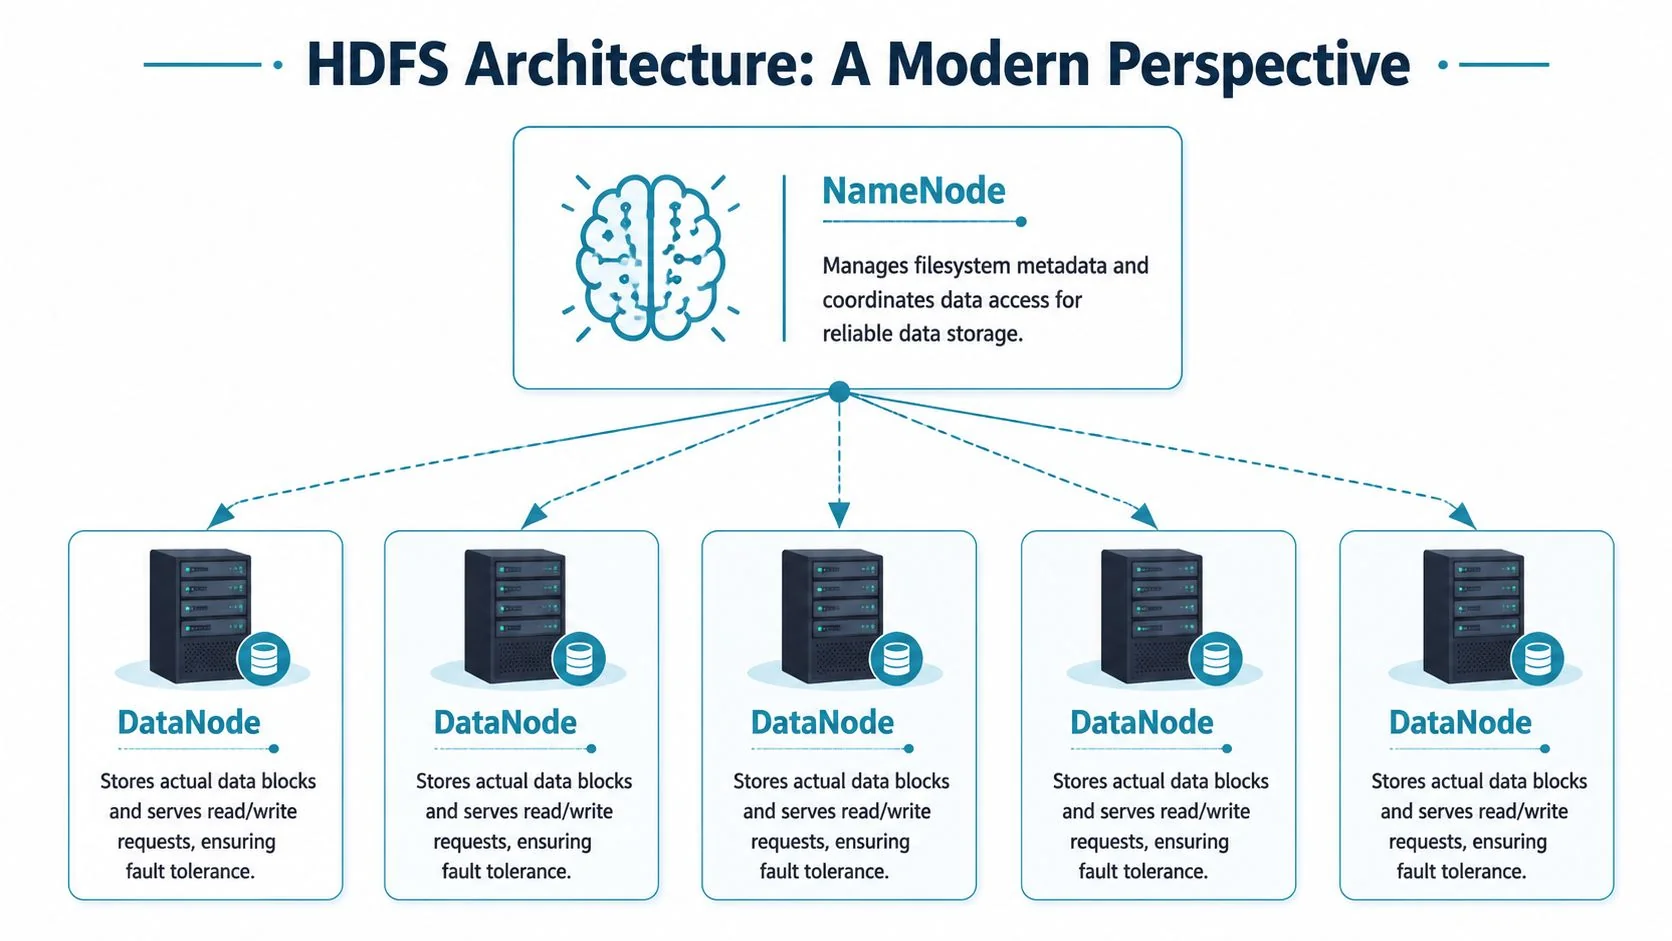
### The design choice that made sense then
Think of HDFS like a warehouse optimized for pallets, not envelopes.
A **128 MB block** works well when Spark, MapReduce, or Hive jobs scan very large files. Fewer, larger blocks mean less metadata overhead and better aggregate throughput across many nodes. That was the right design for log processing, archive-scale batch analytics, and petabyte-oriented storage on commodity hardware.
HDFS also separated concerns cleanly. The NameNode tracked the namespace and block locations. DataNodes handled the actual data blocks. For big sequential reads, that's efficient and predictable.
### Why that same design breaks modern patterns
Modern data platforms don't behave like early Hadoop clusters. They deal with:
- **Many more small objects**
- **Frequent table maintenance**
- **Interactive analytics**
- **Mixed batch and near-real-time pipelines**
- **AI and ML workflows that need lower-latency access patterns**
Those patterns put pressure on metadata, not just throughput.
> HDFS isn't bad technology. It's specialized technology. Most teams now run workloads outside that specialization.
For consulting buyers, this matters because architecture decisions cascade into vendor selection. A partner that only says “HDFS scales” is giving you a history lesson. A serious data engineering consultancy should explain how storage interacts with your orchestration layer, table formats, governance model, and cloud landing zone.
### What this means for platform selection
If your target state includes Snowflake, Databricks, dbt, Airflow, BigQuery, or cloud-native lakehouse patterns, HDFS is usually the wrong control point. The strategic work shifts to:
- storage abstraction over object stores
- open table format choices
- workload isolation
- data governance and lineage
- cost controls by environment and team
That is why “what is HDFS” matters only as background. The primary leadership issue is fit.
## How HDFS Operations Impact Business Agility
The business case against HDFS usually shows up in operations before it shows up in architecture diagrams.
**HDFS achieves fault tolerance with a default replication factor of 3, meaning each block is stored on three separate DataNodes. While this ensures resilience against node failure, it creates a 200% storage overhead and is optimized for a write-once-read-many access pattern, making it suboptimal for low-latency, real-time query workloads** ([Simplilearn HDFS overview](https://www.simplilearn.com/tutorials/hadoop-tutorial/hdfs)).
### The operational trade-off
Replication is the core bargain. You get resilience. You pay for it in storage duplication and operational rigidity.
That trade-off was acceptable when teams prioritized durable batch processing over flexibility. It becomes painful when the business wants rapid model retraining, faster ingestion cycles, or multi-engine access across SQL, notebooks, and downstream applications.
### Why agility suffers
Three constraints show up repeatedly in HDFS estates:
- **Storage overhead is fixed.** Replication protects data, but it also locks in higher storage consumption.
- **Update patterns are restrictive.** Write-once-read-many is a poor fit for workloads that require frequent changes, compacting, or low-latency mutation patterns.
- **Operational tuning stays manual.** Teams spend time managing the platform instead of improving data products.
> If your data team spends more energy preserving the storage layer than improving delivery speed, the platform is holding the business back.
The practical impact isn't abstract. Product teams wait longer for data availability. Platform teams fight backlog instead of modernization. Finance sees infrastructure that doesn't flex with demand. That's why HDFS decisions belong in budget, architecture, and vendor review conversations together.
## HDFS vs Cloud Object Storage A Strategic Comparison
The strategic replacement for HDFS usually isn't another distributed filesystem. It's **cloud object storage** combined with a modern data platform stack.
If you're evaluating AWS data engineering, Azure data engineering, or GCP and BigQuery data engineering options, compare the operating model first. For a useful companion read on how storage choices affect warehouse, lake, and mart design, [get HelpWithMetrics' data insights](https://helpwithmetrics.com/blog/data-warehouse-vs-data-lake-vs-data-mart/) before you lock the target architecture.
### HDFS vs Cloud Object Storage
| Criterion | HDFS | Cloud Object Storage (S3/ADLS/GCS) |
|---|---|---|
| **Primary model** | Distributed filesystem tied closely to Hadoop-era patterns | Object storage used by modern cloud data platforms |
| **Scaling model** | Cluster-based expansion with infrastructure planning | Elastic storage model aligned to cloud services |
| **Operational burden** | Higher. Teams manage storage nodes, replication behavior, and filesystem concerns | Lower. Managed cloud services remove much of the storage administration layer |
| **Workload fit** | Strong for large-file, streaming batch access | Better fit for mixed analytics, lakehouse, sharing, and multi-engine consumption |
| **Latency profile** | Built for throughput, not low-latency interactive behavior | Better aligned with modern cloud analytics stacks and service integration |
| **Small-file handling** | Poor fit when file counts rise sharply | Usually easier to integrate with modern compaction and table-management patterns |
| **Platform ecosystem** | Best within legacy Hadoop environments | Native fit for Snowflake, Databricks, serverless query engines, and governed cloud lakes |
| **Commercial model** | Infrastructure-heavy and operationally fixed | Consumption-oriented and easier to align with cloud finance controls |
### The real decision criteria
Leaders often frame this as HDFS versus S3, ADLS, or GCS. That's incomplete. A more complete comparison is:
- **legacy storage-centric platform**
- versus
- **cloud-native data operating model**
That broader model includes orchestration, transformation, governance, security boundaries, environment promotion, and vendor support. Object storage wins because it enables the rest of the architecture your teams want to build.
### Keep HDFS only if these conditions are true
Use this short filter:
1. **Your core workloads remain batch-oriented and stable**
2. **Your Hadoop dependencies are still business-critical**
3. **A cloud move would create more disruption than value in the near term**
If those conditions aren't true, stop optimizing around HDFS. Start planning the migration.
## Executing the HDFS Modernization Playbook
A successful HDFS modernization project is not a storage copy job. It's a platform redesign with migration sequencing, validation, and cost control built in.
**Data engineering consulting project costs have clear benchmarks: a Discovery Audit typically costs $8k–$40k (2–4 weeks), while a full Platform Build and migration ranges from $60k–$300k (8–16 weeks), giving leaders concrete budget thresholds for planning** ([data engineering consulting cost benchmarks](https://complereinfosystem.com/data-engineering-services-consulting-2026)).
### The four-phase playbook
1. **Discovery and assessment**
Inventory data domains, pipeline dependencies, table formats, access patterns, security requirements, and downstream consumers. During this phase, teams learn which workloads should move first and which should be retired.
2. **Target platform selection**
Choose the destination based on workload shape, governance requirements, and operating model. That usually means combinations such as Databricks plus object storage, Snowflake plus governed ingestion, dbt for transformation, and Airflow for orchestration.
A strong planning reference is [DataEngineeringCompanies.com's migration insights](https://dataengineeringcompanies.com/insights/data-migration-best-practices/), especially for sequencing and risk control.
Before execution, align stakeholders around the migration path:
3. **Migration and refactoring**
Move data, rewrite or adapt pipelines, and replace HDFS-bound assumptions in jobs and access layers. Some assets can be lifted with minimal change. Others need full redesign.
4. **Validation and optimization**
Don't stop at cutover. Tune cost, performance, observability, and governance. For operating discipline, leaders should track **Data Pipeline Latency, Data Accuracy Rate, System Uptime, and Cost Per Terabyte** ([KPI guidance for data engineering](https://kpidepot.com/kpi-data/data-engineering-55)).
> **Practical rule:** Fund the assessment properly. Cheap discovery creates expensive migration surprises.
### The mistake to avoid
Don't approve a migration scoped only around data movement. The meaningful work is dependency analysis, pipeline redesign, security mapping, and platform operating model changes.
## How to Vet a Data Engineering Consultancy for Your Migration
HDFS migration is where generalist firms get exposed. You don't need a vendor that knows Hadoop terminology. You need one that can redesign platform architecture, prove cloud execution capability, and tie migration choices to business latency requirements.
According to **DataEngineeringCompanies.com's analysis of 86 data engineering firms**, the firms worth shortlisting are the ones that connect migration delivery to platform specialization, governance discipline, and measurable operating outcomes, not just “big data experience.”
### The shortlist questions that matter
Ask every consultancy these five questions:
- **How do you map workload latency to platform choices?** A churn model may only need **daily updates**, while a fraud detection system needs **sub-second latency**, and the partner must prove it can meet that inference requirement ([vendor evaluation guidance for predictive analytics](https://www.perceptive-analytics.com/how-to-evaluate-data-engineering-consulting-firms-for-predictive-analytics/)).
- **What target stack do you recommend and why?** Force specificity. Ask whether the destination is Snowflake, Databricks, BigQuery, or a hybrid design, and how dbt and Airflow fit into delivery.
- **How will you measure success after cutover?** Require named operational KPIs such as **Pipeline Completeness Rate**, **Data Freshness SLA Adherence**, **Schema Validation Pass Rate**, and **Mean Time to Detect** ([data quality KPI framework](https://uvik.net/blog/data-quality-metrics-kpis/)).
- **What is your governance model during migration?** This should cover lineage, access controls, auditability, and rollback handling.
- **What happens after go-live?** Demand enablement, documentation, runbooks, and knowledge transfer.
### Specialist depth beats broad claims
If the consultancy positions itself as cloud-native, test it. Ask for point-of-view depth on warehouse and lakehouse trade-offs. For example, a partner discussing **[Snowflake data platform expertise](https://www.faberwork.com/latest-thinking/collaborating-with-faberwork-a-snowflake-partner)** should be able to explain where Snowflake fits versus Databricks, not just claim familiarity.
> A migration partner earns trust by narrowing choices, not by praising every platform equally.
Use a formal scorecard, not sales impressions. This [guide for selecting data engineering partners](https://dataengineeringcompanies.com/insights/data-engineering-due-diligence-checklist/) is a good starting point for procurement and technical due diligence.
The best next step is simple. Decide whether HDFS is a system you're keeping temporarily or exiting deliberately. If you're exiting, scope a discovery audit, define the target platform, and run vendor diligence with a migration-specific scorecard. For teams that want a faster shortlist, DataEngineeringCompanies.com helps buyers compare consultancies by platform expertise, budget fit, and modernization scope before the RFP process starts.
---
## What Is Lakehouse Architecture? A Practical Guide
Source: https://dataengineeringcompanies.com/insights/what-is-lakehouse-architecture/
Published: 2025-12-13T06:58:58.532724+00:00
Description: Discover what is lakehouse architecture and how it merges data lakes and warehouses to power modern AI and analytics. An expert guide to the essentials.
TL;DR: Key Takeaways
The Unification: Lakehouse architecture merges the reliability/structure of Data Warehouses with the scale/flexibility of Data Lakes into a single platform for both BI and AI.
Technical Core: It relies on open table formats (Delta Lake, Iceberg, Hudi) to bring ACID transactions, time travel, and schema enforcement to low-cost cloud object storage.
Cost & Performance: By decoupling storage (cheap object store) from compute (specialized engines like Spark or Trino), it offers massive cost savings over proprietary warehouses without sacrificing query speed.
AI Enablement: It eliminates data movement friction, giving data scientists direct access to fresh production data, which accelerates model development and enables real-time AI use cases.
Migration Strategy: Move incrementally. Start with a pilot project, establish governance first, and use a phased approach rather than a high-risk "rip-and-replace."
Lakehouse architecture is a data platform design that stores all data - structured and unstructured - in low-cost object storage, then adds a transactional layer on top so that layer behaves like a database. **It gives you the ACID transactions, schema enforcement, and query performance of a data warehouse, running directly on the open, cheap storage of a data lake, so one copy of data can serve both BI dashboards and AI/ML workloads.**
## Why Did the Lakehouse Replace the Old Warehouse-vs-Lake Split?
**Data teams used to choose between two incomplete options: a data warehouse for structured, governed reporting, or a data lake for flexible, ungoverned storage. Neither handled both AI and BI well, so companies built costly pipelines to shuttle data between the two. The lakehouse merges both into one governed system.**
### The Old Split: Data Warehouse vs. Data Lake
A **data warehouse** is a highly structured repository, optimized for fast SQL queries and business reporting. Data must be cleaned, transformed, and loaded into a predefined schema before it can be analyzed (a process called schema-on-write). This ensures data quality and performance for BI but is rigid, expensive, and cannot handle unstructured data like video, audio, or raw logs.
A **data lake**, in contrast, is a vast, low-cost storage repository that holds raw data in its native format. It can store any type of data - structured, semi-structured, or unstructured - without a predefined schema (schema-on-read). This flexibility makes it ideal for data science and machine learning, which require massive, diverse datasets. The primary drawback is a lack of governance and transaction support, which often leads to a "data swamp" - a repository of unreliable, untrustworthy data.
> The core conflict was clear: you could have the structure and reliability of a warehouse or the flexibility and scale of a lake, but not both in a single system. This forced companies to build complex and costly data pipelines to move data between the two, creating data duplication, latency, and governance headaches.
The rise of AI and the demand for real-time analytics pushed both models past their limits at once - teams needed diverse data types and the reliability required for production decisions. The lakehouse was designed specifically to close that gap.
## What Are the Core Components of a Lakehouse Architecture?
**A lakehouse is built from four decoupled layers: cloud object storage for raw files, an open table format that adds ACID transactions on top of that storage, a metadata and governance catalog, and a processing layer where separate query engines read the same data.** Each layer can be swapped independently, which is what keeps the stack from locking you into one vendor.
### The Storage Layer
The architecture begins with the **storage layer**. This is the physical repository for all data - structured, semi-structured, and unstructured. The key characteristic is its reliance on low-cost, highly scalable **cloud object storage**.
Instead of proprietary storage systems common in traditional data warehouses, a lakehouse uses standard cloud services:
* [Amazon S3](https://aws.amazon.com/s3/) (Simple Storage Service)
* [Azure Data Lake Storage (ADLS) Gen2](https://azure.microsoft.com/en-us/products/storage/data-lake-storage)
* [Google Cloud Storage (GCS)](https://cloud.google.com/storage)
This approach cuts storage costs by roughly an order of magnitude compared to a traditional warehouse's proprietary storage. Data is stored in open-source columnar formats like **Apache Parquet** or **ORC**, which are optimized for analytical query performance by allowing engines to read only the necessary columns, significantly speeding up queries.
### What Is the Table Format Layer, and Why Does It Matter?
**The table format layer is a metadata and transaction log that sits on top of raw files in object storage, adding database-like reliability to a file-based system.** It is what closes the traditional data lake's biggest gap: no transaction support and no schema enforcement.
The key enabling technologies are open table formats:
* **[Delta Lake](https://delta.io/)**
* **[Apache Iceberg](https://iceberg.apache.org/)**
* **[Apache Hudi](https://hudi.apache.org/)**
These formats provide **ACID transactions** (Atomicity, Consistency, Isolation, Durability) directly on the data lake. This allows multiple users and processes to safely read and write data concurrently without risking data corruption. They also enable governance features like schema enforcement (preventing bad data from being written) and time travel (querying data as it existed at a specific point in the past).
> This is the component that turns a potential "data swamp" into a reliable, high-performance database. It is the technical piece that lets BI dashboards and AI models run on the same copy of data with full transactional integrity.
This diagram shows how the lakehouse evolved, borrowing the best traits from its predecessors.
As you can see, the lakehouse isn't a replacement but a hybrid, inheriting the structure from the data warehouse and the flexibility from the data lake.
### The Central Nervous System: The Metadata And Governance Layer
While the table format layer ensures reliability, the **metadata and governance layer** provides intelligence and control. It functions as a central catalog for all data assets within the lakehouse, defining what the data is, where it is located, who can access it, and its lineage.
This layer centralizes several critical functions:
1. **Data Discovery:** A searchable catalog of datasets, tables, and schemas enables users to find the data they need without manual intervention.
2. **Access Control:** It manages permissions at a granular level (table, row, or column), ensuring data security and compliance.
3. **Data Lineage:** It tracks the origin of data and all transformations applied to it. This matters for auditing, debugging, and understanding dependencies - a common challenge in complex [data pipeline architecture examples](/insights/data-pipeline-architecture-examples/).
A central catalog, such as [AWS Glue](https://aws.amazon.com/glue/) Data Catalog or Unity Catalog by [Databricks](https://www.databricks.com/product/unity-catalog), enforces a single set of governance rules, regardless of the tool used to access the data.
### The Engine: The Processing Layer
Finally, the **processing layer** provides the computational power to execute queries and run jobs on the data. A key advantage of the lakehouse is the separation of storage and compute, which allows organizations to select the optimal processing engine for a specific workload.
This flexibility means different engines can operate on the same single source of data. Common engines include:
* **[Apache Spark](https://spark.apache.org/):** The standard for large-scale data processing and machine learning.
* **[Trino](https://trino.io/) (formerly PrestoSQL):** A high-performance, distributed SQL query engine designed for interactive analytics and BI.
* **Photon, [Dremio](https://www.dremio.com/), and others:** Specialized query engines optimized for accelerating specific types of BI and reporting queries.
With a multi-engine architecture, a data scientist can use Spark for model training while a business analyst uses Trino to power a BI dashboard. Both are accessing the exact same, up-to-date data without interference. This eliminates data silos and the operational overhead of synchronizing data between different systems.
## How Does Lakehouse Architecture Power AI and Analytics?
**A lakehouse lets data scientists and BI analysts query the same governed dataset instead of working from separate copies.** In the older two-tier model, raw ML data sat in a data lake while business-ready data was locked in a warehouse, so teams built ETL pipelines just to move and duplicate data between them - and data scientists often ended up working with stale, isolated datasets.
The lakehouse removes that separation by giving both groups one governed platform for all data types.

### Unifying Data For Smarter AI
The primary benefit for AI is the ability to serve both historical and real-time data directly to machine learning models from a single source of truth. This has a profound impact on the AI development lifecycle.
Instead of waiting for data engineering to provision and move datasets, data scientists gain immediate access to fresh, production-quality data. This direct access dramatically shortens the model development lifecycle, enabling faster iteration and the deployment of more accurate models.
This pattern is now common practice. [Dremio's 2025 State of the Data Lakehouse report](https://www.dremio.com/blog/key-takeaways-from-the-2025-state-of-the-data-lakehouse-report-navigating-the-ai-landscape/) found most surveyed organizations already using data lakehouses to support AI model development.
### Enabling Powerful Real-World Use Cases
The practical applications of this architectural shift are immediate and impactful. The ability to combine structured transactional data with unstructured data like images, text, and sensor logs enables new classes of applications.
Here are a few technical examples:
* **Real-Time Fraud Detection:** A financial institution can train models on a live stream of transaction data combined with historical customer behavior, allowing them to detect and block fraudulent activity in milliseconds.
* **Predictive Maintenance:** An industrial company can analyze IoT sensor data from machinery alongside maintenance logs and production schedules to predict part failure before it occurs, preventing costly downtime.
* **Generative AI and LLMs:** Training large language models requires processing massive, diverse text and code datasets. A lakehouse provides a scalable, governed environment for storing and processing these unstructured datasets efficiently.
In each scenario, the lakehouse removes the friction that previously existed between data storage and its use in data science applications.
> The key takeaway is that the lakehouse isn't just a storage strategy - it's what turns data from a passive asset locked in silos into a resource models and dashboards can both use directly.
### Accelerating The Entire Analytics Spectrum
The benefits extend beyond AI. The lakehouse improves the entire analytics workflow. The same platform used to train complex machine learning models can also power the interactive business intelligence (BI) dashboards used by business leaders.
This means a business analyst and a data scientist can query the same, up-to-the-minute data concurrently. The analyst gets fast, reliable reports for dashboards, while the data scientist has direct access to the raw, granular data needed for deep exploration. This single source of truth ensures consistency and builds trust in data across the organization.
By removing the architectural barriers between BI and AI, the lakehouse fosters a more collaborative and efficient data culture. It provides the flexible, scalable, and reliable foundation required to answer today's business questions and build the intelligent applications of tomorrow.
## How Does a Lakehouse Compare to a Data Warehouse and a Data Lake?
**A data warehouse gives you strong BI performance but rigid, structured-only data. A data lake gives you flexible storage for any data type but weak governance. A lakehouse combines both: open storage for any data type, plus the schema enforcement and transaction guarantees a warehouse provides.** The tradeoffs below determine which workloads each one handles well. For a deeper look at the storage-layer differences alone, see [data warehouse vs. data lake](/insights/data-warehouse-vs-data-lake/).
The decision is not always about replacing one system with another but about selecting the right architecture for the intended workload.
### Data Types And Flexibility
The most significant differentiator is how each architecture handles data.
A **data warehouse** is highly prescriptive. It is designed for structured data, such as transactional records from an ERP or CRM. It requires a rigid **schema-on-write** process, where data must be structured before loading. This guarantees data quality but makes it unsuitable for unstructured or semi-structured data.
The **data lake** is the opposite. It employs a **schema-on-read** approach, allowing any data type to be ingested without prior structuring. This provides maximum flexibility for exploratory analysis and data science but often leads to a "data swamp" of ungoverned, low-quality data.
The **lakehouse architecture** strikes a balance. It stores all data types on low-cost object storage like a data lake but imposes structure and governance through open table formats. This hybrid model offers the flexibility to store any data type with the reliability and schema enforcement needed for production analytics.
### BI Performance vs. AI Workloads
Performance characteristics also vary significantly across these systems.
**Data warehouses** are purpose-built for high-performance SQL queries for business intelligence. Their proprietary storage formats and tightly coupled query engines are optimized for slicing and dicing structured data. For this specific use case, they remain highly performant. However, they are poorly suited for AI and machine learning, which require access to large, diverse datasets that a warehouse cannot store.
A pure **data lake** can store the necessary data for AI but lacks the performance and transactional integrity to serve BI dashboards directly and reliably.
> A lakehouse bridges this performance gap. It supports high-performance SQL for BI while also providing direct, efficient access to the underlying raw data files for AI and ML workloads. This eliminates the need for separate systems, allowing both analysts and data scientists to work from a single, consistent copy of the data.
### Cost Structure And Schema Management
The economic models are as different as the technologies.
Data warehouses typically bundle storage and compute, which becomes costly at scale. Their proprietary nature also creates vendor lock-in, making future migrations expensive and complex.
Data lakes, built on commodity object storage like [Amazon S3](https://aws.amazon.com/s3/) or [Google Cloud Storage](https://cloud.google.com/storage), offer a much more cost-effective storage foundation. A lakehouse inherits this low-cost storage and adds a control layer on top of it. By using open table formats like [Delta Lake](https://delta.io/), [Apache Iceberg](https://iceberg.apache.org/), and [Apache Hudi](https://hudi.apache.org/), it reintroduces schema enforcement. This prevents data corruption and allows schemas to evolve over time without breaking downstream pipelines.
### Lakehouse vs Data Warehouse vs Data Lake: A Feature Comparison
This table provides a clear breakdown of the differences, highlighting the core capabilities and ideal use cases for each architecture.
| Feature | Data Warehouse | Data Lake | Lakehouse Architecture |
| :----------------------- | :------------------------------------------- | :---------------------------------------- | :------------------------------------------------------------ |
| **Primary Data Types** | Structured (Relational) | All types (raw, unstructured) | All types (structured, unstructured) |
| **Schema Management** | Schema-on-Write (rigid) | Schema-on-Read (flexible, but risky) | Balanced (schema enforcement & evolution) |
| **BI Performance** | Excellent | Poor to Fair | Good to Excellent |
| **AI/ML Support** | Limited to None | Excellent (but ungoverned) | Excellent (governed, direct access) |
| **Cost-Effectiveness** | High (proprietary storage) | Low (commodity object storage) | Low (commodity storage with added value) |
| **Data Reliability** | High | Low | High (ACID transactions) |
While a traditional warehouse may still be suitable for specific, high-concurrency reporting workloads, a pure data lake is rarely a viable foundation for production analytics. The lakehouse has established itself as the modern standard, offering a unified platform that serves the dual requirements of both BI and AI.
## Which Lakehouse Platforms Should You Consider?
**Databricks and Snowflake dominate the lakehouse market, with the major cloud providers offering their own native alternatives.** Understanding the architecture in theory is different from picking a platform: each vendor implements it differently, and the right choice depends on your existing stack and team skills. Of the 86 firms profiled in the Data Engineering Companies Index, 66 list Snowflake and 64 list Databricks as a core platform - a rough proxy for how often each shows up in active consulting engagements.
### The Pioneers and the Power Players
[Databricks](https://www.databricks.com/) and [Snowflake](https://www.snowflake.com/en/) built their platforms from opposite starting points, and that history still shapes how each product works today.
**Databricks** originated the lakehouse concept. Its platform is built on open-source technologies, primarily Apache Spark for processing and Delta Lake for the storage management layer. This open-core model is a key differentiator for organizations seeking to avoid vendor lock-in.
* **Philosophy:** Prioritize open standards and provide granular control over the data environment.
* **Target User:** Organizations with strong data engineering capabilities who want to build a customizable platform on top of the open-source ecosystem.
**Snowflake**, a leader in the cloud data warehouse market, has evolved its platform to incorporate lakehouse capabilities. It offers a fully managed, proprietary system focused on ease of use. With features like Snowpark and support for Iceberg tables, Snowflake enables data science and engineering workloads within its established platform.
* **Philosophy:** Provide a polished, all-in-one "data cloud" that abstracts away underlying complexity.
* **Target User:** Companies that prioritize rapid time-to-value, simplified management, and a single platform for both BI and emerging AI use cases.
> The decision often comes down to a strategic choice between the flexibility and control of an open ecosystem versus the turnkey experience of a fully managed service.
### The Cloud Giants Weigh In
The major cloud providers - AWS, Google Cloud, and Microsoft Azure - have also built lakehouse solutions from their native services. Their advantage: storage, catalog, and compute already share IAM, networking, and billing with the rest of the account, which matters most for organizations already committed to a specific cloud platform.
* **Amazon Web Services (AWS):** [AWS](https://aws.amazon.com/) offers the components to build a custom lakehouse. This typically involves using Amazon S3 for storage, AWS Glue for the data catalog, and Amazon Athena or Redshift for querying. This approach provides maximum flexibility but requires more integration effort.
* **Microsoft Azure:** [Azure](https://azure.microsoft.com/en-us) Synapse Analytics is positioned as an integrated platform for data warehousing, data integration, and big data analytics, working in conjunction with Azure Data Lake Storage and Power BI.
* **Google Cloud Platform (GCP):** [GCP](https://cloud.google.com/)'s approach is centered on BigQuery. Its architecture, which has always separated storage and compute, is well-suited for lakehouse workloads. By querying data directly in Google Cloud Storage, BigQuery effectively blurs the line between a warehouse and a lake.
Each cloud provider offers a viable path, particularly for organizations looking to consolidate their technology stack with a single vendor. These platforms are often core components of a comprehensive [modern data stack](/insights/modern-data-stack/).
## How Do You Migrate to a Lakehouse Architecture?
**Migrate in phases, not all at once - a full cutover across every system is the most common way these projects fail.** Start with a well-defined pilot: a new AI initiative or a reporting dashboard struggling with data integration, rather than the most complex legacy system. Each stage should deliver a measurable result before the next one starts.

This focused approach allows the team to gain experience with the new architecture in a controlled environment. Once the POC demonstrates clear value, the migration can be expanded strategically.
### A Phased Migration Roadmap
A structured, step-by-step process cuts the risk of the migration stalling out.
1. **Start with a Single Business Use Case:** Select one specific, tangible problem to solve, such as building a predictive model for customer churn or creating a unified sales dashboard. Maintain a narrow focus.
2. **Establish Governance from Day One:** Data governance cannot be an afterthought; otherwise, you risk creating another data swamp. Implement a unified catalog, define access control policies, and establish data quality monitoring from the outset.
3. **Ingest Relevant Data Incrementally:** Begin by ingesting only the data required for the pilot project. Use modern tools to stream data or replicate it in batches. This is more manageable than a large, one-time data dump. For complex workflows, [data orchestration platforms](/insights/data-orchestration-platforms/) handle the scheduling and dependency management.
4. **Demonstrate Value and Scale Out:** After the pilot succeeds, communicate its value across the organization. Use it as an internal case study to showcase business outcomes, such as faster insights, more accurate models, or reduced costs. This success will help secure the resources needed to tackle subsequent workloads.
> The objective is a series of tactical wins, not a "big bang" cutover. Each successful project builds technical expertise and organizational confidence, creating a flywheel effect that accelerates the broader migration.
### Vetting Your Data Engineering Partner
Unless your organization has a large, specialized data team, you will likely need an external data engineering partner to guide the migration. Selecting the right partner is critical to avoiding costly errors and accelerating time-to-value.
When evaluating potential consultancies, ask specific, technical questions.
* **Open Table Formats:** "Describe your hands-on experience with Delta Lake, Apache Iceberg, and Hudi. Provide a specific example where you used features like time travel or schema evolution to solve a client's problem."
* **Cloud Cost Optimization:** "What are your primary strategies for managing and optimizing cloud spend on a lakehouse?" A strong answer should include details on compute instance selection, storage tiering, and query optimization techniques.
* **MLOps on the Lakehouse:** "Provide a case study of a production MLOps pipeline you have built directly on a lakehouse." This demonstrates practical experience in operationalizing AI, not just building data tables.
Choosing a partner is about verifying technical capability. The right firm will act as an extension of your team, providing the experienced guidance needed for a successful migration.
## Got Questions? We've Got Answers
Here are answers to common questions from teams evaluating a lakehouse architecture.
### Does this mean I have to scrap my data warehouse?
Not necessarily, and certainly not immediately. A rip-and-replace migration is rare. The more common approach is a hybrid model where the lakehouse and data warehouse coexist.
Your existing data warehouse may still be the optimal tool for specific high-performance BI dashboards. The lakehouse often begins by handling new projects, especially those involving unstructured data, streaming analytics, or machine learning. The long-term goal may be consolidation, but the process is typically a gradual migration.
### What is the significance of open table formats like Delta Lake and Iceberg?
These formats are the core enabling technology of the lakehouse. They function as a transactional layer on top of raw data files (e.g., Parquet) in cloud storage.
> These formats bring the reliability of a traditional database to the data lake. They add critical features like **ACID transactions**, schema enforcement, and data versioning ("time travel"). This is what transforms a potential data swamp into a structured, governed, and trustworthy source of truth.
### How does a lakehouse reduce data engineering work?
By simplifying the data stack. The primary benefit is the elimination of data duplication and movement between different systems. Instead of maintaining a separate lake for raw data and a warehouse for refined data, you have one unified platform.
This consolidation results in several efficiencies:
* **Less Data Movement:** It reduces the need for costly and fragile ETL jobs to copy data from the lake to the warehouse, saving on compute costs and engineering overhead.
* **Fewer Systems to Manage:** A single platform reduces operational complexity. The team has one system to secure, govern, and maintain.
* **Single Source of Truth:** All users - from BI analysts to data scientists - work from the same consistent data, which eliminates discrepancies and conflicting reports.
---
Most lakehouse migrations fail on governance and partner selection, not on the technology itself. If you're vetting outside help, use the questions above and compare implementation options in our [Databricks consulting](/databricks-consulting/) directory.
---
## Where to Find Data Engineering Companies: 7 Directories and Cloud Partner Finders Compared (2026)
Source: https://dataengineeringcompanies.com/insights/where-to-find-data-engineering-companies/
Published: 2025-12-30T08:58:39.461684+00:00
Description: Compare Clutch, GoodFirms, and the Databricks, Snowflake, Microsoft, and Google Cloud partner directories for sourcing data engineering firms.
Data engineering firms rarely rank for generic searches, so buyers end up sourcing candidates from directories and cloud partner finders instead. Each source verifies a different thing - client reviews, vendor-awarded certifications, or self-reported rate data - and none of them replace a reference call. Here is how the seven main options compare.
## How the directories compare
| Directory | Best for | What it verifies | Cost |
| :--- | :--- | :--- | :--- |
| **DataEngineeringCompanies.com** | Cross-platform shortlist with rate data | Self-reported rates, project minimums, and platform certifications | Free |
| **Clutch** | Broad market research with client reviews | Client-interview-based reviews and project budgets | Free to browse; paid vendor placement |
| **GoodFirms** | Budget benchmarking across a global pool | User-submitted reviews and a Leaders Matrix ranking | Free to browse |
| **Databricks Consulting Partners** | Databricks-specific delivery validation | Partner tier and delivery badges | Free |
| **Snowflake Partner Directory** | Snowflake-specific delivery validation | Partner tier (Select, Premier, Elite) | Free; some resources need a login |
| **Microsoft Partner Center** | Azure and Fabric delivery validation | Solutions Partner for Data and AI designation | Free |
| **Google Cloud Partner Advantage** | BigQuery and Vertex AI delivery validation | Google-awarded specializations | Free |
Do not treat this table as a ranking. Match the row to what you already know about your platform and budget, then go read the source.
## 1. DataEngineeringCompanies.com
This site indexes 86 data engineering firms with self-reported rate bands, project minimums, and platform certifications, filterable by budget and platform. Across the index, hourly rates run $45 to $250/hr (median $100), and 41% of firms price under $100/hr - a useful budget baseline before contacting anyone. Coverage skews toward major platforms: 88% of listed firms offer AWS work, 81% Azure, 77% Snowflake, 74% Databricks.
Because this is a specialist site rather than a general reviews platform, it does not carry third-party client reviews. Treat the profile data as a starting filter, not a substitute for a reference call. Free to use, no login required.
[Visit DataEngineeringCompanies.com](https://dataengineeringcompanies.com/)
## 2. Clutch
Clutch lists thousands of technology vendors under a "BI and Big Data" category rather than a dedicated data engineering one, so filtering takes more work. Its value is verified client reviews: Clutch analysts interview a sample of each vendor's clients and publish structured write-ups covering project scope, budget range, and outcomes.
Filter by industry, rate, and location to narrow the list, then read individual reviews for pipeline, warehousing, or migration work specifically - the category also includes generalist BI shops that never touch a data pipeline. Free to browse; vendors can pay to improve placement, which affects who shows up first.
[Visit Clutch](https://clutch.co/it-services/analytics)
## 3. GoodFirms
GoodFirms runs a dedicated Data Engineering category with its own review process and a Leaders Matrix that ranks firms by delivery ability and market presence. It draws from a large, global pool, including smaller boutiques that may not appear on Clutch. Hourly-rate filters help with early budget checks.
Because coverage is global, confirm a shortlisted firm's US presence, time zone overlap, and any compliance requirements - HIPAA, SOC 2 - before relying on GoodFirms data alone. Free to browse.
[Visit GoodFirms - Data Engineering](https://www.goodfirms.co/big-data-analytics/data-engineering)
## 4. Databricks Consulting Partners
Databricks publishes its own partner directory, filterable by competency (data engineering, machine learning, governance, migration) and partner tier. Partners are Databricks-certified, and some carry specific delivery badges such as Mosaic AI Delivery Provider.
This is the fastest way to confirm a firm's Databricks credentials are real rather than claimed. It has no rate data or project minimums, and it only covers Databricks-committed firms - it will not surface a strong Snowflake or BigQuery specialist. Free, no login required.
[Visit Databricks Consulting Partners](https://www.databricks.com/company/partners/consulting-and-si)
## 5. Snowflake Partner Directory
Snowflake's directory works the same way: partners hold tiers (Select, Premier, Elite) tied to certified headcount and customer outcomes, and some appear in Partner Connect for in-product trials. Filter by service type, industry, and region.
Like the Databricks directory, it carries no pricing information and is scoped to Snowflake work only - useful once Snowflake is the confirmed platform, less useful for an open platform search. Free to browse; some training resources require a Snowflake login.
[Visit the Snowflake Partner Directory](https://www.snowflake.com/en/why-snowflake/partners/all-partners/)
## 6. Microsoft Partner Center (Data and AI)
Microsoft's partner finder lets you filter for the Solutions Partner for Data and AI (Azure) designation, which requires partners to meet Microsoft's performance and skilling requirements, plus a separate filter for Microsoft Fabric offers.
It is the clearest available signal for Azure- and Fabric-specific delivery experience. As with the other cloud portals, there is no pricing or project-minimum data - use it for validation and shortlisting, then gather commercial terms directly. Free to access.
[Visit Microsoft Partner Finder](https://partner.microsoft.com/en-us/partnership/find-a-partner)
## 7. Google Cloud Partner Advantage
Google's partner directory is organized around specializations - Data Analytics, Data Management, Machine Learning - that require partners to demonstrate repeatable, successful implementations before Google awards the badge.
It is the most direct way to confirm a firm's BigQuery or Vertex AI experience is Google-validated rather than self-claimed. Pricing and project minimums are not listed; expect to gather that information after narrowing to a few Google-specialized partners. Free to access.
[Visit Google Cloud Partner Advantage](https://cloud.google.com/partners/)
## How should you choose a directory?
Match the source to what you already know. If the platform is undecided, start with a cross-platform source - this index, Clutch, or GoodFirms - and compare reviews and rate bands. If the platform is already chosen, go straight to that vendor's official partner directory; the certification bar is higher and the search is faster.
## When is a cloud partner portal the better route?
Use a Databricks, Snowflake, Microsoft, or Google Cloud partner directory once the platform decision is locked and you need delivery-team validation, not platform comparison. These portals verify certifications and delivery history on one specific stack but skip pricing entirely, so pair them with a rate-transparent directory or direct quotes before shortlisting on cost.
## How to turn a directory list into a shortlist
A directory produces a longlist, not a decision. Narrow it in four steps:
1. Filter by platform and budget first, using rate bands where a directory publishes them.
2. Read two or three recent case studies or reviews per firm and check they involve a project similar in scope and data volume to yours.
3. Confirm the platform certifications shown on a directory profile against the vendor's own partner-page listing - directories can lag behind status changes.
4. Run a short technical call with your top four to six candidates before sending a full RFP. Fewer than four weakens comparison; more than six mostly slows procurement.
If you need a structured way to run that comparison, see our [data engineering RFP checklist](/data-engineering-rfp-checklist/).
## FAQ
### Is Clutch or GoodFirms better for finding a data engineering company?
Neither is purpose-built for the category. Clutch has more reviews and stronger geographic filters; GoodFirms has a dedicated Data Engineering category, which narrows the search faster. Use both if the budget allows the extra research time, and cross-check any firm that appears on one but not the other.
### Do the cloud partner directories show pricing?
No. Databricks, Snowflake, Microsoft, and Google Cloud all publish free partner directories, but none list hourly rates or project minimums. Use them to confirm certifications and delivery history, then request pricing directly from the two or three partners you shortlist.
### How many directories should you check before shortlisting?
Two is usually enough: one cross-platform source for rate and review data, plus the relevant cloud partner directory if the platform is already decided. Checking more than three rarely surfaces new candidates and mostly adds duplicate research time.
### Are directory reviews and partner badges the same kind of verification?
No. Reviews (Clutch, GoodFirms) reflect client-reported experience; partner badges (Databricks, Snowflake, Microsoft, Google Cloud) reflect vendor-administered certification requirements. Neither confirms availability, current team quality, or cultural fit - only a reference call and a working session do that.
---
# Section 2: Vendor profiles (86 firms)
## phData
Source: https://dataengineeringcompanies.com/phdata/
Website: https://www.phdata.io
Founded: 2014
Team size: 500
Hourly rate: $150-250
Minimum project: $100K+
Platforms: Snowflake, AWS, Databricks, dbt
Industries: Financial Services, Manufacturing, Healthcare, Retail
Best for: phData is the right call for mid-enterprise teams running or planning a Snowflake migration at $100K+ scale — its 500+ completed migrations and Snowflake Elite status translate into lower risk and faster time-to-value than a generalist SI at the same rate band.
Mid-market fit: High
Premier Snowflake specialist with 500+ successful migrations, proprietary automation tools, and elite partnerships with Snowflake and AWS
#### Why buyers choose phData
phData's case rests on a single, deliberate specialization: Snowflake. The firm holds Snowflake Elite partner status and points to more than 500 completed migrations since it was founded in 2014. For a buyer whose end state is Snowflake and whose main risk is the migration itself, that focus beats a generalist systems integrator at the same rate band.
#### Team, platforms, and industries
The 500-person team is rated expert in both platform migration and data modernization, with strong AI/ML and analytics coverage, and it pairs Snowflake with AWS and dbt rather than spreading across every cloud. That profile fits Fortune 500 buyers in Financial Services, Manufacturing, Healthcare, and Retail moving off legacy warehouses.
#### When phData is the wrong fit
At $150-250/hr with a $100K+ project minimum, phData is an upper-mid-market commitment, not a quick tactical hire. And the same Snowflake focus makes it the wrong pick for a parallel multi-platform program spanning Snowflake, Azure Synapse, and BigQuery, or for SAP and mainframe integration outside its platform focus.
### FAQs
**Q: Is phData a good fit for a Snowflake migration?**
A: Yes. phData is a Snowflake Elite partner and points to 500+ completed migrations since 2014, with expert-rated capability in platform migration. For mid-enterprise teams whose end state is Snowflake, that single-platform depth is its core argument over a generalist systems integrator at the same $150-250/hr band.
**Q: How much does phData cost?**
A: phData bills $150-250/hr with a $100K+ minimum project size. That positions it as an upper-mid-market option suited to enterprise Snowflake migrations and data modernization rather than small, tactical engagements.
**Q: What platforms and industries does phData specialize in?**
A: phData focuses on Snowflake paired with AWS, Databricks, and dbt, not a generic all-cloud claim. Its 500-person team most often serves Financial Services, Manufacturing, Healthcare, and Retail buyers moving off legacy data warehouses.
**Q: When is phData the wrong choice?**
A: phData is a weak fit for a single-vendor program spanning Snowflake, Azure Synapse, and BigQuery in parallel, and more so when the work requires SAP or mainframe integration outside its platform focus. Teams needing broad multi-platform coverage are usually better served elsewhere.
---
## Tiger Analytics
Source: https://dataengineeringcompanies.com/tiger-analytics/
Website: https://www.tigeranalytics.com
Founded: 2011
Team size: 3000
Hourly rate: $100-200
Minimum project: $50K+
Platforms: Snowflake, Databricks, AWS, GCP, Azure, PowerBI
Industries: Retail, CPG, Consumer Goods, Banking
Best for: Tiger Analytics is the right call for large retailers and CPG companies that need advanced analytics, AI/ML, and GenAI capability at enterprise scale — a 3,000-person bench and GenAI accelerators support programs smaller specialist firms cannot staff, at $100–200/hr.
Mid-market fit: High
Analytics and AI specialist working with 16 of top 20 retail companies, delivering GenAI accelerators and data science solutions
#### Why buyers choose Tiger Analytics
Tiger Analytics holds Elite partner status with both Snowflake and Databricks - a combination few firms can claim. A 6,000-person team and a proprietary accelerator stack (Tiger ML, Tiger Datasphere, Tiger Boost, Insights Pro) serve Fortune 1000 companies across retail, CPG, banking, and manufacturing. Google Cloud named it 2026 Data & Analytics Partner of the Year for North America.
#### Certifications, industries, and reach
Platform credentials include 324 Snowflake SnowPro Core and 35 SnowPro Advanced certifications. Industry focus runs deepest in retail and CPG - where ISG named the firm a top choice - with secondary strength in banking, insurance, manufacturing, and life sciences. Tiger Analytics operates across the US, UK, Canada, India, Singapore, and Australia, and appears in Forrester, Gartner, and Everest reports.
#### When Tiger Analytics is the wrong fit
Tiger Analytics is a multi-cloud analytics generalist, not a single-platform deep specialist - a firm that has completed 500+ migrations on one destination offers tighter expertise on that specific path. It is also a poor fit for mid-market teams with sub-$50K budgets or for programs centered on SAP integration, mainframe modernization, or niche verticals outside retail and CPG.
### FAQs
**Q: What type of engagement is Tiger Analytics best suited for?**
A: Tiger Analytics fits best when a buyer needs full-stack analytics and AI delivery at enterprise scale - think a retailer or CPG company modernizing its data platform on Snowflake or Databricks while simultaneously standing up ML and GenAI capabilities. The firm's proprietary accelerators (Tiger ML, Tiger Datasphere, Insights Pro) reduce time-to-value on programs that combine data engineering with advanced analytics or machine learning, which is where its 6,000-person bench pays off.
**Q: What does Tiger Analytics charge and what is the project minimum?**
A: Published rates run $100 - 200 per hour with a $50K+ project floor, positioning the firm in the mid-to-upper market. That rate reflects a large global delivery model with significant India-based staffing, so blended rates are often lower than comparable US-only shops at similar hourly ranges. Buyers with sub-$50K budgets or a need for a small, focused team will find better options elsewhere.
**Q: Which platforms and industries does Tiger Analytics specialize in?**
A: Tiger Analytics holds Elite partner status with both Snowflake and Databricks - the two dominant lakehouse and cloud data warehouse platforms - and is a Google Cloud Premier Partner named Google Cloud's 2026 Data & Analytics Partner of the Year in North America. AWS and Azure round out the platform coverage. Industry depth is strongest in retail and CPG, where ISG named the firm a leader in retail specialty analytics, with secondary strength in banking, insurance, manufacturing, and life sciences.
**Q: When is Tiger Analytics the wrong choice?**
A: Tiger Analytics is a weak fit for a buyer whose primary requirement is a single-platform specialist - for instance, a firm that has done hundreds of migrations exclusively on one destination platform will offer tighter expertise on that path. It is also a poor match when the engagement is centered on mainframe or SAP integration, when the industry is outside retail, CPG, financial services, or manufacturing, or when the budget falls below $50K.
---
## Analytics8
Source: https://dataengineeringcompanies.com/analytics8/
Website: https://www.analytics8.com
Founded: 2002
Team size: 100
Hourly rate: $100-200
Minimum project: $25K+
Platforms: Snowflake, AWS, Azure, GCP, dbt, Databricks, Tableau, PowerBI, Looker
Industries: Cross-industry
Best for: Mid-market companies needing end-to-end data solutions; data modernization projects
Mid-market fit: Very High
Data and analytics consultancy with 20+ years experience, covering entire data lifecycle from strategy to governance
#### Why buyers choose Analytics8
Analytics8 holds Elite Snowflake partner status, the Visionary Tier from dbt Labs (highest tier as of March 2026), and a Databricks Select Tier partnership - spanning the three pillars of the modern data stack. Founded in 2002 with 800+ clients and a vendor-independent philosophy, it suits mid-market buyers who want one partner across data strategy, platform build, BI, and governance.
#### Team, clients, and industries
Roughly 100 consultants operate across US offices and internationally in Bulgaria and the UK. Named clients include Roche, Anheuser-Busch InBev, iFit, Crocs, and Thoma Bravo. Industry coverage - healthcare, life sciences, private equity, financial services, insurance, manufacturing, and retail - has dedicated practice pages and case studies. Boathouse Capital invested in February 2025, signaling an active expansion phase.
#### When Analytics8 is the wrong fit
Analytics8 is a full-lifecycle generalist, which becomes a liability when the selection criterion is the deepest single-platform credential. A buyer specifically needing Snowflake-first migration volume comparable to dedicated Snowflake-only shops, or SAP and mainframe integration outside the modern cloud stack, will find narrower specialists a better match. The $25K+ minimum also rules out early-stage teams with limited scope.
### FAQs
**Q: What type of engagement is Analytics8 best suited for?**
A: Analytics8 fits best when a mid-market organization needs a single partner to own the full data lifecycle - strategy, platform selection, cloud migration, data engineering, BI, and governance - rather than a specialist brought in for one narrow workstream. Its vendor-independent stance and 800+ client history make it particularly well-matched for buyers who have outgrown spreadsheets and point tools and need an accountable end-to-end delivery partner.
**Q: What does Analytics8 typically charge and what is the project minimum?**
A: Analytics8's published rate is $100-200 per hour with a project minimum of $25,000. Clutch reviewers note the firm generally delivers on schedule and within budget, though some have flagged that pricing is not the lowest in the market. The rate positions it above offshore-heavy staffing models but below large consulting firms with comparable partner-driven delivery.
**Q: Which platforms and industries does Analytics8 specialize in?**
A: On the platform side, the firm holds Elite Snowflake partner status, Visionary Tier with dbt Labs (the highest level in that program), and Databricks Select Tier - complemented by AWS, Azure, GCP, Tableau, Power BI, and Looker. Industry coverage includes healthcare, life sciences, private equity, financial services, insurance, manufacturing, and retail, with named client work across Roche, Anheuser-Busch InBev, iFit, Crocs, and Thoma Bravo.
**Q: When is Analytics8 the wrong choice?**
A: Analytics8 is a weaker fit for programs where the primary selection criterion is the deepest single-platform credential - for example, a buyer who needs a Snowflake-first firm with a high volume of completed Snowflake-only migrations, or a Databricks Premier partner, rather than a firm credentialed across multiple platforms. It is also a poor fit for projects requiring SAP or mainframe integration outside the modern cloud stack, or for early-stage companies whose scope and budget fall below the $25K project minimum.
---
## Lovelytics
Source: https://dataengineeringcompanies.com/lovelytics/
Website: https://lovelytics.com
Founded: 2019
Team size: 50
Hourly rate: $150-225
Minimum project: $50K+
Platforms: Snowflake, Databricks, AWS, Azure, dbt, Matillion
Industries: Cross-industry
Best for: Companies seeking Snowflake-to-Databricks migration; cloud data platform specialists
Mid-market fit: High
Cloud data platform specialist with Brickbuilder Migration accelerator for Snowflake-to-Databricks transitions
#### Why buyers choose Lovelytics
Lovelytics holds Databricks Golden Partner status, the Brickbuilder Specialization in AI and Security & Governance (renewed through 2026), and was the first consulting partner backed by Databricks Ventures. That relationship means eligibility for migration funding, early roadmap access, and co-developed GenAI tooling the firm says cuts migration time and cost by up to 80%.
#### Scale, cloud coverage, and industries
Lovelytics acquired Datalytics, a Buenos Aires-based Databricks specialist, in January 2025, growing to roughly 340 professionals across the US, Canada, and Latin America. Delivery covers AWS (Advanced Tier), Azure (Cloud Solutions Partner), and Google Cloud. Industries include manufacturing, healthcare, energy, retail and CPG, and financial services. The firm has won Databricks Partner of the Year four consecutive years.
#### When Lovelytics is the wrong fit
Lovelytics is a Databricks shop, and buyers not committed to that platform will not get the same leverage. Engagements requiring platform-agnostic advice across competing lakehouse vendors, or organizations already on a non-Databricks stack needing operational support rather than migration, will find the focus limiting. The $50K+ minimum and active growth trajectory may also constrain bandwidth for small exploratory scopes.
### FAQs
**Q: What type of buyer is Lovelytics best suited for?**
A: Lovelytics is the strongest fit for mid-market to enterprise organizations that have chosen Databricks as their data and AI platform and need an implementation partner with deep, validated expertise on that stack. The firm's sweet spot is platform migration - particularly moving from Snowflake, Teradata, or legacy on-premises warehouses to the Databricks lakehouse - but it also handles greenfield lakehouse builds, Unity Catalog governance implementations, and production-grade GenAI deployments. Buyers in manufacturing, healthcare, energy, retail, or financial services will find industry-specific accelerators already built.
**Q: What does Lovelytics charge, and what is the project minimum?**
A: Lovelytics rates run $150-225/hr, positioning it as an upper-mid-market firm - below the large SIs but above generalist boutiques. The minimum engagement is $50K+. Buyers should also note that Lovelytics is eligible for Databricks migration funding through the Databricks Migration Partner Program, which can offset a portion of project cost for qualifying migrations.
**Q: Which platforms and industries does Lovelytics cover?**
A: Databricks is the primary platform, and all major cloud hosts are supported: AWS (Advanced Tier partner), Microsoft Azure (Cloud Solutions Partner), and Google Cloud. The firm also works with Snowflake, dbt, Tableau, and governance tooling including Unity Catalog, Collibra, and Atlan. Industry coverage spans manufacturing, healthcare and life sciences, energy and utilities, retail and CPG, financial services, and communications and media - each with named delivery experience and purpose-built accelerators.
**Q: When is Lovelytics the wrong choice?**
A: Lovelytics is not the right fit if your organization is not committed to Databricks as its primary platform. Buyers looking for platform-agnostic advice across competing lakehouse vendors, or those deeply invested in a non-Databricks stack who need ongoing operational support rather than migration, will find the firm's specialization a constraint rather than an advantage. Engagements that are primarily AI/ML research or model development without a Databricks foundation are also a weaker match, given the firm's delivery model is built around lakehouse architecture first.
---
## Slalom
Source: https://dataengineeringcompanies.com/slalom/
Website: https://www.slalom.com
Founded: 2001
Team size: 13000
Hourly rate: $150-250
Minimum project: $50K+
Platforms: AWS, Azure, GCP, Snowflake, Databricks, PowerBI, Tableau
Industries: Cross-industry, Public Sector, Financial Services
Best for: Large enterprises running AWS-anchored digital transformation programs — particularly those involving GenAI — where Slalom's AWS GenAI Partner of the Year status and 13,000-person delivery model are differentiating factors.
Mid-market fit: High
Global business and technology consultancy with fiercely human approach, 45+ offices, recognized AWS/Microsoft/Google partner
#### Why buyers choose Slalom
Slalom's case rests on a genuine AWS relationship: Premier Tier Services Partner since 2010, 20 AWS Competencies, and the 2024 AWS GenAI Consulting Partner of the Year (Global) award verified by Canalys. That credential reflects delivery - including United Airlines' first two GenAI use cases in production - backed by 1,300+ AWS consultants across 54 offices in 12 countries.
#### Team scale, platforms, and industries served
The 13,000-person team covers Financial Services, Public Sector, Retail, Travel & Hospitality, Energy & Utilities, and Healthcare. AWS, Azure, GCP, Snowflake, and Databricks form the platform stack. Data modernization and AI/ML enablement are core practices, not adjacent services - anchored by the AWS Data & Analytics Competency and the Generative AI Competency.
#### When Slalom is the wrong fit
Slalom is a poor choice when work is platform-specific. A Snowflake migration or Databricks build without AWS as the anchor pays for scale it will not use. Boutique specialists holding Elite or Premier status on Snowflake, Databricks, and dbt move faster at lower cost - and Slalom's edge disappears when the buyer's footprint is primarily Azure or GCP.
### FAQs
**Q: What type of engagement is Slalom best suited for?**
A: Slalom fits best when an enterprise has committed to AWS and is running a broad digital transformation program that involves data modernization, GenAI adoption, or cloud migration alongside business process change. Its 1,300+ AWS consultants, 20 AWS Competencies, and local-market delivery model in 54 offices are most valuable when scope is wide and stakeholders are distributed - not when a single data platform needs to be stood up quickly.
**Q: What does Slalom charge and what is the minimum project size?**
A: Slalom's published rate band is $150-250/hr with a $50K+ minimum project. That positions it at the upper end of mid-market and into large-enterprise territory. The rate reflects enterprise-grade governance, industry-specific accelerators, and a local delivery model - overhead that is appropriate for multi-workstream transformation programs but adds cost to narrowly scoped data engineering engagements.
**Q: Which platforms and industries does Slalom focus on?**
A: AWS is Slalom's primary cloud platform - it has held AWS Premier Tier Services Partner status since 2010 and won the 2024 AWS GenAI Consulting Partner of the Year (Global) award. Azure, GCP, Snowflake, and Databricks round out the platform stack. Industry depth is broad, spanning Financial Services, Public Sector, Retail, Travel & Hospitality, Healthcare, and Energy & Utilities, with AWS competencies in each of these verticals.
**Q: When is Slalom the wrong choice?**
A: Slalom is a poor fit for companies that need a focused, single-platform data engagement - particularly Snowflake migrations, dbt implementations, or Databricks Lakehouse builds where AWS is not the anchor. The $150-250/hr rate and enterprise delivery model add overhead that most contained data programs do not justify. If the cloud footprint is primarily Azure or GCP rather than AWS, the firm's deepest competitive advantage does not apply, and a platform-specialist boutique will typically deliver faster and at lower cost.
---
## Tredence
Source: https://dataengineeringcompanies.com/tredence/
Website: https://www.tredence.com
Founded: 2013
Team size: 3000
Hourly rate: $100-200
Minimum project: $50K+
Platforms: Snowflake, Databricks, AWS, Azure, GCP, PowerBI
Industries: Retail, CPG, Consumer Goods
Best for: Tredence is the right call for retail and CPG enterprises running large-scale analytics or GenAI programs where accelerators that cut migration timelines by 50%+ have a measurable ROI — a 3,000-person bench supports the staffing depth those programs require at $100–200/hr.
Mid-market fit: High
GenAI accelerators reducing migrations by 50%+, works with 16 of top 20 retail companies, delivers 30% TCO reduction
#### Why buyers choose Tredence
Tredence has spent twelve years embedding in retail and CPG - serving 8 of the top 10 global retailers and 8 of the top 10 CPG companies. Third-party recognition backs those claims: Snowflake Elite with 388 SnowPro certifications, Databricks Retail & CPG Partner of the Year four consecutive years (2022-2025), and a #1 Leader in ISG's 2025 Provider Lens.
#### Team, accelerators, and platforms
At 4,200+ practitioners organized across 7 practices - GenAI, Data Science, Data Engineering, SCM, CXM, MLOps, Digital Engineering - Tredence runs at enterprise delivery scale. Its Atom.AI library (150+ AI/ML solutions, 12+ GenAI agents) drives the 50%+ time-to-value reduction. Published outcomes include a $220M EBITDA improvement for a US grocery chain and $58M+ retail media revenue, both on Databricks.
#### When Tredence is the wrong fit
Tredence is not the right partner for sub-$50K engagements or teams wanting a tight senior pod over a large delivery organization. Buyers whose primary need is pure-play Snowflake or Databricks migration expertise with no retail or CPG angle will find more focused specialists. At $100-200/hr with a $50K+ minimum, weigh whether vertical accelerators justify the premium over generalist alternatives.
### FAQs
**Q: What type of buyer is Tredence the strongest fit for?**
A: Tredence is strongest for enterprise retail and CPG organizations - ideally those running large-scale data modernization, GenAI programs, or supply chain analytics. The firm serves 8 of the top 10 global retailers and CPG companies, and its Atom.AI accelerator library is purpose-built for those verticals. Buyers outside retail and CPG can still engage Tredence (it covers telecom, healthcare, travel, and manufacturing), but the deepest domain IP and partner recognition are concentrated in consumer-facing industries.
**Q: What are Tredence's typical rates and engagement minimums?**
A: Tredence bills at $100-200/hr with a $50K+ project minimum, positioning it as a mid-market-to-enterprise option. That rate reflects a 4,200-person delivery organization with deep vertical specialization and a library of pre-built accelerators - buyers should evaluate whether the accelerator-driven time-to-value offsets the cost compared to smaller, lower-rate boutiques.
**Q: Which platforms and industries does Tredence cover?**
A: On the platform side, Tredence holds Snowflake Elite partner status (388 SnowPro certifications, 250+ dedicated experts) and has won the Databricks Retail & CPG Partner of the Year award four consecutive years - so both major lakehouse platforms are well-supported. Cloud coverage includes AWS, Azure, and GCP. Vertically, retail and CPG are the primary focus, with secondary practices in telecom, travel and hospitality, manufacturing, healthcare and life sciences, and BFSI.
**Q: When is Tredence the wrong choice?**
A: Skip Tredence if your budget is under $50K, if you need a small senior-heavy pod rather than a large delivery team, or if your project has no meaningful retail or CPG component and you need the deepest possible platform specialization on a single cloud. Buyers who want a boutique Snowflake-only or Databricks-only migration specialist, or who are early-stage and need advisory-level work without a full delivery apparatus, will find better-matched options elsewhere.
---
## Accenture
Source: https://dataengineeringcompanies.com/accenture/
Website: https://www.accenture.com
Founded: 1989
Team size: 779000
Hourly rate: $120-200
Minimum project: $100K+
Platforms: AWS, Azure, GCP, Snowflake, Databricks, SAP, Salesforce, PowerBI
Industries: Cross-industry, All sectors
Best for: Fortune 500 organizations running multi-cloud transformations across AWS, Azure, and GCP simultaneously, where a single integrator needs to own the full program.
Mid-market fit: Medium
Global professional services firm with 9000+ AI experts, comprehensive digital transformation capabilities across all industries
---
## Sigmoid
Source: https://dataengineeringcompanies.com/sigmoid/
Website: https://sigmoid.com
Founded: 2013
Team size: 1000
Hourly rate: $50-150
Minimum project: $25K+
Platforms: Snowflake, Databricks, AWS, GCP, Azure, dbt
Industries: CPG, Retail, Banking, Manufacturing
Best for: Sigmoid is the right call for mid-market companies that need ML engineering and data platform work across Snowflake, Databricks, and the major clouds without paying top-of-market rates — a $50–150/hr range makes serious ML work accessible at a $25K+ entry point.
Mid-market fit: Very High
Exceptional value provider with ML Engineering expertise, Everest 'Star Performer' 2024, 98% ML accuracy
#### Why buyers choose Sigmoid
Sigmoid's case rests on ML engineering depth at offshore price points. Named an Everest Group Star Performer in 2024, the firm delivers end-to-end machine learning pipelines - feature stores, model monitoring, real-time serving - with a reported 98% model accuracy rate, at $50-150/hr. That combination of ML sophistication and cost efficiency is difficult to match in the mid-market.
#### Team, platforms, and industry depth
The 1,000-person team, operating from India and the US, pairs Snowflake and Databricks expertise with proprietary migration accelerators that reduce common modernization timelines by 30-40%. CPG and retail are the strongest verticals, with industry-specific accelerators for demand forecasting and inventory optimization. AI/ML enablement and data modernization are both rated Expert.
#### When Sigmoid is the wrong fit
Sigmoid is the wrong choice for buyers who need deep single-platform specialization - such as Snowflake Elite or Databricks Premier credentials - or for regulated-industry programs where niche domain compliance expertise is the primary selection criterion. Buyers who need breadth across a non-CPG or non-retail vertical may find the firm's industry accelerators less applicable.
### FAQs
**Q: Is Sigmoid good for Snowflake migrations?**
A: Yes. Sigmoid is a certified Snowflake partner with demonstrated expertise in migrating legacy data warehouses to Snowflake. Their team of 1,000 engineers includes Snowflake SnowPro certified practitioners, and they have developed migration accelerators that reduce typical timelines by 30–40% compared to standard implementations.
**Q: How does Sigmoid's pricing compare to US-based data engineering firms?**
A: Sigmoid's rates of $50–$150/hr are 40–60% below comparable US-headquartered data engineering firms. Their offshore delivery model from India enables cost efficiency without sacrificing ML expertise. Clients consistently report 98% model accuracy rates and on-time delivery across CPG, retail, and banking engagements.
**Q: What industries does Sigmoid specialize in?**
A: Sigmoid's primary industry focus is CPG (Consumer Packaged Goods), retail, banking, and manufacturing. They have built proprietary industry-specific data accelerators for CPG demand forecasting, retail inventory optimization, and banking regulatory reporting automation — giving them a measurable speed advantage over generalist firms in these verticals.
**Q: Is Sigmoid a good fit for mid-market companies?**
A: Sigmoid rates 'Very High' for mid-market fit in our analysis. Their $25K+ minimum project size, flexible engagement models, and offshore pricing make them particularly well-suited for companies that need enterprise-grade ML capabilities — feature stores, model monitoring, real-time inference — without enterprise-grade pricing.
---
## Infosys
Source: https://dataengineeringcompanies.com/infosys/
Website: https://www.infosys.com
Founded: 1981
Team size: 300000
Hourly rate: $50-100
Minimum project: $100K+
Platforms: Databricks, AWS, Azure, GCP, Snowflake, SAP, PowerBI
Industries: Global Enterprise, Financial Services, Manufacturing, Retail
Best for: Global enterprises; offshore development model; large-scale implementations
Mid-market fit: Medium
Databricks Disruption Partner, leader in next-gen digital services and consulting with massive global delivery capability
---
## Deloitte
Source: https://dataengineeringcompanies.com/deloitte/
Website: https://www2.deloitte.com
Founded: 1845
Team size: 450000
Hourly rate: $75-175
Minimum project: $50K+
Platforms: AWS, Azure, GCP, Snowflake, Databricks, SAP, PowerBI, Tableau
Industries: Cross-industry, Regulated industries, Financial Services
Best for: Regulated-industry enterprises — healthcare systems, banks, insurers — that need C-suite advisory, compliance framing, and Big Four sign-off alongside the technical delivery.
Mid-market fit: Medium
Big Four consultancy integrating data engineering with business consulting, serving Fortune 500 with comprehensive services
---
## InterWorks
Source: https://dataengineeringcompanies.com/interworks/
Website: https://interworks.com
Founded: 1996
Team size: 500
Hourly rate: $150-275
Minimum project: $50K+
Platforms: Snowflake, Tableau, Matillion, AWS, Azure, GCP
Industries: Cross-industry
Best for: BI and analytics deployments; Tableau and Snowflake specialists
Mid-market fit: Very High
Full-service BI and IT consultancy with world-class data and analytics expertise, Partner of the Year for Snowflake and Tableau
#### Why buyers choose InterWorks
InterWorks pairs two platform loyalties that reinforce each other: Tableau and Snowflake. Founded in 1996, it became Tableau's first Gold Partner in 2012 and has accumulated more than 22 Tableau Partner of the Year awards, including the Salesforce Global award in 2020. InterWorks earned Snowflake's Solution Partner of the Year in 2018 with additional regional awards across Asia-Pacific.
#### Team, KeepWatch, and industries
The team covers data engineering, cloud migration, embedded analytics, and governance across North America, Europe, Australia, and Singapore. KeepWatch - a proprietary managed-services product - monitors BI platforms and data pipelines, which suits mid-market buyers without a 24/7 internal team. More than 2,500 organizations have used InterWorks for Tableau work across finance, healthcare, energy, retail, manufacturing, and government.
#### When InterWorks is the wrong fit
InterWorks rates itself Moderate in AI/ML enablement - a real gap it does not hide. Buyers whose primary workload is Databricks lakehouse architecture, data science, or MLOps pipeline engineering will find the specialization does not align. The $50K+ minimum also rules out small exploratory engagements. A more specialized shop will serve you better if your roadmap is ML-first.
### FAQs
**Q: What kind of buyer gets the most value from InterWorks?**
A: InterWorks is the strongest fit for mid-market organizations whose analytics stack is built around Tableau and Snowflake. The firm has been Tableau's longest-tenured partner - first Gold Partner in 2012 - and has delivered Snowflake migrations and implementations for hundreds of clients globally. Buyers looking to stand up, optimize, or migrate a Tableau-plus-Snowflake environment, including embedded analytics portals or KeepWatch managed services, are in exactly the right place.
**Q: What does InterWorks typically charge, and is there a project minimum?**
A: InterWorks operates in the $150-275/hr range and requires a minimum project engagement of roughly $50K. The firm does not publish fixed-price packages publicly; pricing is scoped to project complexity and engagement type. That rate band positions InterWorks as an upper-mid-market option - not the cheapest Tableau or Snowflake help available, but priced well below large SIs for the caliber of platform-specific expertise on offer.
**Q: Which platforms and industries does InterWorks cover?**
A: Core platform strengths are Tableau and Snowflake, with solid coverage across Matillion, Power BI, Sigma, AWS, Azure, and GCP. Databricks support exists but is not a stated core competency. On the industry side, InterWorks serves finance, healthcare, energy, retail, manufacturing, government, and media - the firm explicitly positions itself as cross-industry rather than vertical-specialist, with clients ranging from Fortune 500 brands to growth-stage companies.
**Q: When is InterWorks the wrong choice?**
A: InterWorks rates itself Moderate in AI/ML enablement, so buyers whose primary workload is Databricks lakehouse architecture, data science platform build-out, or MLOps pipeline engineering will find the specialization does not align well. The $50K+ minimum also rules out small or purely exploratory engagements. If your organization needs deep lakehouse expertise or a firm with a primary identity around data science and ML, a more specialized shop will serve you better.
---
## STX Next
Source: https://dataengineeringcompanies.com/stx-next/
Website: https://www.stxnext.com
Founded: 2005
Team size: 500
Hourly rate: $75-150
Minimum project: $50K+
Platforms: Snowflake, Databricks, AWS, Azure, GCP, Airflow, Spark, Kafka, dbt
Industries: Fintech, Manufacturing, Mobility, Healthcare, Logistics, Financial Services
Best for: European nearshore; fintech, manufacturing, logistics; 200+ data projects; AWS & Snowflake certified
Mid-market fit: Very High
Europe-based leader with 20+ years Python expertise, 500 professionals across Poland/Mexico. AWS & Snowflake certified partner. Dekra ISO 27001/9001 compliant. 200+ data projects delivered. Specializes in enterprise data platforms, real-time streaming, AI-powered analytics. Strong delivery governance and long-term partnerships.
---
## Wipro
Source: https://dataengineeringcompanies.com/wipro/
Website: https://www.wipro.com
Founded: 1945
Team size: 200000
Hourly rate: $50-100
Minimum project: $100K+
Platforms: AWS, Azure, GCP, Snowflake, Databricks, SAP, Hadoop
Industries: Financial Services, Healthcare, Manufacturing, Retail, Telecom
Best for: Large-scale global enterprises; offshore delivery model
Mid-market fit: Medium
Global IT services giant with 200,000+ employees, Big Data platform delivering analytics-driven solutions across industries
---
## Capgemini
Source: https://dataengineeringcompanies.com/capgemini/
Website: https://www.capgemini.com
Founded: 1967
Team size: 300000
Hourly rate: $75-150
Minimum project: $100K+
Platforms: AWS, Azure, GCP, Snowflake, Databricks, SAP, PowerBI
Industries: Manufacturing, Automotive, Financial Services, Energy, Public Sector
Best for: European industrial and engineering-intensive enterprises running Industry 4.0 or R&D data programs where manufacturing-domain depth and on-continent delivery are requirements.
Mid-market fit: Low-Medium
Global leader with 300,000+ professionals, strong Altran engineering capabilities, data & AI transformation at scale
---
## Cognizant
Source: https://dataengineeringcompanies.com/cognizant/
Website: https://www.cognizant.com
Founded: 1994
Team size: 340000
Hourly rate: $75-150
Minimum project: $50K+
Platforms: AWS, Azure, GCP, Snowflake, Databricks, SAP, PowerBI
Industries: Banking, Insurance, Manufacturing, Retail, Energy
Best for: Fortune 2000 retailers and consumer-goods companies running GenAI modernization programs that need a large delivery bench and established enterprise relationships.
Mid-market fit: Medium
Leading with 340,000+ employees, Neuro AI framework, AI Training Data Services, comprehensive data engineering capabilities
---
## Devoteam
Source: https://dataengineeringcompanies.com/devoteam/
Website: https://www.devoteam.com
Founded: 1995
Team size: 11000
Hourly rate: $100-175
Minimum project: $50K+
Platforms: AWS, GCP, Azure, Snowflake, Databricks, Microsoft, Salesforce
Industries: Financial Services, Telecom, Retail, Public Sector
Best for: European enterprises; cloud and cybersecurity specialists
Mid-market fit: Medium
Leading European IT consultancy with 11,000+ experts across 20+ countries, specialized in cloud, data, AI and cybersecurity
---
## Itransition
Source: https://dataengineeringcompanies.com/itransition/
Website: https://www.itransition.com
Founded: 1998
Team size: 3000
Hourly rate: $50-100
Minimum project: $25K+
Platforms: AWS, Azure, GCP, Snowflake, Databricks, Tableau, PowerBI
Industries: Retail, Insurance, Hi-tech, Banking, Manufacturing, Healthcare
Best for: Mid-market companies; full-cycle software development with data engineering
Mid-market fit: High
3000+ engineers providing full-cycle software development, data analytics, ML, and cloud solutions since 1998
---
## Adastra
Source: https://dataengineeringcompanies.com/adastra/
Website: https://adastracorp.com
Founded: 2000
Team size: 100
Hourly rate: $125-200
Minimum project: $50K+
Platforms: Snowflake, Databricks, Keboola, AWS, Azure, GCP
Industries: Financial Services, Banking, Insurance
Best for: Financial services and enterprise data platform implementations
Mid-market fit: Medium
Global data, analytics, and cloud consultancy with 20+ years experience, Snowflake Premier Partner
---
## DataArt
Source: https://dataengineeringcompanies.com/dataart/
Website: https://www.dataart.com
Founded: 1997
Team size: 3000
Hourly rate: $50-100
Minimum project: $50K+
Platforms: AWS, Azure, GCP, Databricks, Snowflake, Spark
Industries: Financial Services, Healthcare, Telecom, Travel, Media
Best for: Custom software development with data engineering; European nearshore
Mid-market fit: High
Global technology consultancy with 3000+ engineers, strong Eastern European presence, custom data solutions
---
## Intellias
Source: https://dataengineeringcompanies.com/intellias/
Website: https://intellias.com
Founded: 2002
Team size: 3000
Hourly rate: $50-100
Minimum project: $50K+
Platforms: AWS, Azure, GCP, Databricks, Snowflake, Spark
Industries: Automotive, Financial Services, Insurance, E-commerce
Best for: Automotive, fintech, and large-scale engineering projects
Mid-market fit: High
3000+ professionals delivering AI/ML, data engineering, and IoT solutions with deep automotive and fintech expertise
---
## iTechArt
Source: https://dataengineeringcompanies.com/itechart/
Website: https://www.itechart.com
Founded: 2002
Team size: 3500
Hourly rate: $50-100
Minimum project: $25K+
Platforms: AWS, Azure, GCP, Databricks, Big Data, Spark
Industries: Fintech, Health Tech, E-commerce, E-learning, Enterprise IT
Best for: VC-backed startups and rapidly scaling tech firms
Mid-market fit: Very High
3500+ engineers specializing in agile dedicated teams, Big Data analytics, AI, and cloud development for startups
---
## Avenga
Source: https://dataengineeringcompanies.com/avenga/
Website: https://www.avenga.com
Founded: 2019
Team size: 2500
Hourly rate: $50-99
Minimum project: $25K+
Platforms: AWS, Azure, GCP, Snowflake, Databricks, Salesforce
Industries: Life Sciences, Financial Services, Manufacturing, Retail
Best for: Regulated industries; nearshore teams; life sciences and finance
Mid-market fit: High
2500+ experts delivering custom software, cloud, and data solutions with security and governance focus for regulated industries
#### Why buyers choose Avenga
Avenga's case rests on nearshore cost efficiency with genuine compliance depth. Engineering centers in Poland, Ukraine, Georgia, and the Philippines deliver Central/Eastern European talent at $50-99/hr - roughly half the cost of equivalent US-based engineering - while working Central European time zones, enabling real-time collaboration with London, Frankfurt, and New York clients.
#### Regulated-industry roots and platform coverage
Avenga formed in 2019 through the merger of three European software consultancies - IT Kontrakt, CoreValue, and Solidbrain - each with roots in financial services and life sciences. That lineage means SOC 2, HIPAA, and GDPR compliance is built in from the start. The firm covers AWS, Azure, GCP, Snowflake, and Databricks across data platform builds and cloud migrations.
#### When Avenga is the wrong fit
Avenga is a broad software consultancy, not a data engineering specialist - all four capability areas sit at Strong rather than Expert. Buyers who need sharp data architecture peaks, cutting-edge ML product development, or deep single-platform credentials will find boutique AI-native firms or dedicated specialists a better match at a comparable rate band.
### FAQs
**Q: Is Avenga a good choice for Snowflake migrations?**
A: Yes, Avenga has strong Snowflake and Databricks capabilities and has delivered cloud migration projects for regulated industries including financial services and life sciences. Their nearshore model (Central European time zones) makes collaboration straightforward for US and European clients. Expect rates of $50–$99/hr for migration engagements, roughly 40–60% below equivalent US-based firms.
**Q: Where are Avenga's engineering teams located?**
A: Avenga operates engineering centers in Poland, Germany, Ukraine, Georgia, and the Philippines. Their primary delivery hubs are in Central and Eastern Europe — specifically Warsaw, Kyiv, and Tbilisi. This nearshore model aligns with US Eastern and European business hours, enabling same-day collaboration without the timezone gap common with India-based offshore teams.
**Q: What industries does Avenga specialize in for data engineering?**
A: Avenga's primary verticals are Life Sciences (pharma, medtech, clinical data), Financial Services (banking, insurance, capital markets), Manufacturing, and Retail. Their compliance experience — SOC 2, HIPAA, GDPR — makes them particularly strong for regulated industry clients who need governance built into the data architecture from the start.
**Q: How does Avenga compare to pure-play data engineering boutiques?**
A: Avenga is a broad software engineering firm with a strong data practice, not a dedicated data engineering boutique. For organizations needing full-stack software plus data capabilities in one partner, Avenga is a strong fit. For organizations with complex ML/AI requirements or deep data architecture challenges, specialist firms like Hashmap, Phdata, or Sigmoid may offer more depth per engagement dollar.
---
## Celebal Technologies
Source: https://dataengineeringcompanies.com/celebal-technologies/
Website: https://celebaltech.com
Founded: 2015
Team size: 1000
Hourly rate: $50-100
Minimum project: $25K+
Platforms: Azure, Databricks, PowerBI, Snowflake, AWS, GCP
Industries: Manufacturing, Retail, CPG, Oil & Gas, BFSI, Healthcare
Best for: Microsoft Azure specialists; PowerBI and AI solutions
Mid-market fit: High
Microsoft Partner of Year 2022-25, Azure AI Platform specialist, enterprise data analytics and migration experts
---
## Fractal Analytics
Source: https://dataengineeringcompanies.com/fractal-analytics/
Website: https://fractal.ai
Founded: 2000
Team size: 5000
Hourly rate: $100-200
Minimum project: $50K+
Platforms: AWS, Azure, GCP, Snowflake, Databricks, Spark
Industries: CPG, Financial Services, Healthcare, Logistics, Retail
Best for: Enterprise AI and decision intelligence; Fortune 500 companies
Mid-market fit: Medium
5000+ employees, Leader in Customer Analytics (Forrester), AI-powered decision intelligence, data engineering services
#### Why buyers choose Fractal Analytics
Fractal holds Forrester Leader recognition in Customer Analytics Services - a designation requiring demonstrated client outcomes and methodology depth, not just self-reported capabilities. For enterprise buyers using analyst reports in vendor evaluation, that credential reduces risk. Fractal's decision intelligence model structures engagements around improving specific business decisions rather than delivering dashboards as an end product.
#### Scale, platforms, and industry depth
At 5,000+ employees, Fractal can staff multi-track programs simultaneously - a data lake build alongside a customer analytics product alongside a forecasting model. Their breadth across CPG, Financial Services, Healthcare, and Logistics is genuine, supported by a full cloud stack: AWS, Azure, GCP, Snowflake, Databricks, and Spark. Data modernization, AI/ML, and business analytics are all rated Expert.
#### When Fractal Analytics is the wrong fit
A 5,000-person firm carries coordination overhead - slower sales cycles, more governance layers, and higher per-hour cost than pure offshore alternatives. Buyers whose primary criterion is deep single-platform specialization, such as Snowflake Elite or Databricks Premier credentials, will find Fractal's broad decision-intelligence methodology less differentiated than its analyst recognition suggests at those narrow scopes.
### FAQs
**Q: Is Fractal Analytics good for Snowflake and Databricks data platform builds?**
A: Yes, Fractal has strong Snowflake and Databricks capabilities, including data lake architecture, ELT pipeline engineering, and ML feature store development on Databricks. Their differentiation is analytics and AI depth layered on top of the platform — they typically combine data engineering with the ML and decision intelligence layer. For pure Snowflake migration work without AI requirements, boutiques like Phdata or Hashmap offer more focused delivery.
**Q: What makes Fractal Analytics different from other large data engineering firms?**
A: Fractal's key differentiator is their decision intelligence methodology and Forrester Leader recognition in Customer Analytics. Unlike firms that deliver dashboards and models as end products, Fractal structures engagements around improving specific business decisions — which creates a clearer ROI story. Their CPG and Financial Services vertical depth (major FMCG and banking clients) is particularly strong.
**Q: What industries does Fractal Analytics serve?**
A: Fractal's strongest verticals are CPG/FMCG (consumer goods analytics, trade promotion optimization), Financial Services (credit risk, fraud detection, customer lifetime value), Healthcare (payer analytics, clinical outcome prediction), and Retail/Logistics (demand forecasting, supply chain optimization). CPG is their most established practice, with major global consumer goods companies as reference clients.
**Q: How does Fractal Analytics compare to BCG X and Accenture for enterprise AI projects?**
A: Fractal offers a middle ground between boutique AI firms and global SIs. Compared to BCG X ($500K+ minimum, strategy-first): Fractal is more accessible ($50K+ minimum), more delivery-focused, and has stronger pure analytics credentials. Compared to Accenture: Fractal has deeper analytics specialization and Forrester recognition in customer analytics, but narrower geographic reach and fewer technology practice breadths. Best for enterprises where analytics and AI are the primary workload, not a component of broader digital transformation.
---
## Solita
Source: https://dataengineeringcompanies.com/solita/
Website: https://www.solita.fi
Founded: 1996
Team size: 2100
Hourly rate: $125-200
Minimum project: $50K+
Platforms: Snowflake, AWS, Azure, GCP, Databricks, dbt
Industries: Manufacturing, Retail, Public Sector, Healthcare, Telecom
Best for: Nordic companies; Snowflake Elite Partner; data-driven transformation
Mid-market fit: High
Nordic Snowflake Elite Partner with 2100+ professionals, Data Cloud Services Growth Partner of Year 2024
---
## BlueCloud
Source: https://dataengineeringcompanies.com/bluecloud/
Website: https://blue.cloud
Founded: 2021
Team size: 100
Hourly rate: $125-200
Minimum project: $50K+
Platforms: Databricks, Snowflake, AWS, Azure, dbt
Industries: Technology, Financial Services, Retail
Best for: Bluecloud is the right fit for mid-market companies modernizing to a cloud data stack on Databricks or Snowflake with AWS or Azure — a 100-person size keeps engagement management lean while a $125–200/hr rate reflects genuine modern-stack expertise rather than generalist consulting margins.
Mid-market fit: High
Cloud-native data engineering consultancy specializing in modern data stack implementations
---
## InData Labs
Source: https://dataengineeringcompanies.com/indata-labs/
Website: https://indatalabs.com
Founded: 2014
Team size: 100
Hourly rate: $70-150
Minimum project: $10K+
Platforms: AWS, Azure, GCP, Databricks, Spark, TensorFlow, PyTorch
Industries: AdTech, E-commerce, Logistics, FinTech, Healthcare, Manufacturing
Best for: AI/ML and data science projects; predictive analytics
Mid-market fit: Very High
80+ AI and data science specialists, 150+ projects worldwide, certified AWS Partner, R&D center
---
## Indium Software
Source: https://dataengineeringcompanies.com/indium-software/
Website: https://www.indium.tech
Founded: 1999
Team size: 3000
Hourly rate: $50-100
Minimum project: $25K+
Platforms: Azure, Databricks, AWS, GCP, Snowflake, PowerBI
Industries: Technology, Healthcare, Financial Services, Retail
Best for: Product engineering with data modernization; Digital assurance
Mid-market fit: High
3000+ associates, AI-driven digital engineering, ibriX accelerator for Databricks, data validation frameworks
---
## Mantel Group
Source: https://dataengineeringcompanies.com/mantel-group/
Website: https://mantelgroup.com.au
Founded: 2017
Team size: 900
Hourly rate: $150-250
Minimum project: $50K+
Platforms: Databricks, Snowflake, AWS, Azure, GCP
Industries: Financial Services, Healthcare, Government, Entertainment
Best for: Australia/NZ enterprises; Elite Databricks Partner; regulated industries
Mid-market fit: High
Elite Databricks Partner in ANZ, 250+ data team with 50+ Snowflake specialists, GenAI powered migrations
---
## N-iX
Source: https://dataengineeringcompanies.com/n-ix/
Website: https://www.n-ix.com
Founded: 2002
Team size: 2400
Hourly rate: $50-100
Minimum project: $25K+
Platforms: AWS, Azure, GCP, Snowflake, Databricks, SAP, OpenText
Industries: Finance, Manufacturing, Telecom, Retail, Healthcare
Best for: European nearshore development; Fortune 500 clients
Mid-market fit: High
2400+ tech experts across 25 countries, 23 years expertise, Global Outsourcing 100 Leader, data and analytics focus
---
## Atrium
Source: https://dataengineeringcompanies.com/atrium/
Website: https://atrium.ai
Founded: 2018
Team size: 100
Hourly rate: $150-250
Minimum project: $50K+
Platforms: Snowflake, Salesforce, Tableau, AWS, Azure, dbt
Industries: Financial Services, Technology, Manufacturing
Best for: Snowflake and Salesforce integration; AI-native consulting
Mid-market fit: High
Snowflake Elite Services Partner, AI-native consulting for data science, analytics, and AI-powered solutions
---
## CHI Software
Source: https://dataengineeringcompanies.com/chi-software/
Website: https://chisw.com
Founded: 2006
Team size: 500
Hourly rate: $50-100
Minimum project: $25K+
Platforms: Azure, AWS, GCP, Databricks, Spark, Kafka
Industries: Healthcare, Education, Financial Services, Technology
Best for: AI-driven software development; GenAI integration; healthcare tech
Mid-market fit: High
AI-driven software development company specializing in GenAI, data engineering pipelines, and ChatGPT integration
---
## Continuus Technologies
Source: https://dataengineeringcompanies.com/continuus-technologies/
Website: https://www.continuus.ai
Founded: 2011
Team size: 100
Hourly rate: $150-250
Minimum project: $25K+
Platforms: Snowflake, Alteryx, FactSet, SimCorp, PowerBI, Tableau
Industries: Financial Services, Banking, Investment Management
Best for: Financial services data cloud; Snowflake Premier Partner
Mid-market fit: Very High
Leading Snowflake integrator for financial services with Financial Services Competency Badge, FactSet and SimCorp partnerships
---
## DATAPAO
Source: https://dataengineeringcompanies.com/datapao/
Website: https://datapao.com
Founded: 2018
Team size: 50
Hourly rate: $100-175
Minimum project: $25K+
Platforms: Databricks, Azure, AWS, Spark, Kafka, MLOps
Industries: Manufacturing, Pharmaceuticals, Energy, Financial Services
Best for: Datapao is the right choice for European companies running Databricks on Azure or AWS that need MLOps architecture and Spark/Kafka expertise — Databricks Premier Partner status since 2017 and a 50-person focus mean buyers get senior practitioners, not rotated generalists, at $100–175/hr.
Mid-market fit: Very High
Strategic Databricks partner since 2017 in Europe, specializing in cloud migration, AI operationalization, and MLOps
---
## DS Stream
Source: https://dataengineeringcompanies.com/ds-stream/
Website: https://www.dsstream.com/about-us?437a08c9_page=1
Founded: 2017
Team size: 150
Hourly rate: $50-99
Minimum project: $25K+
Platforms: Azure, GCP, AWS, Databricks, Spark, Airflow
Industries: FMCG, Retail, E-commerce, Healthcare, Telecom, Finance, Logistics
Best for: AI and data analytics for global brands; GenAI solutions
Mid-market fit: Very High
150+ senior experts with 130+ certifications, Google, Azure, and Databricks partners, GenAI and MLOps focus
---
## Innowise
Source: https://dataengineeringcompanies.com/innowise/
Website: https://innowise.com
Founded: 2007
Team size: 2500
Hourly rate: $50-100
Minimum project: $25K+
Platforms: AWS, Azure, GCP, Databricks, Kafka, Spark
Industries: Healthcare, Logistics, Finance, Retail, Manufacturing
Best for: Full-cycle software development with data engineering; Eastern Europe
Mid-market fit: High
2500+ engineers with 17+ years experience, 1100+ successful projects, 93% recurring customers, Apache Kafka expertise
---
## ProCogia
Source: https://dataengineeringcompanies.com/procogia/
Website: https://procogia.com
Founded: 2013
Team size: 100
Hourly rate: $125-200
Minimum project: $25K+
Platforms: Azure, AWS, GCP, Snowflake, Databricks, Spark
Industries: Life Sciences, Pharma, Biotechnology, Telecom, Financial Services
Best for: Data consultancy and bioinformatics; enterprise data mesh
Mid-market fit: High
Leading data consultancy with Microsoft, T-Mobile, Roche as clients, data mesh, ML, and bioinformatics expertise
---
## Saviant Consulting
Source: https://dataengineeringcompanies.com/saviant-consulting/
Website: https://www.saviantconsulting.com
Founded: 2012
Team size: 500
Hourly rate: $75-150
Minimum project: $25K+
Platforms: Azure, Databricks, AWS, IoT, PowerBI
Industries: Manufacturing, Industrial Engineering, Energy
Best for: Microsoft Azure specialists; Industrial IoT and smart machines
Mid-market fit: High
Preferred Microsoft Azure partner for smart machine manufacturers, multi-cloud expertise, industrial data solutions
---
## Aimpoint Digital
Source: https://dataengineeringcompanies.com/aimpoint-digital/
Website: https://www.aimpointdigital.com
Founded: 2017
Team size: 200
Hourly rate: $175-275
Minimum project: $25K+
Platforms: Snowflake, Databricks, dbt, AWS, Azure, GCP
Industries: Retail, Financial Services, Healthcare, Transportation, Technology
Best for: Aimpoint Digital is the right call for data teams that need a partner credentialed at the elite tier across Snowflake, Databricks, and dbt at once — rare coverage that removes the need to split a modern-stack program across two specialist firms, available from $25K.
Mid-market fit: High
Databricks Digital Native Partner of Year, Snowflake Elite Partner, dbt Premier Partner, 1950% YoY Snowflake growth
#### Why buyers choose Aimpoint Digital
Aimpoint holds Snowflake Elite (2023-2026), Databricks Digital Native Partner of the Year (2024 and 2025), and dbt Labs Visionary Partner - all simultaneously, at roughly 200 people. Most boutiques pick one platform; Aimpoint runs credentialed practices across all three modern-stack cornerstones. Proprietary accelerators FROST Suite and SQLift compress Snowflake and Databricks timelines beyond what headcount alone delivers.
#### Team, credentials, and industry depth
Founded in Atlanta in 2017, the firm operates across the US, UK, and Colombia with 60+ Snowflake certifications, 3 Snowflake Data Superheroes, and 2 Databricks MVPs. SOC 2 (2022) and a delivery guarantee signal enterprise accountability. An operations research and optimization practice is a genuine differentiator for supply-chain and pricing-heavy programs in retail, financial services, healthcare, and logistics.
#### When Aimpoint Digital is the wrong fit
At $175-275/hr, Aimpoint is premium-priced for a boutique - inappropriate for budget-constrained projects. A ~200-person bench also means programs requiring 50+ dedicated resources over multi-year engagements risk hitting capacity limits; large SIs are the better call there. Buyers committed to a single platform may find a pure-play Snowflake or Databricks specialist carries comparable credentials at a narrower price.
### FAQs
**Q: What type of engagement is Aimpoint Digital best suited for?**
A: Aimpoint Digital is the strongest fit for mid-market and enterprise buyers who need a single partner credentialed across the full modern data stack - Snowflake, Databricks, and dbt - without splitting the program across multiple vendors. It is especially well-positioned for organizations in retail, financial services, healthcare, or logistics that need both platform migration and production AI/ML capability delivered by the same team.
**Q: What does Aimpoint Digital typically charge?**
A: Published rates run $175 - 275 per hour, with a minimum project size of $25K+. That range reflects a senior-practitioner model rather than a staffed-delivery approach, so buyers should expect fewer resources at higher individual seniority. Engagements involving Aimpoint's proprietary accelerators (FROST Suite, SQLift) may compress timelines and offset some of the rate premium.
**Q: Which platforms and industries does Aimpoint Digital cover?**
A: Core platform credentials are Snowflake Elite (2023 - 2026), Databricks Gold Partner with back-to-back Digital Native Partner of the Year (2024 - 2025), and dbt Labs Visionary Partner with the 2024 Americas Innovation Partner of the Year award. The firm also works across AWS, Azure, GCP, Sigma, Dataiku, and Alteryx. Industry experience spans retail, financial services, healthcare, transportation, and logistics, with an additional operations research and optimization practice for supply chain and pricing use cases.
**Q: When is Aimpoint Digital the wrong choice?**
A: Aimpoint is a poor fit when budget is the primary constraint - the $175 - 275/hr rate is premium for a boutique, and lower-cost offshore or nearshore options exist. It is also not the right call for programs that require a sustained bench of 50+ resources, as a ~200-person firm has finite capacity for large parallel workstreams. Buyers already committed to a single platform who want the deepest possible specialization may find a pure-play partner in that ecosystem carries equivalent credentials at a more focused price point.
---
## Beyond Key
Source: https://dataengineeringcompanies.com/beyond-key/
Website: https://www.beyondkey.com
Founded: 2005
Team size: 500
Hourly rate: $100-150
Minimum project: $15K+
Platforms: Azure, PowerBI, AWS, Databricks, .NET
Industries: Cross-industry, Technology, Financial Services
Best for: Microsoft technologies and PowerBI consulting; .NET development
Mid-market fit: High
Leading software development and IT consulting company specializing in Microsoft technologies, PowerBI, and data engineering
---
## BigData Boutique
Source: https://dataengineeringcompanies.com/bigdata-boutique/
Website: https://bigdataboutique.com
Founded: 2015
Team size: 50
Hourly rate: $150-250
Minimum project: $25K+
Platforms: Elasticsearch, OpenSearch, Kafka, Spark, Flink, Databricks, ClickHouse
Industries: Technology, Financial Services, E-commerce, IoT
Best for: Open-source big data; Elasticsearch and OpenSearch specialists
Mid-market fit: Very High
Premier big data consultancy specializing in open-source technologies, Elasticsearch, OpenSearch, Flink, and streaming data
---
## Dateonic
Source: https://dataengineeringcompanies.com/dateonic/
Website: https://dateonic.com
Founded: 2016
Team size: 50
Hourly rate: $100-175
Minimum project: $25K+
Platforms: Databricks, AWS, Azure, GCP, Spark, MLflow
Industries: Technology, Financial Services, Retail
Best for: Dateonic is the right call for a team building or scaling a Databricks or MLflow-based ML platform on AWS, Azure, or GCP — 50 specialists available from $100–175/hr with a $25K minimum engagement.
Mid-market fit: High
Expert Databricks consultancy delivering world-class Big Data and AI solutions with ML platform expertise
---
## XenonStack
Source: https://dataengineeringcompanies.com/xenonstack/
Website: https://www.xenonstack.com
Founded: 2012
Team size: 500
Hourly rate: $50-100
Minimum project: $10K+
Platforms: AWS, Azure, GCP, Databricks, Kafka, Spark, Kubernetes
Industries: Technology, Financial Services, Healthcare, Manufacturing
Best for: Agentic AI systems; real-time analytics; platform engineering
Mid-market fit: High
AI Reasoning Foundry for Agentic Enterprises, Data & AI Foundry with autonomous intelligent systems and real-time data engineering
---
## Algoscale
Source: https://dataengineeringcompanies.com/algoscale/
Website: https://algoscale.com
Founded: 2015
Team size: 200
Hourly rate: $75-125
Minimum project: $25K+
Platforms: Databricks, Snowflake, AWS, Azure, GCP, PySpark
Industries: Cross-industry
Best for: Data engineering and analytics; distributed data processing
Mid-market fit: Very High
Data engineering specialists with Databricks, Snowflake, and cloud expertise, cross-industry modern stack implementation
---
## BIZTORY
Source: https://dataengineeringcompanies.com/biztory/
Website: https://www.biztory.com.my
Founded: 2013
Team size: 100
Hourly rate: $75-150
Minimum project: $15K+
Platforms: Azure, PowerBI, Databricks, AWS, Snowflake
Industries: Retail, Manufacturing, Financial Services
Best for: Asian markets; Microsoft Azure and PowerBI specialists
Mid-market fit: High
Data analytics and BI consultancy focused on PowerBI and Azure solutions for Asian enterprises
---
## Damco Solutions
Source: https://dataengineeringcompanies.com/damco-solutions/
Website: https://www.damcogroup.com
Founded: 1996
Team size: 500
Hourly rate: $50-100
Minimum project: $25K+
Platforms: AWS, Azure, GCP, Databricks, Snowflake, Hadoop, Spark
Industries: Retail, Healthcare, Manufacturing, Logistics
Best for: Enterprise data modernization; Big Data solutions
Mid-market fit: High
Big Data and analytics company providing data engineering, cloud migration, and enterprise modernization services
---
## Improving
Source: https://dataengineeringcompanies.com/improving/
Website: https://improving.com
Founded: 2003
Team size: 500
Hourly rate: $125-200
Minimum project: $50K+
Platforms: Azure, AWS, Databricks, Snowflake, PowerBI, .NET
Industries: Technology, Financial Services, Healthcare
Best for: Software consultancy with data engineering; Agile delivery
Mid-market fit: Medium
Software consulting company with data engineering, cloud, and modern application development capabilities
---
## Perficient
Source: https://dataengineeringcompanies.com/perficient/
Website: https://www.perficient.com
Founded: 1997
Team size: 5000
Hourly rate: $125-200
Minimum project: $100K+
Platforms: AWS, Azure, GCP, Snowflake, Databricks, Salesforce, Adobe
Industries: Healthcare, Financial Services, Retail, Manufacturing
Best for: Digital transformation; enterprise data and analytics
Mid-market fit: Medium
Global digital consultancy with 5000+ professionals, comprehensive data and analytics transformation services
---
## Helical IT Solutions
Source: https://dataengineeringcompanies.com/helical-it-solutions/
Website: https://www.helicalinsight.com
Founded: 2012
Team size: 100
Hourly rate: $50-100
Minimum project: $10K+
Platforms: AWS, Azure, Databricks, Tableau, PowerBI, Pentaho
Industries: BFSI, Healthcare, Retail, Manufacturing
Best for: Open-source BI and data engineering; cost-effective solutions
Mid-market fit: High
BI and data engineering company specializing in open-source solutions, Tableau, PowerBI, and data warehousing
---
## Pingahla
Source: https://dataengineeringcompanies.com/pingahla/
Website: https://pingahla.com
Founded: 2019
Team size: 100
Hourly rate: $50-100
Minimum project: $25K+
Platforms: AWS, Azure, Databricks, Spark, Kafka, Airflow
Industries: Technology, E-commerce, Financial Services
Best for: Data engineering and analytics for startups and mid-market
Mid-market fit: High
Data engineering and analytics consultancy providing modern data stack implementations and cloud solutions
---
## Tata Consultancy Services (TCS)
Source: https://dataengineeringcompanies.com/tata-consultancy-services-tcs/
Website: https://www.tcs.com
Founded: 1968
Team size: 600000
Hourly rate: $50-100
Minimum project: $100K+
Platforms: AWS, Azure, GCP, Databricks, Snowflake, SAP, Oracle
Industries: All sectors, BFSI, Manufacturing, Retail, Healthcare, Telecom
Best for: Multinational enterprises running large-scale, multi-year data platform transformations where offshore delivery economics and a 600,000-person bench matter more than specialist depth.
Mid-market fit: Medium
World's largest AI-led tech services company with 600,000+ employees, 1 GW AI data centre, comprehensive data and AI capabilities
---
## Entrans
Source: https://dataengineeringcompanies.com/entrans/
Website: https://www.entrans.ai
Founded: 2020
Team size: 100
Hourly rate: $75-150
Minimum project: $25K+
Platforms: AWS, Azure, GCP, Snowflake, Databricks, dbt
Industries: Technology, Financial Services, Healthcare
Best for: End-to-end data engineering; data lakehouse implementations
Mid-market fit: High
Data engineering solutions provider with expertise in data lakes, lakehouses, and real-time streaming pipelines
---
## Simform
Source: https://dataengineeringcompanies.com/simform/
Website: https://www.simform.com
Founded: 2010
Team size: 500
Hourly rate: $50-100
Minimum project: $25K+
Platforms: AWS, Azure, GCP, Databricks, Snowflake, Spark
Industries: SaaS, Healthcare, Financial Services, E-commerce
Best for: Simform is the right call for a startup or enterprise that needs a 500-person digital product shop to own both the application layer and its cloud-native data infrastructure — AWS, Azure, GCP, Databricks, and Snowflake — under one engagement starting at $25K.
Mid-market fit: Very High
Digital product engineering company with data engineering, cloud, and AI/ML expertise for startups and enterprises
#### Why buyers choose Simform
Simform holds AWS Premier Partner status (top 1% of the network), Azure Solutions Partner for Data & AI, and Databricks credentials - with 200+ dedicated data engineers covering ETL/ELT, real-time streaming, and BI across Redshift, Synapse, Databricks, and Snowflake. Published outcomes include 80% data accuracy improvement for an automotive platform and 70% cost reduction on an EdTech analytics build.
#### Team, delivery model, and industries
350+ platform-certified engineers operate across AWS, Azure, and GCP in 12 countries, with a 4.8/5 rating across 73 verified Clutch reviews. The co-engineering model assigns multi-skilled pods - architects, data engineers, DevOps - under one engagement. Industry depth spans fintech, healthcare, SaaS, retail, and supply chain, with regulated-data experience in HL7/FHIR and financial transaction monitoring.
#### When Simform is the wrong fit
Simform is a product engineering generalist, not a pure-play data specialist. Buyers whose entire scope is a single-platform warehouse migration - a focused Snowflake cutover with no adjacent product work - will pay for breadth they will not use, and a specialist may complete that work faster. Reviews note occasional inconsistency on engagements where product scope shifts mid-delivery.
### FAQs
**Q: What type of organization is Simform best suited for?**
A: Simform is best suited for SaaS companies, mid-market enterprises, and digital-native businesses that need cloud infrastructure and data engineering built as part of a broader product engagement - not as a standalone data project. The firm's co-engineering model and 200+ data engineers make it a strong fit when data pipelines, analytics, and product development need to move in parallel rather than in sequence.
**Q: What does Simform charge and what is the minimum project size?**
A: Published rates run $50-100/hr, positioning Simform competitively relative to US-headquartered peers with India-based delivery. The minimum project size is $25K+. Buyers should expect longer discovery and onboarding cycles consistent with a full-team engagement model - this is not a firm optimized for rapid, narrowly scoped fixed-price statements of work.
**Q: Which cloud platforms and industries does Simform cover?**
A: Simform holds AWS Premier Partner status (top 1% of the AWS partner network) and Azure Solutions Partner for Data & AI, and is a Databricks partner - giving real partnership depth across the three dominant data platform stacks. Platform work covers Databricks, Snowflake, Redshift, Synapse, and open-source tooling including Airflow, Airbyte, and Superset. Industry experience spans fintech, healthcare and life sciences, SaaS, retail and e-commerce, and supply chain and logistics.
**Q: When is Simform the wrong choice?**
A: Simform is the wrong choice when the engagement is purely a single-platform data migration with no application or product layer involved. Buyers who need a firm whose entire practice revolves around, for example, Snowflake migrations or Databricks optimization will find deeper specialist options elsewhere. It is also less suited to buyers with very small or tightly scoped projects where paying for a large-team co-engineering model creates overhead that outweighs the benefit.
---
## ScienceSoft
Source: https://dataengineeringcompanies.com/sciencesoft/
Website: https://www.scnsoft.com
Founded: 1989
Team size: 700
Hourly rate: $50-100
Minimum project: $10K+
Platforms: AWS, Azure, GCP, Databricks, Snowflake, PowerBI, Tableau
Industries: Healthcare, Financial Services, Retail, Manufacturing
Best for: Healthcare and financial services; compliance-focused data solutions
Mid-market fit: High
35+ years IT consulting with 700+ professionals, healthcare and financial services data engineering expertise
---
## Hashmap
Source: https://dataengineeringcompanies.com/hashmap/
Website: https://us.nttdata.com/en/about-us/content/acquisitions/hashmap-is-now-ntt-data
Founded: 2012
Team size: 200
Hourly rate: $150-250
Minimum project: $50K+
Platforms: Snowflake, Azure, AWS, Databricks, dbt
Industries: Energy, Healthcare, Fintech, Manufacturing
Best for: Enterprises needing cloud migrations and IoT data solutions
Mid-market fit: High
NTT DATA Company focused on data engineering, cloud migration, and AI/ML. Known for deep technical expertise in Snowflake and Azure.
#### Why buyers choose Hashmap
Hashmap combines the technical focus of a specialized boutique with the enterprise credibility of its NTT DATA parent. Since the acquisition, Hashmap has retained its Snowflake implementation reputation while gaining access to larger enterprise engagements - multi-year contracts with defined SLAs - that pure boutiques cannot credibly bid on. Platform migration and data modernization are both rated Expert.
#### IoT depth, platforms, and industries
Hashmap's strongest differentiator is IoT and industrial data engineering built through years of energy and manufacturing work. Their engineers understand high-volume time-series data from OT sensors and industrial control systems - an area most cloud-focused firms lack. The 200-person team covers Snowflake, Azure, AWS, Databricks, and dbt, with SnowPro-certified practitioners across Energy, Healthcare, and Manufacturing verticals.
#### When Hashmap is the wrong fit
Hashmap is the wrong choice for buyers who need GCP as the primary platform or for multi-cloud programs spanning platforms beyond Snowflake and Azure. At $150-250/hr with a 200-person team, it also cannot sustain global delivery bench or contractual scale for large parallel workstreams outside its industrial and energy vertical strength.
### FAQs
**Q: Is Hashmap (NTT DATA) good for Snowflake implementations?**
A: Yes. Hashmap built its reputation as a Snowflake implementation specialist and remains one of the most technically credentialed partners for Snowflake projects. Their engineers hold SnowPro certifications and the firm has completed 100+ Snowflake migration projects across Energy, Healthcare, and Manufacturing sectors — making them a top choice for complex, first-time Snowflake deployments.
**Q: How does NTT DATA's acquisition affect Hashmap's consulting services?**
A: Since the NTT DATA acquisition, Hashmap has retained its boutique technical culture while gaining enterprise credibility and financial stability. For clients, this means access to Hashmap's specialized Snowflake and Azure expertise backed by a global corporation's SLA guarantees and insurance capacity — enabling them to take on larger enterprise contracts that smaller boutiques cannot sign.
**Q: What makes Hashmap different from other cloud data engineering firms?**
A: Hashmap's key differentiator is its IoT and industrial data engineering depth, built through years of Energy and Manufacturing projects. They understand time-series data from OT sensors and industrial control systems — a specialized capability most cloud-focused data firms lack. Their $150–$250/hr rate reflects this premium technical expertise and the credibility of NTT DATA backing.
**Q: Is Hashmap a good fit for enterprise clients?**
A: Hashmap rates 'High' for mid-market fit but also serves enterprise clients effectively through NTT DATA. Enterprises benefit from Hashmap's Snowflake SnowPro certification depth, documented multi-sector case studies, and the ability to sign multi-year contracts with SLA guarantees — capabilities smaller boutiques cannot credibly offer at scale.
---
## Dataroots
Source: https://dataengineeringcompanies.com/dataroots/
Website: https://dataroots.io
Founded: 2016
Team size: 50
Hourly rate: $100-175
Minimum project: $25K+
Platforms: AWS, Azure, Python, Spark, Terraform
Industries: Retail, Media, Logistics
Best for: AI-driven data engineering and MLOps implementation
Mid-market fit: Very High
Benelux-based AI and data engineering specialists with a strong focus on MLOps and cloud-native data platforms.
---
## Data Driven
Source: https://dataengineeringcompanies.com/data-driven/
Website: https://data-driven.com
Founded: 2018
Team size: 80
Hourly rate: $125-200
Minimum project: $35K+
Platforms: Snowflake, Databricks, AWS, dbt
Industries: SaaS, E-commerce, Financial Services
Best for: Modern data stack implementation and analytics engineering
Mid-market fit: High
Boutique consultancy specializing in building scalable data platforms and enabling self-service analytics using the modern data stack.
---
## Element Data
Source: https://dataengineeringcompanies.com/elementdata/
Website: https://elementdata.com
Founded: 2019
Team size: 40
Hourly rate: $150-225
Minimum project: $20K+
Platforms: Azure, Power BI, Databricks
Industries: Healthcare, Professional Services, Public Sector
Best for: Microsoft stack optimization and Power BI enterprise rollouts
Mid-market fit: High
Data modernization experts focusing on the Microsoft ecosystem, helping organizations unlock value from Azure Data and Power BI.
---
## Datacoves
Source: https://dataengineeringcompanies.com/datacoves/
Website: https://datacoves.com
Founded: 2020
Team size: 30
Hourly rate: $140-220
Minimum project: $25K+
Platforms: dbt, Snowflake, Airflow
Industries: Technology, Media, Retail
Best for: dbt implementation and analytics engineering workflow optimization
Mid-market fit: Very High
Specialists in reducing friction in analytics engineering. Creators of the Datacoves platform to streamline dbt and Airflow development.
---
## Brooklyn Data Co
Source: https://dataengineeringcompanies.com/brooklyn-data/
Website: https://brooklyndata.co
Founded: 2018
Team size: 70
Hourly rate: $160-240
Minimum project: $40K+
Platforms: dbt, Snowflake, Looker, Fivetran
Industries: Media, E-commerce, SaaS
Best for: Brooklyn Data (now part of Velir) is the right choice for companies building or maturing a dbt-centered modern data stack with Snowflake, Looker, and Fivetran — its 70-person full-stack specialization in that ecosystem delivers tighter engagements than a generalist at $40K+.
Mid-market fit: Very High
A full-service data and analytics consultancy, now part of Velir. Known for deep community involvement and expertise in the dbt ecosystem.
---
## Paradime
Source: https://dataengineeringcompanies.com/paradime/
Website: https://paradime.io
Founded: 2020
Team size: 25
Hourly rate: $130-200
Minimum project: $20K+
Platforms: dbt, Snowflake, BigQuery
Industries: Technology, SaaS
Best for: Analytics engineering productivity tools and consulting
Mid-market fit: High
Focuses on providing tools and services to supercharge analytics engineering teams, with a platform that integrates dbt development.
---
## Hakkoda
Source: https://dataengineeringcompanies.com/hakkoda/
Website: https://hakkoda.io
Founded: 2021
Team size: 150
Hourly rate: $140-220
Minimum project: $50K+
Platforms: Snowflake, AWS, Azure, dbt
Industries: Financial Services, Healthcare, Public Sector
Best for: Hakkoda is the right fit for healthcare and financial-services teams building cloud-native data platforms on Snowflake where domain compliance expertise matters as much as engineering — at $140–220/hr with a $50K minimum, the specialization comes without the overhead of a global SI.
Mid-market fit: High
Born-in-the-cloud Snowflake specialist providing on-demand data teams. Rapidly growing with a strong focus on healthcare and financial services vertical solutions.
---
## Datalytyx
Source: https://dataengineeringcompanies.com/datalytyx/
Website: https://www.datalytyx.com
Founded: 2014
Team size: 60
Hourly rate: $125-200
Minimum project: $30K+
Platforms: Snowflake, Talend, AWS, Azure
Industries: Public Sector, Manufacturing, Retail
Best for: Data governance and managed data services
Mid-market fit: High
UK-based leading provider of big data engineering, data analytics, and cloud solutions. Strong partnership with Snowflake and Talend (Qlik).
---
## Infostrux
Source: https://dataengineeringcompanies.com/infostrux/
Website: https://www.infostrux.com/
Founded: 2021
Team size: 70
Hourly rate: $140-210
Minimum project: $40K+
Platforms: Snowflake, dbt, AWS
Industries: SaaS, Retail, Media
Best for: Infostrux is the right choice for data teams adopting Data Vault 2.0 on Snowflake with dbt — its 70-person pure-play focus means the methodology is the firm's core practice, not an add-on service, available from $40K.
Mid-market fit: Very High
Pure-play Snowflake services partner. Experts in Data Vault methodology and building robust, scalable data engineering solutions on the Data Cloud.
---
## McKinsey & Company
Source: https://dataengineeringcompanies.com/mckinsey/
Website: https://www.mckinsey.com/capabilities/quantumblack/how-we-help-clients
Founded: 1926
Team size: 2000+
Hourly rate: $250+
Minimum project: $500K+
Platforms: QuantumBlack, AWS, Azure, GCP, Snowflake
Industries: Financial Services, Healthcare, Energy, Retail
Best for: Large-scale digital transformation and strategy-led AI initiatives
Mid-market fit: Low
Global strategy leader with QuantumBlack as its data and AI arm. Focuses on high-value business outcomes driven by advanced analytics.
---
## Bain & Company
Source: https://dataengineeringcompanies.com/bain/
Website: https://www.bain.com/vector-digital/advanced-analytics/
Founded: 1973
Team size: 1500+
Hourly rate: $250+
Minimum project: $400K+
Platforms: AWS, Azure, GCP, Snowflake
Industries: Private Equity, Retail, Technology
Best for: Private equity firms and portfolio companies requiring due-diligence-grade analytics strategy on Snowflake, where Bain's PE relationships and $400K+ engagement model are already embedded in the deal process.
Mid-market fit: Low
Combines strategic consulting with Vector, their digital delivery platform. Strong in data strategy and commercial excellence.
---
## BCG X
Source: https://dataengineeringcompanies.com/boston-consulting-group/
Website: https://www.bcg.com/x
Founded: 1963
Team size: 2500+
Hourly rate: $250+
Minimum project: $500K+
Platforms: AWS, Azure, GCP, Databricks
Industries: Consumer, Industrial, Financial Services
Best for: Boards and executive teams commissioning a deep-tech or AI venture build through BCG X, where the engagement is strategic investment rather than data engineering delivery.
Mid-market fit: Low
BCG X is the tech build and design unit of BCG. Focuses on deep tech, AI, and building data-driven business models.
#### What BCG X actually is
BCG X is the technology and product build arm of Boston Consulting Group - distinct from BCG's traditional strategy practice. Where BCG advises, BCG X builds: engineering teams that design and deploy data platforms, AI products, and digital ventures. It operates more like a product engineering studio backed by BCG's strategy network than a conventional IT consultancy.
#### How engagements are structured
BCG X engagements typically begin with a strategic assessment - where does data create competitive advantage? - then move to platform engineering to capture that advantage. Mixed teams of strategy partners, product designers, and data engineers work in parallel. The $500K+ minimum reflects that genuine organizational cost, not just billing rate.
#### When BCG X is the wrong fit
BCG X is the wrong choice for any organization that cannot justify a $500K+ minimum or $250+/hr rate, or that has well-defined technical requirements rather than an open-ended transformation mandate. Hashmap, phData, or Sigmoid deliver equivalent technical output at 30-50% of the cost for scoped migration or BI buildout work.
### FAQs
**Q: What is the difference between BCG and BCG X?**
A: BCG (Boston Consulting Group) is a strategy consultancy that advises executives on business decisions. BCG X is BCG's technology build and design unit that engineers and deploys digital products, AI systems, and data platforms. BCG X teams include engineers, designers, and data scientists who build alongside strategy consultants — not just advise. Think of BCG X as BCG's in-house product studio.
**Q: Is BCG X suitable for mid-market companies?**
A: No. BCG X's minimum project size ($500K+) and strategic engagement model are designed for large enterprises and Fortune 500 companies undertaking multi-year digital transformation programs. Mid-market companies seeking data warehouse implementations, pipeline engineering, or BI buildouts are significantly better served by boutique firms like Hashmap, Phdata, Sigmoid, or Fractal Analytics — which deliver comparable technical output at 30–60% of BCG X's cost.
**Q: What data platforms does BCG X use?**
A: BCG X is platform-agnostic and selects technology based on client context. They have deep experience with AWS (SageMaker, Glue, Redshift), Azure (Synapse, ADF, Azure ML), GCP (BigQuery, Vertex AI), and Databricks for large-scale ML and Lakehouse architectures. Their platform selection process is driven by client industry (GCP for media/retail, Azure for financial services) and existing enterprise agreements.
**Q: How long does a typical BCG X data engineering engagement last?**
A: BCG X data and AI engagements typically run 6–18 months for full platform builds. Initial diagnostic and scoping phases run 6–12 weeks. Platform engineering phases run 4–12 months with integrated BCG-X engineering teams. Multi-year managed programs are common for enterprises with ongoing AI capability development needs. The long engagement model is a structural characteristic — BCG X is not designed for fixed-scope short engagements.
---
## EY
Source: https://dataengineeringcompanies.com/ey/
Website: https://www.ey.com/en_us/services/consulting/analytics-consulting-services
Founded: 1989
Team size: 5000+
Hourly rate: $175+
Minimum project: $200K+
Platforms: Microsoft Fabric, Azure, Snowflake, Databricks
Industries: Financial Services, Public Sector, Automotive
Best for: Global compliance, audit-ready data platforms, and finance transformation
Mid-market fit: Medium
Massive global scale with deep expertise in tax, audit, and finance data. Leading partner for Microsoft Fabric and Azure data solutions.
---
## KPMG
Source: https://dataengineeringcompanies.com/kpmg/
Website: https://kpmg.com/xx/en/home/services/advisory/technology/data-analytics.html
Founded: 1987
Team size: 4000+
Hourly rate: $175+
Minimum project: $150K+
Platforms: Azure, Oracle, Snowflake, AWS
Industries: Banking, Insurance, Government
Best for: Risk management, regulatory reporting, and finance back-office data
Mid-market fit: Medium
Detailed focus on data integrity, governance, and regulatory compliance. Strong in modernizing legacy finance systems.
---
## PwC
Source: https://dataengineeringcompanies.com/pwc/
Website: https://www.pwc.com/us/en/services/consulting/engineering-ai/data-ai.html
Founded: 1998
Team size: 6000+
Hourly rate: $175+
Minimum project: $200K+
Platforms: Azure, AWS, GCP, Snowflake, Salesforce
Industries: Financial Services, Retail, Healthcare
Best for: Busines-led transformation and finance function modernization
Mid-market fit: Medium
Global scale with a focus on 'business-led, technology-enabled' transformations. Massive capabilities in cloud data platforms and governance.
---
## HCLTech
Source: https://dataengineeringcompanies.com/hcl-technologies/
Website: https://www.hcltech.com/data-and-ai
Founded: 1976
Team size: 10000+
Hourly rate: $50-125
Minimum project: $100K+
Platforms: GCP, AWS, Azure, Informatica, Snowflake
Industries: Life Sciences, Manufacturing, Banking
Best for: Large-scale legacy migrations and managed services outsourcing
Mid-market fit: Medium
Global systems integrator known for massive scale execution. Strong capabilities in engineering data pipelines and managing legacy modernization at scale.
---
## Tech Mahindra
Source: https://dataengineeringcompanies.com/tech-mahindra/
Website: https://www.techmahindra.com/services/data-analytics/
Founded: 1986
Team size: 8000+
Hourly rate: $45-120
Minimum project: $80K+
Platforms: AWS, Azure, GCP, IBM, Splunk
Industries: Telecommunications, Automotive, Manufacturing
Best for: Telecom operators and large manufacturers running multi-year data platform programs where offshore delivery economics and domain-specific process knowledge are primary selection criteria.
Mid-market fit: Medium
Deep vertical expertise in telecom and automotive. Focuses on 'NXT.NOW' framework for digital transformation and AI-driven operations.
---
## LTIMindtree
Source: https://dataengineeringcompanies.com/ltimindtree/
Website: https://www.ltimindtree.com/services/data-and-analytics/
Founded: 1996
Team size: 5000+
Hourly rate: $55-130
Minimum project: $100K+
Platforms: Snowflake, Azure, AWS, Databricks
Industries: Insurance, Banking, Retail
Best for: Snowflake migrations for large enterprises
Mid-market fit: High
Formed from the merger of L&T Infotech and Mindtree. A top-tier Snowflake partner with a strong reputation for delivery quality in the GSI space.
#### Why buyers choose LTIMindtree
LTIMindtree pairs GSI scale with deep Snowflake credentials. Formed from the merger of L&T Infotech and Mindtree in November 2022, it holds Snowflake Elite Service Partner status and won Snowflake's global GSI award three consecutive years (2021-2023). The 2025 ISG Provider Lens named it a leader across all three Snowflake ecosystem quadrants. Its PolarSled framework underpins 100+ documented Snowflake implementations.
#### Bench depth, certifications, and industries
The data engineering bench runs 5,000+ practitioners within an 86,000-person firm, with 70%+ of Snowflake practitioners holding Snowflake certifications. LTIMindtree also won the 2025 Databricks Business Transformation Partner of the Year award. Industry coverage is strongest in Insurance, Banking, Retail, and Manufacturing - verticals where legacy data warehouse debt makes the PolarSled playbook directly applicable.
#### When LTIMindtree is the wrong fit
LTIMindtree is a large SI: engagements start at $100K+, and global delivery coordination adds process weight smaller programs cannot absorb. Buyers wanting a nimble, founder-accessible Snowflake specialist or whose scope sits below six figures will pay a mismatch tax. Organizations centered on a platform outside Snowflake or Databricks will also find the firm's tooling and accelerators largely irrelevant.
### FAQs
**Q: What type of data engineering engagement is LTIMindtree best suited for?**
A: LTIMindtree is strongest for large-enterprise Snowflake migrations and data modernization programs - particularly in Insurance, Banking, Retail, and Manufacturing, where legacy data warehouse complexity is high. Its proprietary PolarSled framework and 100+ documented Snowflake implementations give it a structured, repeatable playbook for migrating from platforms like Teradata, Netezza, or on-premise MPP systems to Snowflake. Engagements with multi-year scope, global teams, or regulatory data governance requirements are where the GSI model justifies itself.
**Q: What are LTIMindtree's typical rates and minimum project size?**
A: Published rate ranges are $55-130/hr depending on role seniority and delivery location, reflecting the firm's global delivery mix (India-heavy offshore with onshore coordination). Project minimums start at $100K+. Buyers should expect GSI commercial structures - statement-of-work engagements, not time-and-materials flexibility - so budget certainty and scope clarity matter before engagement.
**Q: Which platforms and industries does LTIMindtree specialize in?**
A: Snowflake is the primary platform specialization - LTIMindtree holds Elite Partner status and has won Snowflake's global GSI award multiple years running. Databricks is a verified secondary platform (2025 Business Transformation Partner of the Year). Azure and AWS round out the cloud layer. Industry depth is strongest in Insurance, Banking and Capital Markets, Retail and CPG, and Manufacturing - all sectors with significant legacy data estate migration backlogs.
**Q: When is LTIMindtree the wrong choice?**
A: LTIMindtree is the wrong fit for engagements under $100K, teams that need a fast-moving specialist boutique, or programs where Snowflake and Databricks are not the target platforms. The GSI model adds coordination layers - account management, offshore-onshore handoffs, SOW governance - that create overhead smaller programs cannot absorb. Buyers looking for a founder-accessible team with direct senior delivery involvement will find the large-SI structure a poor match regardless of rate.
---
## Mphasis
Source: https://dataengineeringcompanies.com/mphasis/
Website: https://www.mphasis.com/home/services/application-services/data-engineering.html
Founded: 2000
Team size: 4000+
Hourly rate: $50-125
Minimum project: $90K+
Platforms: AWS, Azure, Snowflake
Industries: Banking, Insurance, Logistics
Best for: Banking and capital-markets firms running structured data modernization programs on Snowflake where financial-services domain expertise is a baseline requirement.
Mid-market fit: Medium
Specializes in 'Front2Back' transformation. Extremely strong in the financial services sector, helping banks migrate legacy mainframes to cloud data platforms.
---
## dbt Labs Services
Source: https://dataengineeringcompanies.com/dbt-labs/
Website: https://www.getdbt.com/
Founded: 2016
Team size: 400
Hourly rate: $200-300
Minimum project: $40K+
Platforms: dbt, Snowflake, Databricks, BigQuery, Redshift
Industries: Cross-industry
Best for: dbt Labs is the definitive choice for organizations migrating legacy analytics engineering to dbt, standardizing dbt practices across a data organization, or requiring training directly from the team that built and maintains the tool — at $200–300/hr.
Mid-market fit: High
The creators of dbt. Their expert services team helps organizations implement best practices, migrate legacy code to dbt, and train analytics engineers.
#### Why buyers choose dbt Labs Services
dbt Labs Professional Services is the only consulting team whose practitioners built the tool they implement. When their team works on advanced dbt patterns - dbt Mesh, semantic layer, metricflow, cross-project dependencies - they are the authoritative source, not consultants interpreting documentation. That distinction is meaningful for organizations tackling patterns where third-party partners are still learning.
#### Implementation, training, and platform coverage
Engagements combine implementation - dbt project architecture, staging model design, CI/CD setup - with intensive analytics engineering training. The 400-person team covers Snowflake, Databricks SQL, BigQuery, and Redshift with adapter-specific optimization depth. For organizations building a long-term internal dbt practice, the knowledge transfer compounds the implementation value.
#### When dbt Labs Services is the wrong fit
dbt Labs Services is the wrong choice for buyers needing a full-stack data platform partner. ML/AI pipelines, infrastructure or cloud migration, streaming pipelines, and ingestion work are all outside their intentional scope. At $200-300/hr, the rate is also difficult to justify for organizations doing only incidental dbt work alongside broader platform engineering.
### FAQs
**Q: Why hire dbt Labs Professional Services instead of a dbt partner?**
A: dbt Labs' own services team has direct access to product engineering and is the authoritative source for dbt best practices. For advanced dbt patterns — dbt Mesh, semantic layer, metricflow, cross-project refs — no third-party consultant matches their depth. For straightforward dbt Core implementations, certified dbt partners (Hashmap, Phdata, Fivetran) offer comparable quality at lower rates.
**Q: What does a typical dbt Labs Professional Services engagement include?**
A: Typical engagements combine implementation and training. Implementation work covers: dbt project architecture, source and staging model design, mart layer development, CI/CD pipeline setup (dbt Cloud), and metrics layer configuration. Training covers: analytics engineering fundamentals, dbt best practices workshops, and code review sessions. Minimum engagement is typically $40K, with most projects running $80K–$250K.
**Q: Does dbt Labs Services work with Snowflake, Databricks, and BigQuery?**
A: Yes. dbt is warehouse-agnostic and dbt Labs' services team has deep experience across Snowflake, Databricks SQL, BigQuery, Redshift, and DuckDB. They can help with adapter-specific optimization (Snowflake clustering, Databricks Delta materialization, BigQuery partitioning) that generic dbt consultants may not know.
**Q: How much does dbt Labs Professional Services cost?**
A: Rates are $200–$300/hr, positioning them as a premium provider. A typical 12-week engagement (architecture + implementation + training) runs $100,000–$250,000. For organizations building a long-term internal dbt practice, the investment is justified by the quality of the foundation and the knowledge transfer. For simpler implementations, certified dbt partners typically deliver at $100–$180/hr.
---
## Fivetran Services
Source: https://dataengineeringcompanies.com/fivetran-partners/
Website: https://www.fivetran.com/services
Founded: 2012
Team size: 1000
Hourly rate: $200+
Minimum project: $20K+
Platforms: Fivetran, Snowflake, Databricks, BigQuery
Industries: Cross-industry
Best for: Modern data ingestion strategy and connector configuration
Mid-market fit: Very High
Professional services from the नेता in automated data movement. Specialists in setting up high-volume, secure data ingestion pipelines.
---
## Monte Carlo Services
Source: https://dataengineeringcompanies.com/monte-carlo/
Website: https://montecarlo.ai/
Founded: 2019
Team size: 200
Hourly rate: $200+
Minimum project: $30K+
Platforms: Monte Carlo, Snowflake, Databricks, dbt
Industries: Cross-industry
Best for: Implementing data observability and data reliability engineering
Mid-market fit: High
The leaders in data observability. Their services team helps customers design reliable data platforms and implement automated quality monitoring.
---
## Atlan Services
Source: https://dataengineeringcompanies.com/atlan-partners/
Website: https://atlan.com/
Founded: 2018
Team size: 300
Hourly rate: $175-250
Minimum project: $25K+
Platforms: Atlan, Snowflake, Databricks, AWS
Industries: Cross-industry
Best for: Active data governance and metadata management setup
Mid-market fit: High
Services team for the active data catalog platform. Experts in setting up automated lineage, data discovery, and collaborative governance workflows.
#### Why buyers choose Atlan Services
Atlan Services is the implementation arm of the Atlan platform - a Gartner Leader in Metadata Management Solutions and a Forrester Leader in Enterprise Data Catalogs (both 2025). For organizations that need automated lineage, a business glossary, policy-driven access controls, and a self-service catalog non-engineers will actually use, Atlan Services brings genuine domain authority over a generic consulting overlay.
#### Connectors, engagement models, and client credibility
The 300-person team implements Atlan's 100+ pre-built connectors across Snowflake, Databricks, AWS, BI tools, and transformation layers - no custom integration work required. Engagements range from advisory workshops that align stakeholders on governance domains before any configuration begins, through to full implementation and adoption programs. Documented customers include Mastercard, Nasdaq, and JPMorgan Chase across regulated, data-intensive verticals.
#### When Atlan Services is the wrong fit
Atlan Services rates AI/ML enablement as Low and platform migration as Moderate - it will not architect a Databricks lakehouse or build ML pipelines. Buyers whose primary need is platform engineering or broad data engineering delivery will find the rate card misaligned at $175-250/hr. The fit is strongest when a governance program, not a build program, is the goal.
### FAQs
**Q: What type of engagement is Atlan Services best suited for?**
A: Atlan Services is the right call when an organization is standing up or maturing a formal data governance program - specifically catalog implementation, automated lineage setup, business glossary creation, and policy-driven access controls. Buyers who are still in the 'build the data platform' phase, rather than the 'govern and activate the data we already have' phase, should look elsewhere first.
**Q: What does Atlan Services charge and what is the minimum engagement size?**
A: Rates run $175-250/hr with a $25K+ minimum project size. That positions this as a premium-rate engagement - justified when the governance mandate is clear, but a costly mismatch for buyers whose primary need is platform engineering rather than catalog and metadata work.
**Q: Which platforms and tools does Atlan Services specialize in?**
A: The core platform is Atlan itself, which connects to 100+ data sources via pre-built connectors - including Snowflake, Databricks, and AWS as primary warehouse and cloud targets, plus BI tools, transformation layers, and observability systems. The team does not position itself as a generic multi-cloud engineering partner; depth is in governance tooling and metadata activation rather than infrastructure build-out.
**Q: When is Atlan Services the wrong choice?**
A: If the engagement is primarily about platform migration, AI/ML pipeline development, or broad data engineering delivery, Atlan Services is a poor fit - its own capability profile rates AI/ML enablement as Low and platform migration as Moderate. Buyers with a build-first mandate will pay premium governance rates for capabilities that are not this team's core strength.
---
## Hightouch
Source: https://dataengineeringcompanies.com/hightouch/
Website: https://hightouch.com/
Founded: 2018
Team size: 150
Hourly rate: $180-250
Minimum project: $20K+
Platforms: Hightouch, Snowflake, BigQuery, Salesforce
Industries: Retail, SaaS, Marketing
Best for: Reverse ETL and Data Activation strategy
Mid-market fit: Very High
Leading Reverse ETL platform. Helps companies activate their data warehouse by syncing customer data to tools like Salesforce, HubSpot, and Facebook Ads.
---
## RudderStack
Source: https://dataengineeringcompanies.com/rudderstack/
Website: https://www.rudderstack.com/
Founded: 2019
Team size: 120
Hourly rate: $160-230
Minimum project: $25K+
Platforms: RudderStack, Snowflake, BigQuery, Databricks
Industries: Retail, SaaS, Media
Best for: Warehouse-native Customer Data Platform (CDP) implementation
Mid-market fit: High
Provider of warehouse-native customer data infrastructure. Services focus on replacing legacy CDPs with flexible data pipelines built on your warehouse.
---
## Airbyte Services
Source: https://dataengineeringcompanies.com/airbyte-consulting/
Website: https://airbyte.com/
Founded: 2020
Team size: 100
Hourly rate: $150-220
Minimum project: $15K+
Platforms: Airbyte, AWS, Azure, GCP
Industries: Cross-industry
Best for: Custom connector development and large-scale data replication
Mid-market fit: Very High
Experts in open-source ELT. Services include building custom Airbyte connectors and architecting resilient data ingestion pipelines.
---
## Materialize
Source: https://dataengineeringcompanies.com/materialize/
Website: https://materialize.com
Founded: 2019
Team size: 80
Hourly rate: $170-240
Minimum project: $30K+
Platforms: Materialize, Kafka, PostgreSQL
Industries: Fintech, Logistics, Gaming
Best for: Materialize is the right call for an engineering team that needs operational dashboards or real-time analytics built in standard SQL on Kafka and PostgreSQL — without introducing Spark or Flink — at $170–240/hr.
Mid-market fit: High
Pioneers in streaming SQL. Their services focus on helping companies build real-time data products using standard SQL without the complexity of Spark/Flink.
---
## Confluent
Source: https://dataengineeringcompanies.com/confluent-partners/
Website: https://www.confluent.io/services/
Founded: 2014
Team size: 2500+
Hourly rate: $200+
Minimum project: $100K+
Platforms: Kafka, AWS, Azure, GCP
Industries: Financial Services, Retail, Automotive
Best for: Enterprise-scale event streaming and data in motion
Mid-market fit: Low
The company founded by the creators of Apache Kafka. Best-in-class expertise for architecting mission-critical, real-time data streaming platforms.
---
## Dagster Labs
Source: https://dataengineeringcompanies.com/dagster-labs/
Website: https://dagster.io/
Founded: 2018
Team size: 60
Hourly rate: $160-230
Minimum project: $35K+
Platforms: Dagster, Kubernetes, Snowflake, AWS
Industries: Cross-industry
Best for: Modern data orchestration and data platform engineering context
Mid-market fit: High
Services from the creators of Dagster. Focus on implementing asset-based orchestration to make data pipelines more testable, reliable, and observable.
---
## Thoughtworks
Source: https://dataengineeringcompanies.com/thoughtworks/
Website: https://www.thoughtworks.com
Founded: 2010
Team size: 10000
Hourly rate: $150-250
Minimum project: $25k+
Platforms: AWS, Azure, GCP, Databricks, Snowflake, Spark, Kafka
Industries: Financial Services, Retail, Healthcare, Energy
Best for: Organizations adopting data mesh as an architectural pattern who need the team that originated and operationalized the approach at enterprise scale.
Mid-market fit: Medium
Global technology consultancy with 10,000+ professionals, data mesh pioneers, modern data architecture leaders
---
## Kanerika Inc
Source: https://dataengineeringcompanies.com/kanerika-inc/
Website: https://www.kanerika.com
Founded: 2015
Team size: 200
Hourly rate: $75-150
Minimum project: $10K+
Platforms: Azure, AWS, GCP, Databricks, Snowflake, PowerBI
Industries: Manufacturing, Healthcare, Retail, Logistics
Best for: Intelligent automation and data analytics; Microsoft Azure specialists
Mid-market fit: High
Data analytics and intelligent automation consultancy building efficient enterprises with integrated responsive solutions
#### Why buyers choose Kanerika
Kanerika's distinguishing characteristic is the intersection of data engineering and intelligent automation - RPA combined with data pipelines. Where most firms stop at surfacing data in dashboards, Kanerika extends the value chain into automated workflows that act on the data: order processing triggers, inventory replenishment, and exception management without manual analyst intervention.
#### Azure specialization, applied AI, and industries
Among their 200 engineers, Azure Data Factory, Azure Synapse Analytics, and Power BI represent the deepest expertise, making them a natural fit for organizations in the Microsoft ecosystem. Applied AI work covers anomaly detection in manufacturing quality data, demand forecasting for retail and logistics, and document intelligence via Azure Cognitive Services - practical production models, not research AI.
#### When Kanerika is the wrong fit
Kanerika's deep specialization sits firmly inside the Microsoft ecosystem. Buyers whose primary platform is Snowflake without Azure, or programs requiring delivery scale beyond what a 200-person firm can sustain as a parallel workstream, will quickly reach the edge of its mature practice. Novel ML research or large-scale AI platform engineering also falls outside their scope.
### FAQs
**Q: Is Kanerika good for Azure Synapse and Power BI implementations?**
A: Yes, Azure is Kanerika's primary platform. They have deep experience with Azure Data Factory pipelines, Azure Synapse Analytics, Databricks on Azure, and Power BI reporting. For organizations in the Microsoft ecosystem looking for a mid-market partner (not a global SI), Kanerika offers strong technical depth at $75–$150/hr versus $150–$250/hr for larger Microsoft partners.
**Q: What industries does Kanerika specialize in?**
A: Kanerika's strongest verticals are Manufacturing, Healthcare, Retail, and Logistics. In manufacturing, they build quality control analytics and OEE (Overall Equipment Effectiveness) dashboards. In healthcare, they handle clinical data pipelines with HIPAA compliance. In logistics, they build supply chain visibility and demand forecasting solutions. Their intelligent automation practice (RPA + data) is particularly strong in manufacturing operations.
**Q: What is Kanerika's approach to AI and machine learning?**
A: Kanerika focuses on applied AI — practical machine learning models in production solving specific business problems — rather than research AI. Their work includes demand forecasting models (retail, logistics), anomaly detection (manufacturing quality), and document intelligence using Azure Cognitive Services and Azure OpenAI. They are less suited to organizations needing novel ML research or large-scale AI platform engineering.
**Q: How does Kanerika compare to larger Azure partners like Avenga or Accenture?**
A: Kanerika's advantages over larger firms: $10K minimum project (vs. $100K+ at Accenture), faster engagement start (weeks vs. months), and dedicated attention from senior engineers. Trade-offs: smaller team (200 vs. 2500+), narrower global delivery footprint, and less breadth for organizations needing simultaneous work across many technology stacks. Best for focused Azure data and automation projects with a $25K–$250K budget.
---
# Section 3: Hub pages (vendor categories)
- [Databricks Consulting](https://dataengineeringcompanies.com/databricks-consulting/)
- [Snowflake Consulting](https://dataengineeringcompanies.com/snowflake-consulting/)
- [AWS Data Engineering](https://dataengineeringcompanies.com/aws-data-engineering/)
- [Azure Data Engineering](https://dataengineeringcompanies.com/azure-data-engineering/)
- [GCP Data Engineering](https://dataengineeringcompanies.com/gcp-data-engineering/)
- [Healthcare Data Engineering](https://dataengineeringcompanies.com/healthcare-data-engineering/)
- [FinTech Data Engineering](https://dataengineeringcompanies.com/fintech-data-engineering/)
- [Retail Data Engineering](https://dataengineeringcompanies.com/retail-data-engineering/)
- [Enterprise Data Engineering](https://dataengineeringcompanies.com/enterprise-data-engineering/)
- [Data Governance Consulting](https://dataengineeringcompanies.com/data-governance/)
- [Data Migration Companies](https://dataengineeringcompanies.com/data-migration-companies/)
- [AI Data Engineering](https://dataengineeringcompanies.com/ai-data-engineering/)
- [Data Pipeline Architecture](https://dataengineeringcompanies.com/data-pipeline/)
- [Snowflake vs Databricks](https://dataengineeringcompanies.com/snowflake-vs-databricks/)
- [How to Choose a Data Engineering Company](https://dataengineeringcompanies.com/how-to-choose-data-engineering-company/)
- [Data Engineering Companies Index Methodology](https://dataengineeringcompanies.com/methodology/)
- [About Data Engineering Companies Index](https://dataengineeringcompanies.com/about/)
- [Editorial Policy](https://dataengineeringcompanies.com/editorial-policy/)
- [Get Matched — Free Vendor Shortlist](https://dataengineeringcompanies.com/get-matched/)
---
# Stats
- Insight articles: 89
- Vendor profiles: 86
- Hub pages: 19
- Generated: 2026-09-02